
Evaluating Classifiers by Means of Test Data with Noisy Labels
Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence. Pages 513-517.
© 2003 International Joint Conferences on Artificial Intelligence
Abstract
Often the most expensive and time-consuming task in building a pattern recognition system is collecting and accurately labeling training and testing data. In this paper, we explore the use of inexpensive noisy testing data for evaluating a classifier's performance. We assume 1) the (human) labeler provides category labels with a known mislabeling rate and 2) the trained classifier and the labeler are statistically independent. We then derive the number of "noisy" test samples that are, on average, equivalent to a single perfectly labeled test sample for the task of evaluating the classifier's performance. For practical and realistic error and mislabeling rates, this number of equivalent test patterns can be surprisingly low. We also derive an upper and lower bound for the true error rate when the labeler and the classifier are not independent.
- [Blum and Mitchell, 1998] Avrim Blum and Tom Mitchell. Combining labeled and unlabeled data with co-training. In Proceedings of the 11th Annual Conference on Computa- tional Learning Theory (COLT '98), pages 92-100, 1998.
- Duda et a!., 200 I] Richard 0 . Duda, Peter E. Hart, and David G. Stork. Pattern Classification . John Wiley & Sons, 2nd edition, 2001.
- [Eskin, 2000] Eleazar Eskin. Detecting errors within a cor- pus using anomaly detection. In Proceedings of the First Conference of the North American Association for Com- putational Linguistics (NAACL-2000), 2000.
- [Frakes and Baeza-Yates, 1992] William B. Frakes and Ri- cardo Baeza-Yates, editors. information Retrieval: Data Structures & Algorithms. Prentice Hall, 1992.
- [Kaynak and Alpaydin, 2000] Cenk Kaynak and Ethem Al- paydin. Multistage cascading of multiple classifiers: One man's noise is another man's data. In Proceedings of the Seventeenth international Conference on Machine Learn- ing (JCML) , pages 455-462, 2000.
- [Nigam et al., 2000] Kamal Nigam, Andrew McCallum, Se- bastian Thrun, and Tom Mitchell. Text classification from labeled and unlabeled examples. Machine Learning, 39(2): 103-134, 2000.
- [Smyth, 1997] Padhraic Smyth. Bounds on the mean classi- fication error rate of multiple experts. Pattern Recognition Letters, 1997.
- [Stork and Lam, 2000] David G . Stork and Chuck P. Lam. Open Mind Animals: Ensuring the quality of data openly contributed over the world wide web. In AAAJ Workshop on Learning with Imbalanced Data Sets, pages 4-9, 2000.
- [Stork, 1999] David G. Stork. The Open Mind Initiative. IEEE intelligent Systems & Their Applications, 14(3): 19- 20, 1999.
- [Szummer and Jaakkola, 2000] Martin Szummer and Tommi Jaakkola. Kernel expansions with unlabeled examples. In Advances in Neural Information Processing Systems (NIPS), 2000.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The overall construction of a modern classification system can be divided into four broad tasks: (1) specifying the clas sifier type, (2) collecting data, (3) training the classifier (i.e., learning), and ( 4) evaluating the classifier (i.e., testing) [Duda et a!., 200 1]. The second stage, data collection, can further be divided into two tasks: gathering samples and labeling them. Recently, the machine learning community has real ized that in many practical cases the most expensive part of the whole design process is the labeling of such samples. For example, there is an enormous number of text docu ments on the internet that can be obtained at very low cost; however, relatively few of these have been labeled - e.g., according to · content topic, language, or style - in a con sistent way that would facilitate training a classifier. Like wise, there are large databases of recorded speech, handwrit ten digits, and printed characters but these databases, too, are either not labeled accurately or not labeled at all [Stork, 1999]. To reduce the labeling expense, many researchers have sought ways to modify training algorithms so as to utilize both labeled and unlabeled data [Blum and Mitchell, 1998; Nigam eta!., 2000]. This approach has shown surprisingly encouraging results, in some cases reducing the number of
David G. Stork
Ricoh Innovations, Inc. 2882 Sand Hill Road, Suite 115 Menlo Park, CA 94025-7022 stork@rii.ricoh.com
labeled samples by a few orders of magnitude [Nigam eta!., 2000].
In order to build up and extend this success in reducing the labeling cost, we turn to the problem of reducing the need for accurately labeled data in the classifier evaluation stage. In fact, most of the experiments for learning with labeled and unlabeled data use much more labels for testing than train ing [Nigam eta!., 2000]. Thus we now need to address the labeling cost for classifier evaluation.
As with many areas of commerce, the general economics of labeling is such that the higher the quality (accuracy) of la beling, the greater the associated cost. This greater cost may be due to greater expertise of the labeler, or the need for mul tiple passes of cross-checking, or both. There is thus an addi tional cost to "clean" or "truth" those data and labels. In some situations, such as marking a text corpus, the labeling task is complicated enough that even experts need several passes to reduce labeling errors [Eskin, 2000]. Furthermore, in some application domains, obtaining accurate labels is simply too cost prohibitive. For example, for some medical diagnostics, the true disease can only be known with expensive or inva sive techniques. Similarly, in remote sensing, one must send measuring instruments to the ground location to obtain the "ground truth," and the transportation cost can be astronom ical. (It is quite literal for remote sensing of other planets [Smyth, 1997].) For both situations in practice, one must rely on the imperfect judgements of experts [Smyth, 1997].
We propose to lower the labeling cost in classifier evalu ation by using cheaper, noisy labels. This paper examines methodologies of estimating the error rate and classifier con fusion matrix using test data with noisy labels. We shall see that even a slight labeling inaccuracy (say, 1 %) can have a significant effect on the error rate estimate when the classi fier performs well. In addition, when data sets used to be small and expensive to collect, it made sense to spend each additional labeling effort to increase label accuracy on that small data set. However, when data sets are large and cheap to collect, it is no longer obvious how one should spend each additional labeling effort. Should one spend it labeling the unlabeled data, or should one spend it increasing the accuracy of already labeled data? We present a preliminary analysis to this question.
2 Preliminaries and notation
Our formulation assumes an object x possessing a true label y E n, where n = { W} ' .. . 'We} is the set of possible states of nature (e.g., category membership) for the object. The ob ject is presented to a labeler, who marks it with a label fj E 0, as his guess of y. The situation that y =j:. fj is call a labeling error (or a mislabeling). The classifier system, on the other hand, is presented with the feature vector x that represents certain aspects of the object, and the classifier outputs a la bel fj(x) E n, as its guess ofy. For notational convenience, we will call the classifier output fj, and its dependence on the feature vector x is implicit. The situation that y =j:. fj is call a classification error (or a misclassification).
The probability of the labeler making mistakes, Pr[y =j:. y] , is called the mislabeling rate. The probability of the classi fier's label being different from the labeler's label, Pr[Y =j:. y], is called the apparent error rate. Our goal is to estimate Pr[y =j:. y], which is called the true error rate. Note that it is possible to have a high apparent error rate even with a per fect classifier (with a true error rate of zero) simply because of a high mislabeling rate. That is, the classifier can classify all test data perfectly, but will often disagree with the test la bels because those labels are incorrect. On the other hand, it is also possible to have a zero apparent error rate even with a high true error rate if the classifier and the labeler make the same kind of mistakes.
The confusion matrix for the human labeler is defined as
which is the identity matrix for a perfect labeler. Similarly the classifier's confusion matrix is defined as
For many two-class cases where one class has a much higher prior probability, the actual error rate is not a good measure of classifer usefulness. For example, in detecting email spams or network intrusions, the undesirable events are so rare that one can easily get an error rate less than l% by classifying all events as "desirable." In those situa tions, then, one may want to compute the entire confusion matrix or metrics such as precision and recall [Frakes and Baeza-Yates, 1992]. We denote w2 as the "rare" class (e.g. , spams or network intrusions). For the classifier, precision is defined as P(y = w2 lfj = w2 ) and recall is defined as P(fj = w2IY = w2), and analogously for the labeler. Note that precision and recall can be derived from the confusion matrix and the class prior probabilities.
3 Obtaining the true error rate
In examining the relationship between true and apparent error rates, we make the constraint that we have a two-class prob lem, that is, 0 = {w1 ,w2 } . Thus {fj =j:. fj U y =j:. fj} => {y =
- y} . Then we can rewrite the apparent error rate as
and thus
The above derivation assumed that Pr[y =j:. y] =j:. 1/2; other wise the noisy labels are meaningless. In practice, Pr[y =j:. y] is always much less than 1/2. More important is the inde pendence assumption that the labeler and the classifier make errors independently, or stated succintly, Pr[y =j:. fj , y =j:. y] = Pr[y =j:. y] Pr[y =j:. y]. That is, knowing that the labeler had made an error on a pattern does not change the probability that the classifier would also make an error, and vice versa. Section 6 will deal with some situations in which the indepen dence assumption does not hold. In the meantime, we argue for this idealization and simplification based on the fact that human and computer generally classify samples using differ ent methodologies, and thus they may not make similar kinds of mistakes.
3.1 Example: Apparent error rate for various true error rates and mislabeling rates
Equation 2 gives us a way to account for noisy labels when calculating the true error rate. A natural question, then, is how important is it to correct for the influence of noisy la bels? Let's consider some classification systems with error rates between 2% and 10% 1 and testing data sets with 1% to 5% incorrect labels. Table 1 shows the apparent error rate for classifiers of different accuracy and testing data of different mislabeling rates. The percentage increase over the true error rate is also shown. For example, even when only 1% of the testing labels are wrong, a classifier with true error rate of 6% will have an apparent error rate 15% higher (at 6.88%). The percentage increase is even more dramatic with noisier labels or more accurate classifiers. A quick rule of thumb is that, when the labels have relatively few errors, the denominator in Eq. 2 is approximately 1.0 and can be ignored.· The mis labeling rate of the testing labels (Pr[y =j:. fj]) is then just an additive component to the true error rate. Continuing the pre vious example, a 1% mislabeling rate for a classifier with true error rate of 6% makes the apparent error rate approximately 7%, when the actual is 6.88%.
4 Noisy labels for estimating true error rate
Above we assumed knowledge of the apparent error rate, Pr[Y =j:. y], but in practice, we must estimate this rate us ing test data. In this section, we analyze the effects of such estimates. Assume we have l objects in the test set, each with a feature vector X;, true but unknown label y;, noisy label y;, and classification y;. Assume further that tuples { (x1, YI , YI, YI), ... , (xL, Yl , Yl, yl)} are independent and identically distributed as (x, y , y, y). The apparent error rate estimate is Pr[Y =j:. y] = t I:~= I I[Y; =j:. y;J, in which I[·] is the indicator function (i .e., ![event] = 1 if event is true and 0 otherwise). An estimate of the true error rate is
1 We note that many classifi ers on the UCI datasets have accuracy within this range [Kaynak and Alpaydin, 2000] .
| True Error Rate, | Mislabeling Rate, Pr[y =j:. y] | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| Pr[y =j:. y] | 1% | 2% | 3% | 4% | 5% | |||||
| 2% | 2.96% | t48% | 3.92% | t96% | 4.88% | tl44% | 5.84% | tl92% | 6.80% | t240% |
| 4% | 4.92% | t23% | 5.84% | t46% | 6.76% | t69% | 7.68% | t92% | 8.60% | tll5% |
| 6% | 6.88% | tl5% | 7.76% | t29% | 8.64% | t44% | 9.52% | t59% | 10.40% | t73% |
| 8% | 8.84% | til% | 9.68% | t21% | 10.52% | t32% | 11.36% | t42% | 12.20% | t53% |
| 10% | 10.80% | t8% | 11.60% | tl6% | 12.40% | t24% | 13.20% | t32% | 14.00% | t40% |
It is straightforward to verify that t'[Pr[Y =j:. y]] = Pr[Y =j:. y] and t'[Pr[y =j:. y]] = Pr[y =j:. y], thus the estimates are unbiased. Intuitively we know that we have less confidence when the error estimates are based on test data with noisy labels. To formalize this intuition, we examine the variance of the true error rate estimate,
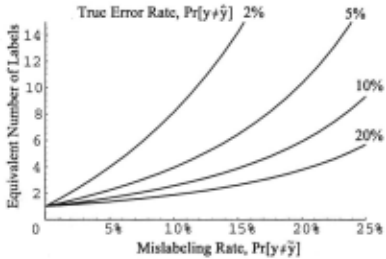
The variance of the error estimate given perfectly labeled data is Pr[y =j:. Y](1 - Pr[y =j:. y])jl. Thus, to get the same vari ance, the ratio of noisy labels to perfect labels is
This ratio will help us understand the economic trade-offs be tween using perfect and noisy labels. Collecting perfect la bels (or collecting noisy labels first and cleaning them) is of ten much more expensive than just collecting noisy labels it self. Therefore it may be economically justified to used noisy labels, as long as one does not need too many more of them.
Unfortunately, applying Eq. 3 requires us to know the true error rate of the classifier, which is exactly what one is trying to estimate. However, we often already have a good idea of a reasonable range for the true error rate. In any case, we exam ine the ratio for a wide range of true error rate and mislabeling rate, and we found the ratio to fall within a relatively narrow range, as shown in Fig. 1. Even for relatively noisy testing data with 10% incorrect labels, unless the classifier is much more accurate (with true error rate of less than 5%), cleaning the testing data to be perfectly labeled increases its value by less than a factor of four. In other words, one needs much less than four such noisy labels to achieve the same effect as one perfect label. Imagine that perfect labels need to be collected from a domain expert, whereas noisy labels can be collected from a non-expert, the high cost of a domain expert can often justify the use of noisy labels.
4.1 Example: Evaluating with many noisy labels or few reliable labels
In many labeling tasks, experts must make multiple passes through samples to ensure accurate labeling [Eskin, 2000]. We now question the wisdom of that policy when the samples are free but labeling cost is a constraint.
Consider a hypothetical labeling situation with two label ers, each paid to look at l samples, and both labelers have an error rate oft. There are two choices in how to use these two labelers. One is to have them look at completely different samples, thus in the end we have a testing set of size 2l and mislabeling rate €. Another choice is to have them look at the exact same samples. Assuming that they make independent labeling errors, and optimistically assume that a sample has a wrong label only if both labelers err, then we have a test ing set of size l and mislabeling rate t: 2 . Which is the better policy?
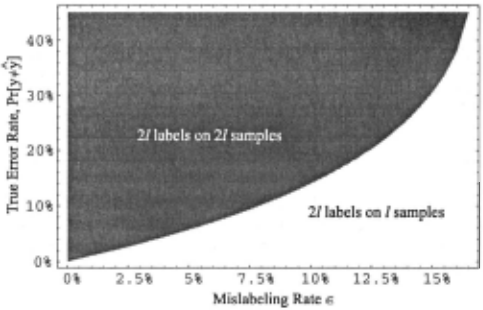
Based on the previous discussion, we can have an unbi ased estimate of the true error rate from either testing set. We then should prefer one that gives us a lower variance estimate. That is, we go with the "2llabels on 2l samples" policy if its variance is lower than the "2llabels on l samples" policy,
Which, after a little algebra, becomes
An interesting observation is that in the realistic range of t: (0 ~ t: < 0.5), the left hand side of Eq. 4 is negative for t: > 0.166, which means that one should always choose the "2l labels on l samples" policy for such inaccurate labelers, and such high mislabeling rate does occur in practice [Smyth, 1997]. For other cases, we have plotted the policy boundary
For fairly accurate labelers (say, t: < 2.5%), Fig. 2 shows that one should prefer the "2l labels on 2l samples" policy unless the classifier error rate is very low. The hint for practi tioners is that time spent cleaning labels is often not as effec tive as time spent labeling extra samples.
5 Obtaining True Confusion Matrix
In evaluating classification systems, we often need to know more than just the error rate. When the cost of different misclassifications (e.g., false positives and false negatives) are not equal, we may want to know the full confusion matrix. In addition, in some domains, such as classifying text or spam, the distribution of classes is highly skewed, and the error rate can be misleadingly low. In those situations, we are more interested in precision and recall statistics, which can be esti mated from the confusion matrix.
| precision/recall | precision/recall (labeler) | ||
|---|---|---|---|
| (classifier) | 99% | 98% | 95% |
| 70% | 69.3% | 68.7% | 66.7% |
| 80% | 79.2% | 78.4% | 76.1% |
| 90% | 89.1% | 88.2% | 85.6% |
| 100% | 99% | 98% | 95% |
We define the joint distribution matrix between labeler and classifier as
which can be estimated from data. Note that unlike our anal ysis of the error rates, it is not necessary to assume two-class problems.
Our goal is to recover the classifer's confusion matrix given the labeler's confusion matrix and the joint distribution matrix between labeler and classifier. If we make the independence assumption that P(fj, YIY) = P(fjly)P(Yiy), then we have the decomposition P(fj, y) = Ly P(y)P(fjly)P(Yiy) . We can rewrite the decomposition in matrix form and solve for the classifier's confusion matrix.
in which Py is defined to be the column vector of prior prob abilities, (P(y = wl), ... , P(y = we) )t .
When Py is not given, it can be derived. To see this, define the probability vector Pii = (P(fj = wl), ... , P(Y = we) )t. It is the case that Pii = P y,yle, in which l eis a column vec tor of c 1 's. It is also the case that Pii = P ii!yPy· Combining those two equations we have
5.1 Example: Precision/recall breakeven points
As mentioned earlier, one benefit of being able to recover the confusion matrix is that one can then work with preci sion and recall measures. We analyze the following system to see some effects of noisy labels on those measures. To reduce the number of variables examined, we only look at precision
'
recall breakeven points, defined as the points where precision and recall are equal. They will simply be denoted as preci sion/recall. For a given Py and precision/recall, the confusion matrix is uniquely determined. Table 2 shows the apparent precision/recall (i.e., P(fj = w2JY = w2) or P(Y = w2JiJ = w2)) for different actual classifier precision/recall and labeler precision/recall. Table 2 assumes Py = ( .9, .l)t , although the values are almost exactly the same for both Py = (.8, .2)t and Py = (.999, .OOl)t.
6 Bounds on true error rate when the classifier and labeler are not independent
In deriving the true error rate (Eq. 2), we have made the as sumption that the labeler and the classifier make errors in dependently. We argue for this assumption because human and computer use different methodologies to classify sam ples. Even for algorithms inspired by human reasoning (e.g., neural networks), they still do not learn human intuition but they do avoid psychological biases. It is even harder to imag ine algorithms based on more abstract models (e.g., support vector machine) to err in similar ways as humans. Further more, in many application domains (e.g., speech recognition), humans label the samples based on a full presentation of the object, whereas the feature vector x used for classification are mathematical notions (e.g., linear vector coefficients) that have little neurological basis. In many other application do mains (e.g. , statistical text classification), assumptions that blatantly violate how human reasons are often made (e.g., as sume words in a text are independently generated, rather than in a grammatical way). Lastly, to make a stronger argument, we can require the training data to be labeled independently from the testing data (or better yet, be perfectly labeled), thus avoiding the possibility that the computer would Jearn biases and other "bad habits" from the training data that would cor relate with labeling errors in the testing data.
However, even with the above reasoning for the indepen dence assumption, it is still conceivable for one to be more conservative and assume some non-negative dependency,
That is, the probability of a classifier misclassifying a sample is higher if the Jabeler has also mislabeled that sample , and vice versa. This can happen, for example, if the training data have been mislabeled in the same way as the testing data, and the classifier has learned to imitate those mislabelings. We have deliberately ignored the case of negative dependency, Pr[y ::j:. f) , y ::j:. y] < Pr[y ::j:. y] Pr[y ::j:. y], as we are hard pressed to find a justification for it in practice.
The non-negative dependency assumption is easily incor porated into Eq. 1 by changing the equal sign to a Jess-than or-equal-to sign. Propagating that change through the deriva tion, we have a lower bound on the true error rate,
The second inequality can be tight if the mislabeling rate is small, as the denominator of the first inequality becomes ap proximately one.
Separately we derive an upper bound for the true error rate.
Note that no assumption is used in deriving the upper bound (not even limiting to two-class problems). One can easily verify that the bound is exact when the mislabeling rate is zero . The bound is also exact when the apparent error rate is zero, such that the true error rate is equal to the mislabeling rate. Thus with the looser assumption of non-negative dependency, the true error rate is in the range ofPr[f) ::j:. y] ± Pr[y ::j:. y].
6.1 Example: Simulation of non-negative dependency between classifier and labeler
In the above derivation, the lower bound is achieved ex actly when the mislabeling rate is small and the indepen dence assumption is true. We examine how tight the upper bound is by simulation. We have taken pairs of classes from UCI's Opt-Digit dataset, which is a handwritten digit recog nition dataset, and trained both a naive Bayes classifier and a nearest-neighbor classifier [Duda eta/., 2001] on the training set of each pair. The nearest-neighbor classifier is then used to simulate a labeler and labeled the testing set. The naive Bayes classifier is the classifier under evaluation. Since we have the actual labels for the testing set, both the mislabel ing rate (of the nearest-neighbor "labeler") and the true error rate (of the naive Bayes classifier) can be determined. The output of the naive Bayes classifier and the nearest-neighbor "labeler"are compared to determine the apparent error rate.
We have chosen the Opt-Digit dataset and the nearest neighbor algorithm because we know that this combination can give very low error rate [Kaynak and Alpaydin, 2000], thus closely matching the accuracy of many human labelers. In fact, for most pairs of classes, the nearest-neighbor algo rithm has zero error. The Opt-Digit dataset is also interesting because the handwritten digit recognition task is a classical example in which much human labeling effort has been ap plied. The naive Bayes classifier is chosen because it is a popular classifier and is sufficiently different from nearest neighbor to give interesting results.
Table 3 shows the results for some pairs of classes where the nearest-neighbor "labeler" has non-zero error. Note that an insignificant positive dependence between the naive Bayes classifier and the nearest-neighbor "labeler" should be ex pected since they both are trained from the same dataset, use the same features, and assume independence ofthose features (explicitly in naive Bayes and implicitly in nearest-neighbor through its distance metric), even though they are different in other aspects (e.g., naive Bayes is generative while nearest neighbor classifier is discriminative). The naive Bayes classi fier's true error rate is almost exactly the upper bound for the pairs ( 1 ,2) and ( 4,5), but it is much closer to the apparent error rate for the pairs (7 ,8) and (8,9). The simulation thus shows the upper bound to be tight in some non-trivial situations.
7 Discussion and Future Work
When designing classification systems there are frequently parameters that are not learned automatically from the training data. Some examples are the number of hidden units in a feedforward neural network, the number k in a k-nearest neighbor classifier, and the window width in a Parzen window classifier [Duda eta!. , 2001]. Validation is one technique to estimate those parameters. In validation, one conceptually creates several classifiers with different values of the param eter and train them with the same training set. The trained classifiers are evaluated on the validation data set, and the best classifier is chosen. Our results for testing with noisy la bels is directly applicable to validation. In fact, validation is not concerned with the actual value of the true error rates, but just their ordering. Therefore the apparent error rate Pr[Y ::j; y] can work just as well, as long as the mislabeling rate Pr[y ::j; y] is less than 0.5.
| classes to discriminate (w1 - w2) | ||||
|---|---|---|---|---|
| 1-2 | 4-5 | 7-8 | 8-9 | |
| Upper bound (apparent error rate+ mislabeling rate) | 9.20% | 1.11% | 2.27% | 6.77% |
| True error rate (Naive Bayes) | 9.19% | 1.10% | 1.70% | 5.65% |
| Apparent error rate | 8.64% | 0.83% | 1.70% | 5.08% |
| Lower bound (apparent error rate- mislabeling rate) | 8.08% | 0.55% | 1.13% | 3.39% |
| Mislabeling rate (Nearest Neighbor) | 0.56% | 0.28% | 0.57% | 1.69% |
In a world where (unlabeled) data is cheap, noisy labels are easily obtained (e.g., the Open Mind Initiative [Stork, 1999; Stork and Lam, 2000]), but perfect labels are expensive, the findings in this paper allow one to confidently use noisy labels for testing and validating. An obvious area for future work is to use noisy labels for training as well. Although some works do allow for training with noisy labels, this has not been an active research area [Szummer and Jaakkola, 2000].
So far in our derivations we have assume either knowledge of the mislabeling rate Pr[y ::j; y] or the labeler's confusion matrix P ii iY. In practice those information must be estimated and be treated as random. The effects of such estimates and the cost/benefit analysis of obtaining more accurate estimates are unknown. We hope to investigate them in the future.
8 Conclusion
Traditionally test data have been assumed to be perfectly la beled. Increasingly this assumption is becoming a burden. We advocate the use of noisy labels as a cheaper alternative. We have shown that, under the assumption in which the Ia beier and the classifier make mistakes independently, the true error rate and true confusion matrix can be derived exactly. We have also examined the number of noisy labels to achieve the equivalent estimation confidence as one perfect label, and we found that number to be less than four in many practi cal situations. Furthermore, if we loosen the independence assumption to the non-negative dependence assumption, the true error rate can be bounded to be between the apparent er ror rate plus or minus the mislabeling rate.
@inproceedings{ijcai2003p76,
  title     = {Evaluating Classifiers by Means of Test Data with Noisy Labels},
  author    = {Lam, Chuck P. and Stork, David G.},
  booktitle = {Proceedings of the Eighteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-03}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Georg Gottlob and Toby Walsh},
  pages     = {513--517},
  year      = {2003},
  url       = {https://ijcai.org/proceedings/2003/76},
}
TY - CPAPER TI - Evaluating Classifiers by Means of Test Data with Noisy Labels AU - Lam, Chuck P. AU - Stork, David G. T2 - Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence, IJCAI-03 PB - International Joint Conferences on Artificial Intelligence PY - 2003 SP - 513 EP - 517 UR - https://ijcai.org/proceedings/2003/76 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





