
PECHC: Robust Tactile Grasping Stabilization in Vision-Denied Peripersonal Space
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. AI and Robotics. Pages 7549-7557.
https://doi.org/10.24963/ijcai.2026/839
© 2026 International Joint Conferences on Artificial Intelligence
Keywords
- Learning to understand, generalize, and explain actions: Learning from language, corrections, preferences, and sparse feedback
- Robot control, planning, and execution with guarantees: Safe and robust control under uncertainty
- AIR: Generative AI, robotic foundation models, and reinforcement learning
- AIR: Robot control, planning, and execution with guarantees
Abstract
In the final "Last-Centimeter" phase of manipulation, where visual occlusion or calibration errors render vision unreliable, robots often suffer high failure rates due to local pose uncertainty and simulation dynamics deviations. To address these issues, this paper proposes the PECHC (Physics-Evolving Cascade Constraint and Human-Correction) algorithm. To rigorously isolate the contribution of tactile feedback in multi-finger coordination, we adopt a decoupled control strategy that focuses on grasp stabilization within the hand's workspace, acting as a fail-safe reflex. The core of our approach is Hybrid Correction Imitation Learning (HCIL), which establishes a "failure-triggered" human-machine mechanism to efficiently resolve the "model gap" via sparse expert corrections. To ensure sample efficiency and baseline performance, we introduce two supporting modules: Cascaded Constraint Scheduling (CCS) addresses the "geometric gap" by enforcing physically plausible behavioral constraints (geometric approach, force closure, and dynamic stability), while Temporal Heterogeneous Distillation (THED) resolves the "physical gap" by enabling implicit system identification from tactile history. Experiments demonstrate that PECHC achieves a 97.3% real-robot success rate on 150 objects from the Visual Dexterity Dataset under fully autonomous testing, where one object is used for one-time HCIL calibration and the remaining 149 objects are evaluated without further intervention. Compared to a standard Sim-to-Real reinforcement learning baseline (Vanilla PPO with Domain Randomization), PECHC delivers a significant performance improvement (+42.8%) and exhibits human-like force modulation capabilities for fragile objects.
- [Andrychowicz et al., 2020] Marcin Andrychowicz, Bowen Baker, Maciek Chociej, Rafal Jozefowicz, Bob McGrew, Jakub Pachocki, Arthur Petron, Matthias Plappert, Glenn Powell, Alex Ray, et al. Learning dexterous in-hand ma- nipulation. The International Journal of Robotics Re- search, 39(1):3-20, 2020.
- [Billard and Kragic, 2019] Aude Billard and Danica Kragic. Trends and challenges in robot manipulation. Science, 364(6446):eaat8414, 2019.
- [Chari et al., 2024] Kartik Chari, Niklas Kueper, Su Kyoung Kim, Frank Kirchner, and Elsa Andrea. Inter-hri compe- tition: intrinsic error evaluation during human-robot inter- action. In Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, pages 8623- 8626, 2024. IJCAI
- [Chen et al., 2023] Tao Chen, Megha Tippur, Siyang Wu, Vikash Kumar, Edward Adelson, and Pulkit Agrawal. Vi- sual dexterity: In-hand reorientation of novel and complex object shapes. Science Robotics, 8(84):eadc9244, 2023.
- [Chen et al., 2025a] Jiayi Chen, Yubin Ke, Lin Peng, and He Wang. Dexonomy: Synthesizing all dexterous grasp types in a grasp taxonomy. arXiv preprint arXiv:2504.18829, 2025.
- [Chen et al., 2025b] Zerui Chen, Shizhe Chen, Etienne Ar- laud, Ivan Laptev, and Cordelia Schmid. Vividex: Learning vision-based dexterous manipulation from hu- man videos. In 2025 IEEE International Conference on Robotics and Automation (ICRA), pages 3336-3343. IEEE, 2025.
- [Church et al., 2022] Alex Church, John Lloyd, Nathan F Lepora, et al. Tactile sim-to-real policy transfer via real-to- sim image translation. In Conference on Robot Learning, pages 1645-1654. PMLR, 2022.
- [Guo et al., 2025] Ce Guo, Xieyuanli Chen, Zhiwen Zeng, Zirui Guo, Yihong Li, Haoran Xiao, Dewen Hu, and Huimin Lu. Grasp like humans: Learning generalizable multi-fingered grasping from human proprioceptive senso- rimotor integration. IEEE Transactions on Robotics, 2025.
- [Guzey et al., 2023] Irmak Guzey, Ben Evans, Soumith Chintala, and Lerrel Pinto. Dexterity from touch: Self- supervised pre-training of tactile representations with robotic play. In Proceedings of the Conference on Robot Learning (CoRL), pages 3142-3166. PMLR, 2023.
- [Hang et al., 2024] Jinglue Hang, Xiangbo Lin, Tianqiang Zhu, Xuanheng Li, Rina Wu, Xiaohong Ma, and Yi Sun. Dexfuncgrasp: A robotic dexterous functional grasp dataset constructed from a cost-effective real-simulation annotation system. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 10306-10313, 2024.
- [Hu et al., 2025] Wenbin Hu, Bidan Huang, Wang Wei Lee, Sicheng Yang, Yu Zheng, and Zhibin Li. Dexterous in- hand manipulation of slender cylindrical objects through deep reinforcement learning with tactile sensing. Robotics and Autonomous Systems, 186:104904, 2025.
- [Jia et al., 2025] Peida Jia, Xuanheng Li, Tianqiang Zhu, Rina Wu, Xiangbo Lin, and Yi Sun. Multi-fingered hand grasps with visuo-tactile fusion via multi-agent deep rein- forcement learning. In Proceedings of the AAAI Confer- ence on Artificial Intelligence, volume 39, pages 14594- 14601, 2025.
- [Jiang et al., 2024] Yunfan Jiang, Chen Wang, Ruohan Zhang, Jiajun Wu, and Li Fei-Fei. TRANSIC: Sim-to- real policy transfer by learning from online correction. In Proceedings of the Conference on Robot Learning (CoRL), pages 1691-1729. PMLR, 2024.
- [Johannink et al., 2019] Tobias Johannink, Shikhar Bahl, Ashvin Nair, Jianlan Luo, Avinash Kumar, Matthias Loskyll, Juan Aparicio Ojea, Eugen Solowjow, and Sergey Levine. Residual reinforcement learning for robot control. In 2019 international conference on robotics and automa- tion (ICRA), pages 6023-6029. IEEE, 2019.
- [Kang et al., 2025] Taewoong Kang, Joonyoung Kim, Se- unghwa Oh, Woosung Lim, Junwoo Lee, Seung-Joon Yi, and Jungwon Seo. Dexterous ungrasping manipulation in three dimensions. In 2025 IEEE International Conference on Robotics and Automation (ICRA), pages 14030-14036. IEEE, 2025.
- [Kojima et al., 2025] Takeshi Kojima, Yaonan Zhu, Yusuke Iwasawa, Toshinori Kitamura, Gang Yan, Shu Morikuni, Ryosuke Takanami, Alfredo Solano, Tatsuya Matsushima, Akiko Murakami, and Yutaka Matsuo. A comprehensive survey on physical risk control in the era of foundation model-enabled robotics. In Proceedings of the Thirty- Fourth International Joint Conference on Artificial Intelli- gence (IJCAI-25), pages 10517-10527. International Joint Conferences on Artificial Intelligence Organization, 2025. IJCAI
- [Kumar et al., 2021] Ashish Kumar, Zipeng Fu, Deepak Pathak, and Jitendra Malik. Rapid motor adaptation for legged robots. In Proceedings of the Conference on Robot Learning (CoRL), pages 1342-1352. PMLR, 2021.
- [Li et al., 2023] Haoming Li, Xinzhuo Lin, Yang Zhou, Xi- ang Li, Yuchi Huo, Jiming Chen, and Qi Ye. Con- tact2grasp: 3d grasp synthesis via hand-object contact constraint. In Proceedings of the Thirty-Second Interna- tional Joint Conference on Artificial Intelligence (IJCAI- 23), pages 1053-1061. International Joint Conferences on Artificial Intelligence Organization, 2023. IJCAI
- [Lin et al., 2022] Yijiong Lin, John Lloyd, Alex Church, and Nathan F Lepora. Tactile gym 2.0: Sim-to-real deep reinforcement learning for comparing low-cost high- resolution robot touch. IEEE Robotics and Automation Letters, 7(4):10754-10761, 2022.
- [Lin et al., 2025] Pei Lin, Yuzhe Huang, Wanlin Li, Jianpeng Ma, Chenxi Xiao, and Ziyuan Jiao. Pp-tac: Paper picking using tactile feedback in dexterous robotic hands. arXiv preprint arXiv:2504.16649, 2025.
- [Liu et al., 2024] Yumeng Liu, Yaxun Yang, Youzhuo Wang, Xiaofei Wu, Jiamin Wang, Yichen Yao, Soeren Schwert- feger, Sibei Yang, Wenping Wang, Jingyi Yu, Xuming He, and Yuexin Ma. Realdex: Towards human-like grasping for robotic dexterous hand. In Proceedings of the Thirty- Third International Joint Conference on Artificial Intel- ligence (IJCAI-24), pages 6859-6867. International Joint Conferences on Artificial Intelligence Organization, 2024. IJCAI
- [Losey et al., 2020] Dylan P Losey, Krishnan Srinivasan, Ajay Mandlekar, Animesh Garg, and Dorsa Sadigh. Con- trolling assistive robots with learned latent actions. In 2020 IEEE International Conference on Robotics and Automa- tion (ICRA), pages 378-384. IEEE, 2020.
- [Lum et al., 2024] Tyler Ga Wei Lum, Martin Matak, Vik- tor Makoviychuk, Ankur Handa, Arthur Allshire, Tucker Hermans, Nathan D. Ratliff, and Karl Van Wyk. DextrAH- G: Pixels-to-action dexterous arm-hand grasping with geo- metric fabrics. In Proceedings of the Conference on Robot Learning (CoRL), pages 3182-3211. PMLR, 2024.
- [Mandlekar et al., 2022] Ajay Mandlekar, Danfei Xu, Josiah Wong, Soroush Nasiriany, Chen Wang, Rohun Kulka- rni, Li Fei-Fei, Silvio Savarese, Yuke Zhu, and Roberto Martín-Martín. What matters in learning from offline hu- man demonstrations for robot manipulation. In Proceed- ings of the 5th Conference on Robot Learning (CoRL), pages 3135-3166. PMLR, 2022.
- [Niu et al., 2024] Haoyi Niu, Jianming Hu, Guyue Zhou, and Xianyuan Zhan. A comprehensive survey of cross-domain policy transfer for embodied agents. In Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence (IJCAI-24), pages 8197-8206. International Joint Conferences on Artificial Intelligence Organization, 2024. IJCAI
- [Singh et al., 2024] Ritvik Singh, Arthur Allshire, Ankur Handa, Nathan Ratliff, and Karl Van Wyk. Dextrah- rgb: Visuomotor policies to grasp anything with dexterous hands. arXiv preprint arXiv:2412.01791, 2024.
- [Suresh et al., 2023] Sudharshan Suresh, Zilin Si, Stuart An- derson, Michael Kaess, and Mustafa Mukadam. Midas- touch: Monte-carlo inference over distributions across sliding touch. In Conference on Robot Learning, pages 319-331. PMLR, 2023.
- [Thananjeyan et al., 2021] Brijen Thananjeyan, Ashwin Bal- akrishna, Suraj Nair, Michael Luo, Krishnan Srinivasan, Minho Hwang, Joseph E Gonzalez, Julian Ibarz, Chelsea Finn, and Ken Goldberg. Recovery rl: Safe reinforcement learning with learned recovery zones. IEEE Robotics and Automation Letters, 6(3):4915-4922, 2021.
- [Xue et al., 2023] Wanqi Xue, Bo An, Shuicheng Yan, and Zhongwen Xu. Reinforcement learning from diverse hu- man preferences. arXiv preprint arXiv:2301.11774, 2023. IJCAI
- [Yang et al., 2024] Libing Yang, Yang Li, and Long Chen. Clothppo: A proximal policy optimization enhanc- ing framework for robotic cloth manipulation with observation-aligned action spaces. In Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence (IJCAI-24), pages 6895-6903. International Joint Conferences on Artificial Intelligence Organization, 2024. IJCAI
- [Yuan et al., 2025] Haoqi Yuan, Ziye Huang, Ye Wang, Chuan Mao, Chaoyi Xu, and Zongqing Lu. Demograsp: Universal dexterous grasping from a single demonstration. arXiv preprint arXiv:2509.22149, 2025.
- [Zhao et al., 2024] Zhou Zhao, Wenhao He, and Zhenyu Lu. Tactile-based grasping stability prediction based on hu- man grasp demonstration for robot manipulation. IEEE Robotics and Automation Letters, 9(3):2646-2653, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Robust dexterous manipulation is a milestone in embodied intelligence. While vision-based methods excel [Billard and Kragic, 2019; Andrychowicz et al., 2020; Yang et al., 2024], they fail in extreme scenarios like occlusion, darkness, or transparent surfaces. In such vision-denied scenarios, tactile feedback serves as the last line of defense, providing the most direct and authentic physical observations of contact states [Liu et al., 2024; Li et al., 2023; Jia et al., 2025; Lin et al., 2025].
∗Corresponding author.
Thus, achieving tactile-driven grasp stabilization serves as a robust "Last-Centimeter" reflex policy [Kang et al., 2025]. Rather than replacing global navigation, it complements vision by handling occlusion-induced localization errors within the peripersonal workspace, where tactile feedback becomes the sole reliable modality [Chen et al., 2025b].
In recent years, Sim-to-Real techniques based on reinforcement learning (RL) have shown great potential in dexterous manipulation [Andrychowicz et al., 2020; Kumar et al., 2021].
However, Sim-to-Real for tactile-based systems faces more severe challenges than vision-the "Tactile Reality Gap", which encompasses two core challenges: 1) Force Adaptation: Real-world properties (e.g., mass, friction) are invisible and variable, risking slippage or damage; 2) Simulation Fidelity: Simulators struggle to model complex contact dynamics (e.g., soft-body deformation), causing policy failure due to distribution shifts. These two factors collectively make policies trained solely in simulation fragile and poorly adaptable when facing complex interactions in the real world [Niu et al., 2024; Chen et al., 2025a].
To address the above core challenges, this paper proposes the PECHC algorithm as an integrated solution to bridge the gaps between simulation and reality.
To bridge the physical gap, we draw inspiration from the privileged distillation paradigm [Kumar et al., 2021]. However, directly applying such methods to blind grasping faces a unique "Geometric Gap": unlike locomotion, a grasper cannot adapt to dynamics if it fails to establish contact due to pose uncertainty. Therefore, PECHC integrates Cascaded Constraint Scheduling (CCS) to first guide geometric exploration, serving as a prerequisite for the subsequent dynamic adaptation (THED). We observe that the Tactile Reality Gap comprises two distinct components: 1) Systemic Bias (e.g., global sensor sensitivity, simulation friction scaling offsets), which is consistent across tasks, and 2) Instancelevel Dynamics (e.g., specific object mass, compliance). While pure Domain Randomization struggles with the former, blindly adapting to everything risks overfitting. Abandoning the traditional full-time demonstration paradigm, Hybrid Correction Imitation Learning (HCIL) innovatively designs a failure-triggered human-machine collaborative mechanism. When the policy fails to adjust grasp force due to object uncertainty (e.g., slippage) or exhibits abnormal actions due to model deviations during real-robot execution, human experts intervene to provide sparse residual corrections. This mechanism not only directly corrects model errors (the model gap) but, more importantly, injects expert physical intuition for handling uncertainty into the policy, correcting systemic simulation biases via sparse human intervention. This calibration aligns the fundamental physics engine parameters, allowing the THED module to handle instance-level object variations (mass, friction) through online inference without further human guidance.
To maximize the correction efficiency of HCIL and ensure the policy possesses strong initial capabilities, we design two key supporting modules:
- Cascaded Constraint Scheduling (CCS) mitigates the geometric gap by decomposing grasping into geometric approach, force closure, and dynamic stability. Physical constraints guide the policy toward plausible tactile primitives and provide a reliable baseline for human corrections.
- Temporal Heterogeneous Distillation (THED) bridges the physical gap by learning to infer privileged physical parameters, such as friction and mass, from tactile history. This enables adaptive force modulation under object uncertainty.
Unlike blind manipulation approaches targeting full-scene navigation or object search, our work strictly focuses on grasping stability within the end-effector's workspace. PECHC specifically addresses the most intractable challenge in dexterous manipulation: dynamic force adaptation after contact establishment.
Scope and Assumption: It is important to clarify that our work focuses on grasp stabilization rather than global object search. We assume a coarse visual system or heuristics has guided the wrist to the object's vicinity (peripersonal space). PECHC addresses the critical challenge that follows: establishing a stable grasp under local pose uncertainty and dynamic mismatch, where vision is no longer reliable.
2 RelatedWork
2.1 Tactile and Proprioception-Based Dexterous Grasping
Blind manipulation relying on tactile and proprioceptive feedback offers unique advantages in vision-denied or highprecision force control scenarios. The core challenge lies in deriving adaptive policies from sparse, noisy signals. Suresh et al. [Suresh et al., 2023] addressed this via a Monte Carlo inference framework to recover object geometry from sliding feedback. OpenAI's Dactyl achieved blind object rotation using large-scale RL and domain randomization [Andrychowicz et al., 2020], though this approach requires immense computational resources. To mitigate reliance on randomization, Lin et al. [Lin et al., 2022] developed Tactile Gym 2.0, a high-fidelity simulator that narrows the sim-to-real gap. Regarding feature extraction, Hu et al. [Hu et al., 2025] utilized low-dimensional features for pose tracking, while Guzey et al. [Guzey et al., 2023] introduced self-supervised learning to derive general representations from interaction data. For stability prediction, Zhao et al. [Zhao et al., 2024] modeled spatiotemporal correlations using "pseudo-3D" tactile images and NDConv. Guo et al. [Guo et al., 2025] employed graph convolutional networks to enable skill transfer and verify tactile grasping of soft, slippery objects. Furthermore, Church et al. [Church et al., 2022] achieved millimeter-level tactile servoing via Real-to-Sim optimization. Despite these advances, existing works still lack effective online adaptation mechanisms for significant physical dynamic discrepancies between simulation and reality [Chari et al., 2024; Hang et al., 2024].
2.2 Human-Machine Interaction Correction and Policy Adaptation
Introducing Human-in-the-Loop (HITL) is effective for bridging sim-to-real gaps. Early methods like Behavior Cloning (BC) relied on full-time teleoperation, which is constrained by data quality and struggles to correct minor deviations [Mandlekar et al., 2022]. Recently, residual learning has gained attention: Johannink et al. [Johannink et al., 2019] compensated for model errors via learned residual actions, while Losey et al. [Losey et al., 2020] utilized physical contact for real-time correction. In vision domains, TRANSIC [Jiang et al., 2024] adapts via online expert corrections but relies on visual feedback for intervention timing, making it infeasible for Blind Grasp Stabilization. Meanwhile, Xue et al. [Xue et al., 2023] focused on preference-based task optimization rather than physical dynamics adaptation. Distinct from these, our Hybrid Correction Imitation Learning (HCIL) is tailored for tactile Blind Grasp Stabilization. Inspired by "Recovery Zones" [Thananjeyan et al., 2021], we replace visual judgment with an automatic failure-triggered mechanism based on Tactile Safety Thresholds. Expert intervention is requested only upon detecting anomalies (e.g., a slip). This on-demand correction significantly reduces annotation burden and guides the policy to focus on learning real-world physical dynamics missed by simulators, facilitating efficient transfer [Kojima et al., 2025].
3 Method
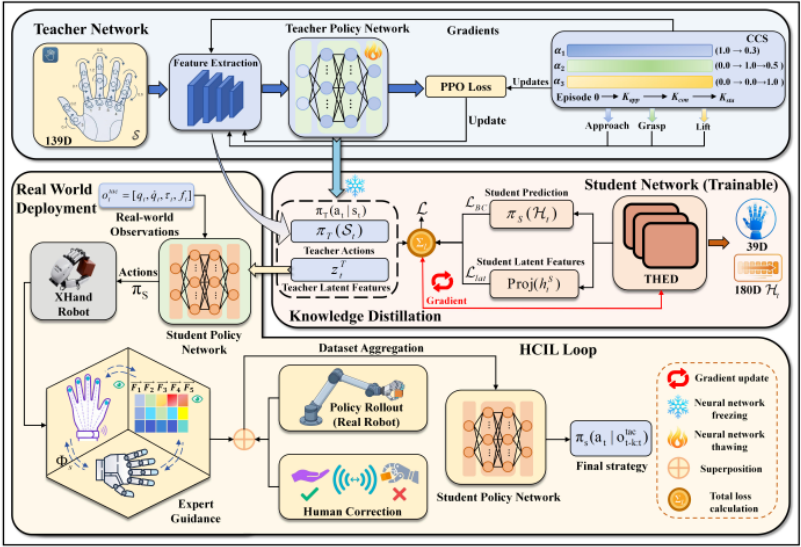
The PECHC algorithm aims to solve the problem of general dexterous grasping relying solely on sparse tactile feedback in unstructured environments. As shown in Figure 1, the algorithm consists of three progressive stages: first, learning physically plausible grasp primitives in fully observable simulations via Cascaded Constraint Scheduling (CCS); second, compressing the teacher's privileged physical information into tactile history representations through Temporal Heterogeneous Distillation (THED); finally, correcting long-tail dynamic errors not covered by simulations via human-machine interaction (HCIL).
3.1 Preliminaries
We model the problem as a Partially Observable Markov Decision Process (POMDP), defined as M = (S, Otac , A, T , R, γ).
Privileged State Space S ∈ R139 : st = [qt, ˙qt ∈ R12 , pobj ∈ R7 , vobj ∈ R6 , ϕphy], where qt, ˙qt are joint positions/velocities (12-DoF), pobj is object pose (3D position + quaternion), vobj is velocity (linear+angular), and ϕphy ∈ R102 contains contact geometry, physical properties (friction µ, mass m), and fine-grained contact states.
Tactile Observation Space Otac ∈ R39 : otac t = [qt, ˙qt ∈ R12 , f tip ∈ R15 ], where f tip represents 5-fingertip 3D forces. Joint torques τ are computed via inverse dynamics. The action space A ∈ R12 consists of joint position increments. Goal: learn πS(at|otac t-k:t ) maximizing E[∑ γ t rt] inMreal.
3.2 Stage I: Constraint-Aware Teacher Learning via CCS
(Resolving the geometric gap) In the simulation stage (Msim), we train the teacher policy πT (at|st) using privileged information. To address low exploration efficiency in high-dimensional action spaces and "non-physical violent grasping", we design the Cascaded Constraint Scheduling (CCS) mechanism. CCS models the grasping task as a physically constrained optimization problem, dynamically adjusting the reward function structure through state machine logic. Unlike traditional scalar rewards, CCS decouples the grasping process into three hierarchical constraints K ∈ {Kapp,Kcon,Ksta} and guides the policy to focus on specific physical sub-goals at different stages via dynamic weights αi.
(a) Geometric Approach Constraint (Kapp): Aims to guide the palm to envelope the object with a reasonable configuration. The reward function rapp is designed to guide the hand configuration without penalizing contact force, avoiding policy shrinking (fear of contact):
Here, dmin is the fingertip-object distance, E(q) aligns palm orientation, and Icontact indicates contact; λd, λe are scaling coefficients. α1 is high in the early training stage and gradually decreases as the stage progresses (as shown in the upper right of Figure 1), preventing the policy from overfitting to geometric positions while ignoring force control. Note that dmin and object pose pobj are privileged information available only during simulation training. The Student Policy πS does not have access to these states and must implicitly infer contact geometry solely from proprioception and tactile history during the approach phase.
(b) Force Closure and Balance Constraint (Kcon): After geometric contact is established, the goal shifts to achieving mechanically stable grasping. We introduce the minimum singular value σmin(G) of the grasp matrix G as a force closure quality metric and penalize the variance Var(∥ftip∥) of fingertip force distribution to induce human-like compliant multi-finger collaboration instead of relying on single-finger heavy squeezing.
Here, σmin(G) quantifies force closure quality, Var(∥ftip∥) ensures load distribution among fingers, and the last term prevents motor overload.
The coefficients and thresholds in CCS are physically grounded rather than arbitrarily tuned. For instance, the safety threshold fmax is derived from the sensor's saturation limit, and the geometric weights evolve based on the kinematic workspace of the XHand. We observed that this physically-constrained reward formulation is robust to minor hyperparameter variations compared to pure scalar reward shaping.
(c) Dynamic Stability Constraint (Ksta): During the lifting stage, the object must maintain a stable state when disturbed. The policy must keep the object's linear velocity ∥vo∥ and angular velocity ∥ωo∥ below thresholds while the object is subjected to random external force disturbances or being lifted (h > htgt).
This term rewards lifting the object to the target height htgt while penalizing jitter in linear velocity vo and angular velocity ωo during lifting. The weight vector α = [α1, α2, α3] dynamically evolves with learning steps. In the early stage, α1 dominates to quickly explore contact states; in the later stage, α2, α3 dominate to optimize the force control policy, ultimately learning the teacher policy πT (at|st). State switching follows an irreversible logic (unless the task fails and resets), and the policy strictly adheres to the physical causal chain of "geometric approach → mechanical balance → dynamic stability". The core role of CCS is to use "contact itself" as a geometric sensor in the absence of visual priors, guiding the policy to smoothly transition from "exploratory contact" to "force closure establishment".
3.3 Stage II: Temporal Heterogeneous Distillation (THED)
(Resolving the physical gap) Building upon the success of Rapid Motor Adaptation [Kumar et al., 2021] in locomotion, THED adopts an asymmetric actor-critic structure. While [Kumar et al., 2021] focuses on body dynamics, THED is specifically tailored to reconstruct contact parameters (e.g., friction, compliance) from sparse tactile history.
To transfer the teacher policy πT relying on privileged information st to the student policy πS with only otac t , this paper proposes Temporal Heterogeneous Distillation (THED).
Its core idea is to implicitly reconstruct environmental physical parameters from tactile temporal history (e.g., sliding history implies friction coefficient information). We explicitly design the student policy as a decoupled tactile reflex layer. In real-robot deployment, the wrist trajectory is handled by a separate kinematic planner, while the student policy assumes full authority over the finger articulations to stabilize the grasp. This decoupling strategy isolates the high-frequency contact stabilization problem from the low-frequency global transport, allowing PECHC to serve as a plug-and-play reflex module compatible with various arm planners.
The teacher encodes st into features zTt via an MLP. The student processes tactile history Ht = {(otac k , ak-1)}tk=t-H using an LSTM to extract hSt , followed by an action MLP. The distillation objective includes two loss functions:
(a) Behavior Cloning Loss (LBC): Collect demonstration trajectories Ddemo in simulation via the teacher policy, forcing the student action distribution to fit the teacher's actions:
(b) Latent Physical Representation Alignment (Llat): Force the projected LSTM latent state hSt of the student network to approximate the teacher's privileged feature zTt . This compels the student network to decouple key physical information from tactile history (System Identification). By minimizing the latent Llat, we force the recurrent latent state of the student network to reconstruct the teacher's beliefs about explicit physical parameters. This process goes beyond behavior cloning; it endows the student with online system identification capabilities, enabling it to infer invisible environmental dynamics (e.g., object mass distribution) from contact force history:
The total optimization objective is L = LBC + βLlat, where β is a balance coefficient.
3.4 Stage III: Hybrid Correction Imitation Learning (HCIL)
(Resolving the model gap) Although simulation training endows the policy with basic capabilities, complex dynamic characteristics in the real environment (e.g., cable pulling, nonlinear friction) may still lead to failures. We design a Hybrid Correction Imitation Learning (HCIL) system, introducing human experts as correctors. Our HCIL proceeds in two stages: (1) Adaptation: at initial deployment, human experts intervene upon failure detection to provide correction data; (2) Autonomous deployment: the fine-tuned π∗S operates independently on unseen objects without further human intervention.
We empirically observe that a significant portion of the Sim-to-Real gap manifests as systematic sensor-motor biases (e.g., global friction scaling, sensor thresholds) rather than purely object-specific dynamics. Therefore, HCIL utilizes a representative object to perform system-level alignment. Our experiments suggest that calibrating these funda-
Algorithm 1 PECHC Training Pipeline
Require: Simulator Msim, Real Robot Mreal, Expert Human E
Ensure: Robust Tactile Policy π∗S
- 1: ▷ Stage I: Teacher Training
- 2: Initialize πT , CCS Rewards {rapp, rcon, rsta}
- 3: while not converged do
- 4: Collect trajectories ζ ∼ πT inMsim
- 5: Update πT using PPOwith curriculum state K(s)
- 6: end while
7:
- 8: ▷ Stage II: Distillation
- 9: Collect dataset Dsim = {(Ht, aTt , zTt )} using πT
- 10: Initialize πS (LSTM-based)
- 11: while not converged do
- 12: Sample batch B ∼ Dsim
- 13: Update πS by minimizing LBC +βLlat
- 14: end while
15:
- 16: ▷ Stage III: Real-World Adaptation (HCIL)
- 17: Dmix ←∅
- 18: for iteration k = 1 to N do
- 19: Rollout πS inMreal
- 20: if Failure Detected (∥˙ f∥ > ˙ fslip or τ > τlimit) then
- 21: Expert E intervenes, collect correction ζexp
- 22: Dmix ←Dmix ∪ ζexp
- 23: else
- 24: Store successful trajectory ζself
- 25: Dmix ←Dmix ∪ Sample(ζself)
- 26: end if
- 27: Fine-tune πS on Dmix
- 28: end for
- 29: return π∗S
RMA [Kumar et al., 2021]. This baseline utilizes the identical LSTM architecture and domain randomization ranges as PECHC but lacks the CCS, THED, and HCIL components. By maintaining architectural parity, we isolate the performance improvements derived specifically from our proposed physics-evolving constraints and human-correction framework rather than general backbone capacity.
mental physics engine offsets significantly improves the policy's zero-shot generalization to unseen objects, reducing the need for per-instance fine-tuning.
Unlike full-time teleoperation, HCIL adopts a "failuretriggered" mechanism via tactile safety thresholds Φs = {fmax = 15N, ˙ fslip = 50N/s, τlimit = 1.5Nm}, derived from hardware specs (sensor saturation, motor rating) rather than object-specific tuning. When ∥˙ f∥ > ˙ fslip (slip detection) or τ > τlimit (overload), the robot pauses and requests expert correction via Manus Pro.
To prevent catastrophic forgetting, we construct a mixed dataset Dmix:
where Dexp is human correction data, Dpolicy is selfexploration data, and ρ = 0.3 (30% self-exploration + 70% human corrections). By fine-tuning πS on Dmix, the policy can quickly adapt to the physical distribution of the real world while retaining the general force control primitives learned in the simulation stage.
The complete algorithm flow is shown in Algorithm 1.
4 Experiments
4.1 Experimental Setup and Baseline Description
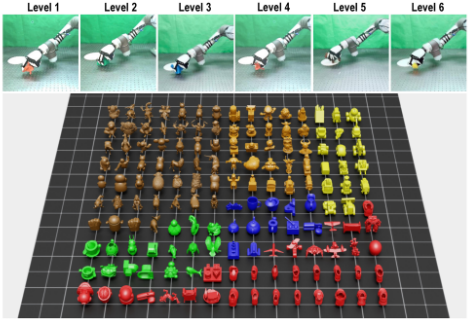
Experiments use a 12-DoF XHand with 3D force sensors and Manus Pro gloves. Simulations (Isaac Lab, 60Hz physics) require lifting objects to htgt = 6 cm for >2 s. Training employs basic geometric shapes, while testing evaluates generalization on 150 complex objects from the Visual Dexterity Dataset and fragile models.
For "Blind Grasp Stabilization", we assume that objects are initialized within a 2 cm×2 cm workspace. The wrist follows a fixed trajectory, relying on mechanical compliance and tactile feedback to accommodate positional errors. This definition decouples global navigation from grasping, focusing specifically on assessing policy robustness against geometric and physical uncertainties within peripersonal space.
To strictly quantify the marginal gain of our tactile adaptation modules, we employ Vanilla PPO with Domain Randomization (DR) as the primary baseline, consistent with the protocols in Dactyl [Andrychowicz et al., 2020] and
4.2 Simulation Performance Analysis
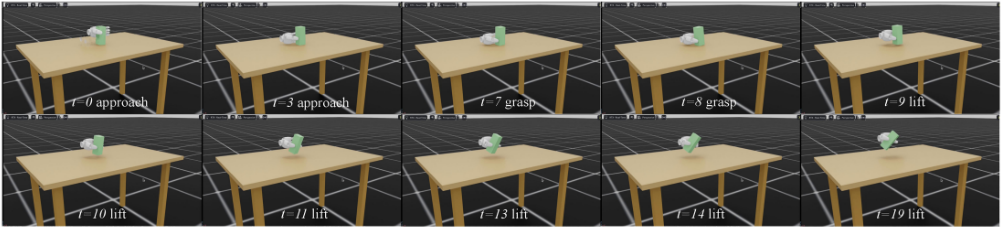
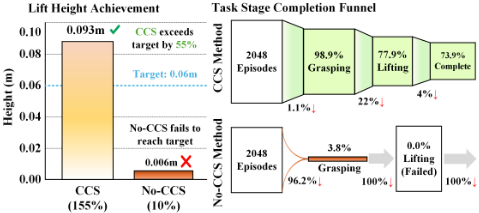
We first evaluate the learning efficiency of the teacher policy in the simulation environment. Figure 2 shows temporal snapshots of successful grasping and lifting objects in the simulation environment. The sequence demonstrates the three stages guided by CCS: approach (t = 0-3), where the hand pre-configures and approaches the object; grasping (t = 7-8), where stable multi-finger contact is established; lifting (t = 9-19), where the object is lifted to the target height while maintaining its posture. The quantitative impact of CCS is shown in Figure 3, which indicates that the CCS mechanism increases the grasping success rate from 3.8% of the unconstrained baseline to 98.9%. Funnel analysis shows that CCS effectively guides the policy to cross the exploration gap from "contact" to "force closure", proving the necessity of physical constraints in long-horizon task learning.
4.3 Real-World Evaluation
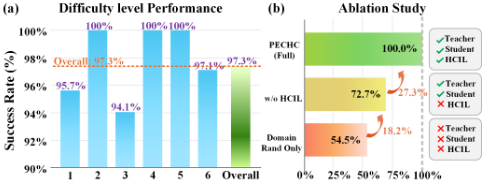
We set 6 difficulty levels for the Visual Dexterity Dataset [Chen et al., 2023] based on [Lum et al., 2024]. Adopting a 'calibrate-then-generalize' protocol, HCIL adaptation is performed once on a single calibration object from the 150-object evaluation set to align physical gaps. The policy is then frozen and evaluated on the full 150-object set, where the remaining 149 objects are unseen during calibration and no further intervention is allowed. As shown in Table 1, PECHC achieved a 97.3% success rate (146/150), demonstrating excellent post-calibration generalization (see Figure 4 and Figure 5(a)). We benchmark against external vision-based SOTA methods (DemoGrasp [Yuan et al., 2025], DextrAH-G [Lum et al., 2024]) and an internal baseline (Vanilla PPO + DR), representing standard Sim-to-Real RL without our proposed modules.
Table 2 presents results across two distinct evaluation paradigms. Vision-based methods (rows 1-3) achieve 80.0%-99.1% in idealized simulation with perfect visual perception, establishing the theoretical upper bound when geometry is fully observable. These results contextualize task difficulty but are NOT direct competitors since our setting deliberately excludes vision. Our primary contribution lies in the tactile-only comparison (rows 4-5): PECHC achieves 97.3% success on 150 real-world objects using only proprioceptive and tactile feedback-a substantial +42.8% improvement over standard Sim-to-Real RL (Vanilla PPO + DR: 54.5%). This gap demonstrates that domain randomization alone is insufficient for tactile-driven manipulation, validating the necessity of our CCS+THED+HCIL framework.
4.4 Ablation Study and Physical Perception Verification
To quantify the marginal contribution of each module and verify whether the policy truly possesses "physical perception" capabilities, we conduct a detailed ablation study (Figure 5(b)).
- HCIL and Systematic Alignment: Removing HCIL drops the success rate from 97.3% to 72.7%. Notably, performance is restored by calibrating on just a single representative object. This confirms that a dominant component of the Sim-to-Real gap in our setup stems from global systematic biases (e.g., sensor sensitivity, friction scaling) rather than per-object geometric variance. HCIL effectively aligns the student's physical beliefs, facilitating zero-shot transfer to unseen rigid objects.
- THED and Implicit Perception: Without tactile history, the success rate plummets to 54.5%, aligning with the vanilla domain randomization baseline. This 42.8%
| Object | Level 1 | Level 2 | Level 3 | Level 4 | Level 5 | Level 6 | Overall |
|---|---|---|---|---|---|---|---|
| Success Rate | 100.0% | 100.0% | 100.0% | 97.1% | 95.7% | 94.1% | 97.3% |
| Successful Captures | 25 | 16 | 12 | 33 | 44 | 16 | 146 |
| Total Number | 25 | 16 | 12 | 34 | 46 | 17 | 150 |
| Method | Perception Modality | Evaluation Domain | Success Rate |
|---|---|---|---|
| DemoGrasp [Yuan et al., 2025] DextrAH-G [Lum et al., 2024] | Vision (RGB-D) Vision (Point (Stereo) | Simulation (Idealized) Simulation (Idealized) | 99.1% 80.0% |
| Cloud) | |||
| DextrAH-RGB [Singh et al., 2024] | Vision | Simulation (Idealized) | ≈89% |
| Vanilla PPO + DR | Tactile | Real World | 54.5% |
| PECHC (Ours) | Tactile | Real World | 97.3% |
Note: Vision methods evaluated in idealized simulation; tactile in real hardware.
Direct comparison not applicable due to different evaluation domains.
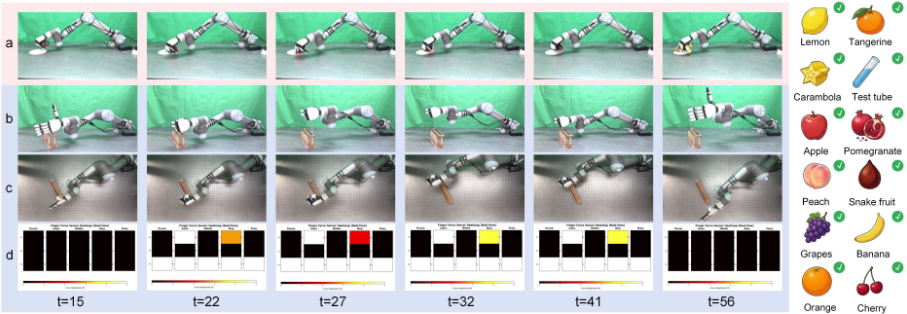
Figure 6: Experimental results on the private dataset
performance gain confirms that THED endows the agent with implicit system identification capabilities. By dynamically inferring invisible environmental parameters (e.g., friction, slip trends) from tactile history, the policy achieves true closed-loop physical adaptation rather than simple open-loop control.
4.5 Fine-Grained Force Control and Failure Analysis
To further evaluate the fine-grained force control capability of the policy, we selected 11 high-fidelity models of fruits with different hardness and shapes (e.g., lemons, red apples, grapes, starfruits) as well as fragile test tubes for testing. Experimental results show that PECHC achieves a 100% success rate (see Figure 6 for details). The policy successfully modulates fingertip force to prevent crushing, a capability often lacking in vision-only policies. Despite the high success rate, we analyzed rare failure cases to understand system limitations:
- Geometric outliers-objects exceeding the hand aperture can fail during the initial "geometric approach" stage, as the blind policy struggles to locate boundaries.
- Sensor saturation-high-speed grasping of heavy objects (> 500 grams) can saturate tactile readings, causing state-estimation loss and slip.
5 Conclusion
The proposed PECHC algorithm addresses the limits of vision-based planning by introducing a tactile-driven "Tactile Reflex" layer that decouples wrist navigation from fingerlevel interaction. With one-object calibration, PECHC closes the "Last-Centimeter" gap in the visual blind zone and achieves a 97.3% success rate on the 150-object benchmark. HCIL verifies that tactile feedback need not replace vision; instead, a human-calibrated tactile reflex loop with physical perception is sufficient for robust last-centimeter dexterous grasping. Future work will explore "In-Hand Reorientation" and vision-tactile fusion control.
Acknowledgments
The experiments, simulations, and model training were performed on the robotic AI-Scientist platform of the Chinese Academy of Sciences. This work was supported by the Major Project of Anhui Province's Science and Technology Innovation Breakthrough Plan (Grant No. 202423h08050003).
@inproceedings{ijcai2026p839,
  title     = {PECHC: Robust Tactile Grasping Stabilization in Vision-Denied Peripersonal Space},
  author    = {Chen, Changlin and Chen, Sisheng and Zhang, Hang and Zhou, Xianglai and Tian, Zhen and Liu, Weitao and Cui, Feng-Qi and Dong, Erbao and Chen, Wenjing},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {7549--7557},
  year      = {2026},
  month     = {8},
  note      = {AI and Robotics},
  doi       = {10.24963/ijcai.2026/839},
  url       = {https://doi.org/10.24963/ijcai.2026/839},
}
TY - CPAPER TI - PECHC: Robust Tactile Grasping Stabilization in Vision-Denied Peripersonal Space AU - Chen, Changlin AU - Chen, Sisheng AU - Zhang, Hang AU - Zhou, Xianglai AU - Tian, Zhen AU - Liu, Weitao AU - Cui, Feng-Qi AU - Dong, Erbao AU - Chen, Wenjing T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 7549 EP - 7557 DO - 10.24963/ijcai.2026/839 UR - https://doi.org/10.24963/ijcai.2026/839 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





