
Invariant Graph Representations for Continuous-Time Dynamic Graphs Under Distribution Shifts
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 2572-2580.
https://doi.org/10.24963/ijcai.2026/286
Keywords
- Machine Learning: Representation learning
- Knowledge Representation and Reasoning: Learning and reasoning
- Data Mining: Mining graphs
Abstract
Continuous-Time Dynamic Graphs (CTDGs) enable fine-grained modeling of evolving relational systems. However, most existing CTDG representation learning methods are tailored to in-distribution settings and exhibit limited robustness under out-of-distribution (OOD) shifts. Although recent causal approaches learn invariant representations via interventions, they are primarily designed for static or discrete-time graphs and become computationally prohibitive for CTDGs due to the combinatorial explosion of structural and temporal variations.
To address these challenges, we propose CIR, a framework grounded in a novel structural causal model termed the ICCM. To avoid exhaustive interventions, we leverage the Normalized Weighted Geometric Mean (NWGM) to efficiently approximate interventional predictions. We further instantiate ICCM within a practical deep learning architecture that jointly captures invariant structural and temporal patterns through dedicated subgraph extractors, and maintains an environment memory bank to model distributional shifts across evolving contexts. Extensive experiments demonstrate that CIR consistently outperforms existing methods under diverse OOD scenarios.
- [Ahmed and Chen, 2016] Nahla Mohamed Ahmed and Ling Chen. An efficient algorithm for link prediction in tem- poral uncertain social networks. Information Sciences, 331:120-136, 2016.
- [Chang et al., 2020] Shiyu Chang, Yang Zhang, Mo Yu, and Tommi Jaakkola. Invariant rationalization. In Inter- national Conference on Machine Learning, pages 1448- 1458. PMLR, 2020.
- [Cong et al., 2023] Weilin Cong, Si Zhang, Jian Kang, Baichuan Yuan, Hao Wu, Xin Zhou, Hanghang Tong, and Mehrdad Mahdavi. Do we really need complicated model architectures for temporal networks? In International Conference on Learning Representations, 2023.
- [De Winter et al., 2018] Sam De Winter, Tim Decuypere, Sandra Mitrović, Bart Baesens, and Jochen De Weerdt. Combining temporal aspects of dynamic networks with node2vec for a more efficient dynamic link prediction. In Advances in Social Networks Analysis and Mining, 2018.
- [Deng and Shen, 2024] Jiale Deng and Yanyan Shen. Self- interpretable graph learning with sufficient and necessary explanations. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 38, pages 11749-11756, 2024.
- [Fan et al., 2022] Shaohua Fan, Xiao Wang, Yanhu Mo, Chuan Shi, and Jian Tang. Debiasing graph neu- ral networks via learning disentangled causal substruc- ture. Advances in Neural Information Processing Systems, 35:24934-24946, 2022.
- [Feng et al., 2023] Kaituo Feng, Changsheng Li, Xiaolu Zhang, and Jun Zhou. Towards open temporal graph neu- ral networks. In International Conference on Learning Representations, 2023.
- [Li et al., 2017] Yaguang Li, Rose Yu, Cyrus Shahabi, and Yan Liu. Diffusion convolutional recurrent neural net- work: Data-driven traffic forecasting. In International Conference on Learning Representations, 2017.
- [Li et al., 2023] Yiming Li, Yanyan Shen, Lei Chen, and Mingxuan Yuan. Zebra: When temporal graph neural net- works meet temporal personalized pagerank. Proceedings of the VLDB Endowment, 16(6):1332-1345, 2023.
- [Li et al., 2024a] Hanjie Li, Changsheng Li, Kaituo Feng, Ye Yuan, Guoren Wang, and Hongyuan Zha. Ro- bust knowledge adaptation for dynamic graph neu- ral networks. IEEE Transactions on Knowledge and Data Engineering, 36(11):6920-6933, 2024. DOI: 10.1109/TKDE.2024.3388453. DOI
- [Li et al., 2024b] Haoyang Li, Xin Wang, Zeyang Zhang, Haibo Chen, Ziwei Zhang, and Wenwu Zhu. Disentan- gled graph self-supervised learning for out-of-distribution generalization. In Forty-first International Conference on Machine Learning, 2024.
- [Li et al., 2025a] Guoyi Li, Die Hu, Xiaomeng Fu, Qirui Tang, Yulei Wu, Xiaodan Zhang, and Honglei Lyu. En- tity graph alignment and visual reasoning for multimodal fake news detection. In Proceedings of the 33rd ACM In- ternational Conference on Multimedia, pages 2486-2495, 2025.
- [Li et al., 2025b] Peiwen Li, Xin Wang, Zeyang Zhang, Zi- wei Zhang, Fang Shen, Jialong Wang, Yang Li, and Wenwu Zhu. Causal-aware graph neural architecture search under distribution shifts. In Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V. 2, pages 1458-1469, 2025.
- [Ma et al., 2019] Yunpu Ma, Volker Tresp, and Erik A Daxberger. Embedding models for episodic knowledge graphs. Journal of Web Semantics, 59:100490, 2019.
- [Mahdavi et al., 2018] Sedigheh Mahdavi, Shima Khoshraftar, and Aijun An. dynnode2vec: Scalable dynamic network embedding. In IEEE International Conference on Big Data, 2018.
- [Ning et al., 2025] Xuecheng Ning, Yujie Wang, Kui Yu, Jiali Miao, Fuyuan Cao, and Jiye Liang. Summary graph induced invariant learning for generalizable graph learn- ing. IEEE Transactions on Knowledge and Data Engi- neering, 2025.
- [Pearl et al., 2016] Judea Pearl, Madelyn Glymour, and Nicholas P Jewell. Causal inference in statistics: A primer. John Wiley & Sons, 2016.
- [Peng et al., 2025] Yufei Peng, Cheng Yang, Zhengjie Fan, and Chuan Shi. Data-centric prompt tuning for dynamic graphs. In Proceedings of the 34th ACM International Conference on Information and Knowledge Management, pages 2336-2345, 2025.
- [Qin et al., 2023] Xiao Qin, Nasrullah Sheikh, Chuan Lei, Berthold Reinwald, and Giacomo Domeniconi. Seign: A simple and efficient graph neural network for large dy- namic graphs. In IEEE International Conference on Data Engineering, 2023.
- [Ranjan et al., 2020] Ekagra Ranjan, Soumya Sanyal, and Partha Talukdar. Asap: Adaptive structure aware pool- ing for learning hierarchical graph representations. In Pro- ceedings of the AAAI conference on artificial intelligence, volume 34, pages 5470-5477, 2020.
- [Rossi et al., 2020] Emanuele Rossi, Ben Chamberlain, Fab- rizio Frasca, Davide Eynard, Federico Monti, and Michael Bronstein. Temporal graph networks for deep learning on dynamic graphs. In International Conference on Machine Learning, 2020.
- [Sankar et al., 2020] Aravind Sankar, Yanhong Wu, Liang Gou, Wei Zhang, and Hao Yang. Dysat: Deep neural rep- resentation learning on dynamic graphs via self-attention networks. In The International Conference on Web Search and Data Mining, 2020.
- [Sui et al., 2022] Yongduo Sui, Xiang Wang, Jiancan Wu, Min Lin, Xiangnan He, and Tat-Seng Chua. Causal at- tention for interpretable and generalizable graph classifi- cation. In Proceedings of the 28th ACM SIGKDD Confer- ence on Knowledge Discovery and Data Mining, 2022.
- [Tolstikhin et al., 2021] Ilya Tolstikhin, Neil Houlsby, Alexander Kolesnikov, Lucas Beyer, Xiaohua Zhai, Thomas Unterthiner, Jessica Yung, Daniel Keysers, Jakob Uszkoreit, Mario Lucic, and Alexey Dosovitskiy. Mlp- mixer: An all-mlp architecture for vision. In Advances in Neural Information Processing Systems, volume 34, pages 24261-24272, 2021.
- [Trivedi et al., 2019] Rakshit Trivedi, Mehrdad Farajtabar, Prasenjeet Biswal, and Hongyuan Zha. Dyrep: Learn- ing representations over dynamic graphs. In International Conference on Learning Representations, 2019.
- [Wang et al., 2025] Botao Wang, Jia Li, Heng Chang, Keli Zhang, and Fugee Tsung. Heterophilic graph neural net- works optimization with causal message-passing. In Pro- ceedings of the Eighteenth ACM International Conference on Web Search and Data Mining, pages 829-837, 2025.
- [Wu et al., 2022] Ying-Xin Wu, Xiang Wang, An Zhang, Xi- angnan He, and Tat-Seng Chua. Discovering invariant ra- tionales for graph neural networks. In International Con- ference on Learning Representations, 2022.
- [Xu et al., 2015] Kelvin Xu, Jimmy Ba, Ryan Kiros, Kyunghyun Cho, Aaron Courville, Ruslan Salakhudinov, Rich Zemel, and Yoshua Bengio. Show, attend and tell: Neural image caption generation with visual attention. In International Conference on Machine Learning, 2015.
- [Xu et al., 2020] Da Xu, Chuanwei Ruan, Evren Korpeoglu, Sushant Kumar, and Kannan Achan. Inductive representa- tion learning on temporal graphs. In International Confer- ence on Learning Representations, 2020.
- [Yu et al., 2018] Wenchao Yu, Wei Cheng, Charu C Aggar- wal, Kai Zhang, Haifeng Chen, and Wei Wang. Netwalk: A flexible deep embedding approach for anomaly detec- tion in dynamic networks. In Proceedings of the 24th ACM SIGKDD international conference on knowledge discov- ery & data mining, pages 2672-2681, 2018.
- [Yuan et al., 2023] Haonan Yuan, Qingyun Sun, Xingcheng Fu, Ziwei Zhang, Cheng Ji, Hao Peng, and Jianxin Li. Environment-aware dynamic graph learning for out-of- distribution generalization. In Thirty-seventh Conference on Neural Information Processing Systems, 2023. https: //openreview.net/forum?id=n8JWIzYPRz. Link
- [Yuan et al., 2025a] Qi Yuan, Yang Liu, Yateng Tang, Xin- huan Chen, Xuehao Zheng, Qing He, and Xiang Ao. Dy- namic graph learning with static relations for credit risk assessment. In Proceedings of the AAAI Conference on Ar- tificial Intelligence, volume 39, pages 13133-13141, 2025.
- [Yuan et al., 2025b] Ruiwen Yuan, Yongqiang Tang, and Wensheng Zhang. A structure-aware invariant learning framework for node-level graph ood generalization. In Proceedings of the 31st ACM SIGKDD Conference on Knowledge Discovery and Data Mining V. 1, pages 1879- 1890, 2025.
- [Zhang et al., 2022] Zeyang Zhang, Xin Wang, Ziwei Zhang, Haoyang Li, Zhou Qin, and Wenwu Zhu. Dynamic graph neural networks under spatio-temporal distribution shift. Advances in Neural Information Processing Systems, 35:6074-6089, 2022.
- [Zhang et al., 2025] He Zhang, Bang Wu, Xiangwen Yang, Xingliang Yuan, Xiaoning Liu, and Xun Yi. Dynamic graph unlearning: A general and efficient post-processing method via gradient transformation. In Proceedings of the ACM on Web Conference 2025, pages 931-944, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Many real-world systems exhibit continuously evolving relational structures, which are naturally modeled as dynamic graphs [Zhang et al., 2025]. Existing dynamic graph models can be broadly categorized into Discrete-Time Dynamic Graphs (DTDGs) [Ahmed and Chen, 2016; Ma et al., 2019], which represent evolution as a sequence of temporal snapshots, and Continuous-Time Dynamic Graphs (CTDGs) [Peng et al., 2025; Yuan et al., 2025a; Li et al., 2017; De Winter et al., 2018], which capture fine-grained structural changes via continuous node and edge updates. Although existing methods have achieved significant success in modeling temporal dynamics, they predominantly overlook robustness under out-of-distribution (OOD) scenarios.
∗ Shanshan Feng is the corresponding author.
Therefore, this paper focuses on invariant representation learning for CTDGs under OOD scenarios. While techniques such as subgraph extraction [Deng and Shen, 2024; Li et al., 2024a] and attention mechanisms [Ranjan et al., 2020] can partially alleviate distribution shifts, they remain vulnerable to exploiting spurious correlations [Chang et al., 2020]. For example, in the link prediction setting illustrated in Figure 1, a triadic closure pattern (highlighted in red) constitutes the invariant subgraph underlying the formation of the target link (u, v). However, because a bridging link (x, u) (highlighted in blue), also appears before (u, v) in most training graphs, the model may incorrectly treat (x, u) as the invariant subgraph for (u, v). As a result, at test time, the model may falsely predict the existence of (u, v) based solely on (x, u), ignoring the absent of the triadic closure pattern.
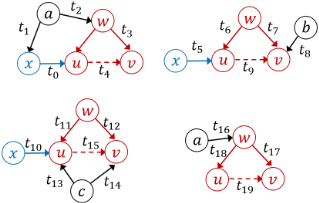
Recent structural causal model (SCM) based methods [Li et al., 2025a; Sui et al., 2022; Wang et al., 2025; Fan et al., 2022] have been proposed to mitigate spurious correlations by identifying and intervening on invariant subgraphs, either across multiple environments or through sampling-based interventions. However, these approaches implicitly assume a fixed or bounded graph structure, where the set of nodes and candidate edges remains stable over time, as in static graphs or DTDGs. Under this assumption, causal invariance can be meaningfully defined and estimated over a shared structural support. In contrast, CTDGs allow nodes and edges to be added or removed at arbitrary time points, resulting in a non-stationary and exponentially expanding space of graph topologies. This fundamentally challenges existing SCMbased intervention mechanisms.
In this paper, we propose Continuous-time Invariant Representation (CIR), a novel method that captures invariant representation and mitigates OOD effects from a new SCM perspective. To effectively address OOD generalization in CTDGs, CIR is designed to satisfy three essential properties: (1) robust mitigation of OOD distribution shifts, which is fundamental for generalization across unseen environments; (2) simultaneous capture of invariant subgraphs across both structural and temporal dimensions, which is crucial in CTDGs where graph topology and event timing evolve continuously; and (3) computationally efficient causal interventions, necessitated by the exponentially large space of possible structural-temporal subgraphs.
CIR is theoretically grounded in a structural causal model termed the Independent and Confounded Causal Model (ICCM), which explicitly models both in-distribution and OOD environments. Directly intervening on all possible structural and temporal subgraphs is computationally infeasible. To address this challenge, we leverage the Normalized Weighted Geometric Mean (NWGM) [Xu et al., 2015] to efficiently approximate the expected interventional outcome, substantially reducing computational cost. We instantiate ICCM within a practical deep learning framework. The architecture first employs dual subgraph extractors to capture causal structural and temporal patterns. An environment memory bank is then maintained to learn environment-specific representations, which are used to condition the prediction process. To approximate the expected outcome of causal interventions defined in ICCM, we aggregate environment-conditioned predictions using the NWGM. Finally, the causal structural and temporal patterns are encoded into invariant representations, and the model performs predictions based on the learned invariant representations together with the environment representations. The main contributions of this paper are summarized as follows:
- To the best of our knowledge, we are the first to investigate invariant representation learning problem for CTDGs under OOD shifts.
- We introduce ICCM, a novel structural causal model that characterizes invariant causal subgraphs in CTDGs, and develop an efficient intervention strategy based on the NWGM to approximate interventional predictions, avoiding exhaustive enumeration of structural and temporal subgraphs.
- We design a framework named CIR that instantialize ICCM, enabling the joint learning of invariant structural and temporal representations along with environmentspecific features.
2 RelatedWork
In this section, we review two areas closely related to our study: dynamic graph neural networks and invariant graph representation.
DynamicGraphNeural Networks. Dynamic graph neural networks encompass two primary classifications: DiscreteTime Dynamic Graphs (DTDGs) [Ma et al., 2019; Qin et al., 2023] and Continuous-Time Dynamic Graphs (CTDGs) [Li et al., 2017; De Winter et al., 2018; Li et al., 2023]. DTDGs comprise a sequence of static graph snapshots captured at regular time intervals [Sankar et al., 2020; Yu et al., 2018; Mahdavi et al., 2018]. CTDGs capture the evolution of graphs by considering modifications on the graph that occur continuously rather than discretely at predefined time steps [Xu et al., 2020; Trivedi et al., 2019; Feng et al., 2023]. However, these GNNs focus primarily on modeling graph dynamics while overlooking robustness to OOD scenarios.
Invariant Graph Representation. Invariant learning enhances the robustness of GNNs by identifying stable, environment-invariant patterns. Existing approaches fall broadly into two categories: disentangled learning and causal learning. Disentangled learning [Yuan et al., 2025b; Ning et al., 2025; Li et al., 2024b] aims to learn representations in which latent factors are separated and interpretable, capturing distinct variations in the data. Such representations have been shown to improve robustness to adversarial attacks and enhance generalization. However, these methods are limited in their ability to identify causal variables that remain invariant in the presence of shortcuts or spurious correlations. Causal inference methods [Li et al., 2025b; Wu et al., 2022] focus on unveiling and comprehending the true causal variables that drive observed phenomena. On realworld graphs, uncovering these causal variables becomes an act of explanation, revealing the "why" behind intricate relationships. However, most of these methods are largely restricted to static settings. To extend causal inference into dynamic scenarios, DIDA [Zhang et al., 2022] has been proposed as an invariant rational discovery framework for DTDGs. However, DIDA requires constructing an intervention set for each snapshot, making it computationally intensive when applied to CTDGs. EAGLE [Yuan et al., 2023] employs a VAE-based model as an environment sample generation network. However, when the number of environments is large and the available sample size is limited, the generated samples may not adequately represent the underlying environments, thereby impairing generalization performance. In this work, we focus on the more realistic and challenging setting of CTDGs, where interactions evolve continuously rather than at discrete time intervals. Existing causal inference methods are generally inapplicable to this setting because they predominantly rely on snapshot-based assumptions, which fail to capture the fine-grained temporal dynamics inherent in CTDGs.
3 ProblemFormulation
Definition 1 (CTDG) A Continuous Time Dynamic Graph (CTDG) G = (V, E, T ) consists of a set of vertices V, a set of edges E, and a continuous time domain T . The graph evolves over t ∈ T through edge additions, removals, or changing characteristics. We represent G as a sequence of time-stamped edges G = ⟨eij(tk)⟩, where eij(tk) denotes an interaction between node vi and vj at time tk with feature vector xeij (tk). Each node vi has a feature vector xni .
Given a CTDG G = (V, E), the task is to predict whether an interaction eij(t) will occur at a future time t, based on the historical sequence of nodes, edges, and their features. To evaluate OOD robustness, the model is trained on one environment and tested on CTDGs from other environments, where structural and temporal distributions may differ.
4 Independent and Confounded Causal Model
In this section, we introduce a novel structural causal model framework, termed Independent and Confounded Causal Model (ICCM).
In dynamic graphs, the existence of an edge can be influenced by both the structural topology (e.g., triadic closure) and temporal dynamics (e.g., temporal burst) [Cong et al., 2023]. These mechanisms may act independently or become entangled through latent confounders, and their influence can vary across environments. Existing causal formulations typically conflate structural and temporal effects, limiting their ability to disentangle spurious correlations under distribution shifts.
To explicitly capture both independent causal effects and environment-dependent confounding, ICCM models structural and temporal causal processes as distinct but potentially confounded components. We formalize ICCM by inspecting the causalities among nine variables: the structural causal subgraph Cs ⊆ G, the temporal causal subgraph Ct ⊆ G, the hidden representations HT and HS , the structural confounder Ds, the temporal confounder Dt, the edge existence probability in the in-distribution environment Y I , the edge existence probability in OOD environments Y O , and the final prediction result Y . Assumption 4.1 summarizes the core principles underlying ICCM:
Assumption 4.1 (ICCM)
In this assumption, Cs and Ct are causal structural and temporal subgraph. These subgraphs are encoded into latent representations HS and HT via fs(·) and ft(·). The indistribution prediction Y I is determined by the outcome function f I o (HS , HT ):
In OOD environments, however, structural and temporal confounders introduce spurious correlations that degrade model generalization. Specifically, structural confounders establish backdoor paths Cs ← C s b → Y and Cs ← Us → Y , where C s b = G \ Cs, and Us represent unobserved variables. These paths induce spurious correlations between Cs and Y C . Temporal confounders exert a similar influence. To mitigate these spurious correlations, we employ the do-operation introduced by Pearl [Pearl et al., 2016]. The do-operation allows us to block backdoor paths, thereby eliminating spurious correlations and isolating the invariant causal effect. Using the do-operation, the prediction Y C can be formulated as:
where Ds = {C s b , Us} and Dt = {C t b ,Ut}, respectively, f C o is output network network:
where W ∗ ∗ denotes the model parameters, f ∗ y (·) denotes linear network, σ denotes the activation function. However, we observe Equation 2 is computationally intractable. It necessitates enumerating all possible pairs of invariant causal subgraphs across the space of structural confounders Ds and temporal confounders Dt. In the context of large-scale CTDGs, this combinatorial explosion of potential subgraph configurations leads to prohibitive computational costs, making exhaustive intervention infeasible.
To address this issue, we propose an efficient intervention process by leveraging the NWGM approximation [Xu et al., 2015]. The NWGM provides a computationally efficient way to estimate the expectation of a softmax or sigmoid output by moving the expectation inside the non-linearity:
By applying the NWGM approximation, the interventional prediction in Equation 2 can be reformulated as:
Note that Ds and Dt denote abstract latent confounders, which may themselves correspond to complex subgraph patterns. While the confounder space can be large, Equation 5 does not require explicit enumeration of all possible confounders. Instead, it only requires expectation over a representative set of confounding modes, which can be approximated via confounder prototypes (Explained in Section 5.2.
5 Neural Instantiation of ICCM
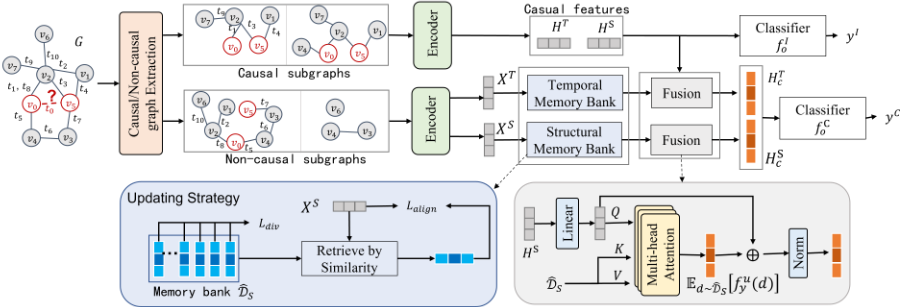
In this section, we describe how the proposed ICCM is instantiated within a neural architecture by mapping latent causal variables to learnable components. The complete architecture is illustrated in Figure 2.
While the theoretical ICCM assumes access to causal subgraphs Cs and Ct, these variables are typically latent and unobserved in real-world scenarios. To address this, we employ causal subgraph extractors to infer structural and temporal subgraphs directly from the input data. The extractors identify invariant structural and temporal patterns and produce hidden representations HS and HT .
For the in-distribution perspective, these representations are passed to the outcome function f I o to predict the label yI . For the out-of-distribution (OOD) perspective, as described in Equation 5, the interventional prediction requires the expected representations of structural and temporal confounders: Eu∼DS [f u y (u)] and Ev∼DT [f v y (v)].
To estimate these expectations without exhaustive enumeration, we maintain structural and temporal memory banks that approximate the latent confounder distributions Ds and Dt. A multi-head attention-based fusion module then aggregates the memory entries to compute the expected environmental context, which approximates the expectation over latent confounder effects. Finally, the invariant representations HS and HT are integrated with the computed expectations from the memory banks and fed into the outcome function f C o to produce the OOD prediction yC . We term this framework Continuous Invariant Representation (CIR).
5.1 Extracting and Encoding Causal/Non-causal Subgraphs
Temporal extraction and encoding. Given a dynamic graph G and a target node pair (u, v) for prediction, our goal is to identify historical temporal interactions that causally contribute to the potential existence of an edge between u and v. Unlike heuristic time-window approaches, we aim to extract temporally relevant evidence that is both time-aware and pair-specific, aligning with the causal assumptions in ICCM. we first extract the temporal edges associated with nodes u and v denoted by SuG and SvG, respectively. Each edge eui(tk) ∈ SuG is encoded using a continuous-time representation following [Cong et al., 2023]: cos((t0 -tk)ω), where t0 is the prediction timestamp, ω = {α-(i-1)/β }di=1 defines a set of multi-scale temporal frequencies, with α and β representing hyperparameters. This encoding is combined with its corresponding edge features as [cos((t0 - tk) ω)∥xeui (tk)].
A 1-layer MLP-mixer [Tolstikhin et al., 2021] is employed to encode the edge features,
where stack(SuG) indicates the stacking of the edge features in sequence SuG. The MLP-Mixer enables global mixing across temporal edges, allowing the representation of higher-order temporal dependencies that are crucial for causal reasoning.
Intuitively, a historical interaction of v is considered temporally causal for predicting (u, v) only if it helps explain u's behavior, and vice versa. Therefore, we introduce a crossnode attention mechanism. The subgraph is generated by:
Here, d denotes a specific hyperparameter, and M e ∗ [k] represents the importance score assigned to the k-th edge within S∗. This attention mechanism filters temporal evidence based on mutual relevance, rather than local frequency or recency alone. Consequently, the highest top-k scores inM e v andM e u are selected to construct the temporal causal subgraphs Ct, while the remaining edges form the temporal non-causal subgraphs ˆBt. Finally, the temporal representations of the causal and non-causal graphs are encoded by:
The final representations are obtained by concatenation:
Causal temporal evidence is disentangled from confounding effects, supporting intervention-based learning.
Structural extraction and encoding. Our objective is to identify structural neighbors that causally support the interaction between u and v, while filtering out background nodes that may introduce spurious correlations. We first encode each node based on its n-hop neighborhood within a recent time window ]t0 - T, t0]: zu = xnu + Mean({xnv | v ∈ N n (u; t0 - T, t0)}). Here, N n (u; t0 - T, t0) denotes the nhop neighbors of node u with valid temporal edges, where T controls the structural temporal scope. The node mask matrices are computed through the equations:
Here, Zu and Zv is the stack of the encoded node features of all nodes in N n (u; t0 -T, t0) and N n (v; t0 -T, t0), respectively. The nodes with the highest top-k scores in M n u and M n v are chosen to form the structural causal subgraph, while the remaining edges form the temporal non-causal subgraphs ˆBs. The final structural representation HS is computed by:
where xnv represents the node feature of v, N n S (u) represents the n-hop neighbors of u in Cs. The final structural representation XS for the non-causal subgraph ˆBs is obtained using the same encoding method applied to Cs.
5.2 Memory Banks
The memory bank is designed to capture all confounders, including both non-causal subgraphs and unobserved factors. Since unobserved factors are not directly observable, we approximate them using the representations of observable noncausal subgraphs, based on the insight that unobserved influences are often implicitly reflected in the structure of these subgraphs.
As the dynamic graph evolves, the number of non-causal subgraphs can grow exponentially, making it infeasible to consider each instance individually. To address this, each entry in the memory bank approximates a cluster of noncausal subgraphs, capturing the shared influence of similar confounders. Specifically, the memory bank consists of K prototype vectors stored in the ˆD∗ ∈ RK×d , where K denotes the number of prototypes and d represents the feature dimensionality. Each element of ˆD∗ is initialized by sampling from a standard normal distribution, after which each prototype is normalized to ensure that they lie on a unit hypersphere. The memory bank is updated during training via gradient descent, guided by two self-supervised loss functions: the alignment loss and the diversity loss.
Given non-causal graphs XT and XS , the alignment loss is defined as:
Here, zT and zS are encoded features of XT and XS , respectively. The term z∗ ˆD⊤ ∗ [k∗] (with ∗ representing either T or S) measures the similarity between the encoded feature z∗ and the k∗-th prototype in ˆD∗. Each sample is assigned to the prototype with the highest similarity. When z∗ is well aligned with ˆD∗[k], the loss contribution for that sample is minimal.
To prevent redundancy among the prototypes, we impose a diversity loss:
Minimizing this loss encourages the prototypes to be as orthogonal as possible, ensuring that each captures a distinct cluster of non-causal subgraphs.
The overall regularization loss is the sum of the alignment and diversity losses:Lreg = Lalign + Ldiv. (14)
This loss is backpropagated during training to update both the encoder parameters and the memory bank, thereby refining the prototypes to more accurately represent distinct clusters of non-causal subgraphs.
5.3 Fusion
As shown in Equations 5, the fusion module combines the causal graph representations (HS and HT ) with the expected contributions of confounders, as approximated by the memory banks ( ˆDS and ˆDT ). This step implements the ICCMinspired interventional reasoning, where the model accounts for potential spurious effects from non-causal subgraphs and unobserved factors. We approximate the expected effect of confounders as:
The attention output is then fused with the original query using a residual connection, followed by dropout and layer normalization:
The fused features HS c and HT c are subsequently processed by a feedforward network and output the final prediction yC .
5.4 Optimization
We define the overall learning objective as:
where λi, λc, and λr are hyperparameters, E denotes the training dataset, which comprises pairs of positive and negative samples. Positive samples are derived from the original edge sets, while negative samples are generated by replacing the destination nodes with randomly sampled nodes from the vocabulary, ensuring a balanced ratio. The variable ye indicates the ground-truth label for edge e, with ye = 1 for positive samples and ye = 0 for negative samples.
| Model | MOOC | WIKI | UCI | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ratio | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 |
| TGN | 90.39±1.27 | 65.49±0.81 | 61.99±2.21 | 95.44±1.09 | 87.70±3.55 | 72.69±0.31 | 68.56±2.03 | 61.92±2.63 | 64.97±0.65 | 68.93±1.41 | 68.43±3.58 | 64.68±2.47 |
| TGAT | 93.75±0.49 | 85.25±1.21 | 73.08±1.49 | 97.32±0.14 | 95.34±0.28 | 89.21±0.48 | 90.90±0.78 | 74.72±0.74 | 73.07±2.74 | 77.66±1.17 | 74.55±0.46 | 72.59±0.54 |
| GraphMixer | 98.06±0.27 | 88.11±4.62 | 48.71±3.02 | 98.41±0.33 | 78.85±3.10 | 91.74±1.32 | 95.90±1.15 | 73.61±5.39 | 64.01±7.36 | 88.67±0.68 | 75.45±2.93 | 65.35±0.39 |
| DIDA | 72.78±3.32 | 59.87±1.30 | 52.00±0.63 | 88.26±0.47 | 64.06±0.06 | 59.05±0.25 | 77.40±0.46 | 60.94±1.10 | 49.47±0.35 | 77.17±1.08 | 76.09±2.87 | 65.92±0.41 |
| Ada-DyGNN | 83.20±4.74 | 74.03±1.21 | 71.22±0.51 | 95.42±0.17 | 94.29±0.54 | 90.79±0.55 | 91.54±0.23 | 72.70±0.61 | 67.57±0.44 | 89.59±0.50 | 74.26±3.43 | 67.15±1.58 |
| EAGLE | 83.41±0.97 | 73.12±0.36 | 64.46±0.37 | 85.07±0.86 | 81.71±0.44 | 67.38±0.35 | 81.51±0.56 | 72.41±0.31 | 60.69±0.59 | 77.90±0.11 | 72.19±0.61 | 65.06±0.55 |
| CIR | 97.72±0.13 | 90.18±2.17 | 77.46±4.07 | 98.91±0.06 | 98.18±0.32 | 93.82±1.25 | 93.26±0.71 | 80.37±2.02 | 76.04±4.58 | 91.84±0.44 | 76.84±0.97 | 74.88±0.65 |
| Model | MOOC | WIKI | UCI | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Ratio | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 | 0.2 | 0.4 | 0.6 |
| TGN | 91.51±1.5 | 59.69±0.8 | 33.75±3.2 | 96.47±0.6 | 86.68±4.0 | 55.41±0.5 | 76.18±1.8 | 64.09±3.8 | 50.30±2.8 | 66.82±2.2 | 64.34±1.4 | 43.01±3.2 |
| TGAT | 93.42±0.3 | 79.92±1.8 | 62.02±0.6 | 97.60±0.1 | 94.64±0.4 | 81.44±0.9 | 91.90±1.5 | 73.06±0.6 | 59.73±0.7 | 65.54±1.0 | 60.84±0.5 | 52.95±0.4 |
| GraphMixer | 98.48±0.2 | 87.71±2.2 | 31.19±4.9 | 98.87±0.3 | 82.84±2.6 | 90.85±2.1 | 97.13±0.5 | 75.68±4.5 | 61.14±11.7 | 86.99±1.5 | 73.13±1.4 | 56.50±0.6 |
| DIDA | 67.15±0.6 | 53.86±1.2 | 50.74±0.4 | 81.94±1.6 | 55.62±0.2 | 53.97±0.3 | 73.23±0.5 | 56.37±1.0 | 48.07±0.5 | 69.66±3.2 | 61.47±0.8 | 55.38±0.8 |
| Ada-DyGNN | 81.81±5.0 | 73.44±1.4 | 70.04±1.2 | 94.26±0.4 | 90.96±0.4 | 90.51±0.5 | 92.63±0.4 | 70.83±0.3 | 64.54±0.3 | 88.20±0.8 | 72.91±1.8 | 62.10±0.8 |
| EAGLE | 72.10±0.3 | 72.03±0.6 | 63.03±0.6 | 79.82±0.3 | 77.47±0.5 | 65.16±0.5 | 76.01±0.5 | 66.43±1.0 | 58.14±0.5 | 74.06±0.1 | 62.36±0.4 | 55.22±0.4 |
| CIR | 98.14±0.5 | 88.24±0.3 | 64.53±2.6 | 98.95±0.1 | 98.15±0.3 | 93.65±2.0 | 94.96±0.7 | 79.10±4.5 | 63.46±6.0 | 90.59±0.6 | 73.55±1.8 | 57.36±0.4 |
The model underwent training for 300 epochs using the Adam optimizer with a learning rate set at 0.0001 and a weight decay of 1e-6. We set the batch size to 600, and the hidden layer dimension to 100. For the extraction of the causal subgraph, we specified the number of recent edges (N) as 50 and employed 1-hop neighbors. All MLP layers were configured to 2. Regarding the link prediction task, negative samples were set at a ratio of 1:5 in the training set and adjusted to 1:1 in both the validation and test sets.
Baselines. Given the limited research on invariant GNNs for CTDGs, we consider three categories of baselines: (1) CTDG GNN Models:TGN [Rossi et al., 2020], TGAT [Xu et al., 2020], and GraphMixer [Cong et al., 2023]. These models are specifically designed for CTDGs but lack the ability to produce explainable and invariant results. Therefore, our comparison primarily focuses on link prediction. (2) Robust DTDG models:DIDA [Zhang et al., 2022], EAGLE [Yuan et al., 2023], and Ada-DyGNN [Li et al., 2024a].
6.2 Link Prediction results (RQ1)
Table 1 reports the AUC results under varying shortcut ratios (0.2, 0.4, 0.6), while Table 2 presents the corresponding AP scores. Higher values indicate better performance. We summarize the key observations below: (1) CTDG models degrade sharply under stronger shortcuts. TGN suffers a substantial performance drop, with AUC decreasing by 31.4% on MOOC and by 23.8% on REDDIT. GraphMixer achieves competitive performance at 0.2 with CIR, but suffering drastic declines, particularly on MOOC (AUC decrease of 50.3%) and WIKI (AUC decrease of 33.3%). TGAT demonstrates relatively better stability but still degrades at higher shortcut ratios. (2) Robust DTDG models perform relatively well but do not generalize as effectively as CIR. Since DTDG models operate on discrete time steps, their effectiveness on CTDGs may be constrained, as they are not explicitly designed to handle fine-grained temporal dependencies. The relatively competitive performance of Ada-DyGNN and EAGLE sug-
6 Experiments
We conduct extensive experiments on four benchmark continuous-time dynamic-graph datasets to answer the following research questions:
- RQ1: How well does CIR mitigate distribution shift?
- RQ2: How efficient is CIR compared to existing baselines?
- RQ3: What is the contribution of each component?
All the experiments are conducted on a computer with Intel(R) Core(TM)2 Duo CPU @2.40 GHz processor, 128 GB RAM, and Tesla T4.
6.1 Experimental Settings
Datasets We conducted experiments on four real-world datasets: Wikipedia 1 , Reddit 2 MOOC 3 , UCI 4 . Following prior work [Zhang et al., 2022], we introduce structural perturbations to the graphs to simulate distributional shifts.
Evaluation Metrics. We partitioned the datasets based on the edge occurrence time: the initial 70% of edges were designated as the training set, the subsequent 15%were allocated to the validation set, and the remaining 15% formed the test set. We employ the average precision (AP) and area under the curve (AUC) as the evaluation metrics for link prediction. AP and AUC are two common metrics used to evaluate the performance of binary classification models. AP is a measure of the average precision across all possible recall thresholds. AUC is a measure of the area under the receiver operating characteristic (ROC) curve.
Training Protocols. An early-stopping mechanism was employed, terminating training when the Average Precision (AP) metric showed no improvement for five consecutive epochs.
1 http://snap.stanford.edu/jodie/wikipedia.csv
2 http://snap.stanford.edu/jodie/reddit.csv
3 http://snap.stanford.edu/jodie/mooc.csv
4 https://zenodo.org/records/7213796#.Y1cO6y8r30o
| Dataset | MOOC | WIKI | UCI | |||||
|---|---|---|---|---|---|---|---|---|
| AP | AUC | AP | AUC | AP | AUC | AP | AUC | |
| remove structural encoder | 78.34±2.50 | 75.12±0.45 | 89.45±0.52 | 90.31±0.38 | 65.82±2.95 | 63.14±5.20 | 60.27±1.68 | 58.91±2.75 |
| remove temporal encoder | 80.12±2.42 | 77.85±0.41 | 91.62±0.49 | 92.78±0.36 | 68.30±2.88 | 66.42±5.08 | 63.50±1.62 | 61.75±2.60 |
| remove Y I | 85.21±2.30 | 82.64±0.38 | 95.14±0.46 | 96.07±0.33 | 74.45±2.75 | 72.10±4.90 | 70.12±1.55 | 68.35±2.42 |
| remove Y C | 81.73±1.26 | 83.47±0.22 | 89.31±0.98 | 90.67±0.52 | 70.98±1.63 | 68.49±1.90 | 67.82±0.96 | 62.46±0.87 |
| CIR | 90.18±2.17 | 88.24±0.27 | 98.18±0.32 | 98.15±0.25 | 80.37±2.02 | 79.10±4.53 | 76.84±0.97 | 73.55±1.81 |
gests that their robustness mechanisms still provide advantages, but their full potential might be underestimated due to the CTDG evaluation setting. (3) CIR achieves the best AUC score across all datasets and shortcut ratios. Even at the highest shortcut ratio (0.6), CIR maintains strong performance, significantly outperforming other models, demonstrating superior generalization under distributional shifts. (4) CIR maintains low variance across datasets and shortcut ratios, indicating consistent performance. In contrast, CTDG models, particularly GraphMixer and TGN, exhibit higher variance at larger shortcut ratios, suggesting instability when shortcut dependencies are removed. TGAT shows moderate variance but still struggles with higher shift levels. Among DTDG models, Ada-DyGNN demonstrates lower variance than CTDG models, reflecting its robustness in link prediction, while EAGLE's variance remains moderate, indicating some inconsistency in handling shifts.
In conclusion, the results demonstrate that CIR achieves SOTA performance in link prediction across varying levels of distribution shift. Unlike existing CTDG and DTDG models, which either suffer from severe performance degradation or exhibit low AUC and AP scores, CIR consistently identifies stable causal structures and maintains high predictive performance with low variance. These results highlight CIR's strong generalization ability and robustness to spurious correlations in CTDGs.
6.3 Efficiency (RQ2)
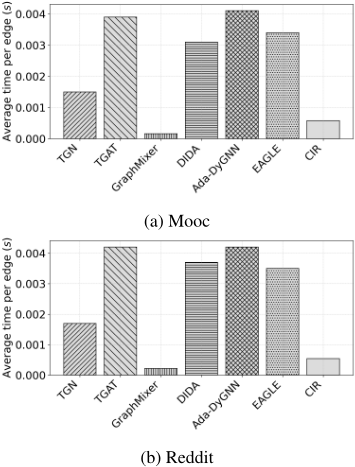
Figure 3 reports the average inference time per edge for each method. CIR demonstrates high efficiency, with average running times per edge of 5.4 × 10⁻⁴ seconds on Reddit and 5.8 × 10⁻⁴ seconds on MOOC. In contrast, TGAT and TGN are slower due to their more complex encoding networks, while DIDA is also slower because it must construct a confounder dictionary for each snapshot. GraphMixer is slightly more efficient than CIR, primarily because it does not output an explainable subgraph. Despite some differences in absolute running times between the Reddit and MOOC datasets, the relative performance across models is consistent, indicating that these efficiency measurements are reproducible across diverse dynamic graph scenarios.
6.4 Ablation Study (RQ3)
Table 3 depicts the ablation study by reporting the AP and AUC across datasets with a fixed shortcut ratio of 0.4. The results reveal that each component contributes significantly to the overall performance. Removing either the structural encoder or the temporal encoder leads to substantial performance drops, particularly on the WIKI and UCI datasets.
Moreover, excluding the Y C causes a marked decline in performance. In contrast, the removal of the Y I has a more modest impact, with performance decreases ranging from about 2% to 8.9%. This suggests that while the ICM plays a supportive role in enhancing performance, the CCM is critical for capturing the essential patterns in the data. In summary, the full CIR model, which integrates all these components, consistently outperforms the ablated versions, highlighting the necessity of each module in achieving optimal performance across diverse datasets.
7 Conclusion
This paper addresses the challenge of developing invariant and self-interpretable GNNs for continuous-time dynamic graphs. By analyzing this problem from a causal effect perspective, we introduce the ICCM, a novel causal inference model meticulously designed to address both IID and OOD scenarios for CTDGs. Building upon the theoretical foundations of ICCM, we propose a novel deep learning architecture, which translates theoretically established causal models into a practical solution for dynamic graphs. Experiments show that CIR outperforms prior methods in link prediction, and robustness under OOD scenarios.
Acknowledgments
This work was supported by the National Natural Science Foundation of China (No.62472091, 62394333, 62572361)
@inproceedings{ijcai2026p286,
  title     = {Invariant Graph Representations for Continuous-Time Dynamic Graphs Under Distribution Shifts},
  author    = {Fang, Lanting and Yang, Yulian and Zhang, Yawei and Feng, Shanshan and Feng, Kaiyu and Yuan, Hanning},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {2572--2580},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/286},
  url       = {https://doi.org/10.24963/ijcai.2026/286},
}
TY - CPAPER TI - Invariant Graph Representations for Continuous-Time Dynamic Graphs Under Distribution Shifts AU - Fang, Lanting AU - Yang, Yulian AU - Zhang, Yawei AU - Feng, Shanshan AU - Feng, Kaiyu AU - Yuan, Hanning T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 2572 EP - 2580 DO - 10.24963/ijcai.2026/286 UR - https://doi.org/10.24963/ijcai.2026/286 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





