
InfoMatch: Entropy Neural Estimation for Semi-Supervised Image Classification
Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence. Main Track. Pages 4089-4097.
https://doi.org/10.24963/ijcai.2024/452
Keywords
- Machine Learning: ML: Semi-supervised learning
- Machine Learning: ML: Self-supervised Learning
- Machine Learning: ML: Unsupervised learning
- Computer Vision: CV: Representation learning
Abstract
Semi-supervised image classification, leveraging pseudo supervision and consistency regularization, has demonstrated remarkable success. However, the ongoing challenge lies in fully exploiting the potential of unlabeled data. To address this, we employ information entropy neural estimation to utilize the potential of unlabeled samples. Inspired by contrastive learning, the entropy is estimated by maximizing a lower bound on mutual information across different augmented views. Moreover, we theoretically analyze that the information entropy of the posterior of an image classifier is approximated by maximizing the likelihood function of the softmax predictions. Guided by these insights, we optimize our model from both perspectives to ensure that the predicted probability distribution closely aligns with the ground-truth distribution. Given the theoretical connection to information entropy, we name our method InfoMatch. Through extensive experiments, we show its superior performance. The source code is available at https://github.com/kunzhan/InfoMatch.
- [Belghazi et al., 2018] Mohamed Ishmael Belghazi, Aristide Baratin, Sai Rajeshwar, Sherjil Ozair, Yoshua Bengio, Aaron Courville, and Devon Hjelm. Mutual information neural estimation. In ICML, pages 531-540, 2018.
- [Berthelot et al., 2019a] David Berthelot, Nicholas Carlini, Ekin D Cubuk, Alex Kurakin, Kihyuk Sohn, Han Zhang, and Colin Raffel. ReMixMatch: Semi-supervised learning with distribution matching and augmentation anchoring. In ICLR, 2019.
- [Berthelot et al., 2019b] David Berthelot, Nicholas Carlini, Ian Goodfellow, Nicolas Papernot, Avital Oliver, and Colin A Raffel. MixMatch: A holistic approach to semi- supervised learning. In NeurIPS, volume 32, 2019.
- [Chen et al., 2023] Hao Chen, Ran Tao, Yue Fan, Yidong Wang, Jindong Wang, Bernt Schiele, Xing Xie, Bhiksha Raj, and Marios Savvides. SoftMatch: Addressing the quantity-quality tradeoff in semi-supervised learning. In ICLR, 2023.
- [Coates et al., 2011] Adam Coates, Andrew Ng, and Honglak Lee. An analysis of single-layer networks in unsupervised feature learning. In AIStat, pages 215-223, 2011.
- [Cubuk et al., 2020] Ekin D Cubuk, Barret Zoph, Jonathon Shlens, and Quoc V Le. RandAugment: Practical auto- mated data augmentation with a reduced search space. In CVPR workshop, pages 702-703, 2020.
- [Deng et al., 2009] Jia Deng, Wei Dong, Richard Socher, Li- Jia Li, Kai Li, and Li Fei-Fei. ImageNet: A large-scale hierarchical image database. In CVPR, pages 248-255, 2009.
- [Ghorban et al., 2022] Farzin Ghorban, Nesreen Hasan, Jörg Velten, and Anton Kummert. Individual weighting of unlabeled data points via confidence-awareness in semi- supervised learning. In ISCAS, pages 1215-1219, 2022.
- [Grill et al., 2020] Jean-Bastien Grill, Florian Strub, Altché, et al. Bootstrap your own latent-a new approach to self- supervised learning. In NeurIPS, volume 33, pages 21271- 21284, 2020.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In CVPR, pages 770-778, 2016.
- [Hjelm et al., 2019] R Devon Hjelm, Alex Fedorov, Samuel Lavoie-Marchildon, Karan Grewal, Phil Bachman, Adam Trischler, and Yoshua Bengio. Learning deep representa- tions by mutual information estimation and maximization. In ICLR, 2019.
- [Krizhevsky and Hinton, 2009] Alex Krizhevsky and Geof- frey Hinton. Learning multiple layers of features from tiny images. Technical Report, University of Toronto, 2009.
- [Lee, 2013] Dong-Hyun Lee. Pseudo-label: The simple and efficient semi-supervised learning method for deep neural networks. In ICML Workshop, volume 3, 2013.
- [Li et al., 2021] Junnan Li, Caiming Xiong, and Steven CH Hoi. Comatch: Semi-supervised learning with contrastive graph regularization. In CVPR, pages 9475-9484, 2021.
- [Ma et al., 2023] Yixuan Ma, Xiaolin Zhang, Peng Zhang, and Kun Zhan. Entropy neural estimation for graph con- trastive learning. In ACM Multimedia, volume 31, pages 435-443, 2023.
- [Miyato et al., 2018] Takeru Miyato, Shin-ichi Maeda, Masanori Koyama, and Shin Ishii. Virtual adversarial training: a regularization method for supervised and semi-supervised learning. TPAMI, 41(8):1979-1993, 2018.
- [Netzer et al., 2011] Yuval Netzer, Tao Wang, Adam Coates, Alessandro Bissacco, Baolin Wu, Andrew Y Ng, et al. Reading digits in natural images with unsupervised feature learning. In NeurIPS Workshop, 2011.
- [Nowozin et al., 2016] Sebastian Nowozin, Botond Cseke, and Ryota Tomioka. f -GAN: Training generative neu- ral samplers using variational divergence minimization. In NeurIPS, pages 271-279, 2016.
- [Oord et al., 2018] Aaron van den Oord, Yazhe Li, and Oriol Vinyals. Representation learning with contrastive predic- tive coding. arXiv preprint arXiv:1807.03748, 2018.
- [Pham et al., 2021] Hieu Pham, Zihang Dai, Qizhe Xie, and Quoc V Le. Meta pseudo labels. In CVPR, pages 11557- 11568, 2021.
- [Rasmus et al., 2015] Antti Rasmus, Mathias Berglund, Mikko Honkala, Harri Valpola, and Tapani Raiko. Semi- supervised learning with ladder networks. In NeurIPS, vol- ume 28, 2015.
- [Samuli and Timo, 2017] Laine Samuli and Aila Timo. Tem- poral ensembling for semi-supervised learning. In ICLR, volume 4, 2017.
- [Sohn et al., 2020] Kihyuk Sohn, David Berthelot, Nicholas Carlini, Zizhao Zhang, Han Zhang, Colin A Raffel, Ekin Dogus Cubuk, Alexey Kurakin, and Chun-Liang Li. FixMatch: Simplifying semi-supervised learning with consistency and confidence. In NeurIPS, volume 33, pages 596-608, 2020.
- [Tarvainen and Valpola, 2017] Antti Tarvainen and Harri Valpola. Mean teachers are better role models: Weight- averaged consistency targets improve semi-supervised deep learning results. In NeurIPS, volume 30, 2017.
- [Tian et al., 2023] Zhibo Tian, Xiaolin Zhang, Peng Zhang, and Kun Zhan. Improving semi-supervised semantic seg- mentation with dual-level Siamese structure network. In ACM Multimedia, volume 31, pages 4200-4208, 2023.
- [Tishby et al., 1999] Naftali Tishby, Fernando C Pereira, and William Bialek. The information bottleneck method. In Annual Allerton Conference on Communication, Control and Computing, pages 368-377, 1999.
- [Verma et al., 2022] Vikas Verma, Kenji Kawaguchi, Alex Lamb, Juho Kannala, Arno Solin, Yoshua Bengio, and David Lopez-Paz. Interpolation consistency training for semi-supervised learning. Neural Networks, 145:90-106, 2022. IJCAI
- [Wang et al., 2023] Yidong Wang, Hao Chen, Qiang Heng, Wenxin Hou, Yue Fan, Zhen Wu, Jindong Wang, Marios Savvides, Takahiro Shinozaki, Bhiksha Raj, et al. FreeMatch: Self-adaptive thresholding for semi- supervised learning. In ICLR, 2023.
- [Wei et al., 2021] Xiang Wei, Xiaotao Wei, Xiangyuan Kong, Siyang Lu, Weiwei Xing, and Wei Lu. FMixCut- Match for semi-supervised deep learning. Neural Net- works, 133:166-176, 2021.
- [Xie et al., 2020] Qizhe Xie, Zihang Dai, Eduard Hovy, Thang Luong, and Quoc Le. Unsupervised data augmen- tation for consistency training. In NeurIPS, volume 33, pages 6256-6268, 2020.
- [Xu et al., 2021] Yi Xu, Lei Shang, Jinxing Ye, Qi Qian, Yu- Feng Li, Baigui Sun, Hao Li, and Rong Jin. Dash: Semi- supervised learning with dynamic thresholding. In ICML, pages 11525-11536, 2021.
- [Yun et al., 2019] Sangdoo Yun, Dongyoon Han, Seong Joon Oh, Sanghyuk Chun, Junsuk Choe, and Youngjoon Yoo. CutMix: Regularization strategy to train strong classifiers with localizable features. In ICCV, pages 6023-6032, 2019.
- [Zagoruyko and Komodakis, 2016] Sergey Zagoruyko and Nikos Komodakis. Wide residual networks. In BMVC, 2016.
- [Zhang et al., 2018] Hongyi Zhang, Moustapha Cisse, Yann N Dauphin, and David Lopez-Paz. mixup: Beyond empirical risk minimization. In ICLR, 2018.
- [Zhang et al., 2021] Bowen Zhang, Yidong Wang, Wenxin Hou, Hao Wu, Jindong Wang, Manabu Okumura, and Takahiro Shinozaki. FlexMatch: Boosting semi- supervised learning with curriculum pseudo labeling. In NeurIPS, volume 34, pages 18408-18419, 2021.
- [Zheng et al., 2022] Mingkai Zheng, Shan You, Lang Huang, Fei Wang, Chen Qian, and Chang Xu. Simmatch: Semi-supervised learning with similarity matching. In CVPR, pages 14471-14481, 2022.
- [Zheng et al., 2023] Mingkai Zheng, Shan You, Lang Huang, Chen Luo, Fei Wang, Chen Qian, and Chang Xu. SimMatchV2: Semi-supervised learning with graph con- sistency. In ICCV, pages 16432-16442, 2023.
- [Zhou et al., 2020] Tianyi Zhou, Shengjie Wang, and Jeff Bilmes. Time-consistent self-supervision for semi- supervised learning. In ICML, pages 11523-11533, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Deep learning image classifiers typically depend on a considerable amount of labeled data, encountering performance limitations as the dataset scale increases. In contrast, semisupervised learning (SSL) [Lee, 2013; Rasmus et al., 2015] leverages both limited labeled data and a substantial pool of unlabeled data, achieving performance comparable to or even surpassing fully-supervised methods with fewer labels.
Most existing SSL methods utilize two key strategies: pseudo supervision and consistency regularization. FixMatch [Sohn et al., 2020] effectively combines these strategies. It utilizes weak augmented view to generate pseudolabels that serve as guidance for the prediction of strong augmented view. FlexMatch [Zhang et al., 2021], FreeMatch [Wang et al., 2023], and SoftMatch [Chen et al., 2023] primarily focus on improving the quality and quantity of pseudolabels. These methods center on pseudolabel selection and leverage confidence metrics to assess uncertainty, labeling samples only when confidence surpasses a predefined threshold. Additionally, variants such as MixMatch [Berthelot et al., 2019b] and ReMixMatch [Berthelot et al., 2019a] delve into generating numerous novel samples through diverse data augmentation techniques, intending to introduce noise and transformations for enhanced model robustness.
∗Corresponding Author.
Our motivation does not focus on pseudolabel selection strategies and data augmentation techniques. Instead, we aim to efficiently exploit the potential of unlabeled data by adapting the entropy neural estimation from unsupervised representation learning [Hjelm et al., 2019; Tian et al., 2023]. The fundamental principle is to maximize the lower bound of mutual information between two augmented views [Nowozin et al., 2016; Belghazi et al., 2018; Hjelm et al., 2019; Tian et al., 2023]. These infomax approaches leverage all available unlabeled data, allowing the model to delve deeper into the inherent structure and patterns of the data, ultimately improving classification accuracy. We generate two strong augmentation views for all unlabeled data, utilizing the mutual information between these views as a lower bound on the dataset entropy. This strategy ensures the model consistently produces accurate output under varying input conditions, accurately capturing the most salient features of the data.
Another motivation of this paper is to improve classifier accuracy by approximating the posterior probability. The probability of a sample belonging to a class is determined by the posterior of the classifier. A neural classifier models its last layer using a softmax function as a parameterized posterior, meaning the classifier's predictive probability distribution approximates the ground-truth posterior distribution. We investigate the connection between posterior entropy and the likelihood function of its predictions. Our observation suggests that the upper bound of posterior entropy is effectively approximated by maximizing the softmax prediction's likelihood. This finding is critical for advancing model optimization, ensuring the predicted-probability distribution more accurately reflects the true distribution. We approximate the entropy of the ground-truth posterior. To apply the posterior entropy neural estimator to unlabeled samples, we employ pseudo supervision and weak-to-strong strategies in addition to the supervision loss of labeled data. We generate pseudolabels through a weak augmentation view, guiding the prediction of two strong augmented views. Additionally, we introduce CutMix [Yun et al., 2019] as a strong augmentation view to capture more non-deterministic target features.
In InfoMatch, we are motivated by two key objectives: estimating the entropy of the data and estimating the entropy of the ground-truth posterior. We propose a novel entropybased methodology that integrates a data entropy neural estimator with a posterior entropy neural estimator. This combination prompts the model to thoroughly explore the intrinsic structure defined by entropy, achieved by maximizing the mutual information between augmented views of all unlabeled data. Moreover, we make the crucial observation that the upper bound on posterior entropy is effectively approximated by maximizing the predicted softmax likelihood function. This insightful observation is applied to unlabeled data in our approach through weak-to-strong, pseudo-supervision, and CutMix strategies. By approximating these entropies through gradient descent, our method progressively captures information about unlabeled data and model characteristics. Since our method primarily focuses on information entropy estimations, we aptly name it InfoMatch. The extensive experimental results consistently validate the effectiveness of InfoMatch, especially in scenarios where labeled data is scarce. Our dual-entropy-based method stands as a robust solution for fully exploiting the potential of unlabeled data, providing valuable insights into both the data structure and the posterior probabilities, thereby enhancing the performance of semisupervised image classification.
The main contributions are summarized as follows: 1) Our proposed InfoMatch effectively exploit the potential of unlabeled data. 2) Leveraging multiple objectives, InfoMatch approximates the data entropy and the ground-truth posterior entropy. By utilizing strong-to-strong constrastive, weak-tostrong pseudo supervision, and CutMix strategies, we apply this approach to unlabeled data, enabling more efficient utilization of unlabeled data information. 3) Experiments across various semi-supervised learning benchmarks validate the superior performance of InfoMatch.
2 RelatedWorks
Semi-supervised learning is a crucial branch in the field of machine learning and computer vision. Its fundamental concept lies in utilizing the data distribution information latent in a substantial quantity of unlabeled samples to enhance learning performance when only a limited number of labeled samples are available. The main strategies behind SSL are pseudo supervision and consistency regularization.
Consistency regularization. Based on the smoothness assumption, consistency regularization suggests that minor perturbations applied to unlabeled samples does not result in substantial variations in their predictions. To ensure consistency, Π Model [Rasmus et al., 2015] introduces perturbations through data augmentation and dropout, aiming to maximize the similarity of predictions derived from two forward propagations of identical unlabeled sample. Temporal Ensembling [Samuli and Timo, 2017] employs a time series combination model to minimize the mean square error loss between current and historical predictions, thus streamlining forward reasoning. MeanTeacher [Tarvainen and Valpola, 2017] converts the exponential moving average of the prediction results into the model weight, penalizing the difference in predictions between student model and teacher model. In addition, Unsupervised Data Augmentation (UDA) [Xie et al., 2020] extends the data augmentation method and employs specific target data augmentation algorithms for specific tasks. In contrast, Pseudo Label [Lee, 2013] works by generating artificial labels for unlabeled data and performing fully-supervised training using both labeled and pseudolabeled data.
Holistic methods. Most SSL methods combine pseudo supervision with consistency regularization to improve performance. MixMatch [Berthelot et al., 2019b] leverages unlabeled data by integrating both consistency regularization and entropy minimization. Based on MixMatch, RemixMatch [Berthelot et al., 2019a] introduces two innovative strategies, distribution alignment and augmentation anchor, to enhance its robustness and accuracy. FixMatch [Sohn et al., 2020] which maintains the use of Augmentation Anchor, simplifies the number of strong augmemtations. To improve the accuracy of pseudolabels, a fixed high threshold is established to eliminate unreliable labels. To alleviate class imbalance and address the issue of low utilization of unlabeled data in the early stage, FlexMatch [Zhang et al., 2021] and FreeMatch [Wang et al., 2023] take the model's learning status and class learning difficulty into consideration to adaptively adjust the confidence threshold. SoftMatch [Chen et al., 2023] uses a truncated Gaussian function to assign weights to samples based on their confidence, addressing the inherent trade-off between the quantity and quality of pseudolabels.
Furthermore, methods such as CoMatch [Li et al., 2021], SimMatch [Zheng et al., 2022], and SimMatchV2 [Zheng et al., 2023] integrate graph-based learning methods into semisupervised image classification, jointly learning two representations, class probabilities and low-dimensional embeddings, of the training data.
Mixing augmentation. The two prevalent mixing methods for images are mixup [Zhang et al., 2018] and CutMix [Yun et al., 2019]. Mixup generates novel training samples by combining two images and their corresponding labels linearly, aiming to facilitate the model in learning smoother decision boundaries. Conversely, CutMix swaps segments of one image with those of another, updating the corresponding labels simultaneously to encourage the model to comprehend and leverage local information within the image. Interpolation consistency training [Verma et al., 2022], MixMatch [Berthelot et al., 2019b] and RemixMatch [Berthelot et al., 2019a] combine mixup with consistency regularization to expand the dataset by generating virtual "mixed" training samples, and utilize consistency regularization to ensure its generalization ability on mixed data. While FMixCutMatch [Wei et al., 2021] combines Fourier space-based data cutting and data mixing to augment both labeled and unlabeled samples, thereby enhancing its performance and generalization. Furthermore, [Ghorban et al., 2022] utilizes mixup and CutMix simultaneously, aiming to blend the semantic information of three images and introduce enhanced perturbations into the data. To further enhance its attention to local information and improve its sensitivity to diverse position cues, we employ CutMix [Yun et al., 2019] in InfoMatch.
3 Entropy Neural Estimation
We employ an independent and identically distributed (i.i.d.) training dataset denoted as X = Xl ∪ Xu, where Xl comprises labeled data pairs (xi, pi), ∀ i ∈ {1, . . . , nl}, and Xu consists of unlabeled data xi, ∀ i ∈ {nl + 1, . . . , nl + nu}. The sizes of labeled and unlabeled datasets are denoted by nl and nu, respectively, with nl ≪ nu, and the total dataset size is n = nl +nu. Here, each xi represents a data point, and pi corresponds to its ground-truth class label, represented using a one-hot encoding. C = {c1, . . . , ck} denotes the class set. If 1xi belongs to cj class, we have p(cj |xi) = pij = 1 .
We employ an encoder to generate a latent feature zi = [zij ] and define the posterior probability σ(cj |xi, θ) of xi belonging to the j-th class cj using a softmax function σ(·):
yij denotes the probability of xi belonging to the j-th class while pij = p(cj|xi) = 1 representing a one-hot encoding. It means that we model σ(cj |xi, θ) as an encoder to approximate the truth posterior pij = p(cj |xi) = 1.
According to the second term of the information bottleneck theory [Tishby et al., 1999], min I(X ; Y)-βI(Y; C), the neural network codes σ(cj|xi, θ) to close to p(cj|xi) . Here, I(·, ·) denotes the mutual information, and H(·) is the entropy.
Theorem 1. For an i.i.d. finite dataset (X, C), the approximation H(C|X ) ≃ - ln p(C|X ) holds .
Proof. Since xi are sampled i.i.d., p(c|xi) corresponds pointto-point with xi and is regarded as an i.i.d. set, the posterior is p(C|X) = ∏ni=1 p(c|xi) . Then the expectation with respect to p(x) is approximated by a finite sum over X , so that
Thus, the equation H(C|X ) ≃ - ln p(C|X ) holds.
3.1 Posterior Entropy Neural Estimation
Suppose that the ground-truth posterior is being generated from the unknown distribution p(c|xi) that we aim to model. We approximate p(c|xi) using the parametric probability distribution σ(c|x, θ),
where divkl denotes the Kullback-Leibler divergence. The left-hand side of Eq. (4) is independent of θ, and the righthand term is the negative log likelihood function for θ under the posterior distribution evaluated using the training dataset. Thus we see that minimizing Eq. (3) is equivalent to maximizing the likelihood function, i.e., minimizing this upper bound of the posterior entropy. For an i.i.d. finite dataset X , when approximating p(c|x) through a parametric distribution σ(c|x, θ), the following Lemma 1 holds:
Lemma 1. Maximizing the likelihood function is equivalent to minimizing the upper bound on the posterior entropy.
3.2 Data Entropy Neural Estimation
We approach H(X) by maximizing the mutual information of pairwise augmentation views of X [Oord et al., 2018; Belghazi et al., 2018; Ma et al., 2023]. Then, we have
Then, the mutual information between the two augmented views X (1) and X (2) is given by
where x(1) and x(2) are two augmented data points.
Following contrastive learning [Oord et al., 2018; Belghazi et al., 2018; Tian et al., 2023], the maximization of the mutual information between two views turns into a lower bound maximization problem. Then, the following Lemma 2 holds,
Lemma 2. Maximizing the mutual information between two augmentation views is equivalent to maximizing the lower bound of the entropy.
3.3 Entropy Estimation for SSL
We assume that both Xl and Xu share the same distribution as X , and implement an encoder to optimize it from two bounds.
Given the modeling of labeled data point (x, p) by the parameter θ to produce y = σ(cj|xi, θ), we encode all labeled data Xl, and the corresponding labeled data set is Cl. During the training process, we strive to align the predictive coding of InfoMatch with the ground-truth coding, which essentially means modeling yij to align closely with pij. In other words, we aim to approximate the entropy of the groundtruth posterior -lnp(C|X) with its negative log likelihood
-lnσ(C|X, θ). Referring to Lemma 1, the likelihood is
where pij is an element of nl × k matrix of ground-truth matrix P = [pij]. The loss is defined by taking the negative logarithm of the likelihood, resulting in the cross-entropy loss:
Referring to Lemma 2, we employ the strategy of contrastive learning by maximizing the lower bound of entropy for Xu . We choose Jensen-Shannon divergence over Kullback-Leibler divergence, following [Nowozin et al., 2016]. The lower bound Llower is derived from
where divjs represents the Jensen-Shannon divergence and d(·, ·) is the similarity score of pairwise logits.
Similar to [Hjelm et al., 2019; Tian et al., 2023], we employ the view-wise contrastive loss, i.e., Llower,
where P and N denote positive and negative sets, respectively, i.e., z(1) i and z(2) i are belong to positive pairs (i, i) ∈ P while z(1) i and z(2) j are negative pairs (i, j) ∈ N, ∀ i ̸= j.
4 InfoMatch
Utilizing a neural network σ(cj|xi, θ) to approximate the information entropy for semi-supervised image classification, we call our method InfoMatch. For each unlabeled data point x ∈ Xu, we conduct augmentation processing, creating one weak view, i.e., performing random flip, and two strong augmented views [Cubuk et al., 2020] represented by x′ , x(1) , and x(2) , respectively.
4.1 Minimize Upper Bound
In InfoMatch, neural networks aim to approximate the upper bound of posterior entropy by maximizing the likelihood.
According to Eq. (8), minimizing the cross entropy between the predicted-probability distribution and the groundtruth distribution amounts to minimizing the likelihood function. By employing optimization algorithms like gradient descent, InfoMatch is gradually steered away from the incorrect distribution towards the accurate one.
In practice, when dealing with labeled data, standard supervised learning which relies on cross-entropy loss is employed, and the corresponding loss function is designated as Llupper .
To incorporate unlabeled data into training, we utilize pseudo supervision and weak-to-strong strategies. Let the one-hot vector ˆ pi = [ˆ pij] represent the pseudolabel corresponding to the weak-view prediction y′i , the pseudosupervised loss function from weak to strong is given by:
where y(1) i and y(2) i correspond to the predictions for x(1) i and x(2) i , respectively, and M = [mij] is utilized to mask pseudolabels with confidence levels below a threshold.
Additionally, we use CutMix to generate a new strong augmentation view on the top of weak augmentation, aiming to create more challenging samples and compel InfoMatch to fully extract meaningful features. To enhance computational efficiency, we shuffle the dataset in batches and randomly select an image, denoted as x′r , at the corresponding position of x′i . Subsequently, these images are used to generate CutMix images in a one-to-one manner. Furthermore, we evaluate the quantity of semantic information retained from the original images within the CutMix images, according to the size of the region. Consequently, the CutMix image and its corresponding pseudolabel is expressed by:
where bη represents a random binary mask indicating where to exclude and incorporate information from two images, η denotes the area proportion of x′i in the mixed image, obtained by averaging the values of the binary matrix bη, and ⊙ performs element-wise multiplication. The loss for the CutMix image is given by
where the prediction of xci is yc i . By combining aforementioned losses, we obtain the upper bound of posterior entropy,
4.2 Maximize Lower Bound
InfoMatch effectively captures the mutual information between pairs of augmentation views derived from the original dataset. By Eq. (10), minimizing the contrast loss is synonymous with maximizing the mutual information between pairwise augmentation views, thereby compelling InfoMatch to delve into the inherent structure dictated by H(X). After multiple random augmentations, the distribution of augmentation views will gradually align with the distribution of the raw dataset, i.e., through multiple trainings with random augmentations of diverse samples, the neural network progressively approaches the information entropy of the original dataset.
Inspired by BYOL [Grill et al., 2020], we compute the contrastive loss by utilizing the positive pairs only, guaranteeing that samples of the same class are situated adjacent to each other in the embedding space. Furthermore, latent features often serve as covert structures or patterns derived from the data, offering a deeper understanding of the relationships within the data than merely predicting probability distributions. Consequently, we utilize the mutual information between the latent features corresponding to the two augmented views to approximate the lower bound of entropy.
The similarity d(·, ·) of positive logits is defined by the Gaussian function [Tian et al., 2023],
and the similarity defined in Eq. (16) implies that if any two logits are identical, the similarity is one; otherwise, it tends to zero as their distance increases significantly.
Algorithm 1 The InfoMatch algorithm.
Input: X = Xl ∪Xu, batch size nbl and nbu , parameter λ. Output: Optimal model parameters θ⋆ .
- 1: Initialization: epoch = 0, epochmax, and θ.
- 2: while epoch ≤ epochmax do
- 3: for mini-batch samples in X do
- 4: Obtain augmented images x′ , x(1) , x(2) and xc ;
- 5: Feed samples into model for forward propagation;
- 6: Calculate Llupper by Eq. (8);
- 7: Obtain the maskM for filtering pseudolabels;
- 8: Calculate Luupper and Lcupper by Eqs. (11) and (14);
- 9: Calculate Lupper = Llupper +Luupper +Lcupper
- 10: Calculate Llower by Eq. (17);
- 11: Calculate L = Lupper +λLlower
- 12: Update parameter θ by minimizing L;
- 13: epoch = epoch + 1;
- 14: end for
- 15: end while
Substituting Eq. (16) into Eq. (10), we obtain
4.3 InfoMatch Algorithm
We introduce an innovative semi-supervised image classification algorithm, called InfoMatch, which treats the classification task as an entropy approximation problem. For labeled data, we utilize the cross entropy loss function as an upper bound for posterior entropy. InfoMatch mainly focuses on effectively leveraging vast amounts of unlabeled data.
In InfoMatch algorithm, we initiate with pseudo supervision and weak-to-strong strategies. This allows us to transform the entropy upper bound into pseudo-supervised cross entropy loss, serving as a supervisory signal for unlabeled data. Furthermore, to enrich the diversity of our dataset, we introduce a new strong augmentation method, CutMix, that enhances its generalization capabilities by formulating corresponding loss. Subsequently, we consider the potential feature contrastive loss between the two augmented views as a lower bound for dataset entropy. By maximizing this lower bound and minimizing the upper bound, we gradually optimize InfoMatch, even when limited labeled data is available.
The overall objective function incorporates the three crossentropy losses of Eq. (15) and contrastive loss of Eq. (17),
where λ serves as a non-negative hyperparameter, regulating the relative influence of the upper and lower bounds. During the experiment, we employ mini-batches for training, utilizing both labeled and unlabeled samples with batch sizes of nbl and nbu , respectively. Algorithm 1 offers a comprehensive overview of the learning process.
5 Experimental Results
5.1 Experimental Setup
We evaluate InfoMatch on well-known benchmark datasets, including CIFAR-10/100 [Krizhevsky and Hinton, 2009], SVHN [Netzer et al., 2011], STL-10 [Coates et al., 2011], and ImageNet [Deng et al., 2009]. Additionally, we conduct experiments using varying amounts of labeled data.
To ensure a fair comparison, we follow the experimental setup as in FixMatch [Sohn et al., 2020] and FreeMatch [Wang et al., 2023]. Specifically, we employ standard stochastic gradient descent algorithm with cosine learning rate decay as the optimizer across all datasets, with an initial learning rate of 0.03 and a momentum of 0.9. For all experiments, we set the total number of iterations to 220 . InfoMatch performance is then evaluated using the EMA with a parameter of 0.999. Additionally, for ImageNet, we maintain a batch size of 128 for both labeled and unlabeled samples, i.e., nbl = nbu = 128, and utilize the ResNet-50 architecture [He et al., 2016]. While for other datasets, we adjust the batch sizes to nbl = 64 and nbu = 448, and employ the Wide ResNet variants, such as Wide ResNet-28-2 [Zagoruyko and Komodakis, 2016] and Wide ResNet-28-8 [Zhou et al., 2020].
To evaluate the impact of the two distinct terms of the loss Eq. (18) in InfoMatch, we introduce a non-negative hyperparameter λ. Then, we ensure an equitable representation of both real and pseudolabels in the likelihood function and maintain equilibrium between RandAugment [Cubuk et al., 2020] and CutMix [Yun et al., 2019]. Subsequently, we adjust the parameter λ that regulates the entropy bounds to 0.002.
In addition, we employ distinct threshold selection strategies to eliminate the impact of pseudolabel errors on InfoMatch. For SVHN, we adopt a fixed threshold of 0.95. Conversely, for other datasets, we utilize the self-adaptive thresholding method proposed by FreeMatch, which measures the overall learning progress by utilizing the expectation of the highest confidence across all unlabeled data in the current batch as the global threshold and assess the class-specific learning status by calculating the average prediction probabilities corresponding to each class.
Finally, to guarantee a precise and unbiased evaluation, we conduct multiple training sessions for each model using various random seeds and calculate the mean and standard deviation of the optimal accuracy achieved.
5.2 Main Results
We compare InfoMatch with full-supervised learning method and a range of representative semi-supervised learning methods, including pseudolabel-based methods such as FlexMatch [Zhang et al., 2021] and FreeMatch [Wang et al., 2023], as well as graph-based methods like SimMatch[Zheng et al., 2022] and SimMatchV2 [Zheng et al., 2023]. The Top1 error rates for CIFAR-10/100, SVHN, and STL-10 under various labeled data sizes are presented in Tables 1 and 2.
Based on these results, it is evident that InfoMatch exhibits superior performance across all benchmarks, enhancing performance by an average of 1.49%, 0.55%, 0.13%, and 2.12% on the four datasets. In particular, InfoMatch impressively lower the mean Top-1 error rate from 8.07% to 4.39% (-3.68%) in the CIFAR-10 dataset, which contains just 10 labeled data. While in in the STL-10 dataset with 40 labeled data, the Top-1 error rate is reduces from 13.74% to 9.86% ( -3.88%). Additionally, on both CIFAR-10 and SVHN datasets, our approach achieves remarkable performance improvements, surpassing not only other semi-supervised baselines but also outperforming fully-supervised learning methods across all benchmarks. Furthermore, comparing to other methods, InfoMatch exhibits a smaller standard deviation across multiple experiments with varying seeds, thereby highlighting the superior stability and robustness of InfoMatch.
| Dataset | CIFAR-10 | CIFAR-100 | |||
|---|---|---|---|---|---|
| # Label | 10 | 40 | 250 | 4000 | 10000 |
| ΠModel [Rasmus et al., 2015] | 79.18 ±1.11 | 74.34 ±1.76 | 46.24 ±1.29 | 13.13 ±0.59 | 36.65 ±0.00 |
| Pseudo Label [Lee, 2013] | 80.21 ±0.55 | 74.61 ±0.26 | 46.49 ±2.20 | 15.08 ±0.19 | 36.55 ±0.24 |
| VAT [Miyato et al., 2018] | 79.81 ±1.17 | 74.66 ±2.12 | 41.03 ±1.79 | 10.51 ±0.12 | 32.14 ±0.19 |
| MeanTeacher [Tarvainen and Valpola, 2017] | 76.37 ±0.44 | 70.09 ±1.60 | 37.46 ±3.30 | 8.10 ±0.21 | 31.75 ±0.23 |
| MixMatch [Berthelot et al., 2019b] | 65.76 ±7.06 | 36.19 ±6.48 | 13.63 ±0.59 | 6.66 ±0.26 | 27.78 ±0.29 |
| ReMixMatch [Berthelot et al., 2019a] | 20.77 ±7.48 | 9.88 ±1.03 | 6.30 ±0.05 | 4.84 ±0.01 | 20.02 ±0.27 |
| UDA [Xie et al., 2020] | 34.53 ±10.69 | 10.62 ±3.75 | 5.16 ±0.06 | 4.29 ±0.07 | 22.49 ±0.23 |
| FixMatch [Sohn et al., 2020] | 24.79 ±7.65 | 7.47 ±0.28 | 4.86 ±0.05 | 4.21 ±0.08 | 22.20 ±0.12 |
| Dash [Xu et al., 2021] | 27.28 ±14.09 | 8.93 ±3.11 | 5.16 ±0.23 | 4.36 ±0.11 | 21.88 ±0.07 |
| MPL [Pham et al., 2021] | 23.55 ±6.01 | 6.62 ±0.91 | 5.76 ±0.24 | 4.55 ±0.04 | 21.74 ±0.09 |
| FlexMatch [Zhang et al., 2021] | 13.85 ±12.04 | 4.97 ±0.06 | 4.98 ±0.09 | 4.19 ±0.01 | 21.90 ±0.15 |
| FreeMatch [Wang et al., 2023] | 8.07 ±4.24 | 4.90 ±0.04 | 4.88 ±0.18 | 4.10 ±0.02 | 21.68 ±0.03 |
| CoMatch [Li et al., 2021] | - | 6.91 ±1.39 | 4.91 ±0.33 | 4.27 ±0.12 | 22.11 ±0.22 |
| SimMatch [Zheng et al., 2022] | - | 5.60 ±1.37 | 4.84 ±0.39 | 3.96 ±0.01 | 20.58 ±0.11 |
| SimMatchV2 [Zheng et al., 2023] | - | 4.90 ±0.16 | 5.04 ±0.09 | 4.33 ±0.16 | 21.37 ±0.20 |
| InfoMatch | 4.39 ±0.22 | 4.22 ±0.14 | 4.01 ±0.07 | 3.29 ±0.08 | 19.47 ±0.56 |
| Fully-Supervised | 4.62 ±0.05 | 19.30 ±0.09 | |||
It is worth noting that InfoMatch significantly outperforms other methods when the number of labeled data is extremely limited. Especially in the CIFAR-10 dataset, even when only one labeled data is available for each class, the average Top-1 error rate reachs 4.39%, which is lower than that of fullysupervised learning methods (-0.23%).
We assess InfoMatch on ImageNet to show its efficacy. Following the settings of FreeMatch, we select 100 labeled samples per class. Table 3 illustrates a comparison of the average Top-1 and Top-5 errors across different models. With identical parameters, InfoMatch has a significant improvement of 4.49% in Top-1 accuracy and 2.86% in Top-5 accuracy over FreeMatch.
5.3 Ablation Study
InfoMatch primarily explores how to utilize of unlabeled data, where we use the weak-to-strong supervision based on two strong augmentation methods, RandAugment [Cubuk et al., 2020] and CutMix [Yun et al., 2019], represented by Luupper and Lcupper respectively, as well as the contrastive loss Llower between two strong augmented views. To evaluate the impact of these losses, we conduct in-depth ablation studies on the CIFAR-10 dataset with 40 labels.
To determine the effectiveness of each loss term, we conduct experiments by excluding some components. As shown in Fig. 1, Results indicate that eliminating certain losses lead to different levels of decline in model performance. This suggests that each component is important and complementary.
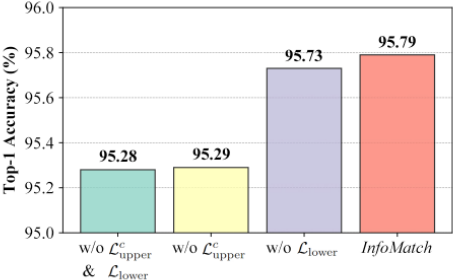
Comparing to RandAugment [Cubuk et al., 2020], CutMix [Yun et al., 2019] employs a stronger augmentation by combining two images, addressing the limitations of low mask-based augmentation ratio. This approach enables InfoMatch to more effectively comprehend and capture the essential features, thus enhancing the generalization performance of InfoMatch. However, utilizing CutMix exclusively may distort the original features, potentially leading InfoMatch to learning incorrect or distorted features during training, ultimately resulting in performance deterioration.
By minimizing Llower, we optimize InfoMatch from a different perspective. InfoMatchmaximizes themutual information between features in different augmented views, enabling InfoMatch to learn feature representations that express the same information from different perspectives. Consequently, the performance of InfoMatch is further improved.
| Dataset | SVHN | STL-10 | |||
|---|---|---|---|---|---|
| # Label | 40 | 250 | 1000 | 40 | 1000 |
| ΠModel [Rasmus et al., 2015] Pseudo Label [Lee, 2013] VAT [Miyato et al., 2018] MeanTeacher [Tarvainen and MixMatch [Berthelot et al., 2019b] ReMixMatch [Berthelot et al., UDA [Xie et al., 2020] FixMatch [Sohn et al., 2020] Dash [Xu et al., 2021] MPL [Pham et al., 2021] FlexMatch [Zhang et al., 2021] FreeMatch [Wang et al., 2023] CoMatch [Li et al., 2021] SimMatch [Zheng et al., 2022] SimMatchV2 [Zheng et al., 2023] | 67.48 ±0.95 64.61 ±5.6 74.75 ±3.38 36.09 ±3.98 30.60 ±8.39 24.04 ±9.13 5.12 ±4.27 3.81 ±1.18 2.19 ±0.18 9.33 ±8.02 8.19 ±3.20 1.97 ±0.02 8.20 ±5.32 7.60 ±2.11 | 13.30 ±1.12 15.59 4.33 ±0.12 3.45 ±0.03 4.56 ±0.32 6.36 ±0.22 1.92 ±0.05 2.02 ±0.02 2.04 ±0.02 2.29 ±0.04 6.59 ±2.29 1.97 ±0.01 2.16 ±0.04 2.48 ±0.61 | 7.16 ±0.11 9.40 4.11 3.27 3.69 5.16 1.89 ±0.01 1.96 1.97 | 74.31 ±0.85 74.68 ±0.99 74.74 ±0.38 71.72 ±1.45 54.93 ±0.96 32.12 ±6.24 37.42 ±8.44 35.97 ±4.14 34.52 ±4.30 35.76 ±4.83 29.15 ±4.16 15.56 ±0.55 13.74 ±4.20 16.98 ±4.24 | 32.78 ±0.40 32.64 ±0.71 37.95 ±1.12 33.90 ±1.37 21.70 ±0.68 6.74 ±0.14 6.64 ±0.17 6.25 ±0.33 6.39 ±0.56 6.66 ±0.00 |
| ±0.95 | ±0.32 | ||||
| ±0.20 | |||||
| Valpola, 2017] | ±0.05 | ||||
| ±0.37 | |||||
| 2019a] | ±0.31 | ||||
| ±0.03 | |||||
| ±0.01 | |||||
| 2.28 ±0.02 | |||||
| 6.72 ±0.30 | 5.77 ±0.18 | ||||
| 1.96 ±0.03 | 5.63 ±0.15 | ||||
| 2.01 ±0.04 | 5.71 ±0.08 | ||||
| 2.05 ±0.05 | 5.74 ±0.31 | ||||
| 7.92 ±2.80 | 2.92 ±0.81 | 2.85 ±0.91 | 15.85 ±2.62 | 5.65 ±0.26 | |
| InfoMatch | 1.84 ±0.07 | 1.79 ±0.01 | 1.75 ±0.03 | 9.86 ±1.13 | 5.27 ±0.09 |
| Fully-Supervised | 2.13 ±0.01 | - | |||
| Method | Top-1 | Top-5 |
|---|---|---|
| FixMatch [Sohn et al., 2020] | 43.66 | 21.80 |
| FlexMatch [Zhang et al., 2021] | 41.85 | 19.48 |
| FreeMatch [Wang et al., 2023] | 40.57 | 18.77 |
| InfoMatch | 36.21 | 15.91 |
5.4 Qualitative Analysis
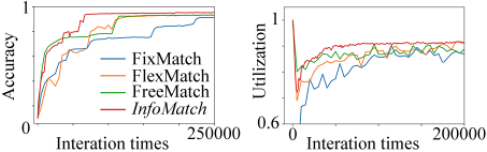
To further evaluate the performance of InfoMatch in classification tasks, we conduct a comparative analysis with FixMatch, FlexMatch, and FreeMatch in terms of Top-1 accuracy and utilization of unlabeled data. This analysis is conducted using the CIFAR-10 dataset with 40 labeled data.
Initially, a noteworthy advantage of InfoMatch is its excellent convergence speed, which is illustrated in Fig. 2(a). Within 100 epochs, InfoMatch achieves a 94.70% accuracy rate. By the time it reaches 200 epochs, our accuracy even exceeds the highest accuracy achieved by FreeMatch, reaching 95.49%. Additionally, as shown in Fig. 2(b), in contrast to other methods, the utilization rate of unlabeled data in InfoMatch quickly rises to and stabilizes above 90% after a brief decline, further encouraging InfoMatch to incorporate more unlabeled samples into training during the early stages.
6 Conclusion
We present an extension of the entropy neural estimation method to the semi-supervised domain, enabling to measure the uncertainty of classification models from an entropy perspective. We introduce an upper bound on the entropy of the ground-truth posterior, indicating that maximizing the likelihood function of InfoMatch corresponds to minimizing the upper bound on the posterior entropy. Similarly, we establish a lower bound on entropy for a given dataset, demonstrating that maximizing the mutual information between different augmented views of the data aligns with maximizing the lower bound of entropy. Drawing upon these two theories, we introduce InfoMatch to optimize it from two perspectives. To leverage unlabeled data more effectively, we employ strategies like weak-to-strong and pseudo supervision, and introduce CutMix as a new strong augmentation view. Using optimization methods such as gradient descent, InfoMatch ensures that its predicted probability distribution gradually aligns with the ground-truth distribution, even in the presence of input perturbations. We introduce InfoMatch that seamlessly integrates pseudo supervision, consistency regularization, and mixing strategies to improve its generalization capabilities. The results from various SSL benchmark tests demonstrate that InfoMatch achieves good performance, especially in scenarios with limited labels, surpassing even fully-supervised learning methods. The experimental results confirm the effectiveness of InfoMatch.
Acknowledgements
This work was supported by the National Natural Science Foundation of China under Grant No. 62176108 , Natural Science Foundation of Qinghai Province of China under No. 2022-ZJ-929, Fundamental Research Funds for the Central Universities under No. lzujbky-2022-ct06, and Supercomputing Center of Lanzhou University. The corresponding author of the paper is Kun Zhan.
@inproceedings{ijcai2024p452,
  title     = {InfoMatch: Entropy Neural Estimation for Semi-Supervised Image Classification},
  author    = {Han, Qi and Tian, Zhibo and Xia, Chengwei and Zhan, Kun},
  booktitle = {Proceedings of the Thirty-Third International Joint Conference on
               Artificial Intelligence, {IJCAI-24}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Kate Larson},
  pages     = {4089--4097},
  year      = {2024},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2024/452},
  url       = {https://doi.org/10.24963/ijcai.2024/452},
}
TY - CPAPER TI - InfoMatch: Entropy Neural Estimation for Semi-Supervised Image Classification AU - Han, Qi AU - Tian, Zhibo AU - Xia, Chengwei AU - Zhan, Kun T2 - Proceedings of the Thirty-Third International Joint Conference on Artificial Intelligence, IJCAI-24 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2024 SP - 4089 EP - 4097 DO - 10.24963/ijcai.2024/452 UR - https://doi.org/10.24963/ijcai.2024/452 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





