
Leveraging Argumentation for Generating Robust Sample-based Explanations
Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence. Main Track. Pages 3104-3111.
https://doi.org/10.24963/ijcai.2023/346
Keywords
- AI Ethics, Trust, Fairness: ETF: Explainability and interpretability
- Knowledge Representation and Reasoning: KRR: Argumentation
Abstract
Explaining predictions made by inductive classifiers has become crucial with the rise of complex models acting more and more as black-boxes.
Abductive explanations are one of the most popular types of explanations that are provided for the purpose. They highlight feature-values that
are sufficient for making predictions. In the literature, they are generated by exploring the whole feature space, which is unreasonable in practice.
This paper solves the problem by introducing explanation functions that generate abductive explanations from a sample of instances. It shows
that such functions should be defined with great care since they cannot satisfy two desirable properties at the same time, namely existence of
explanations for every individual decision (success) and correctness of explanations (coherence). The paper provides a parameterized family of
argumentation-based explanation functions, each of which satisfies one of the two properties. It studies their formal properties and their experimental
behaviour on different datasets.
- [Amgoud and Ben-Naim, 2022] Leila Amgoud and Jonathan Ben-Naim. Axiomatic foundations of explain- ability. In Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI, pages 636-642, 2022.
- [Amgoud, 2021a] Leila Amgoud. Explaining black-box classification models with arguments. In 33rd IEEE Inter- national Conference on Tools with Artificial Intelligence, ICTAI, pages 791-795, 2021.
- [Amgoud, 2021b] Leila Amgoud. Non-monotonic explana- tion functions. In Proceedings of the 16th European Con- ference on Symbolic and Quantitative Approaches to Rea- soning with Uncertainty, ECSQARU, pages 19-31, 2021.
- [Audemard et al., 2022] Gilles Audemard, Steve Bellart, Louenas Bounia, Frédéric Koriche, Jean-Marie Lagniez, and Pierre Marquis. On preferred abductive explanations for decision trees and random forests. In Proceedings of the Thirty-First International Joint Conference on Artifi- cial Intelligence, IJCAI, pages 643-650, 2022. IJCAI
- [Borg and Bex, 2021] AnneMarie Borg and Floris Bex. Nec- essary and sufficient explanations for argumentation-based conclusions. In Symbolic and Quantitative Approaches to Reasoning with Uncertainty -16th European Conference, pages 45-58, 2021.
- [Burkart and Huber, 2021] Nadia Burkart and Marco F. Hu- ber. A survey on the explainability of supervised ma- chine learning. Journal of Artificial Intelligence Research, 70:245-317, 2021.
- [Cocarascu et al., 2020] Oana Cocarascu, Andria Stylianou, Kristijonas Cyras, and Francesca Toni. Data-empowered argumentation for dialectically explainable predictions. In 24th European Conference on Artificial Intelligence ECAI, volume 325, pages 2449-2456. IOS Press, 2020.
- [Cooper and Marques-Silva, 2021] Martin C. Cooper and João Marques-Silva. On the tractability of explaining de- cisions of classifiers. In CP 2021, pages 21:1-21:18, 2021.
- [Cyras et al., 2019a] Kristijonas Cyras, David Birch, Yike Guo, Francesca Toni, Rajvinder Dulay, Sally Turvey, Daniel Greenberg, and Tharindi Hapuarachchi. Explana- tions by arbitrated argumentative dispute. Expert Systems with Applications, 127:141-156, 2019.
- [Cyras et al., 2019b] Kristijonas Cyras, Dimitrios Letsios, Ruth Misener, and Francesca Toni. Argumentation for ex- plainable scheduling. In The Thirty-Third Conference on Artificial Intelligence, AAAI, pages 2752-2759, 2019.
- [Darwiche and Hirth, 2020] Adnan Darwiche and Auguste Hirth. On the reasons behind decisions. In 24th Euro- pean Conference on Artificial Intelligence ECAI, volume 325, pages 712-720. IOS Press, 2020.
- [Dimopoulos et al., 1997] Yannis Dimopoulos, Saso Dze- roski, and Antonis Kakas. Integrating explanatory and de- scriptive learning in ILP. In Proceedings of the Fifteenth International Joint Conference on Artificial Intelligence, IJCAI, pages 900-907, 1997. IJCAI
- [Dung, 1995] Phan Minh Dung. On the Acceptability of Arguments and its Fundamental Role in Non-Monotonic Reasoning, Logic Programming and n-Person Games. Ar- tificial Intelligence, 77:321-357, 1995.
- [Ignatiev et al., 2019a] Alexey Ignatiev, Nina Narodytska, and Joao Marques-Silva. Abduction-based explanations for machine learning models. In National Conference on Artificial Intelligence, pages 1511-1519, 2019.
- [Ignatiev et al., 2019b] Alexey Ignatiev, Nina Narodytska, and Joao Marques-Silva. On relating explanations and ad- versarial examples. In Conference on Neural Information Processing Systems, pages 15857-15867, 2019.
- [Kakas and Riguzzi, 2000] Antonis Kakas and Fabrizio Riguzzi. Abductive concept learning. New Generation Computing, 18(3):243-294, 2000.
- [Liao and van der Torre, 2020] Beishui Liao and Leendert van der Torre. Explanation semantics for abstract argu- mentation. In Computational Models of Argument, volume 326 of Frontiers in Artificial Intelligence and Applications, pages 271-282. IOS Press, 2020.
- [Narodytska et al., 2019] Nina Narodytska, Aditya A. Shrotri, Kuldeep S. Meel, Alexey Ignatiev, and João Marques-Silva. Assessing heuristic machine learning explanations with model counting. In 22nd International Conference on Theory and Applications of Satisfiability Testing, pages 267-278, 2019.
- [Rago et al., 2018] Antonio Rago, Oana Cocarascu, and Francesca Toni. Argumentation-based recommendations: Fantastic explanations and how to find them. In Proceed- ings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI, pages 1949-1955, 2018. IJCAI
- [Rahwan and Simari, 2009] Iyad Rahwan and Guillermo Simari, editors. Argumentation in Artificial Intelligence. Springer, 2009.
- [Ribeiro et al., 2016] Marco Túlio Ribeiro, Sameer Singh, and Carlos Guestrin. Why should itrust you?: Explain- ing the predictions of any classifier. In Proceedings of the 22nd ACM SIGKDD International Conference on Knowl- edge Discovery and Data Mining, page 1135-1144, 2016.
- [Ribeiro et al., 2018] Marco Túlio Ribeiro, Sameer Singh, and Carlos Guestrin. Anchors: High-precision model- agnostic explanations. In Proceedings of the Thirty- Second Conference on Artificial Intelligence, pages 1527- 1535, 2018.
- [Shih et al., 2018] Andy Shih, Arthur Choi, and Adnan Dar- wiche. A symbolic approach to explaining Bayesian net- work classifiers. In Proceedings of the Twenty-Seventh In- ternational Joint Conference on Artificial Intelligence, IJ- CAI, pages 5103-5111, 2018. IJCAI
- [Zhong et al., 2019] Qiaoting Zhong, Xiuyi Fan, Xudong Luo, and Francesca Toni. An explainable multi-attribute decision model based on argumentation. Expert Systems with Applications, 117:42-61, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recent advances in many AI fields rely on inductive models, depending on parameters that are adjusted based on a set of training instances. Such models tend to be large for practical tasks, in the sense of having a lot of parameters, and may allow for non-linear interactions between input features. Consequently, they are perceived as black-boxes whose behaviour is difficult to grasp both from their designers and users' point of view. This opacity has sparked a new sub-field of AI, explainable AI (XAI), whose approaches provide ways to explain what black-box models do and why they do it (see [Burkart and Huber, 2021] for a recent survey on XAI).
One of the most studied types of explanation is the socalled abductive explanations, which highlight feature-values that are sufficient for making a given prediction. For example, a client was refused a loan because he is unemployed. Such explanations are generally generated from the whole feature space (eg., [Darwiche and Hirth, 2020; Ignatiev et al., 2019b; Audemard et al., 2022; Amgoud, 2021a]). While the approach is reasonable when models are interpretable, like Decision Trees or Random Forests, it is not tractable in case of black-boxes (see [Cooper and Marques-Silva, 2021]) as it requires an exhaustive exploration of the feature space.
As a solution, the two prominent explanation functions Anchors [Ribeiro et al., 2018] and LIME [Ribeiro et al., 2016] and the argument-based function [Amgoud, 2021b] generate abductive explanations from a sample (i.e., subset) of instances, avoiding thus exploring the whole feature space. However, it has been shown in [Amgoud, 2021b; Narodytska et al., 2019] that the explanations of Anchors/LIME may be globally inconsistent and thus incorrect. The third function ensures correct explanations but does not guarantee the existence of explanations for every instance. Furthermore, it is very cautious as it simply removes all conflicting explanations that may be generated from the considered sample.
This paper investigates explanation functions that generate abductive explanations from a subset of feature space while satisfying desirable properties. Its contributions are fourfold:
The first consists of proving an impossibility result, which states that a function that generates abductive explanations from a subset of instances cannot guarantee both existence of explanations (success) and their correctness (coherence). This result sheds light on the reason behind violation of success by the argument-based function from [Amgoud, 2021b].
The second contribution consists of a parameterized family of argumentation-based explanation functions, each of which satisfies one of the two incompatible properties. The approach starts by generating arguments in favour of classes, identifies attacks among them, uses stable semantics [Dung, 1995] for generating sets of arguments that can be jointly accepted, identifies accepted arguments, and uses the latter for defining the novel types of abductive explanations. Accepted arguments are defined in our approach using two parameters: selection function and inference rule. The former selects a subset of stable extensions and the latter selects (accepted) arguments from the chosen extensions. We define various instantiations of the two parameters, capturing different criteria for solving conflicts between arguments.
The third contribution is a formal analysis and a comprehensive comparison of the new functions. We show that the family encompasses the argument-based function, however the new functions that ensure correctness of explanations perform better as they explain more instances and more classes.
The fourth contribution is an experimental analysis of the functions on various datasets. The results confirm that abductive explanations that are generated from datasets (as done by Anchors) are generally incorrect. They show also that the new functions which guarantee correctness perform well as they explain quite an important proportion of instances.
The paper is organized as follows: Section 2 gives some background, Section 3 defines plausible explanations, Section 4 presents two desirable properties and shows their incompatibility, Section 5 defines the novel family of argumentation-based functions, and studies their properties, Section 6 presents the first experimental results, Section 7 is devoted to related work, and the last section concludes.
2 Preliminaries
Throughout the paper, we consider a classification theory as a tuple made of a finite set of features, a function which returns the domain of every feature and a finite set of classes.
Definition 1 (Theory). A theory is a tuple T = 〈F, D, C〉 s.t.
- F is a finite set of features,
- D is a function on F such that, for every f ∈ F, D(f) is countable (discrete domains),
- C is a finite set of possible distinct classes with |C| > 1.
We introduce next the useful notion of literal.
Definition 2 (Literal). Let T = 〈F, D, C〉 be a theory. A literal is a pair (f, v) where f ∈ F and v ∈ D(f). Let Lit(T) denote the set of all possible literals of T.
A set of literals is consistent if it does not contain two literals having the same attribute but distinct values.
Definition 3 (Consistency). A set L ⊆ Lit(T) is consistent iff ∄(f, v), (f ′ , v′ ) ∈ L such that f = f ′ and v ̸= v′ . Otherwise, L is said to be inconsistent.
We call instance any assignment of values to all features.
Definition 4 (Instance). Let T = 〈F, D, C〉 be a theory. An instance is a subset I of literals such that every attribute f ∈ F appears exactly once in I. Let IT denote the set of all instances of T, called feature space.
A classification model, or classifier, is a surjective function mapping every instance into a single prediction.
Definition 5 (Classifier). Let T = 〈F, D, C〉 be a theory. A classifier on T is a surjective function R from IT to C.
An explanation function answers questions of the form: why does classifier R assign class c to instance x? One of the most studied types of reasons in the AI literature for a long time is abductive explanations (eg., [Dimopoulos et al., 1997; Kakas and Riguzzi, 2000]). More recently, they have been used for interpreting classifiers (eg., [Shih et al., 2018; Ignatiev et al., 2019a; Darwiche and Hirth, 2020]). An abductive explanation is defined as a subset-minimal set of literals that is sufficient for predicting the class of an instance.
Definition 6 (Abductive Explainer). Let R be a classifier and T a theory. An abductive explainer is a function ga mapping every I ∈ IT into the set of any L verifying the following: a) L ⊆ I,
- ∀I ′ ∈ IT \ {I} such that L ⊆ I ′ , R(I ′ ) = R(I),
- ∄L′ ⊂ L such that L′ satisfies the above conditions.
- The set of literals L is called abductive explanation.
Every instance may have one or several abductive explanations as shown in the following example.
| I(T) | f1 | f2 | R(Ii) |
|---|---|---|---|
| I1 | 0 | 0 | c1 |
| I2 | 0 | 1 | c2 |
| I3 | 1 | 0 | c3 |
| I4 | 1 | 1 | c3 |
The abductive explanations of I1, I2, I3, I4 are given below.
- ga(I1) = {L1} L1 = {(f1, 0), (f2, 0)}
- ga(I2) = {L2} L2 = {(f1, 0), (f2, 1)}
- ga(I3) = ga(I4) = {L3} L3 = {(f1, 1)}
The condition b) in the above definition states that generating an abductive explanation for the prediction of an instance requires testing a set L of literals on the whole feature space, especially when the classifier R is a black-box. This is not reasonable due to the huge size of the feature space in practice, and the complexity of querying black-box classifiers like deep neural networks. Indeed, it has been shown in [Cooper and Marques-Silva, 2021] that the complexity of finding one abductive explanation in case of black-box classifiers is co-NPcomplete. In what follows we propose an alternative solution, which consists of testing L only on a subset of instances.
3 Plausible Abductive Explanations
In the remaining of the paper, we assume fixed but arbitrary theory T = 〈F, D, C〉 and black-box classifier R. We also consider a sample Y ⊆ IT of the feature space. This set may represent a dataset on which R is trained or may be generated in specific ways. Whatever its source, it should satisfy a property stating that every class in C should be represented in Y (i.e., ∀c ∈ C, ∃I ∈ Y such that R(I) = c). This condition ensures a quite well-balanced sample. Furthermore, as we will show later, explanations generated from a sample are approximations of those generated from the feature space. Hence, the condition increases the quality of approximations. We call the latter plausible abductive explanations.
Definition 7 (Plausible Explainer). Let R be a classifier, T a theory, Y ⊆ IT. A plausible explainer is a function gp mapping every I ∈ Y into the set of any L verifying the following:
- L ⊆ I,
- ∀I ′ ∈ Y \ {I} such that L ⊆ I ′ , R(I ′ ) = R(I),
- ∄L′ ⊂ L such that L′ satisfies the above conditions.
The set L is called plausible abductive explanation.
Let us illustrate the definition on an example.
Example 2. Let us consider the theory made of four binary features and three classes. Assume a classifier R which provides the predictions below for the seven instances in Y.
| Y | f0 | f1 | f2 | f3 | R(Ii) |
| I1 | 0 | 0 | 1 | 0 | c1 |
| I2 | 0 | 0 | 1 | 1 | c1 |
| I3 | 0 | 1 | 0 | 0 | c0 |
| I4 | 0 | 1 | 0 | 1 | c2 |
| I5 | 0 | 1 | 1 | 1 | c1 |
| I6 | 1 | 1 | 0 | 1 | c2 |
| I7 | 1 | 1 | 1 | 0 | c2 |
The function gp returns the following explanations.
We show 1 that every abductive explanation of an instance is a superset of a plausible explanation of the same instance. This shows that plausible explanations are approximations of and shorter than abductive ones.
The following example shows that the converse does not hold, i.e., a plausible explanation may not be the subset of any abductive explanation provided by the function ga.
Example 2 (Cont.) Assume that the prediction of the instance I8 ∈ IT below is R(I8) = c1.
| f0 f1 | f2 | f3 | R(I8) | |
|---|---|---|---|---|
| I8 | 1 1 | 0 | 0 | c1 |
Note that L1 ∈ gp(I3) while L1 cannot be a subset of an abductive explanation (i.e., L0 /∈ ga(I3)).
It is worth mentioning that generating one plausible explanation can be achieved in polynomial time. It depends simply on the number of instances in the sample and the number of features in the theory. While this gain is important, we show next that the plausible explainer suffers from a tricky issue.
4 Coherence vs Existence of Explanations
In [Amgoud and Ben-Naim, 2022], the authors introduced a set of principles for explanation functions that interpret the global behaviour of a classifier, i.e., those that explain classes instead of instances. Every principle is seen as a desirable property that should be satisfied. In what follows we adapt two of them to functions explaining instances from samples.
Definition 8. Let R be a classifier, T a theory and Y ⊆ IT. A refined plausible explainer is a function g mapping every I ∈ Y into g(I) ⊆ gp(I).
1 N.B. All proofs are listed in the technical annex because of space constraints.
The first principle, called success, states that any refined plausible explainer should return at least one explanation to every instance. It ensures feedback for end-users.
Principle 1. (Success) A refined plausible explainer g satisfies success iff for any classifier R, any theory T, any Y ⊆ IT, and any I ∈ Y, we have that g(I) ̸= ∅.
The second principle, called coherence, states that the explanations of instances labelled with different classes should be inconsistent. This property prevents the following three undesirable situations: Assume two instances I, I ′ ∈ Y such that R(I) ̸= R(I ′ ). Assume also that L is an explanation for I and L′ is an explanation for I ′ . We may have the following:
- L = L′ ,
- ii) L ⊂ L′ ,
- iii) L ̸⊆ L′ and L∪L′ is consistent.
It is clearly not reasonable to predict different classes on the basis of the same set of information (i), ii)). For the third case, assume L and L′ stand respectively for: Age ≤ 45, salary ≤ 50K and R(I) and R(I ′ ) stand for accepting and rejecting a loan respectively. The two explanations are incompatible since they both match a profile of a customer whose age is 30 and salary is 40K. The first rule states that this customer should have the loan while the second predicts rejection.
Principle 2. (Coherence) A refined plausible explainer g satisfies coherence iff for any classifier R, any theory T, any I, I ′ ∈ Y, if R(I) ̸= R(I ′ ), then ∀L ∈ g(I), ∀L′ ∈ g(I ′ ), L∪L′ is inconsistent.
It is well-known in the literature that the function ga provides at least one explanation for each instance in the theory's feature space. From Proposition 1, it follows that the same holds for the plausible explainer gp, thus gp satisfies success. Proposition 2. For any theory T, any Y ⊆ IT, any classifier R, and any I ∈ Y, gp(I) ̸= ∅.
The situation is different for the second principle. Indeed, the following example shows that the plausible explainer gp violates coherence, and may provide erroneous explanations.
Example 2 (Cont.) Consider the two instances I2 and I3. Note that R(I2) ̸= R(I3) while L5 ∈ gp(I2), L1 ∈ gp(I3) and L1 ∪L5 is consistent. Consequently, there exists I ′ ∈ IT such that L1 ∪ L5 ⊆ I ′ . Since I ′ has a single class, then at least one of the two explanations (L1,L5) is incorrect.
In what follows, we show that the two principles (success, coherence) are incompatible when explanations are generated from a dataset or more generally from a subset of instances. In other words, there is no (refined) plausible explainer that can satisfy the two principles at the same time for every classifier, every theory, and every subset of the feature space.
Theorem 1. There is no refined plausible explainer that satisfies both coherence and success.
To sum up, the previous result shows that generating abductive explanations from a subset of feature space is a tricky issue. A refined plausible explainer can either, like gp always guarantee explanations for every instance but they may be wrong, or provide correct explanations for only a subset of instances. The following section defines in a unified setting various functions for each of the two policies.
5 Parameterized Family of Explainers
Throughout this section we consider an arbitrary but fixed subset Y ⊆ IT of instances of theory T = 〈F, D, C〉. We define a novel parameterized family of refined explanation functions. The family is based on argumentation theory (see [Rahwan and Simari, 2009] on more on argumentation) and follows thus the following steps: it starts by generating arguments from Y, identifies attacks among them, uses a semantics for generating sets of arguments that can be jointly accepted, identifies accepted arguments, and uses the latter for defining novel types of abductive explanations.
In our approach, arguments support classes, in the sense that they provide minimal sets of literals that determine a class. They are thus independent from instances. An advantage of not considering instances is to reduce the number of arguments that can be built from Y. Furthermore, explanations of an instance are explanations of its predicted class.
Definition 9 (Argument). An argument built from Y is a pair 〈L, c〉 such that:
- L ⊆ Lit(T) and c ∈ C,
- ∃I ∈ Y such that L ⊆ I,
- ∀I ∈ Y such that L ⊆ I, R(I) = c,
- ∄L′ ⊂ L that verifies the above conditions.
L and c are called respectively support and conclusion of the argument. Arg(Y) denotes the set of arguments built from Y.
The second condition of the above definition ensures that arguments are extracted from instances of the set Y. It discards any fallacious argument whose support is not included in any instance of Y and thus satisfies the third condition in a vacuous way. The third condition states that the support L is correlated to the conclusion c.
Example 2 (Cont.) Eight arguments are generated from Y:
- a1 = 〈L1, c0〉 a2 = 〈L6, c0〉
- a3 = 〈L2, c1〉 a4 = 〈L5, c1〉 a5 = 〈L7, c1〉
- a6 = 〈L3, c2〉 a7 = 〈L4, c2〉 a8 = 〈L8, c2〉
Notice that the support of every argument is a plausible abductive explanation of one or more instances in Y. Before presenting the result, let us first introduce two notations.
Notations: Let E ⊆ Arg(Y). We denote by covi(E) the set of instances covered by E, ie., covi(E) = {I ∈ Y | ∃〈L, c〉 ∈ E and L ⊆ I}, and by covc(E) the set of classes covered by E, ie., covc(E) = {c ∈ C | ∃〈L, c〉 ∈ E}.
Proposition 3. The following properties hold.
- For every 〈L, c〉 ∈ Arg(Y), the set L is consistent,
- L ∈ ⋃ I∈Y gp(I) iff 〈L, c〉 ∈ Arg(Y),
- For every I ∈ Y, ∃〈L, R(I)〉 ∈ Arg(Y) such that L ⊆ I,
- covi(Arg(Y)) = Y,
- covc(Arg(Y)) = C iff {R(I) | I ∈ Y} = C,
- The set Arg(Y) is finite.
Arguments may be conflicting, particularly when they violate the coherence property, i.e., their supports are consistent but their conclusions are different.
Definition 10 (Attack). Let a = 〈L, c〉, a′ = 〈L′ , c′ 〉 ∈ Arg(Y). We say that a attacks a′ iff L ∪ L′ is consistent and c ̸= c′ . We denote by Att(a) the set of all attackers of a.
Property 1. The attack relation is symmetric and irreflexive.
Example 2 (Cont.) The attacks between the eight arguments are depicted in the figure below.
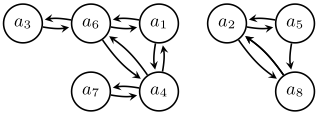
Arguments and their attack relations form an argumentation system as follows.
Definition 11 (Argumentation system). An argumentation system built from Y is a pair AS = 〈Arg(Y), R〉 where R ⊆ Arg(Y) × Arg(Y) such that for a, b ∈ Arg(Y), (a, b) ∈ R iff a attacks b (in the sense of Def. 10).
Since arguments are conflicting, they should be evaluated using a semantics. In this paper, we consider an extensionbased semantics introduced in [Dung, 1995], namely stable semantics. It computes sets of arguments that can be jointly accepted. Each set is called a stable extension and represents a set of compatible plausible explanations.
Definition 12 (Stable Semantics). Let AS = 〈Arg(Y),R〉 and E ⊆ Arg(Y).
- E is conflict-free iff ∄a, b ∈ E such that (a, b) ∈ R.
- E is a stable extension iff it is conflict-free and ∀a ∈ Arg(Y) \ E, ∃b ∈ E such that (b, a) ∈ R.
Let σ(AS) denote the set of all stable extensions of AS.
Example 2 (Cont.) The AS depicted in the above figure has nine stable extensions.
- E1 = {a1, a2, a3, a7} E2 = {a1, a3, a5, a7}
- E3 = {a1, a3, a7, a8} E4 = {a2, a3, a4}
- E5 = {a3, a4, a5} E6 = {a3, a4, a8}
- E7 = {a2, a6, a7} E8 = {a5, a6, a7} E9 = {a6, a7, a8}
An argumentation system has one stable extension if the attack relation is empty and multiple extensions otherwise.
Proposition 4. Let Y ⊆ IT and AS = 〈Arg(Y),R〉.
- σ(AS) ̸= ∅,
- σ(AS) = {Arg(Y)} iff R= ∅.
Let us now turn to the evaluation of individual arguments. Accepted arguments are defined in our approach using two parameters: selection function and inference rule. The former selects a subset of stable extensions and the latter selects arguments from the chosen extensions. We define various instantiations of the two parameters, capturing different criteria for solving conflicts between arguments.
Definition 13 (Selection Functions). Let Σ = {E1, . . . , Ek} such that for any i ∈ {1, . . . , k}, Ei ⊆ Arg(Y). We define below selection functions:
- Max(Σ) = Σ
- Card(Σ) = {E ∈ Σ | ∀E ′ ∈ Σ, |E| ≥ |E ′ |}
- Incli(Σ) = {E ∈ Σ | covi(E) is subset-maximal}
- Cardi(Σ) = {E ∈ Σ | ∀E ′ ∈ Σ, |covi(E)| ≥ |covi(E ′ )|}
- Inclc(Σ) = {E ∈ Σ | covc(E) is subset-maximal}
- Cardc(Σ) = {E ∈ Σ | ∀E ′ ∈ Σ, |covc(E)| ≥ |covc(E ′ )|}
- Mix(Σ) = Cardc(Cardi(Σ))
Applied to the set of stable extensions of an argumentation system, the function Max returns all the extensions, Card selects the extensions that contain more arguments, the two functions Incli, Cardi focus on the instances covered by the extensions and choose extensions with more instances. These functions promote the Success principle, which requires an explainer to have at least one explanation for each instance. The functions Inclc, Cardc focus on classes being justified by arguments. As we will se later, these principles promote explaining a large number of classes. This is useful when explanations are provided for classifier designers as they describe classifier's behaviour. Finally, the function Mix combines Cardi and Cardc, indeed, it starts by selecting the extensions that cover more instances, then it refines the result by selecting extensions that explain more classes.
Example 2 (Cont.) Recall that σ(AS) = {E1, . . ., E9}.
- covi(E1) = {I2, I3, I4, I5, I6}
- covi(E2) = {I1, I2, I3, I4, I5, I6}
- covi(E3) = {I2, I3, I4, I5, I6, I7} with covc(E1) = covc(E2) = covc(E3) = {c0, c1, c2}
- covi(E4) = {I1, I2, I3, I5} covc(E4) = {c0, c1}
- covi(E8) = {I1, I2, I4, I5, I6, I7} covc(E8) = {c1, c2}
- covi(E9) = {I4, I6, I7} covc(E9) = {c2} The selection functions return the following extensions:
- Card(σ(AS)) = Cardc(σ(AS)) = Inclc(σ(AS)) = {E1, E2, E3}
- Incli(σ(AS)) = Cardi(σ(AS)) = {E2, E3, E8}
- Mix(σ(AS)) = {E2, E3}
We show next the links between the selection functions.
Proposition 5. Let Σ be a non-empty set of subsets of arguments of Arg(Y). The following inclusions hold:
- Card(Σ) ⊆ Max(Σ)
- Mix(Σ) ⊆ Cardi(Σ) ⊆ Incli(Σ) ⊆ Max(Σ)
- Cardc(Σ) ⊆ Inclc(Σ) ⊆ Max(Σ)
The selection functions may still return several extensions, hence we need to identify the strongest arguments which will yield explanations. For that purpose, we introduce two inference rules that provide strong arguments from extensions.
Definition 14 (Inference Rules). Let Σ be a non-empty set of subsets of arguments of Arg(Y) and a ∈ Arg(Y). We define the following inference rules:
- Universal inference: Σ|∼ ∀a iff a ∈ ⋂ E∈Σ E.
- Existential inference: Σ |∼ ∃a iff ∃E ∈ Σ s.t. a ∈ E.
The next result shows the links between the two rules.
Proposition 6. Let Σ be a non-empty set of subsets of arguments of Arg(Y) and a ∈ Arg(Y). The following hold:
- Σ|∼ ∀a ⇒Σ|∼ ∃a
- If |Σ| = 1, then Σ|∼ ∀a ⇐⇒ Σ|∼ ∃a.
Selection functions and inference rules are combined for defining accepted arguments. Each pair gives birth to a criterion for declaring an argument as accepted.
Definition 15 (Accepted Arguments). Let AS = 〈Arg(Y), R〉, α be a selection function and β an inference rule. An argument a ∈ Arg(Y) is accepted, denoted by AS |∼ α,β a, iff α(σ(AS)) |∼ β a.
We show that accepted arguments under the function Max (which retains all extensions) are non-attacked ones if Max is combined with the universal rule and they are all arguments of the system when Max is combined with the existential rule.
Proposition 7. Let AS = 〈Arg(Y),R〉 and a ∈ Arg(Y).
- AS |∼ Max,∀a ⇐⇒ Att(a) = ∅
- {a ∈ Arg(Y) | AS |∼ Max,∃a} = Arg(Y)
Below are links between accepted arguments returned using the same inference rule but distinct selection functions.
Proposition 8. Let AS = 〈Arg(Y),R〉, a ∈ Arg(Y), and α, α′ be two selection functions. If α(Σ) ⊆ α′ (Σ), then:
- AS |∼ α,∃a ⇒ AS |∼ α′ ,∃a
Below is a complete list of links between sets of accepted arguments returned by pairs of selection principles and inference rules.
Proposition 9. The following implications hold.
- AS |∼ α,∀a ⇒AS |∼ α,∃a, ∀α
- AS |∼ Max,∀a⇒AS |∼ Card,∀a
- AS |∼ Card,∃a⇒AS |∼ Max,∃a
| Y | I1 | I2 | I3 | I4 | I5 | I6 | I7 |
| g Max,∀ | ∅ | ∅ | ∅ | ∅ | ∅ | ∅ | ∅ |
| g Card,∀ | ∅ | {L2} | {L1} | {L4} | {L2} | {L4} | ∅ |
| g Incli,∀ | ∅ | ∅ | ∅ | {L4} | ∅ | {L4} | ∅ |
| g Cardi,∀ | ∅ | ∅ | ∅ | {L4} | ∅ | {L4} | ∅ |
| g Inclc,∀ | ∅ | {L2} | {L1} | {L4} | {L2} | {L4} | ∅ |
| g Cardc,∀ | ∅ | {L2} | {L1} | {L4} | {L2} | {L4} | ∅ |
| g Mix,∀ | ∅ | {L2} | {L1} | {L4} | {L2} | {L4} | ∅ |
We are now ready to define our new parameterized family of plausible explanation functions. For a given instance I, they return the support of any argument in favour of R(I) inferred by following one of the principles defined above. The support of the argument should be part of the instance I.
Definition 16 (Explanation Functions). Let T be a theory, Y ⊆ IT, R a classifier, α a selection function and β an inference rule. An explainer is a function gα,β mapping every instance I ∈ Y into a set of subsets of literals such that every L ∈ gα,β (I) satisfies the following:
- AS |∼ α,β 〈L, R(I)〉 where AS = 〈Arg(Y), R〉,
- L ⊆ I.
Example 2 (Cont.) Table 1 summarizes the explanations of the seven instances provided by every function which uses the universal inference rule. Note that the new functions explain more instances than the argument-based function (which is equivalent to g Max,∀ ) from [Amgoud, 2021b].
We show that all the above defined explanation functions are refined plausible explainers, i.e., they return subsets of explanations computed by the function gp (see Definition 8).
Proposition 10. Let T be a theory, Y ⊆ IT and R a classifier. For every selection function α, every inference rule β, every I ∈ Y, it holds that gα,β (I) ⊆ gp(I).
The following results show the links between the various explanation functions.
Proposition 11. Let I ∈ IT.
- gα,∀ (I) ⊆ gα,∃ (I) for any selection function α
- gMax,∀ (I) ⊆ gCard,∀ (I)
- gMax,∀ (I) ⊆ gIncli,∀ (I) ⊆ gCardi,∀ (I) ⊆ gMix,∀ (I)
- gMax,∀ (I) ⊆ gInclc,∀ (I) ⊆ gCardc,∀ (I)
- gCard,∃ (I) ⊆ gMax,∃ (I)
- gMix,∃ (I) ⊆ gCardi,∃ (I) ⊆ gIncli,∃ (I) ⊆ gMax,∃ (I)
- gCardc,∃ (I) ⊆ gInclc,∃ (I) ⊆ gMax,∃ (I)
It is worth mentioning that the explanation function g Max,∃ corresponds exactly to the plausible explanation function gp.
The function g Max,∀ coincides with the function g∗ introduced in [Amgoud, 2021b]. We show that this function is very cautious as it discards any explanation which is incoherent with at least one other explanation.
Proposition 12. Let AS = 〈Arg(Y),R〉 and I ∈ Y. g Max,∀ (I) = {L ∈ gp(I) | ∀L′ ∈ gp(I ′ ), if R(I) ̸= R(I ′ ) then L∪L′ is inconsistent}.
We show next how the various explainers behave wrt the two principles of Coherence and Success.
Theorem 2. Let AS = 〈Arg(Y),R〉, α be a selection function and β an inference rule. If |σ(AS)| > 1, then:
- gα,β satisfies Success iff α = Max and β = ∃ .
- gα,β satisfies Coherence iff β = ∀.
The above result shows that g Max,∃ (or gp) is the only function which satisfies success and all the other functions that are based on the existential inference rule violate both success and coherence. Consequently, those functions are not reasonable. Note that in this paper, we investigated the different possibilities for the purpose of completeness and proving formally which function is not suitable and why it is not.
Coherence is guaranteed by all the functions that are based on the universal inference rule. Furthermore, g Card,∀ , g Mix,∀ and g Cardc,∀ are more informative than the other functions that use the same inference rule. Indeed, they provide more explanations for instances, and can thus explain more instances. However, the three functions may return different outcomes as they follow different strategies. g Card,∀ is less interesting than the two others. It selects the extensions that contain more arguments, but the latter may support the same class as in our running example (the arguments in the extension E1 are all in favour of the class c0). Hence, any instance whose prediction is c1 gets an empty set of explanations.
The function g Mix,∀ maximizes the number of instances for which explanations are provided, this is important in domains like healthcare or banking where explanations are generally requested by end-users.
g Cardc,∀ maximizes the number of explained classes. It is suitable for understanding the global behaviour of a classifier, especially for a problem with a lot of classes.
6 Experimental Analysis
Recall that the function gp generates from a sample all possible abductive explanations, which may be incorrect. Our novel functions that use the universal inference rule guarantee correctness of explanations at the cost of success. The aim of this section is to confirm experimentally these findings. We provide two experiments, the first one measures the proportion of correct explanations provided by gp while the second measures the proportion of explained instances by novel functions that satisfy coherence. We implemented five functions: gp, the argument-based function g Max,∀ from [Amgoud, 2021b] and the three new functions that follow different strategies: g Card,∀ , g Cardi,∀ and g Cardc,∀ . Details on the implementation are given in the supplementary material.
We tested the four functions on various datasets, namely diabetes, titanic available on the Kaggle website, and lending adult (shortened) and recidivism (shortened) that are available on Anchors' experiments [Ribeiro et al., 2018]. In each experiment, we built the whole feature space, shuffled the instances, and kept different percentages of the whole space from which we generate arguments.
| %space | adult | diabetes | lending | titanic | rcdv |
|---|---|---|---|---|---|
| 12.50 | 0.00 | 0.00 | 0.00 | 0.00 | 0.00 |
| 25.00 | 0.00 | 0.01 | 0.02 | 0.00 | 0.00 |
| 37.50 | 0.05 | 0.19 | 0.14 | 1.77 | 0.00 |
| 50.00 | 0.52 | 1.01 | 0.85 | 3.48 | 0.04 |
| 62.50 | 2.21 | 4.12 | 3.98 | 8.14 | 0.39 |
| 75.00 | 7.78 | 13.18 | 13.76 | 16.39 | 2.84 |
| 87.50 | 27.36 | 37.60 | 41.51 | 32.63 | 16.03 |
| 93.75 | 50.48 | 60.36 | 66.66 | 50.74 | 38.96 |
| 100.00 | 100.00 | 100.00 | 100.00 | 100.00 | 100.00 |
For checking the proportion of correct explanations provided by gp in a dataset, we measure the percentage of nonattacked arguments generated from the dataset. Table 2 shows that it is very unlikely to find correct explanations by probing a model with a small part of the feature space. This might not entirely reflect the nature of a problem if natural restrictions of possible values confine real instances to a small subspace (something usually hard to know in practice).
| Function | adult | diabetes | titanic | rcdv | lending |
|---|---|---|---|---|---|
| g Max,∀ g Cardc ,∀ g Card,∀ g Cardi ,∀ | 0 | 0 | 0 | 0 | 0 |
| 0 | 0 | 0 | 0 | 0 | |
| 40 | 60 | 43 | 48 | 48 | |
| 14 | 36 | 81 | 96 | 42 |
Table 3 gives the proportion of instances of a dataset that are explained by the argument-based function g Max,∀ and the three new functions, given the guarantee of coherence according to Theorem 2. While g Max,∀ fails to explain any instance in the chosen datasets, g Card,∀ and g Cardi,∀ show better performances. g Cardc,∀ , which maximises the number of explained classes, fails as well but for the simple reason that the classification theories of the datasets contain only two classes.
7 RelatedWork
Most work on finding explanations in the ML literature is experimental, focusing on specific models, exposing their internal representations to find correlations post hoc between these representations and the predictions. There haven't been a lot of formal characterizations of explanations in AI, with the exception of [Ignatiev et al., 2019b], which defines abductive explanations and adversarial examples in a fragment of first order logic, [Darwiche and Hirth, 2020], who focused on semi-factuals, that they consider a specific form of counterfactuals, [Amgoud, 2021a] who defined in a unified setting abductive explanations, counterfactuals and contrastive explanations. These works generate explanations from the whole feature space, which in practice is not reasonable. In our work, we generate abductive explanations for black-box classifiers from subsets of instances. Unlike existing approaches which are based on samples, our novel functions that use the universal inference rule offer theoretical guarantees as they ensure correctness of explanations. They have also a greater explanatory power than the unique function in the literature that satisfies correctness, namely the argumentbased function from [Amgoud, 2021b].
Unlike our work which explains existing black-box models, [Cocarascu et al., 2020] proposed classification models that are based on arguments. Their explanations are defined in dialectical way as fictitious dialogues between a proponent (supporting an output) and an opponent (attacking the output) following [Dung, 1995]. The authors in [Zhong et al., 2019; Rago et al., 2018] followed the same approach for defining explainable multiple decision systems or scheduling systems.
In [Borg and Bex, 2021; Liao and van der Torre, 2020], the authors investigated explainability of argument status in Dung style argumentation setting. This is quite far from our work which uses argumentation for explaining ML models.
8 Conclusion
The paper proposed an argumentation-based approach for defining explanation functions for black-box classifiers. The novel functions provide abductive explanations from samples of instances, some of them guarantee correctness of their outcomes while one function ensures existence of explanations.
This work lends itself to a number of developments in order to improve its generality and the compromise coherence/success of the explanations. We can consider other attack relation for minimizing the distance between plausible and absolute explanations. The idea is to take into account weights of features and thus assign a basic weight to every argument reflecting the importance of features it is based on.
Acknowledgements
This work was supported by the ANR (ANR-19-PI3A-0004) through the AI Interdisciplinary Institute ANITI and by the National Research Foundation, Prime Minister's Office, Singapore under its Campus for Research Excellence and Technological Enterprise (CREATE) programme.
@inproceedings{ijcai2023p346,
  title     = {Leveraging Argumentation for Generating Robust Sample-based Explanations},
  author    = {Amgoud, Leila and Muller, Philippe and Trenquier, Henri},
  booktitle = {Proceedings of the Thirty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-23}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Edith Elkind},
  pages     = {3104--3111},
  year      = {2023},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2023/346},
  url       = {https://doi.org/10.24963/ijcai.2023/346},
}
TY - CPAPER TI - Leveraging Argumentation for Generating Robust Sample-based Explanations AU - Amgoud, Leila AU - Muller, Philippe AU - Trenquier, Henri T2 - Proceedings of the Thirty-Second International Joint Conference on Artificial Intelligence, IJCAI-23 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2023 SP - 3104 EP - 3111 DO - 10.24963/ijcai.2023/346 UR - https://doi.org/10.24963/ijcai.2023/346 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





