
Fine-grained Generalization Analysis of Structured Output Prediction
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 2841-2847.
https://doi.org/10.24963/ijcai.2021/391
© 2021 International Joint Conferences on Artificial Intelligence
Keywords
- Machine Learning: Learning Theory
- Machine Learning: Structured Prediction
Abstract
In machine learning we often encounter structured output prediction problems (SOPPs), i.e. problems where the output space admits a rich internal structure. Application domains where SOPPs naturally occur include natural language processing, speech recognition, and computer vision. Typical SOPPs have an extremely large label set, which grows exponentially as a function of the size of the output. Existing generalization analysis implies generalization bounds with at least a square-root dependency on the cardinality d of the label set, which can be vacuous in practice. In this paper, we significantly improve the state of the art by developing novel high-probability bounds with a logarithmic dependency on d. Furthermore, we leverage the lens of algorithmic stability to develop generalization bounds in expectation without any dependency on d. Our results therefore build a solid theoretical foundation for learning in large-scale SOPPs. Furthermore, we extend our results to learning with weakly dependent data.
- [Bousquet and Elisseeff, 2002] Olivier Bousquet and André Elisseeff. Stability and generalization. JMLR, 2:499-526, 2002.
- [Chen et al., 2017] Liang-Chieh Chen, George Papandreou, Iasonas Kokkinos, Kevin Murphy, and Alan L Yuille. Deeplab: Semantic image segmentation with deep con- volutional nets, atrous convolution, and fully connected CRFs. TPAMI, 40(4):834-848, 2017.
- [Ciliberto et al., 2016] Carlo Ciliberto, Alessandro Rudi, and Lorenzo Rosasco. A consistent regularization ap- proach for structured prediction. In NeurIPS, 2016.
- [Ciliberto et al., 2019] Carlo Ciliberto, Francis Bach, and Alessandro Rudi. Localized structured prediction. In NeurIPS, 2019.
- [Collins, 2001] Michael Collins. Parameter estimation for statistical parsing models: Theory and practice of. In IWPT, pages 4-15, 2001.
- [Cortes et al., 2016] Corinna Cortes, Vitaly Kuznetsov, Mehryar Mohri, and Scott Yang. Structured prediction theory based on factor graph complexity. In NeurIPS, 2016.
- [Guermeur, 2017] Yann Guermeur. Lp-norm sauer-shelah lemma for margin multi-category classifiers. Journal of Computer and System Sciences, 89:450-473, 2017.
- [Hinton et al., 2012] Geoffrey Hinton, Li Deng, Dong Yu, George E Dahl, Abdel-rahman Mohamed, Navdeep Jaitly, Andrew Senior, Vincent Vanhoucke, Patrick Nguyen, Tara N Sainath, et al. Deep neural networks for acous- tic modeling in speech recognition: The shared views of four research groups. IEEE Signal processing magazine, 29(6):82-97, 2012.
- [Koltchinskii and Panchenko, 2002] Vladimir Koltchinskii and Dmitry Panchenko. Empirical margin distributions and bounding the generalization error of combined classifiers. Annals of Statistics, pages 1-50, 2002.
- [Lafferty et al., 2001] John D Lafferty, Andrew McCallum, and Fernando CN Pereira. Conditional random fields: Probabilistic models for segmenting and labeling sequence data. In ICML, pages 282-289, 2001.
- [Ledent et al., 2019] Antoine Ledent, Waleed Mustafa, Yun- wen Lei, and Marius Kloft. Norm-based generalisa- tion bounds for multi-class convolutional neural networks. CoRR, abs/1905.12430, 2019.
- [Lei and Ying, 2020] Yunwen Lei and Yiming Ying. Fine- grained analysis of stability and generalization for stochas- tic gradient descent. In ICML, 2020.
- [Lei et al., 2015] Yunwen Lei, Urun Dogan, Alexander Binder, and Marius Kloft. Multi-class svms: From tighter data-dependent generalization bounds to novel algorithms. In NeurIPS, 2015.
- [Lei et al., 2019] Yunwen Lei, Ürün Dogan, Ding-Xuan Zhou, and Marius Kloft. Data-dependent generalization bounds for multi-class classification. IEEE Transactions on Information Theory, 65(5):2995-3021, 2019.
- [Li et al., 2018] Jian Li, Yong Liu, Rong Yin, Hua Zhang, Lizhong Ding, and Weiping Wang. Multi-class learning: from theory to algorithm. In NeurIPS, 2018.
- [Lucchi et al., 2013] Aurelien Lucchi, Y. Li, and P. Fua. Learning for structured prediction using approximate sub- gradient descent with working sets. In CVPR, 2013.
- [Maurer, 2016] Andreas Maurer. A vector-contraction in- equality for rademacher complexities. In ALT, 2016.
- [Maximov et al., 2018] Yury Maximov, Massih-Reza Amini, and Zaid Harchaoui. Rademacher complexity bounds for a penalized multi-class semi-supervised algorithm. JAIR, 61:761-786, 2018.
- [McAllester, 2007] David McAllester. Generalization bounds and consistency. Predicting structured data, pages 247-261, 2007.
- [Mokkadem, 1988] Abdelkader Mokkadem. Mixing prop- erties of arma processes. Stochastic Processes and Their Applications, 29(2):309-315, 1988.
- Musayeva et al., 19]
- Khadija Musayeva, Fabien Lauer, and Yann Guermeur. Rademacher complexity and general- ization performance of multi-category margin classifiers. Neurocomputing, 342:6-15, 19.
- [Rabiner and Juang, 1986] Lawrence Rabiner and B Juang. An introduction to hidden markov models. IEEE ASSP Magazine, 3(1):4-16, 1986.
- [Rosenblatt, 2012] Murray Rosenblatt. Markov Processes, Structure and Asymptotic Behavior: Structure and Asymp- totic Behavior, volume 184. Springer Science & Business Media, 2012.
- [Shalev-Shwartz et al., 2010] Shai Shalev-Shwartz, Ohad Shamir, Nathan Srebro, and Karthik Sridharan. Learnabil- ity, stability and uniform convergence. JMLR, 11:2635- 2670, 2010.
- [Taskar et al., 2003] Ben Taskar, Carlos Guestrin, and Daphne Koller. Max-margin markov networks. NeurIPS, 16, 2003.
- [Tsochantaridis et al., 2005] Ioannis Tsochantaridis, Thorsten Joachims, Thomas Hofmann, and Yasemin Altun. Large margin methods for structured and in- terdependent output variables. JMLR, 6:1453-1484, 2005.
- [Vinyals et al., 2015] Oriol Vinyals, Alexander Toshev, Samy Bengio, and Dumitru Erhan. Show and tell: A neu- ral image caption generator. In CVPR, 2015.
- [Wu et al., 2021] Liang Wu, Antoine Ledent, Yunwen Lei, and Marius Kloft. Fine-grained generalization analysis of vector-valued learning. In AAAI, 2021.
- [Zhang, 2002] Tong Zhang. Covering number bounds of cer- tain regularized linear function classes. JMLR, 2, 2002.
- [Zhang, 2004] Tong Zhang. Statistical analysis of some multi-category large margin classification methods. JMLR, 5:1225-1251, 2004.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Structured output prediction (SOP) refers to a broad class of machine learning problems with a rich structure in the output space. For instance, the output may be a sequence of tags in part-of-speech (POS) tagging, a sentence in machine translation, or a grid of segmentation labels in image segmentation.
A distinguishing property of these tasks is that the loss function admits a decomposition along the output structures. For instance, if the output is a sequence of partial labels, the loss function could be the Hamming distance. The output structure makes those problems substantially different, both algorithmically and theoretically, from well-studied machinelearning methods such as binary classification. Algorithms specifically targeted at SOPPs have been put forward in [Lafferty et al., 2001; Ciliberto et al., 2016; Taskar et al., 2003; Tsochantaridis et al., 2005; Vinyals et al., 2015; Lucchi et al., 2013; Chen et al., 2017], to mention but a few.
Whilst the subject of SOP is well explored from a practical point of view, existing theoretical analyses have several limitations. For instance, the results in [Taskar et al., 2003;
Collins, 2001] apply only to specific factor graphs and bound errors measured only by the Hamming loss, while other losses such as edit distance and BLUE scores are more natural in many applications. [McAllester, 2007] introduced guarantees that apply to general losses but only to randomized linear algorithms and admit only a square-root dependence on the size of substructures. In [Cortes et al., 2016], the authors introduced general bounds that apply to general factor graphs and general losses from the viewpoint of function class capacity. However, the associated bounds exhibit a square-root dependence on the number d of categories a subset of substructures can take, which can become vacuous when applied to extreme multi-class contexts [Lei et al., 2019] or models that assume a large dependence between the substructures.
In this paper, we aim to advance the state of the art in the theoretical foundation of SOP by developing generalization bounds applicable to large-scale problems with millions of labels. Our contributions are as follows.
- We apply the celebrated technique of Rademacher complexity to develop high-probability generalization bounds with a log dependency on the size of the label set. This substantially improves the existing state of the art, which comes with at least a square-root dependency. We achieve this improvement by using covering numbers measured by the ℓ∞- norm, which can exploit the Lipschitz continuity of loss functions with respect to (w.r.t.) the ℓ∞-norm. For comparison, the existing complexity analysis uses the Lipschitz continuity w.r.t. the ℓ2-norm [Cortes et al., 2016], which does not match the regularity of loss functions in structured output prediction and thus leads to suboptimal bounds.
- We leverage the framework of algorithmic stability to further remove the log dependency for generalization bounds in expectation. We consider two popular methods for structured output prediction: stochastic gradient descent (SGD) and regularized risk minimization (RRM). We adapt the existing stability analysis in a way to exploit the Lipschitz continuity w.r.t. the ℓ∞-norm of loss functions in SOP.
- We extend our discussion to learning with weakly dependent training examples, which are widespread in SOPPs. For example, in natural language processing (NLP), a data set can come in the form of sets of documents, while learning is performed at the sentence level. While assuming that the sentences are independent is inaccurate, it is reasonable to assume that the dependency between sentences decreases when
their distance in a document increases.
The remaining parts of the paper are structured as follows. We discuss some related work in Section 2 and present the problem formulation in Section 3. We present our main results on generalization bounds in Section 4, which are extended to learning with dependent examples in Section 5. We conclude the paper in Section 6.
2 RelatedWork
We first review some work on structured output prediction. Many algorithms have been developed to solve structured output prediction problems. Early techniques considered generative probabilistic models (e.g., hidden Markov models [Rabiner and Juang, 1986]). Motivated by the success of support vector machines (SVM), large-margin models for structured data were proposed in [Taskar et al., 2003; Tsochantaridis et al., 2005]. To reduce the model complexity, conditional random fields (CRFs) [Lafferty et al., 2001] model the conditional distribution of the structured outputs rather than modeling the joint probability of the input and output. A key property of these models is that their prediction step can be viewed as maximising a scoring function. Such a scoring function enjoys a decomposition over the substructure so that the maximisation can be done efficiently. CRFs were combined with convolutional neural networks (CNNs) in [Chen et al., 2017] to approach semantic segmentation problems, achieving better performance than CNNs alone.
In [Collins, 2001; Taskar et al., 2003], the authors showed a generalization bound for their proposed models. However, they considered restricted models and losses (Hamming loss). A PAC-Bayesian bound is proved in [McAllester, 2007] for Bayesian prediction algorithms. In [Cortes et al., 2016] the authors introduced a more general generalization bound that applies to general losses and models. Their bound scales as the square root of the number of classes. This can lead to vacuous bounds when the number of classes per substructure and their dependence on each other continue to increase.
[Ciliberto et al., 2016] introduced the implicit embedding approach to structured output prediction where the label is encoded into a vector in some Hilbert space via an encoding function. A decoding function is also defined so that prediction is performed by composing a regression function and the decoding function, thus establishing a connection between structured output prediction and regression. They provided generalization bounds of the order of O(m- 1 4 ), where m is the number of samples, which can be a problem for large m. Recently, [Ciliberto et al., 2019] introduced the setting of localized structured output prediction, where they assume a form of weak dependence between substructures. Their model utilizes such assumption by treating each part of the structure as an independent sample. They prove bounds of the order O((ml)- 1 4 ) for their method, where l is the number of substructures, under weakly dependent samples.
We now review the related work for multi-class classification (MCC), which is a specific case of structured output prediction. Various capacity measures of function classes were used to study generalization bounds of MCC, including Rademacher complexities [Lei et al., 2015; Maurer, 2016;
Li et al., 2018; Maximov et al., 2018; Musayeva et al., 19], covering numbers [Zhang, 2004; Lei et al., 2019; Ledent et al., 2019] and the fat-shattering dimension [Guermeur, 2017]. While initial analyses implied generalization bounds with at least a linear dependency on the number of classes [Koltchinskii and Panchenko, 2002], the couplings among class components were exploited recently to get a dependency that can be as mild as square-root [Cortes et al., 2016; Li et al., 2018] or even logarithmic [Lei et al., 2019; Wu et al., 2021].
3 ProblemFormulation
SOP refers to machine learning problems with an internal structure in the outputs (and potentially also in the inputs). For example in sequence-to-sequence prediction, both the input and output are sequences. In syntax analysis, the inputs are sequences of words and the output is a parse tree.
Let X be an input space (e.g., sentences in a given language) and Y be an output space (e.g., POS tags for the input sentences). In structured output prediction, the output space can often be decomposed into a number of substructures. Take POS tags as an example, where each word tag represents a substructure and the sequence of tags constitutes the structured output. Formally we define Y = Y1 ×· · ·×Yl, where Yk is the set of possible classes a substructure k can take. For a point (x, y) ∈ X × Y, let yk denote the k-th element in y (i.e., y = (y1 , . . . , yl )).
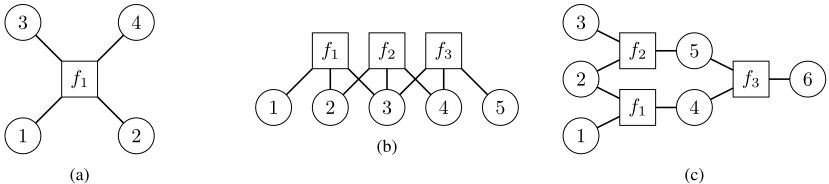
We aim to learn a scoring function h : X × Y → R based on which we can perform the prediction as ˆ y(x) = argmaxy∈Y h(x, y). The score function in structured output prediction can be described via a factor graph G = (V, F, E), where V = [l] := {1, . . . , l} is the set of variable nodes, F is a set of factor nodes, and E is a set of undirected edges between a variable node and a factor node. Let N(f) be the set of nodes connected to the factor f by an edge and Yf = Πk∈N(f)Yk. For brevity, we assume that |Yf | = d for all f, where |Yf | denotes the cardinality of Yf . Now we define the scoring function h(x, y) for x ∈ X and y ∈ Y as
where yf := {yj : j ∈ N(f)} and hf : X ×Yf → R. Figure 1 gives an example of factor graphs and scoring functions.
Let S = {(xi, yi)}mi=1 be a training set with (xi, yi) ∈ X ×Y being independently drawn from a distribution D over X × Y. We use a loss function L : Y × Y → R+ to measure the performance of prediction models, based on which we can define the margin loss [Cortes et al., 2016] as Lρ : X ×Y × H → R:
where Φ∗ (r) = min(M, max(0, r)), M = maxy,y′ L(y, y′ ) and H ⊂ {h : X × Y → R} is some hypothesis class. Note that Lρ(x, y, h) ≥ L(ˆ y(x), y). Therefore, the obtained bounds for Lρ will also hold for L. We then define the population risk R(h) and empirical risk RS(h) to quantify the performance of a model h on testing and training examples, respectively as:
Let Ψ be a feature function which maps an input-output example (x, y) ∈ X × Y to RD , where D is the dimension of feature space. In structured output prediction, the feature extractor takes a composite form according to the factor graph G, that is, Ψ(x, y) = ∑f∈F Ψf(x, yf), where Φf : X × Yf → R. We consider a linear scoring function hw (x, y) = 〈w,Ψ(x, y)〉 indexed by a w ∈ RD . Then the hypothesis space becomes
where ‖w‖p = (∑Di=1 |wi|d ) 1p is the ℓp-norm of w = (w1, . . . , wD). We also define the class of loss functions
4 Main Results
In this section, we present our main results on generalization bounds for structured output prediction. We consider two types of generalization bounds: complexity-based bounds and stability-based bounds. Our aim is to develop bounds with a very mild dependency on the size of the label set, thus laying a solid foundation for structured output prediction, where the size of label set Y is often extremely large in practice. A key discovery to both our stability-based and complexity-based analysis is to note the Lipschitz continuity of loss functions w.r.t. infinity-norm ‖ · ‖∞.
Definition 1 (Lipschitz continuity). We say that a loss function L(x, y, h) is (τ, ℓ∞)-Lipschitz in the last argument if, for any h, ˜h ∈ H and all (x, y) ∈ X × Y, we have:
The existing analysis [Cortes et al., 2016] uses the (τ2, ℓ2) Lipschitz continuity of loss functions:
Note that the Lipschitz continuity w.r.t. ℓ∞-norm is much stronger than that w.r.t. ℓ2-norm. Indeed, if L is (τ, ℓ∞)- Lipschitz then it is also (τ, ℓ2) Lipschitz since ‖ · ‖∞ ≤ ‖ · ‖2. As a comparison, a (τ2, ℓ2)-Lipschitz function can be (τ2√|Y|, ℓ∞)-Lipschitz due to the norm relationship ‖ · ‖2 ≤ √|Y|‖ · ‖∞ (the equality can hold in some cases).
In Lemma 1 we build the ℓ∞-Lipschitz continuity of Lρ for structured output prediction. A remarkable property is that the involved Lipschitz constant is independent of |Y|. This shows that the loss function in structured output prediction is well behaved in the sense of Lipschitz continuity. However, the existing analysis based on the (τ2, ℓ2)-Lipschitz continuity fails to exploit this strong regularity, and therefore only implies suboptimal bounds with at least a square-root dependency on the size of the label set. The proof of Lemma 1 below is given in the arXiv version.
Lemma 1. The loss function Lρ is ( 2ρ , ℓ∞)-Lipschitz with respect to the scoring function h for all x ∈ X and y ∈ Y.
4.1 Complexity-based Generalization Bounds
We develop generalization bounds with high probability here. Our basic tool to this aim is the Rademacher complexity.
Definition 2. The empirical Rademacher complexity of a function class H of real-valued functions is defined as:
where {σi} are random variables with equal probability of being either +1 or -1.
Theorem 1. Let ρ > 0 be. Then the Rademacher complexity of the loss class Fp,Λ,ρ is bounded as follows:
The proof strategy is to to relate the complexity of the loss class Fp,Λ,ρ to a complexity of a scalar linear function class on an extended set of size m|F |d, thus moving contribution of d to the complexity from the output dimension to the size of training set. We then utilize standard bounds [Zhang, 2002] that admit log dependency on the size of training set. The detailed proof is given in the arXiv version of the paper.
Remark 1. We now compare our results with related work. In [Cortes et al., 2016], the authors bounded the Rademacher complexity of Fp,Λ,ρ by a factor graph Rademacher complexity. Specifically for the loss class (3) they proved R(Fp,Λ,ρ) ≤ 2√2 ρ ˆRGS (Hp), where ˆRGS (Hp) is defined as
Here ϵ = (ϵi,f,y)i∈[m],f∈F,y∈Yf and each ϵi,f,y is an independent Rademacher variable. Combining the result from Theorem 2 in [Cortes et al., 2016], we get the following bound for learning with ℓ2-regularization: R(F2,Λ,ρ) ≤ O( ΛΨ∗ |F |√d ρ√m ). Note the bound exhibit a square-root dependence on the number of classes per factor d = |Yf |. Thus it is vacuous for typical SOPPs, where the number of class labels grows exponentially w.r.t. the size of the output. For comparison, our bounds enjoy a log dependency on d and therefore still imply meaningful generalization bounds in this setting.
As a direct corollary, we use the connection between generalization and Rademacher complexity to get Theorem 2.
Theorem 2 (Generalization Bounds). For any ρ > 0, δ ∈ (0, 1), and h ∈ Hp, with probability at least 1 - δ over the draw of training data S, the following bound holds:
4.2 Stability-based Generalization Bounds
In this section, we present generalization bounds in expectation for structured output prediction by leveraging the lens of algorithmic stability. Algorithmic stability is a fundamental concept in statistical learning theory, which measures the sensitiveness of output models when the training dataset of an algorithm A is slightly perturbed. For any algorithm A, we use A(S) to denote the model produced by running A over the training examples S.
Definition 3 (Uniform Stability). A stochastic algorithm A is ϵ-uniformly stable if, for all training datasets S, ˜ S ∈ Z n that differ by at most one example, we have
Algorithmic stability naturally implies quantitative generalization bounds, as shown in the following lemma [ShalevShwartz et al., 2010].
Lemma 2 (Generalization via uniform stability). Let A be ϵuniformly stable. Then ∣∣ES,A[R(A(S)) - RS(A(S))]∣∣ ≤ ϵ.
We will apply algorithmic stability to study two representative algorithms for SOP: regularization and stochastic gradient descent. For brevity, we use the abbreviation R(w) = R(hw ),RS(w) = RS(hw ), etc. We also write w∗ = arg infw R(w) for the minimizer of the population risk.
Regularized Risk Minimization
RRM is a popular scheme to overcome overfitting in machine learning. The basic idea is to add a regularizer to the empirical risk and build a regularized empirical risk RλS . Then we minimize the resulting objective function to obtain a model wS as follows:
Here we omit the dependency of wS on the regularization parameter for brevity. In the following lemma to be proved in the arXiv version, we show that the above regularization algorithm is uniformly stable. Let κ := supx,y ‖Ψ(x, y)‖2.
This lemma is a variant of the stability bound in [Bousquet and Elisseeff, 2002], which, however, requires the loss function to be admissible. We adapt their technique to the setting of structured output prediction and a key step in our analysis is again the Lipschitz continuity of the loss function w.r.t. the ℓ∞ norm. A use of the classical Lipschitz continuity w.r.t. ℓ2 norm would incur a bound with at least a square-root dependency on d. For comparison, the consideration of Lipschitz continuity w.r.t. the ℓ∞ norm allows us to get stability bounds independent of the size of the label set.
We can combine the Lipschitz continuity of loss functions, the stability of regularization schemes established in Lemma 3 and Lemma 2 together to get the following generalization bounds for structured output prediction. Let
be the minimizer of the regularized risk. We have the following result, whose proof is given in the arXiv version.
Theorem 3. Let wS be defined in (7). Then
Furthermore, if we choose λ = 4√2κ √mρ‖w∗ ‖2 , then
Stochastic Gradient Descent
We now turn to the performance of SGD for structured output prediction. SGD is a popular optimization algorithm with wide applications in learning in a big data setting. Let w(1) be the initial point and {ηt} be a sequence of positive step sizes. At the t-th iteration, we first randomly select an index it according to the uniform distribution over [m], which is used to build a stochastic gradient L′ρ (xit , yit , hw(t) ) (L′ρ (xit , yit , hw(t) ) denotes a subgradient of Lρ(xit , yit , hw ) at w = w(t) ). Then we update the model along the negative direction of the stochastic gradient
This scheme of selecting a single example to build a stochastic gradient allows SGD to get sample-size independent iteration complexity, and is especially appealing if m is large. Since we consider a linear scoring function hw , the loss function Lρ is convex w.r.t. w. In the following lemma to be proved in the arXiv version, we build the uniform stability of SGD for structured output prediction. Note here we do not require the loss function to be smooth [Lei and Ying, 2020].
Lemma 4. Let S = {z1, . . . , zm} and S′ = {z′1 , . . . , z ′m} be two datasets that differ only by a single example. Let {w(t) } and ˆw(t) be two sequences produced by SGD based on S and S′ , respectively. Then
According to Lemma 4, we know that the algorithm becomes more and more unstable as we run more and more iterations. We can use this stability bound to derive generalization bounds of SGD for structured output prediction. The proof is given in the arXiv version.
Theorem 4. Let{w(t) } be produced by (10) with ηt =η. Then
where ¯w(T) = 1 T ∑Tt=1 w(t) is an average of iterates.
The upper bound (11) involves two terms. The first term √T + T/m comes from controlling the generalization error R( ¯w(T) ) - RS( ¯w(T) ), while the second term 1+Tη2 Tη comes from controlling the optimization error RS( ¯w(T ) )-RS(w∗ ). It is clear the optimization error decreases w.r.t. T, while the generalization error grows in the learning process. Therefore, we need to trade-off these two terms by early-stoping SGD as done by the following corollary. We write B ≍ ˜ B if there are absolute constants c1 and c2 such that c1B ≤ ˜ B ≤ c2B.
Corollary 1. Let {w(t) } be the sequence produced by (10) with ηt = η. If we choose T ≍ m2 and η ≍ T - 34 /κ, then
Remark 2. According to Theorem 3 and Corollary 1, we know that both the regularization method and SGD are able to achieve the generalization bound O(1/√m), which is minimax optimal. While RRM requires the objective function to be strongly convex, SGD only requires the objective function to be convex. Remarkably, these generalization bounds do not admit any dependency on the size of the label set, and provide a convincing explanation on why SOP often works well even if the problem has more class labels than training examples. To our best knowledge, these are the first labelsize free generalization bounds. As compared to Theorem 2 on high-probability bounds, our generalization bounds here are stated in expectation. It should be noted that our bounds in expectation require the loss functions to be convex, while the high-probability analysis also applies to nonconvex cases.
4.3 Applications
In this section we discuss applications of our bounds and compare them to those of [Cortes et al., 2016].
Example 1. Consider pair-wise Markov networks with fixed number of substructures l [Taskar et al., 2003]. Specifically, we have Y = Y1 × . . . ×Yl and Yk ∈ [c] for k ∈ [l]. Further, we have sequence-like connections, i.e., there is an arrangement of output nodes such that if a factor f ∈ F is connected to two nodes then they are neighbors in that arrangement. Therefore we have |F | = l-1 and d = c2 . We further assume an unnormalized hamming loss L(y, y′ ) = ∑lk=1 Iyk̸=y′k so that we normalize later in the bound to get rid of the dependence on l = |F| + 1. For regularized learning with these Markov networks, the Rademacher complexity of loss function classes was bounded in [Cortes et al., 2016] as R(F2,Λ,ρ) ≤ O( ΛΨ∗ c ρ√m ). As a comparison, our Rademacher complexity bound in Theorem 1 reduces to an upper bound on R(F2,Λ,ρ) that has the form
Therefore, our bound significantly outperforms their bound by dropping their linear dependency on c to a logarithmic dependency. If we further extend the model so that each factor f is connected to v nodes instead of 2, their bound grows, as a function of v, as O(cv/2 ) while ours increase only O(√v). Furthermore, according to Theorems 3, 4, we can get generalization bounds O(κ/√m) in expectation for both RRM and SGD, where the log dependency is further removed.
Example 2. As the second example we consider multi-class classification. In this case we have no substructures and therefore |F| = 1, Y1 = Y where Y = [c], d = c. In [Cortes et al., 2016], the Rademacher complexity for multiclass learning with ℓ2 regularization was shown to satisfy R(F2,Λ,ρ) ≤ O ( Ψ∗Λ√c ρ√m ).
Our analysis instead shows R(F2,Λ,ρ) is bounded by
It is clear that we drop the square root dependency in c in [Cortes et al., 2016] to a log dependence. Analogous to Example 1, the log dependency can be further removed if we consider generalization bounds in expectation, as shown in Theorems 3 and 4.
Example 3. In this example we explore the possibility of combining SOP models above with a learned feature extraction function Ψ as was practically explored in [Chen et al., 2017; Hinton et al., 2012]. Consider the case where Ψ is a CNN that takes x as input and outputs different Ddimensional vector Ψf(x, yf) for each factor f and label yf . Chaining the covers, one can bound the Rademacher complexity of the combined class as ˜O (√q-1Ψ∗Λ|F| ρ√m ) +
factors, ¯D is the number of network parameters and ˜G is a product of norms of network weight matrices. The derivation of this bound is given in the arXiv version.
5 LearningWeakly Dependent Sequences
In the above bounds we assumed that the examples are sampled independently from each other. However, this assumption is often violated in practice. For example, consider the problem of POS tagging. We are usually given a dataset of documents each of which contains a sequence of sentences. There are two natural assumptions. (1) We may assume that each document is a long sequence of dependent words. This assumption is too pessimistic. The considered sample size becomes too small, and the prediction complexity increases while, as sentences get further apart, the dependence between them decreases, and thus the effective sample size increases. (2) We may assume that each sentence is independent of the others within and across documents. This assumption on the other hand is too optimistic. Sentences following each other in the same document indeed have some degree of dependence. We formalize this dependence in a hierarchical manner, thus providing a trade-off between these two assumptions. Namely, we assume that the documents are independent of each other while sentences within a document are only weakly dependent. We note that the term document here does not necessarily mean an actual text document but rather any sequence of examples (e.g., for a dataset of videos, one video is a document as it is a sequence of images).
We now formalize the idea above. We are given a training set of independent documents {Di}mi=1 . Each document Di is a sequence of weakly dependent examples Di = (zj i )Jj=1 . Since the structured output prediction framework in the above section subsumed the usual classification paradigm, we assume that the sequence elements classes follows it. That is, zij ∈ X × Y =: Z, where X and Y defined as above.
Now we define precisely how the examples within each document Di are weakly dependent. We assume that each example within a given document is sampled from a β-mixing process, defined below, at times 1, 2, . . . , J.
Definition 4 (Stationary β-mixing Stochastic Process). Let (zk )∞k=-∞ be a stationary stochastic process and σL = σ((zk )Lk=1 ) and σL+a = σ((zk )∞k=L+a ) be the sigma algebras generated by the random variables Z L 1 = (z1 , . . . , zL) and z∞ L+a = (zL+a , . . . ,Z∞). Define the β-mixing coefficient β(a) := supL≥1 E [supB∈σL+a |P (B|σL) - P (B)|] . The process is called β-mixing if lima→∞β(a) = 0. It is called exponentially mixing if β(a) ≤ β0 exp (-β1ar ) or algebraically mixing if β(a) ≤ β0/ar , for positive β0, β1 and r.
Some examples of exponentially mixing process include a class of Autoregressive Moving Average (ARMA) [Mokkadem, 1988] and a class of Markov process [Rosenblatt, 2012].
Now let H be a structured output prediction function class as defined in the previous section (see (2)). For h ∈ H, let Lh : Z → [0,M] be a loss function over elements of the sequence zk . An example for such a loss is given in equation (1). Again we are interested in high probability bounds on the difference between two quantities: the empirical risk ˆRS(h) and the true risk R(h), which are defined as RS(h) = 1 mJ ∑mi=1 ∑Jj=1 Lh(zj i ) and R(h) = ES[RS(h)]. Theorem 5 summarizes the main results of this section.
Theorem 5. Let Fp,Λ,ρ be the loss class defined in (3) and let S be a set of independent and identically distributed documents Di, i = 1, . . . ,m, where each document is a sequence of examples (zj i ) j = 1, . . . , J drawn from a β-mixing process. For any integer a > 0 such that J is a multiple of 2a. Let δ > 2m( J 2a -1)β(a), then with probability at least 1-δ, the following inequality holds uniformly over all h ∈ Hp
Remark 3. Note that the bound unsurprisingly depends on the same main quantities as the bound in Theorem 2. To better interpret it consider the following two extreme cases. (1) The elements inside each document are independent of each other. Note that in this case β(a) = 0, for all a, hence a can be chosen to be 1 and the bound boils down to the bound in Theorem 2. (2) The elements inside each document are strongly dependent. Thus, β(a) ≈ 1 for all a and therefore selecting a = J2 leads to the bound in Theorem 2 with only m training examples. We further note that β(a) → 0 as a → ∞, therefore, for any process admitting a fast decaying β(a) the term 2m( J 2a - 1)β(a) approaches 0 fast for moderate a.
6 Conclusion
In this paper, we advance the state of the art in the generalization analysis of structured output prediction. We consider two types of generalization bounds: complexity-based and stability-based bounds. Our complexity-based approach produces bounds with high probability that admit a log dependency on the size of the label set. The stability-based approach further removes this log dependency for generalization bounds in expectation. This significantly improves the existing bounds, which have at least a square root dependency. We also extend our discussion to the setting of learning with weakly dependent training examples.
A very interesting question is to investigate whether the log dependency in the high probability analysis is an artefact of our analysis or is really essential. Another question is to extend our generalization bounds in expectation to learning with nonconvex functions.
Acknowledgments
MK, AL and WM acknowledge support by the German Research Foundation (DFG) award KL 2698/2-1 and by the German Federal Ministry of Science and Education (BMBF) awards 01IS18051A, 031B0770E, and 01MK20014U. YL acknowledges support by NSFC under Grant No. 61806091.
@inproceedings{ijcai2021p391,
  title     = {Fine-grained Generalization Analysis of Structured Output Prediction},
  author    = {Mustafa, Waleed and Lei, Yunwen and Ledent, Antoine and Kloft, Marius},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {2841--2847},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/391},
  url       = {https://doi.org/10.24963/ijcai.2021/391},
}
TY - CPAPER TI - Fine-grained Generalization Analysis of Structured Output Prediction AU - Mustafa, Waleed AU - Lei, Yunwen AU - Ledent, Antoine AU - Kloft, Marius T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 2841 EP - 2847 DO - 10.24963/ijcai.2021/391 UR - https://doi.org/10.24963/ijcai.2021/391 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





