
Bayesian Experience Reuse for Learning from Multiple Demonstrators
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 2425-2431.
https://doi.org/10.24963/ijcai.2021/334
Keywords
- Uncertainty in AI: Bayesian Networks
- Machine Learning: Transfer, Adaptation, Multi-task Learning
- Machine Learning: Deep Reinforcement Learning
- Uncertainty in AI: Approximate Probabilistic Inference
Abstract
Learning from Demonstrations (LfD) is a powerful approach for incorporating advice from experts in the form of demonstrations. However, demonstrations often come from multiple sub-optimal experts with conflicting goals, rendering them difficult to incorporate effectively in online settings. To address this, we formulate a quadratic program whose solution yields an adaptive weighting over experts, that can be used to sample experts with relevant goals. In order to compare different source and target task goals safely, we model their uncertainty using normal-inverse-gamma priors, whose posteriors are learned from demonstrations using Bayesian neural networks with a shared encoder. Our resulting approach, which we call Bayesian Experience Reuse, can be applied for LfD in static and dynamic decision-making settings. We demonstrate its effectiveness for minimizing multi-modal functions, and optimizing a high-dimensional supply chain with cost uncertainty, where it is also shown to improve upon the performance of the demonstrators' policies.
- [Amos and Kolter, 2017] Brandon Amos and J Zico Kolter. Optnet: Differentiable optimization as a layer in neural networks. In ICML, pages 136-145, 2017.
- [Argall et al., 2009] Brenna D Argall, Sonia Chernova, Manuela Veloso, and Brett Browning. A survey of robot learning from demonstration. Robotics and autonomous systems, 57(5):469-483, 2009.
- [Auer, 2002] Peter Auer. Using confidence bounds for exploitation-exploration trade-offs. Journal of Machine Learning Research, 3(Nov):397-422, 2002.
- [Azizsoltani et al., 2019] Hamoon Azizsoltani, Yeo Jin Kim, Markel Sanz Ausin, Tiffany Barnes, and Min Chi. Un- observed is not equal to non-existent: using gaussian pro- cesses to infer immediate rewards across contexts. In IJ- CAI, pages 1974-1980, 2019. IJCAI
- [Barreto et al., 2017] André Barreto, Will Dabney, Rémi Munos, Jonathan J Hunt, Tom Schaul, Hado P van Hasselt, and David Silver. Successor features for transfer in rein- forcement learning. In NeurIPS, pages 4055-4065, 2017.
- [Bishop, 2006] Christopher M Bishop. Pattern recognition and machine learning. springer, 2006.
- [Bojarski et al., 2016] Mariusz Bojarski, Davide Del Testa, Daniel Dworakowski, Bernhard Firner, Beat Flepp, Pra- soon Goyal, Lawrence D Jackel, Mathew Monfort, Urs Muller, Jiakai Zhang, et al. End to end learning for self- driving cars. arXiv:1604.07316, 2016.
- [Brown et al., 2020] Daniel Brown, Russell Coleman, Ravi Srinivasan, and Scott Niekum. Safe imitation learning via fast bayesian reward inference from preferences. In ICML, pages 1165-1177. PMLR, 2020.
- [Cruz Jr et al., 2017] Gabriel V Cruz Jr, Yunshu Du, and Matthew E Taylor. Pre-training neural networks with human demonstrations for deep reinforcement learning. arXiv:1709.04083, 2017.
- [Fernández et al., 2010] Fernando Fernández, Javier García, and Manuela Veloso. Probabilistic policy reuse for inter- task transfer learning. Robotics and Autonomous Systems, 58(7):866-871, 2010.
- [Flet-Berliac and Preux, 2019] Yannis Flet-Berliac and Philippe Preux. Merl: Multi-head reinforcement learning. In NeurIPS Workshop, 2019.
- [Gao et al., 2018] Yang Gao, Huazhe Xu, Ji Lin, Fisher Yu, Sergey Levine, and Trevor Darrell. Reinforcement learn- ing from imperfect demonstrations. ICLR Workshop, 2018.
- [Grollman and Billard, 2011] Daniel H Grollman and Aude Billard. Donut as i do: Learning from failed demonstra- tions. In ICRA, pages 3804-3809. IEEE, 2011.
- [Hausman et al., 2017] Karol Hausman, Yevgen Chebotar, Stefan Schaal, Gaurav Sukhatme, and Joseph J Lim. Multi-modal imitation learning from unstructured demon- strations using generative adversarial nets. In NeurIPS, pages 1235-1245, 2017.
- [Hester et al., 2018] Todd Hester, Matej Vecerik, Olivier Pietquin, Marc Lanctot, Tom Schaul, Bilal Piot, Dan Hor- gan, John Quan, Andrew Sendonaris, Ian Osband, et al. Deep q-learning from demonstrations. In AAAI, 2018.
- [Hou et al., 2017] Yuenan Hou, Lifeng Liu, Qing Wei, Xudong Xu, and Chunlin Chen. A novel ddpg method with prioritized experience replay. In SMC, pages 316- 321. IEEE, 2017.
- [Janz et al., 2019] David Janz, Jiri Hron, Przemysław Mazur, Katja Hofmann, José Miguel Hernández-Lobato, and Sebastian Tschiatschek. Successor uncertainties: ex- ploration and uncertainty in temporal difference learning. In NeurIPS, pages 4509-4518, 2019.
- [Kemmer et al., 2018] Lukas Kemmer, Henrik von Kleist, Diego de Rochebouët, Nikolaos Tziortziotis, and Jesse Read. Reinforcement learning for supply chain optimiza- tion. In EWRL, pages 1-9, 2018.
- [Li and Zhang, 2018] Siyuan Li and Chongjie Zhang. An op- timal online method of selecting source policies for rein- forcement learning. In AAAI, 2018.
- [Lillicrap et al., 2016] Timothy P Lillicrap, Jonathan J Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yuval Tassa, David Silver, and Daan Wierstra. Continuous control with deep reinforcement learning. In ICLR, 2016.
- [Madarasz and Behrens, 2019] Tamas Madarasz and Tim Behrens. Better transfer learning with inferred successor maps. In NeurIPS, volume 32, pages 9029-9040, 2019.
- [Nicolescu and Mataric, 2003] Monica N Nicolescu and Maja J Mataric. Natural methods for robot task learning: Instructive demonstrations, generalization and practice. In AAMAS, pages 241-248, 2003.
- [Ober and Rasmussen, 2019] Sebastian W Ober and Carl Edward Rasmussen. Benchmarking the neural linear model for regression. arXiv:1912.08416, 2019.
- [Pardoe and Stone, 2010] David Pardoe and Peter Stone. Boosting for regression transfer. In ICML, pages 863-870, 2010.
- [Rosman et al., 2016] Benjamin Rosman, Majd Hawasly, and Subramanian Ramamoorthy. Bayesian policy reuse. Machine Learning, 104(1):99-127, 2016.
- [Snoek et al., 2015] Jasper Snoek, Oren Rippel, Kevin Swer- sky, Ryan Kiros, Nadathur Satish, Narayanan Sundaram, Mostofa Patwary, Mr Prabhat, and Ryan Adams. Scal- able bayesian optimization using deep neural networks. In ICML, pages 2171-2180, 2015.
- [Suay et al., 2016] Halit Bener Suay, Tim Brys, Matthew E Taylor, and Sonia Chernova. Learning from demonstra- tion for shaping through inverse reinforcement learning. In AAMAS, pages 429-437, 2016.
- [Sutton and Barto, 2018] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction. MIT press, 2018.
- [Tsai et al., 2019] Yao-Hung Hubert Tsai, Paul Pu Liang, Amir Zadeh, Louis-Philippe Morency, and Ruslan Salakhutdinov. Learning factorized multimodal represen- tations. In ICLR, 2019.
- [Wang and Taylor, 2017] Zhaodong Wang and Matthew E Taylor. Improving reinforcement learning with confidence-based demonstrations. In IJCAI, pages 3027-3033, 2017. IJCAI
- [Zadeh et al., 2018] Amir Zadeh, Paul Pu Liang, Soujanya Poria, Prateek Vij, Erik Cambria, and Louis-Philippe Morency. Multi-attention recurrent network for human communication comprehension. In AAAI, page 5642, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Learning from demonstrations (LfD) is a powerful approach for incorporating advice from experts in the form of demonstrations to accelerate the learning of new skills. However, existing work in LfD often assume that demonstrations are generated from a single agent with a single goal [Argall et al., 2009]. In practice, data can be available from multiple sub-optimal agents with conflicting goals. For example, when learning to operate a vehicle autonomously from demonstrators [Bojarski et al., 2016], different drivers can have different goals (destinations), needs (safety) and experience levels. Relying on demonstrators whose goals are misaligned with the new target task can lead to unintended or dangerous behaviors, and can be minimized by actively learning to trust the most relevant demonstrators.
In this paper, we focus on LfD with multiple conflicting demonstrators for solving static and dynamic optimization problems. Following existing work [Gao et al., 2018], demonstrations in our setting also contain immediate rewards, e.g. (s, a, r, s′ ), an instance of LfD referred to as reinforcement learning from demonstrations (RLfD). Our setting also differs from traditional work in LfD, in that the goal is to improve upon the demonstrator rather than simply mimic its behaviors. In order to measure the similarity between demonstrators' reward functions, we parameterize them as linear functions in a common feature space. Furthermore, we take a Bayesian approach by modeling their uncertainty using Normal-Inverse-Gamma priors. These quantities are modeled as Bayesian neural networks with a shared encoder, and trained end-to-end from demonstrations in an online manner. We then formulate a quadratic program whose solution yields a probability distribution over the demonstrators. This allows demonstrators to be sampled directly, while incorporating uncertainty in the estimates of their reward functions. Furthermore, being Bayesian allows us to avoid premature convergence, be more robust to non-stationary, sparse or limited data [Bishop, 2006], and trade off the mean and variance of the reward estimates in a principled way (Theorem 1).
∗Affiliate to Vector Institute, Toronto, Canada.
In order to transfer demonstrations to new tasks in LfD, one approach is to pre-train the learner directly on the source data [Cruz Jr et al., 2017], or learn and reuse auxiliary representations from the source data such as policies [Fern´andez et al., 2010]. However, the former can be ineffective when demonstrations assume conflicting goals, while meaningful policies can be difficult to solicit from the latter when demonstrators are limited, sub-optimal or exploratory in nature [Nicolescu and Mataric, 2003]. On the other hand, experience collected from a failed or inexperienced demonstrator can be just as valuable as an experienced one [Grollman and Billard, 2011]. We present an algorithm called Bayesian Experience Reuse (BERS), for directly reusing multiple demonstrations in a way that is consistent with the learned weighting over the source and target task goals (Algorithm 1). While tailored for LfD, our approach is quite general and can be applied in other areas such as multi-task learning.
2 Background
2.1 Reinforcement Learning
Decision-making in this paper can be summarized in a Markov decision process (MDP), formally defined as a fivetuple 〈S,A, P,R, γ〉, where: S is a set of states, A(s) is a set of possible actions in state s, P(·|s, a) gives the next-state s′ distribution upon taking action a in state s, R(s, a, s′ ) is the corresponding reward, and γ ∈ [0, 1] is a discount factor. The objective of an agent is to find a policy µ : S → A that maximizes the long-run expected return Qµ (s, a) = E[∑∞t=0 γ tR(st, at, st+1) | s0 = s, a0 = a], where at = µ(st) and st+1 ∼ P (·|st, at).
In the reinforcement learning (RL) setting, neither P nor R are known. Instead, the agent interacts with the environment using a randomized exploration policy µe , collecting rewards and observing state transitions. In order to learn optimal policies, temporal difference methods first learn Q(s, a) and use it to recover an optimal policy, while policy gradient methods parameterize and recover an optimal policy µ∗ directly. Actor-critic methods learn a critic Q(s, a) and actor policy µ(s) simultaneously [Sutton and Barto, 2018].
2.2 Common Feature Representations
In our problem setting, each task is associated with an unknown function y : X → R on some domain X. In the RL setting for example, y(x) = R(s, a, s′ ) are reward functions. Given a feature map φ : X → Rd , a function y can be expressed as a linear combination y(x) = φ(x)⊤w, ∀x ∈ X, where w ∈ Rd is a fixed vector.
We are interested in the problem of transferring demonstrations (s, a, r, s′ ) between tasks in a domain Mφ on a common X ,
In the RL setting, Mφ could include all MDPs with shared dynamics and different rewards Ri. In (1), we have explicitly assumed that the (unknown) state features φ are shared among tasks. This is not a restrictive assumption in practice, as given a set of tasks T1, T2 . . . Tn ∈ Mφ, we may trivially define φk(x) = yTk (x), ∀x ∈ X for each k = 1, 2 . . . n. In practice, however, different rewards may share common features. Pooling different sets of basis functions into a common basis in this way will also allow us to represent, and thus compare, conflicting goals consistently. The challenge is to learn suitable common embeddings φ and posterior distributions for y(x), and leverage them for measuring task similarity.
3 Bayesian Experience Reuse
The agent is presented with sets of demonstrations D1,D2, . . .DN sampled from respective source tasks T1, T2, . . . TN ∈ Mφ, that are represented as collections of labeled pairs (xt, yt). The agent would like to leverage these demonstrations to solve a new task, Ttarget ∈ Mφ, for which a limited but gradually growing set of demonstrations Dtarget is available.
In order to make optimal use of the source tasks during training, the agent should learn to favor demonstrators whose underlying reward representation is closest to the target task reward. By actively learning to trust relevant demonstrators and avoiding the irrelevant ones, an agent can maximize the benefit associated with pre-training on the corresponding demonstrations. Furthermore, reward representations are more natural and more robust for measuring task similarity than discounted value functions, because values are more sensitive to small changes in rewards. For instance, given a constant perturbation in rewards of ∆R, the corresponding value function will change by ∆R 1-γ that is considerably greater than ∆R in the non-myopic setting.
3.1 Bayesian Regression with Common Features
In order to facilitate the learning of reward representations, we learn a shared feature space φ, together with Bayesian regressions P(wi|Di) and P(wtarget|Dtarget) for the source and target tasks respectively, such that yi t ≈ φ(xit )⊤wi for all i and (xit , yi t ) ∈ Di and ytarget t ≈ φ(xtarget t )⊤wtarget for all (xtarget t , ytarget t ) ∈ Dtarget. As we will show, the shared feature representation φ is critical in order to allow meaningful comparisons between source wi and target w.
In order to tractably learn the features φ as well as the corresponding posterior distributions, we parameterize φ(x) ≈ φθ(x) using a deep neural network (encoder) with weight parameters θ, and model w1, . . . wN , wtarget using the normalinverse-gamma conjugate prior:
We note that a Gaussian prior on the rewards is quite reasonable, and has been successfully applied in other areas such as exploration [Janz et al., 2019]. The joint posterior P(wi, σ2 i |Di) now factors as
where wi|σ2 i ,Di ∼ N(µi, σ2 i Λ-1 i ) and σ2 i |Di ∼ InvGamma(αi, βi), where:
and where Φi is the matrix of state features φθ(xit ) and yi is the vector of observations yi t in Di [Bishop, 2006]. We have also assumed that, conditioned on data Di, the weights wi and variances σ2 i are mutually independent between tasks, a very mild assumption in practice. Adapting the neural-linear approach of [Ober and Rasmussen, 2019; Snoek et al., 2015], we update θ by gradient ascent on the marginal log-likelihood function for each head i,
where the key quantities are provided by (4) and depend implicitly on θ through Φi.
Now, parameter sharing allows φ to be learned, refined and transferred seamlessly from source to target tasks, and provides a form of transfer in its own right. However, our main contribution is to use the posterior distributions over experts' goals, wi and wtarget, to transfer demonstrations.
3.2 Expert Selection via Quadratic Programming
In order to derive a Bayesian decision rule for source task selection, we first observe that source tasks that are most similar to the target task- and hence those that lead to better transfer - should have wi closest to the true target wtarget. In our setting, we instead have uncertain estimates for wi and wtarget modelled as random variables. We therefore look for a weighting ∑Ni=1 aiwi that is closest to wtarget, while factoring in the uncertainty in these estimates.
More specifically, suppose that the posterior distributions of wi for each i = 1, 2 . . .N and wtarget have been estimated from past data. Our goal is to weight the wi in such a way that the weighted sum, ∑i aiwi, is closest to wtarget in expectation. In other words, we seek a that minimizes the following optimization problem:
where D = ⋃i Di ∪ Dtarget is the union of all source and target demonstrations, and P is a convex polyhedron. Specifically, our goal is to sample source tasks according to a, so we restrict a to a discrete probability distribution by setting P = {a ∈ RN : 1⊤a = 1, a ≥ 0}. In other applications, such as regression problems [Pardoe and Stone, 2010], we may set P = RN , or incorporate other constraints on expert selection depending on the problem.
The following result will facilitate the optimization of (6) under our previous assumptions.
Theorem 1. Suppose w1 . . .wN and wtarget are defined by the posterior (3). Then, for every a ∈ RN ,
with equivalence up to terms constant in a.
Hence, we have shown that optimizing the expected error (6) is equivalent to optimizing the error in the posterior means plus a penalty equal to the product of the noise and posterior variances. The penalty term prevents the posterior a from concentrating all its probability mass on a single demonstrator, whose benefit is demonstrated experimentally. To simplify (7) further, we define M = [µ1 . . .µN] ∈ Rd×N and S ∈ RN×N the diagonal matrix with entries βi αi-1 tr(Σi), i = 1, 2 . . .N. Rewriting (7) in this new notation and invoking Theorem 1, we obtain the following quadratic program (QP):
Here, M⊤M+S is positive definite, since it is the sum of the positive semi-definite matrix M⊤M and the positive definite matrix S. Hence, the above QP can be formulated and solved exactly using an off-the-shelf solver in polynomial time in N, independent of the dimension d and the number of demonstrations |Di|. Hence, (8) remains tractable when the domain complexity is high or the number of demonstrations is s.t. 1⊤a = 1, a ≥ 0.
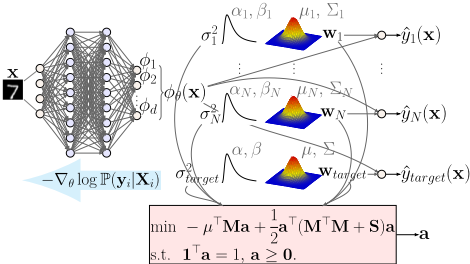
Figure 1: Bayesian multi-headed neural-linear model with shared encoder (MLP) and aggregated QP decision layer.
large. This is no longer the case when the second order term S is omitted, since (8) can become rank-deficient and lack a unique solution.
In the case of very large N, warm starts could be effective since the posterior changes smoothly over time (as we demonstrate experimentally), to use neural networks [Amos and Kolter, 2017], or optimize (8) directly via gradient descent. Our framework is agnostic to how (8) is solved, so we leave these investigations for future work.
The full architecture is summarized conceptually in Figure 1. Here, Bayesian heads with parameters {(µi,Λi, αi, βi)}Ni=1 and (µ,Λ, α, β) are maintained for source and target tasks respectively, while sharing the encoder parameters θ. Periodically, these estimates are used to construct and solve (8). The outputs ˆ yi and ˆ ytarget can also be used for making predictions, such as in regression problems. In this paper, our goal instead is to use the posterior distributions over task goals, and the corresponding QP solution, to rank and transfer the most relevant source demonstrations.
3.3 Bayesian Experience Reuse
A simple, yet effective, approach for transferring demonstrations from a single source is to pre-train the learning agent on the demonstrations [Cruz Jr et al., 2017]. However, when data originates from multiple demonstrators with differing goals, some interaction or prior knowledge about the target environment is necessary in order to determine which data to use for pre-training. Without assuming any prior knowledge about the target environment, we train the agent on the source data in an offline manner while concurrently learning the target task online. Thus, the source demonstrations provide an effective exploration bonus, by enriching the agent's training data with novel experiences that might otherwise never be observed in the target task.
More specifically, in each episode of target task learning m, we sample a source task Ti ∈ Mφ according to a obtained from (8), and train the agent on experiences drawn from the corresponding data Di. In order for the target agent to improve beyond the demonstrator and generalize correctly to the target task, the agent must eventually learn from target demonstrations rather than source data. So, we adapt the sample annealing idea in [Fern´andez et al., 2010], by grad-
Algorithm 1 Bayesian Experience Reuse (BERS)
Require: {Di}Ni=1 , TN+1 = Ttarget ∈ Mφ, Obase, DN+1 = Dtarget = ∅, θ, {µi, Λi, αi, βi}N+1 i=1 , pm, a pre-train θ, {µi, Λi, αi, βi}Ni=1 on {Di}Ni=1 using (4), (5) for episode m = 1, 2, . . . do for step t = 1, 2, . . . T of episode m do explore Ttarget using Obase and collect d = (x, y) Dtarget = Dtarget ∪ d sample train on source data ∼ Bernoulli(pm) if train on source data = true then sample it ∼ a and experience B ⊂ Dit else sample experience B ⊂ Dtarget end if train Obase on B end for train θ, {µi, Λi, αi, βi}N+1 i=1 on {Di}N+1 i=1 using (5) solve QP (8) to obtain the solution a end for return Obaseually decreasing the fraction of time pm ∈ [0, 1] that the agent trains on source data. The resulting approach, which we call Bayesian Experience Reuse (BERS), is outlined in Algorithm 1.
In particular, we define Obase as a learning algorithm for solving the target task, assumed to be a static or dynamic optimization problem in this work. Hence, Obase is either a static optimization algorithm or an reinforcement learning algorithm. We first pre-train the N source heads on the source demonstrations to learn φ and the posteriors for w1 . . .wN. In each episode, we explore the target task and collect data, putting them in Dtarget. At each time step, the agent either trains on a batch of source demonstrations from task i ∼ a with probability pm, or a batch of target demonstrations with probability 1 - pm. At the end of each episode, we refine φ and the posterior distributions for all tasks and recompute a. With simple modifications, BERS can be applied in multitask settings by maintaining a separate QP solution per task.
4 Empirical Evaluation
In order to demonstrate the effectiveness of BERS, we consider two problems: (1) the search for the minimum of static but high-dimensional multi-modal functions, and (2) the dynamic control of a complex supply chain network with stochastic demand 1 .
4.1 Static Optimization of Multi-Modal Functions
We first consider the problem of finding the minimum of a smooth but highly complex multi-modal function. LfD can be useful in this setting because the known solution of one function can be used as an initial "guess" when starting the search for the minimum of another similar function.
1 The appendix can be found at https://github.com/mikegimelfarb/bayesian-experience-reuse.
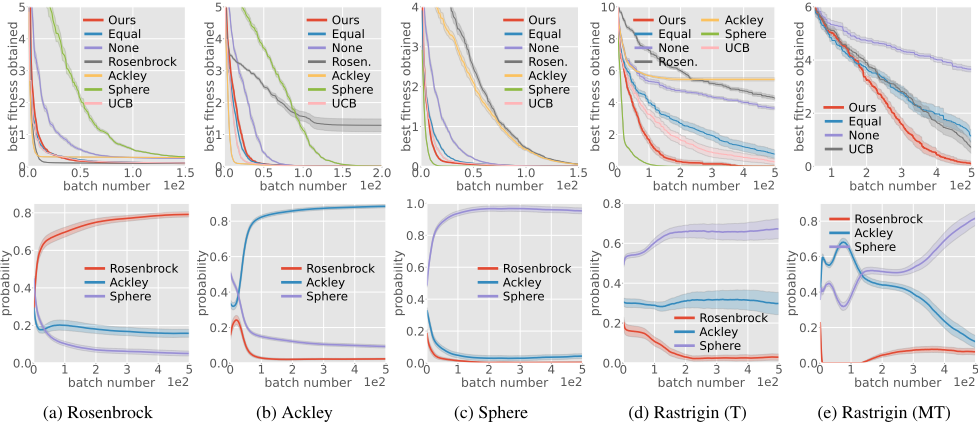
More specifically, we use the 10-dimensional Rosenbrock, Ackley and sphere functions as source tasks, and the Rastrigin function as the target task (please see appendix for definitions and processing). We also consider the simpler setting in which one of the source functions is the ground truth. As the base learning agent Obase, we use Differential Evolution (DE) (please see appendix for details) 2 . The search is limited to xi ∈ [-4, 4] for all i = 1, 2 . . . 10. The global minimums of the functions are: x∗Rosenbrock = 1, x∗Ackley = 0, x∗Sphere = -2 and x∗Rastrigin = -2. Since the sphere and Rastrigin functions are locally similar around the minimum point, a successful LfD experiment should exploit the structure of the functions when optimizing the Rastrigin function. We also consider the multi-task setting by optimizing the Rastrigin function simultaneously with the other source functions, to demonstrate the versatility of BERS. In the latter setting, we maintain a separate QP solution per task. In both cases, the best solution found for each source task to date is transferred directly to Obase (the appendix details how the solutions are transferred).
We consider the following set of baselines in order to compare the performance of BERS (Ours): (1) the UCB algorithm [Auer, 2002] with asymptotically optimal convergence (UCB), in which the reward is the improvement in the function value after transferring a solution from one of the source functions, (2) the equally-weighted prior a = [ 1N , . . . 1N ] (Equal), (3) individual demonstrators (S1, S2. . . ), and (4) standard DE without transfer (None). Figure 3 illustrates the function value of the best solution found to date, and the value of a, after each iteration.
4.2 Dynamic Control of a Supply Chain
A supply chain network for the production and distribution of a single product consists of a central factory and K = 6 warehouses, denoted A, B . . . F. The factory can manufacture up to 35 units of inventory per day, and the factory and the warehouses can each store up to 50 units of inventory at any given time. A very large fleet of trucks is available to move inventory between points in the network. Each truck can deliver up to 4 units of inventory between any two points in the network, and takes a single day regardless of location.
Demand for each warehouse A, B . . . F, in units per day, is Poisson-distributed with respective means {7, 6, 6, 5, 5, 5}. Demand that cannot be fulfilled is lost forever. The selling price per unit of inventory is 0.6, the production cost is 0.1, and the storage cost per unit per day is 0.03 for the factory and each warehouse. However, the cost of dispatching a truck is not fixed, but depends on the source and destination node.
2 Another option is to use Bayesian optimization (BO). However, this is more suitable for expensive functions with relatively low numbers of local optima, such as for hyper-parameter optimization.
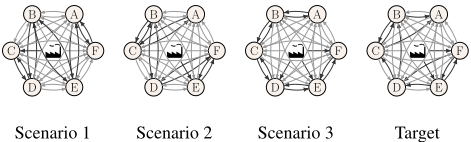
There are two kind of routes: cheap routes are easy to navigate and incur a cost of 0.03 per truck, whereas expensive routes have difficult terrain and tariffs and cost 1.50 or 3.00, depending on source or destination. The company does not know the cost of each route in advance, but has identified three likely scenarios, summarized in Figure 2. Here, cheap routes are indicated with lighter arrows, while more expensive routes are indicated with darker arrows. As before, we will take the company's estimates as source tasks and as the ground truth, and also consider the setting where the target task is different from any of the source tasks. Please note that this problem is quite similar to the one in [Kemmer et al., 2018], but our version is considerably more challenging.
We solve this problem using reinforcement learning, where the state is the current stock in the factory and warehouses, and actions are modelled as follows: (1) one continuous action for production as a proportion of the maximum; (2) K+1 actions for proportions of factory stock to ship to each warehouse (including to keep at the factory); and (3) K actions per warehouse, for proportions of warehouse stocks to ship to all other warehouses (including itself). This leads to a 2 +K +K2 = 44-dimensional continuous action space. In order to tractably solve this problem, we use the actor-critic algorithm DDPG [Lillicrap et al., 2016] as Obase (further details are provided in the appendix).
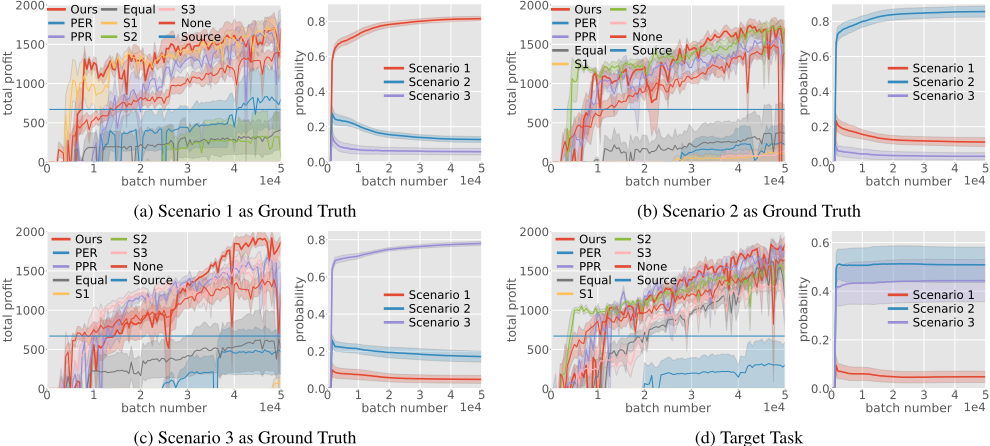
We evaluate BERS (Ours) against: (1) prioritized experience replay initialized with demonstrations from all source tasks [Hou et al., 2017] (PER), and (2) a state-of-the-art policy reuse algorithm [Li and Zhang, 2018] (PPR). In the latter choice, a source policy is trained using the same architecture as the actor network for DDPG for 50 epochs using the crossentropy loss, and used for exploration. Figure 4 illustrates the total profit achieved during each episode of testing using the greedy policy, and the corresponding QP weights.
4.3 Discussion
On the static optimization task, BERS performs comparatively similar to the single best demonstrator, because it is able to identity the most suitable source task after observing a small number of target demonstrations (Figure 3). While UCB is a strong baseline, BERS finds the solution in less iterations while incurring less variability. As postulated, the solution to (8) favours the Sphere function when solving the Rastrigin function, because they are structurally the most similar, and this leads to a quicker identification of the global minimum for the Rastrigin function.
On the supply chain task, BERS also achieves results similar to the single best expert, and does slightly better than PPR. While their asymptotic performance on Scenario 1 is similar, BERS achieves better jump-start performance on Scenario 1 and better asymptotic performance on Scenarios 2 and 3. One reason for this is that PPR, despite being trained on the same data as BERS, must learn a policy from noisy observations. Despite this, both BERS and PPR are able to quickly surpass the performance of the policy that originally generated the source data (horizontal line in Figure 4). On the other hand, PER was not able to obtain satisfactory performance, because PER prioritizes experiences by TD error that is not suitable for ranking demonstrations with different rewards. On the other hand, BERS learns a common feature embedding that allows for consistent comparison between tasks (Appendix).
Finally, on the target scenario, we can see that the weights assigned to Scenarios 1 and 2 are roughly equal, which makes sense as the target task shares some similarities with both of the aforementioned scenarios (Figure 2). By mixing two source tasks, BERS is able to perform substantially better on the target task than the two source tasks (S2 and S3) in isolation. Also, by adopting a Bayesian treatment, it enjoys stable convergence of the task weights a on all experiments.
5 RelatedWork
Most work in LfD incorporates demonstrations from a single expert [Argall et al., 2009]. Some papers in the area of RLfD relax this assumption to a single sub-optimal demonstrator and use pre-training [Gao et al., 2018; Hester et al., 2018], reward shaping [Suay et al., 2016], ranking [Wang and Taylor, 2017], or other approaches. However, these papers cannot learn from multiple demonstrators with conflicting goals. Papers on this topic typically assume multiple near-optimal demonstrators, so that recovering policies [Barreto et al., 2017; Fern´andez et al., 2010; Madarasz and Behrens, 2019] is possible. While our paper shares some similarities with these, it is fundamentally different. First, this stream of literature studies policy transfer, whereas we study LfD. BERS does not learn auxiliary representations for source demonstrators' behaviors (e.g. value functions or policies), allowing it to incorporate sub-optimal exploration data. Furthermore, BERS learns a latent representation of the task goals in an online setting not studied in prior work.
More generally, our approach is related to multi-modal learning, in which a common representation of multiple heterogeneous data sources is learned [Hausman et al., 2017; Tsai et al., 2019]. However, to our knowledge, papers on this topic have not been applied to our problem setting. Furthermore, our learned weightings over demonstrators could be seen as a form of attention [Zadeh et al., 2018]. The idea of learning shared features is inspired by both encoder sharing [Flet-Berliac and Preux, 2019] and uncertainty quantification [Azizsoltani et al., 2019; Brown et al., 2020]. Finally, our approach shares some of the similarities of Bayesian policy reuse [Rosman et al., 2016], by formulating the problem of policy selection as a Bayesian choice problem. However, our work differs in that we apply Bayesian inference for LfD instead of policy transfer. Our work is the first to apply these ideas towards LfD from multiple demonstrators.
6 Conclusion
We studied the problem of LfD with multiple sub-optimal demonstrators with different goals in a Bayesian setting. We proposed a multi-headed Bayesian neural network to efficiently learn consistent representations of the source and target reward functions from the demonstrations. Reward functions were parameterized as linear models, whose uncertainty was modeled using Normal-Inverse-Gamma priors and updated using Bayes' rule. A QP formulation ranked the demonstrators while trading off the mean and variance of the uncertainty in the learned reward representations, and Bayesian Experience Reuse (BERS) was proposed to incorporate demonstrations directly when learning new tasks. Empirical results show that BERS can successfully transfer experience from conflicting demonstrators.
@inproceedings{ijcai2021p334,
  title     = {Bayesian Experience Reuse for Learning from Multiple Demonstrators},
  author    = {Gimelfarb, Mike and Sanner, Scott and Lee, Chi-Guhn},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {2425--2431},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/334},
  url       = {https://doi.org/10.24963/ijcai.2021/334},
}
TY - CPAPER TI - Bayesian Experience Reuse for Learning from Multiple Demonstrators AU - Gimelfarb, Mike AU - Sanner, Scott AU - Lee, Chi-Guhn T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 2425 EP - 2431 DO - 10.24963/ijcai.2021/334 UR - https://doi.org/10.24963/ijcai.2021/334 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





