
Reconciling Rewards with Predictive State Representations
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 2170-2176.
https://doi.org/10.24963/ijcai.2021/299
Keywords
- Machine Learning: Reinforcement Learning
- Uncertainty in AI: Uncertainty Representations
- Planning and Scheduling: POMDPs
Abstract
Predictive state representations (PSRs) are models of controlled non-Markov
observation sequences which exhibit the same generative process governing
POMDP observations without relying on an underlying latent state. In that
respect, a PSR is indistinguishable from the corresponding POMDP. However,
PSRs notoriously ignore the notion of rewards, which undermines the general
utility of PSR models for control, planning, or reinforcement learning.
Therefore, we describe a sufficient and necessary accuracy condition
which determines whether a PSR is able to accurately model POMDP rewards, we
show that rewards can be approximated even when the accuracy condition is not
satisfied, and we find that a non-trivial number of POMDPs taken from a
well-known third-party repository do not satisfy the accuracy condition.
We propose reward-predictive state representations (R-PSRs), a
generalization of PSRs which accurately models both observations and rewards,
and develop value iteration for R-PSRs. We show that there is a mismatch
between optimal POMDP policies and the optimal PSR policies derived from
approximate rewards. On the other hand, optimal R-PSR policies perfectly
match optimal POMDP policies, reconfirming R-PSRs as accurate state-less
generative models of observations and rewards.
- [Bonet, 1998] Blai Bonet. Solving large POMDPs using real time dynamic programming. In Proceedings of AAAI Fall Symposium on POMDPs, 1998.
- [Boots et al., 2011] Byron Boots, Sajid M. Siddiqi, and Ge- offrey J. Gordon. Closing the learning-planning loop with predictive state representations. The International Journal of Robotics Research, 30(7):954-966, 2011.
- [Bowling et al., 2006] Michael Bowling, Peter McCracken, Michael James, James Neufeld, and Dana Wilkinson. Learning predictive state representations using non-blind policies. In Proceedings of the 23rd International Confer- ence on Machine Learning, pages 129-136. ACM, 2006.
- [Cassandra et al., 1994] Anthony R. Cassandra, Leslie Pack Kaelbling, and Michael L. Littman. Acting optimally in partially observable stochastic domains. In Proceedings of the 12th AAAI National Conference on Artificial Intelli- gence, volume 94, pages 1023-1028, 1994.
- [Cassandra et al., 1997] Anthony R. Cassandra, Michael L. Littman, and Nevin Lianwen Zhang. Incremental prun- ing: A simple, fast, exact method for partially observable Markov decision processes. In Proceedings of the 13th Conference on Uncertainty in Artificial Intelligence, pages 54-61, 1997.
- [Cassandra, 1999] Anthony R. Cassandra. Tony's POMDP file repository page, 1999.
- [Izadi and Precup, 2003] Masoumeh T. Izadi and Doina Pre- cup. A planning algorithm for predictive state representa- tions. In Proceedings of the 18th International Joint Con- ference on Artificial Intelligence, pages 1520-1521, 2003.
- [Izadi and Precup, 2008] Masoumeh T. Izadi and Doina Pre- cup. Point-based planning for predictive state representa- tions. In Conference of the Canadian Society for Compu- tational Studies of Intelligence, pages 126-137. Springer, 2008.
- [James and Singh, 2004] Michael R. James and Satinder Singh. Learning and discovery of predictive state represen- tations in dynamical systems with reset. In Proceedings of the 21st International Conference on Machine Learning, page 53. ACM, 2004.
- [James et al., 2004] Michael R. James, Satinder Singh, and Michael L. Littman. Planning with predictive state repre- sentations. In Proceedings of the International Conference on Machine Learning and Applications, pages 304-311. IEEE, 2004.
- [James et al., 2006] Michael R James, Ton Wessling, and Nikos Vlassis. Improving approximate value iteration us- ing memories and predictive state representations. In Pro- ceedings of the 21st National Conference on Artificial In- telligence, volume 1, pages 375-380, 2006.
- [Littman and Sutton, 2002] Michael L. Littman and Richard S. Sutton. Predictive representations of state. In Advances in Neural Information Processing Systems, volume 14, pages 1555-1561, 2002.
- [McCracken and Bowling, 2006] Peter McCracken and Michael Bowling. Online discovery and learning of predictive state representations. In Advances in Neural Information Processing Systems, pages 875-882, 2006.
- [Meuleau et al., 1999] Nicolas Meuleau, Leonid Peshkin, Kee-Eung Kim, and Leslie Pack Kaelbling. Learning finite-state controllers for partially observable environ- ments. In Proceedings of the 15th conference on Uncer- tainty in artificial intelligence, pages 427-436, 1999.
- [Rosencrantz et al., 2004] Matthew Rosencrantz, Geoff Gor- don, and Sebastian Thrun. Learning low dimensional pre- dictive representations. In Proceedings of the 21st Interna- tional Conference on Machine Learning, page 88. ACM, 2004.
- [Singh et al., 2003] Satinder P. Singh, Michael L. Littman, Nicholas K. Jong, David Pardoe, and Peter Stone. Learn- ing predictive state representations. In Proceedings of the 20th International Conference on Machine Learning, pages 712-719, 2003.
- [Singh et al., 2004] Satinder Singh, Michael R. James, and Matthew R. Rudary. Predictive state representations: A new theory for modeling dynamical systems. In Proceed- ings of the 20th conference on Uncertainty in Artificial In- telligence, pages 512-519. AUAI Press, 2004.
- [Smallwood and Sondik, 1973] Richard D. Smallwood and Edward J. Sondik. The optimal control of partially observ- able Markov processes over a finite horizon. Operations research, 21(5):1071-1088, 1973.
- [Wiewiora, 2005] Eric Wiewiora. Learning predictive repre- sentations from a history. In Proceedings of the 22nd In- ternational Conference on Machine Learning, pages 964- 971, 2005.
- [Wolfe et al., 2005] Britton Wolfe, Michael R. James, and Satinder Singh. Learning predictive state representations in dynamical systems without reset. In Proceedings of the 22nd International Conference on Machine Learning, pages 980-987. ACM, 2005.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Predictive state representations (PSRs) are models of controlled observation sequences which exhibit the same generative properties as partially observable Markov decision processes (POMDPs) [Littman and Sutton, 2002; Singh et al., 2004]. Compared to POMDP models, PSRs lack an underlying latent state; instead, the system state is grounded in predicted likelihoods of future observations. The structure of PSRs only involves observable quantities, therefore learning a PSR model is generally considered to be simpler than learning a latent-state model such as a POMDP [Wolfe et al., 2005]. Hence, significant research effort has been collectively spent on PSR model learning [Singh et al., 2003; James and Singh, 2004; Rosencrantz et al., 2004; Wolfe et al., 2005; Wiewiora, 2005; Bowling et al., 2006; McCracken and Bowling, 2006; Boots et al., 2011]. Likewise, a number of control and reinforcement learning methods have been successfully adapted to PSRs, e.g., policy iteration [Izadi and Precup, 2003], incremental pruning [James et al., 2004], point-based value iteration [James et al., 2006; Izadi and Precup, 2008], and Q-learning [James et al., 2004].
∗Appendix available at https://arxiv.org/abs/2106.03926.
†Code available at https://github.com/abaisero/rl-rpsr.
While PSRs are a promising alternative to POMDPs for modeling observation sequences, they notoriously lack the ability to model rewards appropriately. In fact, we show that PSRs are able to represent only a specific subset of reward functions representable by finite POMDPs. Prior work in PSR-based control can be split in two groups depending on how reward modeling is addressed: (a) In the first group, a linear PSR reward function which encodes the appropriate task is directly given and/or assumed to exist [Izadi and Precup, 2003; Izadi and Precup, 2008; Boots et al., 2011], which means that these methods cannot be used to solve problems which cannot be modeled by vanilla PSRs. Further, directly designing PSR rewards which are not grounded to a latent state is extremely unintuitive, compared to designing POMDP rewards grounded on state. (b) In the second group, a reward-aware PSR (RA-PSR) models rewards by making them explicitly observable and an integral part of the agent's observable history [James et al., 2004; James et al., 2006]. However, in partially observable sequential decision making problems such as POMDPs, rewards are a construct meant to rank agent behaviors based on how well they solve a task, rather than an intrinsic aspect of the environment like states and observations. In fact, it is not uncommon for rewards to be available during offline training but not during online execution. Further, an agent which is able to observe rewards will be able to condition its behavior based on rewards and/or infer the latent state using rewards, which is not generally allowed when solving POMDPs. Therefore, while RA-PSRs are able to represent reward functions which are not representable by vanilla PSRs, they are still unable to represent the full range of control tasks representable by POMDPs, which do not assume observable rewards.
In this work, we first develop the theory of PSR reward processes, and then a novel extension of PSRs which is able to model any reward process without making rewards explicitly observable by the agent. Our contributions are as follows: (a) We derive a sufficient and necessary accuracy condition which determines whether the rewards of a POMDP can be accurately represented by a PSR, and a linear approximation for when the accuracy condition is not satisfied; (b) We develop reward-predictive state representations (R-PSRs), a generalization of PSRs capable of representing the reward structure of any finite POMDP; (c) We adapt Value Iteration (VI) to R-PSRs; (d) We show that a non-trivial portion of common finite POMDPs, taken from a third-party repository, do not satisfy the accuracy condition; and (e) We evaluate the optimal policies derived by POMDPs, PSRs and R-PSRs according to the other's reward structure, confirming that even the best linear reward approximations in PSRs may catastrophically alter the underlying task, while the reward structure of R-PSRs perfectly matches that of the original POMDPs. Our work represents a significant step towards being able to use PSRs to model realistic environments which do not assume observable rewards, and opens the door for more complicated and scalable methods able to exploit the structure of the proposed R-PSR model.
2 Background
Notation. We use bracket notation [v]i and [M]ij to index vectors and matrices. [M]i: and [M]:j respectively indicate the i-th row vector and the j-th column vector of M. We use ∆X to indicate the set of probability distributions over set X , and boldface x to indicate a random variable. To avoid ambiguity, we will sometimes denote quantities associated with POMDPs using superscript (b) , those associated with PSRs using (p) , and those associated with R-PSRs using (r) .
2.1 POMDPs
A POMDP [Cassandra et al., 1994] is a tuple 〈S,A,O, T,O,R, γ〉 constisting of: state, action, and observation spaces S, A, O; transition function T : S ×A → ∆S; observation function O: S ×A×S → ∆O; reward function R: S × A → R; and discount factor γ ∈ [0, 1]. We focus on finite POMDPs, whose sets S, A and O are finite; consequently, POMDP functions and related quantities can be represented as matrices and vectors, e.g., the reward matrix [R]ij .= R(s = i, a = j).
Interactions, Histories, and Beliefs. We define an interaction ao ∈ A × O as an action-observation pair representing a single exchange between agent and environment, and its generative matrix Gao ∈ R|S|×|S| as [Gao]ij .= Pr(s′ = i, o | s = j, a), which encodes both state transition and observation emission probabilities. A history h ≡ a1o1a2o2 . . . is a sequence of interactions, and the cumulative observable past. We use string concatenation to denote the concatenation of histories and/or interactions, e.g., h1h2 or hao. We denote the space of all histories as H .= (A×O)∗ , and the empty history as ε. A belief b: H → ∆S is the distribution over states following history h, i.e., vector [b(h)]i .= Pr(s = i | h). We define the history reward function R(h, a) ↦→ E [R(s, a) | h] = b(h)⊤ [R]:a .
2.2 Predictive State Representations
A PSR is a discrete-time controlled dynamical system which lacks the notion of a latent state [Littman and Sutton, 2002; Singh et al., 2004]; rather, the system state is composed of the predictive probabilities of hypothetical futures called tests.
Tests and their Probabilities. A test q ≡ a1o1a2o2 . . . islike a history-a sequence of interactions. We denote the space of all tests as Q .= (A×O)∗ , and the empty test as ε. Although histories and tests are structurally equivalent, they differ semantically in that the former refer to the past, and the latter to hypothetical futures. We generalize the generative matrix to tests via Gq = · · · Ga2o2 Ga1o1 . The action and observation sequences associated with a test q are denoted respectively as aq ∈ A∗ and oq ∈ O∗ . A test probability p(q | h) .= Pr(oq | h, aq) is the probability of the test observations oq if the test actions aq are taken from the history h as a starting point. Test probabilities are the core quantity modeled by a PSR. A linear predictive state p(h) ∈ R|Q† | (where Q† is a core set of tests, defined later) is a representation of history h such that test probabilities are linear in p(h), i.e., p(q | h) = p(h)⊤mq, where mq ∈ R|Q† | is the parameter vector associated to test q. Littman and Sutton [2002] show the vectorized form of test probabilities based on beliefs (using a less general version of the generative matrix Gq),
where the linear products represent an implicit marginalization over the sequence of latent states.
Outcome Vectors. The outcome of a test u(q) ∈ [0, 1]|S| is a vector indicating the test probabilities from each state as a starting point, i.e., [u(q)]i .= Pr(oq | s = i, aq). Outcomes can be defined recursively via the generative matrix,
Combining Equations (1) to (3) results in p(q | h) = b(h)⊤u(q), i.e., the test probability given a history is the expectation of test probabilities given each state. A set of tests is said to be linearly independent iff the respective outcome vectors are linearly independent, and any maximal set of linearly independent tests is called a core set, denoted as Q† . While there are infinite core sets, they all share the same size |Q† |, called the PSR rank, which is upper-bounded by |Q† | ≤ |S| [Littman and Sutton, 2002].
Predictive States. The outcome matrix U ∈ [0, 1]|S|×|Q† | of a core set Q† is the column-wise stacking of the core outcome vectors {u(q) | q ∈ Q† }. By the definition of a core set, the outcome u(q) of any non-empty test q ̸= ε is a linear combination of the core outcome matrix U columns (else the core set would not be maximal), i.e., u(q) ∈ col U and, because UU + is the projection onto col U, then u(q) = UU +u(q). Consequently, p(q | h) = b(h)⊤u(q) = b(h)⊤UU +u(q) = p(h)⊤mq, where p(h)⊤ .= b(h)⊤U is the predictive state, and mq .= U +u(q) is the parameter vector of q. Each dimension of p(h) is itself the test probability of a core test, i.e., [p(h)]i = p(qi | h), where qi is the ith core test.
Emissions and Dynamics. Observation probabilities are Pr(o | h, a) = p(ao | h) = p(h)⊤mao, while the predictive state dynamics are p(hao) = (p(h)⊤Mao )/(p(h)⊤mao ), where Mao is the column-wise stacking of the extended core test parameters {maoq | q ∈ Q† }.
2.3 Value Iteration
Ultimately, we wish to compare POMDP, PSR and R-PSR models by comparing their respective induced optimal policies. Although a number of modern solution methods could be used for this purpose, we employ simple value iteration (VI) as an arguably necessary stepping stone, leaving more modern methods for future work. Value iteration (VI) is a family of dynamic programming algorithms which estimate the optimal value function V ∗(k) (h) for increasing horizons k, from which optimal actions can be derived. Variants have been developed for POMDPs and PSRs [James et al., 2004; Boots et al., 2011]. A k-horizon policy tree π is composed of an initial action aπ and a (k - 1)-horizon sub-policy tree πo for each possible observation. We denote the space of khorizon policies as Π(k) .
Value iteration for POMDPs (POMDP-VI) [Cassandra et al., 1994] is based on the linearity of policy tree value functions in the belief state, Vπ(h) = b(h)⊤α(b) π , where α(b) π is the alpha vector representing the values of π. The optimal k-horizon value function is the maximum over policy value functions, V ∗(k) (h) = maxπ∈Π(k) b(h)⊤α(b) π , and is notably piecewise linear and convex (PWLC) [Smallwood and Sondik, 1973]. POMDP-VI iteratively computes the alpha vectors απ of policy trees π ∈ Π(k) for increasing horizons using απ = [R(b) ]:aπ if k = 1, and απ = [R(b) ]:aπ + γ ∑o G⊤aoαπo if k > 1. In practice, some alpha vectors are dominated by others, and can be pruned to mitigate the exponential growth [Cassandra et al., 1997].
Value iteration can be adapted to PSRs (PSR-VI) [James et al., 2004; Boots et al., 2011] under a linear PSR reward function R(p) (h, a) .= p(h)⊤ [R(p) ]:a . Many properties of POMDP-VI remain valid for PSR-VI, including the linearity of value functions V (p) π = p(h)⊤α(p) π , and the PWLC property of the optimal k-horizon value function. PSR-VI iteratively computes the alpha vectors α(p) π of policy trees π ∈ Π(k) for increasing horizons using απ = [R(p) ]:aπ if k = 1, and απ = [R(p) ]:aπ + γ ∑o Maoαπo if k > 1.
3 The Failure of PSRs as RewardModels
Given any finite POMDP, the respective PSR state p(h) holds sufficient information to represent the probability of future observations. In this section, we show that the same cannot be said about being able to represent future rewards. We develop theory regarding a PSR model's (in)ability to accurately model POMDP rewards.
3.1 Theory of PSRReward Accuracy
Proposition 1. For any finite POMDP and its respective PSR, a (linear or non-linear) function f(p(h), a) ↦→ R(b) (h, a) does not necessarily exist. (proof in Appendix).
For tractability reasons, we consider the family of linear PSR rewards represented by matrix R(p) ∈ R|Q† |×|A| , such that R(p) (h, a) .= p(h)⊤ [R(p) ]:a . Ideally, it would always be possible to express the true rewards R(b) (h, a) in such a way. Unfortunately, this is not always possible.
Theorem 1 (Accurate Linear PSR Rewards). A POMDP reward matrix R(b) can be accurately converted to a PSR reward matrix R(p) iff every column of R(b) is linearly dependent on the core outcome vectors (the columns of U). If this condition is satisfied, we say that the PSR is accurate, and R(p) = U +R(b) accurately represents the POMDP rewards. (proof in Appendix).
As a direct consequence of Theorem 1, a PSR can only accurately model a sub-space of POMDP rewards R(b) ∈ {UW | W ∈ R|Q† |×|A| }. Also, full-rank PSRs are always accurate, while low-rank PSRs-often praised for their representational efficiency-are most likely to suffer from this issue. Corollary 1 shows the reverse problem does not exist.
Corollary 1. Assuming that a PSR can be represented by a finite POMDP, then any PSR rewards R(p) are accurately represented by POMDP rewards R(b) = UR(p) . (proof in Appendix).
Next, we consider whether it is possible to formulate an appropriate approximation of POMDP rewards for a nonaccurate PSR. Ideally, we care for PSR rewards which induce the optimal policy and/or values most similar to those of the POMDP. However, it is extremely challenging to fully analyze the effects of rewards on policies (which is the control problem itself); therefore, we will use reward errors as a proxy. Note that, while this methodology is extremely simple, it is also imperfect, since small reward errors may lead to large policy errors, while large reward errors may lead to small policy errors. While it is possible to consider preferences over histories/beliefs which should result in a lower approximation error (e.g., the reachable histories/beliefs), that kind of prior knowledge is not common. Therefore, we consider reward approximations where the approximation errors for all histories/beliefs are weighted uniformly.
Theorem 2 (Approximate Linear PSR Rewards). The linear approximation of POMDP rewards for non-accurate PSRs which results in the lowest reward approximation error is R(p) .= U +R(b) . (proof in Appendix).
Notably, Theorems 1 and 2 share the same expression for R(p) , which is unsurprising since an accurate estimate is just an errorless approximate estimate. The ability to compute approximate rewards via Theorem 2 begs the question of whether they are accurate enough to serve as a basis for control. Unfortunately, the connection between PSR rewards and optimal policy is not as straightforward and interpretable as in POMDPs, since the rewards are encoded in terms of test probabilities rather than states. To answer this question quantitatively, one can solve both the POMDP and the approximate PSR, and compare the respective optimal policies/values directly; however, this approach is very expensive. Luckily, Corollary 2 provides a simple qualitative approach which allows one to interpret approximate PSR rewards directly by reconstructing equivalent POMDP rewards.
| Core test q ∈ Q† | Outcome u(q)⊤ |
|---|---|
| left loading right travel right unloading right travel, left loading left travel, right travel | (1 1 1 1 0 0 0 0 0 0) (1 1 1 1 1 1 0 0 0 0) (0 0 0 0 0 0 1 1 1 1) (1 1 0 0 0 0 0 0 0 0) (0 0 0 0 1 1 1 1 0 0) |
Corollary 2. ˜R(b) .= UU +R(b) is the reconstructed POMDP-form of the PSR approximation R(p) of the true POMDP rewards R(b) . ˜R(b) and R(b) are equal iff the accuracy condition is satisfied. (proof in Appendix).
Next, we provide a detailed case study demonstrating the theory developed here. In Section 5 we show empirically that, if there is any approximation error at all, then there is a high chance that the policy has been altered catastrophically.
3.2 ACase Study of Approximate PSRRewards
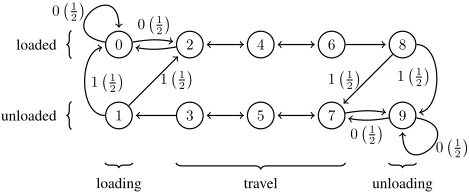
We use the load/unload domain (POMDP in Appendix) shown in Figure 1 as a case study to show a catastrophic failure of approximate PSR rewards. The agent navigates a corridor of 5 cells under partial observability of its own position and whether it is carrying a load or not. Rewards are given for loading (when not loaded) at one end of the corridor, and unloading (when loaded) at the other end. The task is to keep moving back and forth between one end of the corridor (loading) and the other (unloading).
The domain has |S| = 10 states, but its PSR rank is |Q† | = 5. Table 1 shows a core set Q† and the respective outcome vectors u(q). By Theorem 1 there is an entire subspace of reward functions which cannot be accurately represented, and there is a chance that the corresponding PSR model is not accurate; we will verify that this is indeed the case. We note that the outcomes in Table 1 are also the columns of matrix U, and that every pair of rows in U (columns in Table 1) is identical. This means that the PSR is unable to make any distinction between states 0 and 1, 2 and 3, etc, which will cause a problem, because the POMDP reward function specifically needs to differentiate between states 0 and 1, and 8 and 9.
Next, we show the POMDP rewards R(b) (note that only states 1 and 8 emit rewards),
the PSR approximation (Theorem 2) R(p) = U +R(b) ,
and the POMDP reconstruction (Corollary 2) ˜R(b) = UR(p) (note that states 0, 1, 8 and 9 emit rewards),
The approximate rewards R(p) are hard to interpret, and it is not obvious that something is wrong. However, looking at the reconstructed rewards ˜R(b) (also shown in parentheses in Figure 1), we notice that the first two and the last two columns-respectively corresponding to states 0 and 1, and 8 and 9-have the same values, indicating that the PSR has lost the ability to distinguish between those states. After all, the only reason why states 0 and 1 are separate states in load/unload is because they lead to different rewards; they are equivalent in all other aspects, hence the PSR "efficiently" merges them. More critically, the optimal behavior prescribed by ˜R(b) (read R(p) ) has changed catastrophically from that of R(b) . With R(b) , the optimal behavior is to move back-andforth between the corridor ends; with ˜R(b) (read R(p) ), the optimal behavior is to reach one end and stay there.
4 Reward-Predictive State Representations
In this section, we introduce reward-predictive state representations (R-PSRs), a generalization of PSRs which accurately models both the observation processes and the reward processes of all finite POMDPs. The derivation of R-PSRs resembles closely that of PSRs, with a few key differences: (a) a token action is used to unify observation and reward emissions, (b) tests are extended by a final action used which switches between observation and reward emissions, (c) test probabilities are generalized to include reward information.
Extended Action-Space. We define an extended actionspace Z .= A∪{ζ}, where ζ is a token action, and extend the reward function such that R(s, ζ) = 1 for every state s. Token action ζ (with its reward) is a construct which will allow us to define a single model of both observation and reward emissions; however, we are not changing the space of actions available to the agent, and ζ cannot be used to interact with the environment, nor can it be part of a history or test.
Intents and their Expectations. In R-PSRs, the system state incorporates the expected rewards of hypothetical futures we call intents. We define an intent qz as a test q followed by an extended action z, and the space of all intents as I .=Q×Z. An intent reward r(qz | h) .= Pr(q | h)R(hq, z)
Algorithm 1 Depth-first search of a maximal set of linearly independent intents I † .
Require: q ∈ Q (optional, default ε)
Require: Independent intents I ⊂ I (optional, default ∅)
Ensure: Maximal set of independent intents which either be-
long to I or are extensions of q.
function ISEARCHDFS(q, I)
if u(qz) independent of {u(i) | i ∈ I} then
return I
is the test probability multiplied by the expected reward obtained by the intent action following the concatenated historytest. Intent rewards are the core quantity modeled by R-PSRs, and a linear reward-predictive state r(h) ∈ R|I † | (where I † is a core set of intents, defined later) is a representation of history h such that intent rewards are linear in r(h), i.e., r(qz | h) = r(h)⊤mqz, where mqz ∈ R|I † | is the parameter vector associated to intent qz. A focal property of r(qz | h), provided by the token action ζ, is that it generalizes both test probabilities and history rewards,
The intent reward function can be expressed in a vectorized form similar to that of PSRs (proof in Appendix),
Outcome Vectors. The outcome of an intent u(qz) ∈ R|S| is a vector indicating the intent rewards from each state as starting point, i.e., [u(qz)]i = E [R(s′ , a) | s = i, q]. Outcomes can be defined recursively using the generative matrix,
Combining Equations (9) to (11) results in r(qz | h) = b(h)⊤u(qz), i.e., the intent reward given a history is the expectation of intent rewards given each state. A set of intents is said to be linearly independent iff the respective outcome vectors are linearly independent, and any maximal set of linearly independent intents is called a core set, denoted as I † . R-PSR core sets share similar properties to PSR core sets: there are infinite core sets which share the same size |I † |, called the RPSR rank, which is upper-bounded by |I † | ≤ |S|. Note that the PSR rank and the R-PSR rank are not necessarily equal. Algorithm 1 is a depth-first search algorithm to find a core set, analogous to the original PSR search algorithm [Littman and Sutton, 2002], but adapted for R-PSRs (see Appendix for a more efficient breadth-first variant).
Reward-Predictive States. The outcome matrix U ∈ R|S|×|I † | of a core set I † is the column-wise stacking of the core outcome vectors {u(qz) | qz ∈ I † }. By the definition of a core set, the outcome u(qz) of any intent qz is a linear combination of the core outcome matrix U columns (else the core set would not be maximal), i.e., u(qz) ∈ col U and, because UU + is the projection onto col U, then u(qz) = UU +u(qz). Consequently, r(qz | h) = b(h)⊤u(qz) = b(h)⊤UU +u(qz) = r(h)⊤mqz where r(h)⊤ .= b(h)⊤U is the reward-predictive state, and mqz .= U +u(qz) is the parameter vector of qz. Each dimension of r(h) is itself the intent reward of a core intent, i.e., [r(h)]i = r(qz | h), where qz is the ith core intent.
Emissions and Dynamics. According to Equations (7) and (8), observation probabilities and reward emissions are Pr(o | h, a) = r(aoζ | h) = r(h)⊤maoζ and R(h, a) = r(εa | h) = r(h)⊤mεa respectively. Therefore, the test-less intent parameters {mεa | a ∈ A} constitute the columns of reward matrix R(r) . The reward-predictive state dynamics are r(hao) = (r(h)⊤Mao )/(r(h)⊤maoζ ), whereMao is the column-wise stacking of the extended core intent parameters {maoqz | qz ∈ I † } (proof in Appendix).
Value Iteration for R-PSRs. Value iteration can be adapted to R-PSRs (R-PSR-VI). Both the derivation and the equation to compute the alpha vectors α(r) π are identical to those of PSR-VI [James et al., 2004; Boots et al., 2011], also shown in Section 2.3; the only difference being that parameters R(r) andM (r) ao are used, whose values correctly represent the POMDP/R-PSR rewards.
5 Evaluation
We perform empirical evaluations to confirm the theory developed in this work, the issues with PSRs, and the validity of R-PSRs. We show that (a) a non-trivial portion of finite POMDPs used in classical literature do not satisfy the accuracy condition of Theorem 1, i.e., this is a common problem occurring in common domains; (b) PSR-VI based on inaccurate approximate PSR rewards results in catastrophically sub-optimal policies, i.e., approximate rewards are not viable for control; (c) R-PSRs are accurate reward models; and (d) R-PSR-VI results in the same optimal policies as POMDP-VI. Our evaluation involves a total of 63 unique domains: 60 are taken from Cassandra's POMDP page [Cassandra, 1999], a repository of classic finite POMDPs from the literature; 2 are the well-known load/unload [Meuleau et al., 1999] and heaven/hell [Bonet, 1998]; and the last one is float/reset [Littman and Sutton, 2002].
We found that 8 out of these 63 domains-a non-trivial amount-do not satisfy the accuracy condition. Table 2 shows the reward errors between original and reconstructed POMDP rewards. We note that all domains where accurate PSR rewards are not possible also have high relative errors, which implies that inaccurate PSRs are unlikely to be only mildly inaccurate. VI is a fairly expensive algorithm which does not scale well with long planning horizons and is thus not suitable for all problems; convergence to a steady optimal value function was possible within a reasonable timeframe for only 6 of the 8 domains. For each of these 6 domains, we run 4 different policies for 1000 episodes of 100 steps: the uniform policy, and the policies respectively obtained by POMDP-VI, PSR-VI, and R-PSR-VI. Every action-observation sequence is then evaluated by the POMDP, PSR, and R-PSR reward models. Table 3 shows the return estimates for POMDPs, PSRs, and R-PSRs; Note that the POMDP and R-PSR rows are combined since they contain the same values.
| 4x3 | heaven/hell | iff | line4-2goals | load/unload | paint | parr | stand-tiger | |
|---|---|---|---|---|---|---|---|---|
| d∞ | 1.0 | 1.0 | 48.93 | 0.6 | 0.5 | 1.33 | 1.0 | 65.0 |
| rel-d∞ | 1.0 | 1.0 | 0.75 | 0.75 | 0.5 | 1.33 | 0.5 | 0.65 |
| Domain | Model | Random | POMDP-VI | PSR-VI | R-PSR-VI |
|---|---|---|---|---|---|
| heaven/hell | POMDP/R-PSR PSR | 0.0 ± 0.1 -0.0±0.0 | 1.4 ± 0.0 -0.0±0.0 | 0.0 ± 0.0 -0.0±0.0 | 1.4 ± 0.0 -0.0±0.0 |
| line4-2goals | POMDP/R-PSR PSR | 0.4 ± 0.0 4.0 ± 0.0 | 0.4 ± 0.0 4.0 ± 0.0 | 0.4 ± 0.0 4.0 ± 0.0 | 0.4 ± 0.0 4.0 ± 0.0 |
| load/unload | POMDP/R-PSR PSR | 1.2 ± 0.5 4.0 ± 1.0 | 4.5 ± 0.1 2.6 ± 0.1 | 0.6 ± 0.2 9.1 ± 0.5 | 4.5 ± 0.1 2.6 ± 0.1 |
| paint | POMDP/R-PSR PSR | -4.2±1.4 -3.2 ± 1.0 | 3.3 ± 0.3 1.0 ± 0.9 | 0.0 ± 0.0 3.3 ± 0.0 | 3.3 ± 0.3 1.0 ± 1.0 |
| parr | POMDP/R-PSR PSR | 4.3 ± 1.7 4.3 ± 0.8 | 7.1 ± 0.0 3.6 ± 0.0 | 6.5 ± 1.8 6.3 ± 0.0 | 7.1 ± 0.0 3.6 ± 0.0 |
| stand-tiger | POMDP/R-PSR PSR | -122.3±43.1 -122.7±26.4 | 49.2±23.4 -151.1±17.6 | 0.0±0.0 0.0±0.0 | 49.8 ± 23.2 -150.2±18.0 |
In this context, the POMDP represents the true task, which the PSR and R-PSR also attempt to encode; hence, the POMDP rows show how well each model's respective policy solves the original task, while the PSR rows show how the PSR's (inaccurate) encoded task evaluates each model's respective policy. Notably, POMDPs and R-PSRs consistently agree with high numerical precision on the return values of all trajectories, whereas PSRs consistently disagree. The POMDP-VI and R-PSR-VI policies achieve the same values throughout all experiments, i.e., they consistently converge to the same policies. Since the POMDP encodes the true task, both POMDP-VI and R-PSR-VI represent the optimal policy which solves that task. With the singular exception of line4-2goals, a trend appears where the PSR-VI policy is sub-optimal and, in the case of load/unload, is even worse than the random policy (see Section 3.2). Vice versa, the POMDP-VI/R-PSR-VI policies are sub-optimal according to the PSR model; notably, the random policy performs better than the POMDP-VI/R-PSR-VI policies in 3 out of 6 cases, which underlines just how much the task encoded by the PSRs have diverged from their original form.
These results reaffirm not only the theory developed in this document, i.e., that PSRs are equivalent to POMDPs only in relation to their observation process and not their reward process, but also that this is a common problem which causes significant control issues. Further, the results confirm the validity of the developed R-PSR theory, and the equivalence between POMDPs and R-PSRs. Overall, this confirms that RPSRs are better suited for control, compared to vanilla PSRs.
6 Conclusions
In this work, we presented theoretical results on the accuracy of PSR rewards relative to POMDP rewards, identified a sufficient and necessary condition which determines whether a PSR can accurately represent POMDP rewards, and derived the closest linear approximate rewards for non-accurate PSRs. We also showed empirically that reward approximations are likely to warp the implied task in undesirable ways. Therefore, we proposed R-PSRs, a generalization of PSRs which encodes reward values jointly with test probabilities, and solves the reward modeling problem of vanilla PSRs while remaining faithful to the idea of grounding a system state representation on non-latent quantities, and avoiding the pitfalls of observable rewards. R-PSRs combine the benefits of both POMDPs and PSRs: Compared to POMDPs, R-PSRs do not rely on a latent state, which makes model learning easier and grounded in non-latent quantities; Compared to PSRs, R-PSRs are able to model a wider range of tasks, and the reward structure of any finite POMDP. In future work, we aim to adapt more learning and planning algorithms to R-PSRs, and address the discovery problem, i.e., the problem of learning a core set of intents from sample interactions.
Acknowledgments
This research was funded by NSF award 1816382.
@inproceedings{ijcai2021p299,
  title     = {Reconciling Rewards with Predictive State Representations},
  author    = {Baisero, Andrea and Amato, Christopher},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {2170--2176},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/299},
  url       = {https://doi.org/10.24963/ijcai.2021/299},
}
TY - CPAPER TI - Reconciling Rewards with Predictive State Representations AU - Baisero, Andrea AU - Amato, Christopher T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 2170 EP - 2176 DO - 10.24963/ijcai.2021/299 UR - https://doi.org/10.24963/ijcai.2021/299 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





