
Greedy Convex Ensemble
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 3101-3107.
https://doi.org/10.24963/ijcai.2020/429
Keywords
- Machine Learning: Ensemble Methods
- Machine Learning: Learning Theory
Abstract
We consider learning a convex combination of basis models, and present some new theoretical and empirical results that demonstrate the effectiveness of a greedy approach. Theoretically, we first consider whether we can use linear, instead of convex, combinations, and obtain generalization results similar to existing ones for learning from a convex hull. We obtain a negative result that even the linear hull of very simple basis functions can have unbounded capacity, and is thus prone to overfitting; on the other hand, convex hulls are still rich but have bounded capacities. Secondly, we obtain a generalization bound for a general class of Lipschitz loss functions. Empirically, we first discuss how a convex combination can be greedily learned with early stopping, and how a convex combination can be non-greedily learned when the number of basis models is known a priori. Our experiments suggest that the greedy scheme is competitive with or better than several baselines, including boosting and random forests. The greedy algorithm requires little effort in hyper-parameter tuning, and also seems able to adapt to the underlying complexity of the problem. Our code is available at https://github.com/tan1889/gce.
- [Anthony and Bartlett, 2009] Martin Anthony and Peter L Bartlett. Neural network learning: Theoretical founda- tions. Cambridge University Press, 2009.
- [Bach, 2017] Francis Bach. Breaking the curse of dimension- ality with convex neural networks. The Journal of Machine Learning Research, 18(1):629-681, 2017.
- [Barron, 1993] Andrew R Barron. Universal approximation bounds for superpositions of a sigmoidal function. Informa- tion Theory, IEEE Transactions on, 39(3):930-945, 1993.
- [Bartlett and Traskin, 2007] Peter L Bartlett and Mikhail Traskin. Adaboost is consistent. Journal of Machine Learn- ing Research, 8(Oct):2347-2368, 2007.
- [Breiman, 2001] Leo Breiman. Random forests. Machine learning, 45(1):5-32, 2001.
- [Chen and Guestrin, 2016] Tianqi Chen and Carlos Guestrin. XGBoost: A scalable tree boosting system. In KDD, pages 785-794. ACM, 2016.
- [Dheeru and Karra Taniskidou, 2017] Dua Dheeru and Efi Karra Taniskidou. UCI machine learning repository, 2017.
- [Donahue et al., 1997] Michael J Donahue, C Darken, Leonid Gurvits, and Eduardo Sontag. Rates of convex approximation in non-Hilbert spaces. Constructive Approx- imation, 13(2):187-220, 1997.
- [Frank and Wolfe, 1956] Marguerite Frank and Philip Wolfe. An algorithm for quadratic programming. Naval research logistics quarterly, 3(1-2):95-110, 1956.
- [Freund and Schapire, 1995] Yoav Freund and Robert E Schapire. A desicion-theoretic generalization of on-line learning and an application to boosting. In European con- ference on computational learning theory, pages 23-37. Springer, 1995.
- [Gao and Zhou, 2013] Wei Gao and Zhi-Hua Zhou. On the doubt about margin explanation of boosting. Artificial Intelligence, 203:1-18, 2013.
- [Grover and Ermon, 2018] Aditya Grover and Stefano Er- mon. Boosted generative models. In Thirty-Second AAAI Conference on Artificial Intelligence, 2018.
- [Guélat and Marcotte, 1986] Jacques Guélat and Patrice Mar- cotte. Some comments on Wolfe's 'away step'. Mathemati- cal Programming, 35(1):110-119, 1986.
- [Jaggi, 2013] Martin Jaggi. Revisiting Frank-Wolfe: Projection-free sparse convex optimization. In ICML, 2013.
- [Jones, 1992] Lee K. Jones. A simple lemma on greedy ap- proximation in Hilbert space and convergence rates for projection pursuit regression and neural network training. The annals of Statistics, pages 608-613, 1992.
- [Kingma and Ba, 2014] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Koltchinskii and Panchenko, 2005] Vladimir Koltchinskii and Dmitry Panchenko. Complexities of convex combina- tions and bounding the generalization error in classification. The Annals of Statistics, 33(4):1455-1496, 2005.
- [Lacoste-Julien and Jaggi, 2015] Simon Lacoste-Julien and Martin Jaggi. On the global linear convergence of Frank- Wolfe optimization variants. In NIPS, 2015.
- [Lee et al., 1996] Wee Sun Lee, Peter L Bartlett, and Robert C Williamson. Efficient agnostic learning of neural networks with bounded fan-in. Information Theory, IEEE Transactions on, 42(6):2118-2132, 1996.
- [Locatello et al., 2018] Francesco Locatello, Gideon Dres- dner, Rajiv Khanna, Isabel Valera, and Gunnar Rätsch. Boosting black box variational inference. In Advances in Neural Information Processing Systems, 2018.
- [Makovoz, 1996] Yuly Makovoz. Random approximants and neural networks. Journal of Approximation Theory, 85(1):98-109, 1996.
- [Mannor et al., 2003] Shie Mannor, Ron Meir, and Tong Zhang. Greedy algorithms for classification-consistency, convergence rates, and adaptivity. Journal of Machine Learning Research, 4(Oct):713-742, 2003.
- [Mason et al., 2000a] Llew Mason, Jonathan Baxter, Peter L Bartlett, Marcus Frean, et al. Functional gradient tech- niques for combining hypotheses. In Advances in Large Margin Classifiers, pages 221-246. MIT, 2000.
- [Mason et al., 2000b] Llew Mason, Jonathan Baxter, Peter L Bartlett, and Marcus R Frean. Boosting algorithms as gradient descent. In NIPS, pages 512-518, 2000.
- [Mendelson, 2003] Shahar Mendelson. A few notes on sta- tistical learning theory. In Advanced lectures on machine learning, pages 1-40. Springer, 2003.
- [Oglic and Gärtner, 2016] Dino Oglic and Thomas Gärtner. Greedy feature construction. In NeurIPS, 2016.
- [Pollard, 1984] David Pollard. Convergence of stochastic processes. Springer, 1984.
- [Schapire, 2013] Robert E Schapire. Explaining adaboost. In Empirical inference, pages 37-52. Springer, 2013.
- [Tolstikhin et al., 2017] Ilya O Tolstikhin, Sylvain Gelly, Olivier Bousquet, Carl-Johann Simon-Gabriel, and Bern- hard Schölkopf. Adagan: Boosting generative models. In NeurIPS, 2017.
- [Viola and Jones, 2004] Paul Viola and Michael J Jones. Ro- bust real-time face detection. IJCV, 57(2):137-154, 2004.
- [Wager and Walther, 2015] Stefan Wager and Guenther Walther. Adaptive concentration of regression trees, with application to random forests. arXiv preprint arXiv:1503.06388, 2015.
- [Wellner and Song, 2002] Jon A. Wellner and Shuguang Song. An upper bound for uniform entropy numbers, 2002.
- [Wyner et al., 2017] Abraham J Wyner, Matthew Olson, Justin Bleich, and David Mease. Explaining the success of adaboost and random forests as interpolating classifiers. The Journal of Machine Learning Research, 18(1):1558- 1590, 2017.
- [Zhang, 2003] Tong Zhang. Sequential greedy approximation for certain convex optimization problems. IEEE Transac- tions on Information Theory, 49(3):682-691, 2003.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Various machine learning methods combine given basis models to form richer models that can represent more complex input-output relationships. These include random forests [Breiman, 2001] and boosting [Freund and Schapire, 1995; Mason et al., 2000a; Chen and Guestrin, 2016], which have often been found to work well in domains with good features. Interestingly, even combining simple basis models like decision stumps can work very well on hard problems [Viola and Jones, 2004].
In this paper, we consider learning an optimal convex combination of basis models [Lee et al., 1996; Mannor et al., 2003; Oglic and Gärtner, 2016; Wyner et al., 2017], and present new theoretical and empirical insights.
We first compare learning from convex hulls with learning from the closely related linear hulls. Learning from a convex hull can be seen as a regularized version of learning from the corresponding linear hull, where we enforce constraints on the weights of the basis functions. While linear hulls are known to provide universal approximations [Barron, 1993; Makovoz, 1996], our analysis shows that they can be prone to overfitting. Specifically, we show that the capacity of the linear hull of very simple functions can be unbounded, while the convex hull is still rich but has bounded capacity.
Our second contribution is a generalization result for a general class of Lipschitz loss functions. A number of works studied algorithms for learning a convex combination and analyzed their generalization performance. However, previous works mostly focused on generalization performance with quadratic loss [Lee et al., 1996; Mannor et al., 2003] or large margin type analysis [Koltchinskii and Panchenko, 2005] for classification problems. The quadratic loss is a special case of the class of Lipschitz loss functions considered in this paper. In addition, our result shows that we can obtain an O(1/√n) convergence rate for log-loss in the classification setting.
Empirically, we present an extensive experimental evaluation of algorithms for learning from convex hulls. While previous works mainly focused on simple greedy algorithms to learn a convex combination, we leverage on the functional optimization versions of some sophisticated algorithms to develop algorithms for learning a convex combination. In particular, we consider the Frank-Wolfe (FW) algorithm and its variants [Jaggi, 2013], which provide natural ways to build convex combinations. We also show how a convex combination can be non-greedily learned when the number of basis functions is known a priori. Our experiments suggest that the greedy scheme is competitive with or better than several baselines, including boosting and random forests. The greedy algorithm requires little hyper-parameter tuning, and also seems to adapt to the underlying complexity of the problem.
Section 2 further discusses related works. Section 3 presents our theoretical analysis for learning from a convex hull. Section 4 discusses some greedy learning algorithms, and a nongreedy version. Section 5 empirically compares the algorithms for learning from convex hulls, and a few baselines. Section 6 concludes the paper.
2 RelatedWork
A number of works have studied the generalization performance of algorithms for learning convex combinations. Lee et al. [1996] considered learning a convex combination of linear threshold units with bounded fan-in (#inputs) for binary classification using quadratic loss, and they showed that an optimal convex combination is PAC-learnable. Mannor et al. [2003] also considered binary classification, and obtained a generalization result for general basis functions and quadratic loss. They also obtained a consistency result for more general loss functions. Koltchinskii and Panchenko [2005] provided some generalization results for learning a convex combination by maximizing margin. Oglic and Gärtner [2016] considered regression with quadratic loss and presented a generalization analysis for learning a convex combination of cosine ridge functions. We obtained generalization bounds for a class of Lipschitz loss functions and general basis functions.
Various authors considered greedy approaches for learning a convex combination, which iteratively constructs a convex combination by choosing a good convex combination of the previous convex combination and a new basis function. Jones [1992] presented a greedy algorithm and showed that it converges at O(1/k) rate for quadratic loss. This is further developed by Lee et al. [1996] and Mannor et al. [2003]. Zhang [2003] generalized these works to convex functionals. We leverage on the functional versions of more sophisticated greedy optimization algorithms; in particular, the FW algorithm and its variants, which have recently attracted significant attention in the numerical optimization literature [Jaggi, 2013]. Recently, Bach [2017] considered using the FW algorithm to learn neural networks with non-Euclidean regularizations, and showed that the sub-problems can be NP-hard. Besides greedy approaches, we show how to non-greedily learn a convex combination given the number of basis functions. We empirically compared the effectiveness of these algorithms.
Works on random forests [Breiman, 2001] and boosting [Mason et al., 2000b] are also closely related. A random forest can be viewed as a convex combination of trees independently trained on bootstrap samples, where the trees have equal weights. Boosting algorithms greedily construct a conic, instead of convex, combination of basis functions, but for binary classification, a conic combination can be converted to a convex combination without changing the predictions. There are numerous related works on the generalization performance of boosting (e.g. see [Bartlett and Traskin, 2007; Schapire, 2013; Gao and Zhou, 2013]). Random forests are still less well understood theoretically yet [Wyner et al., 2017], and analysis can require unnatural assumptions [Wager and Walther, 2015]. We empirically compared algorithms for learning a convex combination with random forests and boosting.
There have been also several recent applications of boosting for generative models. Specifically, Locatello et al. [2018] show that boosting variational inference satisfies a relaxed smoothness assumption which is sufficient for the convergence of the functional Frank-Wolfe algorithm; Grover and Ermon [2018] consider Bayes optimal classification; and Tolstikhin et al. [2017] propose AdaGAN, which is adapted from AdaBoost for Generative Adversarial Networks. Our work is orthogonal to these works in the sense that we study discriminative models and learning from a convex hull, instead of a linear or a conic hull. Moreover, our bound might be interesting in comparison to vacuous bounds that grow rapidly in the number of parameters: while the number of parameters for a convex combination can be unbounded, our error bound depends only on the pseudodimension of the basis models.
3 Theoretical Analysis
Given an i.i.d. sample z = ((x1, y1), . . . , (xn, yn)) drawn from a distribution P(X, Y ) defined on X × Y ⊆ X × R, we want to learn a function f to minimize the risk R(f) = EL(Y, f(X)), where L(y, ˆ y) is the loss that f incurs when predicting y as ˆ y, and the expectation is taken wrt P. The empirical risk of f is Rn(f) = EnL(Y, f(X)) = 1n ∑ni=1 L(yi, f(xi)). Without loss of generality, we assume X ⊆ Rd .
Given a class of basis functions G ⊆ Y X , we use cok(G) to denote the set of convex combinations of k functions in G, that is, cok(G) = {∑ki=1 αigi : ∑i αi = 1, each αi ≥ 0, each gi ∈ G}. The convex hull of G is co(G) = ∪k≥1 cok(G). We will also use link(G) to denote the set of linear combinations of k functions in G, that is, link(G) = {∑ki=1 αigi : α1, . . . , αk ∈ R, g1, . . . , gk ∈ G}. The linear hull of G is lin(G) = ∪k≥1 link(G). The basis functions are assumed to be bounded, with G ⊆ [-B, B]X for some constant B > 0.
Capacity measures. A function class needs to be rich to be able to fit observed data, but cannot be too rich so as to make generalization possible, that is, it needs to have the right capacity. Commonly used capacity measures include VCdimension, pseudodimension, and Rademacher complexity.
VC-dimension is defined for binary valued functions. Specifically, for a class F of binary valued functions, its VC-dimension dVC(F) is the largest m such that there exists m examples x1, . . . , xm such that the restriction of F to these examples contains 2m functions. Equivalently, for any y1, . . . , ym ∈ {0, 1}, there is a function f ∈ F such that f(xi) = yi for all i. x1, . . . , xm is said to be shattered by F.
Pseudodimension [Pollard, 1984] is a generalization of VC-dimension to real-valued functions. The pseudodimension dP (F) of a class of real-valued functions F is defined as the maximum number m such that there exists m inputs x1, . . . , xm ∈ X, and thresholds t1, . . . , tm ∈ R satisfying {(I(f(x1) ≥ t1), . . . , I(f(xm) ≥ tm)) : f ∈ F} = {0, 1}m. If each f ∈ F is binary-valued, then dP (F) = dV C(F).
Rademacher complexity is defined as Esupf∈F Rnf, where Rn is the Rademacher process defined by Rnf = 1n ∑i ϵif(xi, yi), with (xi, yi)'s being an i.i.d. sample, and ϵi's being independent Rademacher random variables (i.e., they have probability 0.5 to be -1 and 1). Expectation is taken wrt both the random sample and the Rademacher variables.
We refer the readers to the book of Anthony and Bartlett [2009] and the article of Mendelson [2003] for excellent discussions on these capacity measures and their applications in generalization results.
3.1 ARegularization Perspective
Several authors showed that linear hulls of various basis functions are universal approximators [Barron, 1993; Makovoz, 1996]. Naturally, one would like to learn using linear hulls if possible. On the other hand, the richness of the linear hulls also imply that they may be prone to overfitting, and it may be beneficial to consider regularization.
Learning from the convex hull can be seen as a regularized version of learning from the linear hull, where the regularizer
larization in the sense that ℓ2 regularization constrained the weights to be inside an ℓ2 ball, while here we constrain the weights of the basis model to be inside a simplex. A key difference is that standard ℓ2 regularization is often applied to a parametric model with fixed number of parameters, but here the number of parameters can be infinite.
We compare the capacities of the linear hull and the convex hull of a class of basis functions G with finite pseudodimension, and demonstrate the effect of the regularizer I∞ in controlling the capacity: while the convex hull can still be rich, it has a more adequate capacity for generalization.
For a class of functions F, we shall use bin(F) = {x ↦→ I(f(x) ≥ t) : f ∈ F, t ∈ R} to denote the thresholded binary version of F. Consider the set of linear threshold functions T = {I(θ⊤x ≥ t) : θ ∈ Rd , t ∈ R}. It is well-known that the VC-dimension of the thresholded versions of the linear combination of k linear threshold functions can grow quickly.
Proposition 1. ([Anthony and Bartlett, 2009], Theorem 6.4) The VC-dimension of bin(link(T )) is at least dk 8 log2 ( k4 ) for d > 3 and k ≤ 2d/2-2 .
The above result implies that dP (link(T )) is at least dk 8 log2 ( k4 ). A natural question is whether the VC-dimension still grows linearly when k > 2d/2-2 . We give an affirmative answer via a constructive proof, and provide counterpart results for the convex hull.
Proposition 2. (a) Assume that d ≥ 2. Then dVC(bin(link(T ))) ≥ k, thus dP (link(T )) ≥ k, and dP (lin(T )) = ∞. In addition, the Rademacher complexity of lin(T ) is infinite.
(b) Assume that d ≥ 2. Then dVC(bin(cok+1(T ))) ≥ k, thus dP (cok+1(T )) ≥ k, and dP (co(T )) = ∞, but the Rademacher complexity of co(T ) is finite.
Proof. (a) Consider an arbitrary unit circle centered at the origin, and any k points x1, . . . , xk which are equally spaced on the circle. Let θi = xi and bi = 1 for i = 1, . . . , k. For any y1, . . . , yk ∈ {0, 1}, consider the linear combination f(x) = ∑ki=1 wiI(θ⊤ i x ≥ bi), with wi = yi. We have f(xi) = yi. The classifier t(x) = I(f(xi) ≥ 1) is a thresholded classifier obtained from f, and thus t ∈ bin(link(T )). In addition, t(x) = I(yi ≥ 1) = yi. In short, for any y1, . . . , yk ∈ {0, 1}, there is a classifier t ∈ bin(link(T )) such that t(xi) = yi. Thus dV C(bin(link(T ))) ≥ k. It follows that dP (link(T )) ≥ k, and thus dP (lin(T )) = ∞.
The Rademacher complexity of lin(T ) is infinity, because for any c > 0, the Rademacher complexity of c lin(T ) is c times that of lin(T ). On the other hand, c lin(T ) = lin(T ). Hence the Rademacher complexity of lin(T ) can be arbitrarily large, and is thus infinity.
wi = yi/(1+ ∑i yi) for i ≥ 1. The function h(x) is a convex combination of I(0⊤x ≥ 0.5), I(θ⊤ 1 x ≥ b1), . . . , I(θ⊤ k x ≥ bk), where the first one is always 0. For any xj, we have h(xj) = yj/(1 + ∑i yi) ≥ yj/(k + 1), because each yi is either 0 or 1. Hence we have I(h(xj) ≥ 1/(k + 1)) = yj . It follows that x1, . . . , xk can be shattered by the thresholded version of cok+1(T ).
The Rademacher complexity of the convex hull is equal to that of T according to Theorem 2.25 in [Mendelson, 2003], which is finite as dV C(T ) = d + 1 is finite.
Proposition 2 shows that the linear hull has infinite capacity, both in terms of pseudodimension and in terms of Rademacher complexity. Thus, it may easily overfit a training dataset. On the other hand, the convex hull is more restricted with a finite Rademacher complexity, but still rich because it has infinite pseudodimension. This can be attributed to regularization effect imposed by the convex coefficients constraints.
3.2 Generalization Error Bounds
Let f ∗ (x) = miny∈Y E[L(y, Y )|X = x] be the Bayes optimal function . For binary classification problems (that is, Y = {-1, 1}) using the quadratic loss L(y, f(x)) = (f(x) - y)2 , Mannor et al. [2003] obtained the following uniform convergence rate with an assumption on the uniform entropy H(ϵ, co(G), n) of co(G), where G ⊆ [-B, B]X .
Theorem 1. (Theorem 9 in [Mannor et al., 2003]) Assume that for all positive ϵ, H(ϵ, co(G), n) ≤ K(2B/ϵ)2ξ for ξ ∈ (0, 1) and K > 0. Then there exist constants c0, c1 > 0 that depend on ξ and K only, such that ∀δ ≥ c0, with probability at least 1 - e-δ , for all f ∈ co(G),
.
When dP (G) = p, then the assumption on the metric entropy H(ϵ, co(G), n) is satisfied with ξ = p p+2 [Wellner and Song, 2002]. In Theorem 2, we prove a more general bound for a class of Lipschitz losses that includes the quadratic loss considered in Theorem 1 as a special case. Omitted proofs are available at https://github.com/tan1889/gce .
Theorem 2. Assume that dP (G) = p < ∞, and L(y, f(x)) = φ(f(x) - y) for a cφ-Lipschitz nonnegative function φ satisfying φ(0) = 0. With probability at least 1 - δ, for all f ∈ co(G), R(f) -R(f ∗ ) ≤ Rn(f) -Rn(f ∗ ) + c √n , where c = 2cφ ˜B (√2 ln(1/δ) +D√p+2), ˜B ≥ B is the smallest number such that Y ⊆ [- ˜B, ˜B], and D is an absolute constant.
The Bayes optimal function f ∗ is generally not in co(G), thus the chosen convex combination f may not reach the level of performance of f ∗ . Thus we are often interested in the convergence of the empirical minimizer to the optimal model in co(G). We can obtain an O(1/√n) convergence rate by closely following the proof of Theorem 2.
Theorem 3. Assume that dP (G) = p < ∞, L(y, f(x)) = φ(f(x) - y) for a cφ-Lipschitz nonnegative function φ satisfying φ(0) = 0. Let ˆ f = argminf∈co(G)Rn(f), and h∗ = argminf∈co(G)R(f), then with probability at least 1-δ, R( ˆ f) ≤ R(h∗ ) + c √n , where c is defined in Theorem 2.
As a special case, we have the result below for ℓq regression.
Donahue et al. [1997] showed that tighter bounds can be obtained for ℓp regression by exploiting the specific form of ℓp loss. Our analysis provides a looser bound, but is simpler and can be applied to the classification setting below.
Specifically, for binary classification with Y = {-1, 1}, we can also obtain an O(1/√n) generalization bound for a class of Lipschitz loss as a corollary of the proof of Theorem 2. The loss in this case is Lipschitz in yf(x) (not f(x) - y as in the regression case), with a positive value indicating that f(x) is better aligned with y.
Corollary 2. Assume that dP (G) = p < ∞, Y = {-1, 1}, L(y, f(x)) = φ(yf(x)) for a cφ-Lipschitz nonnegative function φ satisfying φ(0) = 0. Let ˆ f = argminf∈co(G)Rn(f), and h∗ = argminf∈co(G)R(f), then with probability at least 1 - δ, R( ˆ f) ≤ R(h∗ ) + c √n , where c is defined in Theorem 2.
As a special case, the above rate holds for the log-loss.
Corollary 3. When y ∈ {-1, 1}, L(y, f(x)) = -ln 1 1+e-yf(x) , the bound in Corollary 2 holds with cφ = 1.
4 Algorithms
We consider algorithms for finding the empirical risk minimizer ˆ f = argminf∈co(G) Rn(f), when G consists of parametric basis models, i.e., G = {gθ : θ ∈ Rp }, where gθ denotes a model with parameters θ.
4.1 Greedy Algorithms
The convexity of co(G) allows the following greedy scheme. Start with some f0 ∈ H. At iteration k, we choose appropriate αt ∈ [0, 1] and gt ∈ G, for the new convex combination
We run the algorithm up to a maximum number of iterations T, or do early stopping if the improvements in the last few iterations is negligible (less than a small threshold).
Such scheme generates sparse solutions in the sense that at iteration t, the convex combination consists of at most t basis functions, even though the optimal combination can include arbitrarily large number of basis functions.
We present several instantiations of this scheme based on results from functional optimization. The derived sub-problems, while being functional optimization problems, are equivalent to finite-dimensional numerical optimizations which can be solved using stochastic gradient descent. Some of them have interesting forms that differ from standard risk minimization problems.
A nonlinear greedy algorithm. One natural way to choose gt and αt is to choose them jointly so as to maximize the decrease in the empirical risk [Jones, 1992; Lee et al., 1996; Mannor et al., 2003; Zhang, 2003]. Specifically,
For common loss functions, the RHS is usually a differentiable function of θ and α, and thus the problem can be solved using first-order methods. We used Adam [Kingma and Ba, 2014] in our experiments.
When L(y, f(x)) is convex and smooth functional of f, it is known, e.g. from [Zhang, 2003], that Rn(ft) -Rn( ˆ f) ≤ O(1/t). In fact, we can still achieve a convergence rate of O(1/t), as long as we can solve the greedy step with an error of O(1/t2 ), that is, if we can choose gt and αt such that Rn((1-αt)ft-1+αtgt) ≤ ming∈G,α∈[0,1] Rn((1-α)ft-1+ αg)+ c t2 , for some constant c > 0 [Zhang, 2003]. In particular, this result applies to the quadratic loss.
The FW algorithm. The FW algorithm [Frank and Wolfe, 1956] does not choose gt to directly minimize the risk functional at each iteration, but chooses it by solving a linear functional minimization problem
where the step size αt can be taken as αt = 1 t+1 or chosen using line search, and DRn(f) denotes the functional gradient of Rn with respect to f, which is only non-zero at the points in the sample and is thus finite. For the quadratic loss L(y, f(x)) = (f(x) - y)2 , gt is gθt with θt chosen by
This optimization problem has an interesting form different from standard risk minimization problems. For quadratic loss, we can also derive the closed form solution for the line-search for αt. For other risk criteria, there is no closed form solution, and we treat that as a parameter in the numerical optimization problem in each iteration. FW also converges at an O(1/t) rate as for smooth and convex functionals (e.g., see Jaggi [2013]), with the constant in the rate being of the same order as that for the nonlinear greedy algorithm.
Away-step and Pairwise FW. The away-step Frank-Wolfe (AFW) [Guélat and Marcotte, 1986], and the pairwise FrankWolfe (PFW) [Lacoste-Julien and Jaggi, 2015] are faster variants which can converge at a linear rate when the solution is not at the boundary.
AFW either takes a standard FW step or an away step which removes a basis network from current convex combination and redistributes the weight to remaining basis networks. Specifically, at each iteration, it finds gt ∈ G that is most aligned with the negative gradient DRn(ft-1) as in the FW algorithm, and a basis function at that is most misaligned with the negative gradient DRn(ft-1) from the set of basis functions in ft-1. Here, the inner product of two vectors measures the degree of alignment between them. It then constructs a FW direction dFW t that moves towards gt, and an away-step direction dAt that moves away from at. The direction that is better aligned with the negative gradient is taken. For the away-step, the step size is restricted to be in [0, αat 1-αat ] so that the weight of at remains non-negative in ft.
PFW swaps the weight of at and gt determined in AFW by moving along the direction gt - at. Line search is used to determine the optimal step size.
4.2 ANon-greedy Algorithm
If we know the number of basis models required a priori, we can train the weights of the basis models and the convex coefficients simultaneously. Instead of using constrained optimization techniques, we can use a softmax normalization. However, we found this not working well in practice.
We propose a simple unconstrained parametrization of the convex coefficients that have been observed to perform well in our experiments. Specifically, if we know that the number of basis model is k, we reparameterize the convex coefficients α1, . . . , αk as a function of the unconstrained parameter vector v ∈ Rk with αi = 1/k+|vi| 1+∑ki=1 |vi| . The model ∑i αigθi (x) can be seen as a neural network that can be trained conventionally.
4.3 Implementation
In practice, a lot of interesting functions are unbounded, and we may need multiple output.
We can convert unbounded functions to bounded ones by using the scaled hard tanh hardtanh(y) = B max(-1, min(y, 1)) to clamp the output to [-B, B]. Sometimes it is beneficial to choose the scaling factor B to be larger than the actual possible range: when G contains the zero function, G is a larger set when B is larger.
When multiple outputs are needed, we can train a model for each output separately. If the convex hull contains the true input-output function for each output channel, then the generalization theory for the case of single output guarantees that we will learn all the input-output functions eventually.
5 Experiments
We choose gθ as a small neural network in our experiments. We compare the performance of the greedy algorithms (nicknamed as GCE, which stands for greedy convex ensemble) in Section 4 to study whether it is beneficial to use more sophisticated greedy algorithms. We also compare the greedy algorithms with XGBoost (XGB) and Random Forest (RF) to study how the convex combination constructed, which can be seen as a weighted ensemble, fare. Both XGB and RF provide strong baselines and are state-of-the-art ensemble methods that won many Kaggle competitions for non-CV non-NLP tasks. In addition, we also compare the greedy algorithms with the non-greedy method in Section 4.2 (NGCE), and a standard regularized neural network (NN). Both NGCE and NN need to assume a given number of basis functions. Comparison with NN sheds light on how the regularization effect of learning from a convex hull compare with standard ℓ2 regularization.
We used 12 datasets of various sizes and tasks (#instances and dimensions in brackets): diabetes (442/10), boston (506/13), ca_housing (20,640/8), msd (515,345/90) for regression; iris (150/4), wine (178/13), breast_cancer (569/30), digits (1,797/64), cifar10_f (60,000/342), mnist (70,000/784), covertype (581,012/54), kddcup99 (4,898,431/41) for classification. Most of the datasets are from UCI ML Repository [Dheeru and Karra Taniskidou, 2017]. All data attributes are normalized to have zero mean and unit variance. Further details on the datasets, their training/validation/test splits, hyper-parameter tuning and experimental setup are available at https://github.com/tan1889/gce .
5.1 Comparison of GCE Algorithms
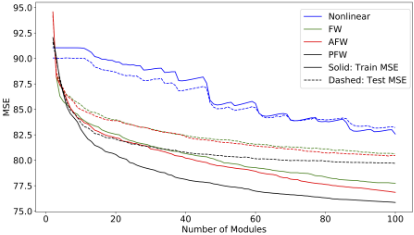
Fig. 1 shows the training and test error (MSE) on the msd dataset for the four greedy algorithms discussed in Section 4. For each variant, we train 100 modules, with each being a single neuron of the form B tanh(uT x). Interestingly, the non-linear greedy variant, which is most commonly studied, is significantly slower than other variants. The PFW variant has the best performance. We observed similar behavior of the algorithms on other datasets and settings, thus we only report the results for the PFWvariant in subsequent experiments.
5.2 Comparison of GCE with Other Algorithms
We compare GCE (using PFW to greedily choose new basis functions), NGCE, XGB, RF, and NN below.
Experimental setup. To ensure a fair comparison between algorithms, we spent a significant effort to tune hyperparameters of competing algorithms. Particularly, XGB and RF are tuned over 2000 hyper-parameters combinations for small datasets (has less than 10000 training samples), and over 200 combinations for large datasets.
The basis module for GCE is a two-layer network with 1 or 10 hidden neurons for small datasets and 100 hidden neurons for other datasets. GCE grows the network by adding one basis module at a time until no improvement on validation set is detected, or until reaching the maximum limit of 100 modules. NGCE and NN are given the maximum capacity achievable by GCE. For NGCE, it is 100 modules, each of 10/100 hidden neurons for small/large datasets. NN is a two layers neural net of 1000/10000 hidden neurons for small/large datasets, respectively. NGCE and NN are tuned using grid search over learning_rate ∈ {0.01, 0.001}, regularization ∈ {0, 10-6 , . . . , 10-1 }, totaling in 14 combinations.
| Datasets | GCE | XGB | RF | NN | NGCE |
|---|---|---|---|---|---|
| diabetes | 42.706 | 46.569 | 49.519 | 43.283 | 44.703 |
| boston | 2.165 | 2.271 | 2.705 | 2.217 | 2.232 |
| ca_housing | 0.435 | 0.393 | 0.416 | 0.440 | 0.437 |
| msd | 6.084 | 6.291 | 6.462 | 6.186 | 7.610 |
| iris | 0.00 | 6.67 | 6.67 | 3.33 | 10.00 |
| wine | 0.00 | 2.78 | 2.78 | 0.0 | 0.0 |
| breast_cancer | 3.51 | 4.39 | 8.77 | 3.51 | 4.39 |
| digits | 2.78 | 3.06 | 2.50 | 3.33 | 3.06 |
| cifar10_f | 4.86 | 5.40 | 5.16 | 5.00 | 4.92 |
| mnist | 1.22 | 1.66 | 2.32 | 1.24 | 1.11 |
| covertype | 26.70 | 26.39 | 27.73 | 26.89 | 26.56 |
| kddcup99 | 0.01 | 0.01 | 0.01 | 0.01 | 0.01 |
GCE uses a fixed set of hyper-parameters without tuning: learning_rate= 0.001, regularization= 0. All these three algorithms use ReLU activation, MSE criterion for training regression problem, cross entropy loss for classification. The training uses Adam SGD with learning_rate reduced by 10 on plateau (training performance did not improve for 10 consecutive epochs) until reaching the minimum learning_rate of 10-5 , at which point the optimizer is ran for another 10 epochs and then returns the solution with the best performance across all training epochs.
Results and Discussion. For each algorithm, the model using the hyper-parameters with the best validation performance is selected. Its test set performance is reported in Table 1. We ran the experiments on train/test splits fixed across all methods in comparison, instead of using multiple train/test splits, which can be useful for further comparison, but is beyond our computing resources.
From Table 1, GCE is competitive with the baselines on datasets with different numbers of features and examples. For regression problems, GCE uses up the maximum number of basis functions, while for classification problems, GCE often terminates way earlier than that, suggesting that it is capable to adapt to the complexity of the task.
We have chosen datasets from small to large in our experiments. The small datasets can be easily overfitted, and are useful for comparing how well the algorithms avoid overfitting. Empirical results show that GCE builds up the convex ensemble to just a right capacity, but not more. Thus, it has good generalization performance despite having almost little parameter tuning, even for the smaller datasets, where overfitting could easily occur. On the other extreme, overfitting a very large datasets, like kddcup99, is hard. So, empirical results for this dataset show that all models, including ours, have adequate capacity, as they have similar generalization performance. All algorithms were able to scale to the largest dataset (kddcup99), but GCE usually requires little hyper-parameter tuning, while XGB and RF involve significant tuning.
(a) Comparison of GCE against NN and NGCE. NN and NGCE have very similar performance as GCE on several datasets. NN does not perform well on msd, iris, digits, and cifar10_f, and NGCE does not perform well on diabetes, msd, iris, and breast_cancer. In particular, both NN and NGCE perform poorly on iris. We suspect that NN and NGCE may be more susceptible to local minimum, leading to an underfitted model, and we examined the training and test losses for GCE, NN and NGCE. For several datasets, the differences between the losses of the three algorithms are small, but large differences show up on some datasets. On diabetes and msd, both NGCE and NN seem to underfit, with much larger training and test losses than those of GCE. NGCE and NN seem to overfit boston, with similar test test losses as GCE, but much smaller training loss. NN seems to overfit on iris as well.
NGCE is slightly poorer than NN overall. An unregularized NN usually does not perform well. Since NGCE is trained without any additional regularization (such as ℓ2 regularization), this suggests that the convex hull constraint has similar regularization effect as a standard regularization, and the improved performance of GCE may be due to greedy training with early stopping.
GCE often learns a smaller model as compared to NGCE and NN on classification problems and does not know the number of components to use a priori. On the other hand, both NGCE and NN requires a priori knowledge of the number of basis functions to use, which is set to be the maximum number of components used for GCE. Finding the best size for a given problem is often hard.
(b) Comparison of GCE against XGBoost and RandomForest. GCE shows clear performance advantage over XGBoost and RandomForest on most domains, except that XGBoost has a clear advantage on ca_housing, and RandomForest performing slightly better on digits.
While RandomForest and XGBoost have quite a few parameters to tune, and a proper tuning often requires searching a large number of hyper-parameters, GCE works well across datasets with a default setting for basis module optimization (no tuning) and two options for module size. Overall, GCE is often more efficient than RandomForest and XGBoost as there is little tuning needed. In addition, for large datasets, RandomForest and XGBoost are slow due to the lack of mechanism for mini-batch training and no GPU speed-up.
6 Conclusion
This paper presents some new results and empirical insights for learning an optimal convex combination of basis models. While we focused on the case with neural networks as the basis models, the greedy algorithms in Section 4 can be applied with trees as basis models. In the case of the nonlinear greedy algorithm and a quadratic loss, the greedy step involves training a regression tree given a fixed step size. For FW variants and other losses, the objective function at each greedy step no longer corresponds to a standard loss function though. Regarding generalization, since trees are nonparametric, our generalization results do not hold, and we may face similar challenges as analyzing random forests. There are interesting questions for further work.
@inproceedings{ijcai2020p429,
  title     = {Greedy Convex Ensemble},
  author    = {Nguyen, Thanh Tan and Ye, Nan and Bartlett, Peter},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {3101--3107},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/429},
  url       = {https://doi.org/10.24963/ijcai.2020/429},
}
TY - CPAPER TI - Greedy Convex Ensemble AU - Nguyen, Thanh Tan AU - Ye, Nan AU - Bartlett, Peter T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 3101 EP - 3107 DO - 10.24963/ijcai.2020/429 UR - https://doi.org/10.24963/ijcai.2020/429 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





