
Accelerating Stratified Sampling SGD by Reconstructing Strata
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 2725-2731.
https://doi.org/10.24963/ijcai.2020/378
Keywords
- Machine Learning: Deep Learning: Convolutional networks
- Machine Learning: Clustering
- Machine Learning: Deep-learning Theory
- Machine Learning: Deep Learning
Abstract
In this paper, a novel stratified sampling strategy is designed to accelerate the mini-batch SGD. We derive a new iteration-dependent surrogate which bound the stochastic variance from above. To keep the strata minimizing this surrogate with high probability, a stochastic stratifying algorithm is adopted in an adaptive manner, that is, in each iteration, strata are reconstructed only if an easily verifiable condition is met. Based on this novel sampling strategy, we propose an accelerated mini-batch SGD algorithm named SGD-RS. Our theoretical analysis shows that the convergence rate of SGD-RS is superior to the state-of-the-art. Numerical experiments corroborate our theory and demonstrate that SGD-RS achieves at least 3.48-times speed-ups compared to vanilla minibatch SGD.
- [Borsos et al., 2018] Zalán Borsos, Andreas Krause, and Kfir Y Levy. Online variance reduction for stochastic op- timization. arXiv preprint arXiv:1802.04715, 2018.
- [Botev and Ridder, 2014] Zdravko Botev and Ad Ridder. Variance reduction. Wiley StatsRef: Statistics Reference Online, pages 1-6, 2014.
- [Finkel et al., 2008] Jenny Rose Finkel, Alex Kleeman, and Christopher D Manning. Efficient, feature-based, condi- tional random field parsing. In Proceedings of ACL-08: HLT, pages 959-967, 2008.
- [He et al., 2016] Kaiming He, Xiangyu Zhang, Shaoqing Ren, and Jian Sun. Deep residual learning for image recog- nition. In Proceedings of the IEEE conference on computer vision and pattern recognition, pages 770-778, 2016.
- [Johnson and Guestrin, 2018] Tyler B Johnson and Carlos Guestrin. Training deep models faster with robust, ap- proximate importance sampling. In Advances in Neural Information Processing Systems, pages 7265-7275, 2018.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In Advances in neural information pro- cessing systems, pages 315-323, 2013.
- [Katharopoulos and Fleuret, 2018] Angelos Katharopoulos and Franc ¸ois Fleuret. Not all samples are created equal: Deep learning with importance sampling. arXiv preprint arXiv:1803.00942, 2018.
- [Krizhevsky et al., 2012] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. In Advances in neural in- formation processing systems, pages 1097-1105, 2012.
- [Kumar and Kannan, 2010] Amit Kumar and Ravindran Kannan. Clustering with spectral norm and the k-means algorithm. In 2010 IEEE 51st Annual Symposium on Foun- dations of Computer Science, pages 299-308. IEEE, 2010.
- [Needell et al., 2016] Deanna Needell, Nathan Srebro, and Rachel Ward. Stochastic gradient descent, weighted sam- pling, and the randomized kaczmarz algorithm. Mathe- matical Programming, 155(1-2):549-573, 2016.
- [Salehi et al., 2017] Farnood Salehi, L Elisa Celis, and Patrick Thiran. Stochastic optimization with bandit sam- pling. arXiv preprint arXiv:1708.02544, 2017.
- [Simonyan and Zisserman, 2014] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv preprint arXiv:1409.1556, 2014.
- [Sutskever, 2013] Ilya Sutskever. Training recurrent neural networks. University of Toronto Toronto, Ontario, Canada, 2013.
- [Tang and Monteleoni, 2016] Cheng Tang and Claire Mon- teleoni. convergence rate of stochastic k-means. arXiv preprint arXiv:1610.04900, 2016. [Wikipedia contributors, 2019] Wikipedia contributors.
- Single-linkage clustering -Wikipedia, the free encyclo- pedia, 2019. [Online; accessed 21-January-2020].
- [Zhang et al., 2017] Cheng Zhang, Hedvig Kjellstrom, and Stephan Mandt. Determinantal point processes for mini- batch diversification. arXiv preprint arXiv:1705.00607, 2017.
- [Zhang et al., 2019] Cheng Zhang, Cengiz Öztireli, Stephan Mandt, and Giampiero Salvi. Active mini-batch sampling using repulsive point processes. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 33, pages 5741-5748, 2019.
- [Zhao and Zhang, 2014] Peilin Zhao and Tong Zhang. Ac- celerating minibatch stochastic gradient descent using stratified sampling. arXiv preprint arXiv:1405.3080, 2014.
- [Zhao and Zhang, 2015] Peilin Zhao and Tong Zhang. Stochastic optimization with importance sampling for reg- ularized loss minimization. In international conference on machine learning, pages 1-9, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Over the past decades, mini-batch Stochastic Gradient Descent (SGD) has become the main workhorse in classical machine learning tasks due to its balance between efficacy and scalability [Finkel et al., 2008; Krizhevsky et al., 2012; Sutskever, 2013]. To form a gradient estimate, the vanilla implementation of mini-batch SGD samples a small and fixed number of training instances uniformly in each iteration. Although uniform sampling is easy to implement, the resulting estimate may have a rather high variance since the component gradient of each sample can vary considerably, which results in the slow convergence of the underlying optimization procedure [Zhao and Zhang, 2015; Borsos et al., 2018].
A strategy that can significantly ameliorate the high variance issue is importance sampling, which constructs a nonuniform sampling distribution to ensure that important training instances are sampled more frequently. Obtaining the sampling distribution that minimizes the variance requires calculating all component gradients and is hence prohibitive. Zhao and Zhang [2015] and Needell et al. [2016] use training instances to calculate a fixed sampling distribution. Recently, there has been abundant research in finding iterationdependent sampling distributions. Katharopoulos and Fleuret
∗Corresponding Author
[2018] propose an upper bound of the gradient norm that can be calculated in the forward pass of the neural network and use this upper bound to calculate the sampling distribution. Johnson and Guestrin [2018] compute the sampling distribution using robust optimization and find the sampling distribution that is minimax optimal with respect to an uncertainty set. Salehi et al. [2017] and Borsos et al. [2018] formulate the sampling distribution learning as an online optimization problemwith the bandit feedback.
Another line of research that also aims to effectively reduce the variance of gradient estimates is stratified sampling [Botev and Ridder, 2014]. Stratified sampling involves two phases: first dividing a population into subpopulations and then applying uniform sampling methods to each subpopulation to form the estimates. When applying to mini-batch SGD, calculating and stratifying all component gradients at every iteration are computationally impractical. To reduce this overhead, Zhao and Zhang [2014] propose a practical algorithm SGD-ss forming fixed strata by clustering training instances instead of component gradients, which essentially determines strata by minimizing a surrogate bounding the stochastic variance from above. More recently, methods based on repulsive point process generalize the idea of SGD-ss by adopting a measure of similarity between data points, and allowing strata to overlap [Zhang et al., 2017; Zhang et al., 2019]. Although these methods substantially alleviate the overhead of stratification, their strata are predetermined before the main gradient descent iterations and cannot partition the time-variant component gradients well.
In this paper, a novel stratified sampling strategy is designed to accelerate the mini-batch SGD. Specifically, we derive a new iteration-dependent surrogate and propose a stochastic stratifying algorithm to find the strata that minimize it. Strata are reconstructed in an adaptive manner, that is, in each iteration, strata are reconstructed only if an easily verifiable condition is met. Based on this novel sampling strategy, we propose an improved stratified mini-batch SGD algorithm named SGD-RS. Our contributions can be summarized as follows.
- We derive a new surrogate bounding the stochastic variance from above. Compared with the counterpart used in SGD-ss, ours is closer to the stochastic variance and does not require the component gradient to be Lipschitz continuous with respect to the feature vector. As a re-
sult, our theoretical analysis shows better convergence rates than SGD-ss for both convex and non-convex objective functions.
- We design a strategy to substantially alleviate the overhead of reconstructing strata. Specifically, a reconstructing condition is devised for our method to avoid periteration computational load of stratification. We prove that, when current strata do not minimize the surrogate, the reconstruction is invoked with high probability. Therefore, strata maintained by this strategy attain the minimum of the surrogate with high probability for all SGD iterations, with only sporadical stratification.
Besides, we prove that our stratifying algorithm can find the optimal strata with high probability in polynomial time. Numerical experiments are conducted on popular applications including logistic regression and neural network based image classification. On the rcv1 binary classification dataset, SGD-RS achieves a more than 4-times speed-up compared to SGD-ss, with only 1.20% iterations reconstructing strata. On the CIFAR10 image classification dataset, a more than 3.5times speed-up is obtained by our method compared to SGDss, with merely 0.33% iterations reconstructing strata. On average, strata reconstructing occurs at a rate of 0.61%.
Notation. We use bold lowercase symbols to denote vectors (e.g., x). We denote the ℓ2 norm of vector a by ‖a‖ and the cardinality of set A by |A|. For a random variable x, Ex is its expectation.
2 Preliminaries
Throughout this paper, we use the empirical risk minimization setting to demonstrate the advantages of our method, from which the nature of stratification can be gleaned. Given training set {(x1, y1), . . . , (xn, yn)} where xs is the feature vector and ys is the label for all s ∈ {1, . . . , n}, we solve the empirical risk minimization problem
where W ⊆ Rd is a convex set, and the component function fs(w) = ℓ(w; xs, ys) designates the loss of model w encountered on datum (xs, ys). Let g be an unbiased estimate of the true gradient ∇f. The variance of g is defined as
2.1 Stratified Sampling for Mini-batch SGD
We now introduce stratified sampling for mini-batch SGD. At the t-th iteration, we partition the training set into k disjoint subsets At = {At1 , . . . ,Atk }. Each subset has cardinality nti = |Ati |. We sample subsets Bt i from Ati , i.e., Bt i ⊆ Ati . The mini-batch is the union of these sampled subsets Bt = Bt1 ∪ · · · ∪Btk . Let bti = |Bt i |. The pre-determined mini-batch size is b = ∑ki=1 bti .
SGD-ss assumes that ∂ℓ(wt ;xs,ys) ∂w is L-Lipschitz continuous with respect to xs [Zhao and Zhang, 2014] and uses iteration-independent strata A throughout training. bti is set as an iteration-independent constant bi = bni√ui ∑nj=1 nj √uj where ui = 1 ni ∑s∈Ai ∥∥xs - 1 |Ai | ∑r∈Ai xr ∥∥2 . SGD-ss then has gradient estimate
and the upper bound of the variance of ˆ∇fss(wt ), i.e.,
The fixed strata in SGD-ss are obtained by minimizing the right hand side of (3).
2.2 Importance Sampling for Mini-batch SGD
At the t-th iteration, importance sampling methods assign each s ∈ {1, . . . , n} a probability qts ≥ 0 such that ∑ns=1 qts = 1, and select training instances according to the sampling distribution qt = (qt1 , . . . , qtn ). The gradient estimate of importance sampling is then
where Bt is is the sampled mini-batch. According to [Johnson and Guestrin, 2018], its variance achieves minimum when qts ∝ ‖∇fs(wt )‖ for all s , i.e,
3 Method
In the section, we discuss two critical details of SGD-RS, strata construction and reconstructing condition.
3.1 Constructing Strata
The gradient estimate adopting both stratified sampling and importance sampling is
where pts is the probability assigned to s in Ati .
Proposition 1. (6) is an unbiased gradient estimate, and its variance can be bounded from above by
Finding the partition At and the probability pt minimizing (7) can be solved in an alternating manner, that is, we first find the best At with fixed pt , and then vice versa. As we shall see in Section 4.3, if we choose pt as a uniform distribution, we can obtain a good partition that already guarantees
Algorithm 1 Stochastic Stratifying
- 1: Input: wt , k, A0 , mini-batch size β and β0, learning rate sequence λτi , termination criterion. 2: Sample S0 of size β0 uniformly with replacement 3: GS0 = {∇fs(wt ), ∀s ∈ S0} 4: c0 ← run Single-Linkage on GS0 5: for τ = 0, . . . do 6: Sample indices S of size β uniformly with replacement; Set counter mi as 0 and Si as an empty set for all i = 1, . . . , k 7: GS = {∇fs(wt ), ∀s ∈ S} 8: for ∇fs(wt ) ∈ GS do 9: Find i = argminl ‖∇fs(wt ) - cτl ‖2 and I the current stratum s belongs to 10: Si = Si ∪ {s}; mi = mi + 1 11: if i ̸= I then Aτi = Aτi ∪ {s}; AτI = AτI -{s} 12: end if 13: end for 14: for i = 1, 2, . . . , k do 15: if mi > 0 then 16: ˆcτ+1 i = ∑s∈Si ∇fs(wt ) mi 17: cτ+1 i = (1 -λτi )cτi +λτi ˆcτ+1 i 18: else 19: cτ+1 i = cτi 20: end if 21: end for 22: if termination criterion is satisfied then return Aτ 23: end if 24: end for
a better performance than SGD-ss. With such pt , V t 0 (At , pt ) is reduced to the following form:
which is also the objective function of the standard k-means. We can find optimal At by algorithm 1 which is a modified version of the stochastic k-means [Tang and Monteleoni, 2016]. The difference is that stochastic k-means only updates the centroids and does not maintain the strata. As we shall see in Section 4.1, we prove that Algorithm 1 can find the strata minimizing (8) in polynomial time by extending Tang and Monteleoni's result.
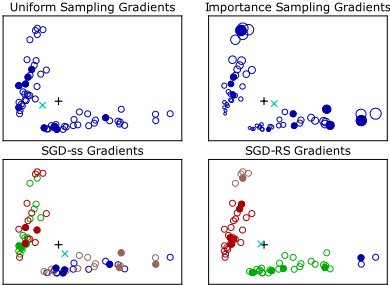
Note that in constrast to SGD-ss, we partition the training set by Euclidian distances between gradient vectors. We use Single-Linkage to initialize the centroids [Wikipedia contributors, 2019]. The stratification results for a 2-D logistic regression task are demonstrated in Figure 1 which shows that SGD-RS forms better strata than what SGD-ss does, and the gradient estimate is also closer to the true gradient.
3.2 Reconstructing Condition
To avoid per-iteration reconstruction of strata, we design a reconstructing condition that exploits a subset of the sampled mini-batch Dt = Dt1 ∪ · · · ∪Dtk , where Dt1 ⊆ Bt1 , . . . , Dtk ⊆
Btk . It is defined as
where vt i (s1, s2) is the distance between two component gradients within the same stratum i, i.e.,
The intuition is that we reconstruct the strata only when component gradients from the same stratum are not homogeneous.
We summarize the proposed SGD-RS in Algorithm 2. SGD-RS reconstructs strata when the reconstructing condition ζ(Dt ) is true. After calculating ˆ∇f(wt ), we perform stochastic gradient descent and project wt+1 into W.
4 Theoretical Analysis
In this section, we conduct theoretical analysis about SGDRS. All proofs are referred to the long version of this paper.
4.1 Algorithm 1 Terminates in Finite Steps
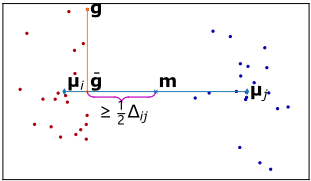
We prove that Algorithm 1 can find At that minimizes (8) in finite steps. We first introduce the proximity condition and illustrate it in Figure 2.
Definition 1 (Proximity condition (cf. [Kumar and Kannan, 2010])). Assume point set X admits ground truth nondegenerate 1 k-clustering (strata) T = {T1, . . . , Tk} with ground truth centroids µ = {µ1, . . . , µk}. Let ¯g be the projection of g onto the µi to µj line. We say a point g ∈ Ti
1 k-clustering is degenerate if any of its k clusters is empty.
Algorithm 2 SGD-RS
- 1: Input: initialization w0 , learning rate sequence ηt
- 2: for t = 0, 1, . . . , T -1 do
- 3: For all i, sample Bt i fromAti
- 4: Calculate gradient vectors {∇fs(wt ), s ∈ Bt }
- 5: if ζ(Dt ) is true then
- 6: Run Algorithm 1 to reconstruct At
- 7: For all i, sample Bt i fromAti
- 8: Calculate gradient vectors {∇fs(wt ), s ∈ Bt }
- 9: end if
- 12: end for
- 13: Output: Select ˜wT from {w0 , . . . ,wT-1 } according to probability P( ˜wT =wt ) = ηt ∑T -1 t=0 ηt
satisfies the proximity condition if for any i ̸= j, ¯g is at least ∆ij closer to µi than to µj, i.e.,
We assume that at iteration t the set of gradient vectors Gt admits ground truth non-degenerate k-clustering (strata) T t = {T t 1 , . . . , T t k } with ground truthcentroids µt = {µt1 , . . . , µtk }. The ground truth strata obtain the minimum of the surrogate. We further make following assumptions about Gt . These assumptions are commonly used in clustering literature (see e.g. [Tang and Monteleoni, 2016]).
Assumption 1 (δt -general dataset). Gt is a general dataset with δt -margin if all points satisfy the proximity condition and
Assumption 2 (F(a)-clusterability). We say that Gt is F(a)- clusterable if Gt has δt -margin such that for all i ̸= j,
where φt = ∑ki=1 ∑g∈T t i ‖g - µti ‖2 and F(a) ≥ max {αt , 64, 5a+5 256a } with 0 < a < 1 and αt = maxi,j |T t i | |T t j | .
Our proof is based on Tang and Monteleoni [2016]'s result which we include here for completeness.
Lemma 2 (Theorem 3 of [Tang and Monteleoni, 2016]). Suppose Gt satisfies Assumptions 1 and 2. Fix any 0 < θ ≤ 1e . If we set parameters β > ln(1-√a) ln (1-mini 4|T t i | ), λτi = c′ τ0+τ ,
ξ2 exp (2( F(a) 4 - 1)2 (ωt )2), then with probability at least (1 - θ)(1 - ξ), Algorithm 1 guarantees that
Algorithm 1 can assign all points to ground truth clusters in polynomial time when Assumptions 1 and 2 hold. The main idea is that ∑ki=1 ∑j̸=i |T t i ∩ Aτj | can be bounded using ∑ki=1 |T t i |‖cτi -µti ‖2 . Extending Lemma 2, we have the following result.
Theorem 3. When Assumptions 1 and 2 hold, if we use parameters in Lemma 2, Algorithm 1 guarantees that
with probability at least (1-ξ)(1-θ)(1-ν τ ), where ν τ = O( k τ ).
4.2 Reconstructing Condition
In this subsection, we prove that At maintained by SGD-RS minimizes (8) for all t with high probability.
The intuition that we can reconstruct strata sporadically is simple: the gradient vectors that are far away from each other at iteration t tend to be still far away at iteration t + 1, while the gradient vectors that are close to each other at iteration t tend to be still close at iteration t + 1. More specifically,
When wt and wt+1 are located within a locally smooth region, ‖∇fs(wt+1 ) - ∇fs(wt )‖ and ‖∇fr(wt+1 ) - ∇fr(wt )‖ are of order O(ηt ‖ˆ∇f(wt )‖) which is small if we set small learning rates. SGD-RS requires ϵt to satisfy ϵt ≤ δt , where δt is the margin in Assumption 1. When s2 and s1 are from different ground truth clusters, vt i (s1, s2) ≥ δt , ζ(Dt ) is true. The following lemma states that w.h.p. we reconstruct strata when there exists i such that Ati ̸= T t i .
Lemma 4. Assume that Gt is a δt -general dataset. When there exists i, such that Ati ̸= T t i , ζ(Dt ) is false with probability at most
Remark. As Lemma 4 states, if we choose an appropriate k, ∏ki=1 ∑kj=1 (ptij )|Dt i | is close to 0 even if some ∑kj=1 (ptij )|Dt i | 's approach 1 that implies ζ(Dt ) holds with high probability when there exists i, such that Ati ̸= T t i .
4.3 Faster Convergence
We now prove that SGD-RS improves the convergence rates for both convex and non-convex objectives by obtaining tighter variance upper bounds. We first give the following lemma.
Lemma 5. The minimum of V t 0 is less than or equal to the minimal upper bound of SGD-ss, i.e.,
Furthermore, SGD-RS has a tighter variance bound than SGD-ss, i.e.,
Now we formally give the convergence rates. Let w∗ = argminw∈W f(w) and σ2 ≥ maxt minAt ˆ V t 0 (At ) where At is maintained by SGD-RS.
Theorem 6. When ‖∇f(w)‖2 ≤ M 2 , and fs(w) is convex for all s = 1, . . . , n, then the objective can be bounded as follows
Theorem 7. If f(w) is non-convex and γ-Lipschitz smooth, then the number of iterations for E ‖∇f( ˜wT )‖2 to be smaller than ϵ2 is
where Ω(·) is the asymptotic lower bound.
Combining Lemma 4 and Lemma 5, SGD-RS has a tighter variance bound than SGD-ss for every iteration with probability at least 1 - ∏ki=1 ( ∑kj=1 (ptij )|Dt i |), which implies SGD-RS converges faster than SGD-ss for both convex and non-convex cases.
5 Experiments
In this section, we compare SGD-RS with state-of-theart algorithms, including SGD-ss [Zhao and Zhang, 2014], PDS [Zhang et al., 2019], Upper-bound [Katharopoulos and Fleuret, 2018], RAIS [Johnson and Guestrin, 2018], VRB [Borsos et al., 2018], and vanilla mini-batch SGD. SGD-ss pre-stratifies the dataset. PDS generalizes the idea of SGD-ss by adopting a measure of similarity between data points and also has iteration-independent sampling behaviours. Upperbound, RAIS, and VRB are importance sampling algorithms.
We run SGD-RS and baseline methods 5 times and report the averaged objective values, averaged testing losses, and the estimated variances of gradient estimates. The overhead of stratification and updating importance sampling distributions is considered in the comparison. To estimate the variances, we calculate the distances between gradient estimates and true gradients each time we run the algorithms and average the distances over the 5 rounds. The datasets and the corresponding parameter setup are summarized in Table 1.
| Dataset | rcv1 | ijcnn1 | w8a | MNIST | CIFAR10 | CIFAR100 |
|---|---|---|---|---|---|---|
| b | 100 | 200 | 300 | 100 | 100 | 100 |
| k | 50 | 100 | 50 | 50 | 50 | 50 |
5.1 Logistic Regression
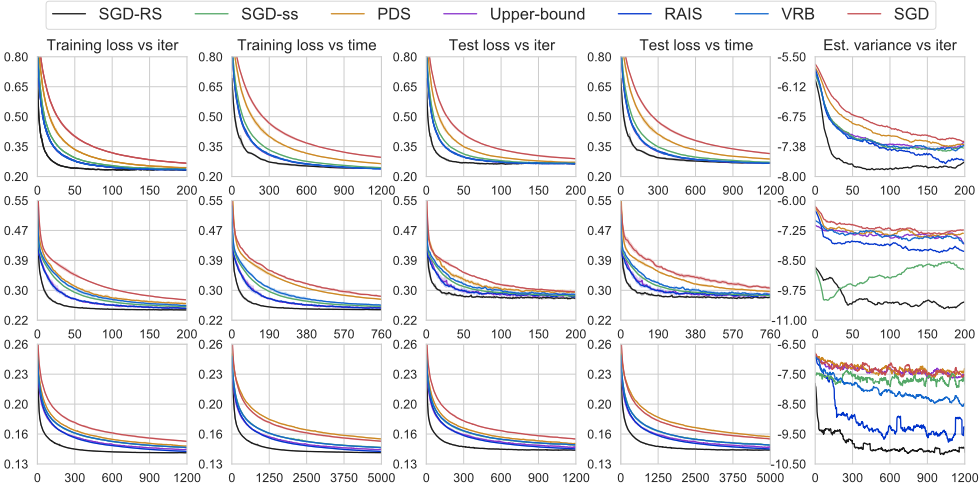
We conduct logistic regression experiments on three realworld benchmark datasets: rcv1, ijcnn1, and w8a 2 .
We can see from Figure 3 that both stratified sampling and importance sampling can reduce the variance of gradient estimates and accelerate the convergence. The gradient estimates in SGD-RS are more accurate than baseline methods and hence SGD-RS converges fastest. The variance of SGDRS can be as small as 8.2% of the variance of SGD-ss. We observe that strata reconstructing happens at rates of 1.20%, 2.90% and 2.07% on rcv1, ijcnn1, and w8a, respectively.
5.2 Image Classification
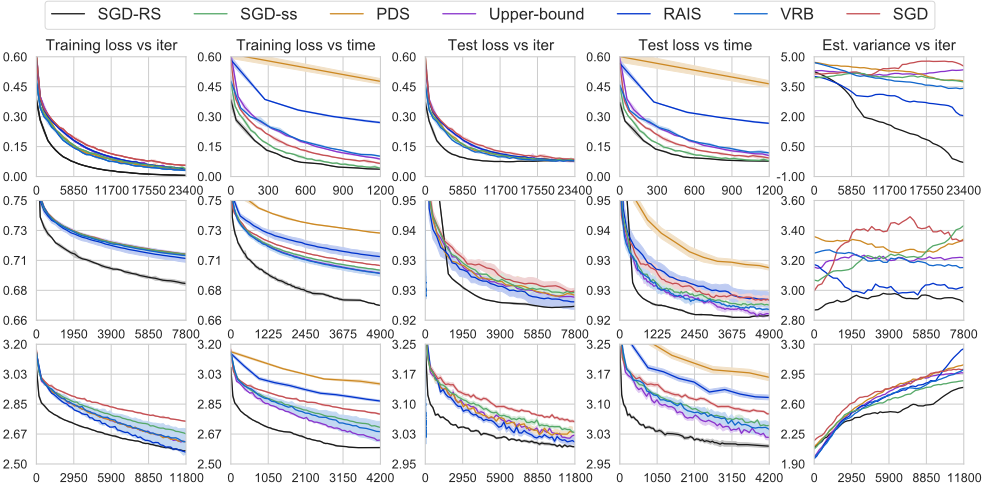
We evaluate the empirical performance of SGD-RS in image classification benchmark datasets: MNIST, CIFAR10, and CIFAR100. On MNIST, we train a simple network that has three fully-connected layers and two ReLU layers. We train VGG-11 [Simonyan and Zisserman, 2014] on CIFAR10 and ResNet-18 [He et al., 2016] on CIFAR100 respectively and the networks are initialized by running vanilla mini-batch SGD for 50 epochs.
2 These datasets are downloaded from libsvm websites https:// www.csie.ntu.edu.tw/∼cjlin/libsvmtools/datasets/
As is shown in Figure 4, SGD-RS consistently outperforms baseline methods both in terms of the objective value and the generalization performance. Strata reconstructing happens at rates of 0.27%, 0.33% and 1.26% on MNIST, CIFAR10, and CIFAR100 respectively. SGD-RS is also the most stable.
6 Conclusion
We propose a novel stratified sampling strategy for minibatch SGD. It maintains strata by minimizing an iterationdependent surrogate majorizing the variance of gradient estimates and accelerates the convergence. To alleviate the overhead of stratifying, we devise a reconstructing condition and reconstruct strata when the condition is met. We demonstrate its superiority in extensive experiments. This strategy is complementary to other variance reduction methods like SVRG [Johnson and Zhang, 2013] and can be used simultaneously.
Acknowledgments
This work is supported by Zhejiang Provincial Natural Science Foundation of China (Grant No: LZ18F020002, LR19F020005), and National Natural Science Foundation of China (Grant No: 61672376, 61751209, 61472347, 61572433, 61972347).
@inproceedings{ijcai2020p378,
  title     = {Accelerating Stratified Sampling SGD by Reconstructing Strata},
  author    = {Liu, Weijie and Qian, Hui and Zhang, Chao and Shen, Zebang and Xie, Jiahao and Zheng, Nenggan},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {2725--2731},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/378},
  url       = {https://doi.org/10.24963/ijcai.2020/378},
}
TY - CPAPER TI - Accelerating Stratified Sampling SGD by Reconstructing Strata AU - Liu, Weijie AU - Qian, Hui AU - Zhang, Chao AU - Shen, Zebang AU - Xie, Jiahao AU - Zheng, Nenggan T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 2725 EP - 2731 DO - 10.24963/ijcai.2020/378 UR - https://doi.org/10.24963/ijcai.2020/378 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





