
Dinkelbach-Type Algorithm for Computing Quantal Stackelberg Equilibrium
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 246-253.
https://doi.org/10.24963/ijcai.2020/35
Keywords
- Agent-based and Multi-agent Systems: Noncooperative Games
- Humans and AI: Cognitive Modeling
- Agent-based and Multi-agent Systems: Algorithmic Game Theory
Abstract
Stackelberg security games (SSGs) have been deployed in many real-world situations to optimally allocate scarce resource to protect targets against attackers. However, actual human attackers are not perfectly rational and there are several behavior models that attempt to predict subrational behavior. Quantal response is among the most commonly used such models and Quantal Stackelberg Equilibrium (QSE) describes the optimal strategy to commit to when facing a subrational opponent. Non-concavity makes computing QSE computationally challenging and while there exist algorithms for computing QSE for SSGs, they cannot be directly used for solving an arbitrary game in the normal form. We (1) present a transformation of the primal problem for computing QSE using a Dinkelbach's method for any general-sum normal-form game, (2) provide a gradient-based and a MILP-based algorithm, give the convergence criteria, and bound their error, and finally (3) we experimentally demonstrate that using our novel transformation, a QSE can be closely approximated several orders of magnitude faster.
- [Boyd and Vandenberghe, 2004] Stephen Boyd and Lieven Vandenberghe. Convex Optimization. Cambridge Univer- sity Press, 2004.
- [Brown and Sandholm, 2018] Noam Brown and Tuomas Sandholm. Superhuman ai for heads-up no-limit poker: Libratus beats top professionals. Science, 359(6374):418- 424, 2018.
- [Camerer, 2011] Colin F Camerer. Behavioral Game The- ory: Experiments in Strategic Interaction. Princeton Uni- versity Press, 2011.
- [Delle Fave et al., 2014] Francesco Maria Delle Fave, Al- bert Xin Jiang, Zhengyu Yin, Chao Zhang, Milind Tambe, Sarit Kraus, and John P Sullivan. Game-theoretic pa- trolling with dynamic execution uncertainty and a case study on a real transit system. Journal of Artificial Intelli- gence Research, 50:321-367, 2014.
- [Dinkelbach, 1967] Werner Dinkelbach. On nonlinear frac- tional programming. Management Science, 13(7):492- 498, 1967.
- [Fang et al., 2017] Fei Fang, Thanh H Nguyen, Rob Pickles, Wai Y Lam, Gopalasamy R Clements, Bo An, Amandeep Singh, Brian C Schwedock, Milind Tambe, and Andrew Lemieux. PAWS -a deployed game-theoretic application to combat poaching. AI Magazine, 2017.
- [Hastie, 2017] Trevor J Hastie. Generalized additive mod- els. In Statistical models in S, pages 249-307. Routledge, 2017.
- [Ibaraki, 1976] Toshimde Ibaraki. Integer programming for- mulation of combinatorial optimization problems. Dis- crete Mathematics, 16(1):39-52, 1976.
- [Kahneman and Tversky, 2013] Daniel Kahneman and Amos Tversky. Prospect theory: An analysis of decision under risk. In Handbook of the Fundamentals of Financial Decision Making: Part I, pages 99-127. World Scientific, 2013.
- [Kolodziej et al., 2013] Scott Kolodziej, Pedro M Castro, and Ignacio E Grossmann. Global optimization of bilin- ear programs with a multiparametric disaggregation tech- nique. Journal of Global Optimization, 57(4):1039-1063, 2013.
- [McCormick, 1976] Garth P McCormick. Computability of global solutions to factorable nonconvex programs: Part I -Convex underestimating problems. Mathematical Pro- gramming, 10(1):147-175, 1976.
- [McFadden, 1976] Daniel L. McFadden. Quantal choice analaysis: A survey. In Annals of Economic and So- cial Measurement, Volume 5, number 4, pages 363-390. NBER, 1976.
- [McKelvey and Palfrey, 1995] Richard D. McKelvey and Thomas R. Palfrey. Quantal response equilibria for normal form games. Games and Economic Behavior, 10(1):6-38, 1995.
- [Moravčík et al., 2017] Matěj Moravčík, Martin Schmid, Neil Burch, Viliam Lisý, Dustin Morrill, Nolan Bard, Trevor Davis, Kevin Waugh, Michael Johanson, and Michael Bowling. DeepStack: Expert-level artificial in- telligence in no-limit poker. Science, 2017.
- [Nguyen et al., 2016] Thanh H Nguyen, Arunesh Sinha, Shahrzad Gholami, Andrew Plumptre, Lucas Joppa, Milind Tambe, Margaret Driciru, Fred Wanyama, Aggrey Rwetsiba, Rob Critchlow, et al. Capture: A new predic- tive anti-poaching tool for wildlife protection. In Proceed- ings of the 15th International Conference on Autonomous Agents & Multiagent Systems, pages 767-775, 2016.
- [Nudelman et al., 2004] Eugene Nudelman, Jennifer Wort- man, Yoav Shoham, and Kevin Leyton-Brown. Run the GAMUT: A comprehensive approach to evaluating game- theoretic algorithms. In Proceedings of the 3rd Interna- tional Joint Conference on Autonomous Agents and Multi- agent Systems, volume 4, pages 880-887, 2004.
- [Pita et al., 2008] James Pita, Manish Jain, Janusz Marecki, Fernando Ordóñez, Christopher Portway, Milind Tambe, Craig Western, Praveen Paruchuri, and Sarit Kraus. De- ployed ARMOR protection: The application of a game theoretic model for security at the Los Angeles Interna- tional Airport. In Proceedings of the 7th International Joint Conference on Autonomous Agents and Multiagent Systems, pages 125-132, 2008.
- [Potts, 1999] William JE Potts. Generalized additive neural networks. In Proceedings of the 5th ACM SIGKDD in- ternational conference on Knowledge discovery and data mining, pages 194-200. ACM, 1999.
- [Tambe, 2011] Milind Tambe. Security and Game Theory: Algorithms, Deployed Systems, Lessons Learned. Cam- bridge University Press, New York, NY, USA, 2011.
- [Vielma et al., 2010] Juan Pablo Vielma, Shabbir Ahmed, and George Nemhauser. Mixed-integer models for non- separable piecewise-linear optimization: Unifying frame- work and extensions. Operations Research, 58(2):303- 315, 2010.
- [Wahba, 1990] Grace Wahba. Spline Models for Observa- tional Data, volume 59. SIAM, 1990.
- [Yang et al., 2012] Rong Yang, Fernando Ordonez, and Milind Tambe. Computing optimal strategy against quan- tal response in security games. In Proceedings of the 11th International Conference on Autonomous Agents and Mul- tiagent Systems-Volume 2, pages 847-854, 2012.
- [Yano et al., 2013] Masayuki Yano, James Douglass Penn, George Konidaris, and Anthony T Patera. Math, Numerics & Programming (for Mechanical Engineers). MIT, 2013.
- [Yechiam and Hochman, 2013] Eldad Yechiam and Guy Hochman. Losses as modulators of attention: Review and analysis of the unique effects of losses over gains. Psycho- logical Bulletin, 139(2):497, 2013.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Game-theoretic algorithms have been used for improving physical security (see examples in [Tambe, 2011]), protecting wildlife in natural parks [Fang et al., 2017], or beating human professionals in poker [Moravˇc´ık et al., 2017; Brown and Sandholm, 2018]. Following the standard game-theoretic assumption of perfectly rational players is, however, not optimal against human opponents and there are more effective strategies against subrational opponents [Pita et al., 2008; Delle Fave et al., 2014; Nguyen et al., 2016]. One of the most commonly used subrational models (a model of bounded rationality) is Quantal Response (QR) assuming that players choose better actions more often than worse actions instead of choosing only the best action [McKelvey and Palfrey, 1995]. In practical applications, the goal is to find the best strategy to deploy (i.e., to commit to) while assuming the other player plays the best response to this commitment - i.e., to compute a Stackelberg Equilibrium. QR is used as the response function in case of human players and the desired solution concept is termed Quantal Stackelberg Equilibrium (QSE).
Stackelberg Security Games (SSGs) [Tambe, 2011] are particularly useful game model with many deployed realworld applications but with certain limitations. The problem must be formulated in terms of allocating limited resources to a set of targets. This is often impossible, e.g., in classical games from economics (i.e., prisoner's/traveler's dilemma, location game [Nudelman et al., 2004]). In order to solve real-world problems beyond SSGs, we study optimal behavior against a quantal response opponent in more general models of normal-form games. We consider a very general class of response functions modelling both risk-averse and riskseeking opponents. An optimal strategy of the rational player against such a subrational opponent is described by a leaderfollower solution concept: the QSE. The leader computes and implements a fixed strategy and the follower responds to this strategy based on the quantal response function.
The natural formulation of the optimization problem computing QSE is non-concave. Moreover, we show that the number of local minima may grow linearly with the number of actions even in a zero-sum game. Hence, simple gradient ascent approaches are not likely to be effective. It is difficult to further analyze the problem of computing QSE directly, therefore, we derive a Dinkelbach-type formulation of the problem and use it to identify sufficient conditions for concavity of the problem. If the conditions are satisfied, the optimal solution can be found by gradient ascent. Furthermore, we generalize the linear relaxation developed for SSGs [Yang et al., 2012] to general normal-form game and use it to formulate a mixed integer linear program (MILP) for approximately solving the problem. The approach of SSGs cannot be applied directly, because it uses specific properties of SSGs.
In the experiments, we compare the convergence speed of gradient ascent in direct formulation to approximated Dinkelbach-type MILP formulation of QSE with various quantal functions. We show that the Dinkelbach-type algorithm is up to 25.5-times faster than one restart of gradient ascent and it also provides solutions of higher quality. For the most common quantal function (i.e., logit function) and sufficiently large games, the gradient ascent couldn't find a solution of the same quality even when running 153-times longer than the Dinkelbach-type algorithm.
2 Background
Normal-form games model one-shot interactions between players and can be visually represented as game matrices. Formally, a two-player NFG is defined as a tuple G = (N,A, u): N = {l, f} is a set of players, the leader and the follower. We use i to refer to one of the players, and -i to refer to his opponent. A = (Al,Af) denotes ordered sets of actions for each player. For each pair of actions (al, af), al ∈ Al, af ∈ Af , we define a utility function for each player ui : Al × Af → R. In zero-sum setting, we assume that u = uf , setting ul = -uf .
Pure strategies Πi assign one action to play in the game. A mixed strategy δi ∈ ∆i is a probability distribution over Πi. Because the actions are ordered, δj i denotes the probability of player i taking the j th action. For any pair of strategies δl ∈ ∆l, δf ∈ ∆f) we use ui(δl, δf) for the expected outcome of the game for player i when players follow strategies δl, δf . A best response of player i to the opponent's strategy δ-i is a strategy δBR i ∈ BRi(δ-i), where ui(δBR i , δ-i) ≥ ui(δ′i , δ-i) for all δ′i ∈ ∆i.
Solution Concepts in NFGs
We provide the formal definitions of Nash Equilibrium (NE) and Quantal Stackelberg Equilibrium (QSE).
Definition 1. Given a normal-form game G = (N, A, u), a tuple of mixed strategies (δN l , δN f ), δN l ∈ ∆l, δN f ∈ ∆f is a Nash Equilibrium if δN i is an optimal strategy of player i against strategy δN -i . Formally:
In NE, both players make decisions fully rationally. In this work, we assume two possible diversions from this assumption. Both are often observed in laboratory experiments with human players [Camerer, 2011]. First, humans differ from rational players in their approaches towards risk. When exposed to uncertainty, humans might intentionally attempt to avoid the gamble (risk aversion) or, in contrast, they may seek higher risks (risk love). The approaches are modelled via strictly increasing expected-utility function e. While the function of risk-neutral players is the identity, risk-averse players behave according to a concave and risk-seeking players according to a convex function. Humans also tend to combine both approaches: loss-attentive functions are riskaverse when the utility is non-positive and risk-seeking when the utility is positive [Yechiam and Hochman, 2013]. Vice versa, functions, which are risk-seeking when the utility is non-positive and risk-averse when the utility is positive are called loss-averse [Kahneman and Tversky, 2013].
Second, fully rational players always select the utilitymaximizing option. Relaxing this assumption leads to a "statistical version" of best response, which takes into account the inevitable error-proneness of humans and allows the players to make systematic errors [McFadden, 1976].
Definition 2. Let e be an expected-utility function. Function QR : ∆l →∆f is a quantal response function if it is monotonically increasing in expected utility:
where QRi (δ) is the probability of playing action ai . Quantal function QR is called canonical if
for all δ ∈ ∆l, aif ∈ Af and some real-valued function q.
Note that whenever q is a strictly positive increasing function, the corresponding QR is a valid quantal response function. We call such functions q generators of canonical quantal functions. Because of the conceptual differences between the quantal and expected-utility functions (i.e., error proneness vs. risk assessment), we keep both functions separated.
Definition 3. Given a normal-form game G = (N , A, u) and a quantal response function QR of the follower, a mixed strategy δQS ∈ ∆l describes a Quantal Stackelberg Equilibrium (QSE) if and only if
In QSE, a leader is fully rational. He commits to an optimal strategy given that a follower quantal-responds according to given quantal and expected-utility functions. We refer to Equation (4) as to the criterion function of QSE.
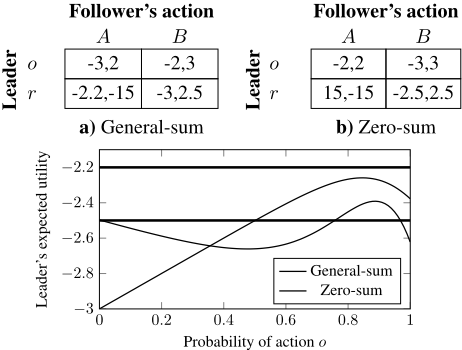
Example 1. Consider the matrix game shown on the left in Figure 1. Let the follower behave according to a canonical quantal function with generator q(x) = ex/2 and utility function e(x) = x (identity). Below the matrix is depicted a criterion function of the game's QSE (dashed) and a criterion function of the game's zero-sum variant's QSE (dotted), in which we set ul = -uf . In the general-sum game, the optimal strategy of the leader is to commit to playing action o with probability 0.846. To achieve the QSE in the zero-sum variant, the leader plays o with probability 0.887.
The example shows that in general, finding the QSE is a non-linear non-concave problem. To design methods for efficient computation of QSE, we analyze the properties of QSE in more detail in the next section.
3 Properties of QSE in NFGs
In this section, we first study the relation of QSE to NE. Then we show why gradient ascent methods often fail to compute a global optimum. Note that because NFGs have a finite number of actions and all utilities are finite, there always exists a strategy maximizing the QSE criterion function with a finite value. Moreover, in zero-sum NFGs, the leader's utility in QSE is always greater or equal to his utility in NE.
Observation 1. Let G = (N,A, u) be a zero-sumNFG, QR be a quantal response function of the follower and δN , δQS be the mixed strategies of the leader in NE and QSE, respectively. Then ul(δN , BR(δN )) ≤ ul(δQS , QR(δQS )).
Proof. From the definition of quantal response function uf(δ,BR(δ))) ≥ uf(δ,QR(δ)) for all δ ∈ ∆l. Therefore, in zero-sum games it holds that ul(δ,BR(δ))) ≤ ul(δ,QR(δ)). From the definition of QSE ul(δ,QR(δ))) ≤ ul(δQS ,QR(δQS )). Setting δ = δN yields the result.
The same observation does not hold for general-sum games. As shown in Figure 1, the expected utility of the leader in the general-sum game is -2.26. In NE, the leader plays action o and the follower responds with B, resulting in the expected utility of the leader -2.2, strictly higher than in QSE. In other words, facing a subrational opponent does not have to be an advantage in a general-sum game. From now on, we will focus our analysis on canonical quantal functions.
Observation 2. Let G = (N,A, u) be a normal-form game and q be a generator of a quantal function with an expectedutility function e. Then the leader's strategy δQS of QSE in G can be formulated as the following non-concave problem:
Non-concave maximization problems can be solved by gradient ascent. The gradient ascents are an efficient class of algorithms with a guarantee to approach a local maximum in a polynomial number of steps in case the gradient of the criterion function is Lipschitz-continuous [Boyd and Vandenberghe, 2004]. Unfortunately, the criterion function of QSE can have a large number of such local optima.
Conjecture 3. For every n, |Af | = n, there exists a zerosum NFG G and a generator q of a canonical quantal function with an expected-utility function e, such that a criterion function of QSE in G has at least n - 1 local maxima.
For every n, we define Gn = ((l, f), (Al,Anf ), uf) and set Al = {a1 , a2 }, Anf = {b1 , b2 , . . . , bn }. The utility function uf is defined as uf(a1 , b1 ) = 0.5, uf(a1 , bi ) = -10i for i ∈ [2, n] and uf(a2 , bi ) = 0 for all i ∈ [n], ul = -uf . Let q(x) = ex and e(x) = x if x < 0 and e(x) = 0 for
Algorithm 1 Dinkelbach-Type Algorithm for QSE
1: UB ←maxπ∈Π ul(π), LB ←minπ∈Π ul(π) 2: δ∗ ← argmaxδ∈∆l ∑π∈Πf (ul(δ, π) - LB)[e ◦ q](uf (δ, π)) 3: repeat 4: p ← (UB -LB)/2 5: v ←maxδ∈∆l ∑π∈Πf (ul(δ, π) - p)[e ◦ q](uf (δ, π)) 6: δp ← argmaxδ∈∆l ∑π∈Πf (ul(δ, π) - p)[e ◦ q](uf (δ, π)) 7: if v < 0 then LB ← p, δ∗ ← δp else UB ← p end if 8: until UB -LB < ϵ 9: return δ∗x ≥ 0. We were experimentally able to verify the conjecture up to games with n = 100, then the optima became too close to zero to verify their existence numerically. Applying restarted gradient ascent for solving QSE is thus impractical and can often lead to globally suboptimal local optima. Moreover, analysing the conditions when the criterion function of formulation (5) is concave is difficult, as concavity is not preserved under division 1 .
4 Dinkelbach-Type Formulation of QSE
This section introduces a transformation of the QSE formulation (5) into an equivalent optimization problem. This new formulation allows us to devise the conditions for approximating QSE in polynomial time.
The transformation is called the Dinkelbach's method for solving nonlinear fractional programming problems [Dinkelbach, 1967] and we can adapt it for finding the QSE because formulation (5) is a fractional program. The key idea of the Dinkelbach's algorithm is to express a problem in a form of maxx∈M f(x)/g(x), g(x) > 0 for some convex set M and continuous, real-valued functions f and g as an equivalent problem of finding a unique root of function F(p) = maxx∈M{f(x) - pg(x)}, p ∈ R. It holds that maxx∈M f(x)/g(x) = p∗ if and only if F(p∗ ) = 0. Because F is a maximum of functions affine in p, it is convex. Finding the root is hence straightforward (e.g., a binary search method can be used for this purpose) and it can be done efficiently if and only if we are able to effectively determinate the value of function F for any p. Computing the maximum of the original formulation of QSE (5) is hence equivalent to solving a sequence of optimization subproblems
as described in Algorithm 1. We refer to Equation (6) as to the Dinkelbach subproblem of the Dinkelbach formulation of QSE. Algorithm 1 iteratively updates the upper bound (UB) and lower bound (LB) on the value of QSE according to a binary search method for finding a root of a function. Note that because of Observation 1, we are able to set the initial lower bound to the value of NE in case the game is zerosum. This binary-search approach generalizes the same technique already used for computing logit QSE in security games [Yang et al., 2012]. The following proposition derives sufficient conditions for Algorithm 1 to run in polynomial time.
1 Generalized concavity (e.g., pseudoconvavity or quasiconcavity) is preserved under division, but it imposes too strong assumptions on the game utilities to be used in practice.
Proposition 4. Let G = (N,A, u) be an NFG, q be a twice differentiable generator of a canonical quantal function and e be a twice differentiable expected-utility function, such that the gradient of the Dinkelbach formulation is Lipschitz-continuous. For each pure strategy π ∈ Πf , denote uiπ = minπl∈Πl ui(π, πl) and uiπ = maxπl∈Πl ui(π, πl). Moreover, let ui = minπ∈Πf uiπ and ui = maxπ∈Πf uiπ . Then QSE is polynomially approximable if for all π ∈ Πf and any x ∈ [ulπ , ulπ ], y ∈ [ufπ , ufπ ] and p ∈ [ul , ul]
where for any function g, g′ denotes a derivative of g.
Proof. If the Dinkelbach subproblem is concave, the gradient-ascent methods are guaranteed to reach a global optimum. We hence analyse the conditions when an equivalent minimization formulation is convex, i.e., its Hessian matrix is positive semidefinite (PSD). The Hessian matrix is of a form c · uf(π)uf(π)T -
[[e ◦ q](uf (π)T δ))]′ (ul(π)uf (π)T + uf (π)ul(π)T ), where c = (p-ul(π)T δ) (q′ (e(uf(π)T δ))e′′ (uf(π)T δ) + q′′ (e(uf(π)T δ))e′2 (uf(π)T δ)) and ul(π)T δ is the expected utility ul(δ, π) (and similarly for the follower). A well-known fact from linear algebra states that for nonzero n-dimensional real-valued vectors u, v, the matrix uvT is positive semidefinite iff uT v ≥ 0. By this fact, uf(π)uf(π)T is PSD. The matrix c · uf(π)uf(π)T is then PSD if c ≥ 0. Because q, e are increasing functions, matrices -ul(π)uf(π)T ,-uf(π)ul(π)T are PSD if ul(π)T uf(π) ≤ 0. Because the expected utility ui(π)T δ always lies in the interval [uiπ , uiπ ] and p is upper (lower) bounded by leader's maximal (minimal) utility in the game, by substituting for c we conclude that the Dinkelbach formulation of QSE is concave if conditions (7) holds.
Note that with additional assumptions about functions q and e (e.g., concavity or convexity), the condition stated in Proposition 4 can be expressed just in the terms of maximal and minimal utility in the game and is hence easier to check.
5 Solving the Dinkelbach Subproblem
In case a game and the quantal and expected-utility functions do satisfy the condition stated in Proposition 4, the gradientascent methods will converge to a globally optimal strategy of the leader. In the opposite case, however, the guarantees are lost. In this section, we introduce efficient linearization methods with bounds on the solution quality to approximate the global optimum through a piecewise-linear approximation (PWLA) of the Dinkelbach subproblem in any game. The PWLA is subsequently turned into a mixed-integer linear program (MILP) and solved using standard methods.
Limitations of PWLA in General NFGs
In SSGs, the formulation of the logit QSE has separable variables, i.e., the multivariate function can be written as a sum of univariate functions. Therefore, the authors were able to linearize it efficiently [Yang et al., 2012]. In contrast, the Dinkelbach formulation in NFGs is not separable in general and the probability simplex must be linearized into multivariate polytopes. The most straightforward method is to split the simplex into an exponential number of hypercubes of dimension |Al| using a fixed step size. To obtain a continuous PWLA, each hypercube must be split into an exponential number of triangulations. To escape the curse of dimensionality, instead of splitting a hypercube, we compute the PWLA in the whole hypercube by linear least squares. The resulting formulation is transformed to an MILP using the DLog construction [Ibaraki, 1976; Vielma et al., 2010]. The DLog construction was shown to be the fastest by [Vielma et al., 2010], because of introducing only a logarithmic number of binary variables in the number of polytopes. Since we construct one polytope for every hypercube and the number of hypercubes is exponential in |Al|, the final MILP is of a polynomial size in |Al|.
We implemented PWLA and experimentally verified that it won't scale to games with more than 5 actions of the leader. To improve its efficiency, it is necessary to find a precise enough separable approximation of the Dinkelbach subproblem: maxδ∈∆l d1p (δ) - pd2p (δ), where d1p (δ) = ∑π∈Πf ul(δ, π)[e ◦ q](uf(δ, π)), d2p (δ) = ∑π∈Πf [e ◦ q](uf(δ, π)))). Each of d1p , d2p is approximated as d1p (δ) ≈ ∑|Al | i=1 ˜ d1p,i (δi ) and d2p (δ) ≈ ∑|Al| i=1 ˜ d2p,i (δi ), where ˜ d1p,i , ˜ d2p,i are (possibly) non-linear univariate functions.
Separation via Substitution
To introduce a method for finding the separable approximation, we split the whole class of general-sum games into two disjoint classes: linearly dependent and linearly independent games.
Definition 4. A normal-form game G is called linearly dependent, if for each strategy π ∈ Πf there exists a constant cπ ∈ R, such that for each action al ∈ Al it holds that ul(al, π) = cπuf (al, π).
Note that all zero-sum games are linearly dependent since we can set cπ = -1. For linearly dependent games, we can introduce a new variable yπ for each pure strategy π ∈ Πf with a linear substitution uf(δ, π) = yπ. The problem of solving the Dinkelbach subproblem is hence expressed as
Both functions [e ◦ q](yπ) and yπ[e ◦ q](yπ) are easily linearizable univariate functions. In case each yπ is divided uniformly into K segments, the final standard MILP formulation has (K - 1) × |Πf | binary variables [Yang et al., 2012]. The following proposition claims that the error goes to zero as ϵ goes to zero and K approaches infinity.
Proposition 5. Let δ∗ be a strategy computed by Algorithm 1 with precision ϵ and the subproblems solved via linearization of (8) and (9) with K segments. Let δQS be a mixed strategy of the leader in QSE. Then for the utility difference
Proof. For any twice differentiable univariate function g, let g be a uniform piece-wise linearization of g into K segments on interval [a, b]. The maximum difference in values of g and g is then [Yano et al., 2013]
where C = maxx∈[a,b] |g′′ (x)|. The fractional criterion function (5) of the direct formulation of QSE can be expressed as QSE(δ) = ul(δ, QR(δ)) = N(δ)/D(δ), where
where I is the identity function. The linearized criterion function is then QSE(δ) = N(δ)/D(δ), where
Denote δQS the optimal solution of maxδ∈∆l QSE(δ). Then we have
We bound each of these terms separately. For the first and the last term we use the first part of Lemma 7 of [Yang et al., 2012]. By this Lemma, for each δ ∈ ∆l, we have
where dD = ∣∣D(δ) -D(δ)∣∣ and dN = ∣∣N(δ) -N(δ)∣∣. From the linearization bound (10),
Because D(δ) ≥ [e◦q](uf ) and QSE(δ) ≤ ul, together with (11), we conclude that
Because δQS and δQS are the maxima of QSE and QSE, respectively, the difference in their values is also at most (ul ˜ C2 + ˜ C1)/[e ◦ q](uf ). To see why this is true, for contradiction, assume that |QSE(x) -QSE(x)| ≤ c, but without a loss of generality QSE(δQS ) -QSE(δQS ) > c. By combining both inequalities we have QSE(δQS ) > QSE(δQS ), δQS is hence not a maximum.
For bounding the second term we use the properties of the Dinkelbach formulation. From Algorithm 1, for each δ ∈ ∆l, we have N(δ) - UBD(δ) ≤ 0 and N(δ∗ ) - LBD(δ∗ ) ≥ 0. Therefore, for the optimal strategy δQS it holds that LB ≤ N(δQS )/D(δQS ) ≤ UB and hence
By combining the bounds (12) and (13) we conclude that
In NFGs which are linearly independent, we can take advantage of the fact that all quantal and expected-utility functions are invertible because they are strictly monotone. Let g-1 be an inverse of a function g. A substitution [e ◦ q](uf (δ, πl)) = yπ leads to an easily linearizable constraint
With an additional substitution ul(δ, π)) = zπ, the problem of solving the Dinkelbach subproblem is expressed as
where zπyπ are |Πf | bilinear terms 2 . For linearizing the bilinear terms, we can use either McCormick's envelopes [McCormick, 1976], which are fully linear, or the MDT method [Kolodziej et al., 2013]. The size of the MILP formulation for the McCormick's envelopes is |Πf | real variables and (K - 1) × |Πf | binary variables. Experimental evaluation of the MDT method showed that while it provides close-tooptimal solutions, the additional binary variables required by the method significantly slow down the computation. We hence focus more on the McCormick's envelopes.
Proposition 6. Let δ∗ be a strategy computed by Algorithm 1 with precision ϵ, the subproblems solved via linearization of (15) - (17) with K segments and bilinear terms relaxed using McCormick's envelopes. Let δQS be a mixed strategy of the leader in QSE. Then for the utility difference d = |ul(δ∗ ,QR(δ∗ )) -ul(δQS ,QR(δQS ))| it holds that
2 Note that if we would use the same substitution as in the case of linearly dependent games, the number of bilinear terms would be K × |Πf |, i.e., K-times larger.
Proof. We follow a reasoning of proof of Proposition 5 up to Equation (11). In linearly independent games, we linearize the composition of inverse functions [e ◦ q]-1 in constraint (16), instead of function [e ◦ q]. Therefore, to estimate the differences |N(δ) - N(δ)| and |D(δ) - D(δ)|, we seek to bound the linearization error ∣∣∣[e ◦ q](x) - [e ◦ q]-1-1 (x)∣∣∣.
Assume that [e ◦ q]-1 is uniformly linearized in points x0, x1, . . . , xK-1, i.e., [e ◦ q]-1 (xi) = [e ◦ q]-1 (xi) = yi, ∀i ∈ [K]. Every piece-wise linear function is invertible. Since [e ◦ q](yi) = xi = [e ◦ q]-1-1 (yi), function [e ◦ q]-1-1 is a linearization of function [e ◦ q]. Function [e ◦ q]-1 in not identity in general. Hence, the linearization is non-uniform. Since the distance between any xi, xi+1 is ([e ◦ q](uf) - [e ◦ q](uf )) /K, the maximum difference in values of any consecutive yi, yi+1 is bounded by
where eq = [e ◦ q](uf ) and eq = [e ◦ q](uf). Using the bound on a maximum difference between [e ◦ q](x) and
[e ◦ q]-1-1 (x) by [Yano et al., 2013], we have
For bounding the difference |N(δ) -N(δ)|, we need to take into account also the error arising from relaxing the bilinear terms using McCormick's envelopes. The McCormick's envelope is a convex polytope defined by four linear inequalities [McCormick, 1976]. Using simple algebra, it can be shown that the difference between a bilinear term zπyπ in Equation (15) and its approximation by McCormick's envelope is at most M, where
Using the bound (19), the difference between N(δ) and N(δ) can be bounded as
We proceed as in Proposition 5, using Equations (11), (13), and a modified Equation (12), which uses bounds (18) and (20). The result follows.
Note that because of the relaxation, the bound does not go to zero with increasing K and decreasing ϵ. However, it can be fairly small for games with a higher value of [e ◦ q](uf ).
Separation via Additive Approximations
Besides substitution, we considered computing separable approximations also through generalized additive models (GAMs) [Hastie, 2017]. GAMs can be used to approximately solve the Dinkelbach subproblem in case the link function of the model is an identity. We implemented two methods for fitting GAMs in the subproblem: a spline method ( ˜ d1p and ˜ d2p are smoothing splines [Wahba, 1990]) and a deep neural network method ( ˜ d1p and ˜ d2p are constructed from activation functions [Potts, 1999]). Our experimental evaluation showed that piecewise-linear separable approximations of the Dinkelbach subproblem lead to fast computation of a solution of the approximation (especially for linearly independent games), but neither the spline method nor the neural networks provide approximations precise enough for the Dinkelbach method to converge to an optimum.
6 Experiments
Finally, we demonstrate practical aspects of proposed algorithms for computing QSE in NFGs. As a benchmark, we use the original formulation solved by gradient ascent (GA). We compare it to the Dinkelbach-type algorithm (DTA) - Algorithm 1 with subproblems solved via substitutional PWLA. All implementations were done in C++17. We used an implementation of the SLSQP GA algorithm in the NLOPT 2.6.1 library for non-linear optimization. A single-threaded IBM CPLEX 12.8 solver carried all MILP computations. The experiments were performed on a 3.2GHz CPU with 16GB RAM. Because the algorithm is domain independent, we used Randomly Generated Games (RGGs) for evaluation.
Experimental Setting. We consider six different generators of canonical quantal functions (four convex functions: e0.4x , e0.8x , e1.2x and -1050/(x + 20), and two concave functions: lnx+12 and √x+11) and three expected-utility functions (one risk-neutral: x, one loss-attentive: x3 /100 and one loss-averse: 20/(1+e-x )-10). We construct games with action spaces of sizes from 3, 000×50 up to 7, 500×50. The tolerance parameter for the GA algorithm in NLOPT was set to 10-6 (equivalent to the default CPLEX tolerance parameter) and ϵ = 2% of the leader's utility range for the DTA's binary search. The linearization uses K = 5. For each combination of game size × generator function × expected-utility function, we constructed and solved 5 instances. The utilities of the follower were generated uniformly randomly from interval [-10, 10], while the constants cπ for linearly dependent RGGs were generated from interval [-3, 3].
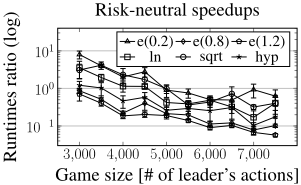
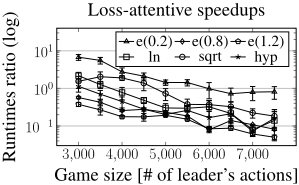
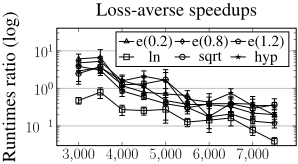
Runtimes. In Figure 2 we present the speedup results achieved with the DTA in linearly dependent RGGs. The xaxis shows the game size, while the y-axis varies the mean speedup in the game. We measure the speedup as a ratio between runtime of the DTA and runtime of one restart of the GA. Every point in the graph corresponds to the mean over the sampled instances and also shows the achieved standard error. The results show that with the increasing size of the game, the speedup of the DTA also increases, being up to 25.5-times faster than one restart of GA for games with 7500 leader's actions. It suggests that for even larger games, the DTA should perform significantly better than the GA.
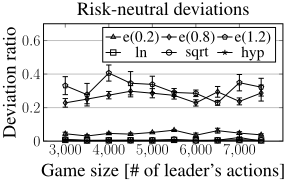
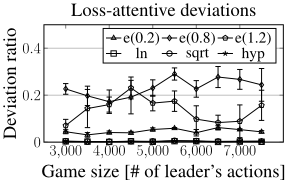
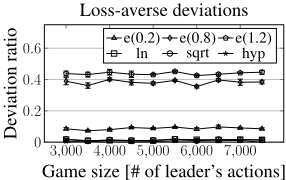
SolutionQuality. The relative errors of computed solutions are presented in Figure 3. The x-axis varies the game size. The y-axis shows the mean ratio of the difference in the defender's expected utility computed using one restart of the Game size [# of leader's actions]
| Risk-neutral restarts | Loss-attentive restarts | Loss-averse restarts | |||||||
|---|---|---|---|---|---|---|---|---|---|
| size | ln | sqrt | hyp | ln | sqrt | hyp | ln | sqrt | hyp |
| 3000 | 7.60 ± 3.68 | 5.40 ± 3.30 | 1.80 ± 0.71 | 1.00 ± 0.00 | 4.80 ± 3.39 | 1.00 ± 0.00 | 19.00 ± 1.15 | 6.25 ± 4.58 | 1.60 ± 0.35 |
| 4000 | 1.00 ± 0.00 | 6.25 ± 4.60 | 1.40 ± 0.35 | 1.00 ± 0.00 | 1.00 ± 0.00 | 1.00 ± 0.00 | 5.75 ± 4.75 | 13.60 ± 7.31 | 1.00 ± 0.00 |
| 5000 | 1.00 ± 0.00 | 1.00 ± 0.00 | 1.00 ± 0.00 | 1.00 ± 0.00 | 1.00 ± 0.00 | 1.00 ± 0.00 | 4.00 ± 2.38 | 2.30 ± 1.53 | 1.20 ± 0.17 |
GA and the DTA to the absolute difference between the maximal and minimal utility in the game. While the DTA is guaranteed to approximate a global solution, there is no guarantee of a solution quality for the GA. The results show that the GA never finds a better solution than the DTA (otherwise the ratio would be negative). However, the GA's solution quality is comparable to the DTA for concave functions and the hyperbole. The quality degrades rapidly for the exponential functions for all three expected-utility functions, especially for higher coefficients. For the loss-averse function, the quality of the GA's solution with exponential quantal function with coefficient 1.2 is on average at least 42.5-times worse than the solution of the DTA.
GA Restarts. The number of restarts of the GA required to reach a deviation from the DTA's solution less than 1% is shown in Table 1. We restarted the GA 20 times and counted the first restart when the deviation was sufficiently small. None of the exponential functions was able to find a good-enough solution within the 20 restarts. This suggests that to obtain comparable results with the most commonly used quantal function - the exponential function with a higher coefficient - in games with at least 7000 actions of the leader, the GA has to run at least 153× longer than the DTA. In contrast, the concave functions and the hyperbole computed nearly-optimal solutions within the first few restarts. This result is consistent with the deviations reported in Figure 3.
Due to space constraints, we do not report the results achieved with linearly independent games and the GA solving the Dinkelbach subproblem. Because of McCormick's envelopes, the DTA achieved even faster speedups: up to 3030times faster than one restart of GA for exponential functions and games with at least 7000 actions. However, due to the relaxation, the quality of the solutions was often worse (but no more than 12% for the exponential functions and 6% for other quantal functions) than GA's solutions. The GA running on the Dinkelbach subproblem has the theoretical guarantees (Proposition 4), but its runtimes are comparable to GA on the direct formulation.
7 Conclusion
We introduced a Dinkelbach-type formulation of computing a boundedly-rational quantal Stackelberg equilibrium in normal-form games. In contrast to the direct formulation, the Dinkelbach formulation has both the theoretical advantages (i.e., we can explicitly check how closely we approximate the global optimum) as well as positive computational consequences - the formulation offers up to 25.5-times speedup when compared with the original formulation.
Acknowledgments
This research is supported by the SIMTech-NTU Joint Laboratory on Complex Systems, the Czech Science Foundation (grant no. 1827483Y and 19-24384Y) and by the OP VVV MEYS funded project CZ.02.1.01/0.0/0.0/16 019/0000765 "Research Center for Informatics". Bo An is partially supported by Singtel Cognitive and Artificial Intelligence Lab for Enterprises (SCALE@NTU), which is a collaboration between Singapore Telecommunications Limited (Singtel) and Nanyang Technological University (NTU) that is funded by the Singapore Government through the Industry Alignment Fund - Industry Collaboration Projects Grant.
@inproceedings{ijcai2020p35,
  title     = {Dinkelbach-Type Algorithm for Computing Quantal Stackelberg Equilibrium},
  author    = {Cerny, Jakub and Lisý, Viliam and Bošanský, Branislav and An, Bo},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {246--253},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/35},
  url       = {https://doi.org/10.24963/ijcai.2020/35},
}
TY - CPAPER TI - Dinkelbach-Type Algorithm for Computing Quantal Stackelberg Equilibrium AU - Cerny, Jakub AU - Lisý, Viliam AU - Bošanský, Branislav AU - An, Bo T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 246 EP - 253 DO - 10.24963/ijcai.2020/35 UR - https://doi.org/10.24963/ijcai.2020/35 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





