
Diversity-Inducing Policy Gradient: Using Maximum Mean Discrepancy to Find a Set of Diverse Policies
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. AI for Improving Human Well-being. Pages 5923-5929.
https://doi.org/10.24963/ijcai.2019/821
Keywords
- Special Track on AI for Improving Human-Well Being: Health applications (Special Track on AI and Human Wellbeing)
Abstract
Standard reinforcement learning methods aim to master one way of solving a task whereas there may exist multiple near-optimal policies. Being able to identify this collection of near-optimal policies can allow a domain expert to efficiently explore the space of reasonable solutions. Unfortunately, existing approaches that quantify uncertainty over policies are not ultimately relevant to finding policies with qualitatively distinct behaviors. In this work, we formalize the difference between policies as a difference between the distribution of trajectories induced by each policy, which encourages diversity with respect to both state visitation and action choices. We derive a gradient-based optimization technique that can be combined with existing policy gradient methods to now identify diverse collections of well-performing policies. We demonstrate our approach on benchmarks and a healthcare task.
- [Chen et al., 2018] W. Y. Chen, L. Mackey, J. Gorham, F.-X. Briol, and C. J. Oates. Stein Points. ArXiv e-prints, March 2018.
- [Cohen et al., 2019] Andrew Cohen, Xingye Qiao, Lei Yu, Elliot Way, and Xiangrong Tong. Diverse exploration via conjugate policies for policy gradient methods. arXiv preprint arXiv:1902.03633, 2019.
- [Eysenbach et al., 2018] Benjamin Eysenbach, Abhishek Gupta, Julian Ibarz, and Sergey Levine. Diversity is all you need: Learning skills without a reward function. arXiv preprint arXiv:1802.06070, 2018.
- [Fard and Pineau, 2011] Mahdi Milani Fard and Joelle Pineau. Non-deterministic policies in markovian decision processes. J. Artif. Intell. Res.(JAIR), 40:1-24, 2011.
- [Gangwani et al., 2018] Tanmay Gangwani, Qiang Liu, and Jian Peng. Learning self-imitating diverse policies. arXiv preprint arXiv:1805.10309, 2018.
- [Ghavamzadeh et al., 2015] Mohammad Ghavamzadeh, Shie Mannor, Joelle Pineau, Aviv Tamar, et al. Bayesian reinforcement learning: A survey. Foundations and Trends R in Machine Learning, 8(5-6):359-483, 2015.
- [Gretton et al., 2007] Arthur Gretton, Karsten M Borgwardt, Malte Rasch, Bernhard Schölkopf, and Alex J Smola. A kernel method for the two-sample-problem. In Advances in neural information processing systems, pages 513-520, 2007.
- [Gretton et al., 2012] Arthur Gretton, Dino Sejdinovic, Heiko Strathmann, Sivaraman Balakrishnan, Mas- similiano Pontil, Kenji Fukumizu, and Bharath K Sriperumbudur. Optimal kernel choice for large-scale two-sample tests. In Advances in neural information processing systems, pages 1205-1213, 2012.
- [Haarnoja et al., 2017] Tuomas Haarnoja, Haoran Tang, Pieter Abbeel, and Sergey Levine. Reinforcement learn- ing with deep energy-based policies. arXiv preprint arXiv:1702.08165, 2017.
- [Hong et al., 2018] Zhang-Wei Hong, Tzu-Yun Shann, Shih- Yang Su, Yi-Hsiang Chang, Tsu-Jui Fu, and Chun-Yi Lee. Diversity-driven exploration strategy for deep reinforce- ment learning. In Advances in Neural Information Pro- cessing Systems, pages 10489-10500, 2018.
- [Johnson et al., 2017] Alistair EW Johnson, David J Stone, Leo A Celi, and Tom J Pollard. The mimic code repos- itory: enabling reproducibility in critical care research. Journal of the American Medical Informatics Association, 25(1):32-39, 2017.
- [Lange et al., 2012] Sascha Lange, Thomas Gabel, and Mar- tin Riedmiller. Batch reinforcement learning. In Rein- forcement learning, pages 45-73. Springer, 2012.
- [Lehman and Stanley, 2011] Joel Lehman and Kenneth O Stanley. Abandoning objectives: Evolution through the search for novelty alone. Evolutionary computation, 19(2):189-223, 2011.
- [Levine and Koltun, 2013] Sergey Levine and Vladlen Koltun. Guided policy search. In International Confer- ence on Machine Learning, pages 1-9, 2013.
- [Liu et al., 2014] Chunming Liu, Xin Xu, and Dewen Hu. Multiobjective reinforcement learning: A comprehensive overview. IEEE Transactions on Systems, Man, and Cy- bernetics: Systems, 45(3):385-398, 2014.
- [Liu et al., 2017] Yang Liu, Prajit Ramachandran, Qiang Liu, and Jian Peng. Stein variational policy gradient. arXiv preprint arXiv:1704.02399, 2017.
- [Masood and Doshi-Velez, 2019] Muhammad A Masood and Finale Doshi-Velez. Diversity-inducing policy gra- dient: Using maximum mean discrepancy to find a set of diverse policies. arXiv preprint arXiv:1906.00088, 2019.
- [Schulman et al., 2017] John Schulman, Filip Wolski, Pra- fulla Dhariwal, Alec Radford, and Oleg Klimov. Prox- imal policy optimization algorithms. arXiv preprint arXiv:1707.06347, 2017.
- [Smith et al., 2018] Matthew Smith, Herke Hoof, and Joelle Pineau. An inference-based policy gradient method for learning options. In International Conference on Machine Learning, pages 4710-4719, 2018.
- [Sohrabi et al., 2016] Shirin Sohrabi, Anton V Riabov, Octa- vian Udrea, and Oktie Hassanzadeh. Finding diverse high- quality plans for hypothesis generation. In ECAI, pages 1581-1582, 2016.
- [Sriperumbudur et al., 2010] Bharath K Sriperumbudur, Kenji Fukumizu, Arthur Gretton, Bernhard Schölkopf, and Gert RG Lanckriet. Non-parametric estimation of integral probability metrics. In Information Theory Proceedings (ISIT), 2010 IEEE International Symposium on, pages 1428-1432. IEEE, 2010.
- [Srivastava et al., 2007] Biplav Srivastava, Tuan Anh Nguyen, Alfonso Gerevini, Subbarao Kambhampati, Minh Binh Do, and Ivan Serina. Domain independent approaches for finding diverse plans. In IJCAI, pages 2016-2022, 2007. IJCAI
- [Sutton et al., 2000] Richard S Sutton, David A McAllester, Satinder P Singh, and Yishay Mansour. Policy gradient methods for reinforcement learning with function approxi- mation. In Advances in neural information processing sys- tems, pages 1057-1063, 2000.
- [Thomas, 2015] Philip S Thomas. Safe reinforcement learn- ing. PhD thesis, University of Massachusetts Libraries, 2015.
- [Toussaint and Lopes, 2017] Marc Toussaint and Manuel Lopes. Multi-bound tree search for logic-geometric pro- gramming in cooperative manipulation domains. In (ICRA 2017), 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Standard reinforcement learning methods find one way to solve a task, even though there may exist multiple nearoptimal policies that are distinct in some meaningful way. Identifying this collection of near-optimal policies can allow a domain expert to efficiently explore the space of reasonable solutions. For example, knowing that there exist comparablyperforming policies that trade between several small doses of a drug or a single large dose may enable a clinician to identify what might work best for a patient (e.g., based on whether the patient will remember to take all the small doses).
Unfortunately, existing approaches to find a set of diverse policies involve notions of diversity that are not aligned with the kind of efficient exploration-amongst-reasonable-options setting described above. [Liu et al., 2017] characterize the uncertainty over policies via computing a posterior over policy parameters, but differences in policy parameters may not result in qualitatively different behavior (especially in overparameterized architectures). [Haarnoja et al., 2017] encourage diversity via encouraging high entropy distributions over actions (given states), which may result in sub-optimal behavior. [Fard and Pineau, 2011] seek a single non-deterministic policy that may make multiple decisions at any state, which may be overly restrictive if action choices across states must be correlated to achieve near-optimal performance.
∗Contact Author
We argue that differences in trajectories (state visits and action choices) better capture the kinds of distinct behavior we are seeking. For example, does one prefer a policy that achieves wellness through a surgery, or via prolonged therapy? More formally, stochasticity in the environment dynamics and the policy will induce a distribution over trajectories. We use the maximum mean discrepancy (MMD) metric to compare these distributions over trajectories under different policies. As noted in [Sriperumbudur et al., 2010], the MMD metric has a closed form solution (unlike the Wasserstein and Dudley metrics) and exhibits better convergence behavior than φ-divergences such as Kullback-Leibler (KL).
In this work, we first formalize notions of policy diversity via the MMD over their induced trajectories. We show that unbiased gradient estimates of the MMD term can be obtained without knowledge of transition dynamics of the environment, and describe how it can be applied to any policy gradient objective. Across both benchmark domains and a healthcare task, our approach discovers diverse collections of well-performing policies.
2 Background
Reinforcement Learning
We consider Markov decision processes (MDPs) defined by a continuous state space S, a (discrete or continuous) action space A, state transition probabilities pT (s, a, s′ ), reward function r(s, a), as well as a discount factor γ. A policy π(s, a) indicates the probability of action a in state s; together with the transition probability pT (s, a, s′ ), it induces a distribution pπ(τ) over trajectories τ = s0, a0, . . . aT-1, sT . Traditionally, the task is to find a policy that maximizes the long-term expected discounted sum of rewards (return) g(τ):
In this work, we shall seek multiple near-optimal policies.
Policy Gradient Methods
Policy gradient methods use gradients to iteratively optimize a policy πθ(s, a) that is parameterized by θ. The standard objective JPG(θ) is the return g(τ). An unbiased estimate of the gradient of the objective can be obtained by Monte Carlo rollouts generated by the policy πθ using the likelihood ratio trick. For a single rollout {st, at, rt}, the gradient can be estimated as
where gt = ∑Tt′=t γ t′-t rt′ is the return over the rewards received from time t onwards. [Schulman et al., 2017] introduced Proximal Policy Optimization (PPO); a popular variant that achieves state-of-the-art performance on many benchmark domains and uses trust region updates that are compatible with stochastic gradient descent.
In this work we augment the PPO objective for the policy network with an MMD-based term which encourages policies that lead to different state visitation and/or action choice distribution than previously-identified policies. An iterative use of this diversity inducing variant of policy gradient methods allows us to sequentially obtain distinct policies.
Off-Policy Evaluation
The off-policy RL framework applies when trajectories are collected from a behavior policy that is distinct from the policy being trained, e.g., using observations from clinician behavior to optimize an agent's behavior. In the batch setting, there are model-based and importance sampling approaches to estimating the value of a policy. Model-based approaches learn a dynamics model for the transitions and use those to simulate outcomes of a policy in order to estimate its value. Importance sampling approaches appropriately re-weight existing batch data to estimate the value for a different policy.
Maximum Mean Discrepancy
We use the MMD metric to measure the difference between two trajectory distributions. The MMD is an integral probability metric [Gretton et al., 2007] that measures the difference between two distributions p, q using test functions h from a function space H. It is given by:
Computing the MMD is tractable when the function space H is a unit-ball in a reproducing kernel hilbert space (RKHS) defined by a kernel k(·, ·) and is given by:
MMD2 (p, q, H) = E[k(x, x′ )] - 2E[k(x, y)] + E[k(y, y′ )] where x, x′ i.i.d. ∼ p and y, y′ i.i.d. ∼ q. The expectation terms in the analytical expression for the MMD can be approximated using samples. In Section 3, we will show that computing the derivative of the MMD metric between trajectories with respect to the policy parameters θ is tractable.
3 Diversity-Inducing Policy Gradient (DIPG)
Our algorithm constructs a set of diverse policies for an MDP by iteratively finding policies that are diverse relative to an existing set of policies. First, we formulate a diversity inducing objective function that regularizes any policy gradient objective. Then, we show that optimizing this objective is tractable using the familiar log-derivative trick. Next, we explain how to iteratively apply this diversity-inducing policy gradient objective in conjunction with an existing algorithm to find a set of distinct policies that solve an MDP. Finally, we introduce an extension to the proposed framework for off-policy batch reinforcement learning.
3.1 DIPGObjective
We propose adding a regularization term to encourage learning a policy πθ(s, a) that induces a distribution over trajectories pθ(τ) that is distinct from a specified set of distributions over trajectories Q = {qm(τ)}Mm=1 . (Below, these distributions qm(τ) will come from previously-identified policies.) Our diversity measure DMMD(pθ(τ ), Q) is the squared MMD between the distribution of trajectories under the current policy πθ and the distribution q∗(τ) in Qmost similar to it.
We define a kernel over a pair of trajectories (τ, τ ′ ) using a kernel K (such as Gaussian kernel) defined over some function (g) of a vectorized representation of N steps of trajectories (x = φN(τ), x′ = φN(τ ′ )). For trajectories that are not of the same length, we pick N to be the number of steps corresponding to the shorter of the two trajectories.
The function φN is simply a way to stack the states and actions from the first N steps of a trajectory into a single vector. The function g gives the flexibility to adjust the focus of the diversity measure for different aspects such as state visits, action choices, or both.
The MMD-based diversity-inducing objective function is given by JMMD(θ):
Where JPG(θ) is the objective function of a policy gradient algorithm of the user's choice (e.g. for vanilla policy gradient it would be the expected return) and the second term is proportional to the diversity measure between a policy distribution and the set of specified distributions Q. The parameter α decides the relative importance of optimality and diversity of the new policy πθ(s, a).
To optimize the MMD-based diversity-inducing objective, we need to specify how gradients of the diversity term can be computed with respect to the policy parameters θ.
3.2 Optimization via Gradient Ascent
To use gradient ascent on JMMD(θ), what remains to specify is the gradient with respect to θ of the diversity inducing term DMMD. Let q∗(τ) be the distribution in Q that minimizes the MMD between the state trajectory distribution of the policy πθ and qm ∈ Q. Then, the gradient with respect to the policy
Algorithm 1 MMD-based Diversity-Inducing Policy
Input: Known policies Pknown, MDP {S, A, ps, r}, policy gradient objective JPG, learning rate η, diversity parameter
αInitialize policy parameters θ
Q ← Sampled trajectories from policies in Pknown
repeat
Generate an episode s0, a0, r1, . . . , sT-1, aT-1, rT , following policy πθ
1: Estimate ∇θJPG and ∇θDMMD(pθ(τ ), Q)
2: Update policy parameters via gradient ascent
θ ← θ + η(∇θJPG + α∇θDMMD(pθ(τ ), Q))
end for
until convergence
Output: policy pθ
Algorithm 2 DIPG
Input: Number of policies N, MDP {S,A, ps, r}, policy gradient objective JPG, learning rate η, diversity parameters α1...N
Collection of known policies Pknown = ∅
for n = 1 to N do
1: Find a policy pn that is distinct from the current set of known policies Pknown:
pn ← Algorithm 1(Pknown, MDP, JPG, η, αn)
2: Add pn to the set of known policies Pknown:
Pknown ← Pknown ∪ pn
end for
Output: Set of policies Pknown
parameters θ of the diversity term is given by
where τp, τ ′p i.i.d. ∼ pθ(τ) and τq, τ ′q i.i.d. ∼ q∗(τ). The last term only involves the distribution q∗(τ) ∈ Q that has no dependence on θ. The gradient term can be estimated by linear combinations of the ∇θ log pθ(τ) involving the kernel between sample trajectories from the policy πθ and with a set of specified trajectories from Q. It is well-known [Sutton et al., 2000] that the gradient of the score function of the trajectory distribution ∇θ log pθ(τp) does not require the dynamics model and can be expressed in terms of the score function of the policy network (∇θ log pθ(τ ) = ∑Ht=0 ∇θ log πθ(at|st)).
We now have all the machinery in place to augment any existing policy gradient method with a diversity inducing term. Next, we will specify the basic algorithm for finding a policy that is diverse with respect to some specified set of trajectory distributions and then introduce an algorithm that leverages this to find a set of diverse policies.
3.3 FindingMultiple Diverse Policies
Our goal is to find a collection of policies that perform optimally or near-optimally and are diverse in terms of the distributions over trajectories that they induce. In Algorithm 1, we state how the diversity inducing term DMMD is used in order to learn a single policy that is distinct with respect to a specified set of distributions over trajectories Q. In Algorithm 2, we iteratively apply Algorithm 1 to find the desired set of N distinct policies (agents): The first policy is learned without any diversity term because there is no set of known policies to begin with. Subsequent policies are learned by initializing random policy parameters and training with the augmented objective function that encourages diversity with respect to previously discovered policies. The strength of the diversity parameter α can be varied (e.g., to seek diverse policies more aggressively as more policies are discovered).
3.4 DIPGExtension: Batch Off-Policy Setting
Batch reinforcement learning [Lange et al., 2012] aims to learn policies from a fixed set of previously-collected trajectories. It is common in domains such as medicine, dialogue management, and industrial plant control where logged data are plentiful but exploration is expensive or infeasible.
We now extend our DIPG framework to this batch setting. In the on-policy case, we defined the DIPG diversity term as a kernel over the distribution of trajectories induced by different policies. However, in the batch case, trajectories cannot be simulated from the learned policies. Thus, we instead define the diversity as a kernel over the likelihoods of specific (observed) trajectories in the batch with respect to a policy.
Specifically, let T = {τi}Ii=1 be a batch of I trajectories. We use p(T |π) ∈ RI to indicate a vector where the ith coordinate equals the probability of the ith trajectory under the policy π i.e. pi(T |π) = p(τi|π). Now, the diversity term can be defined in an analogous fashion to the on-policy case where we compare our policy being optimized πθ to the previous policies {q1, ..., qM}:
We also require a measure of quality for the policies. [Levine and Koltun, 2013] note that gradient-based optimization of importance sampling estimates is difficult with complex policies and long rollouts. We suggest a surrogate that is equal to the sum of the likelihoods of each trajectory in the batch J T Surrogate (θ) = ∑Ii=1 p(τi|θ). This surrogate is more robust to optimize and encourages 'safe' behavior from the agent, a desirable feature in the healthcare setting.
While we optimize with respect to this surrogate, in our results, we still report on the value of the policy with respect to a standard importance sampling-based estimator (CWPDIS, from [Thomas, 2015]).
4 Experimental Setup
We augment Proximal Policy Optimization (PPO) [Schulman et al., 2017] with the diversity inducing term (referred to as DIPG-PPO). We set the maximum number of steps taken by all baseline algorithms to be 1 million and set the maximum number of steps for each of the N policies in DIPG-PPO to 0.2 million. Since we choose N < 5 for all our testing environments, the total number of steps to learn all N policies is necessarily less than 1 million. In these experiments we set αn = 1.0 across all environments and iterations n1 . For the MMD kernel, we choose the Gaussian kernel with bandwidth set to 1. Each algorithm is run 3 times to assess variability in performance, except for RR-PPO which does not have any inherent diversity component, so we run it with 10 random restarts to help it make up for this disadvantage.
4.1 Environments
Synthetic Environments
We illustrate qualitative aspects of our approach on 2dimensional navigational tasks.
Multi-goal environment of [Haarnoja et al., 2017] is solved by reaching one of four symmetrically placed goals in a continuous 2-D world. An ideal collection of diverse policies would include policies that solve the task via reaching different goals in different parts of the state space.
Asymmetric goals environment has one goal that is closer to the starting point and easier to reach than the second. While most agents find the region closest to the initial position, a distinct collection of policies solves the environment by also reaching the goal further away. We use this environment to explore the case where there exist a slightly sub-optimal solution that is clearly distinct from the optimal one.
Benchmark Environments
We evaluated the performance of our algorithm on standard benchmark environments: Reacher, Ant, Humanoid and Humanoid Flag Run [Schulman et al., 2017] 2 .
Clinical batch
Hypotension batch data is built from a cohort of patients from MIMIC critical care data set [Johnson et al., 2017]. In this work, we aim to learn multiple treatment strategies using offpolicy methods. Cohort and MDP formulation details are in [Masood and Doshi-Velez, 2019].
4.2 Algorithm and Baselines
We compare our approach [DIPG-PPO] to the following other algorithms that can encourage diverse behavior:
Random Restarts [RR-PPO]: Independent runs of PPO without the diversity inducing regularization. Due to variability in initializations and experience, we obtain a collection of policies that are not exactly the same.
Stein Variational Policy Gradient [SVPG]: [Liu et al., 2017] use functional gradient descent to compute a pointbased posterior distribution over the policy parameter space.
1 The performance of our algorithm may improve when this parameter is tuned based on the environment or which of the N policies is being learned)
2 https://github.com/benelot/pybullet-gym
We report results for a collection of 8 agents, and for comparison also on a single agent's performance.
Deep Energy-Based Policy [Soft-Q]: [Haarnoja et al., 2017] present a way to train a single stochastic policy that is encouraged to have high entropy on the probability of the action (given state). The higher entropy encourages the agent to choose actions that are diverse. We try Soft-Q learning with the default entropy regularization parameter of 1 as well as variants with 0.5 and 0. We choose the smaller (and zero) values of the regularization parameter to see the effect of the tradeoff between diversity and quality in this algorithm.
5 Results
We evaluate the performance based on both quality and similarity scores (figure 2). The quality is evaluated by averaging the returns coming from rollouts of the final stochastic policy (or collection of policies) and the similarity score comes from the kernel used to measure similarity between trajectories (smaller kernel values indicate higher diversity). Additional results can be found in [Masood and Doshi-Velez, 2019].
DIPG method does not sacrifice quality. Figure 2 shows that DIPG-PPO and RR-PPO generally provide the highest quality policies. The baseline algorithms designed for finding a diverse set of policies (SVPG and Soft-Q) have significantly worse quality performance (SVPG in particular) and find policies that lead to high variability in the rewards even though each individual policy in SVPG and Soft-Q is trained for longer (1 million steps) as compared to RR-PPO and DIPG-PPO (0.2 million steps). Such variability in the distribution of returns suggests that the diversity in SVPG and Soft-Q comes not only at the cost of quality, but importantly (especially in the clinical setting) at the cost of consistency of quality returns. It must be emphasized that diversity in policies is only meaningful if they are beyond some threshold of quality and are able to 'solve' a domain consistently.
DIPG method finds meaningfully diverse policies with fewer runs. The diversity information in figure 2 shows that SVPG and Soft-Q algorithms give policies that are quite diverse (comparison of pairwise trajectories shows negligible overlap). Since these collections of stochastic policies fail to provide high rewards in the environments, the diversity in the trajectory distribution that is induced is of little value. The DIPG-PPO (N = 2 and N = 4) and RR-PPO collections (N = 10) are collections of policies that essentially 'solve' these environments and discover the set of ways these environments were designed to be solved (see figure 1). In comparison to RR-PPO, DIPG-PPO requires many fewer agents to discover an appropriate collection of diverse agents.
Clinical Example: A collection of DIPG policies reveals different choices of treatment in the ICU. We learned four policies through our off-policy extension of DIPG using real data from the ICU and evaluated their performance using the CWPDIS importance sampling estimator [Thomas, 2015]. Not only were all four learned policies of slightly higher quality (∼ 9.33 on held out test data) than the clinician behavior policy (9.29), they are also distinct.
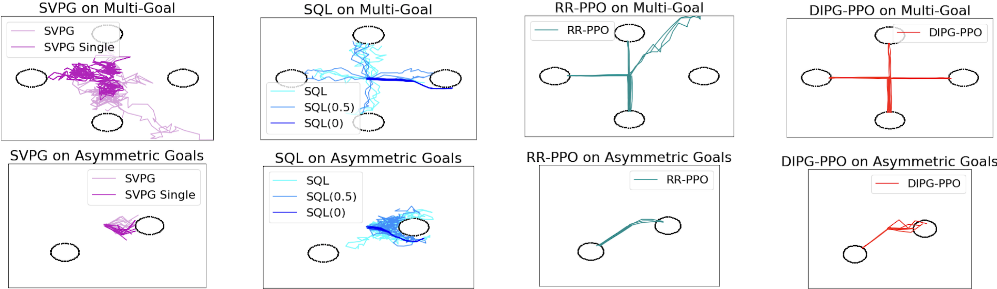
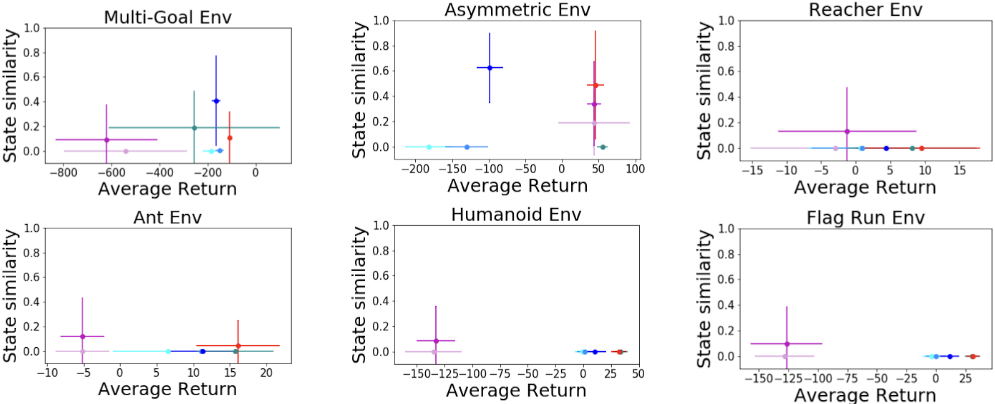
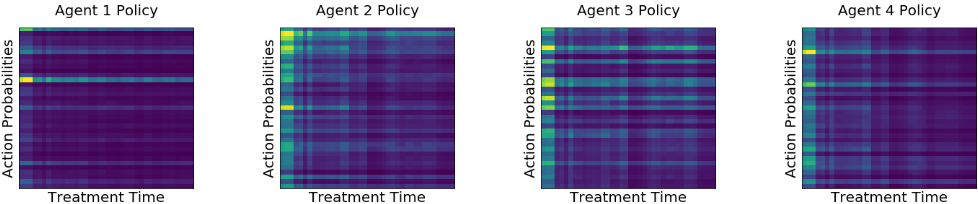
Figure 3 plots the probabilities of each action for each policy for a single patient over their ICU stay duration. The discrete actions correspond to different combinations of vasopressor and IV fluid dosages. Agent 1 has a neardeterministic policy with an emphasis on a single treatment that is a combination of a low vasopressor dosage and a medium fluid dosage. Agents 2 and 3 are more aggressive than other agents, giving weights to medium and high vasopressor dosages as well. All agents emphasize taking action early rather than later in the duration (by which time hopefully the patient is in a stable state). Importantly, all of these policies cannot be differentiated by value alone; thus they form a collection to be presented to clinicians for further review of potentially valuable options.
6 RelatedWork
Whereas we compute diversity (using MMD) between complete trajectories (including state and action), many related works, quantify diversity only via differences in the action space. E.g., the KL diversity term in [Hong et al., 2018] is between the actions. Similarly, in [Gangwani et al., 2018], the kernel incorporates trajectory information but the definition of the target density is still according to the action-based maximum entropy RL framework.
[Smith et al., 2018] learn a policy over options and can train multiple options (in an off-policy manner) using a rollout from a single option. The distinct options can give rise to behavior that is diverse, however there is no explicit diversity component in the objective and it is unclear how to summarize the kinds of distinct trajectories that are possible. Unlike [Eysenbach et al., 2018], our proposed method does not impose a latent structure defining 'skills'. [Cohen et al., 2019] uses diversity for exploration in order to get closer to an optimal policy whereas our work solves multi-goal domains and identifies diverse policies of interest to experts (e.g. in clinical setting).
In the graph-based planning literature (limited to the discrete setting), there is also an interest in diversity; [Srivastava et al., 2007] seek to do this using domain independent distance measures for evaluating diversity of plans whereas [Sohrabi et al., 2016] first generate a large set of high quality plans and then use clustering to identify a diverse set of representative plans that can be used for further analysis. Our motivation for seeking diverse policies in the reinforcement learning setting is aligned most closely with the end goal of [Sohrabi et al., 2016]: presenting a diverse set of representative solutions as a tool for hypothesis generation and to discover specific directions of interest for further inquiry.
There exists a literature on Bayesian methods for reinforcement learning [Ghavamzadeh et al., 2015]. Also related are evolutionary [Lehman and Stanley, 2011] and multi-objective [Liu et al., 2014] reinforcement learning approaches. However, these approaches do not systematically attempt to identify a small set of distinct policies.
7 Discussion
Our DIPG algorithm successfully finds multiple goals in an optimal or near-optimal manner whereas baseline approaches are either unable to reach multiple goals or do so suboptimally. The poor task performance of SVPG could be due to the difficulties of performing functional gradient descent over a high-dimensional parameter space. However, even if those difficulties were to be overcome, the search for diversity in the space of neural network parameters does not correspond directly to any meaningful notion of diversity in the trajectories. The Soft-Q algorithm exhibits some meaningful diversity in the policies it finds (e.g. reaching different goals in the multi-goal environment), however, there is unnecessary stochasticity in the actions, leading to sub-optimal policies. Unlike the baselines, random restarts do result in near-optimal in-task performance. However, the diversity of the policies is at the mercy of the basins of attraction of each local optima (based on the initialization and subsequent experience). In contrast, DIPG-PPO successfully identifies a collection of distinct policies consistently and efficiently (that is, with few runs).
While we have focused on certain notions of distinctness here (state visits, action counts), our approach extends easily to other measures of distinctness as measured by alternative kernels (see [Chen et al., 2018] and [Gretton et al., 2012] for novel kernels and discussion). Whereas the full trajectory may be needed for training the RL agent, we can capture (MMD-based) distinctness more generally using an arbitrary function of the trajectory. For example, we could group patients into clinically meaningful clusters which can be used to define a kernel for measuring diversity. There are also opportunities for incorporating more efficient search algorithms than gradient descent (e.g. [Toussaint and Lopes, 2017]).
While we have focused on the task of returning policies as possible options to a human user, another use-case could be for situations in which we have a cheap, low fidelity simulator and a more expensive, high-fidelity simulator. In this case, the distinct trajectories from the low-fidelity simulator could be used as seeds for deep exploration in the more expensive simulator. Diverse policies can help manage the explorationexploitation trade-off.
8 Conclusion
We presented an approach for identifying a collection of nearoptimal policies with significantly different distributions of trajectories. Our MMD-based regularizer can be applied to the distribution of any statistic of the trajectories-state visits, action counts, state-action combinations-and can also be easily incorporated into any policy-gradient method. We applied these to several standard benchmarks and developed an off-policy extension to identify meaningfully different treatment options from observational clinical data. The ability to find these diverse policies may be useful when the agent does not have complete information about the task, and for presenting a set of potentially reasonable options to a downstream human or system, who can use that information to efficiently choose amongst reasonable options.
Acknowledgements
We acknowledge support from AFOSR FA 9550-17-1-0155.
@inproceedings{ijcai2019p821,
  title     = {Diversity-Inducing Policy Gradient: Using Maximum Mean Discrepancy to Find a Set of Diverse Policies},
  author    = {Masood, Muhammad and Doshi-Velez, Finale},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {5923--5929},
  year      = {2019},
  month     = {8},
  note      = {AI for Improving Human Well-being},
  doi       = {10.24963/ijcai.2019/821},
  url       = {https://doi.org/10.24963/ijcai.2019/821},
}
TY - CPAPER TI - Diversity-Inducing Policy Gradient: Using Maximum Mean Discrepancy to Find a Set of Diverse Policies AU - Masood, Muhammad AU - Doshi-Velez, Finale T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 5923 EP - 5929 DO - 10.24963/ijcai.2019/821 UR - https://doi.org/10.24963/ijcai.2019/821 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





