
Motion Invariance in Visual Environments
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 2009-2015.
https://doi.org/10.24963/ijcai.2019/278
Keywords
- Machine Learning: Unsupervised Learning
- Computer Vision: Computer Vision
- Machine Learning: Learning Theory
- Computer Vision: Motion and Tracking
Abstract
The puzzle of computer vision might find new challenging solutions when we realize that most successful methods are working at image level, which is remarkably more difficult than processing directly visual streams, just as it happens in nature. In this paper, we claim that the processing of a stream of frames naturally leads to formulate the motion invariance principle, which enables the construction of a new theory of visual learning based on convolutional features. The theory addresses a number of intriguing questions that arise in natural vision, and offers a well-posed computational scheme for the discovery of convolutional filters over the retina. They are driven by the Euler- Lagrange differential equations derived from the principle of least cognitive action, that parallels the laws of mechanics. Unlike traditional convolutional networks, which need massive supervision, the proposed theory offers a truly new scenario in which feature learning takes place by unsupervised processing of video signals. An experimental report of the theory is presented where we show that features extracted under motion invariance yield an improvement that can be assessed by measuring information-based indexes.
- [Anderson and Rosenfeld, 1988] J.A. Anderson and E. Rosenfeld, editors. Neurocomputing: Foundations of Research. MIT Press, Cambridge, 1988.
- [Baker et al., 2011] Simon Baker, Daniel Scharstein, J. P. Lewis, Stefan Roth, Michael J. Black, and Richard Szeliski. A database and evaluation methodology for opti- cal flow. Int. J. Comput. Vision, 92(1):1-31, March 2011.
- [Betti and Gori, 2016] Alessandro Betti and Marco Gori. The principle of least cognitive action. Theor. Comput. Sci., 633:83-99, 2016.
- [Deng et al., 2009] J. Deng, W. Dong, R. Socher, L.-J. Li, K. Li, and L. Fei-Fei. ImageNet: A Large-Scale Hierar- chical Image Database. In CVPR09, pages 248-255, 2009.
- [Goodale and Milner, 1992] Melvyn A. Goodale and A. David. Milner. Separate visual pathways for perception and action. Trends in Neurosciences, 15(1):20-25, 1992.
- [Gori et al., 2012] Marco Gori, Stefano Melacci, Marco Lippi, and Marco Maggini. Information theoretic learn- ing for pixel-based visual agents. In European Conference on Computer Vision, pages 864-875. Springer, 2012.
- [Gori et al., 2016] Marco Gori, Marco Lippi, Marco Mag- gini, and Stefano Melacci. Semantic video labeling by developmental visual agents. Computer Vision and Image Understanding, 146:9-26, 2016.
- [Horn and Schunck, 1981] B. K.P. Horn and B.G. Schunck. Determining optical flow. Artificial Intelligence, 17(1- 3):185-203, 1981.
- [Huang et al., 2007] Fu Jie Huang, Y-Lan Boureau, Yann LeCun, et al. Unsupervised learning of invariant feature hi- erarchies with applications to object recognition. In Com- puter Vision and Pattern Recognition, 2007. CVPR'07. IEEE Conference on, pages 1-8. IEEE, 2007.
- [Kavukcuoglu et al., 2010] Koray Kavukcuoglu, Pierre Ser- manet, Y lan Boureau, Karol Gregor, Michael Mathieu, and Yann L. Cun. Learning convolutional feature hierar- chies for visual recognition. In J. D. Lafferty, C. K. I. Williams, J. Shawe-Taylor, R. S. Zemel, and A. Culotta, editors, Advances in Neural Information Processing Sys- tems 23, pages 1090-1098.
- Curran Associates, Inc., 2010.
- [Li et al., 2016] Yin Li, Manohar Paluri, James M Rehg, and Piotr Dollár. Unsupervised learning of edges. In Proceed- ings of the IEEE Conference on Computer Vision and Pat- tern Recognition, pages 1619-1627, 2016.
- [Lowe, 2004] D. Lowe. Distinctive image features from scale-invariant keypoints. International Journal of Com- puter Vision, 60(2):91-110, 2004.
- [Marr, 1982] D. Marr. Vision. Freeman, San Francisco, 1982. Partially reprinted in [Anderson and Rosenfeld, 1988].
- [Marszałek et al., 2009] Marcin Marszałek, Ivan Laptev, and Cordelia Schmid. Actions in context. In IEEE Conference on Computer Vision & Pattern Recognition, pages 2929- 2936, 2009.
- [Melacci and Gori, 2012] Stefano Melacci and Marco Gori. Unsupervised learning by minimal entropy encoding. IEEE Trans. Neural Netw. Learning Syst., 23(12):1849- 1861, 2012.
- [Pathak et al., 2017] Deepak Pathak, Ross B Girshick, Piotr Dollár, Trevor Darrell, and Bharath Hariharan. Learning features by watching objects move. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recog- nition, pages 2701-2710, 2017.
- [Poggio and Anselmi, 2016] Tomaso A. Poggio and Fabio Anselmi. Visual Cortex and Deep Networks: Learning In- variant Representations. The MIT Press, 1st edition, 2016.
- [Sun et al., 2014] Lin Sun, Kui Jia, Tsung-Han Chan, Yuqiang Fang, Gang Wang, and Shuicheng Yan. Dl-sfa: deeply-learned slow feature analysis for action recogni- tion. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 2625-2632, 2014.
- [Wang and Gupta, 2015] Xiaolong Wang and Abhinav Gupta. Unsupervised learning of visual representations using videos. In Proceedings of the IEEE International Conference on Computer Vision, pages 2794-2802, 2015.
- [Wiskott and Sejnowski, 2002] Laurenz Wiskott and Ter- rence J Sejnowski. Slow feature analysis: Unsupervised learning of invariances. Neural computation, 14(4):715- 770, 2002.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
While the emphasis on a general theory of vision was already the main objective at the dawn of the discipline [Marr, 1982], computer vision has evolved without a systematic exploration of foundations in the framework of machine learning. In particular, in most cases, computer vision is regarded just as an application of machine learning. When the target is moved to unrestricted visual environments and the emphasis is shifted from huge labelled databases to a human-like protocol of interaction, we need to go beyond the current peaceful interlude that we are experimenting in vision and machine learning. So far, the semantic labeling of pixels of a given video stream has been mostly carried out at frame level. This seems to be the natural outcome of well-established pattern recognition methods working on images, which have given rise to nowadays emphasis on collecting big labelled image databases (e.g., [Deng et al., 2009]) with the purpose of devising and testing sophisticated machine learning algorithms.
A crucial problem that has been recognized by Poggio and Anselmi [Poggio and Anselmi, 2016] is the need to incorporate visual invariances into deep nets that go beyond simple translation invariance that is currently characterizing convolutional networks. They propose an elegant mathematical framework on visual invariance and enlighten some intriguing neurobiological connections. Overall, the ambition of extracting distinctive features from vision poses a challenging task. While we are typically concerned with feature extraction methods that are independent of classic geometric transformation, it looks like we are still missing the fantastic human skill of capturing distinctive features to recognize "ironed and rumpled shirts", for example. There is no apparent difficulty to recognize shirts by keeping the recognition coherence in case we roll up the sleeves, or we simply curl them up into a ball for the laundry basket. Of course, there are neither rigid transformations, like translations and rotation, nor scale maps, that transforms an ironed shirt into the same shirt thrown into the laundry basket. In this paper, we claim that motion invariance can in fact capture all we need. Translation and scale invariance, that have been the subject of many studies [Lowe, 2004; Gori et al., 2016], are in fact examples of invariances that can be fully gained whenever we develop the ability to detect features that are invariant under motion. For instance, the moving of the finger experimented by infants leads them to enforce a natural invariance: The finger will become bigger and bigger as it approaches their face, but it is still their inch, which requires to impose a consistent decision. Clearly, translation, rotation, and complex deformation invariances derive from motion invariance. Humans always experiment motion in their life, so as the gained visual invariances naturally arise from motion invariance. Animals with foveal eyes also move quickly the focus of attention when looking at fixed objects, which means that they continually experiment motion. Hence, also in case of fixed images, conjugate, vergence, saccadic, smooth pursuit, and vestibulo-ocular movements lead to acquire visual information from relative motion. We claim that the production of such a continuous visual stream naturally drives feature extraction, since the corresponding convolutional features are expected not to change during motion. The enforcement of this consistency condition creates a mine of visual data during animal life. Of course, we need to compute the optical flow at pixel level so as to enforce the consistency of all the extracted features. Early studies on this problem [Horn and Schunck, 1981], along with recent related improvements (see e.g. [Baker et al., 2011]) suggest to start computing the velocity field by enforcing brightness invariance. As the optical flow is gained, it is used to enforce motion consistency on the visual features. Interestingly, the theory we propose is quite related to the variational approach that is used to determine the optical flow in [Horn and Schunck, 1981], so that the developed features could be also used to reinforce motion estimation. It is worth mentioning that an effective visual system must also develop features that do not follow motion invariance. What we study in this paper is general enough to embrace also the case in which some of the learned features are not subject to motion invariance. These kind of features can be conveniently combined with those that are discussed in this paper with the purpose of carrying out high level visual tasks.
The visual features that we propose in this paper are derived in the framework of the principle of cognitive action [Betti and Gori, 2016], which gives rise to a timevariant differential equation, where the Lagrangian coordinates correspond with the values of the convolutional filters. The learning process can be interpreted in the framework of the minimization of the cognitive action that offers a selfconsistent framework. There are other works that study the unsupervised learning of visual features for temporally varying signals, such as Slow Feature Analysis (SFA) [Wiskott and Sejnowski, 2002; Sun et al., 2014]. SFA includes motion estimation as an example of application of SFA itself, while here we focus on exploiting motion to learn pixel-level features. In the last decade, a number of approaches have been proposed to develop features in an unsupervised manner, mostly using collections of images [Huang et al., 2007; Kavukcuoglu et al., 2010]. Only in the last few years we find some works that consider unsupervised learning from video data, jointly with motion [Wang and Gupta, 2015; Li et al., 2016; Pathak et al., 2017]. These works usually learn image-level representations, and, to the best of our knowledge, none of them aims at developing a learning theory for the unsupervised development of visual features that is specifically rooted around the notion of motion, that is the goal of this paper.
This paper is organized as follows. Section 2 introduces the principle of least cognitive action and the basic elements of the proposed architecture. Section 3 focusses on the discrete case, and defines the differential equations that we integrate to develop features while processing the video stream. Section 4 includes a collection of experiments aimed at showing the behaviour of the system under different configurations, in terms of information-based indices. Finally, Section 5 concludes the paper. Supplementary Material can be found at http://sailab.diism.unisi.it/motion-invariance/.
2 The Principle of Least Cognitive Action
We consider the mechanisms that give rise to the construction of local features for any pixel x ∈ X of the retina, at any time t ∈ [0, T]. These features, along with the video itself, therefore can be regarded as visual fields, that are defined on the domain D = X × [0, T ]. A set of symbols are extracted at every layer of a deep architecture, so as each pixel-along with its context-turns out to be represented by the list of symbols extracted at each layer.
In what follows, points on the retina will be represented with two dimensional vectors x = (x1, x2). The temporal coordinate is usually denoted by t, and, therefore, the video signal on the pair (x, t) is C(x, t). This color field can be thought of as a field that is characterized by m components for each single pixel (m = 3 for RGB) . We are concerned with the problem of extracting visual features that, unlike the components of the video, express the information associated with the pair (x, t) and with the neighborhood of pixel x. A possible way of constructing this kind of features is to define
Here we assume that n symbols (indexed by i) are generated from the m components of the video. Notice that the kernel ϕ(x, y, t) is responsible of expressing the spatial dependencies. It is worth mentioning that whenever ϕ(x, y, t) ⇝ ϕ(x-y, t) the above definition reduces to an ordinary spatial convolution. The computation of C1 i(x, t) yields a field with n features, and Eq. (1) can be used for carrying out a piping scheme where a new set of features C2 is computed from C1 . Of course, this process can be continued according to a deep computational structure with a homogeneous convolutionalbased computation, which yields the features Cz at the z-th convolutional layer. The theory proposed in this paper focuses on the construction of any of these convolutional layers which are expected to provide higher and higher abstraction as we increase the number of layers. The filters ϕ are what completely determines the features Cz . In this paper we formulate a theory for the discovery of ϕ that is based on three driving principles, that are described below.
Optimization of information-based indices. Beginning from the color field C, we attach a symbol yi ∈ Σ of a discrete vocabulary to pixel (x, t) with probability C1 i(x, t), assuming that ∀x, t : C1 i(x, t) is subject to the probabilistic constraints ∑i C1 i(x, t) = 1 (normalization) and 0 ≤ C1 i(x, t) ≤ 1 (positivity). The quantity C1 i(x, t) can be identified with the conditional probability of the random variable Y associated with the symbols yi subject to a certain value of the random variables X, T and F that models, respectively, the distribution of the position over the retina, of the temporal coordinate and of all the possible configurations of pixel intensities over the frame. The conditional entropy S(Y | X, T, F) is given by S(Y | X, T, F) = - ∫Ω ∑ni=1 dPX,T,F pi log pi where pi is the conditional probability of Y conditioned to the values of X, T and F , dPX,T,F is the joint measure of the variable X, T, F , and Ω is a Borel set in the (X, T, F ) space. We can rewrite the conditional entropy as S(Y | X, T, F) = - ∫D dµ(x, t) ∑ni=1 C1 i(x, t) log C1 i(x, t), where µ(x, t) is a space-time measure. Clearly, we want to keep the conditional entropy as small as possible so as to develop dominating features. At the same time we must ensure that the entropy of variable Y , S(Y ) = - ∑ni=1 Pr(Y = yi) logPr(Y = yi), must be as high as possible, since this ensures the development of all the features associated with the alphabet of symbols. If we use the law of total probability to express Pr(Y = yi) in terms of the conditional probability pi and use the above assumptions we get Pr(Y = yi) = ∫Ω dPX,T,F pi = ∫D dµ(x, t)C1 i(x, t). Then S(Y ) = - ∑ni=1 (∫D dµ(x, t) C1 i(x, t)) · log(∫D dµ(x, t) C1 i(x, t)). To sum up (see the Supplementary Material for further details on the computation of S(Y )), the index
which is somewhat related to the classic Shannon mutual information, must be maximized [Gori et al., 2012; Melacci and Gori, 2012].
Motion invariance. If we focus attention on a pixel x at time t, which moves according to the trajectory x(t) then C1 (x(t), t) = c, being c a constant. This "adiabatic" condition is thus expressed by the condition dC1 /dt = 0, which yields
where v : D → R2 is the velocity field that we assume to be given, and ∂k is the partial derivative with respect to xk. When replacing C1 i as stated by Eq. (1) we get
which holds for any (t, x) ∈ D. Notice that this constraint is linear in the field ϕ. This can be interpreted by stating that learning under motion invariance consists of determining elements of the kernel of the function M(ϕ). Clearly, the learning process is expected to keep the value of M(ϕ) as small as possible.
Parsimony principle. Like any principled formulation of learning, we require the filters to obey the parsimony principle. Amongst the philosophical implications, it also favors the development of a unique solution. Given the filters ϕ, there are two parsimony terms, one P(ϕ), that penalizes abrupt spatial changes, and another one, K(ϕ) that penalizes quick temporal transitions. Ordinary regularization issues suggest to discover functions ϕij such that
is "small", where Px, Pt are spatial and temporal differential operators, and λP , λK are non-negative reals. We assumed an ergodic translation of dµ, that, in this case, only involves the temporal factor h(t).
Overall, the process of learning is regarded as the minimization of the cognitive action
where λM, λP , λK are positive multipliers. While the first and third principles are typically adopted in classic unsupervised learning, motion invariance does characterize the approach followed in this paper. The motion invariance principle can also be limited to a subset of the n features. In other words, our model can also develop visual features that do not obey the motion invariance principle. Basically, the process of learning consists of solving the variational problem ˆ ϕ = arg minϕ A(ϕ) (see the Supplementary Material for futher details). As it will be shown in the following, in our multi-layer implementation the minimization of A(·) takes place at each layer of the architecture, involving the filters of the considered layer only, relying on a piping scheme that is inspired to developmental learning issues.
3 Euler-Lagrange Equations
The field theory of the previous section can be approximated over the discrete (and bounded) retina X♯ , where the video frames are represented. Then, the Euler-Lagrange equations of the cognitive action (3) lead to those differential equations that we can integrate to learn the convolutional filters.
In detail, instead of the fields ϕij(x, t), we consider a bunch of functions of time ϕijx(t), indexed by the point on the retina x other than the filter/feature index i and the input channel index j. Similarly, the color field will be replaced by Ckx(t). In doing so the motion invariance becomes a quadratic form in ϕ and ˙ϕ, while the other relevant terms of the theory (entropy, relative entropy) are trivially functions of ϕ(t) and t.
We assume filters to have a unique and finite size for all the features. As a consequence, for each feature i, we can flatten the filter ϕijx into a vector, and concatenate the n filtervectors into q. We selected a second order term to implement the parsimony principle, h/2(α|¨ q|2 +β| ˙ q|2 + 2γ ¨ q · ˙ q + k|q|2 ), being α, β, γ and k positive constants. If we make the entropy term local in time, and evaluate the first variation of the discretized cognitive action, the differential Euler-Lagrange (EL) equations are (for the sake of simplicity, we skip the derivations, see Supplementary Material for all the details):
where q(4) , q(3) are the fourth and third derivatives of q over time, λC is a positive constant, and we have used the notation ˆ f = hf (so that for example ¨ˆα = ¨hα). In order to define the other terms, we introduce the notation Γx to indicate the area (volume if m > 1) of the input signal centred around x, of the same size of the filters, flattened into a vector. We have R := β +λMM ♮ , and the notation A♮ indicates a block-diagonal matrix whose blocks are A. The matrix M is composed of Mal := ∑x∈X♯ gxΓx(a)Γx(l), and gx is a distribution over the retina. Analogously, we define Nal := ∑x∈X♯ gxr(a)Γx(l), being r := ˙Γx + v · ∆Γx. We have Z := k+B♮ -λCM ♮ +λ1 ˜M+λMO♮ , where ˜M is a squared matrix composed of m×m repetitions of M, λ1 is a positive constant, Bal = babl, and ba = ∑x∈X♯ gxΓx(a). The matrix O is composed of Oal = ∑x∈X♯ gxr(a)r(l). Finally, w(t, q) := ∑x∈X♯ gx( 1n + ξ(q, Γx))′ [ 1n + ξ(q, Γx) < 0], where ξ(q, Γx) returns the n-length vector with the result of the convolutions of the n filters with the input, [·] = 1 if the condition in brackets is true, otherwise it is 0, and it operates element-wise when a vector of conditions is provided.
In deriving equations some conditions arises naturally at t = T (see the Supplementary Material for more details):
An interesting special case of these equations is that obtained with a null signal C ≡ 0. With this assumption and assuming that h(t) = eθt , θ > 0, our equations (4) become
In order to see whether this equation can be stable we need to apply the Routh-Hurvitz criterion. For a fourth order ODE q(4) +aq(3) + b¨ q+c ˙ q+dq = 0 this criterion reduces to check if a > 0, b > 0, 0 < c < ab and 0 < d < (abc - c2 )/a2 that in our case means that
So for example if we choose α = k = 1/2, γ = 2 and θ = β = 1 we obtain a stable equation. This being said it is also crucial to notice that we have control over the important parameter of the theory θ as long as we choose the regularization parameters carefully.
4 Experiments
We implemented a solver for the differential equation of (4) that is based on the Euler method with step size τ. After having reduced the equation to the first order, the variables that were updated at each t are q, ˙ q, ¨ q, and q(3) . The code and data we used to run the following experiments can be downloaded at http://sailab.diism.unisi.it/motion-invariance/, together with the full list of model parameters. We randomly selected two real world video sequences from the Hollywood Dataset HOHA2 [Marszałek et al., 2009], that we will refer to as "skater" and "car", and a clip from the movie "The Matrix" ( c©Warner Bros. Pictures). The frame rate of all the videos is ≈ 25 fps (we set τ = 1/25), each frame was rescaled to 240 × 110 and converted to grayscale. Videos have different lengths, ranging from ≈ 10 to ≈ 40 seconds, and they were repeated in loop until 45, 000 frames were generated, thus covering a significantly longer time span. We randomly initialized q(0), while the derivatives at time t = 0 were set to 0. We used the softmax function to force a probabilistic activation of the features, and computed the optical flow v using an implementation from the OpenCV library. Convolutional filters cover squared areas of the input frame, and we set gx to be the uniform distribution. All the results that we report are averaged over 10 different runs of the algorithms. The video is presented gradually to the agent so as to favour the acquisition of small chunks of information.
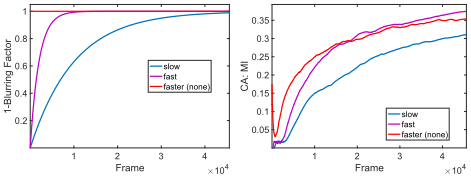
In detail, C(x, t) = φ(t)[gauss(δ(1 - φ(t))) x∗C o (x, t)], where x∗ is the spatial convolution operator, C o (x, t) is the source video signal, gauss(σ2 ) is a Gaussian filter of variance σ2 , and δ > 0 is a customizable scaling factor. We start with φ(0) = 0, and then φ is progressively increased as time passes, φ(t+1) = φ(t)+η(1-φ(t)) (we set η = 0.0005). We refer to the quantity 1-φ as the "blurring factor". In order to be able to (approximately) satisfy the conditions in Eq. (5) we need to keep the derivatives small, so we implement a "reset plan" according to which the video signal undergoes a "reset" whenever the derivatives become too large. Formally, if ‖ ˙ q(t′ )‖2 ≥ ϵ1, or ‖¨ q(t′ )‖2 ≥ ϵ2, or ‖q(3) (t′ )‖2 ≥ ϵ3 then we forced φ(t′ ) to 0 (ϵj = 300 · n, for all j), and then we set to 0 all the derivatives.
Our experiments are designed (i) to evaluate the dynamics of the cognitive action in function of different temporal regularities imposed to the model weights (parsimony), and then (ii) to evaluate the effects of motion, that introduces a spatio-temporal regularization on single and multi-layer architectures. We recall that our learning task is fully unsupervised, so we focus on the transfer of information from each considered video stream to the learned features at different layers, evaluating the impact of the motion-based term. For this reason, we report the Mutual Information (MI) index, together with other measurements on the internal state of systems.
| (a) | ||||
|---|---|---|---|---|
| Config | (Skater) | Blurring | (b) (n = 10, 5 × 5) | |
| ¯ S ¯R | 0.54±0.07 | Slow | 0.35±0.08 | |
| ¯ SR | 0.54±0.08 | Fast | 0.39±0.05 | |
| S ¯R | 0.44±0.11 | None | 0.34±0.08 | |
| SR | 0.45±0.13 | |||
| (c) | ||||
| Video | (n = 5, 5 × 5) | (n = 11, 11 × 11) | ||
| Car | 0.38±0.03 | 0.272 ±0.003 | ||
| Matrix | 0.60±0.03 | 0.45 ±0.02 | ||
| Skater | 0.45±0.13 | 0.35 ±0.05 | ||
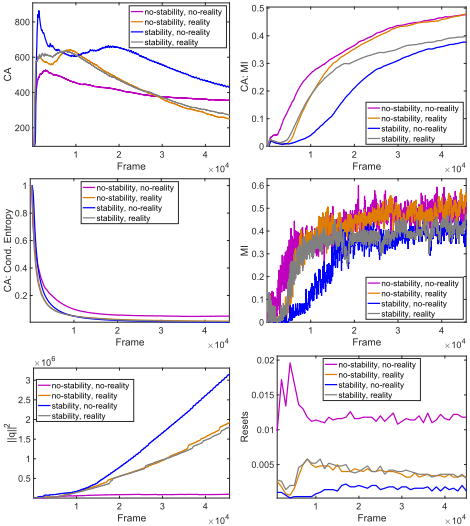
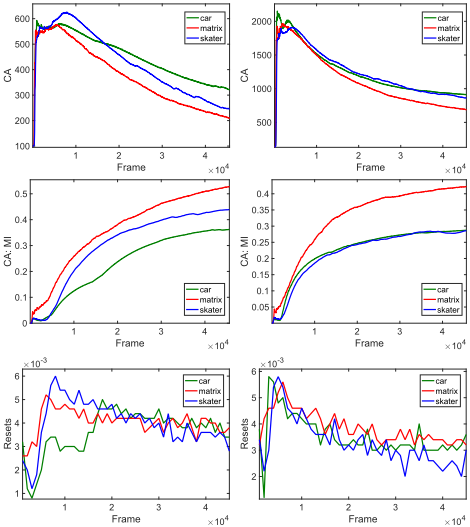
Temporal regularities. When evaluating the temporal regularities, the cognitive action is composed by the entropybased and parsimony terms only, and we experiment four instances of the set of parameters {α, β, γ, k}. Each instance is characterized by the roots of the characteristic polynomial that lead to stable or not-stable configurations, and with only real or also imaginary parts, keeping the roots close to zero, and fulfilling the conditions of Eq. (7) when stability and reality are needed. These configurations are all based on values of k ∈ [10-19 , 10-3 ], while θ = 10-4 . We performed experiments on the "skater" video clip, setting n = 5 features, and chose filters of size 5 × 5. Results are reported in Fig. 1. The plots indicate that there is an initial oscillation that is due to the effects of the blurring factor, that vanish after about 10k frames. The Mutual Information (MI) (I) portion of the cognitive action correctly increases over time , and it is pushed toward larger values in the two extreme cases of "no-stability, reality" and "no-stability, no-reality". The latter shows more evident oscillations in the frame-by-frame MI value, due to the roots with imaginary part. The norm of q changes over time with different speeds, due to the small values of k, while the frequency of reset operations is larger in the "no-stability, no-reality" case, as expected. We evaluated the quality of the developed features by freezing the final q of Fig. 1 and computing the MI index over a single repetition of the whole video clip, reporting the results in Tab. 1 (a). This is the procedure we will follow in the rest of the paper when reporting numerical results in all the tables. We notice that, while in Fig. 1 we compute the MI on a frame-by-frame basis, here we compute it over the whole frames of the video at once, thus in a batch-mode setting. The result confirms that the two extreme configurations "no-stability, reality" and "nostability, no-reality" show better results, on average. These performances are obtained thanks to the effect of the reset mechanism, that allows even such unstable configurations to develop good solutions. When the reset operations are disabled, we easily incurred into numerical errors due to strong oscillations, while for example, the "stability" cases were less affected by this phenomenon. We also compared the dynamics of the system on multiple video clips and using different filter sizes (5×5 and 11×11) and number of features (n = 5 and n = 11) in Fig 2. We selected the "stability, reality" configuration of Fig. 1, that fulfils the conditions of Eq. (7). Changing the video clip does not change the considerations we did so far, while increasing the filter size and number of features can lead to smaller MI index values, mostly due to the need of a better balancing the two entropy terms to cope with the larger number of features. The MI of Tab. 1 (c) confirms this point. Interestingly, the best results are obtained in the longer video clip ("The Matrix") that requires less repetitions of the video, being closer to the real online setting. Figure 3 and Tab. 1 (b) show the results we obtain when using different blurring plans ("skater" clip), that is, different values of η that lead to the blurring factors reported in the first graph of Fig. 3. These results suggest that a gradual introduction of the video signal helps the system to find better solutions, but also that a too-slow process is not beneficial. The cognitive action has a big bump when no-plans are used, while this effect is more controlled and reduced in the case of both the slow and fast plans.
| λM = 0 | 10-8 | 10-6 | 10-4 | 10-2 | 1 | 102 | ||
|---|---|---|---|---|---|---|---|---|
| Skater ℓ | = 1 | .61±.11 | .54± .11 | .52± .07 | .53± .08 | .69± .07 | .53±0 | .01±0 |
| ℓ = 2 | .53± .12 | .62± .15 | .60± .11 | .43± .06 | .48± .06 | .1± .1 | .03± .01 | |
| ℓ = 3 | .56± .17 | .58± .20 | .62± .10 | .18± .16 | .16± .17 | .04± .02 | .03± .02 | |
| ℓ = 1 | .49± .05 | .44± .02 | .46± .04 | .47± .04 | .66± .10 | .60± .02 | .01±0 | |
| Car | ℓ = 2 | .25± .26 | .54± .10 | .65± .08 | .46± .03 | .63± .11 | .18± .32 | .03± .01 |
| ℓ | = 3 | .26± .34 | .45± .22 | .51± .11 | .38± .20 | .24± .20 | .09± .12 | .04± .02 |
| ℓ = 1 | .66± .01 | .66± .02 | .67± .01 | .63± .05 | .59± .03 | .44±0 | .23± .02 | |
| Matrix | ℓ = 2 | .55± .13 | .56± .14 | .43±0 | .45± .04 | .62± .02 | .35± .19 | .13± .08 |
| ℓ = 3 | .64± .03 | .54± .11 | .35± .07 | .40± .01 | .21± .07 | .06± .03 | .04± .02 |
| λM = 0 | 10-8 | 10-6 | 10-4 | 10-2 | 1 | 102 | |
|---|---|---|---|---|---|---|---|
| Skater ℓ = 2 | .38± .34 | .53± .12 | .50± .1 | .47± .1 | .41± .02 | .33± .17 | .21± .2 |
| ℓ = 3 | .55± .12 | .62± .11 | .55± .13 | .42± .01 | .36± .09 | .2± .18 | .39± .22 |
| ℓ = 2 | .48± .1 | .59± .17 | .59± .18 | .55± .12 | .41± .01 | .01±0 | .64± .01 |
| Car ℓ = 3 | .67± .01 | .60± .12 | .73± .09 | .36± .05 | .33± .11 | .27± .14 | .73± .01 |
| ℓ = 2 | .55± .13 | .56± .14 | .43±0 | .45± .04 | .62± .02 | .35± .19 | .13± .08 |
| Matrix ℓ = 3 | .55± .12 | .53± .12 | .82± .14 | .35± .05 | .35± .31 | .02± .01 | .01±0 |
Effects of motion. In order to study the effect of motion in multi-layer architectures (up to 3 layers), we still kept the most stable configuration ("stability, reality", 5 × 5 filters, 5 features), and introduced the motion-related term in the cognitive action. Our multi-layer architecture is composed of a stack of computational models developed accordingly to (3). A new layer ℓ is activated whenever layer ℓ-1 has processed a large number of frames (≈ 45k), and the parameters of layer ℓ - 1 are not updated anymore. We initially considered the case in which all the layers ℓ = 1, . . . , 3 share the same value λM that weighs the motion-based term. Tab. 2 shows the MI we get for different weighting schemes. Introducing motion helps in almost all the cases (for appropriate λM - the smallest values of λM are a good choice on average), and, as expected, a too strong enforcement of the motion-related term leads to degenerate solutions with small MI. We repeated these experiments also in a different setting. In detail, after having evaluated layer ℓ for all the values of λM, we selected the model with the largest MI and started evaluating layer ℓ+1 on top of it. Tab. 3 reports the outcome of this experience. We clearly see that motion plays an important role in increasing the average MI. In the case of "car", we also obtained two (uncommon) positive results when strongly weighing λM. They are due to very frequent reset operations, that avoided the system to alter the filters when the motion-based term was leading to very large derivatives. This is an interesting behaviour that, however, was not common in the other cases we reported.
5 Conclusions
In this paper we have introduced a new approach to learning visual features according to the principle of least cognitive action. The experiments indicate the remarkable difference coming from the incorporation of motion invariance, with respect to the features only driven by information-based principles, which also results in the improvement of the mutual information from the video to the features. The theory is coherent with the different role of the ventral stream and dorsal stream [Goodale and Milner, 1992] that has been observed in humans. The enforcement of motion invariance is conceived for extracting features that are useful for object recognition to assolve the "what" task (ventral stream), whereas "dorsal neurons", that are involved for where/how environmental interactions are expected not to use motion invariance. The model behind the learning of the filters indicates the need to access to velocity estimation, which is consistent with neuroanatomical evidence. Although the experimental results reported in the paper assume a uniform probability distribution in the spatial domain, the given formulation in the framework of the principle of least cognitive action suggests that the optimization must take place in areas of high saliency. In this case, the reformulation of the Euler equations given in this paper leads to identify the crucial role of eye movements in animals with foveal eyes. In future work we will also study the problem of building higher-level motion-based object predictors on top of the motion-invariant features described in this paper, with the same goal of giving a clear theoretical foundation to the development of such predictors.
@inproceedings{ijcai2019p278,
  title     = {Motion Invariance in Visual Environments},
  author    = {Betti, Alessandro and Gori, Marco and Melacci, Stefano},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {2009--2015},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/278},
  url       = {https://doi.org/10.24963/ijcai.2019/278},
}
TY - CPAPER TI - Motion Invariance in Visual Environments AU - Betti, Alessandro AU - Gori, Marco AU - Melacci, Stefano T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 2009 EP - 2015 DO - 10.24963/ijcai.2019/278 UR - https://doi.org/10.24963/ijcai.2019/278 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





