
Asynchronous Stochastic Frank-Wolfe Algorithms for Non-Convex Optimization
Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence. Main track. Pages 737-743.
https://doi.org/10.24963/ijcai.2019/104
Keywords
- Machine Learning Applications: Big data ; Scalability
- Computer Vision: Big Data and Large Scale Methods
Abstract
Asynchronous parallel stochastic optimization for non-convex problems becomes more and more important in machine learning especially due to the popularity of deep learning. The Frank-Wolfe (a.k.a. conditional gradient) algorithms has regained much interest because of its projection-free property and the ability of handling structured constraints. However, our understanding of asynchronous stochastic Frank-Wolfe algorithms is extremely limited especially in the non-convex setting. To address this challenging problem, in this paper, we propose our asynchronous stochastic Frank-Wolfe algorithm (AsySFW) and its variance reduction version (AsySVFW) for solving the constrained non-convex optimization problems. More importantly, we prove the fast convergence rates of AsySFW and AsySVFW in the non-convex setting. To the best of our knowledge, AsySFW and AsySVFW are the first asynchronous parallel stochastic algorithms with convergence guarantees for solving the constrained non-convex optimization problems. The experimental results on real high-dimensional gray-scale images not only confirm the fast convergence of our algorithms, but also show a near-linear speedup on a parallel system with shared memory due to the lock-free implementation.
- [Allen-Zhu and Li, 2018] Zeyuan Allen-Zhu and Yuanzhi Li. Neon2: Finding local minima via first-order oracles. In Advances in Neural Information Processing Systems, pages 3720-3730, 2018.
- [Chen and Wang, 2018] Hong Chen and Yulong Wang. Kernel-based sparse regression with the correntropy- induced loss. Applied and Computational Harmonic Anal- ysis, 44(1):144-164, 2018.
- [Dudik et al., 2012] Miroslav Dudik, Zaid Harchaoui, and Jérôme Malick. Lifted coordinate descent for learning with trace-norm regularization. In Artificial Intelligence and Statistics, pages 327-336, 2012.
- [Feng et al., 2015] Yunlong Feng, Xiaolin Huang, Lei Shi, Yuning Yang, and Johan AK Suykens. Learning with the maximum correntropy criterion induced losses for regres- sion. Journal of Machine Learning Research, 16:993- 1034, 2015.
- [Frank and Wolfe, 1956] Marguerite Frank and Philip Wolfe. An algorithm for quadratic programming. Naval Research Logistics (NRL), 3(1-2):95-110, 1956.
- [Garber and Hazan, 2015] Dan Garber and Elad Hazan. Faster rates for the frank-wolfe method over strongly- convex sets. In ICML, volume 15, pages 541-549, 2015.
- [Goldfarb et al., 2017] Donald Goldfarb, Garud Iyengar, and Chaoxu Zhou. Linear convergence of stochastic frank wolfe variants. arXiv preprint arXiv:1703.07269, 2017.
- [Gu and Huo, 2018] Bin Gu and Zhouyuan Huo. Asyn- chronous doubly stochastic group regularized learning. In International Conference on Artificial Intelligence and S- tatistics (AISTATS 2018), 2018.
- [Gu et al., 2017] Bin Gu, Guodong Liu, and Heng Huang. Groups-keeping solution path algorithm for sparse regres- sion with automatic feature grouping. In KDD, pages 185- 193. ACM, 2017.
- [Gu et al., 2018a] Bin Gu, Zhouyuan Huo, Cheng Deng, and Heng Huang. Faster derivative-free stochastic algorithm for shared memory machines. In International Conference on Machine Learning, pages 1807-1816, 2018.
- [Gu et al., 2018b] Bin Gu, De Wang, Zhouyuan Huo, and Heng Huang. Inexact proximal gradient methods for non- convex and non-smooth optimization. In AAAI, pages 3093-3100, 2018.
- [Hazan and Luo, 2016] Elad Hazan and Haipeng Luo. Variance-reduced and projection-free stochastic optimiza- tion. In International Conference on Machine Learning, pages 1263-1271, 2016.
- [Hsieh et al., 2015] Cho-Jui Hsieh, Nagarajan Natarajan, and Inderjit S Dhillon. Pu learning for matrix completion. In ICML, pages 2445-2453, 2015.
- [Huo et al., 2018] Zhouyuan Huo, Bin Gu, Ji Liu, and Heng Huang. Accelerated method for stochastic composition optimization with nonsmooth regularization. In Thirty- Second AAAI Conference on Artificial Intelligence, 2018. [Jaggi, 2013] Martin Jaggi. Revisiting frank-wolfe: Projection-free sparse convex optimization. In ICML (1), pages 427-435, 2013.
- [Lacoste-Julien and Jaggi, 2015] Simon Lacoste-Julien and Martin Jaggi. On the global linear convergence of frank- wolfe optimization variants. In Advances in Neural Infor- mation Processing Systems, pages 496-504, 2015.
- [Lacoste-Julien et al., 2013] Simon Lacoste-Julien, Martin Jaggi, Mark Schmidt, and Patrick Pletscher. Block- coordinate frank-wolfe optimization for structural svm- s. In ICML 2013 International Conference on Machine Learning, pages 53-61, 2013.
- [Lacoste-Julien, 2016] Simon Lacoste-Julien. Convergence rate of frank-wolfe for non-convex objectives. arXiv preprint arXiv:1607.00345, 2016.
- [Lan, 2013] Guanghui Lan. The complexity of large-scale convex programming under a linear optimization oracle. arXiv preprint arXiv:1309.5550, 2013.
- [Lei et al., 2017] Lihua Lei, Cheng Ju, Jianbo Chen, and Michael I Jordan. Non-convex finite-sum optimization via scsg methods. In Advances in Neural Information Process- ing Systems, pages 2348-2358, 2017.
- [Mania et al., 2017] Horia Mania, Xinghao Pan, Dimitris Pa- pailiopoulos, Benjamin Recht, Kannan Ramchandran, and Michael I Jordan. Perturbed iterate analysis for asyn- chronous stochastic optimization. SIAM Journal on Op- timization, 27(4):2202-2229, 2017.
- [Moharrer and Ioannidis, 2017] Armin Moharrer and Stratis Ioannidis. Distributing frank-wolfe via map-reduce. In 2017 IEEE International Conference on Data Mining, ICDM 2017, New Orleans, LA, USA, November 18-21, 2017, pages 317-326, 2017. IJCAI
- [Recht et al., 2011] Benjamin Recht, Christopher Re, Stephen Wright, and Feng Niu. Hogwild: A lock-free approach to parallelizing stochastic gradient descent. In Advances in neural information processing systems, pages 693-701, 2011.
- [Reddi et al., 2016] Sashank J Reddi, Suvrit Sra, Barnabás Póczos, and Alex Smola. Stochastic frank-wolfe meth- ods for nonconvex optimization. In Communication, Con- trol, and Computing (Allerton), 2016 54th Annual Allerton Conference on, pages 1244-1251. IEEE, 2016.
- [Wang et al., 2016] Yu-Xiang Wang, Veeranjaneyulu Sad- hanala, Wei Dai, Willie Neiswanger, Suvrit Sra, and Er- ic Xing. Parallel and distributed block-coordinate frank- wolfe algorithms. In International Conference on Machine Learning, pages 1548-1557, 2016.
- [Yang et al., 2018] Yuning Yang, Yunlong Feng, and Jo- han AK Suykens. Correntropy based matrix completion. Entropy, 20(3):171, 2018.
- [Zhang et al., 2017] Wenpeng Zhang, Peilin Zhao, Wenwu Zhu, Steven CH Hoi, and Tong Zhang. Projection-free dis- tributed online learning in networks. In International Con- ference on Machine Learning, pages 4054-4062, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Asynchronous parallel stochastic optimization algorithms are popular in the current big data era because of the outstanding scalability w.r.t. the sample size and the full exploitation of the computing resources of multi-core machines. For example, Hogwild! [Recht et al., 2011] is a famous asynchronous parallel stochastic gradient descent algorithm for solving smooth finite-sum optimization problems. Non-convex optimization is now ubiquitous in machine learning especially due to the popularity of deep learning. Thus, the research of asynchronous parallel stochastic optimization for non-convex problems becomes more and more important in machine learning.
∗To whom all correspondence should be addressed.
In machine learning, a lot of learning problems are formulated as a finite-sum of loss functions with one or more structured constraints. For example, multi-class classification [Dudik et al., 2012] and matrix completion [Hsieh et al., 2015] consider a finite-sum function with the trace-norm constraint. Octagonal shrinkage and clustering algorithm for regression (OSCAR) [Gu et al., 2017] considers a finite-sum function with ℓ1 norm and pairwise ℓ∞ norm constraints. Normally, we use proximal gradient descent algorithms [Gu et al., 2018b] to solve the above constrained optimization problems, in which each iteration solves a projection mapping. However, it is maybe time-consuming to solve the projection mapping which is a quadratic problem for a lot of norms (including the trace norm [Dudik et al., 2012] and the OSCAR norm [Gu et al., 2017]). Alternatively, [Frank and Wolfe, 1956] first proposed the Frank-Wolfe (a.k.a. conditional gradient) algorithm where only a less expensive linear subproblem need to be solved per iteration. Recently, the Frank-Wolfe algorithms have regained much interest due to its projection-free property and its ability to handle structured constraints.
Most of existing Frank-Wolfe algorithms were designed for the constrained smooth convex optimization problems. Specifically, several variants of deterministic Frank-Wolfe algorithms [Frank and Wolfe, 1956; Jaggi, 2013; Garber and Hazan, 2015; Lacoste-Julien et al., 2013; Lacoste-Julien and Jaggi, 2015] were proposed, and their convergence rates in the convex setting were provided. To handle large-scale problems, corresponding stochastic Frank-Wolfe algorithms [Lan, 2013; Hazan and Luo, 2016; Goldfarb et al., 2017] were proposed recently, and their convergence rates were also provided. In addition to the stochastic Frank-Wolfe algorithms, distributed parallel Frank-Wolfe algorithms [Wang et al., 2016; Moharrer and Ioannidis, 2017; Zhang et al., 2017] were also proposed recently and their convergence rates were provided. As mentioned above, the convergence analysis of most of existing Frank-Wolfe algorithms were provided only for the convex setting.
Because non-convex optimization is now ubiquitous in machine learning as mentioned previously, in this paper, we mainly consider the constrained non-convex optimization Algorithm 1 Asynchronous Stochastic Frank-Wolfe Algorithm (AsySFW)
| Algorithm | Reference | Function f(x) | Stochastic gradient | Variance reduced | Asynchronous |
|---|---|---|---|---|---|
| Frank-Wolfe SFW SVFW SAGAFW AsySFW AsySVFW | [Lacoste-Julien, 2016] [Reddi et al., 2016] [Reddi et al., 2016] [Reddi et al., 2016] Our Our | Non-convex Non-convex Non-convex Non-convex Non-convex Non-convex | No Yes Yes Yes Yes Yes | No No Yes (SVRG) Yes (SAGA) No Yes (SVRG) | No No No No Yes Yes |
Parameter: The number of iterations T, the mini-batch size b and the learning rate γ.
Initialize: Initialize x0 ∈M.
- 1: For each thread, do:
- 2: for t = 0, 1, 2, · · · , T -1 do
- 3: Randomly sample a mini-batch B of the size of b from {1, ..., n} with equal probability.
- 4: Compute ̂ vt ← 1b ∑i∈B ∇fi(̂ xt), and ̂ dt = arg mind∈M 〈d, ̂ vt〉.
- 5: Update xt+1 ← xt +γ ( ̂ dt - ̂ xt).
- 6: end for
2 Asynchronous Stochastic Frank-Wolfe Algorithms
In this section, we first propose our asynchronous stochastic Frank-Wolfe algorithm (i.e., AsySFW) to solve the constrained non-convex optimization problem (1), and then propose its SVRG version (i.e., AsySVFW). Finally, we provide several discussions to AsySFW and AsySVFW.
2.1 AsySFWAlgorithm
AsySFW repeats the following three steps concurrently for each thread without any lock. First, AsySFW reads the vector x from the shared memory to the local memory which is denoted as ̂ x. After that, AsySFW randomly chooses a mini-batch B of the size of b from {1, ..., n} with equal probability, and locally computes ̂ vt ← 1b ∑i∈B ∇fi(̂ xt), and ̂ dt = arg mind∈M 〈d, ̂ vt〉. Finally, AsySFW updates the vector x in the shared memory by the following formulation.
where γ is the learning rate. We summarize our AsySFW in Algorithm 1.
2.2 AsySVFWAlgorithm
We use the variance reduction technique specifically SVRG [Gu et al., 2018a; Huo et al., 2018] to accelerate AsySFW algorithm, which is called as AsySVFW. AsySVFW has twolayer loops. The outer layer is to parallelly compute the full gradient ∇f(xs ) = 1n ∑li=1 ∇fi(xs ), where the superscript s denotes the s-th outer loop. The inner layer is to parallelly and repeatedly update the vector x in the shared memory.
problem as follows.
where fi : Rd ↦→ R is a non-convex and smooth loss function, and M is a convex and compact set. To the best of our knowledge, there are only two works to solve the nonconvex problem (1) by Frank-Wolfe algorithms. Specifically, [Lacoste-Julien, 2016] proposed the deterministic FrankWolfe algorithm to solve (1) and provide its convergence rate. [Reddi et al., 2016] proposed vanilla stochastic Frank-Wolfe algorithm and its variants of SVRG and SAGA to solve (1), and provided their convergence rates. We also summarize these representative Frank-Wolfe algorithms to solve (1) in Table 1. As far as we know, the convergence guarantee of asynchronous stochastic Frank-Wolfe algorithms for solving the constrained non-convex optimization problem (1) is still an open question.
To address this challenging problem, in this paper, we propose our asynchronous stochastic Frank-Wolfe algorithm (AsySFW) and its variance reduction version (AsySVFW) for solving the constrained non-convex optimization problem. More importantly, we prove the fast convergence rates of AsySFW and AsySVFW in the non-convex setting. To the best of our knowledge, AsySFW and AsySVFW are the first asynchronous parallel stochastic Frank-Wolfe algorithms with convergence guarantees for solving the constrained nonconvex optimization problems. The experimental results on real high-dimensional gray-scale images not only confirm the fast convergence of our algorithms, but also show a nearlinear speedup on a parallel system with shared memory due to the lock-free implementation.
The main contributions of this paper are summarized as follows.
- We propose vanilla asynchronous stochastic Frank-Wolfe algorithm (i.e., AsySFW) and prove the ergodic convergence rate of AsySFW in the non-convex setting.
- We propose the SVRG version of AsySFW (i.e., AsySVFW) and prove the ergodic convergence rate of AsySVFW in the non-convex setting.
We organize the rest of paper as follows. In Section 2, we propose our AsySFW and AsySVFW algorithms. In Section 3, we provide the convergence analysis to AsySFW and AsySVFW. In Section 4, we show the experimental results. Finally, in Section 5, we conclude the paper.
Algorithm 2 AsySVFW Algorithm
Parameter: The number of outer loop iterations S, the number of inner loop iterations m where T = S × m, the mini-batch size b and the learning rate γ.
Initialize: Initialize x0 ∈M.
- 1: for s = 0, 1, 2, · · · , S -1 do
- 2: Set ˜ xs ← xs , and parallelly compute the full gradient ∇f (˜ xs ) = 1n ∑li ∇fi(˜ xs ).
- 3: For each thread, do:
- 4: for t = 0, 1, 2, · · · ,m-1 do
- 5: Randomly sample a mini-batch B of the size of b from {1, ..., n} with equal probability.
- 6: Compute ̂ vs+1 t ← 1b ∑i∈B ∇fi(̂ xs+1 t ) - 1b ∑i∈B ∇fi(˜ xs ) + ∇f (˜ xs ).
- 7: Compute ̂ ds+1 t = argmind∈M 〈d, ̂ vs+1 t 〉.
- 8: Update xs+1 t+1 ← xs+1 t +γ ( ̂ ds+1 t - ̂ xs+1 t ).
- 9: end for
- 10: xs+1 ← xs+1 m
- 11: end for
Specifically, all cores repeat the following steps independently and concurrently without any lock.
- Read: Read the vector x from the shared memory to the local memory without reading lock. We use ̂ xs+1 t to denote its value, where the subscript t denotes the t-th inner loop.
- Compute: Randomly choose a mini-batch B of the size of b from {1, ..., n} with equal probability, and locally compute ̂ vs+1 t ← 1b ∑i∈B ∇fi(̂ xs+1 t ) - 1b ∑i∈B ∇fi(˜ xs ) + ∇f (˜ xs ), and ̂ ds+1 t = argmind∈M 〈d, ̂ vs+1 t 〉.
- Update: Update the vector x in the shared memory as xs+1 t+1 ← xs+1 t +γ ( ̂ ds+1 t - ̂ xs+1 t ) without writing lock.
We summarize our AsySVFW in Algorithm 2. Note that the expectation of ̂ vs+1 t on B is equal to∇f(̂ xs+1 t ), i.e., Ê vs+1 t = ∇f (̂ xs+1 t )-∇f(˜ xs ) + ∇f (˜ xs ) = ∇f (̂ xs+1 t ). Thus, ̂ vs+1 t is called an unbiased stochastic gradient of ∇f(̂ xs+1 t ).
2.3 Discussions
We provide several discussions of AsySFW and AsySVFW in terms of solving the subproblem and parallel computing environment respectively as follows.
- Solving the Subproblem: Different to the proximal gradient descent algorithms [Gu et al., 2018b] which need to solve a quadratic subproblem in each iteration, AsySFW and AsySVFW solve a linear subproblem (lines 4 and 7 in Algorithms 1 and 2 respectively) which can be solved easier compared to the quadratic subproblem. [Jaggi, 2013] provides a lot of discussions and examples to solve the linear subproblems associated to the convex and compact sets M (including the trace-norm constraint [Dudik et al., 2012] considered in this paper).
- Parallel Computing Environment: AsySFW and AsySVFW are designed for the parallel environment with
shared memory, such as multi-core processors and GPUaccelerators which can allow for the situation of concurrent write-read to happen in the process. Besides, AsySFW and AsySVFW can also work in the parallel environment with distributed memory.
3 Convergence Analysis
In this section, we first give several basic assumptions and notations, and then discuss three major difficulties for proving the convergence rates of AsySFW and AsySVFW for constrained non-convex problems. Finally, we give the convergence rates of our AsySFW and AsySVFW.
3.1 Basic Assumptions and Notations
We introduce the assumptions of Lipschitz smoothness (i.e., Assumption 1) and bounded gradients (i.e., Assumption 2) for the function fi(x), which are standard for non-convex optimization [Lacoste-Julien, 2016; Gu et al., 2018b; Lei et al., 2017; Allen-Zhu and Li, 2018].
Assumption 1 (Lipschitz smoothness) For smooth function fi(x) (∀i ∈ {1, . . . , l}) in (1), fi(x) is called L-Lipschitz smoothness, if for all x and y, we have that:
Assumption 2 (Bounded gradients) For smooth function fi(x) (∀i ∈ {1, . . . , l}) in (1), the gradient ∇fi(x) is called bounded if there exists a parameter G such that ‖∇fi(x)‖ ≤ G for all x ∈ M.
To make this section easier to follow, we give a summary of the notations in the following list.
- Λ = {x : g(x) ≤ c} is the original constrained set.
- Ω is the expanded constrained set.
- D is the diameter of the compact convex set Ω.
- (x)i is the i-th coordinate of the vector x.
- Bt′ is a diagonal matrix with diagonal entries either 1 or 0 (if the corresponding updating has been received, the entry is 0, otherwise 1).
3.2 Difficulties of the Convergence Rate Analysis
In this subsection, we discuss the difficulties of convergence criteria, write-write conflict, inconsistent reading and beyonding the feasible set respectively when analyzing the convergence rates of AsySFW and AsySVFW for constrained non-convex problems.
Convergence Criteria
Because the objective function f(x) is non-convex, our AsySFW and AsySVFW algoritms cannot guarantee to produce the global optimum solution. Thus, the closeness to the optimal solution (i.e., f(x) - f(x∗ ) and ‖x - x∗ ‖) cannot be used for the convergence analysis, where x∗ is the global optimal solution. For unconstrained problems, the gradient norm ‖∇f(x)‖ is normally used to measure convergence, because ‖∇f(x)‖ translates into convergence to a stationary point. However, this criterion cannot be used for constrained problems of the form (1). Similar to [Lacoste-Julien, 2016; Reddi et al., 2016], we use the Frank-Wolfe gap (4) as the convergence criteria.
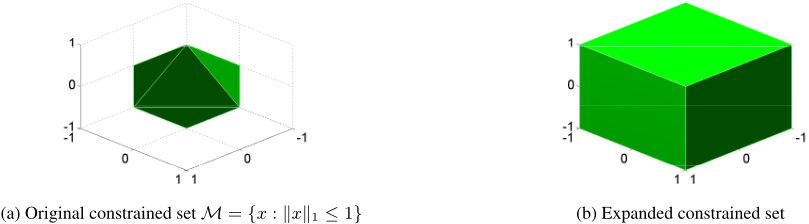
Specifically, for the constrained non-convex optimization problem (1), the gap g(x) = 0 if and only if x is a stationary point.
Write-Write Conflict
Because we do not use any writing lock in AsySFW and AsySVFW, all cores can update the vector x in the shared memory, which could lead to write-write conflict and make the convergence analysis more complicated.
To address this challenge, we first assume that all writes are atomic, in the sense that they will be successfully recorded in the shared memory at some point (Assumption 3).
Assumption 3 Each coordinate of vector x in Lines 5 and 8 in Algorithms 1 and 2 respectively will be updated successfully.
This assumption implies that the order in which these updates are recorded in the shared memory is irrelevant which is also called as the commutativity. Because the property of commutativity holds for our updating rules (i.e., Lines 5 and 8 in Algorithms 1 and 2 respectively), the updating rule with the write-write conflict can be formalized as follows:
where xt denotes the ideal one in the shared memory. Thus, we can analyze the convergence rates through the ideal x like [Recht et al., 2011; Mania et al., 2017; Gu and Huo, 2018]. Note that we use ̂ xt for computing ∆t instead of xt which reduces the frequency of reading x from the shared memory, but makes our analysis more difficult.
Inconsistent Read
Because AsySFW and AsySVFW do not use the reading and writing locks, the vector ̂ xt read into the local memory may be inconsistent to the vector xt in the shared memory. We call this as inconsistent read. To address the challenge, we denote the delay updating iterations for xt by a set K(t) such that the relationship between xt and ̂ xt can be builded as follows:
where t′ ≤ t - 1. It is reasonable to assume there exists an upper bound τ to the delay of updating such that τ ≥ t - min{t′ |t′ ∈ K(t)} (i.e., Assumption 4).
Assumption 4 (Bound of delay) There exists an upper bound τ such that τ ≥ t - min{t′ |t′ ∈ K(t)} for all iterations t in AsySFW or AsySVFW.
Beyond the Feasible Set
Due to the inconsistent writing and write-write conflict, ̂ xt read into the local memory could be beyond the original constrained set M. To handle this challenge, we define an expanded constrained set Ω (see Definition 1 and Figure 1) based on Mwhich is used only for our analysis. It is easy to verify that Ω is a compact convex set with M ⊆ Ω and ̂ xt belongs to the expanded constrained set Ω.
Definition 1 (Extended constrained set) Given a constrained set M. Let Mmin i = minx∈M(x)i and Mmax i = maxx∈M(x)i. We define the expanded constrained set of M as Ω = {x : (x)i ∈ [Mmin i ,Mmax i ], ∀i = 1, . . . , n}.
3.3 Convergence Rate Analysis
After addressing the above challenges, we provide the convergence rates to our AsySFW (Theorem 1) and AsySVFW (Theorem 2). All the detailed proofs are provided in our Appendix 1 .
AsySFW
We first give the convergence rate of AsySFW in Theorem 1. Theorem 1 Let γ = √ f(x0)-f(x∗ ) T ((2τ+ 1 2)LD2+τGD)β and b = T. Under Assumptions 1, 2, 3 and 4, for AsySFW algorithm, we have that
Remark 1 To achieve 1 - ϵ accuracy, AsySFW algorithm requires O( 1 ϵ4 ) stochastic gradient evaluations and O( 1 ϵ2 ) linear optimizations. If the bound
1 The Appendix is available at https://drive.google.com/open?id= 1FeXGqQBr6sqmO1zmeHaPx80imvOrYfXH.
τ of delay is equal to 0, the convergence rate is D √T (2G + √ L(f (x0)-f (x∗ )) 2 (√β + 1 √β )) which matches the convergence rate of sequential SFW algorithm [Reddi et al., 2016].
AsySVFW
We also give the convergence rate of AsySVFW in Theorem 2.
m2 , where T = m × S. Under Assumptions 1, 2, 3 and 4, for AsySVFW algorithm, we have that
where a = 2τLD2 + τGD + 3LD2 2 .
Remark 2 To achieve 1 - ϵ accuracy, AsySVFW algorithm requires O ( 1 ϵ2 m2 ) exact gradient evaluations, O( m2 ϵ2 ) stochastic gradient evaluations and O( 1 ϵ2 ) linear optimizations. If the bound τ of delay is equal to 0, the convergence rate is D √T (√ 3L(f (x0)-f (x∗ )) 2 (√β + 1 √β )) which matches the convergence rate of sequential SVFW algorithm [Reddi et al., 2016].
4 Experiments
In this section, we first give the experimental setup, and then present our experimental results with discussions.
4.1 Experimental Setup
Design of Experiments
We consider the robust matrix completion problem [Yang et al., 2018] in the experiments. Given an incomplete matrix Y , the robust matrix completion is to recover the incomplete matrix Y based on the correntropy-induced loss [Feng et al., 2015; Chen and Wang, 2018] and trace-norm constraint [Dudik et al., 2012]. Specifically, the robust matrix completion problem considers the objective function and the tracenorm constraint as follows.
where d1 × d2 is the size of the matrix, σ > 0 is a scale parameter and Λ is the set of all observed entries.
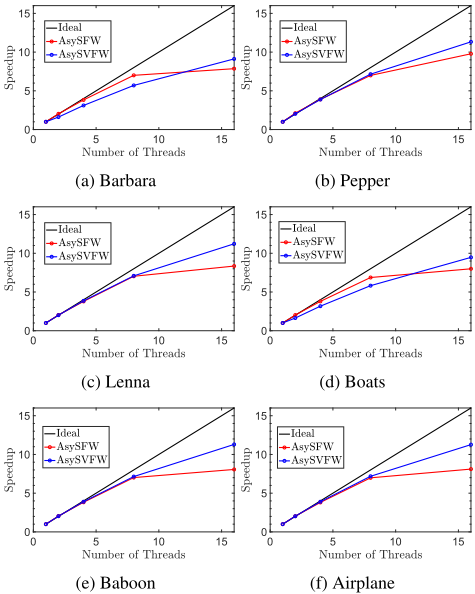
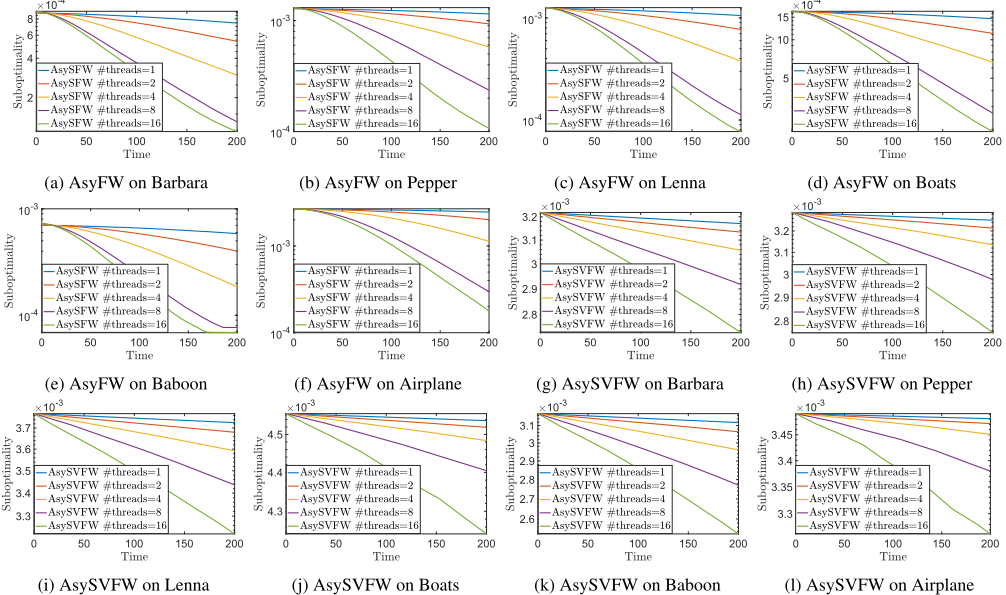
In the experiments, we test the suboptimality (difference between the objective function and its closest minimum value) of AsySFW and AsySVFW with different numbers of threads to verify the fast convergence of AsySFW and AsySVFW. We also observe the speedup of AsySFW and AsySVFW on a parallel system with shared memory.
Implementation Details
Our experiments are performed on a 32-core two-socket Intel Xeon E5-2699 machine where each socket has 16 cores. We implement our AsySFW and AsySVFW using C++, where the shared memory parallel computation is handled via OpenMP. We focus on the convergence of AsySFW and AsySVFW so that the tuning of the parameters σ and c is less important. Thus, the parameters σ and c are fixed at 0.15 and 500 respectively. In addition, we set the learning rate γ = 0.0001, the mini-batch size b = 500, the inner loop size of AsySVFW m = 50. We choose X = 1 2 αY as the initial solution for AsySFW and AsySVFW, where α is the smallest value in {1, 2, . . . , 10} such that ‖X‖∗ ≤ c.
Datasets
[Yang et al., 2018] conducted an image recovery experiment based on real gray-scale images 2 . In our experiments, we used the robust matrix completion problem defined in (9)- (10) to achieve image recovery. Specifically, we select six images, i.e., Airplane, Baboon, Barbara, Boats, Lenna and Pepper from the same image source. These images are originally with pixels of the size of 728 × 642, which means that d1 = 728 and d2 = 642. We miss 30% pixels randomly and let it be the incomplete matrix Y . Thus, the size of the set
2 The real gray-scale images are available at https://homepages. cae.wisc.edu/∼ece533/images/
Λ of all observed entries is 327, 163. In the experiments, all results are the average of 10 trials.
4.2 Results and Discussions
Figure 3 illustrates the lines of the suboptimality vs. running time of our AsyFW and AsySVFW algorithms with 1, 2, 4, 8 and 16 cores on the six real gray-scale images. The results show that our AsyFW and AsySVFW algorithms with different numbers of threads can always converge to a stationary (empirically local) solution. More importantly, the results verify that AsyFW and AsySVFW with more threads converge faster than the ones with less threads. To sum up, the results in Figure 3 confirm that our AsyFW and AsySVFW algorithms converge to a stationary solution with fast convergence.
Figure 2 presents the speedup results of AsyFW and AsySVFW with 1, 2, 4, 8 and 16 cores on the six real grayscale images. The results show that AsyFW and AsySVFW can have a near-linear speedup on a parallel system with shared memory. This is because we do not use any lock in the implementations of AsyFW and AsySVFW which keeps all computational resources busy all the time.
5 Conclusion
The convergence guarantee of asynchronous stochastic Frank-Wolfe algorithms for solving the constrained nonconvex optimization problem (1) is still an open question.
To address this challenging problem, in this paper, we propose an asynchronous stochastic Frank-Wolfe algorithm (i.e., AsySFW) and its variance reduction version (i.e., AsySVFW) for solving the constrained non-convex optimization problems. We prove the fast convergence rates of AsySFW and AsySVFW in the non-convex setting. To the best of our knowledge, AsySFW and AsySVFW are the first asynchronous parallel stochastic algorithms with convergence guarantees for solving the constrained non-convex optimization problems. The experimental results on real high-dimensional gray-scale images not only confirm the fast convergence of our algorithms, but also show a near-linear speedup on a parallel system with shared memory due to the lock-free implementation.
Acknowledgments
H.H. was partially supported by U.S. NSF IIS 1836945, IIS 1836938, DBI 1836866, IIS 1845666, IIS 1852606, IIS 1838627, IIS 1837956. B.G. was partially supported by the National Natural Science Foundation of China (No: 61573191), and the Natural Science Foundation (No. BK20161534), Six talent peaks project (No. XYDXX-042) in Jiangsu Province.
@inproceedings{ijcai2019p104,
  title     = {Asynchronous Stochastic Frank-Wolfe Algorithms for Non-Convex Optimization},
  author    = {Gu, Bin and Xian, Wenhan and Huang, Heng},
  booktitle = {Proceedings of the Twenty-Eighth International Joint Conference on
               Artificial Intelligence, {IJCAI-19}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Sarit Kraus},
  pages     = {737--743},
  year      = {2019},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2019/104},
  url       = {https://doi.org/10.24963/ijcai.2019/104},
}
TY - CPAPER TI - Asynchronous Stochastic Frank-Wolfe Algorithms for Non-Convex Optimization AU - Gu, Bin AU - Xian, Wenhan AU - Huang, Heng T2 - Proceedings of the Twenty-Eighth International Joint Conference on Artificial Intelligence, IJCAI-19 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2019 SP - 737 EP - 743 DO - 10.24963/ijcai.2019/104 UR - https://doi.org/10.24963/ijcai.2019/104 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





