
Finding Communities with Hierarchical Semantics by Distinguishing General and Specialized topics
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 3648-3654.
https://doi.org/10.24963/ijcai.2018/507
Keywords
- Machine Learning Applications: Networks
- Multidisciplinary Topics and Applications: AI and the Web
Abstract
Using network topology and semantic contents to find topic-related communities is a new trend in the field of community detection. By analyzing texts in social networks, we find that topics in networked contents are often hierarchical. In most cases, they have a two-level semantic structure with general and specialized topics, to respectively denote common and specific interests of communities. However, the existing community detection methods ignore such a hierarchy and take all words used to describe node semantics from an identical perspective. This indiscriminate use of words leads to natural defects in depicting networked content in which the deep semantics is not fully utilized. To address this problem, we propose a novel probabilistic generative model. By distinguishing the general and specialized topics of words, our model not only can find community structures more accurately, but also provide two-level semantic interpretation for each community. We train the model by deriving an efficient inference method under the framework of variational expectation-maximization. We provide a case study to show the ability of our algorithm in deep semantic interpretability of communities. The superiority of our algorithm for community detection is further demonstrated in comparison with eight state-of-the-art algorithms on eight real-world networks.
- [Balasubramanyan and Cohen, 2011] Ramnath Bal- asubramanyan and Willim W.Cohen. Block-LDA: Jointly modeling entity annotated text and entity-entity links. In Proceedings of 11th SIAM International Conference on Data Mining, pages 450-461, Philly, USA, Feb 2011.
- [Cantador, 2016] Cantador, I. The 2nd International Work- shop on Information Heterogeneity and Fusion in Rec- ommender Systems, 2016. http://ir.ii.uam.es/hetrec2011. Link
- [Girvan and Newman, 2002] Michelle Girvan and Mark EJ Newman. Community structure in social and biological networks. In Proceeding of the National Academy of Science, 99(12):7821-7826, April 2002.
- [Jin et al., 2018] Di Jin, Xiaobao Wang, Ruifang He, Dongxiao He, Jianwu Dang and Weixiong Zhang. Robust Detection of Link Communities in Large Social Networks by Exploiting Link Semantics. In Proceedings of the 32th AAAI Conference on Artificial Intelligence, pages 314-321, Louisiana, USA, February 2018.
- [He et al., 2017] Dongxiao He, Zhiyong Feng, Di Jin, Xiaobao Wang and Weixiong Zhang. Joint Identification of Network Communities and Semantics via Integrative Modeling of Network Topologies and Node Content. In Proceedings of the 31th AAAI conference on Artificial Intelligence, pages 116-124, California, February 2017.
- [Hu et al., 2014] Han Hu, Zhouchen Lin, Jianjiang Feng and Jie Zhou. Smooth representation clustering. In Proceed- ings of the 27th Conference on CVPR, pages 3834-3841, Piscataway, New Jersey, USA, June 2014. Karrer and Newman, 2011] Brian Karrer and Mark EJ Newman. Stochastic block models and community structure in networks. Physical Review E, 83(1): 016107.
- [Leskovec, 2016] Leskovec Jure. Stanford Network Analysis Project. http://snap.standford.edu. Link
- [Liu et al., 2012] Haifeng Liu, Zhaohui Wu, Xuelong Li, Deng Cai and Thomas S. Huang. Constrained nonnega- tive matrix factorization for image representation. IEEE Transactions on Pattern Analysis and Machine Intelli- gence, 34(7): 1299-1311, July 2012.
- [Pei et al., 2015] Yulong Pei, Nilanjan Chakraborty and Katia Sycara. Nonnegative matrix tri-factorization with graph regularization for community detection in social networks. In Proceedings of the 24th International Joint Conference on Artificial Intelligence, pages 2083-2089, San Francisco, California, USA, July 2015. IJCAI
- [Pool et al., 2014] Simon Pool, Francesco Bonchi and Mat- thijs Leeuwen. Description-driven community detection. Intelligent Systems and Technology, 5(2):28, 2014.
- [Wang et al., 2011] Fei Wang, Tao Li, Xin Wang, Shenghuo Zhu and Chris Ding. Community discovery using nonnegative matrix factorization. Data Mining and Knowledge Discovery, 22(3): 493-521, 2011.
- [Wang et al., 2016] Xiao Wang, Di Jin, Xiaochun Cao, Liang Yang and Weixiong Zhang. Semantic community identi- fication in large attribute networks. In Proceedings of the 30th AAAI Conference on Artificial Intelligence, pages 172-178, Palo Alto, California, USA, February 2016.
- [Xie and Xing, 2013] Pengtao Xie and Eric P. Xing. Inte- grating document clustering and topic modeling. ArXiv:1309.687, (2013):694-703, 2013.
- [Yang and Leskovec, 2013] Jaewon Yang and Jure Leskovec. Overlapping community detection at scale: a nonnegative matrix factorization approach. In Proceedings of the 6th ACM international conference on Web search and data mining, pages 587-596, Rome, Italy, February 2013.
- [Yang and Leskovec, 2015] Jaewon Yang and Jure Leskovec. Defining and evaluating network communities based on ground-truth. Knowledge and Information Systems, 42(1):181-213, 2015.
- [Yang et al., 2009] Tianbao Yang, Rong Jin, Yun Chi and Shengguo Zhu. Combining link and content for commu- nity detection: A discriminative approach. In Proceedings of the 15th ACM SIGKDD International Conference, pages 927-936, Paris, June 2009.
- [Yang et al., 2013] Jaewon Yang, Julian McAuley, and Jure Leskovec. Community detection in networks with node attributes. In Proceedings of the 13th IEEE International Conference on Data Mining, pages 1151-1156, Pisca- taway, New Jersey, USA, December 2013.
- [Zhang et al., 2018] Ziwei Zhang, Peng Cui, Jian Pei, Xiao Wang and Wenwu Zhu. TIMERS: Error-Bounded SVD Restart on Dynamic Networks. In Proceedings of the 32th AAAI conference on Artificial Intelligence, pages 224-231, Louisiana, USA, February 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
As a fundamental tool for network analysis, community detection has gained more and more attention in the scientific field. Its primary task of community detection is to identify community structures in networks. Community structures correspond to functional modules composed of nodes. The identification of these modules provides a perspective for understanding and analyzing networks. Community detection can be used in many areas such as targeted advertising, protein network analysis, recommendation system, etc.
*Corresponding author.
In the early stages of community detection, a large number of algorithms emerged, only using topology, such as hierarchical clustering [Girvan and Newman, 2002], metric-based algorithms [Yang and Leskovec, 2015], generative models [Wang et al., 2011; Yang and Leskovec, 2013] and statistical inference [Karrer and Newman, 2011; Zhang et al., 2018]. However, when there is noise in network topology, the results of these methods could be improved. In recent years, researchers started integrating network topology and content, since content is beneficial to compensate for noisy topological information. Furthermore, the integration of content information provides the possibility of finding semantic communities, i.e. to offer semantic interpretation for each community. Semantic interpretation usually refers to finding the topics that embody the interests or functions of communities. Several algorithms [Pei et al., 2015; Wang et al., 2016; He et al., 2017] have been proposed to find communities with semantic interpretation by using both topology and contents.
However, most existing community detection algorithms that attempt to use contents to find topic words to explain communities have overlooked an important problem, that is, topics in the generation of contents in real life often do not come from a unique level. By analyzing a large number of texts in social networks, we found that topics contained in each document are hierarchical, and in most cases, with a two-level semantic structure. Here we call the first level the general topic, reflecting a high-level area of this document, which often covers several specialized topics. We call the second level the specialized topic, i.e. the core thought of this document. That way, a document can be summed up with general topic as well as specialized topic. Take a citation network as an example, in which each paper represents a node and the citation relationships between papers represent links. We select a node in this network, for example a classical network community detection article, i.e. [Girvan and Newman, 2002] and analyze its content. Through the statistics of topic words of this paper, we find that there is an obvious two-level topic structure, as shown in Figure 1. To reflect the difference between these two levels of topic words more clearly, we divide the partial topic words into two word clouds, to denote general and specialized topic, respectively. As we can see, the general topic words refer to the large area of network analysis. While, the core thought of [Girvan and Newman, 2002] is to provide a new perspective of network analysis, i.e. community detection, which is reflected by the specialized topic words. So, the general and specialized topics work together to form the complete semantics of this paper. Also, a general topic can derive a number of specialized topics though they share different levels of representative words, e.g., "network" is only from the general topic while "community" is only from a specialized topic under this general topic, and they cannot switch.
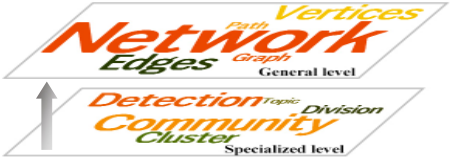
Unfortunately, the existing methods that integrate network topology and contents ignore the two-level structure of topics. As a consequence, ignoring the hierarchy structure will lead to the inaccurate fitting to the semantic contents. Besides, the topology with noise may not be fully compensated by contents, which affects the ability of algorithms to find communities, as well as the richness of semantic interpretation. Therefore, a deep analysis of the hierarchical structure of content semantics can help not only to better find communities but also get richer explanations of communities.
In order to solve the above problem, we propose a novel probabilistic generative model for jointly identifying communities and their two-level semantics at the same time. Our algorithm can automatically identify that words used to describe attributes are derived from either a general topic or a specialized topic. Due to the full utilization of the hierarchy structure of semantic topics in semantic contents, our model not only can accurately find community structures, but also describe communities using both specialized topics (to denote their particular interests) and general topics (to denote their shared features with similar communities). We finally derive an efficient inference method, based on variational expectation maximization, to train the model.
Also of note, if more information is considered, we may have more than two topic levels contained in texts. However, considering too many topic levels will often lead to poor matching between topology and contents. This mismatching issue often occurs in community detection when integrating topology and contents [He et al., 2017; Jin et al., 2018]. Fortunately, two-level topics are often sufficient to express the rich semantic of documents [Xie and Xing, 2013], and also provide a good matching between topology and contents.
So, in this paper, to simplify the model's complexity, we only consider two-level topics which is a special case of multi-level cases. The contributions of this work are as follows.
1) We find that topics in the generation of contents in real life are often not from a unique level. We design a novel model, which can fit semantic contents more accurately by distinguishing the general and specialized topic words. The hierarchical use of content enables our model to not only find communities with similar interests but also provide two-level semantic interpretation for each community in the network.
- We propose a Bayesian treatment on the model, and design an effective inference algorithm based on variational expectation maximization to train the model.
- The superiority of our algorithm in finding community structures is evaluated on eight real-world networks by comparing with eight state-of-the-art algorithms. We also present a case study to show its superiority in two-level semantic interpretability over the existing methods.
2 The Model
We develop a novel probabilistic generative model, Two-Level Semantic Community (TLSC). This model works on undirected and unweighted attributed networks.
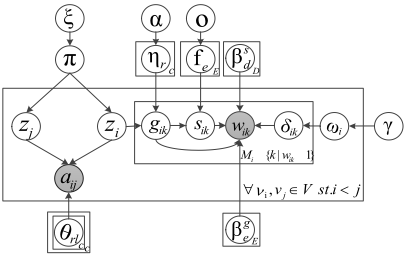
An attributed network G is represented by n nodes and m attributes. The relation among n nodes can be represented by an adjacency matrix A = (aij)n×n. If there is an edge between nodes vi and vj, aij = 1, and 0 otherwise. W = (wik)n×m denotes the attributes matrix, if node vi has the k th attribute, wik = 1, and 0 otherwise. We assume that the numbers of communities, general and specialized topics are c, E and D, respectively. Each community has a specialized topic to denote the interest itself, while some related communities, which belong to a large area, share a general topic. TLSC aims at fitting observed quantities by adjusting latent quantities and model parameters. Table 1 shows the notations of important parameters and Figure 2 the graphical representation of model.
| Sets | Sign | Description |
|---|---|---|
| X: Set of observed quantities | A W c E, D | Adjacency matrix Attribute matrix Number of communities Number of general and specialized topics |
| : Set of latent quantities | i z ik ik g ik s | Community assignment of node i v 1) δik = 0: wik is generated from general topic; 2) δik = 1: wik is generated from specialized topic General topic assignment of attribute ik w Specialized topic assignment of attribute ik w |
| : Set of model parameters having prior | i r re ed f | Parameter responsible for generating ik Probability that a node belongs to community r Probability that vi is in e th general topic given it belongs to r th community Probability that vi is in d th specialized topic given it belongs to e th generalized topic |
| : Set of parameters with no prior | rl g ek s dk | Probability that r th and l th communities connected Probability that e th general topic generates wik Probability that d th specialized topic generates wik |
2.1 Generative Process
We first introduce how to generate model parameters (having prior distribution), and then introduce how we use model parameters to generate the latent and observed quantities.
Generating Model Parameters in Set Π having Prior
We propose a Bayesian treatment for the model generation process. Instead of assuming a fixed value for each parameter in set , we treat ω , π , H and F as random variables and place a prior distribution over them. We then introduce how to generate these parameters in based on some hyper-parameters. Hyper-parameters set include ξ , α , ο and γ, which are assumed to be given first.
- We use a Dirichlet distribution to generate model parameter 1 2 π ( , ,..., ) c , where r denotes the proportion of nodes belonging to community r, and satisfies the constraint [0,1] r and 1 1 c r r . The density function of Dirichlet distribution is defined as:
parameterized by a positive real c-dimensional vector 1 2 ξ ( , ,..., ) c . We refer to ξ as hyper-parameter.
- We use a Dirichlet distribution to generate parameter matrix H ( ) re c E , in which each row η r is the general topics distribution over community r. H can be also viewed as the matrix of probabilistic transition from communities to general topics, and satisfies [0,1] re and 1 1 e E re e . The density function is defined as:
The hyper-parameter is an E-dimensional vector 1 2 α = ( , ,..., ) E . All communities share the same α .
- Similar to H, we use a Dirichlet distribution to generate matrix F ( ) ed E D f . F is a matrix of probabilistic transition from general topics to specialized topics, in which each row f e is the specialized topics distribution over general topic e, subject to [0,1] ed f and 1 1 d D ed d f . The hyper-parameter used to generate ed f is a D-dimensional vector 1 2 ο = ( , ..., ) D , defined as:
Vector ο is shared by all general topics.
- We use Beta distribution to generate model parameter 1 2 ω ( , ,..., ) n , in which i is the parameter of Bernoulli distribution. Through the Bernoulli distribution, we can get the value of ik , 0 or 1. There are two hyper-parameters in the Beta distribution, i.e. 0 and 1 .
These two hyper-parameters are shared by all nodes.
Generating Observed and Latent Quantities in sets X &Ι
After the model parameters (having prior) have been generated, we then use model parameters to generate observed and latent quantities. The part is critical in the generation process.
- We first sample the community label i z of each node i v from a multinomial distribution independently. The multinomial distribution is defined as:
- Given the community labels zi and zj of nodes vi and vj, respectively, we sample indicator ij a from a Bernoulli distribution, defined as:
This describes the fitting of the model to network topology from the degree-corrected stochastic block model [Karrer and Newman, 2011], where ( ) rl c c is the block matrix, and di is the degree of vi. This model performs well in fitting network topology.
- Given the community label i z of node vi, we need to sample the general topic label gik of attribute wik of node vi from a multinomial distribution, defined as:
The meaning of H has been explained in last subsection.
- Then, in order to determine whether each attribute wik of node vi is generated from a general topic or a specialized topic, we utilize a binary variable ik from a Bernoulli distribution parameterized by i , defined as:
The value of δik determines the generative process in the next step. That is:
- If 0 ik , wik will be generated by the general topic. Recall that, in step 3 of this subsection we have identified this general topic. So here we need to generate the attribute wik of node vi. To be specific, we sample each attribute from a multinomial distribution, defined as:
In g B ( ) g ek E m , ( 1 | ) g ek ik ik p w g e denotes the probability that the e th general topic generates the k th attribute, which is independent of node vi subject to , 1 1 ik m g g k k and , [0,1] ik g g k .
- If 1 ik , wik will be generated by a specialized topic, given the general topic label gik of the attribute wik. So first we need to sample the specialized topic label from a multinomial distribution, which is defined as:
The specific meaning of F has been explained in step 3 of the last subsection. We then generate the attribute wik of node vi from a multinomial distribution, defined as:
In s B ( ) s dk D m , ( 1 | ) s dk ik ik p w s d denotes the probability that the d th specialized topic generates the k th attribute of node vi, subject to , 1 1 ik m s s k k and , [0,1] ik s s k .
Here the choice of Dirichlet and Beta distribution as priors for π , H, F and ω are not arbitrary. The Dirichlet and Beta distribution are conjugate priors of multinomial and Bernoulli distribution, respectively. It will give a closed-form expression for the posterior and provide mathematical convenience when we derive inference.
2.2 Model Formulation
We note that the generative process implicitly makes a number of conditional independence assumptions among all parameters. In Figure 2, each rectangle denotes the repetition of the enclosed structure, where the number of repetitions is indicated by the subscript. The set of conditional independence assumptions can be readily read off the graph. A node is independent of all its non-descendants given its parent nodes.
Given the hyper-parameters and the model parameters without prior, we decompose the joint distribution over other parameters using the probability chain rule and apply the conditional independence assumptions, as follows:
The sub functions in (12) have all been defined in (1) - (11). We abbreviate (12) to (X, , | , ) p in the following.
3 Learning the Model
We give an efficient variational expectation-maximization (EM) algorithm to train the model. We first introduce our variational inference process, and then our algorithm.
3.1 Variational Inference
The Bayesian model proposed in the previous section defines a joint distribution (X, , | , ) p . Based on this model, the problem of clustering observed quantities X = (A, W) can be transformed into a standard probabilistic inference problem, i.e. finding the maximum a posteriori (MAP) configuration of the latent quantities conditioning on A and W, the posterior function is then defined as:
For brevity, we abbreviate this to ( , | , , ) p , where
Since the calculation of (13) is intractable, our basic idea is to approximate the posterior by a novel variational distribution function q. According to the theory of variational optimization, the variational distribution q can be defined as:
(z | ) ( | T) (G | P) (S| ) (π | ξ) (H | A) (F | O) (ω | ) q q q q q q q q Here is a set of variational parameters. The sub distributions in (14) take exactly the similar parametric forms as the sub functions in (1) - (11). The variational parameters in set are free to vary, while the hyper-parameters in are fixed throughout the generative process. Three variational parameters need to be emphasized. The first is ( ) ir n c , where ( ) ir i p z r is the posterior of node vi belonging to community r. The second is , P ( ) ik e n m E , which denotes the probability of wik belonging to general topic e. The third is , =( ) ik d n m D , which denotes the probability that wik belongs to specialized topic d on the premise that 1 ik .
Our goal is now to find the variational function ( , ') q | closest to the real posterior ( , | X, , ) p . We adopt the Kullback-Leibler (KL) divergence to measure the distance between the variational function and real posterior, defined as
Note that the KL divergence is a function of the variational parameters { T,P, , ,A O, } , ξ , and model parameters { ,B ,B } g s . Our problem is to find the optimal state of these parameters that minimizes this KL divergence. However, since the calculation of the KL divergence involves the real posterior ( , | X, , ) p , this cannot be solved directly. So instead of directly minimizing the KL divergence, we solve an equivalent maximization problem. The objective function of this maximization problem is defined as:
Since the sum of these two functions is a constant, that is:
In order to maximize the objective function ( ) L q , we need to take the derivatives of ( ) L q with respect to the variational parameters { T,P, , ,A O, } , ξ , and model parameters { ,B ,B } g s , and set these derivatives to zeros.
We get the expressions of parameters needing to be updated.
where ( ) is the Digamma function.
3.2 Iterative Optimization Algorithm
The process of TLSC is shown in Alg. 1. We can use: 1) matrix to derive the final community label of each node, 2) matrix H and F to find the general topic of each community and which specialized topics belong to the same general topic, 3) the product of H and F (i.e. HF) to find the specialized topic of each community, and 4) g B and s B to find the key words generated by two-level topics, respectively.
Alg. 1: Process of TLSC
Input: A, W, c, E, D, a threshold , countmax
Output:
g s ,H,F,B ,B
- Initialize variational and model parameters randomly
- count ← 1
- repeat:
- (b) Compute ( ) ( ) count L q
(a) Update , ξ, ,P, ,A,O,T, , ,B B s g via (16) - (25)
(c) count ← count+1
- Compute H and F using the derived ,P,
Until ( ) ( 1) ( ) ( ) count count L q L q or count > countmax
4 Experiments
We first use an online music system to assess the interpretabilities of this model. We then evaluate our approach on 8 real networks in comparison with 8 state-of-the-art methods.
4.1 A Case Study
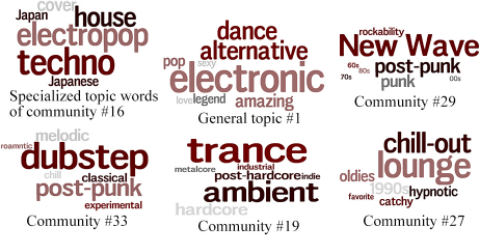
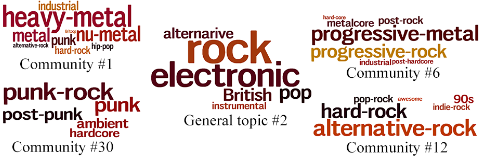
The dataset we use in this case study analysis is the British online music platform Last.fm [Cantador, 2016]. The dataset has 1,892 users and 11,946 attributes, the connections between them form a friendship network. Since no ground-truth is known regarding user communities in the network, we set the number of communities and specialized topics to 38 (c = 38, D = 38) as done in [Wang et al., 2016]. We also performed some experiments to vary the number of general topics, and found that highly overlapping general topics will appear when the number of general topics is greater than 4. So we set this number to 4 (E = 4). We found four groups of communities under different general topics. The two-level semantics of these four groups of communities are shown in Figures 3, 4, 5 and 6, respectively. Due to space limitation, we only show some of the communities in each group.
Figure 3 shows a group of communities of electronic music lovers. These words in general topic #1 can be used to describe all types of electronic music. The communities sharing this general topic are fans of different branches of electronic music. Community #16 is a group of "high techno" music lovers, and the highest probability word in this community is "techno". Community #33 is a group of fans of "dubstep" music, and the origin of dubstep is related to "post-punk". "New wave" is also a branch of electronic music, shown as community #29. Community #27 gathers the "lounge" music fans, and this form of music is also called "chill-out". "Trance" fans gather in community #19.
Communities in Figure 4 are all related to rock music. Words of general topic #2 reflect detailed keywords of rock music. Specially, community #1 gathers "heavy-metal" music lovers. "Punk" fans gather in community #30. "Progressive-rock" fans are in community #6. Community #12 is a group of "alternative-rock" fans.
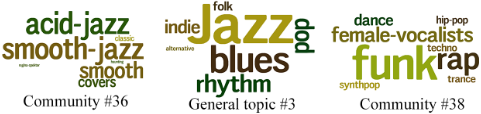
According to the words of general topic #3 in Figure 5, we can realize that community #36 and #38 both belong to "jazz" music. The "acid-jazz" and "smooth-jazz" shown by the specialized topic words of community #36 both are fusion jazz. Community #38 gathers lovers of "funk".
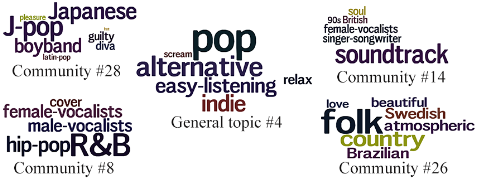
Words of general topic #4 in Figure 6 show that this is a group of pop music enthusiasts. Specialized topic of community #28 is about Japanese pop, generally called "J-pop". Community #8 gathers fans of "R&B" and "hip-pop". "Soundtrack" and "Folk" lovers gather in community #14 and #26, respectively.
In summary, this case study validates that our model can find related communities with similar interests, describing their shared characteristics with general topic words and the distinct interest tendencies of each community with specialized topic. We can get more appropriate explanations for communities by differentiating these two-level topics clearly.
4.2 Quality Evaluation on Real-World Networks
Here we evaluate the performance of TLSC for detecting communities on eight real-world networks with ground truth of communities, as shown in Table 2. We consider three types of existing community detection methods for comparison. The first type uses network topology alone, including DCSBM [Karrer and Newman, 2011] and BigCLAM [Yang and Leskovec, 2013]. The second, including SMR [Hu et al., 2014], exploits only content information, i.e. node attributes. The last type uses information of network topology and node contents together, including PCL-DC [Yang et al., 2009], Block-LDA [Balasubramanyan and Cohen, 2011], CESNA [Yang et al., 2013], DCM [Pool et al., 2014] and SCI [Wang et al., 2016]. All the above methods require the number of communities to be pre-specified, as well as our method. We set it to the same value that in the ground truth. In our algorithm, we set the number of specialized topics and general topics to 1 and 1/2 of the number of communities.
We used 4 well-known metrics in community detection for evaluation. Accuracy (AC) and normalized mutual information (NMI) [Liu et al., 2012] are the first group of evaluation metrics. But some baselines aim at finding overlapping communities which cannot be evaluated using AC and NMI. We also adopt a new group of evaluation metrics, which includes F-score and Jaccard similarity [Yang et al., 2013].
| Datasets | n | e | m | c Descriptions [Leskovec, 2016] |
|---|---|---|---|---|
| Texas | 187 | 328 | 1,703 | 5 The WebKB network consists of four subnetworks from four |
| Cornell | 195 | 304 | 1,703 | American universities, which are Texas, Cornell, Washington 5 |
| Washington | 230 | 446 | 1,703 | and Wisconsin, respectively. 5 |
| Wisconsin | 265 | 530 | 1,703 | 5 |
| 171 | 796 | 578 | 7 Largest subnetwork (id 629863) in Twitter data | |
| Cite | 3,312 | 4,732 | 3,703 | 6 A Citeseer citation network |
| Cora | 2,708 | 5,429 | 1,433 | 7 A Cora citation network |
| Pubmed | 19,729 | 44,338 | 500 | 3 Publications in PubMed on diabetes |
| Metrics | Methods | Datasets | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| (%) | Type | Name | Texas | Cornell | Washington | Wisconsin | Cora | Cite | Pubmed | |
| Topo | DCSBM | 48.09 | 37.95 | 31.80 | 32.82 | 60.49 | 26.57 | 38.48 | 53.64 | |
| Cont | SMR | 47.54 | 31.79 | 49.77 | 40.84 | 38.27 | 30.28 | 30.87 | 39.95 | |
| AC | Both | Block-LDA | 54.10 | 46.15 | 39.17 | 49.62 | 35.80 | 24.35 | 25.52 | 49.01 |
| Both | PCL-DC | 38.80 | 30.26 | 29.95 | 30.15 | 56.79 | 24.85 | 34.08 | 63.55 | |
| Both | SCI | 62.30 | 45.64 | 51.15 | 50.38 | 50.62 | 27.98 | 40.62 | N/A | |
| Both | TLSC | 65.02 | 47.69 | 51.61 | 49.23 | 62.87 | 47.62 | 35.74 | 61.38 | |
| Topo | DCSBM | 16.65 | 9.69 | 9.87 | 3.14 | 57.48 | 4.13 | 17.07 | 12.28 | |
| Cont | SMR | 3.55 | 8.45 | 7.3 | 7.21 | 3.26 | 1.18 | 13.28 | 0.0367 | |
| NMI | Both | Block-LDA | 4.21 | 6.81 | 3.69 | 10.09 | 0 | 2.42 | 1.41 | 6.58 |
| Both | PCL-DC | 10.37 | 7.23 | 5.66 | 5.01 | 52.64 | 2.99 | 17.54 | 26.84 | |
| Both | SCI | 17.84 | 11.44 | 12.37 | 17.03 | 43.00 | 4.87 | 19.26 | N/A | |
| Both | TLSC | 23.92 | 13.61 | 17.63 | 16.65 | 49.14 | 33.20 | 23.16 | 19.63 | |
| Metrics | Methods | Datasets | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|
| (%) | Type | Name | Texas | Cornell | Washington | Wisconsin | Cora | Cite | Pubmed | |
| Topo | BigCLAM | 20.64 | 13.23 | 13.35 | 12.84 | 39.79 | 9.30 | 18.89 | 7.72 | |
| F-score | Both | CESNA | 23.54 | 23.48 | 21.91 | 23.17 | 43.82 | 3.38 | 31.05 | 27.97 |
| Both | DCM | 11.15 | 14.38 | 12.45 | 10.45 | 10.57 | 2.50 | 3.43 | 0.38 | |
| Both | TLSC | 46.92 | 38.47 | 38.67 | 49.23 | 49.85 | 45.74 | 31.08 | 38.85 | |
| Topo | BigCLAM | 12.18 | 7.18 | 7.25 | 7.01 | 26.13 | 5.01 | 10.89 | 4.04 | |
| Jaccard | Both | CESNA | 13.57 | 13.47 | 12.40 | 13.14 | 29.63 | 1.73 | 19.10 | 16.26 |
| Both | DCM | 6.03 | 7.95 | 6.72 | 5.54 | 5.75 | 1.27 | 1.76 | 0.19 | |
| Both | TLSC | 34.38 | 25.14 | 26.10 | 28.75 | 36.65 | 31.14 | 18.80 | 29.15 | |
The experimental results are shown in Tables 3 and 4 using different types of metrics. TLSC basically almost always surpasses state-of-the-art. We can conclude that the hierarchical use of contents indeed improves the accuracy of community detection. This may be because contents intrinsically have more than one level (we used two levels here) and we use more information in this new model.
5 Conclusion
In this paper, we have proposed a probabilistic generative model on attributed networks, which aims at finding community structures as well as the two-level semantics description for communities. This novel Bayesian model is trained through the variational expectation-maximization framework. Our model can 1) automatically recognize that words describing the attributes are either from general or specialized topics; 2) find the general topic and specialized topic for each community, and find which communities related to the same area share a common general topic; and 3) if some topology information is missing or noisy, the full use of semantics can further help finding more accurate community structures. A case study shows the good performance of TLSC for semantic interpretation of communities; comparison experiments on community detection demonstrate the superiority of TLSC in finding community structures.
Acknowledgments
This work was supported by National Key R&D Program of China (No. 2017YFC0820106), Natural Science Foundation of China (No. 61772361, 61502334, 61402070, 61702435) and Hong Kong General Research Fund (GRF) Project No. HKBU 1220091.
@inproceedings{ijcai2018p507,
  title     = {Finding Communities with Hierarchical Semantics by Distinguishing General and Specialized topics},
  author    = {Zhang, Ge and Jin, Di and Gao, Jian and Jiao, Pengfei and Fogelman-Soulié, Françoise and Huang, Xin},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {3648--3654},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/507},
  url       = {https://doi.org/10.24963/ijcai.2018/507},
}
TY - CPAPER TI - Finding Communities with Hierarchical Semantics by Distinguishing General and Specialized topics AU - Zhang, Ge AU - Jin, Di AU - Gao, Jian AU - Jiao, Pengfei AU - Fogelman-Soulié, Françoise AU - Huang, Xin T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 3648 EP - 3654 DO - 10.24963/ijcai.2018/507 UR - https://doi.org/10.24963/ijcai.2018/507 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





