
Cost-aware Cascading Bandits
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 3228-3234.
https://doi.org/10.24963/ijcai.2018/448
Keywords
- Machine Learning: Online Learning
- Uncertainty in AI: Sequential Decision Making
- Machine Learning: Cost-Sensitive Learning
Abstract
In this paper, we propose a cost-aware cascading bandits model, a new variant of multi-armed bandits with cascading feedback, by considering the random cost of pulling arms. In each step, the learning agent chooses an {\it ordered} list of items and \congr{examines} them sequentially, until certain stopping condition is satisfied. Our objective is then to maximize the expected {\it net reward} in each step, i.e., the reward obtained in each step minus the total cost incurred in examining the items, by deciding the ordered list of items, as well as when to stop examination. We study both the offline and online settings, depending on whether the state and cost statistics of the items are known beforehand. For the offline setting, we show that the Unit Cost Ranking with Threshold 1 (UCR-T1) policy is optimal. For the online setting, we propose a Cost-aware Cascading Upper Confidence Bound (CC-UCB) algorithm, and show that the cumulative regret scales in $O(\log T)$. We also provide a lower bound for all $\alpha$-consistent policies, which scales in $\Omega(\log T)$ and matches our upper bound. The performance of the CC-UCB algorithm is evaluated with both synthetic and real-world data.
- [Anantharam et al., 1987] Venkatachalam Anantharam, Pravin Varaiya, and Jean Walrand. Asymptotically effi- cient allocation rules for the multiarmed bandit problem with multiple plays-part i: Iid rewards. IEEE Transactions on Automatic Control, 32(11):968-976, 1987.
- [Audibert and Bubeck, 2010] Jean-Yves Audibert and Sébastien Bubeck. Best Arm Identification in Multi- Armed Bandits. In the 23th Conference on Learning Theory, Haifa, Israel, June 2010.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine learning, 47(2-3):235-256, 2002.
- [Badanidiyuru et al., 2013] Ashwinkumar Badanidiyuru, Robert Kleinberg, and Aleksandrs Slivkins. Bandits with knapsacks. In Proceedings of the IEEE 54th Annual Symposium on Foundations of Computer Science, pages 207-216, 2013.
- [Bubeck et al., 2009] Sébastien Bubeck, Rémi Munos, and Gilles Stoltz. Pure exploration in multi-armed bandits problems. In Proceedings of the 20th International Con- ference on Algorithmic Learning Theory, pages 23-37, 2009.
- [Burnetas and Kanavetas, 2012] Apostolos Burnetas and Odysseas Kanavetas. Adaptive policies for sequential sampling under incomplete information and a cost con- straint. Applications of Mathematics and Informatics in Military Science, page 97-112, 2012.
- [Burnetas et al., 2017] Apostolos Burnetas, Odysseas Kanavetas, and Michael N Katehakis. Asymptotically optimal multi-armed bandit policies under a cost con- straint. Probability in the Engineering and Informational Sciences, 31(3):284-310, 2017.
- [Ding et al., 2013] Wenkui Ding, Tao Qiny, Xu-Dong Zhang, and Tie-Yan Liu. Multi-armed bandit with bud- get constraint and variable costs. In Proceedings of the Twenty-Seventh AAAI Conference on Artificial Intel- ligence, pages 232-238, 2013.
- [Guha and Munagala, 2007] Sudipto Guha and Kamesh Mu- nagala. Approximation algorithms for budgeted learning problems. In Proceedings of the Thirty-ninth Annual ACM Symposium on Theory of Computing, pages 104-113, New York, NY, USA, 2007. ACM. [Int, 2011] "Internet mathematics". https: //academy.yandex.ru/events/data_ analysis/relpred2011/, 2011. Link
- [Kalathil et al., 2014] D. Kalathil, N. Nayyar, and R. Jain. Decentralized learning for multiplayer multiarmed ban- dits. IEEE Transactions on Information Theory, 60(4):2331-2345, April 2014.
- [Komiyama et al., 2015] Junpei Komiyama, Junya Honda, and Hiroshi Nakagawa. Optimal regret analysis of thomp- son sampling in stochastic multi-armed bandit problem with multiple plays. In Proceedings of the 32nd Inter- national Conference on Machine Learning, pages 1152- 1161, Lille, France, Jul 2015. Kveton et al., 2015a] Branislav Kveton, Csaba Szepesvari, Zheng Wen, and Azin Ashkan. Cascading bandits: Learn- ing to rank in the cascade model. In Proceedings of the 32nd International Conference on Machine Learning (ICML-15), pages 767-776, 2015.
- [Kveton et al., 2015b] Branislav Kveton, Zheng Wen, Azin Ashkan, and Csaba Szepesvari. Combinatorial cascading bandits. In Advances in Neural Information Processing Systems, pages 1450-1458, 2015.
- [Radlinski et al., 2008] Filip Radlinski, Robert Kleinberg, and Thorsten Joachims. Learning diverse rankings with multi-armed bandits. In In 25th Intl. Conf. on Machine Learning (ICML), pages 784-791, 2008.
- [Slivkins et al., 2013] Aleksandrs Slivkins, Filip Radlinski, and Sreenivas Gollapudi. Ranked bandits in metric spaces: Learning diverse rankings over large document collec- tions. J. Mach. Learn. Res., 14(1):399-436, February 2013.
- [Streeter and Golovin, 2008] Matthew Streeter and Daniel Golovin. An online algorithm for maximizing submodular functions. In Advances in Neural Information Processing Systems 21, pages 1577-1584. 2008.
- [Tran-Thanh et al., 2010] Long Tran-Thanh, Archie C. Chapman, Enrique Munoz de Cote, Alex Rogers, and Nicholas R. Jennings. Epsilon-first policies for budget-limited multi-armed bandits. In AAAI, 2010.
- [Tran-Thanh et al., 2012] Long Tran-Thanh, Archie Chap- man, Alex Rogers, and Nicholas R. Jennings. Knapsack based optimal policies for budget-limited multi-armed bandits. In Proceedings of the Twenty-Sixth AAAI Con- ference on Artificial Intelligence, pages 1134-1140, 2012.
- [Xia et al., 2015] Yingce Xia, Haifang Li, Tao Qin, Nenghai Yu, and Tie-Yan Liu. Thompson sampling for budgeted multi-armed bandits. In Proceedings of the 24th Interna- tional Conference on Artificial Intelligence, pages 3960- 3966, 2015. IJCAI
- [Xia et al., 2016a] Yingce Xia, Wenkui Ding, Xu-Dong Zhang, Nenghai Yu, and Tao Qin. Budgeted bandit prob- lems with continuous random costs. In Geoffrey Holmes and Tie-Yan Liu, editors, Asian Conference on Machine Learning, volume 45, pages 317-332, Hong Kong, Nov 2016.
- [Xia et al., 2016b] Yingce Xia, Tao Qin, Weidong Ma, Nenghai Yu, and Tie-Yan Liu. Budgeted multi-armed ban- dits with multiple plays. In Proceedings of the Twenty- Fifth International Joint Conference on Artificial Intelli- gence, pages 2210-2216. AAAI Press, 2016. IJCAI
- [Zong et al., 2016] Shi Zong, Hao Ni, Kenny Sung, Nan Rosemary Ke, Zheng Wen, and Branislav Kveton. Cascading bandits for large-scale recommendation prob- lems. In Proceedings of the Thirty-Second Conference on Uncertainty in Artificial Intelligence, pages 835-844, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In this paper, we introduce a new cost-aware cascading bandits (CCB) model. We consider a set of K items (arms) denoted as [K] = {1, 2, . . . ,K}. Each item i ∈ [K] has two possible states 0 and 1, which evolve according to an independent and identically distributed (i.i.d.) Bernoulli random variable. The learning agent chooses an ordered list of items in each step and examines them sequentially until certain stopping condition is met. The reward that the learning agent receives in a step equals one if one of the examined items in that step has state 1; Otherwise, it equals zero. We associate a random cost for examining each item. The overall reward function, termed as net reward, is the reward obtained in each step minus the total cost incurred in examining the items before the learner stops.
The CCB model is a natural but technically non-trivial extension of cascading bandits [Kveton et al., 2015a], and is a more suitable model in many fields, including the following examples.
- Opportunistic spectrum access. In cognitive radio systems, a user is able to probe multiple channels sequentially at the beginning of a transmission session before it decides to use at most one of the channels for data transmission. Assuming the channel states evolve between busy and idle in time, the user gets a reward if there exists one idle channel for transmission. The cost then corresponds to the energy and delay incurred in probing each channel.
- Dynamic treatment allocation. In clinic trials, a doctor must assign one of several treatments to a patient in order to cure a disease. The doctor accrues information about the outcome of previous treatments before making the next assignment. Whether a treatment cures the disease can be modeled as a Bernoulli random variable, and the doctor gets a reward if the patient is cured. The doctor may not only be interested in the expected effect of the treatment but also its riskiness, which can be interpreted as the cost of the treatment.
In both examples, the net reward in each step is determined not only by the subset of items included in the list, but also by the order that they are pulled. Intuitively, if the costs in examining the items are homogeneous, we would prefer to have the channel with higher probability to be idle, or the more effective treatment ranked higher in the list. Then, the learner would find an available channel or cure the patient after a few attempts and then stop examination, thus saving the cost without decreasing the reward. However, for more general cases where the costs are heterogeneous or even random, the optimal solution is not immediately clear.
In this paper, we consider a general cost model where the costs of pulling arms are heterogeneous and random, and investigate the corresponding solutions. Our main contributions are three-fold:
- We propose a novel CCB model, which has implications in many practical scenarios, such as opportunistic spectrum access, dynamic treatment allocation, etc. The CCB model is fundamentally different from its costoblivious counterparts, and admits a unique structure in the corresponding learning strategy.
- Second, with a priori statistical knowledge of the arm states and the costs, we explicitly identify the special structure of optimal policy (coined as the offline policy), which serves as the baseline for the online algorithm we develop. The optimal offline policy, called Unit Cost Ranking with Threshold 1 (UCR-T1), is to rank the arms based the statistics of their states and costs, and pull those above certain threshold sequentially until a state 1 is observed.
- Third, we propose a cost-aware cascading Upper Confidence Bound (CC-UCB) algorithm for the scenario when prior arm statistics are unavailable, and show that it is order-optimal by establishing order-matching upper and lower bounds on the regret. Our analysis indicates that the UCB based algorithm performs well for ranking the arms, i.e., the cumulative regret of ranking the desired arms in a wrong order is bounded.
2 Related Literature
There have been some attempts that take the cost of pulling arms and budget constraint into the multi-armed bandit (MAB) framework recently. They can be summarized in two types. In the first type [Audibert and Bubeck, 2010; Bubeck et al., 2009; Guha and Munagala, 2007], pulling each arm in the exploration phase has a unit cost and the goal is to find the best arm given the budget constraint on the total number of exploration arms. This type of problems is also referred to as "best-arm identification" or "pure exploration". In the second type, pulling an arm is always associated with a cost and constrained by a budget, no matter in the exploration phase or the exploitation phase, and the objective usually is to design an arm pulling algorithm in order to maximize the total reward with given cost or budget constraint. References [Tran-Thanh et al., 2010; Tran-Thanh et al., 2012; Burnetas and Kanavetas, 2012] consider the problem when the cost of pulling each arm is fixed and becomes known after the arm is used once. A sample-path cost constraint with known bandit dependent cost is considered in [Burnetas et al., 2017]. References [Ding et al., 2013; Xia et al., 2016a; Xia et al., 2015; Xia et al., 2016b] study the budgeted bandit problems with random arm pulling costs. Reference [Badanidiyuru et al., 2013] considers the knapsack problem where there can be more than one budget constraints and shows how to construct polices with sub-linear regret.
In the proposed CCB model, the net reward function is related to the cost of pulling arms and the learning agent faces a "soft constraint" on the cost instead of a fixed budget constraint. If the learner only pulls one arm in each step, the cost of pulling an arm can be absorbed into the reward of that arm (i.e., net reward). Our model then reduces to a conventional MAB model for this case. In this paper, however, we are interested in the scenario where the learner is allowed to sequentially pull a number of arms in each step, and the reward obtained in each step cannot be decomposed into the summation of the rewards from the pulled arms. Thus, the cost cannot be simply absorbed into the reward of individual arms. The intricate relationship between the cost and the reward, and its implications on the optimal policy require more sophisticated analysis, and that is the focus of this paper.
MAB with more than one arm to pull in each step has been studied in multiple-play MAB (MP-MAB) models in [Anantharam et al., 1987; Komiyama et al., 2015; Kalathil et al., 2014], cascading bandits (CB) models in [Kveton et al., 2015a; Kveton et al., 2015b; Zong et al., 2016], and ranked bandits (RB) models in [Radlinski et al., 2008; Streeter and Golovin, 2008; Slivkins et al., 2013]. Under MP-MAB, the learner is allowed to pull L out of K arms, and the reward equals to the summation of the rewards from individual arms. Although the proposed CCB model also allows the user to pull multiple arms in each step, the reward is not accumulative, thus leading to different solutions.
The CCB model proposed in this paper is closely related to the CB model investigated in [Kveton et al., 2015a]. Specifically, [Kveton et al., 2015a] considers the scenario where at each step, L out of K items are listed by a learning agent and presented to a user. The user examines the ordered list from the first to the last, until he/she finds the first attractive item and clicks it. The system receives a reward if the user finds at least one of the items to be attractive. Our model has the same reward model as that in the cascading bandits setting. However, there are also important distinctions between them. In the CB model in [Kveton et al., 2015a], the total number of items to be examined each step is fixed, and the cost of pulling individual arms is not considered. As a result, the same subset of items on a list will give the same expected reward, irrespective of their order on the list. However, for the proposed CCB model, the ranking of the items on a list does affect the expected net reward. Therefore, the structure of the optimal offline policy and the online algorithm we develop are fundamentally different from those in [Kveton et al., 2015a].
The proposed CCB model is also related to RB in the sense that the order of the arms to pull in each step matters. A crucial feature of RB is that the click probability for a given item may depend on the item and its position on the list, as well as the items shown above. However, in our case, we assume the state of an arm evolves in an i.i.d. fashion from step to step.
3 SystemModel and ProblemFormulation
Consider a K-armed stochastic bandit system where the state of each arm evolves independently from step to step. Let Xi,t be the state of arm i ∈ [K] in step t. Then, Xi,t ∈ {0, 1} evolves according to an i.i.d. Bernoulli distribution with parameter θi. Denote Yi,t as the cost of pulling arm i in step t, where Yi,t ∈ [0, 1] evolves according to an i.i.d. unknown distribution with E[Yi,t] = ci.
In step t, the learning agent chooses an ordered list of arms from [K] and pull the arms sequentially. Once an arm is pulled, its state and the pulling cost are revealed instantly. Denote the ordered list as It := {It(1), It(2), . . . , It(|It|)}, where It(i) is the ith arm to be pulled, and |It| is the cardinality of It. Denote ˜ It as the list of arms that have been actually pulled in step t. We have ˜ It ⊆ It.
The reward that the learning agent receives in step t depends on both ˜ It and {Xi,t}i∈˜ It . Specifically, it can be expressed as 1- ∏| ˜ It | i=1 (1-X˜ It(i),t ), i.e., the learning agent gets reward one if one of the arms that have been examined in step t has state 1; Otherwise, it equals zero. The cost that is incurred at step t also depends on ˜ It, and it can be expressed as ∑| ˜ It | i=1 Y˜ It(i),t .
With a given ordered list It, ˜ It is random and its realization depends on the observed Xi,t, Yi,t and the stopping condition in general. Denote the net reward received by the learning agent at step t as rt := 1 - ∏|˜ It | i=1 (1 - X˜ It(i),t ) -
∑| ˜ It | i=1 Y˜ It(i),t . Define the per-step regret regt := r∗ t - rt, where r∗ t is the net reward that would be obtained at step t if the statistics of {Xi,t}i and {Yi,t}i were known beforehand and the optimal It and stopping condition were adopted. Denote the observations up to step t - 1 as Ht-1 . Then, Ht-1 := ∪t-1 τ=1 {Xi,τ , Yi,τ}i∈˜ Iτ . Without a priori statistics about {Xi,t} and {Yi,t}, our goal is to design an online algorithm to decide It based on observations obtained in previous steps Ht-1 , and ˜ It based on observed states and costs in step t, so as to minimize the cumulative regret R(T) := E [∑Tt=1 regt ] .
In the following, we will first identify the structure of the optimal offline policy with a priori arm statistics, and then develop an online algorithm to learn the channel statistics and track the optimal offline policy progressively.
4 Optimal Offline Policy
We first study the optimal offline policy for the non-trivial case where ci > 0. We assume that the arm statistics {θi}Ki=1 and {ci}Ki=1 are known to the learning agent as prior knowledge. However, the instantaneous realization of rewards and costs associated with arms are unknown to the learning agent until they are pulled. Under the assumption that the distributions of arm states and costs are i.i.d. across steps, the optimal offline policy should remain the same for different steps. Thus, in this section, we drop the step index and focus on the policy at an individual step.
According to the definition of the cascading feedback, for any ordered list, the reward in each step will not grow after the learner observes an arm with state 1. Therefore, to maximize the net reward, the learner should stop examining the rest of the list when a state 1 is observed, in order to save the cost of examination. Let the ordered list under the optimal offline policy be I ∗ , then
We note that the expected net reward structure is more complex than the standard multi-armed bandits problem or the standard cascading model, and the optimal offline policy is not straightforward. By observing (1), we note that there are both a subtraction part θI(i) - cI(i) and a product part ∏i-1 j=1 (1 - θI(j)) inside each summation term. On one hand we should choose large θi to increase the value of θi - ci, but on the other hand we should not choose an arm with a big gap between θi and ci, because big θi contributes to smaller 1-θi. In the extreme case where no cost is assigned to arms, the optimal policy is to pull all arms in any order, and the problem becomes trivial.
For simplicity of the analysis, we make the following assumptions:
Assumption 1 1) θi ̸= ci, for all i ∈ [K]. 2) There exists a constant ϵ > 0, such that ci > ϵ for all i ∈ [K].
Under Assumptions 1, we present the optimal offline policy in Theorem 1, which is called Unit Cost Ranking with Threshold 1 (UCR-T1), as it ranks the expected reward normalized by the average cost and compares against threshold one.
Theorem 1 Arrange the arm indices such that
Then, I ∗ = {1∗ , 2∗ , . . . , L∗ }, and the corresponding optimal per-step reward is E[r∗ ] = ∑Li=1 (θi∗ - ci∗ ) ∏i-1 j=1 (1 - θj ∗ ).
Due to space limitation, the proof of Theorem 1 is omitted. Theorem 1 indicates that ranking the arms in a descending order of θi ci and only including those with θi ci > 1 in I ∗ achieves a balanced tradeoff between the subtraction θi - ci and the product ∏(1 - θi). This is an important observation which will also be useful in the online policy design.
5 Online Policy
With the optimal offline policy explicitly described in Theorem 1, in this section, we will develop an online algorithm to maximize the cumulative expected net rewards without a priori knowledge of {θi}Ki=1 and {ci}Ki=1 .
Unlike the previous work on MAB, the net reward structure in our setting is rather complex. One difficulty is that the learner has to rank θi/ci and compare it with threshold 1 for exploitation. A method to deal with this difficulty is using an UCB-type algorithm following the Optimism in Face of Uncertainty (OFU) principle [Auer et al., 2002]. More specifically, we use an UCB-type indexing policy to rank the arms. Though the upper confidence bound is a biased estimation of the statistics, it will converge to the expectation asymptotically.
5.1 Algorithm and Upper Bound
The cost-aware cascading UCB (CC-UCB) algorithm is described in Algorithm 1. The costs are assumed to be random but the learning agent has no knowledge of their distributions. We use Ni,t to track the number of steps that arm i has been pulled up to step i, and ˆ θi,t, ˆ ci,t to denote the sample average of θi and ci at step t, respectively. The UCB padding term on the state and cost of arm i at step t is ui,t := √ α log t Ni,t , where α is a positive constant no less than 1.5.
CC-UCB adopts the OFU principle to construct an upper bound of the ratio θi ci . The main technical difficulty and Input: ϵ, α.
Algorithm 1 Cost-aware Cascading UCB (CC-UCB)
1: Initialization: Pull all arms in [K] once, and observe their states and costs. 2: while t do 3: for i = 1 : K do 4: Ui,t = ˆ θi,t + ui,t; 5: Li,t = max(ˆ ci,t - ui,t, ϵ); 6: if Ui,t/Li,t > 1 then i → It; 7: end if 8: end for 9: Rank arms in It in the descending order of Ui,t Li,t . 10: for i = 1 : |It| do 11: Pull arm It(i) and observe XIt(i),t, YIt(i),t; 12: i → ˜ It; 13: if XIt(i),t = 1 then break; 14: end if 15: end for 16: Update Ni,t, ˆ θi,t, ˆ ci,t for all i ∈ ˜ It . 17: t = t + 1; 18: end whilecorrespondingly our novel contribution, however, lies in the theoretical analysis. This is because we have to deal with two types of regret: the regret caused by pulling "bad" arms (θi < ci); and that caused by pulling "good" arms in a wrong order. To the authors' best knowledge, the latter component has not been addressed in the bandit literature before, and is technically challgening. The overall regret analysis of CCUCB is thus complicated and non-trivial.
We have the following main result for the cumulative regret upper bound of Algorithm 1.
Theorem 2 Denote ∆i := ci - θi. The accumulative regret under Algorithm 1 is upper bounded as follows:
where [K]\I ∗ includes all items in [K] except those in I ∗ .
The proof of Theorem 2 is deferred to Section 5.2.
Remark: In Theorem 2, the upper bound depends on (ci - θi)2 , while conventional upper bounds for UCB algorithms usually depend on the gap between the ranking parameters. It is because the regret caused by pulling "good" arms in a wrong order is bounded, as shown in Section 5.2; Thus, the regret is mainly due to pulling "bad" arms, which is determined by arm i itself (Ui,t > Li,t) and not related to the θ/c gap between the best arm and arm i. When cis are known a priori, the upper bound can be reduced by a factor of 4.
5.2 Analysis of the Upper Bound
Define Et := {∃i ∈ [K], |ˆ θi,t - θi| > ui,t or |ˆ ci,t - ci| > ui,t}, i.e. there exists an arm whose sample average of reward or cost lies outside the corresponding confidence interval. Denote ¯ Et as the complement of Et. Then, we have the following observations.
Lemma 1 If 1( ¯ Et) = 1, then, under Algorithm 1, all arms in I ∗ will be included in It.
Proof: According to Algorithm 1, arm i will be included in It if Ui,t Li,t ≥ 1. When 1(Et) = 0, we have |ˆ θi,t - θi| < ui,t, |ˆ ci,t - ci| < ui,t. Thus, ˆ θi,t + ui,t ≥ θi, ˆ ci,t - ui,t ≤ max{ˆ ci,t - ui,t, ϵ} ≤ ci, which implies that Ui,t Li,t ≥ 1. ■
Lemma 2 Under Algorithm 1, we have ∑Tt=1 E[1(Et)] ≤ ψ := K (1 + 4π2 3 ).
Uj∗,t Lj∗,t }, which represents the event that arms from I ∗ are not ranked in the correct order. Since those arms are pulled linearly often in order to achieve small regret, intuitively, Bt happens with small probability.
The proof of Lemma 2 is based on Hoeffding's inequality. The proof of Lemma 3 is derived based on the observation that the arms in I ∗ are pulled linearly often if ¯ Et is true, and the corresponding confidence intervals ui,t shrinks fast in time. As ui,t decreases below certain threshold, ¯ Bt happens. The detailed proofs of Lemma 2 and Lemma 3 are omitted due to space limitation.
Lemma 4 Consider an ordered list It that includes all arms from I ∗ with the same relative order as in I ∗ . Then, under Algorithm 1, E[regt | ˜ It] ≤ ∑i∈˜ It\I ∗ ci.
Proof: First, we point out the difference between It and I ∗ is that in It, there may exist arms from [K]\I ∗ that are inserted between the arms in I ∗ . Denoted such ordered subset of arms as It\I ∗ . Then, depending on the realization of the states of the arm on It, a random subset of It\I ∗ will be pulled (i.e., ˜ It\I ∗ ), resulting in a different regret. Denote the index of the last pulled arm in ˜ It\I ∗ as ˜i. Then, depending on the state of arm˜i, there are two possible cases:
i) X˜i,t = 0. For this case, the regret comes from the cost of pulling the arms in ˜ It\I ∗ only. This is because if I ∗ were the list of arms to pull, with the same realization of arm states, the learner would only pull the arms in ˜ It ∩I ∗ and receive the same reward. Thus, given ˜ It and X˜i,t = 0, we have E[r∗ t -rt |
ii) X˜i,t = 1. This indicates that ˜i is the last arm on ˜ It due to the stopping condition. For this case, the learner spends costs on pulling the arms in ˜ It\I ∗ but also receives the full reward one. If I ∗ were the list of arms to pull, with the same realization of arm states, the learner would first pull all arms in ˜ It ∩ I ∗ . Since the states of such arms should be 0, she would then continue pulling the remaining arms in I ∗ if there is any. Denote the net reward obtained from the remaining pullings as r(I ∗ \˜ It). Then, E[r(I ∗ \˜ It)] ≤ 1. Therefore, given ˜ It and X˜i,t = 1, we have E[r∗ t - rt|˜ It,X˜i,t = 1] = E[r(I ∗ \ ˜ It)] - (1 - ∑i∈ ˜ It\I ∗ ci) ≤ ∑i∈˜ It\I ∗ ci.
Combining both cases, we have E[regt | ˜ It] = E[r∗ t - rt | ˜ It] ≤ ∑i∈˜ It\I ∗ ci, which completes the proof. ■
Next, we consider the regret resulted from including arms outside I ∗ in the list It. We focus on the scenario when both Et and Bt are false. Notice that the condition of Lemma 4 is satisfied in this scenario. Thus,
where (2) is based on Lemma 4; (5) is due to the fact that 1( ¯ Et)1 ( Ui,t Li,t > 1) is always less than or equal to 1(θi +2ui,t > ci -2ui,t), which is equivalent to 1 (Ni,t < 16α log t ∆2i ).
Denote δ∗ as the largest possible per-step regret, which is bounded by ∑i∈[K] ci, corresponding to the worst case scenario that the learner pulls all arms but does not receive reward one. Then, combining the results from above, we have
which proves Theorem 2.
6 Lower Bound
Before presenting the lower bound, we first define αconsistent policies.
Definition 1 Consider online policies that sequentially pull arms in It until one arm with state 1 is observed. If
Lemma 5 For any ordered list It, the per-step regret in step t is lower bounded by E[regt ] ≥ E [∑i∈ ˜ It\I ∗ (ci - θi)].
Proof: Consider an ordered list I ∗ t := It∩I ∗ , i.e., the sub-list of It that only contains the arms from I ∗ while keeping their relative order in It. Denote rt(I ∗ t ) as the reward obtained at step t by pulling the arms in I ∗ t sequentially. We have
where inequality (6) follows from the fact that I ∗ maximizes the expected reward in every step.
Similar to the proof of Lemma 4, we denote the index of the last pulled arm in ˜ It\I ∗ as˜i. Then, given ˜ It and X˜i,t = 0, we have E[rt(I ∗ t ) - rt | ˜ It, X˜i,t = 0] = ∑i∈˜ It\I ∗ ci.
If X˜i,t = 1, based on the assumption that all policy should stop pulling in a step if a state 1 is observed, we infer that the arms in ˜ It ∩ I ∗ should have state 0. If I ∗ t were the list of arms to pull, with the same realization of arm states, the learner would continue pulling the remaining arms in I ∗ t if there is any. Denote the net reward obtained from the rest pulling as r(I ∗ t \˜ It). Then, due to the definition of I ∗ , we have E[r(I ∗ t \˜ It)] ≥ 0. Therefore, given ˜ It and X˜i,t = 1, we have E[rt(I ∗ t ) - rt | ˜ It,X˜i,t = 1] = E[r(I ∗ t \˜ It)] - (1 - ∑i∈ ˜ It\I ∗ ci) ≥ ∑i∈˜ It\I ∗ ci - 1.
Combining both cases, we have E[r∗ t - rt | ˜ It] ≥ ∑i∈ ˜ It\I ∗ ci - θ˜i ≥ ∑i∈˜ It\I ∗(ci - θi). Taking expectation with respect to ˜ It, we obtain the lower bound for E[regt ]. ■
Theorem 3 Under any α-consistent policy,
where d(θi; ci) is the KL divergence of Bernoulli distributions with means θi and ci.
Proof: According to Lemma 5, we have
Therefore,
Leveraging the lower bound on E[Ni,T ] from the proof of Theorem 4 in [Kveton et al., 2015a], we have
Combining (10) with (11), we obtain the lower bound. ■ Comparing Theorem 3 with Theorem 2, we conclude that Algorithm 1 achieves order-optimal regret performance.
7 Experiments
In this section we will resort to numerical experiments to evaluate the performances of the CC-UCB algorithm in Algorithm 1. We set α = 1.5 and ϵ = 10-5 . Both synthetic and real-world datasets are used.
7.1 Synthetic Data
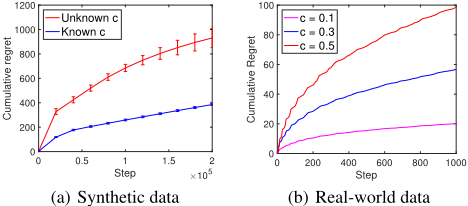
We consider a 6-arm bandits setting with θ = {0.8, 0.7, 0.6, 0.5, 0.4, 0.3}, and the mean of the cost c = 0.55 for all arms. According to the UCR-T1 policy, we have L = 3, i.e., the first three arms should be included in I ∗ . We then perform the CC-UCB algorithm under the assumption that both θ and c are unknown to the learning agent. We run it for T = 2 × 10⁵ steps, and average the accumulative regret over 20 runs. The result is plotted in Figure 1(a). The error bar corresponds to one standard deviation of the regrets in 20 runs. We also study the case where the mean of the cost c is known beforehand, however, the cost of each arm is still random. The result is also plotted in the same figure. As we observe, both curves increase sublinearly in T, which is consistent with the O(logT) bound we derive in Theorem 2. The regret with known cost statistics is significantly smaller than that of the unknown cost statistics case.
Next, we evaluate the impact of system parameters on the performance of the algorithm. We vary K and L, i.e., the total number of arms K, and the number of arms in I ∗ , respectively. We also change ∆i, i.e., ci - θi, for i ∈ [K]\I ∗ . Specifically, we set θi = 0.5 for i ∈ I ∗ , θi = 0.3 for i ∈ [K]\I ∗ , and let ci be a constant c across all arms. By setting ∆L+1, the value of c can be determined. The cumulative regrets at T = 105 averaged over 20 runs are reported in Table 1. We observe four major trends. First, the regret increases when the number of arms K doubles. Second, the regret decreases when the number of arms in I ∗ (i.e., L) increases. Third, a prori knowledge of cost statistics always improve the regret. Fourth, when c is known, the regret increases as ∆L+1 decreases. These trends are consistent with Theorem 2. However, the dependency on ∆L+1 when c is unknown is not obvious from the experiment results. This might be because the algorithm depends on the estimation of the cost as well as the arm state, and the complicated interplay between cost and the optimal arm pulling policy makes the dependency on ∆L+1 hard to discern.
7.2 Real-world Data
In this section, we test the proposed CC-UCB algorithm using real-world data extracted from the click log dataset of Yandex Challenge [Int, 2011]. The click log contains complex user behaviors. To make it suitable for our algorithm, we extract data that contains click history of a specific query. We choose the total number of links for the query to be 15 and set a constant and known cost c for all of them. We estimate the probability that a user would click a link based on the dataset and use it as the ground truth θi. We then test the CC-UCB based on the structure of the optimal offline policy. We plot the cumulative regret in Figure 1(b) with different values of c. We observe that the cumulative regret grows sub-linearly in time, and monotonically increases as c increases, which are consistent with Theorem 2. This indicates that the CCUCB algorithm performs very well even when some of the assumptions (such as the i.i.d. evolution of arm states) we used to derive the performance bounds do not hold.
| K | L | ∆L+1 | Known c | Unknown c |
|---|---|---|---|---|
| 6 | 1 | 0.1 | 580.3288 | 2.2862e+03 |
| 6 | 3 | 0.1 | 352.8772 | 1.4453e+03 |
| 6 | 5 | 0.1 | 117.5846 | 364.6771 |
| 12 | 1 | 0.1 | 2.5284e+03 | 1.0225e+04 |
| 12 | 3 | 0.1 | 1.2996e+03 | 4.8120e+03 |
| 12 | 5 | 0.1 | 387.8936 | 1.3728e+03 |
| 6 | 1 | 0.05 | 1.1536e+03 | 4.7941e+03 |
| 6 | 3 | 0.05 | 697.7550 | 1.4431e+03 |
| 6 | 5 | 0.05 | 160.7688 | 212.0552 |
8 Conclusions
In this paper, we studied a CCB model by taking the cost of pulling arms into the cascading bandits framework. We first explicitly characterized the optimal offline policy UCRT1, and then developed the CC-UCB algorithm for the online setting. We analyzed the regret behavior of the proposed CC-UCB algorithm by analyzing two different types of error events under the algorithm. We also derived an ordermatching lower bound, thus proving that the proposed CCUCB algorithm achieves order-optimal regret. Experiments using both synthetic data and real-world data were carried out to evaluate the CC-UCB algorithm.
@inproceedings{ijcai2018p448,
  title     = {Cost-aware Cascading Bandits},
  author    = {Zhou, Ruida and Gan, Chao and Yang, Jing and Shen, Cong},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {3228--3234},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/448},
  url       = {https://doi.org/10.24963/ijcai.2018/448},
}
TY - CPAPER TI - Cost-aware Cascading Bandits AU - Zhou, Ruida AU - Gan, Chao AU - Yang, Jing AU - Shen, Cong T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 3228 EP - 3234 DO - 10.24963/ijcai.2018/448 UR - https://doi.org/10.24963/ijcai.2018/448 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





