
Thompson Sampling for Budgeted Multi-Armed Bandits
Proceedings of the Twenty-Fourth International Joint Conference on Artificial Intelligence. Special Track on Machine Learning. Pages 3960-3965.
© 2015 International Joint Conferences on Artificial Intelligence
Abstract
Thompson sampling is one of the earliest randomized algorithms for multi-armed bandits (MAB). In this paper, we extend the Thompson sampling to Budgeted MAB, where there is random cost for pulling an arm and the total cost is constrained by a budget. We start with the case of Bernoulli bandits, in which the random rewards (costs) of an arm are independently sampled from a Bernoulli distribution. To implement the Thompson sampling algorithm in this case, at each round, we sample two numbers from the posterior distributions of the reward and cost for each arm, obtain their ratio, select the arm with the maximum ratio, and then update the posterior distributions. We prove that the distribution-dependent regret bound of this algorithm is O(ln B), where B denotes the budget. By introducing a Bernoulli trial, we further extend this algorithm to the setting that the rewards (costs) are drawn from general distributions, and prove that its regret bound remains almost the same. Our simulation results demonstrate the effectiveness of the proposed algorithm.
- [Agmon Ben-Yehuda et al., 2013] Orna Agmon Ben- Yehuda, Muli Ben-Yehuda, Assaf Schuster, and Dan Tsafrir. Deconstructing amazon ec2 spot instance pricing. ACM Transactions on Economics and Computation, 1(3):16, 2013.
- [Agrawal and Goyal, 2012] Shipra Agrawal and Navin Goyal. Analysis of thompson sampling for the multi- armed bandit problem. In Proceedings of the 25th Annual Conference on Learning Theory (COLT), June 2012.
- [Agrawal and Goyal, 2013] Shipra Agrawal and Navin Goyal. Further optimal regret bounds for thompson sampling. Sixteenth International Conference on Artificial Intelligence and Statistics (AISTATS), April 2013.
- [Amin et al., 2012] Kareem Amin, Michael Kearns, Peter Key, and Anton Schwaighofer. Budget optimization for sponsored search:censored learning in mdps. In Uncer- tainty in Artificial Intelligence (UAI). Uncertainty in Arti- ficial Intelligence (UAI), August 2012.
- [Ardagna et al., 2011] Danilo Ardagna, Barbara Panicucci, and Mauro Passacantando. A game theoretic formulation of the service provisioning problem in cloud systems. In Proceedings of the 20th international conference on World wide web, pages 177-186. ACM, 2011.
- [Audibert et al., 2009] Jean-Yves Audibert, Rémi Munos, and Csaba Szepesvári. Exploration-exploitation tradeoff using variance estimates in multi-armed bandits. Theor. Comput. Sci., 410(19):1876-1902, April 2009.
- [Auer et al., 2002] Peter Auer, Nicolo Cesa-Bianchi, and Paul Fischer. Finite-time analysis of the multiarmed bandit problem. Machine learning, 47(2-3):235-256, 2002.
- [Badanidiyuru et al., 2013] Ashwinkumar Badanidiyuru, Robert Kleinberg, and Aleksandrs Slivkins. Bandits with knapsacks. In FOCS, pages 207-216. IEEE, 2013.
- [Bubeck et al., 2009] Sébastien Bubeck, Rémi Munos, and Gilles Stoltz. Pure exploration in multi-armed bandits problems. In Algorithmic Learning Theory, pages 23-37. Springer, 2009.
- Chapelle and Li, ] Olivier Chapelle and Lihong Li. An em- pirical evaluation of thompson sampling. In NIPS (2011).
- [Ding et al., 2013] Wenkui Ding, Tao Qin, Xu-Dong Zhang, and Tie-Yan Liu. Multi-armed bandit with budget con- straint and variable costs. In AAAI, 2013.
- [Fisher, 1980] Marshall L Fisher. Worst-case analysis of heuristic algorithms. Management Science, 26(1):1-17, 1980.
- [Gai et al., 2010] Yi Gai, Bhaskar Krishnamachari, and Rahul Jain. Learning multiuser channel allocations in cog- nitive radio networks: A combinatorial multi-armed bandit formulation. In New Frontiers in Dynamic Spectrum, 2010 IEEE Symposium on, pages 1-9. IEEE, 2010. [Garivier and Cappé, 2011] Aurélien Garivier and Olivier Cappé. The kl-ucb algorithm for bounded stochastic ban- dits and beyond. arXiv preprint arXiv:1102.2490, 2011.
- [Kaufmann et al., 2012a] Emilie Kaufmann, Olivier Cappé, and Aurélien Garivier. On bayesian upper confidence bounds for bandit problems. In AISTATS, pages 592-600, 2012.
- [Kaufmann et al., 2012b] Emilie Kaufmann, Nathaniel Ko- rda, and Rémi Munos. Thompson sampling: An asymptot- ically optimal finite-time analysis. In Algorithmic Learn- ing Theory, pages 199-213. Springer, 2012.
- [Kohli and Krishnamurti, 1992] Rajeev Kohli and Ramesh Krishnamurti. A total-value greedy heuristic for the in- teger knapsack problem. Operations research letters, 12(2):65-71, 1992.
- [Lai and Robbins, 1985] Tze Leung Lai and Herbert Rob- bins. Asymptotically efficient adaptive allocation rules. Advances in applied mathematics, 6(1):4-22, 1985.
- [Li et al., 2010] Lihong Li, Wei Chu, John Langford, and Robert E Schapire. A contextual-bandit approach to per- sonalized news article recommendation. In WWW, pages 661-670. ACM, 2010.
- [Martello and Toth, 1990] Silvano Martello and Paolo Toth. Knapsack problems: algorithms and computer implemen- tations. John Wiley & Sons, Inc., 1990.
- [Thompson, 1933] William R Thompson. On the likelihood that one unknown probability exceeds another in view of the evidence of two samples. Biometrika, pages 285-294, 1933.
- [Tran-Thanh et al., 2010] Long Tran-Thanh, Archie Chap- man, Enrique Munoz de Cote, Alex Rogers, and Nicholas R. Jennings. Epsilon-first policies for budget lim- ited multi-armed bandits. In AAAI, April 2010.
- [Tran-Thanh et al., 2012] Long Tran-Thanh, Archie C Chap- man, Alex Rogers, and Nicholas R Jennings. Knapsack based optimal policies for budget-limited multi-armed bandits. In AAAI, 2012.
- [Tran-Thanh et al., 2014] Long Tran-Thanh, Lampros Stavrogiannis, Victor Naroditskiy, Valentin Robu, Nicholas R Jennings, and Peter Key. Efficient regret bounds for online bid optimisation in budget-limited sponsored search auctions. In UAI. AUAI, July 2014.
- [Vazirani, 2001] Vijay V Vazirani. Approximation algo- rithms. Springer Science & Business Media, 2001.
- [Xia et al., 2015] Yingce Xia, Haifang Li, Tao Qin, Nenghai Yu, and Tie-Yan Liu. Thompson sampling for budgeted multi-armed bandits. arXiv preprint, 2015.
- [Yu and Nikolova, 2013] Jia Yuan Yu and Evdokia Nikolova. Sample complexity of risk-averse bandit-arm selection. In IJCAI, pages 2576-2582. AAAI Press, 2013. IJCAI
- [yves Audibert and Bubeck, 2009] Jean yves Audibert and Sbastien Bubeck. Minimax policies for adversarial and stochastic bandits. In COLT, pages 773-818, 2009.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The multi-armed bandit (MAB) problem, a classical sequential decision problem in an uncertain environment, has been widely studied in the literature [Lai and Robbins, 1985; Auer et al., 2002]. Many real world applications can be modeled as MAB problems, such as news recommendation [Li et al., 2010] and channel allocation [Gai et al., 2010]. Previous studies on MAB can be classified into two categories: one focuses on designing algorithms to find a policy that can maximize the cumulative expected reward, such as UCB1 [Auer et al., 2002], UCB-V [Audibert et al., 2009], MOSS [yves Audibert and Bubeck, 2009], KL-UCB [Garivier and Capp´e, 2011] and Bayes-UCB [Kaufmann et al., 2012a]; the other aims at studying the sample complexity to reach a specific accuracy, such as [Bubeck et al., 2009; Yu and Nikolova, 2013].
∗This work was done when the first two authors were interns at Microsoft Research.
Recently, a new setting of MAB, called budgeted MAB, was proposed to model some new Internet applications, including online bidding optimization in sponsored search [Amin et al., 2012; Tran-Thanh et al., 2014] and on-spot instance bidding in cloud computing [Agmon Ben-Yehuda et al., 2013; Ardagna et al., 2011]. In budgeted MAB, pulling an arm receives both a random reward and a random cost, drawn from some unknown distributions. The player can keep pulling the arms until he/she runs out of budget B. A few algorithms have been proposed to solve the budgeted MAB problem. For example, in [Tran-Thanh et al., 2010], an ϵ-first algorithm was proposed which first spends ϵB budget on pure explorations, and then keeps pulling the arm with the maximum empirical reward-to-cost ratio. It was proven that the ϵ-first algorithm has a regret bound of O(B 23 ). KUBE [Tran-Thanh et al., 2012] is another algorithm for budgeted MAB, which solves an integer linear program at each round, and then converts the solution to the probability of each arm to be pulled at the next round. A limitation of the ϵ-first and KUBE algorithms lies in that they assume the cost of each arm to be deterministic and fixed, which narrows their application scopes. In [Ding et al., 2013], the setting was considered that the cost of each arm is drawn from an unknown discrete distribution and two algorithms UCB-BV1/BV2 were designed. A limitation of these algorithms is that they require additional information about the minimum expected cost of all the arms, which is not available in some applications.
Thompson sampling [Thompson, 1933] is one of the earliest randomized algorithms for MAB, whose main idea is to choose an arm according to its posterior probability to be the best arm. In recent years, quite a lot of studies have been conducted on Thompson sampling, and good performances have been achieved in practical applications [Chapelle and Li, ]. It is proved in [Kaufmann et al., 2012b] that Thompson sampling can reach the lower bound of regret given in [Lai and Robbins, 1985] for Bernoulli bandits. Furthermore, problem-independent regret bounds were derived in [Agrawal and Goyal, 2013] for Thompson sampling with Beta and Gaussian priors.
Inspired by the success of Thompson sampling in classical MAB, two natural questions arise regarding its extension to budgeted MAB problems: (i) How can we adjust Thompson sampling so as to handle budgeted MAB problems? (ii) What is the performance of Thompson sampling in theory and in practice? In this paper, we try to provide answers to these two questions.
Algorithm: We propose a refined Thompson sampling algorithm that can be used to solve the budgeted MAB problems. While the optimal policy for budgeted MAB could be very complex (budgeted MAB can be viewed as a stochastic version of the knapsack problem in which the value and weight of the items are both stochastic), we prove that, when the reward and cost per pulling are supported in [0, 1] and the budget is large, we can achieve the almost optimal reward by always pulling the optimal arm (associated with the maximum expected-reward-to-expected-cost ratio). With this guarantee, our proposed algorithm targets at pulling the optimal arm as frequently as possible. We start with Bernoulli bandits, in which the random rewards (costs) of an arm are independently sampled from a Bernoulli distribution. We design an algorithm which (1) uses beta distribution to model the priors of the expected reward and cost of each arm, and (2) at each round, samples two numbers from the posterior distributions of the reward and cost for each the arm, obtains their ratio, selects the arm with the maximum ratio, and then updates the posterior distributions. We further extend this algorithm to the setting that the rewards (costs) are drawn from general distributions by introducing Bernoulli trials.
Theoretical analysis: We prove that our proposed algorithm can achieve a distribution-dependent regret bound of O(lnB), with a tighter constant before lnB than existing algorithms (e.g., the two algorithms in [Ding et al., 2013]). To obtain this regret bound, we first show that it suffices to bound the expected pulling times of all the suboptimal arms (whose expected-reward-to-expected-cost ratios are not maximum). To this end, for each suboptimal arm, we define two gaps, the δ-ratio gap and the ϵ-ratio gap, which compare its expectedreward-to-expected-cost ratio to that of the optimal arm. Then by introducing some intermediate events, we can decompose the expected pulling time of a suboptimal arm i into several terms, each of which depends on only the reward or only the cost. After that, we can bound each term by the concentration inequalities and two gaps with careful derivations.
To our knowledge, it is the first time that Thompson sampling is applied to the budgeted MAB problem. We conduct a set of numerical simulations with different rewards/costs distributions and different number of arms. The simulation results demonstrate that our proposed algorithm is much better than several baseline algorithms.
2 ProblemFormulation
In this section, we give a formal definition to the budgeted MAB problem.
In budgeted MAB, we consider a slot machine with K arms (K ≥ 2). 1 At round t, a player pulls an arm i ∈ [K], receives a random reward ri(t), and pays a random cost ci(t) until he runs out of his budget B, which is a positive integer. Both the reward ri(t) and the cost ci(t) are supported on [0, 1]. For simplicity and following the practice in previous works, we make a few assumptions on the rewards and costs: (i) the rewards of an arm are independent of its costs; (ii) the rewards and costs of an arm are independent of other arms; (iii) the rewards and costs of the same arm at different rounds are independent and identically distributed.
1 Denote the set {1, 2, · · · ,K} as [K].
We denote the expected reward and cost of arm i as µri and µci respectively. W.l.o.g., we assume ∀i ∈ [K], µri > 0, µci > 0, and argmaxi∈[K] µri µci = 1. We name arm 1 as the optimal arm and the other arms as suboptimal arms.
Our goal is to design algorithms/policies for budgeted MAB with small pseudo-regret, which is defined as follows:
where R∗ is the expected reward of the optimal policy (the policy that can obtain the maximum expected reward given the reward and cost distributions of each arm), rt is the reward received by an algorithm at round t, TB is the stopping time of the algorithm, and the expectation is taken w.r.t. the randomness of the algorithm, the rewards (costs), and the stopping time.
Please note that it could be very complex to obtain the optimal policy for the budgeted MAB problem (under the condition that the reward and cost distributions of each arm are known). Even for its degenerated case, where the reward and cost of each arm are deterministic, the problem is known to be NP-hard (actually in this case the problem becomes an unbounded knapsack problem [Martello and Toth, 1990]). Therefore, generally speaking, it is hard to calculate R∗ in an exact manner.
However, we find that it is much easier to approximate the optimal policy and to upper bound R∗ . Specifically, when the reward and cost per pulling are supported in [0, 1] and B is large, always pulling the optimal arm could be very close to the optimal policy. For Bernoulli bandits, since there is no time restrictions on pulling arms, one should try to always pull arm 1 so as to fully utilize the budget 2 . For the general bandits, the situation is a little more complicated and always pulling arm 1 will result in a suboptimiality of at most 2 µr1 µc1 . These results are summarized in Lemma 1, together with upper bounds on R∗ .
Lemma 1 When the reward and cost per pulling are supported in [0, 1], for Bernoulli bandits, we have R∗ = µr1 µc1 B and the optimal policy is exactly always pulling arm 1; for general bandits, we have R∗ ≤ µr1 µc1 (B + 1), and the suboptimality of always pulling arm 1 (as compared to the optimal policy) is at most 2 µr1 µc1 .
For any i ≥ 2, define Ti as the pulling time of arm i when running out of budget. Denote the difference of the expectedreward-to-expected-cost ratio between the optimal arm 1 and a suboptimal arm i(≥ 2) as ∆i:
2 This is inspired by the greedy heuristic for the knapsack problem [Fisher, 1980], i.e., at each round, one selects the item with the maximum value-to-weight ratio. Although there are many approximation algorithms for the knapsack problem like the total-value greedy heuristic [Kohli and Krishnamurti, 1992] and the FPTAS [Vazirani, 2001], under our budgeted MAB setting, we find that they will not bring much benefit on tightening the bound of R∗ .
Lemma 2 relates the regret to Ti and ∆i (i ≥ 2). It is useful when we analyze the regret of a pulling algorithm.
Lemma 2 For Bernoulli bandits, we have
For general bandits, we have
The intuition behind Lemma 2 is as follows. As aforementioned, for Bernoulli bandits, the optimal policy is to always pull arm 1. If one pulls a suboptimal arm i (> 1) for Ti times, then he/she will lose some rewards. Specifically, the expected budget spent on arm i is µci Ti, and if he/she spent such budget on the optimal arm 1, he/she can get µci ∆iTi extra reward. For general bandits, always pulling arm 1 might not be optimal (see Lemma 1) - actually it leads to a regret at most 2µr1 µc1 . Therefore, we need to add an extra term 2µr1 µc1 to the result for Bernoulli bandits.
3 Budgeted Thompson Sampling
In this section, we first show how Thompson sampling can be extended to handle budgeted MAB with Bernoulli distributions, and then generalize the setting to general distributions. For ease of reference, we call the corresponding algorithm Budgeted Thompson Sampling (BTS).
First, the BTS algorithm for the budgeted Bernoulli bandits is shown in Algorithm 1. In the algorithm, Sr i (t) denotes the times that the player receives reward 1 from arm i before (excluding) round t, Sc i (t) denotes the times that the player pays cost 1 for pulling arm i before (excluding) round t, and Beta(·, ·) denotes the beta distribution. Please note that we use the beta distribution as a prior in Algorithm 1 because it is the conjugate distribution of the binomial distribution: If the prior is a Beta(α, β), after a Bernoulli experiment, the posterior distribution is either Beta(α+1, β) (if the trial is a success) or Beta(α, β + 1) (if the trial is a failure).
In the original Thompson sampling algorithm, one draws a sample from the posterior beta distribution for the reward of each arm, pulls the arm with the maximum sampled reward, receives a reward, and then updates the reward distribution based on the received reward. In Algorithm 1, in addition to sampling rewards, we also sample costs for the arms at the same time, pull the arm with the maximum sampled rewardto-cost ratio, receive both the reward and cost, and then update the reward distribution and cost distribution.
As compared to KUBE [Tran-Thanh et al., 2012], Algorithm 1 does not need to solve a complex integer linear program. As compared to the UCB-style algorithms like fractional KUBE [Tran-Thanh et al., 2012] and UCB-BV1 [Ding et al., 2013], Algorithm 1 does not need carefully designed confidence bounds. As can be seen, BTS only simply chooses one out of the K arms according to their posterior probabilities to be the best arm, which is an intuitive, easy-toimplement, and efficient approach.
Algorithm 1 Budgeted Thompson Sampling (BTS)
- 1: For each arm i ∈ [K], set Sr i (1) ← 0, F r i (1) ← 0, Sc i (1) ← 0, and F c i (1) ← 0 ;
- 2: Set B1 ←B; t ← 1;
- 3: while Bt > 0 do
- 4: For each arm i ∈ [K], sample θr i (t) fromBeta(Sr i (t) + 1, F r i (t) +1), and sample θc i (t) from Beta(Sc i (t) + 1, F c i (t) +1);
- 5: Pull arm It = argmaxi∈[K] θr i (t) θc i (t) ; receive reward rt; pay cost ct; update Bt+1 ← Bt - ct;
- 6: For Bernoulli bandits, ˜ r ← rt, ˜ c ← ct; for general bandits, sample ˜ r from B(rt) and sample ˜ c from B(ct);
- 7: Sr It (t + 1) ← Sr It (t) + ˜ r; F r It (t + 1) ← F r It (t) + 1 - ˜ r;
- 8: Sc It (t + 1) ← Sc It (t) + ˜ c; F c It (t + 1) ← F c It (t) + 1 - ˜ c;
- 9: ∀j ̸= It, Sr j (t + 1) ← Sr j (t), F r j (t + 1) ← F r j (t), Sc j (t + 1) ← Sc j (t), F c j (t + 1) ← F c j (t);
- 10: Set t ← t +1.
- 11: end while
By leveraging the idea proposed in [Agrawal and Goyal, 2012], we can modify the BTS algorithm for Bernoulli bandits and make it work for bandits with general reward/cost distributions. In particular, with general distributions, the reward rt and cost ct (in Step 5) at round t become real numbers in [0, 1]. We introduce a Bernoulli trial in Step 6: Set ˜ r ← B(rt) and ˜ c ← B(ct), in which B(rt) is a Bernoulli test with success probability rt and so is B(ct). Now Sr i (t) and Sc i (t) represent the number of success Bernoulli trials for the reward and cost respectively. Then we can use ˜ r and ˜ c to update Sr i (t) and Sc i (t) accordingly.
4 Regret Analysis
In this section, we analyze the regret of our proposed BTS algorithm. We start with Bernoulli bandits and then generalize the results to general bandits. Due to space restrictions, we only give proof sketches here. Although the proof sketches are self-contained, interested readers can find more details (as well as colored figures for experiments) in the online full version of this paper [Xia et al., 2015].
In the classical MAB, the player only needs to explore the expected reward of each arm, however, in the budgeted MAB the player also needs to explore the expected cost simultaneously. Therefore, as compared with [Agrawal and Goyal, 2012], our regret analysis will heavily depends on some quantities related to the reward-to-cost ratio (such as the two gaps defined below).
For an arm i(≥ 2) and a given γ ∈ (0, 1),we define
It is easy to verify the following equation for any i ≥ 2.
For ease of reference, ∀i ≥ 2, we call δi(γ) the δ-ratio gap between the optimal arm and a suboptimal arm i, and ϵi(γ) the ϵ-ratio gap. In the remaining part of this section, we simply write ϵi(γ) as ϵi when the context is clear and there is no confusion.
The following theorem says that BTS achieves a regret bound of O(ln(B)) for both Bernoulli and general bandits:
Theorem 3 ∀γ ∈ (0, 1), for both Bernoulli bandits and general bandits, the regret of the BTS algorithm can be upper bounded as below.
in which ∆i is defined in Eqn. (2) and Φi(γ) is defined as
We first prove Theorem 3 holds for Bernoulli bandits in Section 4.1 and then extend the result for general bandits in Section 4.2 .
4.1 Analysis for Bernoulli Bandits
First, we describe the high-level idea of how to prove the theorem. According to Lemma 2, to upper bound the regret of BTS, it suffices to bound E{Ti} ∀i ≥ 2. For a suboptimal arm i, E{Ti} can be decomposed into the sum of a constant and the probabilities of two kinds of events (see (6)). The first kind of event is related to the δ-ratio gap δi(γ), and its probability can be bounded by leveraging concentrating inequalities and the relationship between the binomial distribution and the beta distribution. The second one is related to the ϵ-ratio gap ϵi(γ), according to which the probability of the event related to arm i can be converted to that related to the optimal arm 1. To bound the probability of the second kind of event, we need some complicated derivations, as shown in the later part of this subsection.
Then, we define some notations and intermediate variables, which will be used in the proof sketch.
ni,t denotes the pulling time of arm i before (excluding) round t; It denotes the arm pulled at round t; 1{·} is the indicator function; µcmin = mini∈[K]{µci }; Ht-1 denotes the history until round t-1, including the arm pulled from round 1 to t-1, and the rewards/costs received at each round; θi(t) denotes the ratio θr i (t) θc i (t) ∀i ∈ [K] where θr i (t) and θc i (t) are defined in Step 4 of Algorithm 1; Bt denotes the budget left at the beginning of round t; Eθ i (t) denotes the event that given γ ∈ (0, 1), θi(t) ≤ µri +δi(γ) µci -δi(γ) ∀i > 1; the probability pi,t denotes P{θ1(t) > µr1 -ϵi(γ) µc1+ϵi(γ) |Ht-1, Bt > 0} given γ ∈ (0, 1) ∀i > 1; event denotes the "event" does not hold.
After that, we give the proof sketch as follows, which can be partitioned into four steps.
It can be shown that the pulling time of a suboptimal arm i can be decomposed into three parts: a constant invariant to t and the probabilities of two kinds of events:
where Li = 2 lnB δ2 i (γ) . Note that Li depends on γ. We omit the γ when there is no confusion throughout the context. We then bound the probabilities of the two kinds of events in the next two steps.
Step 2: Bound ∑∞t=1 P{Eθ i (t), ni,t ≥ ⌈Li⌉, Bt > 0}. Define two new events: ∀i ≥ 2 and t ≥ 1,
If Eθ i (t) holds, at least one event of Er i (t) and Ec i (t) holds. Therefore, we have
Intuitively, when ni,t is large enough, θr i (t) and θc i (t) should be very close to µri and µci respectively. Then, both Er i (t) and Ec i (t) will be low-probability events. Mathematically, ∀γ ∈ (0, 1), the two terms in the right-hand side of (7) could be bounded as follows, by considering the relationship between the binomial distribution and the beta distribution.
As a result, we have
One can also verify that ∑∞t=1 P{Bt > 0} is bounded by
where ci(t) is the cost of arm i at round t.
Therefore, we obtain that
Step 3: Bound ∑∞t=1 P{It = i, Eθ i (t), Bt > 0}.
Let τk (k ≥ 0) denote the round that arm 1 has been pulled for the k-th time and define τ0 = 0. ∀i ≥ 2 and ∀t ≥ 1, pi,t is only related to the pulling history of arm 1, thus pi,t will not change between τk + 1 and τk+1, ∀k ≥ 0. With some derivations, we can get that
(12) bridges the probability of an event related to arm 1 and that related to arm i (i ≥ 2). To further decompose the r.h.s. of (12), define the following two probabilities which are related to the ϵ-ratio gap between arm 1 and arm i:
Since the reward of an arm is independent of its cost, we can verify pi,t ≥ pri,tpci,t and then get
According to (12) and (13), ∑∞t=1 P{It = i, Eθ i (t), Bt > 0} can be bounded by the sum of the right-hand side of (13) over index k from 0 to infinity, which is related to the pulling time of arm 1 and the ϵ-ratio gap between arm 1 and arm i.
It is quite intuitive that when arm 1 is played for enough times, θr 1 (t) and θc1 (t) will be very close to µr1 and µc1 respectively. That is, probabilities pri,τk+1 and pci,τk+1 will be close to 1, and so will their reciprocals. To mathematically characterize pri,τk+1 and pci,τk+1 , we define some notations as follows, which are directly or indirectly related to the ϵratio gap: yi = µr1 - ϵi, zi = µc1 + ϵi, R1,i = µr1 (1-yi) yi(1-µr1 ) , R2,i = µc1 (1-zi) zi(1-µc1 ) , D1,i = yi ln( yi µr1 ) + (1 - yi) ln( 1-yi 1-µr1 ) and D2,i = zi ln( zi ) + (1 - zi) ln( 1-zi ).
Based on the above notations and discussions, we can obtain the following results regarding the right-hand side of (13): ∀i > 1 and k ≥ 1
If zi ≥ 1, E{ 1 pci,τk+1 } = 1; otherwise,
Specifically, if zi ≥ 1, E[ 1 pi,τ0+1 ] ≤ 1 1-yi ; otherwise E[ 1 pi,τ0+1 ] ≤ 1 (1-yi)zi . The derivations of (14) and (15) need tight estimations of partial binomial sums and careful algebraic operations, which can be found in the online full version of this work [Xia et al., 2015].
According to (12) and (13), to bound ∑∞t=1 P{It = i, Eθ i (t),Bt > 0}, we only need to multiply each term in (14) by each one in (15), and sum up all the multiplicative terms over k from 0 to ∞ except the constant 1. Using Taylor series expansion, we can verify that w.r.t. γ,
Similarly, if ϵi(γ) + µc1 < 1, we can obtain that w.r.t γ,
Note that the constants in the O(·) of (16) and (17) do not depend on B (but depend on µri and µci ∀i ∈ [K]).
Step 4: Bound E{Ti} ∀i ≥ 2 for Bernoulli bandits.
Combining (6), (11), (16) and (17), we can get the following result:
in which ∆i is defined in (2) and Φi(γ) is defined in (5).
According to the Eqn. (3) of Lemma 2, we can eventually obtain the regret bound of Budgeted Thompson Sampling as shown in Theorem 3 by first multiplying µci∆i on the right of (18) and then summing over i from 2 to K.
4.2 Analysis for General Bandits
The regret bound we obtained for Bernoulli bandits in the previous subsection also works for general bandits, as shown in Theorem 3.
The result for general bandits is a little surprising since the problem of general bandits seems more difficult than the Bernoulli bandit problem, and one may expect a slightly looser asymptotic regret bound. The reason why we can retain the same regret bound lies in the Bernoulli trials of the general bandits. Intuitively, the Bernoulli trials can be seen as the intermediate that can transform the general bandits to Bernoulli bandits while keeping the expected reward and cost of each arm unchanged. Therefore, when B is large, there should not be too many differences in the regret bound between the Bernoulli bandits and general bandits.
Specifically, similar to the case of Bernoulli bandits, in order to bound the regret of the BTS algorithm for the general bandits, we only need to bound E{Ti} (according to inequality (4)). To bound E{Ti}, we also need four steps similar to those described in the previous subsection. In addition, we need one extra step which is related to the Bernoulli trials. Details are described as below.
S0: Obtain the success probabilities of the Bernoulli trials. Denote the reward and cost of arm i at round t as ri(t) and ci(t) respectively. Denote the Bernoulli trial results of arm i at round t as ˜ ri(t) (for reward) and ˜ ci(t) (for cost). We need to prove P{˜ ri(t) = 1} = µri and P{˜ ci(t) = 1} = µci , which is straightforward:
S1: Decompose E{Ti}: This step is the same as Step 1 in the Bernoulli bandit case. For the general bandit case, E{Ti} can also be bounded by inequality (6).
S2: Bound ∑∞t=1 P{Eθ i (t), ni,t ≥ ⌈Li⌉,Bt > 0}. S2 is almost the same as Step 2 in the proof for Bernoulli bandits but contains some minor changes. For the general bandits, we have ci(t) ∈ [0, 1] rather than ci(t) ∈ {0, 1}. Then we have ∑∞t=1 P{Bt > 0} ≤ B+1 µcmin , and can get a similar result to (11).
S3: Bound ∑∞t=1 P{It = i, Eθ i (t),Bt > 0}. Since we have already got the success probabilities of the Bernoulli trials, this step is the same as Step 3 for the Bernoulli bandits.
S4: Substituting the results of S2 and S3 into the corresponding terms in (6), we can get an upper bound of E{Ti} for the general bandits. Then according to (4), for general bandits, the results in Theorem 3 can be eventually obtained.
The classical MAB problem in [Auer et al., 2002] can be regarded as a special case of the budgeted MAB problem by setting ci(t) = 1 ∀i ∈ [K], t ≥ 1, and B is the total pulling time. According to [Lai and Robbins, 1985], we can verify the order of the distribution-dependent regret bound of the budgeted MAB problem is at least O(lnB). Comparing with the two algorithms in [Ding et al., 2013], we have the following results:
Remark 4 By setting γ = 1 √2 in Theorem 3, we can see that BTS gets a tighter asymptotic regret bound in terms of the constants before lnB than the two algorithms proposed in [Ding et al., 2013].
5 Numerical Simulations
In addition to the theoretical analysis of the BTS algorithm, we are also interested in its empirical performance. We conduct a set of experiments to test the empirical performance of BTS algorithm and present the results in this section.
For comparison purpose, we implement four baseline algorithms: (1) the ϵ-first algorithm [Tran-Thanh et al., 2010] with ϵ = 0.1; (2) a variant of the PD-BwK algorithm [Badanidiyuru et al., 2013]: at each round, pull the arm with the maximum min{ri,t+ϕ(ri,t,ni,t),1} max{ci,t-ϕ(ci,t,ni,t),0} , in which ri,t (ci,t) is the average reward (cost) of arm i before round t, ϕ(x,N) = √ νx N + νN and ν = 0.25 log(BK); (3) the UCB-BV1 algorithm [Ding et al., 2013]; (4) a variant of the KUBE algorithm [Tran-Thanh et al., 2012]: at round t, pull the arm with the maximum ratio (ri,t + √ 2 ln t ni,t )/ci,t. ϵ-first and PD-BwK need to know B in advance, and thus we try several budgets as {100, 200, 500, 1K, 2K, 5K, 10K, 15K, 20K, · · · , 50K}. BTS, UCB-BV1 and KUBE do not need to know B in advance, and thus by setting B = 50K we can get their empirical regrets for every budget smaller than 50K.
We simulate bandits with two different distributions: one is the Bernoulli distribution (simple), and the other is the multinomial distribution (complex). Their parameters are randomly chosen. For each distribution, we simulate a 10armed case and a 100-armed case. We then independently run the experiments for 500 times and report the average performance of each algorithm.
The average regret and the standard deviation of each algorithm over 500 random runs are shown in Figure 1. From the figure we have the following observations:
First, for both the Bernoulli distribution and the multinomial distribution, and for both the 10-arm case and 100-arm case, our proposed BTS algorithm has clear advantage over the baseline methods: It achieves the lowest regrets. Furthermore, the standard deviation of the regrets of BTS over 500 runs is small, indicating that its performance is very stable across different random run of the experiments.
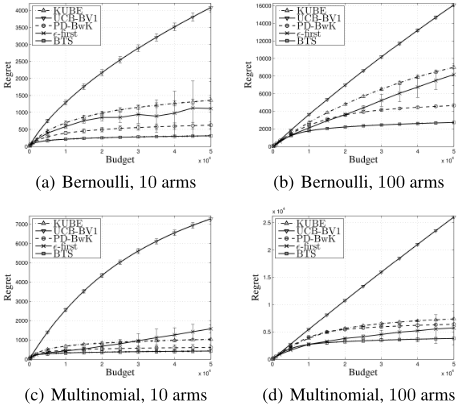
Second, as the number of arms increases (from 10 to 100), the regrets of all the algorithms increase, given the same budget. This is easy to understand because more budget is required to make good explorations on more arms.
Third, the standard deviation of the regrets of the ϵ-first algorithm is much larger than the other algorithms, which shows that ϵ-first is not stable under certain circumstances. Take the 10-armed Bernoulli bandit for example: when B = 50K, during the 500 random runs, there are 13 runs that ϵfirst cannot identify the optimal arm. The average regret over the 13 runs is 4630. However, over the other 487 runs, the average regret of ϵ-first is 1019.9. Therefore, the standard derivation of ϵ-first is large. In comparison, the BTS algorithm is much more stable.
Overall speaking, the simulation results demonstrate the effectiveness of our proposed Budgeted Thompson Sampling algorithm.
6 Conclusion and Future work
In this paper, we have extended the Thompson sampling algorithm to the budgeted MAB problems. We have proved that our proposed algorithm has a distribution-dependent regret bound of O(lnB). We have also demonstrated its empirical effectiveness using several numerical simulations.
For future work, we plan to investigate the following aspects: (1) We will study the distribution-free regret bound of Budgeted Thompson Sampling. (2) We will try other priors (e.g., the Gaussian prior) to see whether a better regret bound and empirical performance can be achieved in this way. (3) We will study the setting that the reward and the cost are correlated (e.g., an arm with higher reward is very likely to have higher cost).
Acknowledgments
This work is partially supported by National Natural Science Foundation of China (NSFC, NO.61371192).
@inproceedings{ijcai2015p556,
  title     = {Thompson Sampling for Budgeted Multi-Armed Bandits},
  author    = {Xia, Yingce and Li, Haifang and Qin, Tao and Yu, Nenghai and Liu, Tie-Yan},
  booktitle = {Proceedings of the Twenty-Fourth International Joint Conference on
               Artificial Intelligence, {IJCAI-15}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Qiang Yang and Michael Wooldridge},
  pages     = {3960--3965},
  year      = {2015},
  month     = {7},
  note      = {Special Track on Machine Learning},
  url       = {https://ijcai.org/proceedings/2015/556},
}
TY - CPAPER TI - Thompson Sampling for Budgeted Multi-Armed Bandits AU - Xia, Yingce AU - Li, Haifang AU - Qin, Tao AU - Yu, Nenghai AU - Liu, Tie-Yan T2 - Proceedings of the Twenty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-15 PB - International Joint Conferences on Artificial Intelligence PY - 2015 SP - 3960 EP - 3965 UR - https://ijcai.org/proceedings/2015/556 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





