
Self-Supervised Deep Low-Rank Assignment Model for Prototype Selection
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 3141-3147.
https://doi.org/10.24963/ijcai.2018/436
Keywords
- Machine Learning: Active Learning
- Machine Learning: Clustering
- Machine Learning: Semi-Supervised Learning
Abstract
Prototype selection is a promising technique for removing redundancy and irrelevance from large-scale data. Here, we consider it as a task assignment problem, which refers to assigning each element of a source set to one representative, i.e., prototype. However, due to the outliers and uncertain distribution on source, the selected prototypes are generally less representative and interesting. To alleviate this issue, we develop in this paper a Self-supervised Deep Low-rank Assignment model (SDLA). By dynamically integrating a low-rank assignment model with deep representation learning, our model effectively ensures the goodness-of-exemplar and goodness-of-discrimination of selected prototypes. Specifically, on the basis of a denoising autoencoder, dissimilarity metrics on source are continuously self-refined in embedding space with weak supervision from selected prototypes, thus preserving categorical similarity. Conversely, working on this metric space, similar samples tend to select the same prototypes by designing a low-rank assignment model. Experimental results on applications like text clustering and image classification (using prototypes) demonstrate our method is considerably superior to the state-of-the-art methods in prototype selection.
- [Bengio et al., 2013] Yoshua Bengio, Aaron Courville, and Pascal Vincent. Representation learning: A review and new perspectives. TPAMI, 35(8):1798-1828, 2013.
- [Cai et al., 2005] Deng Cai, Xiaofei He, and Jiawei Han. Document clustering using locality preserving indexing. TPAMI, 17(12):1624-1637, 2005.
- [Chan, 1987] Tony F Chan. Rank revealing QR factoriza- tions. Linear algebra and its applications, 88:67-82, 1987.
- [Chen and Cai, 2011] Xinlei Chen and Deng Cai. Large s- cale spectral clustering with landmark-based representa- tion. In AAAI, pages 313-318, 2011.
- [Cong et al., 2011] Yang Cong, Junsong Yuan, and Ji Liu. S- parse reconstruction cost for abnormal event detection. In CVPR, pages 3449-3456, 2011.
- [Cong et al., 2017] Yang Cong, Ji Liu, Gan Sun, Quanzeng You, Yuncheng Li, and Jiebo Luo. Adaptive greedy dic- tionary selection for web media summarization. TIP, 26(1):185-195, 2017.
- [Dornaika and Aldine, 2015] Fadi Dornaika and I Kamal Al- dine. Decremental sparse modeling representative s- election for prototype selection. Pattern Recognit., 48(11):3714-3727, 2015.
- [Duda et al., 2012] Richard O Duda, Peter E Hart, and David G Stork. Pattern classification. John Wiley & Sons, 2012.
- [Elhamifar and Kaluza, 2017] Ehsan Elhamifar and MCDP Kaluza. Online summarization via submodular and con- vex optimization. In CVPR, pages 1783-1791, 2017.
- [Elhamifar et al., 2012] Ehsan Elhamifar, Guillermo Sapiro, and Rene Vidal. See all by looking at a few: Sparse mod- eling for finding representative objects. In CVPR, pages 1600-1607, 2012.
- [Elhamifar et al., 2016] Ehsan Elhamifar, Guillermo Sapiro, and S Shankar Sastry. Dissimilarity-based sparse subset selection. TPAMI, 38(11):2182-2197, 2016.
- [Fan et al., 2017] Mingyu Fan, Xiaojun Chang, and Dacheng Tao. Structure regularized unsupervised discriminant fea- ture analysis. In AAAI, pages 1870-1876, 2017.
- [Frey and Dueck, 2007] Brendan J Frey and Delbert Dueck. Clustering by passing messages between data points. Sci- ence, 315(5814):972-976, 2007.
- [Garcia et al., 2012] Salvador Garcia, Joaquin Derrac, Jose Cano, and Francisco Herrera. Prototype selection for n- earest neighbor classification: Taxonomy and empirical s- tudy. TPAMI, 34(3):417-435, 2012.
- [Hull, 1994] Jonathan J. Hull. A database for handwritten text recognition research. TPAMI, 16(5):550-554, 1994.
- [Kaufman and Rousseeuw, 1987] Leonard Kaufman and Pe- ter Rousseeuw. Clustering by means of medoids. In Y. Dodge (Ed.) Statistical Data Anal. Based on the ℓ 1 -norm and Related Methods, pages 405-416, 1987.
- [Krause et al., 2008] Andreas Krause, H Brendan McMa- han, Carlos Guestrin, and Anupam Gupta. Robust sub- modular observation selection. J. Mach. Learn. Research, 9:2761-2801, 2008.
- [Lazebnik et al., 2006] S. Lazebnik, C. Schmid, and J. Ponce. Beyond bags of features: Spatial pyramid matching for recognizing natural scene categories. In CVPR, pages 2169-2178, 2006.
- [Lin et al., 2018] Liang Lin, Keze Wang, Deyu Meng, Wangmeng Zuo, and Lei Zhang. Active self-paced learn- ing for cost-effective and progressive face identification. TPAMI, 40(1):7-19, 2018.
- [Meng et al., 2016] Jingjing Meng, Hongxing Wang, Jun- song Yuan, and Yap-Peng Tan. From keyframes to key ob- jects: Video summarization by representative object pro- posal selection. In CVPR, pages 1039-1048, 2016.
- [Nellore and Ward, 2015] Abhinav Nellore and Rachel Ward. Recovery guarantees for exemplar-based cluster- ing. Inform. and Computat., 245:165-180, 2015.
- [Ng et al., 2002] Andrew Y Ng, Michael I Jordan, and Yair Weiss. On spectral clustering: Analysis and an algorithm. In NIPS, pages 849-856, 2002.
- [Okura et al., 2017] Shumpei Okura, Yukihiro Tagami, Shin- go Ono, and Akira Tajima. Embedding-based news rec- ommendation for millions of users. In KDD, pages 1933- 1942, 2017.
- [Simonyan and Zisserman, 2014] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. arXiv:1409.1556, 2014.
- [Song et al., 2017] Hyun Oh Song, Stefanie Jegelka, Vivek Rathod, and Kevin Murphy. Deep metric learning via fa- cility location. In CVPR, pages 5382-5390, 2017.
- [Vincent et al., 2008] Pascal Vincent, Hugo Larochelle, Yoshua Bengio, and Pierre-Antoine Manzagol. Extract- ing and composing robust features with denoising autoen- coders. In ICML, pages 1096-1103, 2008.
- [Wang and Zhang, 2013] Shusen Wang and Zhihua Zhang. Improving CUR matrix decomposition and the nyström approximation via adaptive sampling. J. Mach. Learn. Res., 14(9):2729-2769, 2013.
- [Wang et al., 2017] Hongxing Wang, Yoshinobu Kawahara, Chaoqun Weng, and Junsong Yuan. Representative selec- tion with structured sparsity. Pattern Recognit., 63:268- 278, 2017.
- [Yin et al., 2016] Ming Yin, Junbin Gao, and Zhouchen Lin. Laplacian regularized low-rank representation and its ap- plications. TPAMI, 38(3):504-517, 2016.
- [Zhang et al., 2018] Xingxing Zhang, Zhenfeng Zhu, Yao Zhao, and Dongxia Chang. Learning a gener- al assignment model for video analytics. TCSVT, DOI:10.1109/TCSVT.2017.2713480, in press, 2018. DOI
- [Zhuang et al., 2012] Liansheng Zhuang, Haoyuan Gao, Zhouchen Lin, Yi Ma, Xin Zhang, and Nenghai Yu. Non- negative low rank and sparse graph for semi-supervised learning. In CVPR, pages 2328-2335, 2012.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
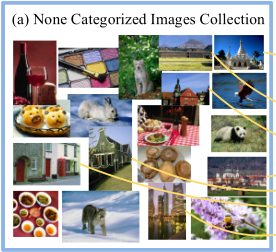
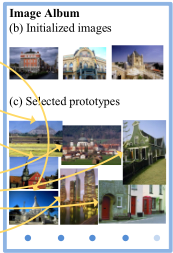
Prototype selection is the task of finding exemplar samples, called prototypes, from a large collection of data points. This is at the center of many problems in data analysis and processing field because it holds several advantages over data storage, compression, synthesis, cleansing and visualization. First, the memory cost for storing information on the data can be significantly reduced using prototypes. Second, prototypes help in clustering of data, and, as the most prototypical samples, can be used for efficient synthesis of new data points. More importantly, the computational efficiency for data modeling, such as classifier training [Garcia et al., 2012; Zhang et al., 2018] and active learning [Lin et al., 2018], can be improved by working on prototypes. In addition, selecting prototypes helps to remove redundant or irrelevant points, such as outliers. Finally, prototype selection has been applied for anomaly detection [Cong et al., 2011], web media summarization and recommendation [Meng et al., 2016; Cong et al., 2017] (see Figure 1), segmentation of dynamic data [Elhamifar et al., 2016], and more.
To characterize the informativeness of prototypes in terms of ability to represent the entire distribution, many selection strategies have been proposed, generally including two categories. The first one involves greedy methods that select next prototype with respect to the previously selected prototypes, and usually maximizes submodular functions, such as graph-cuts and facility location [Wang and Zhang, 2013; Elhamifar and Kaluza, 2017; Krause et al., 2008]. Obviously, they usually result in high computational complexity. The second category is comprised of model-driven methods that aim to maximize global objective based on subspace leaning or pairwise relationship. Their resulting solutions are closely related to a variety of optimization algorithms.
Concretely, subspace leaning based models mainly focus on the data that lie in one or several low-dimensional subspaces. The Rank Revealing QR algorithm [Chan, 1987] is a representative one. By representing data in a low dimensional space with possibly minimal representation error, various effective models have been formulated to learn a selection matrix, such as the sparse dictionary selection (SDS) method [Cong et al., 2011] and sparse modeling representative selection (SMRS) model [Elhamifar et al., 2012].
To further exploit data structure, some improved methods have been proposed [Dornaika and Aldine, 2015; Wang et al., 2017]. For instance, structured sparse dictionary selection (SSDS) [Wang et al., 2017] method tried to select prototypes with both representativeness and diversity via three structured regularizers. However, by multi-linear coding criteria, these methods are effective only when the samples from different groups are sufficiently dissimilar.
In contrast, pairwise relationship based models aim at the data that could be naturally grouped under a certain dissimilarity metric. One naive approach is Kmedoids [Kaufman and Rousseeuw, 1987], which finds k medoid centers as prototypes by pursuing the minimum total distance from all samples. Some variants [Nellore and Ward, 2015] were further proposed based on Kmedoids. Unlike Kmeans [Duda et al., 2012] or Kmedoids, Affinity Propagation (AP) algorithm [Frey and Dueck, 2007] does not require any initialization for prototypes, but has suboptimal property. To tackle this issue, dissimilarity-based sparse subset selection (DS3) method [Elhamifar et al., 2016] was recently proposed to select prototypes via a trace minimization model. In general, this kind of methods performs well only under appropriate similarity metric.
Furthermore, some real datasets do not live in a vector space, e.g., social network data or proteomics data. Therefore, model-driven methods based on pairwise relationship have more advantages on prototype selection. However, most existing algorithms suffer from imposing restrictions on the type of pairwise relationship. More importantly, unreliable metric caused by outliers or uncertain data distribution significantly reduces the quality of prototypes. Inspired by representation learning [Song et al., 2017], we consider introducing a unified framework for dissimilarity learning and prototype selection. As a result, the metric is efficiently self-refined with weak supervision from prototypes, and conversely, prototypes are more informative by using refined metrics. These construct the basic motivation of our framework.
In summary, the main contributions of this work are highlighted as follows.
- By considering the prototype selection as a task assignment problem, we develop a Self-supervised Deep Lowrank Assignment model (SDLA), which aims to jointly learn ideal dissimilarity metrics in embedding space and select informative prototypes in metric space.
- Unlike DS3 [Elhamifar et al., 2016], inspired by the good performance of deep representation learning, we propose to learn dissimilarity metrics based on a variant of a denoising autoencoder, in which categorical similarity is preserved with weak supervision from prototypes.
- Working on the learned metric space, similar samples tend to select the same prototypes by designing a low-rank assignment model, thus guaranteeing a diversified selection.
- The quality of prototypes selected by the proposed framework is reasonably evaluated with examples in text clustering and image classification (using prototypes), showing very promising results.
2 The Proposed Framework
2.1 Problem Statement
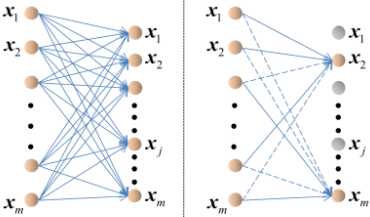
Let X = [x1, . . . , xm] ∈ Rd×m be the source data matrix of m samples in Rd . As shown in Figure 2, we consider the problem of selecting an interesting subset of m samples, called prototype set, that can efficiently describe and summarize all samples in source data. Inspired by DS3 [Elhamifar et al., 2016], we primarily pursue the minimum assignment cost based on pairwise relationships on source.
2.2 ProblemFormulation
It is noteworthy that pairwise dissimilarity matrix D = {dij }j=1,...,m i=1,...,m between samples is directly given as the input to DS3 [Elhamifar et al., 2016]. Actually, the given {dij}, such as Euclidean distance or χ2 distance, may be not discriminative due to uncertain distribution and outliers in X, thus leading to a less representative and diversified selection. In light of the good performance of representation learning [Bengio et al., 2013], we consider circularly refining the dissimilarity metric and the selection indicator. Thereby, available semantic information from selected prototypes can be employed to learn the parameters of metric architecture, while conversely, more discriminative metric can improve the quality of prototypes. Towards this end, we develop a Selfsupervised Deep Low-rank Assignment model (SDLA) for prototype selection as follows:
where Φrep(Θ; ·) learns a deep representation of a sample, and Θ is the set of related parameters. ΦdSim(·, ·) aims to capture the dissimilarity of two samples in learned embedding space, thus dij = ΦdSim(Φrep(Θ; xi),Φrep(Θ; xj)). Z = {zij}j=1,...,m i=1,...,m is a selection matrix, zij ∈ [0, 1] is the probability of selecting xi as the prototype of xj, thus enforcing ∑mi=1 zij = 1 for xj. The first term in the objective function corresponds to the total assignment cost, the second term corresponds to the constraints in the deep architecture, and the last term corresponds to the number of prototypes. ω1 and ω2 are nonnegative parameters to balance these terms. Figure 3 provides an illustration of the proposed model in (1).
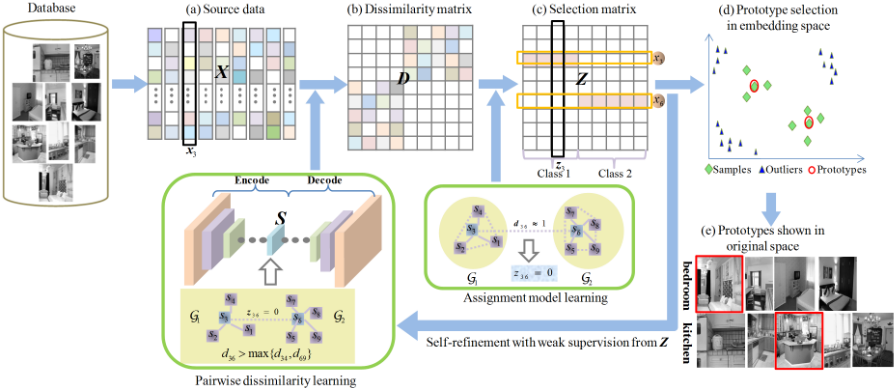
Concretely, for any xi and xj, if dij = 0, then zij = 1 due to low assignment cost, which implies that xi and xj are from the same class. While zij = 0 if dij = ∞, which implies that xi and xj are from different classes. Since Z provides additional semantic information for all samples, D will be learned more discriminatively by preserving categorical similarity with weak supervision from Z.
Considering the separability of both objective and constraints in (1), we further divide (1) into two subproblems P1 and P2, which are cyclic self-refinement:
- P1 corresponding to the pairwise dissimilarity learning module in Figure 3, is written as
- P2 corresponding to the assignment model learning module in Figure 3, is written as
The details about learning Θ and Z are introduced in Section 3.1 and Section 3.2, respectively. As a result, the indices of nonzero rows of the solution Z∗ correspond to the indices of those samples that are chosen as the data prototypes. In addition, Z∗ shows the membership of samples in X to prototypes. That is, z∗ j = [z∗ 1j , . . . , z ∗mj ]T ∈ Rm corresponds to the probability vector of xj being represented by each sample in X. Therefore, we can obtain a partitioning of X under the rule that, if χ = {xl1 , . . . , xlκ } denotes the set of selected prototypes, we can assign xj to the prototype xδj by
Consequently, X is classified into κ groups corresponding to κ prototypes via the selection matrix Z∗ .
3 Optimization
3.1 Pairwise Dissimilarity Learning
As shown in (2), optimizing Θ aims to refine pairwise dissimilarities {dij}, and it seamlessly connects the visual content and dissimilarity metric with weak supervision from Z. However, due to the outliers and uncertain distribution on X, we consider generating distributed representation vectors and pairwise dissimilarities on the basis of a denoising autoencoder [Vincent et al., 2008]. The general denoising autoencoder is formulated as:
where xi ∈ X is the original input vector, i = 1, . . . ,m, and q (·|·) is the corrupting distribution. The stochastically corrupted vector, ˜ xi, is obtained from q (·|xi). Generally, ˜ xi = (1 - β)xi, and β is the corruption rate in the training phase. The hidden representation, si, is mapped from ˜ xi through the network, which consists of an activation function f(·), parameter matrix W, and parameter vector b. In the same way, the reconstructed vector, yi, is also mapped from si with parameter matrix W ′ and parameter vector b′ . Using a loss function, LR(·, ·), we learn these parameters to minimize the total reconstruction error of {yi} and {xi}.
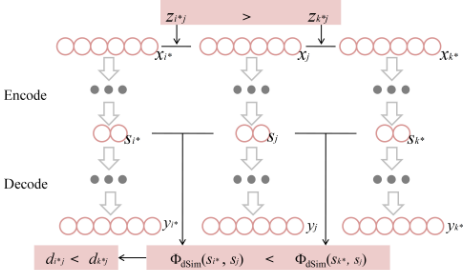
Here, our proposed deep framework contains L layers of nonlinear transformation, and the output si of the middle layer is usually used as a representation vector that corresponds to xi [Okura et al., 2017], thus si = Φrep(Θ; xi). Then dij is captured in embedding space. In this work, we define dij = ΦdSim(si, sj) = 1 - sTi sj. However, si in (5) only holds the information of xi. As shown in Figure 4, it is expected that the distance between two representation vectors si and sj, i.e., dij, is smaller, if xj is more similar to xi compared with xk (which is evaluated by zij > zkj). This is just the weak supervision from selected prototypes via Z. For this end, we add a triplet loss LT to the objective as follows:
In essence, the loss function LT is a penalty function for sample similarity to correspond to categorical similarity.
In addition, as observed in (2), the assignment cost LE should be as small as possible.
Consequently, the total loss function LA(X) is rewritten as follows:
where α1 and α2 are two hyperparameters to balance three loss terms. T is the set of triplets, which is constructed by associating each positive pair in the minibatch with a semihard negative sample. Specifically, xi∗ and xk∗ denote the positive and negative samples of xj in a triplet, and
Finally, we use the elementwise sigmoid function as f(·), and masking noise as q(·|·). The following model is trained by mini-batch Adaptive Moment Estimation:
where Ω(Θ) = ∑L/2 l=1 (‖Wl‖2F + ‖bl‖22 + ∥∥Wl ′∥∥2F + ∥∥bl ′∥∥22 ), and l = 1, . . . , L/2.
3.2 Assignment Model Learning
As shown in (3), optimizing Z aims to select a small number of prototypes with both diversity and representativeness. Then we consider enforcing the lowest rank and sparsity properties on Z. That is, Ψ(Z) = λ1rank(Z) +λ2card(Z), where λ1, λ2 > 0, rank(Z) denotes the rank of Z, and card(Z) denotes the number of nonzero elements of Z. As observed in [Zhuang et al., 2012], the low-rankness criterion is better at capturing the global structure of dissimilarity D, while the sparsity criterion can capture the local structure of each data vector. Specifically, low-rankness can encourage similar samples to have similar codes (i.e., ith and j th columns of Z), so as to select the same prototypes. Thus, (3) is rewritten as
where ∑mi,j=1 dijzij = tr(DTZ), tr(·) denotes the trace operator, and dij has been obtained from (2). ‖·‖∗ and ‖·‖0 are the nuclear norm and ℓ0-norm of a matrix, respectively. λ1 and λ2 are two nonnegative regularization parameters to balance these terms. 1 ∈ Rm is a column vector with all 1′ s.
The problem in (11) could be solved by Inexact Augmented Lagrangian Method (IALM). It is an iterative algorithm, and thus needs to first introduce two auxiliary variables Z1 and Z2 to make the objective function separable. The following problem is obtained:
where ‖·‖1 is the ℓ1-norm of a matrix to relax the ‖·‖0 . Then, the augmented Lagrangian function of (12) is as follows.
where ∆1, ∆2 ∈ Rm×m and δ3 ∈ Rm are the Lagrange multipliers. η is a penalty parameter.
According to the IALM, the objective function converges with a sequence of closed form updating steps. The variable Z, Z1, or Z2 is updated with other variables fixed. The detailed updating rules are presented as follows.
Algorithm 1 The implementation of SDLA
Input: X, λ1, λ2, ρ, α. Initial.: k ← 0, D(k) . 1: repeat 2: Initial. t ← 0, Z(t) = Z(t) 1 = Z(t) 2 = Z(k) , η(t) = 1, ∆(t) 1 =∆(t) 2 = 0, δ(t) 3 = 0. 3: while not converged do 4: Update Z(t+1) according to (14); 5: Update Z(t+1) 1 according to (15); 6: Update Z(t+1) 2 according to (16); 7: ∆(t+1) 1 ←∆(t) 1 + η(Z(t+1) -Z(t+1) 1 ); 8: ∆(t+1) 2 ←∆(t) 2 + η(Z(t+1) -Z(t+1) 2 ); 9: δ(t+1) 3 ← δ(t) 3 + η(1TZ(t+1) -1T); 10: η(t+1) ← ρη(t) ; 11: t ← t + 1; 12: end while 13: Z(k) ←Z(t) ; 14: Update Θ in deep architecture (10); 15: D← dij = ΦdSim(Φrep(Θ; xi),Φrep(Θ; xj)); 16: D(k+1) =D(k) +αD; // Update with memory 17: k ← k +1; 18: until Convergence criterion satisfied Output: Optimal solution Z∗ = Z(k) .where Z in (14) is computed by equating the partial derivative of (13) with respect to Z to zero.
where Γ and S are singular value soft-thresholding and shrinkage-thresholding operator, respectively. In detail, for any matrix A and parameter γ, the form of analytic solution for S is as follows.
Then, we have the definition of Γ as
where A = UΛV T is the singular value decomposition.
4 Implementation Framework
In summary, Alg. 1 shows the steps of detailed implementation of the SDLA model in (1). The algorithm should not be terminated until the change of objective value is smaller than a pre-defined threshold (10-1 in our experiments). In addition, we initialize D by Euclidean distance.
5 Experimental Results and Analysis
In this section, we evaluate the performance of SDLA for selecting prototypes on several illustrative problems.
5.1 Clustering via Prototypes
To examine the performance of our proposed framework, we consider the problem of text clustering using prototypes that act as cluster centers. We compare our SDLA mainly with prototype selection based clustering methods, including AP [Frey and Dueck, 2007], Kmeans [Duda et al., 2012], Kmedoids [Kaufman and Rousseeuw, 1987], Spectral Clustering (SC) [Ng et al., 2002], LSC [Chen and Cai, 2011], NSHLRR [Yin et al., 2016] and DS3 [Elhamifar et al., 2016]. To further verify the effectiveness of joint learning, we also compare SDLA with Dis-SDLA, which is our assignment model in (3) with given dissimilarity metric 1 . Note that many selection methods (e.g. SSDS) cannot be used for clustering.
The standard document collections TDT2 2 [Cai et al., 2005] is used for this task, which consists of 9 groups of experiments corresponding to different cluster numbers. For each given cluster number, 30 tests are conducted on different randomly chosen clusters and the average performance is computed. The metric, clustering accuracy (AC), is used to measure the quality of prototypes. Table 1 shows the results of those methods, which prove that the proposed method works well with clustering task using prototypes. This is due to the fact that SDLA selects the most representative prototypes, thus improving grouping performance.
5.2 Evaluation by Classification
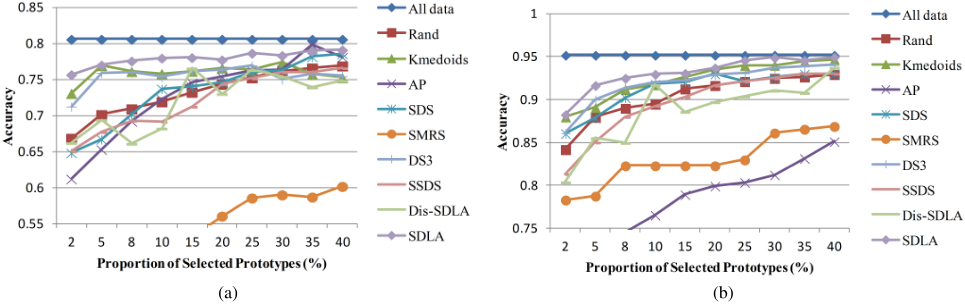
To further evaluate the discrimination of selected prototypes, we employ a classifier to compare the classification results when working on prototype set and source set. Here, we choose the 1-Nearest Neighbor (1-NN) classifier since it is parameter free and the results will be easily reproducible [Fan et al., 2017]. Because the optimal number of prototypes is unknown, we compare each prototype selection method, including no selection (All data), random selection of samples (Rand), Kmedoids [Kaufman and Rousseeuw, 1987], AP [Frey and Dueck, 2007], SDS [Cong et al., 2011], SMRS [Elhamifar et al., 2012], DS3 [Elhamifar et al., 2016], SSDS [Wang et al., 2017], Dis-SDLA and SDLA, with varying numbers of selected prototypes. To this end, we consider the problems of scene categorization and handwriting recognition. The experiments are conducted on the Fifteen Scene Categories dataset [Lazebnik et al., 2006] and the USPS digit dataset [Hull, 1994], which consist of 15 and 10 classes, respectively. We randomly select 80% of images in each class to form the source training set and use the rest for testing. For scene images, we take the 4096-dimensional CNN features [Simonyan and Zisserman, 2014] as input. Then a subset of training set is selected for 1-NN classification, whose averaged results over 6 times of execution with different training set selections are shown in Figure 5. Obviously, SDLA is the most closest to the ideal performance of using all data. This comes from the fact that SDLA effectively removes confusing samples by selecting the most discriminative prototypes.
1 We choose the same dissimilarity metric with DS3.
2 http://www.cad.zju.edu.cn/home/dengcai/Data/TextData.html
| # cluster | AP | Kmeans | Kmedoids | SC | LSC | NSHLRR | DS3 | Dis-SDLA | SDLA |
|---|---|---|---|---|---|---|---|---|---|
| 2 | 77.18±1.10 | 57.74±1.39 | 96.72±0.90 | 79.34±2.12 | 65.31±2.09 | 86.65±1.28 | 96.72±1.55 | 95.39±1.95 | 97.06±0.83 |
| 3 | 68.28±1.91 | 62.74±2.80 | 50.96±2.14 | 78.11±1.42 | 94.36±1.48 | 89.35±2.33 | 97.45±0.96 | 96.23±1.15 | 97.72±1.01 |
| 4 | 63.95±2.79 | 64.47±1.95 | 65.79±1.65 | 86.65±1.03 | 71.84±2.84 | 82.62±1.93 | 99.47±0.67 | 97.91±0.75 | 98.12±0.74 |
| 5 | 60.41±1.39 | 45.11±3.65 | 60.27±2.17 | 68.59±3.70 | 71.95±1.03 | 78.35±1.27 | 71.80±2.04 | 72.82±3.09 | 76.55±2.82 |
| 6 | 63.52±1.69 | 66.05±2.31 | 69.48±3.95 | 74.73±1.03 | 87.68±1.43 | 74.09±2.38 | 74.93±1.76 | 73.21±1.79 | 80.36±1.18 |
| 7 | 65.89±1.48 | 56.65±1.40 | 53.34±3.63 | 62.05±2.70 | 65.78±3.75 | 70.77±2.27 | 70.65±1.66 | 70.23±1.65 | 76.22±1.16 |
| 8 | 52.37±3.11 | 68.49±1.49 | 58.06±3.95 | 71.66±2.34 | 70.02±2.58 | 71.69±1.22 | 70.92±3.75 | 71.29±2.24 | 78.18±1.51 |
| 9 | 59.78±3.70 | 68.51±2.89 | 65.95±2.96 | 69.30±2.55 | 69.66±2.14 | 70.13±1.14 | 69.45±3.26 | 69.10±3.84 | 75.50±2.25 |
| 10 | 60.11±1.81 | 52.83±3.24 | 58.41±2.92 | 76.81±1.35 | 72.30±1.19 | 79.17±1.25 | 82.51±1.61 | 81.33±1.47 | 86.68±1.35 |
| ave. | 63.50±2.11 | 60.30±2.35 | 64.33±2.69 | 74.10±2.02 | 74.32±2.06 | 78.09±1.67 | 81.43±1.91 | 80.77±1.99 | 85.15±1.42 |
5.3 Robustness to Outliers
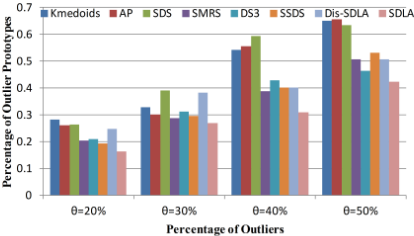
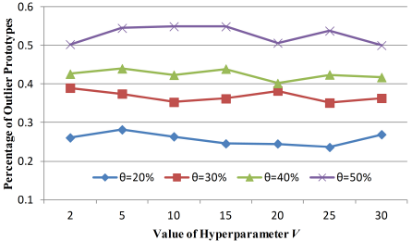
To evaluate the performance of SDLA for rejecting outliers, we form a dataset of 9000 images, of which 1 - θ fraction are randomly selected from the Extended YaleB face database, and the remaining, corresponding to outliers, are random images downloaded from the internet. For θ ∈ {20%, 30%, 40%, 50%}, we run SDLA as well as Kmedoids, AP, SDS, SMRS, DS3, SSDS and Dis-SDLA to select roughly 300 prototypes from the dataset. Figure 6 shows the percentage of outliers among the selected prototypes as we increase the number of outliers in the dataset. Obviously, SDLA results in less outliers compared with other methods. To facilitate the parameter tuning, we run Algorithm 1 with λi = λ0/υ, where i = 1, 2, λ0 is computed fromX [Elhamifar et al., 2012], and υ ∈ [2, 30]. Actually, the sensibility of SDLA degenerates into that of Dis-SDLA. Figure 7 presents the parameter analysis results for several values of υ.
6 Conclusion
In this work, we introduced a SDLA framework to select representative and discriminative prototypes. Promising experimental results show the effectiveness of SDLA.
Acknowledgments
This work was supported in part by the National Key R&D Program of China under Grant 2016YFB0800404 and the National Natural Science Foundation of China under Grants 61532005, 61332012, and 61572068, and in part by the Fundamental Research Funds for the Central Universities under Grant 2017YJS056.
@inproceedings{ijcai2018p436,
  title     = {Self-Supervised Deep Low-Rank Assignment Model for Prototype Selection},
  author    = {Zhang, Xingxing and Zhu, Zhenfeng and Zhao, Yao and Kong, Deqiang},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {3141--3147},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/436},
  url       = {https://doi.org/10.24963/ijcai.2018/436},
}
TY - CPAPER TI - Self-Supervised Deep Low-Rank Assignment Model for Prototype Selection AU - Zhang, Xingxing AU - Zhu, Zhenfeng AU - Zhao, Yao AU - Kong, Deqiang T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 3141 EP - 3147 DO - 10.24963/ijcai.2018/436 UR - https://doi.org/10.24963/ijcai.2018/436 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





