
Semi-Supervised Optimal Margin Distribution Machines
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 3104-3110.
https://doi.org/10.24963/ijcai.2018/431
Keywords
- Machine Learning: Classification
- Machine Learning: Semi-Supervised Learning
Abstract
Semi-supervised support vector machines is an extension of standard support vector machines with unlabeled instances, and the goal is to find a label assignment of the unlabeled instances, so that the decision boundary has the maximal \textit{minimum margin} on both the original labeled instances and unlabeled instances. Recent studies, however, disclosed that maximizing the minimum margin does not necessarily lead to better performance, and instead, it is crucial to optimize the \textit{margin distribution}. In this paper, we propose a novel approach SODM (Semi-supervised Optimal margin Distribution Machine), which tries to assign the label to unlabeled instances and achieve optimal margin distribution simultaneously. Specifically, we characterize the margin distribution by the first- and second-order statistics, i.e., the margin mean and variance, and extend a stochastic mirror prox method to solve the resultant minimax problem. Extensive experiments on UCI data sets show that SODM is significantly better than compared methods, which verifies the superiority of optimal margin distribution learning.
- [Beck and Teboulle, 2003] A. Beck and M. Teboulle. Mir- ror descent and nonlinear projected subgradient methods for convex optimization. Operations Research Letters, 31(3):167-175, 2003.
- [Belkin et al., 2006] M. Belkin, P. Niyogi, and V. Sind- hwani. Manifold regularization: A geometric framework for learning from labeled and unlabeled examples. Journal of Machine Learning Research, pages 2399-2434, 2006.
- [Bennett and Demiriz, 1999] K. P. Bennett and A. Demiriz. Semi-supervised support vector machines. In Proceedings of the 1998 Conference on Advances in Neural Informa- tion Processing Systems II, pages 368-374, 1999.
- [Chapelle and Zien, 2005] O. Chapelle and A. Zien. Semi- supervised classification by low density separation. In Pro- ceedings of the 8th International Conference on Artificial Intelligence and Statistics, pages 57-64, 2005.
- [Collobert et al., 2006] R. Collobert, F. Sinz, J. Weston, and L. Bottou. Large scale transductive svms. Journal of Ma- chine Learning Research, 7:1687-1712, 2006.
- [Cortes and Vapnik, 1995] C. Cortes and V. Vapnik. Support-vector networks. Machine Learning, 20(3):273- 297, 1995.
- [Cristianini and Shawe-Taylor, 2000] N. Cristianini and J. Shawe-Taylor. An Introduction to Support Vector Machines and Other Kernel-based Learning Methods. Cambridge University Press, Cambridge, UK, 2000.
- [Gao and Zhou, 2013] W. Gao and Z.-H. Zhou. On the doubt about margin explanation of boosting. Artificial Intelli- gence, 203:1-18, 2013.
- [Joachims, 1999] T. Joachims. Transductive inference for text classification using support vector machines. pages 200-209.
- Morgan Kaufmann, 1999.
- [Johnson and Zhang, 2013] R. Johnson and T. Zhang. Accel- erating stochastic gradient descent using predictive vari- ance reduction. In C. J. C. Burges, L. Bottou, M. Welling, Z. Ghahramani, and K. Q. Weinberger, editors, Advances in Neural Information Processing Systems 26, pages 315- 323.
- Curran Associates, Inc., 2013.
- [Kim and Boyd, 2008] Seung-Jean Kim and Stephen Boyd. A minimax theorem with applications to machine learn- ing, signal processing, and finance. SIAM Journal on Op- timization, 19(3):1344-1367, 2008.
- [Li and Zhou, 2011] Y.-F. Li and Z.-H. Zhou. Towards mak- ing unlabeled data never hurt. In Proceedings of the 28th International Conference on International Conference on Machine Learning, pages 1081-1088, 2011.
- [Li et al., 2009a] Y.-F. Li, James T. Kwok, and Z.-H. Zhou. Semi-supervised learning using label mean. In Interna- tional Conference on Machine Learning, pages 633-640, 2009.
- [Li et al., 2009b] Y.-F. Li, Ivor W. Tsang, James T. Kwok, and Z.-H. Zhou. Tighter and convex maximum margin clustering. In In Proceeding of the 12th International Con- ference on Artificial Intelligence and Statistics, volume 5, pages 344-351, 2009.
- [Li et al., 2010] Y.-F. Li, J. T. Kwok, and Z.-H. Zhou. Cost- sensitive semi-supervised support vector machine. In Pro- ceedings of the 24th AAAI Conference on Artificial Intelli- gence, pages 500-505. AAAI Press, 2010.
- [Li et al., 2013] Yu-Feng Li, Ivor W. Tsang, James T. Kwok, and Zhi-Hua Zhou. Convex and scalable weakly la- beled svms. Journal of Machine Learning Research, 14(1):2151-2188, jan 2013.
- [Nemirovski, 2005] A. Nemirovski. Prox-Method with Rate of Convergence O(1/t) for Variational Inequalities with Lipschitz Continuous Monotone Operators and Smooth Convex-Concave Saddle Point Problems. Society for In- dustrial and Applied Mathematics, 2005.
- [Schmidt et al., 2015] Mark Schmidt, Reza Babanezhad, Mohamed Ahmed, Aaron Defazio, Ann Clifton, and Anoop Sarkar. Non-uniform stochastic average gradient method for training conditional random fields. In Guy Lebanon and S. V. N. Vishwanathan, editors, Proceedings of the Eighteenth International Conference on Artificial Intelligence and Statistics, volume 38 of Proceedings of Machine Learning Research, pages 819-828, San Diego, CA, 09-12 May 2015. PMLR.
- [Schölkopf and Smola, 2001] B. Schölkopf and A. J. Smola. Learning with kernels: support vector machines, regular- ization, optimization, and beyond. MIT Press, Cambridge, MA, 2001.
- [Sion, 1958] Maurice Sion. On general minimax theorems. Pacific Journal of Mathematics, 8(1):171-176, 1958.
- [Xu et al., 2005] L. Xu, J. Neufeld, B. Larson, and D. Schu- urmans. Maximum margin clustering. In L. K. Saul, Y. Weiss, and L. Bottou, editors, Advances in Neural In- formation Processing Systems 17, pages 1537-1544. MIT Press, 2005.
- [Zhang and Zhou, 2014] T. Zhang and Z.-H. Zhou. Large margin distribution machine. In Proceedings of the 20th ACM SIGKDD Conference on Knowledge Discovery and Data Mining, pages 313-322, New York, NY, 2014.
- [Zhang and Zhou, 2017] T. Zhang and Z.-H. Zhou. Multi- class optimal distribution machine. In Proceedings of the 34th International Conference on Machine Learning, pages 4063-4071, Sydney, NSW, Australia, 2017.
- [Zhang and Zhou, 2018] T. Zhang and Z.-H. Zhou. Optimal margin distribution clustering. In Proceedings of the 20th National Conference on Artificial Intelligence, AAAI'18. AAAI Press, 2018.
- [Zhou, 2014] Z.-H. Zhou. Large margin distribution learn- ing. In Proceedings of the 6th IAPR International Work- shop on Artificial Neural Networks in Pattern Recognition, pages 1-11, Montreal, Canada, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Traditional supervised learning uses only labeled instances to train the classifiers. However, labeled instances are often difficult or expensive to obtain since they require the efforts of experienced human annotators. On the other hand, unlabeled instances are universal and relatively easy to collect. To exploit the value of them, many semi-supervised learning algorithms have been proposed, among which a very popular type of algorithms is the semi-supervised support vector machines (S3VMs). Examples include the semi-supervised SVM [Bennett and Demiriz, 1999], the transductive SVM (TSVM) [Joachims, 1999], the Laplacian SVM [Belkin et al., 2006], and the S3VM using label mean (MeanS3VM) [Li et al., 2009a], just to name a few. Bennett and Demiriz's S3VM
∗This research was supported by National Key R&D Program of China (2018YFB1004300) and NSFC (61751306) and the Program B for outstanding PhD candidate of Nanjing University.
and the TSVM are built upon the cluster assumption and use the unlabeled instances to regularize the decision boundary. Specifically, these methods prefer the decision boundary that passes through low-density regions [Chapelle and Zien, 2005]. The Laplacian SVM is a S3VM that exploits the instance's manifold structure via the graph Laplacian. It encodes both the labeled and unlabeled instances by a connected graph, where each instance is represented as a vertex and two vertices are connected by an edge if they are quite similar to each other. The goal is to find labels for the unlabeled instances such that their inconsistencies with both the labeled instances and the underlying graph structure are minimized. The MeanS3VM bases on the observation that S3VMs with knowledge of the means of the labels of the unlabeled instances is closely related to the supervised SVM with known labels on all the unlabeled instances. So the approach is consist of two steps, i.e., first estimate the label means of the unlabeled instances, and then build a SVM model. Moreover, several works also try to extend S3VMs for other learning settings, e.g., the CS4VM [Li et al., 2010] considers the situation where different misclassification errors are associated with unequal costs, and the safe S3VM (S4VM) [Li and Zhou, 2011] tries to exploit many candidate low-density separators simultaneously to reduce the risk of identifying only one poor separator with unlabeled instances, so it always performed better than S3VMs.
Aforementioned all kinds of S3VMs are all based on the large margin principle, i.e., try to maximize the minimum margin of training instances. However, recent studies on margin theory [Gao and Zhou, 2013] disclosed that maximizing the minimum margin does not necessarily lead to better performance, and instead, it is crucial to optimize the margin distribution. Inspired by this recognition, Zhang and Zhou (2014) proposed ODMs (optimal margin distribution machines) which can achieve better generalization performance than large margin based methods. Later, Zhang and Zhou (2017; 2018) extends the idea to multi-class learning and clustering. The success of optimal margin distribution learning suggests that there may still exist large space to further enhance for S3VMs.
In this paper, we propose a novel approach ssODM (semisupervised optimal margin distribution machines), which tries to learn the label assignments of unlabeled instances and to achieve optimal margin distribution simultaneously.
Specifically, we characterize the margin distribution by the first- and second-order statistics, i.e., the margin mean and variance, and then apply the minimax convex relaxation proposed in [Li et al., 2009b], which is proven to be tighter than SDP relaxations [Xu et al., 2005], to get a convex reformulation. For the optimization of the resultant saddle point problem, we propose a stochastic mirror prox method which can converge more quickly in practise than the general subgradient descent for non-smooth problem. Extensive experiments on twenty UCI data sets show that ssODM is significantly better than compared methods, which verifies the superiority of optimal margin distribution learning.
The rest of this paper is organized as follows. We first introduce some preliminaries and then present the ssODM method. Next we show the experimental studies. Finally we conclude this paper with future work.
2 Preliminaries
We start with the traditional supervised learning. Denote X as the instance space and Y = {+1, -1} as the label set. Let D be an unknown (underlying) distribution over X ×Y. A training set S = {(x1, y1), (x2, y2), . . . , (xm, ym)} ∈ (X ×Y)m is drawn identically and independently (i.i.d.) according to D. Let φ : X ↦→ H be a feature mapping associated to some positive definite kernel κ : X×X ↦→ R. The hypothesis is defined based on the linear model h(x) = w⊤φ(x) and the predicted label of instance x is the sign of h(x), then the decision function naturally leads to the definition of margin for a labeled instance, i.e., γ(x, y) = yw⊤φ(x) [Cristianini and ShaweTaylor, 2000]. Thus the higher the margin value, the more confidence we will have that x's label is y, and h misclassifies (x, y) if and only if it produces a negative margin. Given a hypothesis set H of functions mapping X to Y and the labeled training set S, our goal is to learn a function h ∈ H such that the generalization error R(h) = E(x,y)∼D[1sign(h(x))̸=y] is small, where 1(·) is the indicator function that returns 1 when the argument holds, and 0 otherwise.
2.1 Optimal Margin DistributionMachine
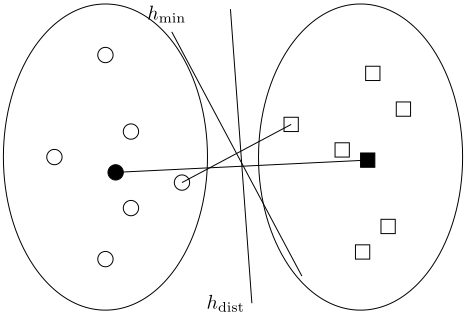
It is well known that SVM employs the large margin principle to select h and tries to maximize the minimum margin of training instance, i.e., the smallest distance from the instances to the decision boundary. As a result, the solution of SVM just consists of a small amount of instance, that is support vectors (SV), and the rest (non-SVs) are totally ignored, which may be misleading in some situations. See Figure 1 for an illustration [Zhou, 2014].
A more robust strategy is to consider the whole instances, i.e., optimizing the margin distribution. To characterize the distribution, the two most straightforward statistics are the first- and second-order statistics, that is, the margin mean and variance. Moreover, a recent study [Gao and Zhou, 2013] on margin theory proved that maximizing the margin mean and minimizing the margin variance simultaneously can yield a tighter generalization bound, so we arrive at the following formulation,
where ¯ γ is the margin mean, η and λ are trading-off parameters, ξi and ϵi are the deviation of γ(xi, yi) to the margin mean. It's evident that ∑mi=1 (ξ 2 i + ϵ2i )/m is exactly the margin variance.
First, by scaling w which doesn't affect the final classification results, the margin mean can be fixed as 1, then the deviation of γ(xi, yi) to the margin mean is |yiw⊤φ(xi) - 1|. Secondly, the hyperplane yiw⊤φ(xi) = 1 divides the feature space into two parts and for each instance, no matter which part it lies in, it will suffer a loss which is quadratic with the deviation. So it is more reasonable to set different weights for the two kinds of deviations because the instances lie in {x | yw⊤φ(x) < 1} are much easier to be misclassified than the other. Thirdly, according to representer theorem [Sch¨olkopf and Smola, 2001], the optimal solution is spanned only by SVs. To achieve a sparse solution, we introduce a θ-insensitive loss like SVR, i.e., the instances whose deviation is smaller than θ are tolerated and only those whose deviation is larger than θ will suffer a loss. Finally, we obtain the formulation of ODM,
where ν is a parameter for trading-off different kinds of deviations, θ is a parameter for controlling the sparsity of the solution, and (1 - θ)2 in the denominator is to scale the second term to be a surrogate loss for 0-1 loss.
It can be found that the least square loss is a special case of ODM's loss fucntion by ignoring the asymmetry, so it is more sensitive to outliers and can only be suitable for some specific distribution. In addition, without θ-insensitivity, all the instances will be support vectors, which can result in unnecessary computation cost. In other words, ODM is more flexible and can characterize the margin distribution more adaptively.
3 ssODM
In semi-supervised learning setting, not all the training labels are known. Let SL = {xi, yi}li=1 and SU = {xj}mj=l+1 be the sets of labeled and unlabeled instances, respectively. L = {1, . . . , l} and U = {l + 1, . . . ,m} are the index sets of the labeled and unlabeled instances. In semi-supervised learning, unlabeled data are typically much more abundant than labeled data, that is, m- l ≫ l. Hence, one can obtain a trivially "optimal" solution with infinite margin by assigning all the unlabeled examples to the same label. To prevent such a useless solution, Joachims (1999) introduced the balance constraint:
where ˆ y⊤ = [ˆ y1, . . . , ˆ ym] is the vector of learned labels on both labeled and unlabeled examples, y⊤ L = [y1, . . . , yl], ˆ y⊤ U = [ˆ yl+1, . . . , ˆ ym], and e stands for the all-one vector. The basic idea of ssODM is to minimize the objective function in Eq. (1) w.r.t. both the labeling ˆ y and decision function parameter w, ξi, ϵi. Hence, Eq. (1) is extended to
where B = {ˆ y | ˆ y = [ˆ yL; ˆ yU], ˆ yL = yL, ˆ yU ∈ {0, 1}m-l , e⊤ ˆ yU m-l = e⊤yL l } is a set of candidate label assignments. λi = λ1(m-l)-λ2l l(m-l) 1i∈L + λ2 m-l , and λ1, λ2 trade off empirical losses on the labeled and unlabeled data, respectively.
To avoid the curse of dimensionality, the inner minimization problem of Eq. (2) is usually cast in the dual form. Denote X as the data matrix whose i-th column is φ(xi), i.e., X = [φ(x1), . . . , φ(xm)], and introduce the dual variables α ⪰ 0, the Lagrangian of Eq. (2) leads to
where K = X⊤X is the kernel matrix, λ⊤ = [λ1, . . . , λm], ⊙ and ⊘ denotes the element-wise product and division, respectively. Note that the objective function is a negative definite quadratic formwhose stationary point can't locate at the infinity, so we can replace the constraint {α | α ⪰ 0} by a bounded box A = {α | 0 ⪯ α ⪯ τe}, where the auxiliary parameter τ is introduced for the sake of mathematical soundness. For a sufficiently large τ, the new problem is equal to the original problem.
To overcome the difficulty of this mixed-integer programming, many relaxations have been proposed, among which the minimax convex relaxation proposed in [Li et al., 2009b; 2013] is proven to be the tightest. So in this paper, we also employ this method to deal with the mixed-integer problem, i.e., interchanging the order of maxα∈A and minˆ y∈B, then we can obtain
where G(α, ˆ y) is the objective function of Eq. (3), and this can be further transformed into
For the inner optimization in Eq. (4), introduce the dual variables µ⊤ = [µ1, . . . , µ|B|] ⪰ 0, the Lagrangian leads to
By setting the partial derivative of δ to zero, we can obtain ∑k: ˆ yk∈B µk = 1 and the dual turns to
where M = {µ ∈ R|B| + | e⊤µ = 1} is the simplex in R|B| . By substituting Eq. (5) into Eq. (4) and denoting ϕ(µ,α) = ∑k: ˆ yk∈B µkG(α, ˆ yk), Eq. (4) can be rewritten as
Note that ϕ(µ,α) is a convex combination of negative definite quadratic forms, so it's convex in µ and concave in α. According to Sion's minimax theorem [Sion, 1958], there exists a saddle point (µ⋆ , α⋆ ) ∈ M× A such that
By combining with the following minimax inequality [Kim and Boyd, 2008],
we can realize that all the equalities hold in Eq. (6) and arrive at the final formulation of ssODM:
4 Optimization
In this section, we commence with a simple introduction to minimax problem, followed by a stochastic mirror prox method to find the saddle point.
4.1 Minimax Problem
Since ϕ(·,α) is convex and ϕ(µ, ·) is concave, according to the convex inequality, for any pair (¯µ, ¯α) ∈M×Awe have
By adding the above two inequalities together we have
where w = (µ,α),u = (¯µ, ¯α) ∈ M× A, and g(u) = (∂µϕ(u),-∂αϕ(u)), which plays a similar role as gradient in general convex optimization. Note that Eq. (8) holds for any µ and α, in particular we have
The left hand side is referred to as the "duality gap", which can be decomposed into two parts, i.e.,
As can be seen, the primal gap and the dual gap are both nonnegative and the more closer to the saddle point, the smaller both gaps. So duality gap can be viewed as a measure to evaluate the closeness of current point (¯µ, ¯α) to the saddle point (µ⋆ ,α⋆ ).
4.2 Stochastic Mirror ProxMethod
For ssODM, the feasible set of µ and α are simplex and bounded box, respectively, so the most suitable optimization method is mirror descent [Beck and Teboulle, 2003], and the corresponding mirror maps are ΦM(µ) = ∑k µk log µk and ΦA(α) = ‖α‖22 /2, respectively. Further note that the objective of inner optimization is smooth function, mirror descent can be accelerated to the rate O(1/t) by applying the mirror prox technique in [Nemirovski, 2005].
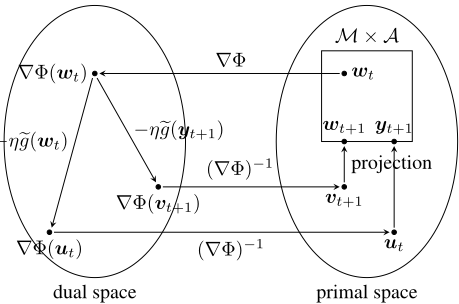
Introduce the joint map Φ(w) = aΦM(µ) + bΦA(α), where a = 1/√log |B| and b = √2/τ √m. It can be shown that ∇ΦM(µ) = logµ + e, ∇ΦA(α) = α and ∇Φ(w) = (a logµ + ae, bα). At the t-th iteration, we first map wt = (µt,αt) into the dual space ∇Φ(wt) = (a log µt + ae, bαt), followed by one step of stochastic gradient descent in the dual space,
where ∂µ ˜ ϕ, ∂α˜ ϕ and ˜ g are the noisy unbiased estimation of ∂µϕ, ∂αϕ and g, respectively, and η is the step size. Next, we map ∇Φ(ut) back to the primal space, i.e., to find ut = (¯µt, ¯αt) such that
which implies that ¯µt = µt exp(-η∂µ˜ ϕ(µt,αt)/a) and ¯αt = αt + η∂α˜ ϕ(µt,αt)/b. Finally, we project (¯µt, ¯αt) back to M× A based on Kullback-Leibler divergence and Euclidean distance, respectively, i.e., we solve the following two optimization problems:
Fortunately, both problems have a closed-form solution. The latter is to project ¯αt onto the bounded box, so we have ¯αt+1 = max{min{¯αt, τe}, 0}. For the former, the Lagrangian function leads to µ⊤ log(µ/¯µt) + ζ(e⊤µ - 1), where ζ is the dual variable. By setting the partial derivative of µ to zero, i.e., log(µ/¯µt) + e + ζe = 0, we have ¯µt+1 = ¯µt exp(-1 - ζ). Since ¯µt+1 belongs to a simplex, hence 1 = e⊤ ¯µt+1 = e⊤ ¯µt exp(-1 - ζ) = ‖ ¯µt‖1 exp(-1 - ζ), which implies that exp(-1 - ζ) = 1/‖¯µt‖1, thus we have ¯µt+1 = ¯µt/‖¯µt‖1. Once we have yt+1 = (¯µt+1, ¯αt+1), start the above procedures fromwt again, but this time using the gradient evaluated at yt+1 instead of wt. In words, one iteration of mirror prox consists of two steps of mirror descent starting from the same point, but using gradients evaluated at different points. Figure 2 illustrates one iteration of stochastic mirror prox method.
The remaining question is how to find the stochastic gradient ∂µ˜ ϕ(µt,αt) and ∂α˜ ϕ(µt,αt). Note that ϕ(µ,α) = ∑k: ˆ yk∈B µkG(α, ˆ yk), so we have
By uniformly choosing an index it from {1, 2, . . . , |B|}, we can obtain ∂µ˜ ϕ(µt,αt, it) = [0, . . . , |B|G(αt, ˆ yit ) . . . , 0].
| Algorithm 1 Stochastic mirror prox for ssODM | |
|---|---|
| 1: | Input: maximum iteration number T, ODM parameters λ1, λ2, ν, θ, upper bound τ, stopping criteria ι. |
| 2: | Initialize µ0 ← [1/|B|, . . . , 1/|B|], α0 ← 0, t ← 0. |
| 3: | while t < T do |
| 4: | Uniformly select it, i′t from {1, 2, . . . , |B|}. |
| 5: | ∂µ˜ ϕ ← [0, . . . , |B|G(αt, ˆ yit ) . . . , 0]. |
| 6: | Select jt from {1, 2, . . . , |B|} according to µt. |
| 7: | ∂α˜ ϕ← ∂αG(αt, ˆ yjt ). |
| 8: | ¯µt ←µt exp(-η∂µ˜ ϕ/a). |
| 9: | ¯αt ←αt + η∂α˜ ϕ/b. |
| 10: | ¯µt+1 ← ¯µt/‖¯µt‖1. |
| 11: | ¯αt+1 ←max{min{¯αt, τe}, 0}. |
| 12: | ∂µ˜ ϕ ← [0, . . . , |B|G( ¯αt+1, ˆ yi′t ) . . . , 0]. |
| 13: | Select j ′t from {1, 2, . . . , |B|} according to ¯µt+1. |
| 14: | ∂α˜ ϕ← ∂αG( ¯αt+1, ˆ yj ′t ). |
| 15: | ¯µt+1 ←µt exp(-η∂µ˜ ϕ/a). |
| 16: | ¯αt+1 ←αt + η∂α˜ ϕ/b. |
| 17: | µt+1 ← ¯µt+1/‖¯µt+1‖1. |
| 18: | αt+1 ←max{min{¯αt+1, τe}, 0}. |
| 19: | t ← t + 1. |
| 20: | if duality gap is smaller than ι then |
| 21: | Break. |
| 22: | end if |
| 23: | end while |
| 24: | Output: µ, α. |
On the other hand, by randomly sampling an index jt according to the distribution µt on {1, 2, . . . , |B|}, we can obtain ∂α ˜ ϕ(µt, αt, jt) = ∂αG(αt, ˆ yjt ). It can be shown that
and ˜ g(wt) = (∂µ ˜ ϕ(µt, αt, it), -∂α ˜ ϕ(µt,αt, jt)) is an unbiased estimation of g(wt). Algorithm 1 summarizes the pseudo-code of ssODM.
4.3 Recovering the Label Assignment
Once the saddle point (µ⋆ ,α⋆ ) is found, we can obtain the label assignment of unlabeled instances according to sign(∑k: ˆ yk∈B µ⋆k ˆ yk).
5 Empirical Study
In this section, we empirically evaluate the proposed method on twenty UCI data sets. Table 1 summarizes the statistics of these data sets. As can be seen, the number of instance is ranged from 62 to 72,309, and the dimensionality is ranged from 6 to 20,958, covering a broad range of properties.
5.1 Setting
For each UCI data set, 75% of the examples are randomly chosen for training, and the rest for testing. We investigate the performance of each approach with varying amount of labeled data (namely, 5%, 10% of the labeled data). The whole setup is repeated 10 times and the average accuracies as well as the standard deviations on the test set are recorded.
| ID | Data set | #Instance | #Feature |
|---|---|---|---|
| 1 | echocardiogram | 62 | 8 |
| 2 | house | 232 | 16 |
| 3 | heart | 270 | 9 |
| 4 | heart-statlog | 270 | 13 |
| 5 | haberman | 306 | 14 |
| 6 | live-discorders | 345 | 6 |
| 7 | ionosphere | 351 | 33 |
| 8 | vehicle | 435 | 16 |
| 9 | house-votes | 435 | 16 |
| 10 | clean1 | 476 | 166 |
| 11 | wdbc | 569 | 14 |
| 12 | isolet | 600 | 51 |
| 13 | austra | 690 | 15 |
| 14 | australian | 690 | 42 |
| 15 | diabetes | 768 | 8 |
| 16 | german | 1,000 | 59 |
| 17 | optdigits | 1,143 | 42 |
| 18 | krvskp | 3,196 | 36 |
| 19 | sick | 2,643 | 28 |
| 20 | real-sim | 72,309 | 20,958 |
We compare our method with 1) the standard SVM (using labeled data only) [Cortes and Vapnik, 1995], and four state-of-the-art S3VMs, namely 2) Transductive SVM (TSVM) [Joachims, 1999]; 3) Laplacian SVM [Belkin et al., 2006]; 4)UniverSVM (USVM) [Collobert et al., 2006]; and 5) S4VM [Li and Zhou, 2011]. Note that TSVM and USVM adopt the same objective but with different optimization strategies (local search and constrained convex-concave procedure, respectively), so they may converge to different local minimum.
For all the methods, the parameters C, λ1, λ2 are selected from {1, 10, 100, 1000}. For ssODM, ν and θ are selected from [0.2, 0.4, 0.6, 0.8]. For all data sets, both the linear and Gaussian kernels are used. In particular, the width σ of Gaussian kernel is picked from {0.25√γ, 0.5√γ, √γ, 2√γ, 4√γ}, where γ is the average distance between instances. All the experiments are repeated 10 times and the average performance is reported with the best parameter setting.
5.2 Performance
Table 2 summarizes the results on the twenty UCI data sets. As can be seen, for the two settings, i.e., 5% labeled data and 10% labeled data, ssODM achieves the best performance on 14 and 13 data sets, respectively. In addition, in comparing with S3VMs which do not consider margin distribution, the win/tie/loss counts show that ssODM is always better or comparable, almost never worse than S3VMs.
6 Conclusions
Semi-supervised support vector machines (S3VMs), which employs the large margin heuristic from support vector machines, have achieved more accurate results than other semisupervised methods. Recent studies disclosed that instead of minimum margin, it is more crucial to optimize the margin distribution for SVM-style learning algorithms. Inspired by this recognition, we propose a novel approach ssODM for semi-supervised learning by optimizing the margin distribution. To conquer the resultant saddle point problem, we extend a stochastic mirror prox method which can converge more quickly in practise than general sub-gradient descent for non-smooth problem. Experimental results in various data sets show that our method achieves promising performance, which further verifies the superiority of optimal margin distribution learning. In the future, we will apply importance sampling [Schmidt et al., 2015] and variance reduction techniques [Johnson and Zhang, 2013] to further accelerate our method and extend it to other learning settings, i.e., multiinstance multi-label learning.
| Data set | Label | SVM | TSVM | LapSVM | USVM | S4VM | ssODM |
|---|---|---|---|---|---|---|---|
| echocardiogram | 5% | .800±.071• | .741±.082• | .644±.221• | .801±.061• | .804±.078• | .819±.011 |
| house | 10% 5% | .812±.077• .900±.041• | .761±.087• .903±.056• | .684±.201• .906±.067• | .821±.063• .903±.068• | .824±.073• .909±.073• | .839±.015 .917±.014 |
| heart | 10% 5% | .912±.047• .700±.080• .751±.049• | .921±.057• .752±.062• | .918±.171• .733±.063• | .911±.053• .762±.063• .779±.053• | .924±.066 .772±.061• | .923±.018 .783±.054 |
| 10% 5% | .730±.010• .751±.008• | .783±.047• .762±.061• | .756±.041• | .781±.053• | .784±.056 | .798±.016 | |
| heart-statlog | 10% | .792±.062• | .753±.068• .793±.058• | .791±.041• | .791±.061 .831±.056 | .789±.054 .824±.045 | |
| haberman | 5% 10% | .651±.071• .683±.067• | .614±.053• .634±.047• | .577±.112• .601±.098• .556±.055• | .743±.123 .794±.113 | .732±.121 .787±.111 | .737±.141 |
| live-discorders ionosphere | 5% 10% 5% 10% 5% | .568±.051• .583±.067• .678±.061• .691±.057• .748±.041• | .555±.053• .584±.047• .822±.113◦ .861±.047◦ | .601±.088• .656±.058• .681±.058• .773±.052• | .590±.052 .642±.103 .770±.064• .791±.043• .741±.069• | .530±.071• .590±.091• .701±.064• .761±.054• .789±.062 | .788±.011 .588±.048 .639±.008 .791±.041 |
| vehicle house-votes | 10% 5% 10% 5% | .761±.035• .888±.031• .897±.026• | .751±.083• .772±.062• .891±.043• | .791±.046• .899±.032• .901±.032• | .760±.060• .901±.053• | .819±.067 .912±.041 | .831±.015 .791±.041 .823±.035 |
| clean1 | 10% 5% 10% | .580±.061• .591±.054• .813±.064• | .899±.031• .621±.074• .641±.054• | .641±.065• .649±.055• .808±.048• | .910±.045• .623±.065• .634±.542• .820±.061• | .925±.035 .641±.041• .651±.038• | .925±.035 .929±.031 .661±.045 .671±.035 |
| wdbc | 5% | .831±.054• .970±.029• .973±.025• | .803±.034• .823±.031• .976±.031• | .818±.044• .980±.038• | .825±.060• .987±.037• | .821±.048 .829±.043 .988±.048 | .829±.039 .835±.033 |
| isolet | .978±.030• | .985±.032• | .989±.035• | .989±.043 | .991±.040 | ||
| 10% | .766±.033• | ||||||
| austra | 5% 5% | .770±.059• .790±.051• .672±.081• | .820±.030 .850±.032 | .796±.031• .782±.031• .791±.030• | .781±.045• .788±.037• .789±.041• | .775±.041• | .992±.045 .813±.040 |
| australian diabetes | 5% 10% 5% | .681±.075• .679±.080• .703±.071• | .681±.034• .692±.038• .683±.039• | .761±.069• | .792±.040• .771±.049• | .799±.036• .788±.042• .797±.041• .768±.048• | .843±.034 .799±.035 .805±.039 .790±.049 |
| german optdigits | 10% 5% | .700±.030• .700±.030• .922±.020 | .703±.034• .703±.010• .708±.010• .891±.090• | .770±.063• .708±.021• .709±.016• .902±.050• | .776±.040• .710±.029• .713±.023• .913±.069• | .771±.044• .715±.041• .718±.043• | .798±.040 .726±.045 .731±.037 .919±.042 |
| krvskp sick real-sim | 10% 5% 10% 5% 10% 5% 10% 5% | .925±.023 .911±.023• .919±.020• .941±.021 .946±.020 .901±.022• | .894±.091• .899±.091• .903±.090• .932±.090• .938±.088• .913±.065• | .912±.055• .921±.054• .927±.050• .939±.034• .941±.033• .922±.035• .929±.031• | .917±.064• .916±.068• .925±.069• .935±.048• .939±.041• .930±.043• | .918±.041 .913±.040 .926±.042• .929±.040• .929±.045• .934±.041• .924±.049• | .921±.040 .932±.040 .936±.045 .948±.048 .955±.043 .922±.033 |
| ssODM: | 10% 5% | .909±.020• 18/2/0 | .919±.062• 18/1/1 | 20/0/0 | .933±.040• 18/2/0 | 13/7/0 | |
| 10% | .928±.043• | ||||||
| .941±.028 | |||||||
| 18/2/0 | 20/0/0 | ||||||
| w/t/l | 18/1/1 | 18/2/0 | 11/9/0 |
@inproceedings{ijcai2018p431,
  title     = {Semi-Supervised Optimal Margin Distribution Machines},
  author    = {Zhang, Teng and Zhou, Zhi-Hua},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {3104--3110},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/431},
  url       = {https://doi.org/10.24963/ijcai.2018/431},
}
TY - CPAPER TI - Semi-Supervised Optimal Margin Distribution Machines AU - Zhang, Teng AU - Zhou, Zhi-Hua T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 3104 EP - 3110 DO - 10.24963/ijcai.2018/431 UR - https://doi.org/10.24963/ijcai.2018/431 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





