
A Unified Approach for Multi-step Temporal-Difference Learning with Eligibility Traces in Reinforcement Learning
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2984-2990.
https://doi.org/10.24963/ijcai.2018/414
Keywords
- Uncertainty in AI: Markov Decision Processes
- Machine Learning: Machine Learning
- Machine Learning: Reinforcement Learning
- Uncertainty in AI: Sequential Decision Making
- Uncertainty in AI: Decision;Utility Theory
Abstract
Recently, a new multi-step temporal learning algorithm Q(σ) unifies n-step Tree-Backup (when σ = 0) and
n-step Sarsa (when σ = 1) by introducing a sampling parameter σ. However, similar to other multi-step
temporal-difference learning algorithms, Q(σ) needs much memory consumption and computation time. Eligibility trace is an important mechanism to transform the off-line updates into efficient on-line ones which consume less memory and computation time. In this paper, we combine the original Q(σ) with eligibility traces and propose a new algorithm, called Qπ(σ,λ), where λ is trace-decay parameter. This new algorithm unifies Sarsa(λ) (when σ = 1) and Qπ (λ) (when σ = 0). Furthermore, we give an upper error bound of Qπ(σ,λ) policy evaluation algorithm. We prove that Qπ (σ, λ) control algorithm converges to the optimal value function exponentially. We also empirically compare it with conventional temporal-difference learning methods. Results show that, with an intermediate value of σ, Qπ(σ,λ) creates a mixture of the existing algorithms which learn the optimal value significantly faster than the extreme end (σ = 0, or 1).
- [Bertsekas and Tsitsiklis, 1996] Dimitri P. Bertsekas and John N. Tsitsiklis. Neuro Dynamic Programming. Athena scientific Belmont, MA, 1996.
- [Bertsekas et al., 2012] Dimitri P Bertsekas, Dimitri P Bert- sekas, Dimitri P Bertsekas, and Dimitri P Bertsekas. Dynamic programming and optimal control, volume 2. Athena scientific Belmont, MA, 2012.
- [De Asis et al., 2018] Kristopher De Asis, J Fernando Hernandez-Garcia, G Zacharias Holland, and Richard S Sutton. Multi-step reinforcement learning: A unifying al- gorithm. AAAI, 2018.
- [Dumke, 2017] Markus Dumke. Double q(σ) and q(σ, λ): Unifying reinforcement learning control algorithms. arXiv preprint arXiv:1711.01569, 2017.
- [Harutyunyan, 2016] Rémi Harutyunyan. Q (λ) with off- policy corrections. In Algorithmic Learning Theory: 27th International Conference, ALT 2016, Bari, Italy, Octo- ber 19-21, 2016, Proceedings, volume 9925, page 305. Springer, 2016.
- [Jaakkola et al., 1994] Tommi Jaakkola, Michael I Jordan, and Satinder P Singh. Convergence of stochastic iterative dynamic programming algorithms. In Advances in neural information processing systems, pages 703-710, 1994.
- [Kearns and Singh, 2000] Michael J Kearns and Satinder P Singh. Bias-variance error bounds for temporal difference updates. In COLT, pages 142-147, 2000.
- [Munos et al., 2016] Rémi Munos, Tom Stepleton, Anna Harutyunyan, and Marc Bellemare. Safe and efficient off- policy reinforcement learning. In Advances in Neural In- formation Processing Systems, pages 1054-1062, 2016.
- [Rummery and Niranjan, 1994] Gavin A Rummery and Ma- hesan Niranjan. On-line Q-learning using connectionist systems, volume 37. University of Cambridge, Department of Engineering, 1994.
- [Seijen and Sutton, 2014] Harm Seijen and Rich Sutton. True online td (lambda). In International Conference on Machine Learning, pages 692-700, 2014.
- [Singh and Dayan, 1998] Satinder Singh and Peter Dayan. Analytical mean squared error curves for temporal differ- ence learning. Machine Learning, 32(1):5-40, 1998.
- [Singh and Sutton, 1996] Satinder P Singh and Richard S Sutton. Reinforcement learning with replacing eligibility traces. Machine learning, 22(1-3):123-158, 1996.
- [Singh et al., 2000] Satinder Singh, Tommi Jaakkola, Michael L Littman, and Csaba Szepesvári. Convergence results for single-step on-policy reinforcement-learning algorithms. Machine learning, 38(3):287-308, 2000.
- [Sutton and Barto, 1998] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction, vol- ume 1. MIT press Cambridge, 1998.
- [Sutton and Barto, 2017] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction, vol- ume 1. MIT press Cambridge, 2017.
- [Sutton, 1984] Richard S Sutton. Temporal credit assign- ment in reinforcement learning. PhD thesis, University of Massachusetts, 1984.
- [Sutton, 1988] Richard S Sutton. Learning to predict by the methods of temporal differences. Machine learning, 3(1):9-44, 1988.
- [Sutton, 1996] Richard S Sutton. Generalization in rein- forcement learning: Successful examples using sparse coarse coding. In Advances in neural information process- ing systems, pages 1038-1044, 1996.
- [Van Seijen et al., 2009] Harm Van Seijen, Hado Van Has- selt, Shimon Whiteson, and Marco Wiering. A theoretical and empirical analysis of expected sarsa. In Adaptive Dy- namic Programming and Reinforcement Learning, 2009. ADPRL'09. IEEE Symposium on, pages 177-184. IEEE, 2009.
- [Van Seijen et al., 2016] Harm Van Seijen, A Rupam Mah- mood, Patrick M Pilarski, Marlos C Machado, and Richard S Sutton. True online temporal-difference learn- ing. Journal of Machine Learning Research, 17(145):1- 40, 2016.
- [Watkins, 1989] Christopher John Cornish Hellaby Watkins. Learning from delayed rewards. PhD thesis, King's Col- lege, Cambridge, 1989.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
In reinforcement learning (RL), experiences are sequences of states, actions and rewards which are generated by the agent interacts with environment. The agent's goal is learning from experiences and seeking an optimal policy from the delayed reward decision system. There are two fundamental mechanisms of learning have been studied in RL, one is temporaldifference (TD) learning method which is a combination of Monte Carlo method and dynamic programming [Sutton, 1988]. The other one is eligibility trace [Sutton, 1984; Watkins, 1989] which is a short-term memory process as a function of states. TD(λ) combines TD learning with eligibility trace and unifies one-step learning (λ = 0) and Monte Carlo methods (λ = 1) through the trace-decay parameter λ [Sutton, 1988]. Results show that the unified algorithm TD(λ) performs better at an intermediate value of λ rather than either extreme case.
∗Corresponding author.
Recently, Multi-step Q(σ) [Sutton and Barto, 2017] unifies n-step Sarsa (σ = 1, full-sampling) and n-step Treebackup (σ = 0, pure-expectation). For some intermediate value σ(0 < σ < 1), Q(σ) creates a mixture of full-sampling and pure-expectation approach, can perform better than the extreme case σ = 0 or 1 [De Asis et al., 2018].
The results in [De Asis et al., 2018] implies a fundamental trade-off problem in reinforcement learning: should one estimates the value function by adopting pure-expectation (σ = 0) algorithm or full-sampling (σ = 1) algorithm? Although pure-expectation approach has lower variance, it needs more complexity and larger calculation [Van Seijen et al., 2009]. On the other hand, full-sampling algorithm needs smaller calculation time, however, it may have a worse asymptotic performance [De Asis et al., 2018]. Multi-step Q(σ) [Sutton and Barto, 2017] firstly attempts to combine pure-expectation with full-sample algorithms, however, multi-step temporaldifference learning is too expensive in complexity of time and space during its training.
Eligibility trace is an effective way to address the above complexity problem. In this paper, we try to combine the Q(σ) algorithm with eligibility trace, and create a new algorithm, called Qπ (σ, λ). The proposed Qπ (σ, λ) unifies the Sarsa(λ) algorithm [Rummery and Niranjan, 1994] and Qπ (λ) algorithm [Harutyunyan, 2016]. When σ varies from 0 to 1, Qπ (σ, λ) changes continuously from Sarsa(λ) (σ = 1 in Qπ (σ, λ)) to Qπ (λ) (σ = 0 in Qπ (σ, λ)). We also focus on the trade-off between pure-expectation and full-sample in control task, our experiments show that an intermediate value σ achieves a better performance than either extreme case.
Our contributions are summarised as follows: We define a mixed-sampling operator through which we derive the proposed Qπ (σ, λ) policy evaluation algorithm and control algorithm. The new algorithm Qπ (σ, λ) unifies Sarsa(λ) and Qπ (λ). For Qπ (σ, λ) policy evaluation algorithm, we give its upper error bound. For the control problem, we prove that both of the off-line and on-line Qπ (σ, λ) algorithm converge to the optimal value function.
2 Framework and Notation
The standard episodic reinforcement learning framework [Sutton and Barto, 2017] is often formalized as Markov decision processes (MDPs). Such framework considers 5-tuples formM = (S,A,P,R, γ), where S indicates the set of all states, A indicates the set of all actions, P a ss′ is the element of P and it indicates a state-transition probability from state s to state s′ under taking action a, a ∈ A, s′ , s ∈ S; Ra ss′ is the element of R and it indicates the expected reward for a transition, γ ∈ [0, 1] is the discount factor. A policy π is a probability distribution on S × A and stationary policy is a policy that does not change over time. In this paper, we denote {(St,At,Rt)}t≥0 as a trajectory of the state-reward sequence in one episode.
state-action value q maps on S ×A to R, for a given policy π, has a corresponding state-action value:
Optimal state-action value is defined as:
Bellman operator T π :
Bellman optimal operator T ∗ :
where P π ∈ R|S|×|S| , Rπ ∈ R|S|×|A| , and the corresponding entry is:
Value function qπ and q∗ satisfy the following Bellman equation and optimal Bellman equation correspondingly:
Both T π and T ∗ are γ-contraction operator with sup-norm, that is to say, ‖T Q1 - T Q2‖∞ ≤ γ‖Q1 - Q2‖∞ for any Q1, Q2 ∈ R|S|×|A| , where T = T π or T ∗ . Based on the fact that the fixed point of a contraction operator is unique, then value iteration converges: (T π )nQ→ qπ , (T ∗ )nQ→ q∗ , as n→∞, for any initial Q.
2.1 One-step TD Learning Algorithms
Unfortunately, both the system (1) and (2) can not be solved directly because of fact that the P and R in the environment are usually unknown or the dimension of S is huge in practice. A unavailable model in reinforcement learning is called model free.
TD learning algorithm [Sutton, 1984; Sutton, 1988] is one of the most significant algorithms in model free reinforcement learning, the idea of bootstrapping is critical to TD learning: the evluation of the value function are used as targets during the learning process.
In reinforcement learning, target policy µ is the policy being learned about , and the policy µ used to generate trajectory {(St,At,Rt)}t≥0 is called the behavior policy. If π = µ, the learning is called on-policy learning, otherwise it is off-policy learning.
Sarsa: For a given sample transition (S,A,R, S′ ,A′ ), Sarsa [Rummery and Niranjan, 1994] is a on-policy learning algorithm and it updates Q value as follows:
where δS k is the k-th TD error, αk is stepsize.
Expected-Sarsa: Expected-Sarsa [Van Seijen et al., 2009] uses expectation of all the next state-action value pairs according to the target policy π to estimate Q value as follows:
where δES k is the k-th expected TD error. Expected-Sarsa is a off-policy learning algorithm if µ ̸= π, for example, when π is greedy with respect to Q then Expected-Sarsa is restricted to Q-Learning [Watkins, 1989]. If the trajectory is generated by π, Expected-Sarsa is a on-policy algorithm [Van Seijen et al., 2009].
The above two algorithms are guaranteed convergence under some conditions [Singh et al., 2000; Van Seijen et al., 2009].
Q(σ): One-step Q(σ) [Sutton and Barto, 2017; De Asis et al., 2018] is a weighted average between the Sarsa update and Expected Sarsa update through a sampling parameter σ:
where σ ∈ [0, 1] is degree of sampling. When σ = 1, Q(σ) denotes a full-sampling, and σ = 0 , Q(σ) denotes a pureexpectation with no sampling. δS t and δES t are defined in (4) and (5).
2.2 λ-Return Algorithm
One-step TD learning algorithm can be generalized to multistep bootstrapping learning method. The λ-return algorithm [Watkins, 1989] is a particular way to mix many multi-step TD learning algorithms through weighting n-step returns proportionally to λn-1 .
λ-operator 1 T π λ is a flexible way to express λ-return algorithm, for a given trajectory {(St,At,Rt)}t≥0 that is generated by policy π,
1 The notation is coincident with [Bertsekas et al., 2012].
where Gn = ∑nt=0 γ tRt + γ nQ(Sn+1,An+1) is n-step returns from initial state-action pair (S0,A0), the term ∑∞n=0 (1 - λ)λnGn is called λ-returns, and δn = Rn + γQ(Sn+1, An+1) - Q(Sn, An).
Based on the fact that qπ is fixed point of T π , thus qπ remains the fixed point of T π λ . When λ = 0, T π λ is equal to the usual Bellman operator T π . When λ = 1 , the evaluation iteration Qk+1 = T π λ |λ=1Qk becomes Monte Carlo method. It is well-known that λ trades off the bias of the bootstrapping with an approximate qπ , with the variance of sampling multi-step returns estimation [Kearns and Singh, 2000]. In practice, a high and intermediate value of λ could be typically better [Singh and Dayan, 1998; Sutton, 1996].
3 Mixed-sampling Operator
In this section, we present the mixed-sampling operator T π,µ σ , which is one of our key contribution and is flexible to analysis our new algorithm later. By introducing a sampling parameter σ ∈ [0, 1], the mixed-sampling operator varies continuously from pure-expectation method to full-sampling method. In this section, we analysis the contraction of T π,µ σ firstly. Then we introduce the λ-return vision of mixed-sampling operator T π,µ σ,λ . Finally, we give a upper error bound of the corresponding policy evaluation algorithm.
3.1 Contraction of Mixed-sampling Operator
Definition 1. Mixed-sampling operator T π,µ σ is a map on R|S|×|A| to R|S|×|A| , ∀s ∈ S, a ∈ A, σ ∈ [0, 1] :
where
The parameter σ is also degree of sampling that is introduced by the Q(σ) algorithm [De Asis et al., 2018]. In one of extreme end (σ = 0, pure-expectation), T π,µ σ=0 deduces the n-step returns Gπn in Qπ (λ) [Harutyunyan, 2016], where Gπn = ∑t+n k=t γ k-t δES k +γ n+1EπQ(St+n+1, ·), δES k is the kth expected TD error. Multi-step Sarsa [Sutton and Barto, 2017] is in another extreme end (σ = 1, full-sampling). Every intermediate value σ creates a mixed method varies continuously from pure-expectation to full-sampling which is why we call T π,µ σ mixed-sample operator.
λ-Return Version We now define the λ-version of T π,µ σ , and denote it as T π,µ σ,λ :
where the λ is the parameter takes the from TD(0) to Monte Carlo version as usual. When σ = 0, T π,µ σ=0,λ is restricted to T π,µ λ [Harutyunyan, 2016], when σ = 1, T π,µ σ=1,λ is restricted to λ-operator.
The next theorem provides a basic property of T π,µ σ,λ .
Theorem 1. The operator T π,µ σ,λ is a γ-contraction: for any q1, q2,
Furthermore, for any initial Q0, the sequence {Q}∞k=0 is generated by the iterationQk+1 = T π,µ σ,λ Qk,
then {Qk}∞k=0 converges to the unique fixed point of T π,µ σ,λ .
Proof. Unfolding the operator T π,µ σ,λ , we have
where B = (I - γλP µ )-1 . Based the fact that both T µ λ [Bertsekas et al., 2012] and T π,µ λ [Harutyunyan, 2016; Munos et al., 2016] are γ-contraction operators, and T π,µ σ,λ is the convex combination of above operators, thus T π,µ σ,λ is a γ-contraction.
3.2 Upper Error Bound of Policy Evaluation
In this section we discuss the ability of policy evaluation iteration Qk+1 = T π,µ σ,λ Qk in Theorem 1. Our results show that when µ and π are sufficiently close, the ability of the policy evaluation iteration increases gradually as the σ decreases from 1 to 0.
Lemma 1. If a positive sequence {ak}∞k=1 satisfies ak+1 ≤ αak + β, then for any |α| < 1, we have
Furthermore, for any ϵ > 0, ∃K, s.t, ∀k > K has the following estimation
Theorem 2 (Upper error bound of policy evaluation). Consider the policy evaluation algorithm Qk+1 = T π,µ σ,λ Qk, if the behavior policy µ is ϵ-away from the target policy π, in the sense that maxs∈S ‖π(s, a) - µ(s, a)‖1 ≤ ϵ, ϵ < 1-γ λγ , and γ(1 + 2λ) < 1, then ∃K, s.t, ∀k > K, the policy evaluation sequence{Qk}∞k=0 satisfies
where for a given policy π, M, Cπ is determined by the learning system.
Proof. Firstly, we provide an equation which could be used later:
Rewrite the policy evaluation iteration:
Note qπ is fixed point of T π,µ λ [Harutyunyan, 2016], then we merely consider next estimator:
The first equation is derived by replacing q in (10) with Qk. Since µ is ϵ-away from π, the first inequality is determined the following fact:
where Ms = |A|maxa |Ras | is determined by the reinforcement learning system and is independent of π, µ. M = maxs∈S Ms. For the given policy π, ‖qπ ‖ is a constant that is determined by learning system, we denote it Cπ.
Remark 1: The proof in Theorem 2 strictly dependent on the assumption that ϵ is smaller but never to be zero, where the ϵ is a bound of discrepancy between the behavior policy µ and target policy π. That is to say, the ability of the prediction of policy evaluation iteration is dependent on the gap between µ and π. A more profound discussion about this gap is related to λ-ϵ trade off [Harutyunyan,2016] which is beyond the scope in this paper.
4 Qπ (σ, λ) Control Algorithm
In this section, we present Qπ (σ, λ) 2 algorithm for control. We analyze the off-line version of Qπ (σ, λ) which converges to optimal value function exponentially fast.
Considering the typical iteration (Qk, πk), where πkis calculated by the following two steps: {µk}k≥0 is a sequence of corresponding behavior policies,
2 The work in [Dumke, 2017] proposes a similar method, called Q(σ, λ) control algorithm. Our Qπ (σ, λ) is different from theirs due to the different version of eligibility trace updating.
that is πk+1 is greedy policy with repect to Qk+1. We call the approach introduced by above step1 and step2 Qπ (σ, λ) control algorithm.
In the following Theorem 3, we presents the convergence rate of Qπ (σ, λ) control algorithm.
Theorem 3 (Convergence of Qπ (σ, λ) Control Algorithm). Considering the sequence {(Qk, πk)}k≥0 generated by the Qπ (σ, λ) control algorithm, for the given λ, γ ∈ (0, 1), then
Particularly, if λ < 1-γ 2γ , then 0 < η < 1 and sequence {Qk}k≥1 converges to q∗ exponentially fast:
Proof. By the definition of T π,µ σ,λ ,
we have 3 :
Algorithm1:On-line Qπ (σ, λ) algorithm
Require:Initialize Q0(s, a) arbitrarily, ∀s ∈ S, ∀a ∈ A
Require:Initialize µk to be the behavior policy
Parameters: step-size αt ∈ (0, 1]
Repeat (for each episode):
End For
3 The section inequality is based on the next two results: [Munos et al., 2016] Theorem2 and [Bertsekas et al., 2012] Proposition6.3.10.
5 On-line Implementation of Qπ (σ, λ)
We have discussed the contraction property of mixedsampling operator T π,µ σ,λ , and via it we have introduced the Qπ (σ, λ) control algorithm. Both of the iterations in Theorem 2 and Theorem 3 are the version of offline. In this section, we give the on-line version of Qπ (σ, λ) and discuss its convergence.
5.1 On-line Learning
Off-line learning is too expensive due to the learning process must be carried out at the end of an episode, however, online learning updates value function with a lower computational cost, better performance. There is a simple interpretation of equivalence between off-line learning and on-line learning which means that, by the end of an episode, the total updates of the forward view(off-line learning) is equal to the total updates of the backward view(on-line learning) [Sutton and Barto, 1998]. By the view of equivalence 4 , on-line learning can be seen as an implementation of offline algorithm in an inexpensive manner. Another interpretation of online learning was provided by [Singh and Sutton, 1996], TD learning with accumulate trace comes to approximate everyvisit Monte-Carlo method and TD learning with replace trace comes to approximate first-visit Monte-Carlo method.
The iterations in Theorem 2 and Theorem 3 are the version of expectations. In practice, we can only access to the trajectory {(St, At, Rt)}t≥0. By statistical approaches, we can utilize the trajectory to estimate the value function. Algorithm 1 corresponds to online form of Qπ (σ, λ).
5.2 On-line Learning Convergence Analysis
We make some common assumptions which are similar to [Bertsekas and Tsitsiklis, 1996; Harutyunyan, 2016].
Assumption 1. ∑t≥0 P[(St,At) = (s, a)] > 0, minimum visit frequency, which implies a complete exploration.
Assumption 2. For every historical chain Ft in a MDPs, P[Nt(s, a) ≥ k|Ft] ≤ γρk , where ρ is a positive constants, k is a positive integer and Nt(s, a) denotes the times of the pair (s, a) is visited in the t-th trajectory Ft.
For the convenience of expression, we give some notations firstly. Let Qok,t be the vector obtained after t iterations in the k-th trajectory, and the superscript o emphasizes online learning. We denote the k-th trajectory as {(St,At,Rt)}t≥0 sampled by the policy µk. Then the online update rules can be expressed as follows: ∀ (s, a) ∈ S × A :
where Tk is the length of the k-th trajectory.
4 The true online learning was firstly introduced by [Seijen and Sutton, 2014], more details in [Van Seijen et al., 2016].
Theorem 4. Based on the Assumption 1 and Assumption 2, step-size αt satisfying,∑t αt = ∞, ∑t α2 t < ∞, πk is greedy with respect to Qok , then Qok w.p.1 ---→ q∗ as k → ∞, where w.p.1 is short for with probability one.
Proof. After some simple algebra:
αk = E[Nk(s, a)]αk(s, a).
We rewrite the off-line update:
where ˜
where Qλk,t (s, a) is the λ-returns at time t when the pair (s, a) is visited in the k-th trajectory, the superscript f in Qfk+1 (s, a) emphasizes the forward (off-line) update. Nk(s, a) denotes the times of the pair (s, a) visited in the k-th trajectory. We define Resk(s, a) as the residual between on-line estimate Gok and off-line estimate Gfk (s, a) in the k-th trajectory:
Set ∆k(s, a) = Qok (s, a)-q∗ (s, a) which is the error between after k-episode the learned value function Qok and optimal value function q∗ , then we consider the next random iterative process:
where
Step1:Upper bound on Resk(s, a):
where 0 ≤ t ≤ Tk. Resk,t(s, a) is the difference between the total on-line updates of first t steps and the first t times off-line update in k-th trajectory. By induction on t, we have:
where C is a consist and ∆k,t = ‖Qok,t (s, a) - q∗ (s, a)‖, αM = max0≤t≤Tk {αt(s, a)}. Based on the condition of step-size in the Theorem 4, αM w.p.1 ---→ 0, then we have (12). Step2: max(s,a) Eµk [Fk(s, a)] ≤ γ max(s,a) ‖∆k(s, a)‖.
From the property of eligibility trace(more details refer to [Bertsekas et al., 2012]) and Assumption 2, we have:
Then according to (11), for some t > 0:
Step3: Qok w.p.1 ---→ q∗ as k →∞. Considering the iteration (11) and Theorem 1 in [Jaakkola et al., 1994], then we have Qok w.p.1 ---→ q∗ .
6 Experiments
6.1 Experiment for Prediction Capability
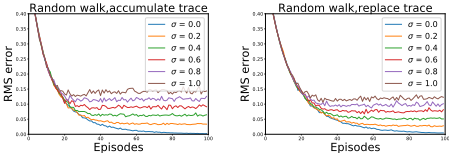
In this section, we test the prediction abilities of Qπ (σ, λ) in 19-state random walk environment [De Asis et al., 2018]. The agent at each state has two action : left and right, and taking each action with equal probability. We compare the rootmean-square(RMS) error as a function of episodes, σ varies dynamically σ from 0 to 1 with steps of 0.2. In this experiment, we set behavior policy µ=[0.5-D,0.5+D], D ∼ U[- 0.01,0.01], where U is uniform distribution.
Results in Figure 1 show that the performance of Qπ (σ, λ) increases gradually as the σ decreases from 1 to 0, which just verifies the upper error bound in Theorem2.
6.2 Experiment for Control Capability
We test the control capability of Qπ (σ, λ) in the classical episodic task, mountain car [Sutton and Barto, 1998]. Because the state space in this environment is continuous, we use tile coding function approximation [Sutton and Barto,
1998], and use the version 3 of Sutton's tile coding software (n.d.) with 8 tilings.
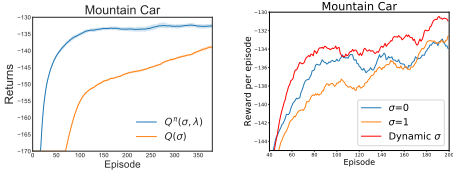
In the right part of Figure 2, we collect the data by varing σ from 0 to 1 with steps of 0.02. Results show that Qπ (σ, λ) significantly converges faster than Q(σ). In the left part of Figure 2, results show that the Qπ (σ, λ) with σ in an intermediate value can outperform Qπ (λ) and Sarsa(λ).
Table1 and Table2 summarize the average return after 50 and 200 episodes. In order to gain more insight into the nature of the results, we run σ from 0 to 1 with steps of 0.02, we take the statistical method according to [De Asis et al., 2018], lower (LB) and upper (UB) 95% confidence interval bounds are provided to validate the results. Dynamic σ in the table mean that σ does not need to remain constant throughout every episode [De Asis et al., 2018].In this experiment, σ is a function of time, a normal distribution, σt ∼ N(0.5, 0.12 ). The average return after only 50 episodes could be interpreted as a measure of initial performance, whereas the average return after 200 episodes shows how well an algorithm is capable of learning[De Asis et al., 2018]. Results show that Qπ (σ, λ) with a intermediate value had the best final performance.
| Algorithm | Mean | UB | LB |
|---|---|---|---|
| Qπ (σ = 0, λ),Qπ (λ) | -193.56 | -179.33 | -197.06 |
| Qπ (σ = 1, λ),Sarsa(λ) | -196.84 | -182.69 | -200.42 |
| Qπ (σ = 0.5, λ) | -195.99 | -181.60 | -199.62 |
| Dynamic σ | -195.01 | -177.14 | -195.01 |
| Algorithm | Mean | UB | LB |
|---|---|---|---|
| Qπ (σ = 0, λ),Qπ (λ) | -144.04 | -138.49 | -146.44 |
| Qπ (σ = 1, λ),Sarsa(λ) | -145.72 | -140.04 | -148.21 |
| Qπ (σ = 0.5, λ) | -143.71 | -137.92 | -146.12 |
| Dynamic σ | -142.62 | -137.24 | -145.09 |
7 Conclusion
In this paper we presented a new method, called Qπ (σ, λ), which unifies Sarsa(λ) and Qπ (λ). We solved a upper error bound of Qπ (σ, λ) for the ability of policy evaluation. Furthermore, we discussed the convergence of Qπ (σ, λ) control algorithm to q∗ under some conditions. The proposed approach was compared with one-step and multi-step TD learning methods and the results demonstrated its effectiveness.
Acknowledgements
This work was partly supported by National Key Research and Development Program of China (2017YFB1002503), Natural Science Foundation of China (No.61772460), and Zhejiang Provincial Natural Science Foundation of China (LR15F020001).
@inproceedings{ijcai2018p414,
  title     = {A Unified Approach for Multi-step Temporal-Difference Learning with Eligibility Traces in Reinforcement Learning},
  author    = {Yang, Long and Shi, Minhao and Zheng, Qian and Meng, Wenjia and Pan, Gang},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2984--2990},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/414},
  url       = {https://doi.org/10.24963/ijcai.2018/414},
}
TY - CPAPER TI - A Unified Approach for Multi-step Temporal-Difference Learning with Eligibility Traces in Reinforcement Learning AU - Yang, Long AU - Shi, Minhao AU - Zheng, Qian AU - Meng, Wenjia AU - Pan, Gang T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2984 EP - 2990 DO - 10.24963/ijcai.2018/414 UR - https://doi.org/10.24963/ijcai.2018/414 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





