
Efficient Adaptive Online Learning via Frequent Directions
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2748-2754.
https://doi.org/10.24963/ijcai.2018/381
Keywords
- Machine Learning: Machine Learning
- Machine Learning Applications: Big data ; Scalability
- Machine Learning: Online Learning
Abstract
By employing time-varying proximal functions, adaptive subgradient methods (ADAGRAD) have improved the regret bound and been widely used in online learning and optimization. However, ADAGRAD with full matrix proximal functions (ADA-FULL) cannot deal with large-scale problems due to the impractical time and space complexities, though it has better performance when gradients are correlated. In this paper, we propose ADA-FD, an efficient variant of ADA-FULL based on a deterministic matrix sketching technique called frequent directions. Following ADA-FULL, we incorporate our ADA-FD into both primal-dual subgradient method and composite mirror descent method to develop two efficient methods. By maintaining and manipulating low-rank matrices, at each iteration, the space complexity is reduced from $O(d^2)$ to $O(\tau d)$ and the time complexity is reduced from $O(d^3)$ to $O(\tau^2d)$, where $d$ is the dimensionality of the data and $\tau \ll d$ is the sketching size. Theoretical analysis reveals that the regret of our methods is close to that of ADA-FULL as long as the outer product matrix of gradients is approximately low-rank. Experimental results show that our ADA-FD is comparable to ADA-FULL and outperforms other state-of-the-art algorithms in online convex optimization as well as in training convolutional neural networks (CNN).
- [Chang and Lin, 2011] Chih-Chung Chang and Chih-Jen Lin. Libsvm : a library for support vector machines. ACM Transactions on Intelligent Systems and Technology, 2(3):1-27, 2011.
- [Charikar et al., 2004] Moses Charikar, Kevin Chen, and Martin Farach-Colton. Finding frequent items in da- ta streams. Theoretical Computer Science, 312(1):3-15, 2004.
- [Chechik et al., 2010] Gal Chechik, Varun Sharma, Uri Shalit, and Samy Bengio. Large scale online learning of image similarity through ranking. Journal of Machine Learning Research, 11:1109-1135, 2010.
- [Drineas et al., 2006] Petros Drineas, Ravi Kannan, and Michael W. Mahoney. Fast monte carlo algorithms for matrices i: Approximating matrix multiplication. SIAM Journal on Computing, 36(1):132-157, 2006.
- [Duchi et al., 2010] John Duchi, Shai Shalev-Shwartz, Y- oram Singer, and Ambuj Tewari. Composite objective mir- ror descent. In Proceedings of the 23rd Annual Conference on Learning Theory, pages 14-26, 2010.
- [Duchi et al., 2011] John Duchi, Elad Hazan, and Yoram Singer. Adaptive subgradient methods for online learning and stochastic optimization. Journal of Machine Learning Research, 12:2121-2159, 2011.
- [Freund and Schapire, 1999] Yoav Freund and Robert E. Schapire. Large margin classification using the perceptron algorithm. Machine Learning, 37(3):277-296, 1999.
- [Ghashami and Phillips, 2014] Mina Ghashami and Jeff M. Phillips. Relative errors for deterministic low-rank matrix approximations. In Proceedings of the twenty-fifth annu- al ACM-SIAM symposium on Discrete algorithms, pages 707-717, 2014.
- [Ghashami et al., 2016] Mina Ghashami, Jeff M. Phillips E- do Liberty, and David P. Woodruff. Frequent directions: Simple and deterministic matrix sketching. SIAM Journal on Computing, 45(5):1762-1792, 2016.
- [Hager, 1989] William W. Hager. Updating the inverse of a matrix. SIAM review, 31(2):221-239, 1989.
- [Hazan et al., 2007] Elad Hazan, Amit Agarwal, and Satyen Kale. Logarithmic regret algorithms for online convex op- timization. Machine Learning, 69(2):169-192, 2007.
- [Jain et al., 2008] Prateek Jain, Brian Kulis, Inderjit S. D- hillon, and Kristen Grauman. Online metric learning and fast similarity search. In Advances in Neural Information Processing Systems 21, pages 761-768, 2008.
- [Kakade et al., 2008] Sham M. Kakade, Shai Shalev- Shwartz, and Ambuj Tewari. Efficient bandit algorithms for online multiclass prediction. In Proceedings of the 25th International Conference on Machine Learning, pages 440-447, 2008.
- [Kaski, 1998] Samuel Kaski. Dimensionality reduction by random mapping: Fast similarity computation for cluster- ing. In Proceedings of the 1998 IEEE International Joint Conference on Neural Networks, pages 413-418, 1998.
- [Krizhevsky, 2009] Alex Krizhevsky. Learning multiple lay- ers of features from tiny images. Technical report, Univer- sity of Toronto, 2009.
- [Krummenacher et al., 2016] Gabriel Krummenacher, Brian McWilliams, Yannic Kilcher, Joachim M. Buhmann, and Nicolai Meinshausen. Scalable adaptive stochastic opti- mization using random projections. In Advances in Neu- ral Information Processing Systems 29, pages 1750-1758, 2016.
- [LeCun et al., 1998] Yann LeCun, Léon Bottou, Yoshua Bengio, and Patrick Haffner. Gradient-based learning ap- plied to document recognition. In Proceedings of the IEEE, volume 86, pages 2278-2324, 1998.
- [Liberty, 2013] Edo Liberty. Simple and deterministic ma- trix sketching. In Proceedings of the 19th ACM SIGKDD international conference on Knowledge discovery and da- ta mining, pages 581-588, 2013.
- [Luo et al., 2016] Haipeng Luo, Alekh Agarwal, Nicolo Cesa-Bianchi, and John Langford. Efficient second order online learning by sketching. In Advances in Neural Infor- mation Processing Systems 29, pages 902-910, 2016.
- [Mairal et al., 2010] Julien Mairal, Francis Bach, Jean Ponce, and Guillermo Sapiro. Online learning for ma- trix factorization and sparse coding. Journal of Machine Learning Research, 11:19-60, 2010.
- [Misra and Gries, 1982] J. Misra and David Gries. Finding repeated elements. Science of Computer Programming, 2(2):143-152, 1982.
- [Nalko et al., 2011] N. Nalko, P. G. Martinsson, and J. A. Tropp. Finding structure with randomness: Probabilistic algorithms for constructing approximate matrix decompo- sitions. SIAM review, 53(2):217-288, 2011.
- [Netzer et al., 2011] Yuval Netzer, Tao Wang, Adam Coates, Alessandro Bissacco, Bo Wu, and Andrew Y. Ng. Reading digits in natural images with unsupervised feature learn- ing. In NIPS Workshop on Deep Learning and Unsuper- vised Feature Learning 2011, 2011.
- [Shalev-Shwartz, 2011] Shai Shalev-Shwartz. Online learn- ing and online convex optimization. Foundations and Trends in Machine Learning, 4(2):107-194, 2011.
- [Wan and Zhang, 2018] Yuanyu Wan and Lijun Zhang. Ac- celerating adaptive online learning by matrix approxima- tion. In Proceedings of the 22nd Pacific-Asia Conference on Knowledge Discovery and Data Mining, 2018.
- [Woodruff, 2014] David P. Woodruff. Sketching as a tool for numerical linear algebra. Foundations and Trends in Ma- chine Learning, 10(1-2):1-157, 2014.
- [Xiao, 2009] Lin Xiao. Dual averaging method for regu- larized stochastic learning and online optimization. In Advances in Neural Information Processing Systems 22, pages 2116-2124, 2009.
- [Yuan et al., 2015] Yuan Yuan, Jianwu Fang, and Qi Wang. Online anomaly detection in crowd scenes via structure analysis. IEEE Transactions on Cybernetics, 43(3):548- 561, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Online learning refers to the process of answering a sequence of questions given answers to previous questions, which enjoys an attractive combination of computational efficiency and theoretical guarantees [Shalev-Shwartz, 2011]. Recently, it has received ever-increasing attention due to the emergence of large-scale applications such as online classification [Freund and Schapire, 1999; Kakade et al., 2008], online metric learning [Jain et al., 2008; Chechik et al., 2010], online matrix factorization [Mairal et al., 2010] and online anomaly detection [Yuan et al., 2015]. Adaptive subgradient methods (ADAGRAD), which employ proximal functions that adapt to the geometry of the data observed in earlier iterations, are popular for online learning and optimization [Duchi et al., 2011]. According to the type of proximal functions, ADAGRAD can be divided into learning with full matrix proximal functions (ADA-FULL) and learning with diagonal matrix proximal functions (ADA-DIAG). In contrast to ADA-FULL, ADA-DIAG has been successfully applied to many large-scale applications because of its light computations and storages.
However, the diagonal matrix maintained in ADA-DIAG only contains limited information of gradient outer products. This shortcoming causes the regret of ADA-DIAG worse than that of ADA-FULL when the high-dimensional data is dense and has an approximately low-rank structure. In consideration of this dilemma, Duchi et al. [2011] proposed an open question concerning whether we can efficiently use full matrices in the proximal functions. To solve this problem, Krummenacher et al. [2016] utilized random projections to approximate ADA-FULL, and developed two methods, namely ADA-LR and RADAGRAD. Compared with ADA-FULL, ADA-LR has the same space complexity O(d2 ) and a slightly reduced time complexity O(τ d2 ) where d is the dimensionality of the data and τ ≪ d is the number of random projections. Due to the quadratic dependence on d, ADA-LR is impractical for high-dimensional data, though it is equipped with a formal regret bound. In contrast, the time and space complexities of RADAGRAD are linear in d, but it lacks theoretical guarantees owing to further approximations. In our recent work [Wan and Zhang, 2018], we also utilized random projections to accelerate ADA-FULL, and proposed ADA-DP that has complexities linear in d. However, its theoretical guarantees are non-deterministic, and the regret bound contains additional terms that never vanish.
To tackle the above limitations, we develop an efficient variant of ADA-FULL that is also principled. The computational bottleneck of ADA-FULL is to store the outer product matrix of gradients and compute its square root in each round. We note that a similar bottleneck also exists in other second order methods such as online Newton step (ONS) [Hazan et al., 2007], and recently matrix sketching techniques have been used to reduce the computational cost of ONS [Luo et al., 2016]. Motivated by previous works, we propose to employ frequent directions [Ghashami et al., 2016] to approximate the outer product matrix of gradients in ADA-FULL. By utilizing the low-rank structure, the efficient variant of ADA-FULL, named ADA-FD, reduces the space complexity fromO(d2 ) to O(τd) and the time complexity fromO(d3 ) to O(τ 2d), which implies both the space and time complexities of our method are linear in the dimensionality d.
Moreover, because the idea of ADAGRAD can be incorporated into either primal-dual subgradient method [Xiao, 2009] or composite mirror descent method [Duchi et al., 2010], we also develop two efficient methods according to the type of subgradient methods, and prove that our methods enjoy the regret bound close to that of ADA-FULL. The slight differences in the regret bound are caused by the approximation error of frequent directions and vanish when the sketching size τ is larger than the rank of gradient outer products. More generally, when the outer product matrix of gradients is approximately low-rank, the differences do not affect the order of the regret bound. To verify the efficiency and effectiveness of our ADA-FD, we conduct several numerical experiments on online convex optimization and training CNN. The results turn out that our ADA-FD performs comparably with ADAFULL but is much more efficient.
2 RelatedWork
ADAGRAD Adaptive subgradient methods describe and analyze an apparatus for learning the proximal functions which are modified according to data observed in earlier iterations. This property significantly simplifies choosing the step size while ensures regret guarantees as good as the proximal functions tuned manually. In the following, we provide a brief introduction of ADAGRAD for primal-dual subgradient method [Xiao, 2009] and composite mirror descent method [Duchi et al., 2010].
At each round t = 1, 2, · · · , T, the online learner predicts a point βt ∈ Rd and then the adversary reveals a composite function Ft(β) = ft(β) + ϕ(β) where ft and ϕ are convex. The learner suffers loss Ft(βt) for this round, and the goal of learner is to minimize the regret that is defined as R(T ) = ∑Tt=1 Ft(βt) - ∑Tt=1 Ft(β∗ ) where β∗ is the fixed optimal predictor. Let gt ∈ ∂ft(βt) be a particular vector in the subdifferential set ∂ft(β) of function ft. The outer product matrix of gradients is defined as Gt = ∑ti=1 gig⊤ i , and Ht has the following two choices:
where δ > 0 is a parameter making Ht invertible. The proximal term is given by Ψt(β) = 1 2 〈β,Htβ〉 and let BΨt (x, y) = Ψt(x) - Ψt(y) - 12 〈∇Ψt (y), x - y〉 denote the Bregman divergence associated with Ψt. Let η > 0 be a fixed step size and ¯ gt = ∑ti=1 gi. In each iteration, the primal-dual subgradient method updates by
And the composite mirror descent method updates by
Because the storage complexity of Gt is O(d2 ) and the time complexity of finding its square root is O(d3 ), ADA-FULL is impractical for large-scale problems.
To reduce the complexities of ADA-FULL, Krummenacher et al. [2016] proposed two methods based on the fast randomized singular value decomposition (SVD) [Nalko et al., 2011] to approximate the proximal term Ψt(β). Let Π ∈ Rτ×d be the random matrix of the subsampled randomized Fourier transform. They first used the following steps to update βt:
and the resulting algorithm is refereed to as ADA-LR. Note that the space and time complexities of ADA-LR are respectively O(d2 ) and O(τd2 ), which prevent ADA-LR from being practical for high-dimensional data. By introducing more randomized approximations, they presented a more scalable algorithm RADAGRAD that performs the following updates:
where qr update means QR decomposition with rank-one updates. In this case, RADAGRAD reduces the space and time complexities to O(τd) and O(τ 2d) respectively. Unfortunately, it is a heuristic method and lacks theoretical guarantees. When ft(βt) = l(β⊤ t xt) where xt is a data vector independent from algorithm, we recently proposed ADA-DP [Wan and Zhang, 2018] based on random projections to attain theoretical guarantees and keep complexities linear in d. However, due to the randomness of random projections, the regret bound of ADA-DP is non-deterministic and is worse than ADA-FULL even when τ = d.
Matrix Sketching and Frequent Directions For any given matrix A ∈ Rt×d , the purpose of sketching is to generate a matrix B ∈ Rτ×d where τ ≪ t is the sketching size such that A ≈ B or AA⊤ ≈ BB⊤. There are many matrix sketching techniques via frequent directions [Liberty, 2013; Ghashami and Phillips, 2014; Woodruff, 2014; Ghashami et al., 2016], random projection [Kaski, 1998; Charikar et al., 2004; Woodruff, 2014] and column selection [Drineas et al., 2006]. Frequent directions [Ghashami et al., 2016] is a deterministic matrix sketching technique by extending the well-known algorithm for approximating item frequencies in streams [Misra and Gries, 1982]. Let B = [b1, b2, · · · , bτ ]⊤ = 0τ×d where τ ≪ min{t, d}. For
Algorithm 1 Adaptive Dual Averaging via Frequent Directions
- 1: Input: η > 0, δ > 0, τ, S0 = 0τ×d, ¯ g0 = 0, β1 = 0;
- 2: for t = 1, ..., T do
- 3: Receive gradient gt =∇ft(βt)
- 4: Insert gt into the last row of St-1 and ¯ gt = ¯ gt-1 + gt
- 5: Compute UΣV⊤ = St-1, σt = Σ2tt
- 6: Compute St = Σ′V⊤ where Σ′ = √Σ2 -σtIτ
- 7: βt+1 = - ηδ (¯ gt -V(δIτ +Σ′ )-1Σ′V⊤¯ gt )
- 8: end for
any given matrix A = [a1, a2, · · · , at]⊤, frequent directions processes each row of A as follows
and products a sketch matrix B.
Recently, the techniques of matrix sketching have been used by Luo et al. [2016] to accelerate online Newton step [Hazan et al., 2007]. They studied ONS that updates by
where α > 0 and ηt > 0 are some parameters for general convex functions, and used matrix sketching techniques to construct a low-rank approximation of the second order information. Motivated by Luo et al. [2016], our work employs frequent directions to calculate a low-rank approximation of the full matrix, which obviously reduces the storage and time complexities of ADA-FULL. Compared to the approximation algorithm used by Krummenacher et al. [2016], frequent directions has two advantages which are deterministic theoretical properties and easy implementations.
3 An Efficient Variant of ADA-FULL
In this section, we first describe how to make ADA-FULL more efficient by frequent directions. Then we introduce our proposed methods and the corresponding theoretical results. Finally, we compare our work with Krummenacher et al. [2016] and Luo et al. [2016]. To facilitate presentations, we consider the case ϕ = 0, and our methods can be extended to the general case ϕ ̸= 0.
3.1 Algorithms
Define Ct = [g1, g2, ..., gt]⊤ ∈ Rt×d , where each row is a gradient vector. The outer product matrix of gradients can be calculated as
To accelerate the computation of H-1 t , we take advantage of frequent directions to produce a low-rank approximation of Ct denoted by St = [st1 , st2 , ..., stτ ]⊤ ∈ Rτ×d . Then we can redefine the Ht in the proximal term as
Algorithm 2 Adaptive Mirror Descent via Frequent Directions
- 1: Input: η > 0, δ > 0, τ, S0 = 0τ×d, β1 = 0;
- 2: for t = 1, ..., T do
- 3: Receive gradient gt =∇ft(βt)
- 4: Insert gt into the last row of St-1
- 5: Compute UΣV⊤ = St-1, σt = Σ2tt
- 6: Compute St = Σ′V⊤ where Σ′ = √Σ2 -σtIτ
- 7: βt+1 = βt - ηδ (gt -V(δIτ +Σ′ )-1Σ′V⊤gt )
- 8: end for
Let SVD of St be St = UΣV⊤ where U ∈ Rτ×τ , Σ ∈ Rτ×τ and V ∈ Rτ×d , then we have (S⊤t St)1/2 = VΣV⊤. By Woodbury Formula [Hager, 1989], we have
With the above procedures, we propose an efficient variant of ADA-FULL, named as adaptive online learning via frequent directions (ADA-FD). Then, we first consider to incorporate ADA-FD into primal-dual subgradient method. According to the update rules in (1), in the t-th round our algorithm performs the following updates
The detailed procedures of ADA-FD for primal-dual subgradient method are summarized in Algorithm 1 and this method is named as adaptive dual averaging via frequent directions.
Moreover, we incorporate ADA-FD into composite mirror descent method. According to the update rules in (2), in the t-th round our algorithm performs the following updates
The detailed procedures of ADA-FD for composite mirror descent method are summarized in Algorithm 2 and this method is named as adaptive mirror descent via frequent directions.
Remark First, the space complexity of our two methods is O(τd) caused by the maintenance of St,U,V. And the time complexity of our two methods is O(τ 2d) caused by step 5 in each algorithm which contains SVD. Thus, both of them are linear in the dimensionality d. Second, compared with the update rules of ADA-LR (3) and RADAGRAD (4), our update rules (6) and (7) do not need random projection and are more simple. Third, when ϕ ̸= 0, the computational cost of H-1 t can still be reduced dramatically, though the updating of βt may not have closed-form solution.
3.2 Theoretical Guarantees
Compared with RADAGRAD, a significant advantage of our methods is they are equipped with formal theoretical guarantees similar to ADA-FULL. We present regret bounds for Algorithms 1 and 2 in the following two theorems respectively and postpone the detailed analysis to the supplementary material due to the limitation of space.
Theorem 1. Adaptive dual averaging via frequent directions ensures
where ∆T = ∑Ti=1 σi.
Theorem 2. Adaptive mirror descent via frequent directions ensures
where ∆T = ∑Ti=1 σi.
For comparisons, let us introduce the theoretical guarantees of ADA-FULL below.
Theorem 3. (Theorem 7 of Duchi et al. [2011]) Provided with δ ≥ max t≤T ‖gt‖2, ADA-FULL incorporated into primal-
dual subgradient method ensures
ADA-FULL incorporated into composite mirror descent method ensures
Remark Compared with the Theorem 3, we confirm that our methods enjoy the regret bound close to that of ADAFULL, and we point out the slight differences as following. First, the regret bounds of our two methods contain an additional term, respectively ∑Tt=1 √σt 2η max t≤T ‖βt+1‖22 and
inequality and ∆T = ∑Ti=1 σi, we have
which means the additional term does not affect the order of the regret bounds when ∆T is small. Second, our two bound-
max (1, √∆T δ ) respectively, which does not change the order of the regret bounds when ∆T is small. Let Ckt denote the minimizer of ‖Ct -Ckt ‖F over all rank k matrices. According to the property of frequent directions, we have
for any k < τ , which means ∆T is small when the outer product matrix of gradients is approximately low-rank. Moreover, when GT is low-rank and rank(GT ) = r, we have ∆T = 0 by choosing τ = r + 1.
3.3 Discussions
We would like to emphasize the differences between our work and Krummenacher et al. [2016]. First, both ADALR and RADAGRAD only consider composite mirror descent method, ignoring primal-dual subgradient method. Second, unlike random projections adopted in Krummenacher et al. [2016], our work makes use of frequent directions that belongs to deterministic matrix sketching techniques. As a result, our methods are much more simple than ADA-LR and RADAGRAD while the theoretical guarantees of our methods are deterministic, contrary to the probabilistic regret bound of ADA-LR. Third, our methods are very efficient in the sense that the time and storage complexities are linear in the dimensionality d, without losing regret bound. By contrast, RADAGRAD reaches similar complexities while does not have theoretical justifications.
Next, we discuss the differences between our work and Luo et al. [2016]. First, our methods and Luo et al. [2016] are designed for different tasks. Our goal is to develop an efficient variant of ADA-FULL, and the goal of Luo et al. [2016] is to accelerate ONS. Note that ADA-FULL is a data dependent algorithm for general convex functions and ONS is proposed to derive a logarithmic regret for exp-concave functions. Second, the theoretical analysis in our work is obviously different from Luo et al. [2016]. They provide a regret bound of ONS with order O(√Td) for general convex functions by setting ηt = O(1/√t). Although its update rules (5) can be reformulated as
which is similar to ADAGRAD, its O(√Td) bound destroys the data dependent property. Third, the main algorithm of Luo et al. [2016] can be regarded as a mirror descent method. In contrast, our work proposes two efficient methods for primal-dual subgradient method and composite mirror descent method respectively.
4 Experiments
In this section, we perform numerical experiments to verify the efficiency and effectiveness of our ADA-FD. First, we show that ADA-FD approximates ADA-FULL well and outperforms ADA-DIAG. Second, we compare ADA-FD with RADAGRAD that is also an approximation of ADA-FULL and FD-SON [Luo et al., 2016] that is an approximation of ONS by frequent directions.
4.1 Online Regression
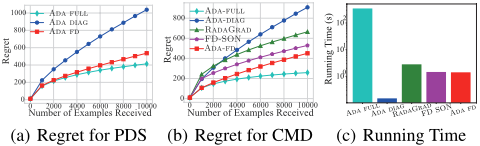
First, we consider the problem of online regression where ft(β) = |β⊤xt - yt| and yt = β⊤ ∗ xt with ideal synthetic data. Specifically, we set T = 10, 000, d = 500 and β∗ = ˆ β∗/‖ ˆ β∗‖2 where each entry of ˆ β∗ is drawn independently fromN(0, 1). In order to meet the requirement of approximately low-rank structure, each data point xt is sampled independently from a Gaussian distribution N(µ, Σ) where µ = 1 and Σ has rapidly decaying eigenvalues λj(Σ) = λ0j-α with α = 2 and λ0 = 100.
For primal-dual subgradient method, we compare ADAFD against ADA-FULL and ADA-DIAG. And for composite mirror descent method, we compare ADA-FD against ADAFULL, ADA-DIAG, RADAGRAD and FD-SON. Parameters η and δ are searched in {1e-4, 1e-3, · · · , 100}, and we choose the best values for each algorithm. For fairness, all algorithms are run with the same permutation of the function sequence. Because of the randomness of RADAGRAD, its results are averaged over 5 runs. Figure 1 shows the comparison of regret among different algorithms and the comparison of running time among different algorithms for composite mirror descent method where we set τ = 10 for methods using matrix approximation. For both primal-dual subgradient method and composite mirror descent method, our ADA-FD outperforms ADA-DIAG and is significantly faster than ADA-FULL. For composite mirror descent method, our ADA-FD outperforms RADAGRAD and FD-SON. From the comparison of running time, we find that ADA-FD is faster than RADAGRAD and as fast as FD-SON. The comparison of running time for following experiments is similar and can be found in the supplementary.
4.2 Online Classification
Then, we perform online classification to evaluate the performance of our ADA-FD with two real world datasets from LIBSVM repository [Chang and Lin, 2011]: Gisette and Epsilon which are high-dimensional and dense. At each round, the learning algorithm receives a single example (xt, yt) and suffers the squared hinge loss ft(β) =
| Dataset | #Examples | #Features | #Classes |
|---|---|---|---|
| Gisette | 6,000/1,000 | 5,000 | 2 |
| Epsilon | 400,000/100,000 | 2,000 | 2 |
| MNIST | 60,000/10,000 | 784 | 10 |
| CIFAR10 | 50,000/10,000 | 3,072 | 10 |
| SVHN | 73,257/26,032 | 3,072 | 10 |
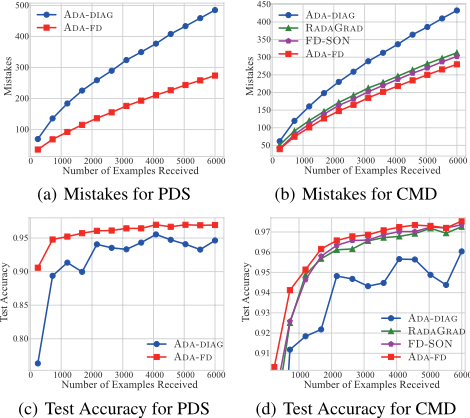
12 (max (0, 1- ytβ⊤xt ))2 . Each learning algorithm ends with a single pass through the training data. Following Duchi et al. [2011], we adopt two metrics to measure the performance: the online mistakes and the offline accuracy on the testing data. For primal-dual subgradient method, we compare ADA-FD against ADA-DIAG. And for composite mirror descent method, we compare ADA-FD against ADA-DIAG, RADAGRAD and FD-SON. We omit the result of ADA-FULL, because it is too slow. Similar as before, parameters η and δ are searched in {2e-4, 2e-3, · · · , 20}, and we choose the best values for each algorithm. To reduce the computational cost, we set the sketching size τ = 10 for Gisette and τ = 40 for Epsilon.
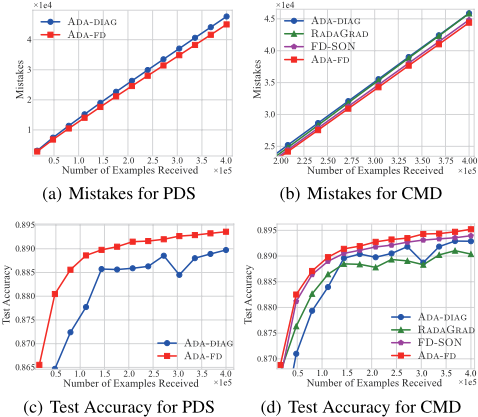
Both datasets are divided into training part and testing part, and the numbers of training and testing examples are shown in Table 1. For training data, we generate 5 random permutations, and report the average results. Figures 2 and 3 show the comparison of mistakes and test accuracy during training among different algorithms on Gisette and Epsilon. We find that our ADA-FD outperforms ADA-DIAG, RADAGRAD and FD-SON on both datasets. Note that RADAGRAD is outperformed by ADA-DIAG in term of test accuracy on Epsilon as shown in Figure 3(d). It means that our ADA-FD has better ability to approximate ADA-FULL than RADAGRAD.
4.3 Non-convex Optimization in CNN
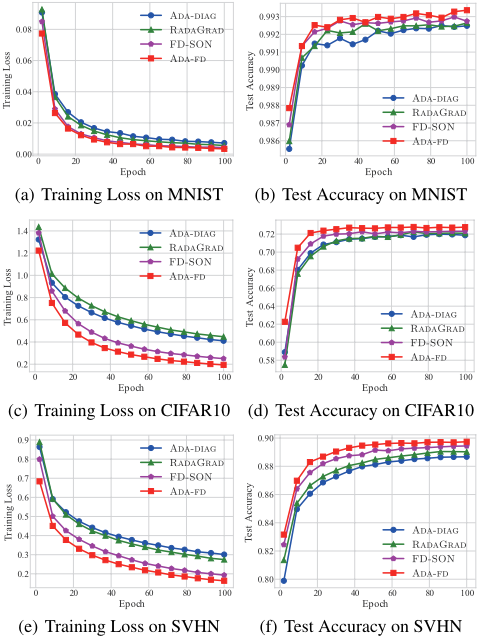
Besides convex optimization, ADA-DIAG incorporated into composite mirror descent method has also been applied to non-convex optimization such as training neural networks and has performed well. Therefore, we take convolutional neural networks (CNN) as an example and compare ADAFD against ADA-DIAG, RADAGRAD and FD-SON on training the classical neural networks. We consider a 4-layer CNN from Keras examples directory 1 , which contains two 3 × 3 convolutional layers and one fully connected layer (128 hidden units followed by 0.5 dropout). The activation function is ReLU. The first convolutional layer generates 32 channels, and the second convolutional layer generates 64 channels followed by 2 × 2 max-pooling and 0.25 dropout. The final layer is a softmax layer and the objective is cross-entropy loss. We use this simple and standard architecture to perform classification on the MNIST [LeCun et al., 1998], CIFAR10 [Krizhevsky, 2009] and SVHN datasets [Netzer et al., 2011]. Parameters η and δ of all algorithms are searched in {1e-8, 1e-7, · · · , 1}, andwe choose the best values for each algorithm. Following Krummenacher et al. [2016], we only consider applying ADA-FD, RADAGRAD and FD-SON to the convolutional layers, and other layers are still trained with ADA-DIAG. To reduce the computational cost, we set the sketching size τ = 20 for all datasets. For all algorithms, we run 5 times with batch size 128 and report the average results. Figure 4 shows the comparison of training loss and test accuracy during training among different algorithms. We find that our ADA-FD outperforms ADA-DIAG, RADAGRAD and FDSON on all datasets when applied to training CNN. We note that RADAGRAD is outperformed by ADA-DIAG in term of
training loss on CIFAR10 as shown in Figure 4(c). This result once again validates that our ADA-FD has better ability to approximate ADA-FULL than RADAGRAD.
1 https://github.com/keras-team/keras/blob/master/examples
5 Conclusions
In this paper, we present ADA-FD to approximate ADA-FULL using frequent directions. According to the type of subgradient methods, we develop two efficient methods. The time and space complexities of both algorithms are linear in the dimensionality d, which means our methods have similar efficiency compared to ADA-DIAG. Furthermore, according to our theoretical analysis, our methods enjoy the regret bound close to that of ADA-FULL when the outer product matrix of gradients is approximately low-rank. Numerical experiments show that our ADA-FD outperforms ADA-DIAG, RADAGRAD and FD-SON and is close to ADA-FULL.
Acknowledgments
This work was partially supported by the National Key R&D Program of China (SQ2018YFB100002), NSFC (61603177), JiangsuSF (BK20160658), YESS (2017QNRC001), and the Collaborative Innovation Center of Novel Software Technology and Industrialization.
@inproceedings{ijcai2018p381,
  title     = {Efficient Adaptive Online Learning via Frequent Directions},
  author    = {Wan, Yuanyu and Wei, Nan and Zhang, Lijun},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2748--2754},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/381},
  url       = {https://doi.org/10.24963/ijcai.2018/381},
}
TY - CPAPER TI - Efficient Adaptive Online Learning via Frequent Directions AU - Wan, Yuanyu AU - Wei, Nan AU - Zhang, Lijun T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2748 EP - 2754 DO - 10.24963/ijcai.2018/381 UR - https://doi.org/10.24963/ijcai.2018/381 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





