
Algorithms or Actions? A Study in Large-Scale Reinforcement Learning
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2717-2723.
https://doi.org/10.24963/ijcai.2018/377
Keywords
- Uncertainty in AI: Markov Decision Processes
- Machine Learning Applications: Game Playing
- Machine Learning: Reinforcement Learning
- Multidisciplinary Topics and Applications: Computer Games
Abstract
Large state and action spaces are very challenging to reinforcement learning. However, in many domains there is a set of algorithms available, which estimate the best action given a state. Hence, agents can either directly learn a performance-maximizing mapping from states to actions, or from states to algorithms. We investigate several aspects of this dilemma, showing sufficient conditions for learning over algorithms to outperform over actions for a finite number of training iterations. We present synthetic experiments to further study such systems. Finally, we propose a function approximation approach, demonstrating the effectiveness of learning over algorithms in real-time strategy games.
- [Barriga et al., 2015] Nicolas A. Barriga, Marius Stanescu, and Michael Buro. Puppet Search: Enhancing Scripted Behavior by Look-Ahead Search with Applications to Real-Time Strategy Games. In AIIDE, 2015.
- [Barriga et al., 2017] Nicolas A. Barriga, Marius Stanescu, and Michael Buro. Combining strategic learning and tactical search in real-time strategy games. In AIIDE, 2017.
- [Barriga et al., 2018] Nicolas A. Barriga, Marius Stanescu, and Michael Buro. Game Tree Search Based on Non-Deterministic Action Scripts in Real-Time Strategy Games. IEEE Transactions on Games, 10(1):67-77, 2018.
- [Bontrager et al., 2016] Philip Bontrager, Ahmed Khalifa, André Mendes, and Julian Togelius. Matching Games and Algorithms for General Video Game Playing. In AIIDE, 2016.
- [Churchill and Buro, 2013] David Churchill and Michael Buro. Portfolio Greedy Search and Simulation for Large-Scale Combat in StarCraft. In CIG, 2013.
- [Dietterich, 2000] Thomas G. Dietterich. Hierarchical reinforce- ment learning with the MAXQ value function decomposition. JAIR, 13:227-303, 2000.
- [Jiang et al., 2014] Albert Xin Jiang, Leandro Soriano Marcolino, Ariel D. Procaccia, Tuomas Sandholm, Nisarg Shah, and Milind Tambe. Diverse randomized agents vote to win. In NIPS, 2014.
- [Lagoudakis and Littman, 2000] Michail G. Lagoudakis and Michael L. Littman. Algorithm selection using reinforcement learning. In ICML, 2000.
- [Lelis, 2017] Levi H. S. Lelis. Stratified Strategy Selection for Unit Control in Real-Time Strategy Games. In IJCAI, 2017. IJCAI
- [Marcolino et al., 2013] Leandro Soriano Marcolino, Albert Xin Jiang, and Milind Tambe. Multi-agent team formation: diver- sity beats strength? In IJCAI, 2013. IJCAI
- [Marcolino et al., 2014] Leandro Soriano Marcolino, Haifeng Xu, Albert Xin Jiang, Milind Tambe, and Emma Bowring. Give a hard problem to a diverse team: Exploring large action spaces. In AAAI, 2014.
- [Ontañón, 2017] Santiago Ontañón. Combinatorial multi-armed ban- dits for real-time strategy games. JAIR, 58, 2017.
- [Ontañón and Buro, 2015] Santiago Ontañón and Michael Buro. Ad- versarial hierarchical-task network planning for complex real-time games. In IJCAI, 2015.
- [Ontañón et al., 2013] Santiago Ontañón, Gabriel Synnaeve, Al- berto Uriarte, Florian Richoux, David Churchill, and Mike Preuss. A survey of real-time strategy game AI research and competition in StarCraft. IEEE Transactions on Computational Intelligence and AI in Games (TCIAIG), 5(4):293-311, 2013.
- [Rice, 1976] John R. Rice. The algorithm selection problem. Ad- vances in computers, 15:65-118, 1976.
- [Rummery and Niranjan, 1994] Gavin A. Rummery and Mahesan Niranjan. On-line Q-learning using connectionist systems. Tech- nical report, Cambridge University, 1994.
- [Sailer et al., 2007] Frantisek Sailer, Michael Buro, and Marc Lanc- tot. Adversarial planning through strategy simulation. In CIG, 2007.
- [Sutton and Barto, 1998] Richard S. Sutton and Andrew G. Barto. Reinforcement learning: An introduction, volume 1. MIT press Cambridge, 1998.
- [Sutton et al., 1999] Richard S. Sutton, Doina Precup, and Satinder Singh. Between MDPs and semi-MDPs: A framework for tempo- ral abstraction in reinforcement learning. Artificial Intelligence, 112:181-211, 1999.
- [Tavares et al., 2016] Anderson Tavares, Hector Azpúrua, Amanda Santos, and Luiz Chaimowicz. Rock, Paper, StarCraft: Strategy Selection in Real-Time Strategy Games. In AIIDE, 2016.
- [Xu et al., 2008] Lin Xu, Frank Hutter, Holger H. Hoos, and Kevin Leyton-Brown. SATzilla: portfolio-based algorithm selection for SAT. JAIR, 32:565-606, 2008.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Reinforcement learning aims at developing general agents, which learn by acting directly on the problem action space [Sutton and Barto, 1998]. However, as the state and action spaces grow large, learning agents struggle to attain high performance. On the other hand, many domains have existing algorithms, tailored to the specific problem, and an agent could rely on a pool of algorithms to act on its behalf [Rice, 1976].
Given limited computational resources, however, there is an important conflict: should we learn over actions, training a reinforcement learning agent to discover the best actions to take, or should we learn over algorithms, trying to discover the best algorithm to estimate the best action in each state?
Previous work on reinforcement learning with abstract actions [Sutton et al., 1999; Dietterich, 2000] have shown that the optimal policy may not be attainable when learning over algorithms, although it may accelerate the reinforcement learning process. However, it is still unclear when each method should be preferred. Additionally, having a pool of algorithms may still not enable one to directly apply reinforcement learning techniques when the state space is also very large. In particular, Real-Time Strategy Games are a major challenge for Artificial Intelligence research, given their enormous action and state spaces [Onta˜n´on et al., 2013].
* A. R. Tavares and S. Anbalagan are both first authors.
In this work we establish the conditions where learning over algorithms is helpful, evaluating the sufficient strength of available algorithms, the relation among algorithms and actions set sizes, and possible underlying algorithm creation processes. Synthetic experiments further develop our conclusions. Additionally, we introduce a function approximation approach for Real-Time Strategy Games, demonstrating the effectiveness of learning over algorithms in a complex domain.
2 RelatedWork
In algorithm selection, one finds a performance-maximizing mapping from problem instances to algorithms [Rice, 1976]. It has been applied to a variety of problems, including SAT [Xu et al., 2008], sorting [Lagoudakis and Littman, 2000], and general video game playing [Bontrager et al., 2016].
Learning over algorithms is also related to action abstractions in reinforcement learning (RL). In MAXQ [Dietterich, 2000], a MDP "calls" other sub-MDPs organized in a graph. Options on MDPs [Sutton et al., 1999] are temporallyextended actions. Algorithms can be seen as one-step options: they can initiate in any state, act according to their internal policy and terminate after one transition. While Sutton et al. [1999] showed that the optimal policy is not attainable when the RL agent has no access to actions, they did not present a detailed study on the dilemma between learning over actions or over algorithms/options. Our theory provides new insights in terms of the required strength of algorithms, relations among algorithms and actions set sizes, and underlying algorithm creation processes.
The use of algorithms, or scripts, is widely adopted in realtime strategy games (RTS) research. For example, in script selection via Monte Carlo planning [Sailer et al., 2007] or assignment of scripts directly to units [Churchill and Buro, 2013] or unit types [Lelis, 2017] via hill-climbing. However, these works are combat-oriented, and do not tackle RTS games as a whole. Recent planning-based approaches, on the other hand, address the full games: AHTN [Onta˜n´on and Buro, 2015] combines hierarchical-task network (HTN) planning, with a minimax-like tree-search algorithm. PuppetSearch combines scripted behavior with game-tree search, by letting the scripts expose a restricted set of actions for the search algorithms to investigate. Two variations exist: PuppetAB [Barriga et al.,
2015] and PuppetMCTS [Barriga et al., 2018], which uses α-β pruning and Monte Carlo Tree Search as their search algorithms, respectively. StrategyTactics [Barriga et al., 2017] uses a convolutional neural network to predict the output of PuppetSearch, allowing more time to be used by a tactical search algorithm. NaiveMCTS [Onta˜n´on, 2017] also employs a Monte Carlo Tree Search, but uses a sampling strategy based on combinatorial multi-armed bandits (and thus does not use scripts). We test against all these approaches in our experiments.
All foregoing approaches require a forward model of the world to perform searches, which is not available in commercial RTS games and some real-world scenarios. Tavares et al. [2016] present a model-free approach that estimates algorithms' performance by running matches offline. However, a fixed algorithm must be chosen to play an entire match.
Our reinforcement learning approach with function approximation for algorithm selection in RTS games combines many strengths of related work: it tackles the game as a whole (not only combats), dynamically selects algorithms, and dismisses forward models.
3 Learning over Algorithms
We consider reinforcement learning (RL) tasks specified via Markov Decision Process (MDP), which are defined by a set of states S, a set of actions A, a reward function R : S×A → R, and a state transition function T : S × A × S → [0, 1]. The aim in reinforcement learning is to discover the optimal actionvalue function Q∗ (s, a), which indicates the value of taking action a in state s and following the optimal policy thereafter. Q∗ maximizes the expected sum of discounted rewards E[∑∞j=0 γ j rt+j], where t is the current time and rt+j is the reward received j steps in the future. The discount factor γ ∈ [0, 1] specifies how much the agent considers future rewards. RL agents also balance exploration and exploitation. As usual, we consider that when exploring (e.g., with ϵ probability) the agent chooses an action uniformly at random. When exploiting, the agent selects the action that maximizes Q∗ (s, a), with ties broken randomly.
Learning over actions is difficult in MDPs with large action sets, often requiring an impractical number of interactions with the environment to learn useful action-values. Thus, an agent may resort to existing algorithms, which could incorporate heuristics, search-based approaches, and/or domain knowledge, to act on its behalf. Formally, at each state, the agent selects an algorithm x from a set of algorithms X, which then selects an action a ∈ A to affect the environment. The agent observes r and s′ , and chooses a new x ∈ X to act in this new state. Algorithms' performance may vary across different states, and thus it is necessary to learn which x to use at each state. We can apply usual RL methods, but an "action" corresponds to choosing an algorithm, and the algorithm outputs an action for the current state.
As in Marcolino et al. [2013], and Marcolino et al. [2014], we model each algorithm x ∈ X as a probability distribution function (pdf) over A. That is, algorithms do not know in advance the action-values, and output the action that they estimate to be the best, according to their own decision procedures.
| Algorithm / Action | a1 | a2 | a3 | a4 |
| x1 | 0.8 | 0.2 | 0 | 0 |
|---|---|---|---|---|
| x2 | 0.2 | 0 | 0.7 | 0.1 |
Given a state, there is a certain probability that the algorithm outputs the true best action, and a certain probability for other actions. Let pxa be the probability of x selecting an action a. Although we use the pdfs in our analysis, in general they may be unknown. Our analysis allows a deeper understanding of the conflict between learning over algorithms or actions, but a designer may still need to estimate the pdfs when taking a decision between both approaches. There are examples of estimating algorithms' pdfs in the literature [Marcolino et al., 2013; 2014; Jiang et al., 2014]. Our theoretical analysis is done by comparing the likelihood of selecting the (unknown) optimal action a∗ , which maximizes the expected sum of discounted rewards. We consider two RL agents, P1 and P2, which reason over actions and algorithms, respectively.
Simple Example
Consider a single state, four actions {a1, a2, a3, a4} and two available algorithms {x1, x2}. We assume a1 is the optimal action, but that is not known in advance, and the algorithms select each action according to the probabilities shown in Table 1, which results from their reasoning procedures.
In the first iteration, P1 picks a1 with probability 0.25. P2 picks x1 with probability 0.5, which selects a1 with probability 0.8. Hence, P2 selects a1 indirectly with probability at least 0.5 · 0.8 = 0.4 > 0.25. Thus P2's expected performance is better than P1's. In the next few iterations P2 is even more likely to pick x1, while P1 may still need to explore further, until finally playing enough training iterations for the actionvalue of a1 to be higher than the other actions.
When the number of training iterations becomes sufficiently large, P1 learns to always select a1, and P2 to always select x1. However, since x1 selects a1 with probability 0.8, it turns out that P2 selects a1 with probability 0.8 < 1, and hence is outperformed by P1 in the long run. Therefore, until a certain number of training iterations, a RL agent may perform better by learning over algorithms, depending on the algorithms' pdfs. In the long run, however, learning over actions will always perform better. We formalize this notion below.
3.1 Theoretical Analysis
Our main result is a sufficient condition for learning over algorithms to outperform learning over actions. That allows a formal guarantee when learning over algorithms, besides guiding in the number of algorithms used, as we discuss next. P1 or P2 selects the best choice (best action a∗ or best algorithm x∗ , respectively) with a certain probability pi. Let l be the current training iteration. As usual, we consider RL agents where l → ∞ ⇒ pi → 1. We model pi by a learning curve given by the function 1 - (ξi + el×βi )-1 , where ξi and βi are parameters defining the initial error and the convergence "speed", respectively. A training process is noisy by nature, but
these functions model the average behavior over many training pa∗
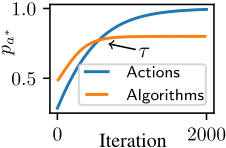
events. They converge to 1 in a diminishing returns fashion, as it would be expected in a training process. We then have:
Theorem 1. Let P i l be the probability that Pi picks a∗ at iteration l. P 2 l > P 1 l for a finite number of iterations, if ∃ x ∈ X, where pxa∗ > |X| |A| . If l →∞, however, P 1 l ≥ P 2 l .
Proof. If P2 selects x∗ , it indirectly selects a∗ with probability px∗ a∗ . Hence, at iteration l it selects a∗ with probability at least (1 - (ξ2 + el×β2 )-1 ) × px∗ a∗ . P1, on the other hand, selects a∗ with probability 1 - (ξ1 + el×β1 )-1 . Hence, if px∗ a∗ > 1-(ξ1+1)-1 1-(ξ2+1)-1 , then P2 selects a∗ with higher probability than P1 in the first iteration (l = 0). Eventually, however, P1 outperforms P2, since liml→∞ 1 - (ξ1 + el×β1 )-1 = 1, and liml→∞(1 - (ξ2 + el×β2 )-1 ) × px∗ a∗ = px∗ a∗ ≤ 1. As in the first iteration P1 selects randomly, 1-(ξ1+1)-1 = 1 |A| . Similarly,
|X| |A| , then P2 outperforms P1 until a certain iteration τ. We only need one x such that pxa∗ > |X| |A| , since px∗ a∗ ≥ pxa∗ .
We show examples of P1 and P2's theoretical learning curves in Figure 1. τ is the training iteration where learning over actions starts to outperform learning over algorithms. Note that Theorem 1 gives us sufficient, but not necessary conditions. That is, if pxa∗ > |X| |A| , we have a formal guarantee that learning over algorithms is better than over actions until a certain training iteration τ. However, there could be cases where pxa∗ ≤ |X| |A| , ∀x, and P2 still outperforms P1.
For instance, consider 2 actions and 10 algorithms, where pxa∗ = 0.99, ∀x. In l = 0, P1 picks a∗ with probability 0.5, while P2 with probability 0.99, even though 0.99 < |X| |A| = 5.
P2 outperforms P1 up to a certain training iteration τ . The previous theorem shows that τ > 0 if ∃x, pxa∗ > |X| |A| . We can obtain a lower bound τ ′ for τ , by solving the following equation: 1 - (ξ1 + eτ ′×β1 )-1 = (1 - (ξ2 + eτ ′×β2 )-1) × px∗ a∗ , since the probability of P2 selecting a∗ is at least (1 - (ξ2 + eτ ′×β2 )-1 ) × px∗ a∗ . Hence, up to training iteration τ ′ , we have a formal guarantee that P2 is better than P1, if the theorem condition is satisfied. If x∗ is unknown, we derive a less tight lower bound τ ′′ < τ ′ by solving: 1 - (ξ1 + eτ ′′×β1 )-1 = (1- (ξ2 + eτ ′′×β2 )-1) × pxa∗, where x is any algorithm.
Hence, if one is able to estimate pxa∗ (for at least one x) and β, then one would also have a lower bound for τ, leading to a formal guarantee for learning over algorithms up to that training iteration (ξ can be calculated given |A| and |X|).
Additionally, note that Theorem 1 does not say that we must have one algorithm whose probability of playing a∗ is higher than the probability of playing any other a. The condition pxa∗ > |X| |A| can be valid, even if ∃a ̸= a∗ such that pxa > pxa∗. In fact, we can show that learning over algorithms outperforms over actions in a very large action space, even if the probability of an algorithm selecting the best action is very small:
Corollary 1. As |A| →∞, P2 is better than P1 for a finite number of iterations, if and only if ∃x, where pxa∗ > 0.
Proof. Follows from lim|A|→∞ |X| |A| = 0, thus pxa∗ > 0 satisfies Theorem 1. The "only if" side is trivially true.
Hence, if the number of actions is very large, we only need pxa∗ > 0 for at least one algorithm. This result is very relevant even in domains where a designer cannot easily estimate pxa∗ .
Interestingly, however, Theorem 1 seems to suggest that the higher the number of algorithms, the worse, as we have that:
Corollary 2. If |X| = 1, x only needs to play better than uniformly random. As |X| grows, however, the sufficient condition eventually is never satisfied, independent of pxa∗.
Proof. Follows immediately from |X| |A| → 1 |A| for |X| → 1, hence we need pxa∗ > 1 |A| . Likewise, |X| |A| > 1 for |X| > |A|, hence we would need pxa∗ > 1, which is impossible.
In fact, if there is a fixed algorithm x, where pxa∗ ≥ px′ a∗ , ∀x′ ̸= x in all states, then we should always pick x. Intuitively, however, it should be beneficial to have multiple algorithms to choose from. Informally, this may happen because different algorithms may perform better at different states, as discussed in Marcolino et al. [2013]. That is, in many domains we do not have a fixed algorithm x that has a higher probability of selecting a∗ than the other algorithms in all states. Therefore, |X| may implicitly also affect the probability of P2 selecting a∗ , since P 2 l ≥ (1-(ξ2 +el×β2 )-1 )×px∗ a∗ (remember that x∗ is the algorithm x with the highest pxa∗ across all x ∈ X). Hence, informally, as the size n of X grows, we may have a greater chance of adding a new xn that has a higher probability of playing a∗ than the other algorithms (i.e., pxn a∗ > pxi a∗ , ∀0 ≤ i < n). Therefore, although adding a new algorithm may sacrifice initial performance, it may lead to a higher convergence point (i.e., a higher value for P 2 l ≥ (1- (ξ2 + el×β2 )-1 ) ×px∗ a∗ as l →∞). A larger value for P 2 l as l →∞ also increases the number of training iterations where the curve P 2 l is above P 1 l . That is, we may have that τX′ > τX, if |X′ | > |X|. Hence, a larger |X| should increase the number of training iterations where P2 still outperforms P1.
Formally, however, it is not true that τ increases with |X| in general. The way P 2 l changes as new algorithms are added depends on the algorithms' pdfs. For example, if every new algorithm selects the worst action with probability 1, then P2 just gets worse. If, however, we assume distributions over pxa∗, then we can show that τ increases with |X|. Similarly as before, this does not mean that an algorithm designer would directly sample a number from a distribution in order to "decide" pxa∗ . We are just proposing to model the phenomenon of new algorithms being created as a distribution over pxa∗ . For instance, given a set of algorithms X′ , one can calculate the average and standard deviation over all pxa∗ , if one assumes that pxa∗ comes from a Gaussian distribution. As |X′ | grows, the calculated average and standard deviation would approximate those of the true distribution. Hence, in order to formally study the effect of adding new algorithms, we evaluate different distributions for pxa∗ . We analyze three possible cases below: (i) when pxa∗ comes from a uniform distribution; (ii) when pxa∗ comes from a Gaussian; (iii) when there is a fixed pool of algorithms ˜X to choose from. Similar techniques could be employed to analyze the most appropriate distribution for a given domain.
The uniform distribution could model the case where there is not yet an established framework for developing "strong" algorithms (i.e., with a high pxa∗). Hence, the designer would not be able to develop an algorithm x with pxa∗ greater than some bound u; and given a certain state, the algorithm may be strong or weak with equal likelihood.
The Gaussian, on the other hand, models a situation with common knowledge or an established framework to develop strong algorithms (e.g., Monte Carlo Tree Search for computer Go). Then, we can expect that, in a set of algorithms, there will be a mean and a variance over pxa∗ (the variance resulting from different design decisions or parameter configurations).
Finally, we also consider the case where there is a fixed, previously known pool of algorithms available. That is, the designer must choose an algorithm x′ ∈ ˜X to include in X.
We start by analyzing the uniform distribution:
Proposition 1. If the underlying algorithm creation process originates xi with pxi a∗ ∼ U(0, u), then: (i) px∗ a∗ grows with |X| in expectation; (ii) ∃x where pxa∗ > |X| |A| in expectation, if and only if |X| < u × |A| - 1
Proof. The expected value of the k-th order statistic of the uniform distribution with n samples is given by: k×u n+1 . Hence, the expected maximum value for pxa∗ when |X| = n is n×u n+1 (which grows with n). In order for n×u n+1 > |X| |A| , we must have that u × |A| > n + 1 ⇝ n < u × |A| - 1. Conversely, if |X| = u × |A| - 1 + z, for z ≥ 0, we would have that: (u×|A|-1+z)×u u×|A|+z > |X| |A| ⇝ (u×|A|-1+z)×u (u×|A|-1+z) > u×|A|+z |A| ⇝ u × |A| > u × |A| + z, which is not possible for z ≥ 0.
Since px∗ a∗ grows with |X|, the proposition seems to indicate that we should use as large X as possible up to the upper bound u × |A| - 1. Interestingly, however, we show in synthetic experiments (Section 3.2) that performance still improves for |X| ≥ u × |A| - 1.
For the Gaussian, we find that:
Proposition 2. If the underlying algorithm creation process originates algorithms xi with pxi a∗ ∼ N(µ, σ) (truncated to the interval [0, 1]), then: (i) px∗ a∗ grows with |X| in expectation;
(ii) ∃x, where pxa∗ > |X| |A| in expectation, by following in order of priority: (a) |X| ≥ 741, if |A| > |X| µ+3σ ; (b) |X| ≥ 44, if |A| > |X| µ+2σ (c) |X| ≥ 7, if |A| > |X| µ+σ .
Proof. From the "68-95-99.7" rule, we have: p(pxa∗ ≥ µ + σ) ≈ 0.5 - 0.6827 2 = 0.15865; p(pxa∗ ≥ µ + 2σ) ≈ 0.5 - 0.9545 2 = 0.022275; p(pxa∗ ≥ µ + 3σ) ≈ 0.5 - 0.9973 2 = 0.00135. Hence, in order to have in expectation at least one x such that pxa∗ ≥ µ + σ, we need at least tσ samples, where tσ × 0.15865 = 1 ⇝ tσ ≈ 7. Likewise, for pxa∗ ≥ µ + 2σ, we need at least t2σ ≈ 44; and for pxa∗ ≥ µ + 3σ, at least t3σ ≈ 741. µ+3σ ≥ µ+2σ ≥ µ+σ (the equality comes from pxa∗ > 1 being equivalent to pxa∗ = 1). Hence, px∗ a∗ grows with |X|, in expectation. Now consider the sufficient condition pxa∗ > |X| |A| . For pxa∗ ≥ µ + 3σ in expectation, we need µ+ 3σ ≥ |X| |A| ⇝ |A| > |X| µ+3σ . Likewise, for pxa∗ ≥ µ + 2σ, we need |A| > |X| µ+2σ ; and for pxa∗ ≥ µ+σ, |A| > |X| µ+σ .
Hence, Proposition 2 allows a designer to estimate how many algorithms to use, even without an estimation of pxa∗ available. However, the proposition requires an estimation of µ and σ, which might come from previous knowledge designing and/or analyzing algorithms for the specific domain.
Fundamentally, however, even if all distribution parameters are unknown, Proposition 1 and Proposition 2 show that under distribution assumptions, one can expect px∗ a∗ to growwith |X|. Since P2 converges to (1-(ξ2+el×β2 )-1 )×px∗ a∗ , then τ also grows with |X|. We study this further in Section 3.2.
Proposition 3. Let Pxi be the probability that xi has the highest pxa∗ (across all x ∈ ˜X) in a state s. Let pe be the expected value of pxa∗ in ˜X. Then, in expectation: (i) px∗ a∗ grows with |X|; (ii) ∃x, where pxa∗ > |X| |A| , if |X| < pe × |A|.
Next, we do not assume an underlying distribution. Instead, algorithms must be chosen from an existing pool ˜X (X ⊆ ˜X):
Proof. Given n algorithms, the probability that at least one of them has the highest pxa∗ (across all x ∈ ˜X) is p = 1 - ∏ni=1 (1 - Pxi ). Clearly, p → 1 as n → ∞, and thus px∗ a∗ grows with |X|. However, to satisfy the sufficient condition, we must have pe > |X| |A| ⇝ |X| < pe × |A|.
Proposition 3 allows an estimation of the best |X| as ⌊pe × |A|⌋, given pe. With a fixed ˜X, in some domains one could estimate pe by experimentation over a set of states with a known ground truth. Fundamentally, however, it again shows that one should expect px∗ a∗ (and τ, consequently) to growwith |X|. We study this further in the next section.
3.2 Synthetic Experiments
We ran several synthetic experiments, to better investigate the dilemma between learning over actions or algorithms. Each experiment consists of many simulations, where we randomly generate a single state MDP. That is, we sample the mean reward ri from N(0, 1), for each action ai. When playing ai, the reward returned is sampled from N(ri, 0.25). For each simulation, we create an agent that learns over actions, and another that learns over algorithms. For both we considered α and ϵ starting as 1, and decaying at the rate 0.999. We sample pxa∗ from different distributions, to simulate the creation of algorithms in a given domain.
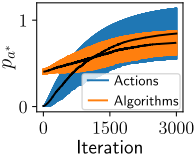
For each experiment, we run 1000 simulations of 10000 training iterations each. As an example, Figure 2 shows the probability of playing the best action (pa∗ ) when learning over actions or algorithms, for a Gaussian model (black lines shows mean pa∗ , and colored areas indicate the standard deviation). Note how the curves follow a similar shape as the ones predicted by our theory (Figure 1). In the appendix 1 , we show that the reward curves also follow a similar shape.
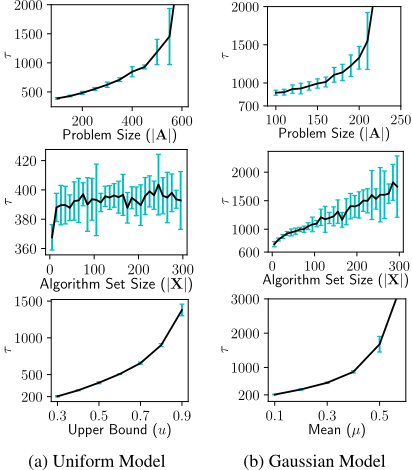
Our theoretical analysis does not yet give the exact number of iterations τ where learning over algorithms is better. Hence, in Figure 3 we study how τ changes as several parameters change (problem size |A|, algorithm set size |X|, u or µ), under a uniform or Gaussian model. A curve beyond the y-axis means that τ > 10000. We repeat the whole procedure 5 times, and the error bars show the confidence interval (p = 0.01). When changing one parameter we fix the others (100 actions, 25 algorithms, u = 0.5, µ = 0.4). We see that τ grows with statistical significance, under all parameters considered, for both models. When increasing u and µ we increase the overall expected performance of the algorithms, and hence this result is expected. It is interesting to note, however, that the curves tend to grow in an exponential fashion.
Concerning |A|, the meeting point τ also tends to grow exponentially. Hence, it gets more advantageous to learn over algorithms as problems grow in complexity. This happens since it gets harder for a RL agent to find the best action, as it requires more exploration. On the other hand, we can still see τ increasing with |X|. That is, even though it gets harder to find the best algorithm, px∗ a∗ tends to increase with |X|, compensating for the harder exploration, as we discussed in our analysis. Based on Theorem 1, one may expect τ to drop when |X| > |A|. Interestingly, however, we see that τ tends to converge as |X| grows for both models, instead of dropping (remember that the theorem only gives sufficient conditions).
Our theory focused on pa∗, but the actual reward obtained may be more significant. We evaluated the reward and cumulative reward, and found similar results (shown in the appendix 1 ). In the uniform model reward curves, however, we notice that τ starts to drop when |X| ≫ |A|.
1 http://www.lancaster.ac.uk/staff/sorianom/ijcai18-ap.pdf
4 Learning over Algorithms in RTS Games
We evaluate learning over algorithms in a real-time strategy (RTS) game, which is a very complex domain, where directly learning over actions is impractical. The number of actions for a given state is estimated as over 1050 [Onta˜n´on et al., 2013]. Hence, we would need over 1050 training iterations just to explore a single time all the possible actions for a single state. The objective of this section, therefore, is to demonstrate that we can obtain a good performance when learning over algorithms in a complex and relevant domain.
RTS games are adversarial, normally involving resource management, construction, and combat between a large number of military units. They impose a great challenge for AI algorithms, since they have huge action and state spaces and require fast decisions. In this paper we use µRTS, a simplified RTS game developed for AI research 2 .
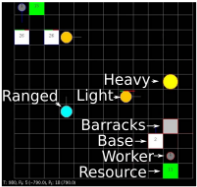
A screenshot of µRTS is shown in Figure 4. In µRTS, entities are either buildings, units or resources. Buildings are either bases, which can produce workers or barracks, which produce military units. Units are either workers, which harvest resources and have limited combat ability; or military units. Military units are: heavy and light, which are strong but slow or weak but fast melee units, respectively; or ranged, which are long range attack units.
2 https://github.com/santiontanon/microrts
A set of four simple rush algorithms is available in µRTS: (i) Worker: create worker units, have one of them gather resources, and send all others to attack; (ii) Ranged: use a worker to gather resources. With enough resources, build a barrack and generate ranged units, sending them to attack. (iii) Heavy: same as Ranged, but creates the heavy unit instead; (iv) Light: same as before, but creates the light unit. In addition, we implemented two algorithms: (v) BuildBarracks: build a new barrack, allowing faster production of military units; and (vi) Expand: build a new base, increasing the production of worker units and faster gathering of multiple resources. All these compose our set X. In order to handle the large state space, we propose next a Function Approximation approach.
4.1 Function Approximation (FA)
In this section, we say that we are taking an "action" a ∈ A in a state s even though we are selecting an algorithm x ∈ X. This is to follow the traditional notation in RL literature. The main idea of FA is to learn a functional representation of the action-value function Q. This allows us to generalize Q for similar state-action pairs. We use SARSA [Rummery and Niranjan, 1994], with linear function approximation. Hence, a state s is represented by a feature vector [k1(s), . . . , kn(s)], and Q(s, a) is approximated by ˜Q(s, a, w) = ∑ni=1 ki(s) ·wi, where [w1, . . . ,wn]a is a weight vector for action a. The learning problem is to find the best weights for each action. Each time the agent takes an action a, observes the next state s′ , and chooses an action a′ in s′ , we update wi with: ∆wi = α(r + γ ˜Q(s′ , a′ , w) - ˜Q(s, a, w)) × ki(s), where α is the training step size.
The features for a given state of µRTS are obtained as follows: we split the map into 3 × 3 quadrants of equal size. Within each quadrant, the number of units of each type owned by each player p is a separate feature. Thus, 9 quadrants, 7 unit types and 2 players lead to 9 × 7 × 2 features. Additionally, the cumulative average health of each player's units within each quadrant is included, leading to 9 × 2 more features. We also include the resources harvested by each player, the current game time and the independent term, with value 1. Hence, given ρp = {u11 , . . . , u91 , . . . , u17 , . . . , u97 }, where uji is the number of units of type ui in quadrant j for player p; and βp = {h11 , . . . , h91 , . . . , h17 , . . . , h97 }, where hji is the cumulative average health of units of type ui in quadrant j; the feature vector is: k = [1, ρ1, ρ2, β1, β2, ω1, ω2, t], where ωp is the amount of resources owned by player p, and t is the current game time. This linear combination of features is replicated for each x ∈ X. Hence, we have |X| equations with |k| features, leading to |X| × |k| weights to adjust. We select an algorithm x ∈ X using exponentially decaying ϵ-greedy (decayed after every training game).
4.2 Results
We evaluate the performance of learning over algorithms using the proposed FA approach. We compare against the state of the art in µRTS: AHTN, PuppetMCTS, PuppetAB, NaiveMCTS and StrategyTactics. They are described in Section 2 and references therein. StrategyTactics won the 2017 µRTS competition, and NaiveMCTS was in the top 5. We used the map "basesWorkers24×24", and the best parametrization we found: α = 10-4 , γ = 0.9, ϵ exponentially decaying from 0.2 against PuppetAB, PuppetMCTS and AHTN; and decaying from 0.1 for NaiveMCTS and StrategyTactics, after every game (decay rate ≈ 0.9984). All games have 3000 cycles at most, declared a draw on timeout. Rewards are -1, 0 or 1 for defeat, draw and victory, respectively.
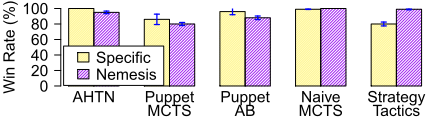
We perform two evaluations. In the first, named Specific, we trained FA in 500 games against PuppetAB, PuppetMCTS and AHTN; and in 100 games against NaiveMCTS and StrategyTactics. The resulting policy is tested against the same adversary that FAwas trained against. In the second, named Nemesis, we: (i) trained FA against PuppetMCTS, fixing the resulting policy; and (ii) trained a new instance of FA against the resulting policy of (i), in 500 games. The single resulting policy of (ii) is tested against all adversaries (showing robustness). All tests have 100 games, with α = ϵ = 0. We ran 5 repetitions of all experiments, and the error bars show the 99% confidence interval. We consider statistical significance as p ≤ 0.01. Figure 5 shows the results.
In both cases FA significantly defeats all opponents, with win rates higher than 80%. Nemesis and Specific have similar win rates, but Nemesis is significantly better against StrategyTactics. We believe this happens because Nemesis further elaborates on a policy that was already strong (the resulting policy of FA trained against PuppetMCTS).
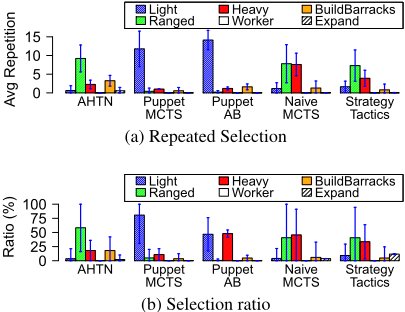
Allowing algorithm switches at any state could have a negative effect: it could happen so frequently that algorithms would not be able to follow a course of action. Indeed, the agent may switch "too fast" during exploration, but eventually it learns a strong policy, and tends to pick a certain algorithm repeatedly if this leads to higher performance. On the other hand, the agent learns to switch to different algorithms when that is more profitable. Figure 6 confirms both situations with the Specific agents, by showing (a) the average number of times an algorithm is chosen consecutively and (b) the average percentage of selections (error bars indicate standard deviation). Hence, all algorithms tend to be chosen, but at different proportions depending on the adversary.
Finally, Figure 7 compares Nemesis and the individual algorithms (x ∈ X), when playing against all opponents. We find that our performance is either significantly better than all individual algorithms, or not statistically different than the best algorithm (which is still relevant, since we may not know in advance which one to use), against each adversary. Pvalues when comparing against the best algorithm x are: 0.97,
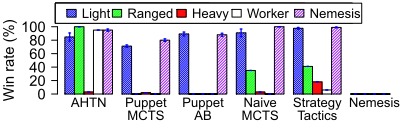
0.004, 0.61, 0.04, 0.14; for AHTN, PuppetMCTS, PuppetAB, NaiveMCTS and StrategyTactics, respectively. Additionally, the last set of bars shows that all algorithms are individually defeated by Nemesis.
5 Conclusion
Although action abstractions have been introduced before, our model for learning over algorithms gives novel guidelines backed by a theoretical analysis. Synthetic experiments demonstrate an increase in relative performance with action and algorithm set sizes. We also introduce a Function Approximation approach for learning over algorithms in RTS games, significantly outperforming state-of-the-art search-based players. The source code of synthetic and µRTS experiments are available at: https://github.com/andertavares/syntheticmdps and https://github.com/SivaAnbalagan1/micrortsFA, respectively.
Acknowledgments
We would like to thank Fapemig, CNPq, CAPES, and the School of Computing and Communications for their support. We also thank Tom McCracken for kindly checking our code.
@inproceedings{ijcai2018p377,
  title     = {Algorithms or Actions? A Study in Large-Scale Reinforcement Learning},
  author    = {Tavares, Anderson Rocha and Anbalagan, Sivasubramanian and Marcolino, Leandro Soriano and Chaimowicz, Luiz},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2717--2723},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/377},
  url       = {https://doi.org/10.24963/ijcai.2018/377},
}
TY - CPAPER TI - Algorithms or Actions? A Study in Large-Scale Reinforcement Learning AU - Tavares, Anderson Rocha AU - Anbalagan, Sivasubramanian AU - Marcolino, Leandro Soriano AU - Chaimowicz, Luiz T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2717 EP - 2723 DO - 10.24963/ijcai.2018/377 UR - https://doi.org/10.24963/ijcai.2018/377 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





