
Exploration by Distributional Reinforcement Learning
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2710-2716.
https://doi.org/10.24963/ijcai.2018/376
Keywords
- Machine Learning: Reinforcement Learning
- Machine Learning: Neural Networks
Abstract
We propose a framework based on distributional reinforcement learning and recent attempts to combine Bayesian parameter updates with deep reinforcement learning. We show that our proposed framework conceptually unifies multiple previous methods in exploration. We also derive a practical algorithm that achieves efficient exploration on challenging control tasks.
- [Azizzadenesheli et al., 2017] Kamyar Azizzadenesheli, Emma Brunskill, and Animashree Anandkumar. Ef- ficient exploration through bayesian deep q networks. Symposium on Deep Reinforcement Learning, NIPS, 2017.
- [Bellemare et al., 2017] Marc G. Bellemare, Will Dabney, and Remi Munos. A distributional perspective on rein- forcement learning. International Conference on Machine Learning, 2017.
- [Blei et al., 2017] David M. Blei, Alp Kucukelbir, and Jon D. McAuliffe. Variational inference: A review for statisticians. Journal of the American Statistical Associ- ation, Volume 112 -Issue 518, 2017.
- [Brockman et al., 2016] Greg Brockman, Vicki Cheung, Ludwig Pettersson, Jonas Schneider, John Schulman, Jie Tang, and Wojciech Zaremba. Openai gym. Arxiv: 1606.01540, 2016.
- [Dearden et al., 1998] Richard Dearden, Nir Friedman, and Stuart Russel. Bayesian q learning. American Association for Artificial Intelligence (AAAI), 1998.
- [Duan et al., 2016] Yan Duan, Xi Chen, Rein Houthooft, John Schulman, and Pieter Abbeel. Benchmarking deep reinforcement learning for continuous control. Interna- tional Conference on Machine Learning, 2016.
- [Fortunato et al., 2017] Meire Fortunato, Moham- mad Gheshlaghi Azar, Bilal Piot, Jacob Menick, Ian Osband, Alex Graves, Vlad Mnih, Remi Munos, Demis Hassabis, Ilivier Pietquin, Charles Blundell, and Shane Legg. Noisy network for exploration. arXiv:1706.10295, 2017.
- [Henderson et al., 2017] Peter Henderson, Thang Doan, Ri- ashat Islam, and David Meger. Bayesian policy gradients via alpha divergence dropout inference. 2nd Workshop on Bayesian Deep Learning, NIPS, 2017.
- [Levine et al., 2016] Sergey Levine, Chelsea Finn, Trevor Darrell, and Pieter Abbeel. End to end training of deep visuomotor policies. Journal of Machine Learning Re- search, 2016.
- [Lillicrap et al., 2016] Timothy P. Lillicrap, Jonathan J. Hunt, Alexander Pritzel, Nicolas Heess, Tom Erez, Yu- val Tassa, David Silver, and Daan Wierstra. Continuous control with deep reinforcement learning. International Conference on Learning Representations, 2016.
- [Lipton et al., 2016] Zachary C. Lipton, Xiujun Li, Jianfeng Gao, Lihong Li, Faisal Ahmed, and Li Deng. Effi- cient dialogue policy learning with bbq-networks. ArXiv: 1608.05081, 2016.
- [Mnih et al., 2013] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Alex Graves, Ioannis Antonoglou, Daan Wierstra, and Martin Riedmiller. Playing atari with deep reinforcement learning. NIPS workshop in Deep Learning, 2013. [Moerland et al., 2017]
- Thomas M. Moerland, Joost Broekens, and Catholijn M. Jonker. Efficient exploration with double uncertain value networks. Symposium on Deep Reinforcement Learning, NIPS, 2017.
- [Morimura et al., 2010] Tetsuro Morimura, Masashi Sugiyama, Hisashi Kashima, Hirotaka Hachiya, and Toshiyuki Tanaka. Nonparametric return distribution approximation for reinforcement learning. ICML, 2010.
- [Morimura et al., 2012] Tetsuro Morimura, Masashi Sugiyama, Hisashi Kashima, Hirotaka Hachiya, and Toshiyuki Tanaka. Parametric return density estimation for reinforcement learning. UAI, 2012.
- [Osband and Van Roy, 2015] Ian Osband and Benjamin Van Roy. Bootstrapped thompson sampling and deep explo- ration. arXiv:1507:00300, 2015.
- [Osband et al., 2013] Ian Osband, Daniel Russo, and Ben- jamin Van Roy. (more) efficient reinforcement learning via posterior sampling. Arxiv: 1306.0940, 2013.
- [Osband et al., 2016] Ian Osband, Charles Blundell, Alexan- der Pritzel, and Benjamin Van Roy. Deep exploration via bootstrapped dqn. arXiv:1602.04621, 2016.
- [Osband et al., 2017] Ian Osband, daniel Russo, Zheng Wen, and Benjamin Van Roy. Deep exploration via randomized value functions. arXiv: 1703.07608, 2017.
- [Plappert et al., 2016] Matthias Plappert, Rein Houthooft, Prafulla Dhariwal, Szymon Sidor, Richard Y. Chen, Xi Chen, Tamim Asfour, Pieter Abbeel, and Marcin Andrychowicz. Parameter space noise for exploration. In- ternational Conference on Learning Representation, 2016.
- [Ranganath et al., 2014] Rejesh Ranganath, Sean Gerrish, and David M. Blei. Black box variational inference. Pro- ceedings of the 17th International Conference on Artificial Intelligence and Statistics (AISTATS), 2014.
- [Russo, 2017] Daniel Russo. Tutorial on thompson sam- pling. arxiv, 2017.
- [Schulman et al., 2015] John Schulman, Sergey Levine, Philipp Moritz, Michael I. Jordan, and Pieter Abbeel. Trust region policy optimization. International Conference on Machine Learning, 2015.
- [Tang and Kucukelbir, 2017] Yunhao Tang and Alp Ku- cukelbir. Variational deep q network. 2nd Workshop on Bayesian Deep Learning, NIPS, 2017.
- [Thompson, 1933] William R. Thompson. On the likelihood that one unknown probability exceeds another in view of the evidence of two samples. Biometrika, Vol. 25, No. 3/4, 1933.
- [Todorov et al., 2012] Emanuel Todorov, Tom Erez, and Yu- val Tassa. Mujoco: A physics engine for model-based con- trol. International Conference on Intelligent Robots, 2012.
- [Tsitsiklis and Van Roy, 1996] John N. Tsitsiklis and Ben- jamin Van Roy. Feature based methods for large scale dynamic programming. Machine Learning, 1996.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Deep reinforcement learning (RL) has enjoyed numerous recent successes in various domains such as video games and robotics control [Schulman et al., 2015; Duan et al., 2016; Levine et al., 2016]. Deep RL algorithms typically apply naive exploration strategies such as ϵ-greedy [Mnih et al., 2013; Lillicrap et al., 2016]. However, such myopic strategies cannot lead to systematic exploration in hard environments [Osband et al., 2017].
We provide an exploration algorithm based on distributional RL [Bellemare et al., 2017] and recent attempts to combine Bayesian parameter updates with deep reinforcement learning. We show that the proposed algorithm provides a conceptual unification of multiple previous methods on exploration in deep reinforcement learning setting. We also show that the algorithm achieves efficient exploration in challenging environments.
2 Background
2.1 Markov Decision Process and Value Based Reinforcement Learning
In a Markov Decision Process (MDP), at time step t ≥ 0, an agent is in state st ∈ S, takes action at ∈ A, receives reward rt and gets transitioned to next state st+1 ∼ p(st+1|st, at). At time t = 0 the agent's state distribution follows s0 ∼ ρ(s0). A policy is a mapping from a state to a distribution over action at ∼ π(·|st). The objective is to find a policy π to maximize the discounted cumulative reward
where γ ∈ (0, 1] is a discount factor. In state s, the actionvalue function Qπ (s, a) is defined as the expected cumulative reward that could be received by first taking action a and following policy π thereafter
From the above definition, it can be shown that Qπ (st, at) satisfies the Bellman equation
Let π∗ = argmaxπ J be the optimal policy and Q∗ (s, a) its action value function. Q∗ (s, a) satisfies the following Bellman equation
The above equations illustrate the temporal consistency of the action value functions that allows for the design of learning algorithms. Define Bellman operator
When γ ∈ (0, 1), starting from any Q(0) (s, a), iteratively applying the operator Q(t+1) (s, a) ← T ∗Q(t) (s, a) leads to convergence Q(t) (s, a) → Q∗ (s, a) as t → ∞.
In high dimensional cases, it is critical to use function approximation as a compact representation of action values. Let Qθ(s, a) be such a function with parameter θ that approximates a table of action values with entry (s, a). The aim is to find θ such that Qθ(s, a) ≈ Q∗ (s, a). Let Π be the operator that projects arbitrary vector Q(s, a) ∈ R|S|×|A| to the subspace spanned by function Qθ(s, a). Since the update of action values can now only take place in the subspace spanned by function Qθ(s, a), the iterate Q(t) (s, a) is updated as Q(t+1) (s, a) ← ΠT ∗Q(t) (s, a). In cases where Qθ(s, a) is linear, the above procedure can be shown to converge [Tsitsiklis and Van Roy, 1996]. However, in cases where Qθ(s, a) is nonlinear (neural network), the function approximation becomes more expressive at the cost of no convergence guarantee. Many deep RL algorithms are designed following the above formulation, such as Deep Q Network (DQN) [Mnih et al., 2013].
2.2 Distributional Reinforcement Learning
Following [Bellemare et al., 2017], instead of considering action value Qπ (s, a) under policy π, which is itself an expectation, consider the random return at (st, at) by following policy π, Rπ (st, at) = ∑t′≥t rt′γ t′-t . It follows that Qπ (s, a) = E[Rπ (s, a)]. Let Z π (s, a) be the distribution of Rπ (s, a). The Bellman equation for random return is similar to that of the action value functions
where both sides are distributions and =D denotes equality in distribution. 1 Define distributional Bellman operator Hπ under policy π as
Notice that Hπ operates on distributions. Define H∗ as follows
When γ ∈ (0, 1), starting from any distribution Z (0) (s, a), applying the operator as Z (t+1) (s, a) ← H∗Z (t) (s, a) leads to convergence in expectation E[Z (t) (s, a)] → Q∗ (s, a). However, the distribution Z (t) (s, a) itself may not weakly converge.
To design a practical algorithm, one must use a parametric family of distribution Zθ(s, a) to approximate Z π (s, a), with parameter θ. Let D(Z1,Z2) be a discrepancy measure between distribution Z1 and Z2. Define the projection operator Π as follows
In other words, Π projects a distribution Z into another distribution Zθ in the parametric family with smallest discrepancy from Z. Hence the distribution Z is updated as Z (t+1) (s, a) ← ΠH∗Z (t) (s, a). In practice, the operator is applied to different entries (s, a) asynchronously. For a given pair (st, at), one first selects a greedy action for next state
then updates the distribution Zθ(st, at) to match the target distribution by minimizing the discrepancy
When only samples xi ∼ rt + γZθ(st+1, a′ ), 1 ≤ i ≤ N are available, let the empirical distribution be ˆ Z = ∑Ni=1 1N δ(xxi) 2 , then (2) reduces to minimizing D( ˆ Z, Zθ ).
3 RelatedWork
In reinforcement learning (RL), naive explorations such as ϵ-greedy [Mnih et al., 2013; Lillicrap et al., 2016] do not explore well because local perturbations of actions break the consistency between consecutive steps [Osband and Van Roy, 2015]. A number of prior works apply randomization to parameter space [Fortunato et al., 2017; Plappert et al., 2016] to preserve the consistency in exploration, but their formulations are built on heuristics. Posterior sampling is a principled exploration strategy in the bandit setting [Thompson, 1933; Russo, 2017], yet its extension to RL [Osband et al., 2013] is hard to scale to large problems. More recent prior works have formulated the exploration strategy as sampling randomized value functions and interpreted the algorithm as approximate posterior sampling [Osband et al., 2016; 2017]. Instead of modeling value functions, our formulation is built on modeling return distributions which reduces to exact posterior sampling in the bandit setting.
1 In future notations, we replace =D by = for simplicity.
2 δ(x - xi) is the Dirac distribution that assigns point mass of probability 1 at x = xi.
Following similar ideas of randomized value function, multiple recent works have combined approximate Bayesian inference [Ranganath et al., 2014; Blei et al., 2017] with Q learning and justified the efficiency of exploration by relating to posterior sampling [Lipton et al., 2016; Tang and Kucukelbir, 2017; Azizzadenesheli et al., 2017; Moerland et al., 2017]. Though their formulations are based on randomized value functions, we offer an alternate interpretation by modeling return distribution and provide a conceptual framework that unifies these previous methods (Section 5). We will also provide a potential approach that extends the current framework to policy based methods as in [Henderson et al., 2017].
Modeling return distribution dated back to early work of [Dearden et al., 1998; Morimura et al., 2010; 2012], where learning a return distribution instead of only its expectation presents a more statistically challenging task but provides more information during control. More recently, [Bellemare et al., 2017] applies a histogram to learn the return distribution and displays big performance gains over DQN [Mnih et al., 2013]. Based on [Bellemare et al., 2017], we provide a more general distributional learning paradigm that combines return distribution learning and exploration based on approximate posterior sampling.
4 Exploration by Distributional Reinforcement Learning
4.1 Formulation
Recall that Z(s, a) is the return distribution for state action pair (s, a). In practice, we approximate such distribution by a parametric distribution Zθ(s, a) with parameter θ. Following [Bellemare et al., 2017], we take the discrepancy to be KL divergence. Recall ˆ Z is the empirical distribution of samples ˆ Z = ∑Ni=1 1N δ(x - xi), hence the KL divergence reduces to
where we have dropped a constant - logN in the last equality. Let θ follow a given distribution θ ∼ qφ(θ) with parameter φ. We propose to minimize the following objective
where H(qφ(θ)) is the entropy of qφ(θ). Note that (3) corresponds to the projection step ΠH∗ defined in (2), and the first term of (4) takes an expectation of projection discrepancy over the distribution θ ∼ qφ(θ). The intuition behind (4) is that by the first term, the objective encourages low expected discrepancy (which is equivalent to Bellman error) to learn optimal policies; the second term serves as an exploration bonus to encourage a dispersed distribution over θ for better exploration during learning.
We now draw the connection between (4) and approximate Bayesian inference. First assign an improper uniform prior on θ, i.e. p(θ) ∝ 1. The posterior is defined by Bayes rule given the data {xi}Ni=1 as p(θ|{xi}Ni=1 ) ∝ p(θ)p({xi}Ni=1 |θ) where p({xi}Ni=1 |θ) = Πip(xi|θ) 3 . Since by definition p(xi|θ) = Zθ(xi), (4) is equivalent to
Hence to minimize the objective (4) is to search for a parametric distribution qφ(θ) to approximate the posterior p(θ|{xi}Ni=1 ). From (5) we can see that the posterior p(θ|{xi}Ni=1 ) is the minimizer policy of (4), which achieves the optimal balance between minimizing low discrepancy and being as random as possible. The close resemblance between our formulation and posterior sampling partially justifies the potential strength of our exploration strategy.
4.2 Generic Algorithm
A generic algorithm Algorithm 1 can be derived from (5). We start with a proposed distribution qφ(θ) over parameter θ and a distribution model Zθ(s, a). During control, in state st, we sample a parameter from θ ∼ qφ(θ) and choose action at = argmaxa E[Zθ(st, a)]. This is equivalent to taking an action based on the approximate posterior probability that it is optimal. During training, we sample from one-step lookahead distribution of the greedy action, and update parameter by optimizing (4).
Algorithm 1 Exploration by Distributional RL: Generic
- 1: INPUT: generic return distribution Zθ(s, a) with parameter θ, parameter distribution qφ(θ) with parameter φ.
- 2: while not converged do
- 3: // Control
- 4: Sample θ ∼ qφ(θ).
- 5: In state st, choose at = argmaxa E[Zθ(st, a)], get transition st+1 and reward rt.
- 6: // Training
- 7: Given state action pair st, at, choose greedy onestep lookahead distribution a′ = argmaxa E[rt + γZθ(st+1, a)].
- 8: Sample from the distribution rt + γZθ(st+1, a′ ) and let ˆ Z be the empirical distribution of samples, update parameter φ by minimizing objective (4).
- 9: end while
3 We assume samples drawn from the next state distributions are i.i.d. as in [Bellemare et al., 2017].
4.3 Practical Algorithm: Gaussian Assumption
We turn Algorithm 1 into a practical algorithm by imposing assumption on Zθ(s, a). [Dearden et al., 1998] assumes Zθ(s, a) to be Gaussian based on the assumption that the chain is ergodic and γ close to 1. We make this assumption here and let Zθ(s, a) be a Gaussian with parametrized mean Qθ(s, a) and fixed standard error σ. The objective (3) reduces to
We now have an analytical form E[Zθ(s, a)] = Qθ(s, a). The objective (4) reduces to
Algorithm 2 Exploration by Distributional RL: Gaussian
- 1: INPUT: target parameter update period τ ; learning rate α; Gaussian distribution parameter σ2 .
- 2: INITIALIZE: parameters φ, φ-; replay buffer B ← {}; step counter counter ← 0.
- 3: for e = 1, 2, 3...E do
- 4: while episode not terminated do
- 5: counter ← counter + 1.
- 6: Sample θ ∼ qφ(θ).
- 7: In state st, choose at = argmaxa Qθ(st, a), get transition st+1 and reward rt.
- 8: Save experience tuple {st, at, rt, st+1} to buffer B.
- 9: Sample N parameters θj ∼ qφ-(θ-) and sample N tuples D = {sj , aj , rj , s′j } from B.
- 10: Sample target xj ∼ rj + γZθj (s′j , a′ ) for jth tuple in D where a′ is greedy w.r.t. Qθ-(s′j , a).
- 11: Take gradient ∆φ of the KL divergence in (7).
- 12: φ ← φ - α∆φ.
- 13: if counter mod τ = 0 then
- 14: Update target parameter φ- ← φ.
- 15: end if
- 16: end while
- 17: end for
Parallel to the principal network qφ(θ) with parameter φ, we maintain a target network qφ-(θ-) with parameter φ- to stabilize learning [Mnih et al., 2013]. Samples for updates are generated by target network θ- ∼ qφ-(θ-). We also maintain a replay buffer B to store off-policy data.
4.4 Randomized Value Function as Randomized Critic for Policy Gradient
In off-policy optimization algorithm like Deep Deterministic Policy Gradient (DDPG) [Lillicrap et al., 2016], a policy πθp (s) with parameter θp and a critic Qθ(s, a) with parameter θ are trained at the same time. The policy gradient of reward objective (1) is
where replacing true Qπ (s, a) by a critic Qθ(s, a) introduces bias but largely reduces variance [Lillicrap et al., 2016].
To extend the formulation of Algorithm 2 to policy based methods, we can interpret Qθ(s, a) as a randomized critic with a distribution induced by θ ∼ qφ(θ). At each update we sample a parameter ˆ θ ∼ qφ(θ) and compute the policy gradient (8) through the sampled critic Qˆ θ (s, a) to update θp. The distributional parameters φ are updated as in Algorithm 2 with the greedy actions replaced by actions produced by the policy πθp .
Policy gradients computed from randomized critic may lead to better exploration directly in the policy space as in [Plappert et al., 2016], since the uncertainties in the value function can be propagated into the policy via gradients through the uncertain value functions.
5 Connections with Previous Methods
We now argue that the above formulation provides a conceptual unification to multiple previous methods. We can recover the same objective functions as previous methods by properly choosing the parametric form of return distribution Zθ(s, a), the distribution over model parameter qφ(θ) and the algorithm to optimize the objective (5).
5.1 Posterior Sampling for Bandits
In the bandit setting, we only have a set of actions a ∈ A. Assume the underlying reward for each action a is Gaussian distributed. To model the return distribution of action a, we set Zθ(a) to be Gaussian with unknown mean parameters µa, i.e. Zθ = N(µa, σ2 ). We assume the distribution over parameter qφ(µ) to be Gaussian as well. Due to the conjugacy between improper uniform prior p(µ) (assumed in Section 4.1) and likelihood Zθ(a), the posterior p(µ|{xi}) is still Gaussian. We can minimize (5) exactly by setting qφ(µ) = p(µ|{xi}). During control, Algorithm 1 selects action at = argmaxa µ(a) with sampled µ ∼ qφ(µ) = p(µ|{xi}), which is exact posterior sampling. This shows that our proposed algorithm reduces to exact posterior sampling for bandits. For general RL cases, the equivalence is not exact but this connection partially justifies that our algorithm can achieve very efficient exploration.
5.2 Deep QNetwork with Bayesian Updates
Despite minor algorithmic differences, Algorithm 2 has very similar objective as Variational DQN [Tang and Kucukelbir, 2017], BBQ Network [Lipton et al., 2016] and Bayesian DQN [Azizzadenesheli et al., 2017], i.e. all three algorithms can be interpreted as having Gaussian assumption over return distribution Zθ(s, a) ∼ N(Qθ(s, a), σ2 ) and proposing Gaussian distribution over parameters qφ(θ). However, it is worth recalling that Algorithm 2 is formulated by modeling return distributions, while previous methods are formulated by randomizing value functions.
If we are to interpret these three algorithms as instantiations of Algorithm 2, the difference lies in how they optimize (7). Variational DQN and BBQ apply variational inference to minimize the divergence between qφ(θ) and posterior p(θ|{xi}), while Bayesian DQN applies exact analytical updates (exact minimization of (7)), by using the conjugacy of prior and likelihood distributions as discussed above. Algorithm 1 generalizes these variants of DQN with Bayesian updates by allowing for other parametric likelihood models Zθ(s, a), though in practice Gaussian distribution is very popular due to its simple analytical form.
To recover NoisyNet [Fortunato et al., 2017] from (7), we can properly scale the objective (by multiplying (7) by σ2 ) and let σ → 0. This implies that NoisyNet makes less strict assumption on return distribution (Gauss parameter σ does not appear in objective) but does not explicitly encourage exploration by adding entropy bonus, hence the exploration purely relies on the randomization of parameter θ. To further recover the objective of DQN [Mnih et al., 2013], we set qφ(θ) = δ(θ - φ) to be the Dirac distribution. Finally, since DQN has no randomness in the parameter θ, its exploration relies on greedy action perturbations.
5.3 Distributional RL
Distributional RL [Bellemare et al., 2017] models return distribution using categorical distribution and does not introduce parameter uncertainties. Since there is no distribution over parameter θ, Algorithm 1 recovers the exact objective of distributional RL from (4) by setting qφ(θ) = δ(θ - φ) and letting Zθ(s, a) be categorical distributions. As the number of atoms in the categorical distribution increases, the modeling becomes increasingly close to non-parametric estimation. Though having more atoms makes the parametric distribution more expressive, it also poses a bigger statistical challenge during learning due to a larger number of parameters. As with general Zθ(s, a), choosing a parametric form with appropriate representation power is critical for learning.
6 Experiments
In all experiments, we implement Algorithm 2 and refer to it as GE (Gauss exploration) in the following. We aim to answer the following questions,
- In environments that require consistent exploration, does GE achieve more efficient exploration than conventional naive exploration strategies like ϵ-greedy in DQN and direct parameter randomization in NoisyNet?
- When a deterministic critic in an off-policy algorithm like DDPG [Lillicrap et al., 2016] is replaced by a randomized critic, does the algorithm achieve better exploration?
6.1 Testing Environment
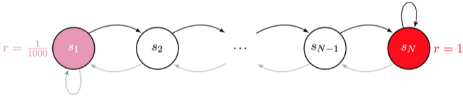
Chain MDP. The chain MDP [Osband et al., 2016] (Figure 1) serves as a benchmark to test if an algorithm entails consistent exploration. The environment consists of N states and each episode lasts N + 9 time steps. The agent has two actions {left, right} at each state si, 1 ≤ i ≤ N, while state s1, sN are both absorbing. The transition is deterministic. At state s1 the agent receives reward r = 1 1000 , at state sN the agent receives reward r = 1 and no reward anywhere else. The initial state is always s2, making it hard for the agent to escape local optimality at s1. If the agent explores uniformly randomly, the expected number of time steps required to reach sN is 2N-2 . For large N, it is almost not possible for the randomly exploring agent to reach sN in a single episode, and the optimal strategy to reach sN will never be learned.
Sparse Reward Environments. All RL agents require reward signals to learn good policies. In sparse reward environment, agents with naive exploration strategies randomly stumble around for most of the time and require many more samples to learn good policies than agents that explore consistently. We modify the reward signals in OpenAI gym [Brockman et al., 2016] and MuJoCo benchmark tasks [Todorov et al., 2012] to be sparse as follows.
- MountainCar, Acrobot: r = 1 when the episode terminates and r = 0 otherwise.
- CartPole, InvertedPendulum, InvertedDoublePendulum: r = -1 when the episode terminates and r = 0 otherwise.
6.2 Experiment Results
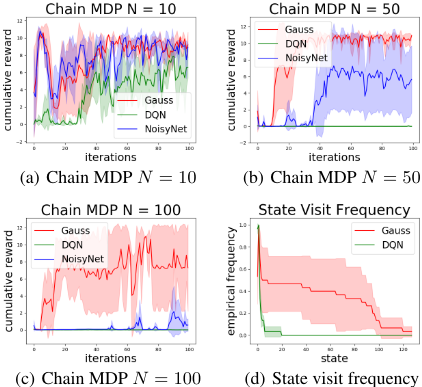
Exploration in Chain MDP. In Figure 2 (a) - (c) we compare DQN vs NoisyNet vs GE in Chain MDP environments with different number of states N. When N = 10, all three algorithms can solve the task. When N = 50, DQN cannot explore properly and cannot make progress, GE explores more efficiently and converges to optimal policy faster than NoisyNet. When N = 100, both NoisyNet and DQN get stuck while GE makes progress more consistently. Compared to Bootstrapped DQN (BDQN)[Osband et al., 2016], GE has a higher variance when N = 100. This might be because BDQN represents the distribution using multiple heads and can approximate more complex distributions, enabling better exploration on this particular task. In general, however, our algorithm is much more computationally feasible than BDQN yet still achieves very efficient exploration.
Figure 2 (d) plots the state visit frequency for GE vs. DQN within the first 10 episodes of training. DQN mostly visits states near s2 (the initial state), while GE visits a much wider range of states. Such active exploration allows the agent to consistently visit sN and learns the optimal policy within a small number of iterations.
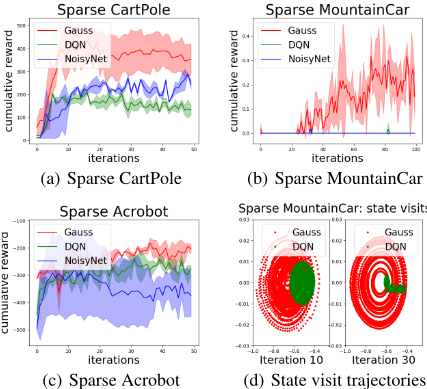
Exploration in Sparse Reward Environments. In Figure 3 (a) - (c) we present the comparison of three algorithms in sparse reward environments. For each environment, we plot the rewards at a different scale. In CartPole, the plotted cumulative reward is the episode length; in MountainCar, the plotted cumulative reward is 1 for reaching the target within one episode and 0 otherwise; in Acrobot, the plotted cumulative reward is the negative of the episode length. In all sparse reward tasks, GE entails much faster progress than the other two algorithms. For example, in Sparse MountainCar, within the given number of iterations, DQN and NoisyNet have never (or very rarely) reached the target, hence they make no (little) progress in cumulative reward. On the other hand, GE reaches the targets more frequently since early stage of the training, and makes progress more steadily.
In Figure 3 (d) we plot the state visit trajectories of GE vs. DQN in Sparse MountainCar. The vertical and horizontal axes of the plot correspond to two coordinates of the state space. Two panels of (d) correspond to training after 10 and 30 iterations respectively. As the training proceeds, the state visits of DQN increasingly cluster on a small region in state space and fail to efficiently explore. On the contrary, GE maintains a widespread distribution over states and can explore more systematically.
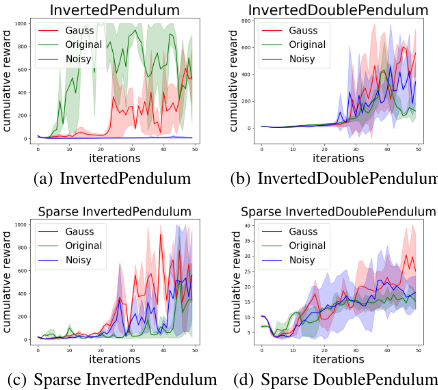
Randomized Critic for Exploration. We evaluate the performance of DDPG with different critics. When DQN is used as a critic, the agent explores by injecting noise into actions produced by the policy [Lillicrap et al., 2016]. When critics are NoisyNet or randomized DQN with GE, the agent explores by updating its parameters using policy gradients computed through randomized critics, effectively injecting noise into the parameter space. In conventional continuous control tasks (Figure 4 (a) and (b)), randomized critics do not enjoy much advantage: for example, in simple control task like InvertedPendulum, where exploration is not important, DDPG with action noise injection makes progress much faster (Figure 4 (a)), though DDPG with randomized critics seem to make progress in a steadier manner. In sparse reward environments (Figure 4 (c) and (d)), however, DDPG with randomized critics tend to make progress at a slightly higher rate than action noise injection.
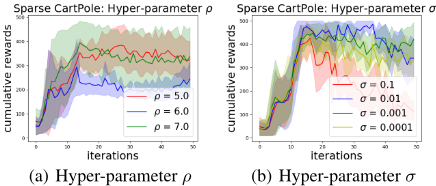
Hyper-parameter. In all experiments, we set qφ(θ) to be factorized Gaussian. In GE, as in NoisyNet [Fortunato et al., 2017], each parameter θ in a fully connected layer (weight and bias) has two distributional parameters: the mean µθ and standard error σθ. Set σθ = log(1 + exp(-ρθ)) and let ρθ be the actual hyper-parameter to tune. If ρθ is large, the distribution over θ is widespread and the agent can execute a larger range of policies before committing to a solution. For both NoisyNet and GE, we require all ρθ to be the same, denoted as ρ, and set the range ρ ∈ [-1,-10] for grid search. A second hyper-parameter for GE is the Gauss parameter σ2 to determine the balance between expected Bellman error and entropy in (7). In our experiments, we tune σ on the log scale log10 σ ∈ [-1, -8].
We empirically find that both ρ, σ are critical to the performance of GE. For each algorithm, We use a fairly exhaustive grid search to obtain the best hyper-parameters. Each experiment is performed multiple times and the reward plots in Figure 2,3,4 are averaged over five different seeds. In Figure 5, we plot the performance of GE under different ρ and σ on Sparse CartPole. From Figure 5 we see that the performance is not monotonic in ρ, σ: large σ (small ρ) generally leads to more active exploration but may hinder fast convergence, and vice versa. One must strike a proper balance between exploration and exploitation to obtain good performance. In DQN, we set the exploration constant to be ϵ = 0.1. In all experiments, we tune the learning rate α ∈ {10-3 , 10-4 , 10-5 }.
7 Conclusion
We have provided a framework based on distributional RL that unifies multiple previous methods on exploration in reinforcement learning, including posterior sampling for bandits as well as recent efforts in Bayesian updates of DQN parameters. We have also derived a practical algorithm based on the Gaussian assumption of return distribution, which allows for efficient control and parameter updates. We have observed that the proposed algorithm obtains good performance on challenging tasks that require consistent exploration. A further extension of our current algorithm is to relax the Gaussian assumption on return distributions. We leave it be future work if more flexible assumption can lead to better performance and whether it can be combined with model-based RL.
@inproceedings{ijcai2018p376,
  title     = {Exploration by Distributional Reinforcement Learning},
  author    = {Tang, Yunhao and Agrawal, Shipra},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2710--2716},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/376},
  url       = {https://doi.org/10.24963/ijcai.2018/376},
}
TY - CPAPER TI - Exploration by Distributional Reinforcement Learning AU - Tang, Yunhao AU - Agrawal, Shipra T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2710 EP - 2716 DO - 10.24963/ijcai.2018/376 UR - https://doi.org/10.24963/ijcai.2018/376 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





