
On Q-learning Convergence for Non-Markov Decision Processes
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 2546-2552.
https://doi.org/10.24963/ijcai.2018/353
Keywords
- Machine Learning: Reinforcement Learning
- Machine Learning: Online Learning
- Planning and Scheduling: Markov Decisions Processes
Abstract
Temporal-difference (TD) learning is an attractive, computationally efficient framework for model- free reinforcement learning. Q-learning is one of the most widely used TD learning technique that enables an agent to learn the optimal action-value function, i.e. Q-value function. Contrary to its widespread use, Q-learning has only been proven to converge on Markov Decision Processes (MDPs) and Q-uniform abstractions of finite-state MDPs. On the other hand, most real-world problems are inherently non-Markovian: the full true state of the environment is not revealed by recent observations. In this paper, we investigate the behavior of Q-learning when applied to non-MDP and non-ergodic domains which may have infinitely many underlying states. We prove that the convergence guarantee of Q-learning can be extended to a class of such non-MDP problems, in particular, to some non-stationary domains. We show that state-uniformity of the optimal Q-value function is a necessary and sufficient condition for Q-learning to converge even in the case of infinitely many internal states.
- [Baird, 1995] Leemon Baird. Residual algorithms: Reinforcement learning with function approximation. In Machine Learning Pro- ceedings 1995, pages 30-37. Elsevier, 1995.
- [Bertsekas and Tsitsiklis, 1995] Dimitri P Bertsekas and John N Tsitsiklis. Neuro-dynamic programming: an overview, volume 1. Belmont: Athena Scientific, 1995.
- [Cassandra et al., 1994] Anthony R Cassandra, Leslie Pack Kael- bling, and Michael L Littman. Acting optimaly in partially ob- servable stochastic domains. AAAI, pages 1023-1023, 1994.
- [Cassandra, 1994] Anthony R Cassandra. Optimal Policies for Par- tially Observable Markov Decision Processes. Technical Report August, Report CS-94-14, Brown Univ, 1994.
- [Hutter, 2005] Marcus Hutter. Universal Artificial Intelligence: Se- quential Decisions based on Algorithmic Probability. Springer, Berlin, 2005.
- [Hutter, 2016] Marcus Hutter. Extreme state aggregation beyond Markov decision processes. Theoretical Computer Science, 650:73-91, 2016.
- [Leike, 2016] Jan Leike. Nonparametric General Reinforcement Learning. PhD thesis, Australian National University, 2016.
- [Li et al., 2006] Lihong Li, Thomas J Walsh, and Michael L Littman. Towards a unified theory of state abstraction for mdps. In ISAIM, 2006.
- [Lin and Mitchell, 1992] L.J. Lin and T.M. Mitchell. Memory ap- proaches to reinforcement learning in non-Markovian domains. Artificial Intelligence, 8(7597):28, 1992.
- [Littman, 1994] Michael L Littman. Memoryless policies: Theoret- ical limitations and practical results. In From Animals to Animats 3: Proceedings of the third international conference on simula- tion of adaptive behavior, volume 3, page 238. MIT Press, 1994.
- [McCallum, 1995] R. Andrew McCallum. Instance-based utile dis- tinctions for reinforcement learning with hidden state. ICML, pages 387-395, 1995.
- [Murphy, 2000] Kevin P Murphy. A survey of pomdp solution tech- niques. environment, 2:X3, 2000.
- [Pendrith and McGarity, 1998] Mark D Pendrith and Michael J Mc- Garity. An analysis of direct reinforcement learning in non- Markovian domains. ICML, pages 421-429, 1998.
- [Perkins and Pendrith, 2002] Theodore J Perkins and Mark D Pen- drith. On the existence of fixed points for Q-learning and Sarsa in partially observable domains. ICML, pages 490-497, 2002.
- [Singh et al., 1994] S Singh, T Jaakkola, and M Jordan. Learning Without State-Estimation in Partially Observable Markov Deci- sion Processes. ICML, 31(0):37, 1994.
- [Sutton and Barto, 1984] R S Sutton and A G Barto. Temporal credit assignment in reinforcement learning. Computer Science, page 210, 1984.
- [Sutton, 1988] Richard S Sutton. Learning to Predict by the Method of Temporal Differences. Machine Learning, 3(1):9-44, 1988.
- [Thrun et al., 2005] Sebastian Thrun, Wolfram Burgard, and Dieter Fox. Partially Observable Markov Decision Processes. Proba- bilistic Robotics, page 2005, 2005.
- [Tsitsiklis, 1994] John N. Tsitsiklis. Asynchronous Stochastic Ap- proximation and Q-Learning. Machine Learning, 16(3):185-202, 1994.
- [Watkins and Dayan, 1992] Christopher J. C. H. Watkins and Peter Dayan. Q-learning. Machine Learning, 8(3-4):279-292, 1992.
- [Whitehead and Lin, 1995] Steven D. Whitehead and Long Ji Lin. Reinforcement learning of non-Markov decision processes. Arti- ficial Intelligence, 73(1-2):271-306, 1995.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Temporal-difference learning [Sutton, 1988] is a wellcelebrated model-free learning framework in machine learning. In TD, an agent learns the optimal action-value function (also known as the Q-value function) of the underlying problem without explicitly building or learning a model of the environment. The agent can learn the optimal behavior from the learned Q-value function: the optimal action maximizes the Q-value function. It is generally assumed that the environment is Markovian and ergodic for a TD agent to converge [Tsitsiklis, 1994; Bertsekas and Tsitsiklis, 1995].
The TD agents, apart from a few restrictive cases 1 , are not proven to learn 2 non-Markovian environments, whereas most real-world problems are inherently non-Markovian: the full true state of the environment is not revealed by the last observation, and the set of true states can be infinite, e.g. as effectively in non-stationary domains. Therefore, it is important to know if the agent performs well in such non-Markovian domains to work with a broad range of real-world problems.
1 See Section 5 for exceptions.
2 In this work we use the term "learn a domain" in the context of learning to act optimally and not to learn a model/dynamics of the domain.
In this work, we investigate convergence of one of the most widely used TD learning algorithms, Q-learning [Watkins and Dayan, 1992]. Q-learning has been shown to converge in MDP domains [Tsitsiklis, 1994; Bertsekas and Tsitsiklis, 1995], whereas there are empirical observations that Qlearning sometimes also work in some non-MDP domains [Sutton and Barto, 1984]. First non-MDP convergence of Q-learning has been reported by Li et al. [2006] for the environments that are Q-uniform abstractions of finite-state MDPs. The recent results in Extreme State Aggregation (ESA) [Hutter, 2016] indicate that under some conditions there exists a deterministic, near-optimal policy for non-MDP environments which are not required to be abstractions of any finite-state MDP. These positive results motivated this work to extend the non-MDP convergence proof of Q-learning to a larger class of infinite internal state non-MDPs.
The most popular extension of MDP is a finite-state partially observable Markov decision process (POMDP). In a POMDP the environment has a hidden true state, and the observations from the environment, generally, do not reveal the true state. Therefore, the agent either has to keep a full interaction history, estimate the true state or maintain a belief over the possible true states. In our formulation, we use an even more general class of processes, history-based decision process (HDP): the history-based process is equivalent to an infinite-state POMDP [Leike, 2016]. We provide a simple proof of Q-learning convergence to a class of domains that encompasses significantly more domains than MDP and intersects with POMDP and HDP classes. We name this class Q-value uniform Decision Process (QDP) and show that Qlearning converges in QDPs. Moreover, we show that QDP is the largest class where Q-learning can converge, i.e. QDP provides the necessary and sufficient conditions for Q-leaning convergence.
Apart from a few toy problems, it is always a leap of faith to treat real-world problems as MDPs. An MDP model of the underlying true environment is implicitly assumed even for model-free algorithms. Our result helps to relax this assumption: rather assuming the domain being a finite-state MDP, we can suppose it to be a QDP, which is a much weaker implicit assumption. The positive result of this paper can be interpreted in a couple of ways; a) as discussed above, it provides theoretical grounds for Q-learning to be applicable in a much broader class of environments or b) if the agent has access to a QDP aggregation map as a potential model of the true environment or the agent has a companion map learning/estimation algorithm to build such a model, then this combination of the aggregation map with Q-learning converges. It is an interesting topic to learn such maps, but is beyond the scope this work.
The rest of the paper is structured as follows. In Section 2 we set up the framework. Section 3 drafts the QDP class. Section 4 gives a preview of our main convergence result. Section 5 provides a context of our work in the literature. Section 6 contains the proof of the main results. In Section 7 we numerically evaluate Q-learning on a few non-MDP toy domains. Section 8 concludes the paper.
2 Setup
We use the general history-based agent-environment reinforcement learning framework [Hutter, 2005; Hutter, 2016]. The agent and the environment interact in cycles. At the beginning of a cycle t ∈ N the agent takes an action at from a finite action-space A. The environment dispenses a realvalued reward rt+1 from a set R ⊂ R and an observation ot+1 from a finite set of observations O. However, in our setup, we assume that the agent does not directly use this observation, e.g. because O maybe too huge to learn from. The agent has access to a map/model φ of the environment that takes in the observation, reward and previous interaction history and provides the same reward rt+1 and a mapped state st+1 from a finite set of states S; and the cycle repeats. Formally, this agent-environment interaction generates a growing history ht+1 := htatot+1rt+1 from a set of histories Ht := (A×O×R)t . The set of all finite histories is denoted by H∗ := ⋃t Ht . The map φ is assumed to be a surjective mapping fromH∗ to S. We use ht := ϵ to denote the empty history and := to express an equality by definition. In general (non-MDPs), at any time-instant t the transition probability to the next observation o′ := ot+1 and reward r′ := rt+1 is a function of the history-action (h, a) := (ht, at)-pair and not of the state-action (s, a) := (st, at)-pair. The true environment as is a history-based (decision) process.
Definition 1 (History-based Decision Process (HDP)) A history-based decision process P is a stochastic mapping from a history-action pair to observation-reward pairs. Formally, P : H∗ × A ⇝ O × R, where ⇝ denotes a stochastic mapping.
We use Q to denote an action-value function of a HDP, and Q∗ denotes the optimal Q-value function.
where γ ∈ [0, 1) is a discount factor. In our setup, the agent does not maintain a complete history and effectively experiences the agent-environment interaction as an action-statereward sequence (at, st, rt)t∈N. We call it a state-process 3 induced by the map φ.
Definition 2 (State-process) For a history h that is mapped to a state s, a state-process ph is a stochastic mapping from a state-action pair with the fixed state s to state-reward pairs. Formally, ph : {s}×A⇝S ×R.
The relationship between the underlying HDP and the induced state-process for an s = φ(h) is formally defined as:
We denote the action-value function of the state-process by q, and the optimal Q-value function is given by q∗ :
It is clear that ph(s′ r′ |sa) may not be same as p˙h (s′ r′ |sa) for any two histories h and ˙h mapped to a same state s. If the state-process is an MDP, then ph is independent of history and so is q∗ , and convergence of Q-learning follows from this MDP condition [Bertsekas and Tsitsiklis, 1995]. However, we do not assume such a condition and go beyond MDP mappings. We later show - by constructing examples - that q∗ can be made independent of history while the state-process is still history dependent, i.e. non-MDP.
Now we formally define Q-learning: At each time-step t the agent maintains an action-value function estimate qt. The agent in a state s := st takes an action a := at and receives a reward r′ := rt+1 and the next state s′ := st+1. Then the agent performs an action-value update to the (s, a)-estimate with the following Q-learning update rule:
where (αt)t∈N is a learning rate sequence.
3 Q-Value UniformDecision Process (QDP)
In this section we formulate a class of environments called Q-value uniform decision processes, i.e. QDP class. This class is substantially larger than MDP and has a non-empty intersection with POMDP and HDP (Figure 1). In a stateaggregation context, a model is a QDP if it satisfies the following state-uniformity condition.
Definition 3 (State-uniformity condition) For any action a, if any two histories h and ˙h map to the same state s, then the optimal Q-values of the underlying HDP of these histories are the same, i.e. state-uniform; Q∗ (h, a) = Q∗ ( ˙h, a). It is easy to see that in this case q∗ (s, a) = Q∗ (h, a) [Hutter, 2016].
3 It is technically a state and reward process, but since rewards are not affected by the mapping φ, we suppress the reward part to put more emphasis on the contrast between history and state dependence.
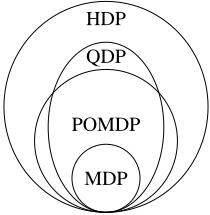
The state-uniformity condition is weaker than the MDP condition: the latter implies the former but not the other way around [Hutter, 2016]. Therefore, trivially MDP ⊆ QDP POMDP ⊆ HDP. The example in Figure 2 shows that QDP ∩ POMDP\MDP ̸= ∅. The example in Figure 5 proves that QDP \POMDP ̸= ∅. Moreover, it is easy to find examples in POMDP\QDP and HDP\QDP.
It is easy to see that QDP is a much larger class than MDP since the former allows non-stationary domains: it is possible to have pht (·|sa) ̸= phτ (·|sa) for some histories φ(ht) = φ(hτ) = s at two different time-steps but still maintaining Q∗ (ht, a) = Q∗ (hτ , a) (Figure 5). Moreover, the definition of QDP enables us to approximate most if not all problems as a QDP model: any number of similar Q∗ - value histories can be merged into a single QDP state [Hutter, 2016]. In particular, a QDP model of the environment can provide more compression in terms of state space size as compared to an MDP model: multiple MDP states with the same/similar Q-value can be merged into a single QDP state but not necessarily the other way around. Thus, QDP allows for more compact models for an environment than its MDP counterparts.
In general, we can say that a POMDP has both the dynamics and Q-values as functions of history. Whereas, the definition of QDP provides models where only the dynamics can be history-dependent. Therefore, QDP captures a subset of POMDP models that have history-independent Q-values.
4 Main Result
We assume that the state-process is ergodic - i.e. all states are reachable under any policy from the current state after sufficiently many steps.
Assumption 4 (Ergodicity) The state-process is ergodic.
Because of the ergodicity assumption we can suppose the following standard stochastic approximation conditions on each state-action (s, a)-pair's learning rate sequence (αt)t∈N4 .
The above conditions on the learning rate ensure that the agent asymptotically decreases the learning rate to converge to a fixed point but never stops learning to avoid local maxima [Bertsekas and Tsitsiklis, 1995]. It is critical to note that we assume ergodicity of the state-process but not of the underlying HDP: a state can be reached multiple times from different histories but any history is only reached once. We assume that the state-process is a QDP.
4 Note that αt(s, a) := 0, ∀(s, a) ̸= (st, at).
Assumption 5 (QDP) The state-process is a QDP.
It is important to consider that we only assume the optimal action-value to be a function of states. We do not suppose any structure on the intermediate action-value estimates cf. qt(s, a) ̸= Qt(h, a). We also assume that rewards are bounded. This is a standard condition for Q-learning convergence.
Assumption 6 (Bounded rewards) The rewards are bounded, i.e. r ∈ [rmin, rmax].
We have all the components in place to extend Q-learning convergence in QDP.
Theorem 7 (Q-learning Convergence in QDP) Under Assumptions 4, 5 and 6, and with a learning rate sequence (αt)t∈N satisfying (5), the sequence (qt)t∈N generated by the iteration (4) converges to q∗ = Q∗ .
Hence, the agent learns the optimal action-value function of a QDP state-process.
5 RelatedWork
A similar result was first reported by Li et al. [2006] in a finite state MDP setting. We confirm and extend the findings by considering a more general class of environments, i.e. HDP. Also, we do not assume a weighting function to define the state-process cf. [Li et al., 2006, Definition 1], and our proof is based on time-dependent contraction mappings (see Section 6 for the details).
A finite-state POMDP is the most commonly used extension of an MDP. It is well-known that the class of finitestate POMDPs is a subset of HDP class [Leike, 2016]. One prevalent approach to handle the non-Markovian nature of a POMDP is to estimate a Markovian model with a state estimation method [Whitehead and Lin, 1995; Lin and Mitchell, 1992; Cassandra et al., 1994; Cassandra, 1994] or use a finite subset of the recent history as a state [McCallum, 1995] to form a k-order MDP (k-MDP). Then Q-learning is applied to learn this resultant state-based MDP. This is a different approach to ours. We do not try to estimate an MDP or k-MDP representation of the underlying HDP.
Singh et. al. [Singh et al., 1994] investigate a direct application of model-free algorithms to POMDPs without a state estimation step akin to our setup but limited to finite state POMDPs only. They show that an optimal policy in a POMDP may be non-stationary and stochastic. But the learned policy in direct model-free algorithms, such as Qlearning, is generally stationary and deterministic by design. Moreover, they also show that the optimal policy of POMDP can be arbitrarily better than the optimal stationary, deterministic policy of the corresponding MDP. These negative results of [Singh et al., 1994] are based on counter-examples that violate the state-uniformity assumption of the optimal Q-value function. Similar negative findings are reported by Littman [1994]. Our positive convergence result holds for a subset of POMDPs that respects the state-uniformity condition.
Pendrith and McGarity [1998] show that a direct application of standard reinforcement learning methods, such as Q-learning, to non-Markovian domains can have a stationary optimal policy, if undiscounted return is used as a performance measure. Perkins and Pendrith [2002] prove existence of a fixed point in POMDPs for continuous behavior policies. However, this fixed point could be significantly worse than the average reward achieved by an oscillating discontinuous behavior policy. It signifies the effect of behavior policy on the learning outcome. On the other hand, our convergence result is valid as long as all the state-action pairs are visited infinitely often. The nature of the behavior policy does not directly affect our convergence result. A comprehensive survey of solution methods for POMDPs is provided by Murphy [2000] and more recently by Thrun et al. [2005].
6 Convergence Proof
We provide a proof of Theorem 7 in this section. Superficially, the proof looks similar to a standard MDP proof [Bertsekas and Tsitsiklis, 1995], however, a subtlety is involved in the definition of the contraction map: the contraction map is a function of history. This history-dependence lets the proof scale to non-MDP domains, especially to non-stationary domains.
Proof of Theorem 7. At a time-instant t with a history ht we rewrite (4) in terms of an operator and a noise term.
where, the noise term is defined as follows,
Since the agent samples from the underlying HDP, the operator Fht is a history-based operator.
where Ft is a complete history of the algorithm up to timestep t that signifies all information including ht, (αk)k≤t and the state sequence (sk)k≤t. We use Epht as an expectation operator with respect to pht .
Noise is bounded. Now we show that the noise term is not a significant factor that affects the convergence of Q-learning. By construction it has a zero mean value:
Due to the bounded reward assumption the variance of the noise term is also bounded.
(a) follows from Popoviciu's inequality, Var(X) ≤ 1/4(maxX - minX)2 , (b) is due to the bounded rewards assumption; and (c) results from some algebra with constants A := ∆/4 (2γ/1-γ +∆) and B := γ 2/4, where ∆ := (rmax - rmin) /(1 - γ). We denote a sup-norm by || · ||∞.
Fh is a contraction. For a fixed history h, we show that an operator Fh is a contraction mapping.
(a) for a fixed history, the expectation only depends on the (s, a)-pair rather than the complete history Ft.
Same fixed point. We show that for any history h, the contraction operator Fh has a fixed point q∗ . Let h be mapped to state s:
(a) is the QDP assumption; and (b) follows from (2) and again using the QDP assumption. We also show that for any history h the operator Fh has a same contraction factor γ.
(a) follows from (12); and (b) is due to (11). Therefore, for any history h the operator Fh has the same fixed point q∗ with the same contraction factor γ.
We have all the conditions to invoke a convergence result from Bertsekas and Tsitsiklis [1995]. We adopt 5 and state Proposition 4.5 from Bertsekas and Tsitsiklis [1995] without reproducing the complete proof.
Proposition 8 (Prop. 4.5 [Bertsekas and Tsitsiklis, 1995])
Let (qt)t∈N be the sequence generated by the iteration (4). We assume the following.
- (a) The learning rates αt(s, a) are nonnegative and satisfy,
- (b) The noise termwt(s, a) satisfies,
where, A and B are constants.
- (c) There exists a vector q∗ , and a scalar γ ∈ [0, 1), such that,
Then, qt converges to q∗ with probability 1.
Proof Sketch. We have a sequence of maps (Ft)t∈N. At any time-step t, the map Ft is a contraction and every map moves the iterates toward the same fixed point q∗ . Since, the contraction factor is the same, the rate of convergence is not affected by the order of the maps. Every map contracts the iterates by a factor γ with respect to the fixed point that asymptotically converges to q∗ .
Proposition 8 uses a sequence of maps (Ft)t∈N with a same fixed point. In our case, we have this sequence based on histories, i.e.(Fht )t∈N. Similarly, for wt and pt we have corresponding history-based instances. Therefore, Proposition 8 with pt = pht , Ft = Fht and wt = wht provides the main result. This can be done, since αt, qt,wt and Ft are allowed to be random variables.
Obviously, state-uniformity is a necessary condition, since otherwise Q∗ (h, a) can not even be represented as q∗ (s, a). Typically, the state-process is assumed to be an MDP. This makes the state-process ph independent of history, and leads to a history-independent operator F := Fh for any history h, which (trivially) all have the same fixed point. We relax this MDP assumption, and only demand state-uniformity of the optimal value-function. The proof shows that this condition is sufficient to provide a unique fix point for the historydependent operators. Therefore, the state-uniformity is not only a necessary but also a sufficient condition for Q-learning convergence.
5 The original proposition is slightly more general than we need for our proof. It has an extra diminishing noise term which we do not have/require in our formulation.
7 Empirical Evaluation
In this section, we empirically evaluate two example nonMDP domains to show the validity of our result.
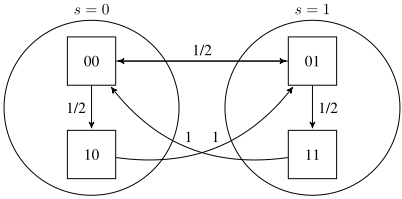
Non-Markovian Reward Process. Let us consider our first example from [Hutter, 2016] to demonstrate Q-learning convergence to a non-Markovian reward processes (non-MRP). We consider that the underlying HDP is an MDP over the observation space O (in fact an action-independent MDP, i.e. an MRP) with a transition matrix T and a deterministic reward function R. The state diagram of the process is shown in Figure 2.
Due to this structure, the HDP is expressible as, P(o′ r′ |ha) = Too′ · Jr′ = R(o)K, such that h has a last observation o, where J·K denotes an Iverson bracket. The observation space is O = {00, 01, 10, 11}. Let us consider the state space S = {0, 1}, and the agent experiences the state-process under the following aggregation map:
It is easy to see that the resultant state-process is not an MDP (MRP):
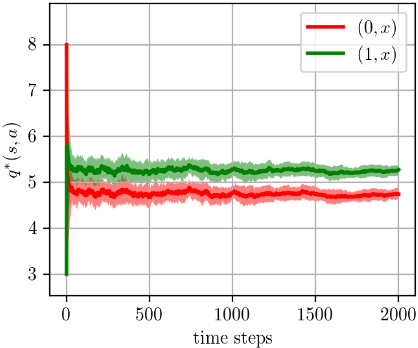
which implies p00 ̸= p10, but this state-process satisfies the optimal Q-value function state-uniformity condition (see below). Hence, the state-process is a QDP ∈ POMDP\MDP: the underlying HDP has a finite set of hidden states, i.e. the states of the underlying MDP. Since it is an actionindependent process, the action-value function is the same for any action a ∈ A. We denote the only available action with x:
We apply Q-learning to the induced state-process and the learning curves plot is shown in Figure 3. The plot shows that Q-learning is able to converge to the optimal action-value function of the process, despite the fact that the state-process is a non-MDP (non-MRP).
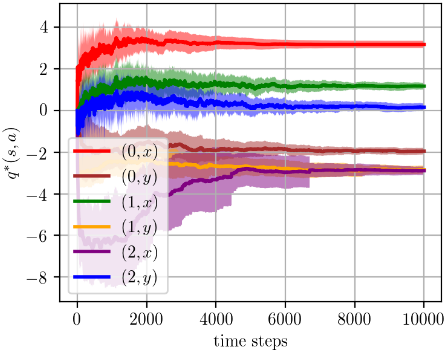
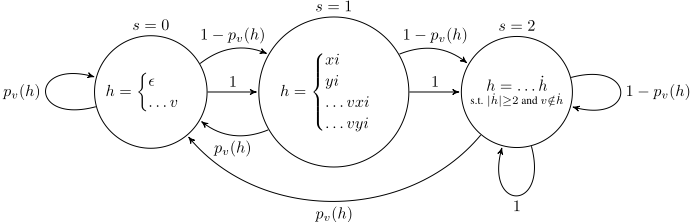
Non-Markovian Decision Process. The previous example demonstrated that Q-learning is able to learn a non-MRP ∈ QDP. Now we provide an example QDP which is a two-action non-MDP ∈ HDP\POMDP: the state space of the underlying HDP is infinite. The agent is facing a non-stationary state-process with state space S = {0, 1, 2} and action space A = {x, y}. The agent has to input a right key-action ks at a state s = φ(h) but the environment accepts the key action with a certain history-dependent probability pv(h) by providing an observation from O = {v, i}, where v and i indicate acceptance or rejection of an input, respectively.
where, %(v, h) is the percentage of accepted keys in h and pmin is a minimum acceptance probability. Without loss of generality, we use the key sequence k0 := x, k1 := x, k2 := y. The history to state mapping is defined as:
It is apparent from the mapping function that state-0 is the start state, and it is also the case when a key is accepted in the last time-step, state-1 is defined when a key input is rejected once, and state-2 is reached when the key input has been recently rejected at least twice in a row.
The transition probabilities are formally given as follows (see Figure 5 for a graphical representation):
The reward is also a function of the complete history.
It is easy to see that Q-values are only a function of stateaction pairs as follows for φ(h) = s:
Despite the history-based dynamics, Figure 4 shows that Q-learning is able to learn the Q-values of the non-stationary state-process due to the fact that it is a QDP.
8 Conclusion
In this paper, we proved that Q-learning convergence can be extended to a much larger class of decision problems than finte-state MDP. We call this class of environments QDP. In QDP, the optimal action-value function of the state-process is still only a function of states, but the dynamics can be a function of the complete history (in effect, a function of time). That enables QDP to allow non-stationary domains in contrast to finite-state MDPs that can only model stationary domains. We also showed that this state-uniformity condition is not only a necessary but also a sufficient condition for Qlearning convergence. An empirical evaluation of a few nonMDP domains is also provided. In the state-aggregation context, we only extended the convergence for an exact aggregation case. A natural next step is to investigate if this proof can be extended to the approximate aggregation case. Approximate aggregation is a special case of function approximation, but there are known counter-examples of Q-learning diverging with function approximation [Baird, 1995]. Therefore, it is intriguing to know if there exist some non-trivial conditions that provide convergence guarantee for Q-learning in the approximate aggregation case and yet avoid these counterexamples.
@inproceedings{ijcai2018p353,
  title     = {On Q-learning Convergence for Non-Markov Decision Processes},
  author    = {Majeed, Sultan Javed and Hutter, Marcus},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {2546--2552},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/353},
  url       = {https://doi.org/10.24963/ijcai.2018/353},
}
TY - CPAPER TI - On Q-learning Convergence for Non-Markov Decision Processes AU - Majeed, Sultan Javed AU - Hutter, Marcus T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 2546 EP - 2552 DO - 10.24963/ijcai.2018/353 UR - https://doi.org/10.24963/ijcai.2018/353 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





