
Better and Faster: Knowledge Transfer from Multiple Self-supervised Learning Tasks via Graph Distillation for Video Classification
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 1135-1141.
https://doi.org/10.24963/ijcai.2018/158
Keywords
- Computer Vision: Recognition: Detection, Categorization, Indexing, Matching, Retrieval, Semantic Interpretation
- Computer Vision: Structural and Model-Based Approaches, Knowledge Representation and Reasoning
Abstract
Video representation learning is a vital problem for
classification task. Recently, a promising unsupervised
paradigm termed self-supervised learning
has emerged, which explores inherent supervisory
signals implied in massive data for feature learning
via solving auxiliary tasks. However, existing
methods in this regard suffer from two limitations
when extended to video classification. First, they
focus only on a single task, whereas ignoring complementarity
among different task-specific features
and thus resulting in suboptimal video representation.
Second, high computational and memory cost
hinders their application in real-world scenarios. In
this paper, we propose a graph-based distillation
framework to address these problems: (1) We propose
logits graph and representation graph to transfer
knowledge from multiple self-supervised tasks,
where the former distills classifier-level knowledge
by solving a multi-distribution joint matching problem,
and the latter distills internal feature knowledge
from pairwise ensembled representations with
tackling the challenge of heterogeneity among different
features; (2) The proposal that adopts a
teacher-student framework can reduce the redundancy
of knowledge learned from teachers dramatically,
leading to a lighter student model that solves
classification task more efficiently. Experimental
results on 3 video datasets validate that our proposal
not only helps learn better video representation
but also compress model for faster inference.
- [Agrawal et al., 2015] Pulkit Agrawal, Joao Carreira, and Ji- tendra Malik. Learning to see by moving. In ICCV, pages 37-45, 2015.
- [Arjovsky et al., 2017] Martin Arjovsky, Soumith Chintala, and Léon Bottou. Wasserstein gan. arXiv preprint arXiv:1701.07875, 2017.
- [Charikar et al., 2002] Moses Charikar, Kevin Chen, and Martin Farach-Colton. Finding frequent items in data streams. ALP, pages 784-784, 2002.
- [Chen et al., 2017] Yuntao Chen, Naiyan Wang, and Zhaox- iang Zhang. Darkrank: Accelerating deep metric learn- ing via cross sample similarities transfer. arXiv preprint arXiv:1707.01220, 2017.
- [Fernando et al., 2017] Basura Fernando, Hakan Bilen, Efs- tratios Gavves, and Stephen Gould. Self-supervised video representation learning with odd-one-out networks. In CVPR, pages 5729-5738, 2017.
- [Gao et al., 2016] Yang Gao, Oscar Beijbom, Ning Zhang, and Trevor Darrell. Compact bilinear pooling. In CVPR, pages 317-326, 2016.
- [Hinton et al., 2015] Geoffrey Hinton, Oriol Vinyals, and Jeff Dean. Distilling the knowledge in a neural network. In NIPS Workshop, 2015.
- [Jayaraman and Grauman, 2016] Dinesh Jayaraman and Kristen Grauman. Slow and steady feature analysis: higher order temporal coherence in video. In CVPR, pages 3852-3861, 2016.
- [Jiang et al., 2011] Yu-Gang Jiang, Guangnan Ye, Shih-Fu Chang, Daniel Ellis, and Alexander C Loui. Consumer video understanding: A benchmark database and an eval- uation of human and machine performance. In ICMR, page 29, 2011.
- [Krizhevsky et al., 2012] Alex Krizhevsky, Ilya Sutskever, and Geoffrey E Hinton. Imagenet classification with deep convolutional neural networks. In NIPS, pages 1097- 1105, 2012.
- [Kuehne et al., 2013] Hilde Kuehne, Hueihan Jhuang, Rainer Stiefelhagen, and Thomas Serre. Hmdb51: A large video database for human motion recognition. In HPCSE, pages 571-582. 2013.
- [Lee et al., 2017] Hsin-Ying Lee, Jia-Bin Huang, Maneesh Singh, and Ming-Hsuan Yang. Unsupervised representa- tion learning by sorting sequences. In ICCV, pages 667- 676, 2017.
- [Lopez-Paz et al., 2016] David Lopez-Paz, Léon Bottou, Bernhard Schölkopf, and Vladimir Vapnik. Unifying dis- tillation and privileged information. In ICLR, 2016.
- [Lotter et al., 2017] William Lotter, Gabriel Kreiman, and David Cox. Deep predictive coding networks for video prediction and unsupervised learning. In ICLR, 2017.
- [Luo et al., 2017] Zelun Luo, Lu Jiang, Jun-Ting Hsieh, Juan Carlos Niebles, and Li Fei-Fei. Graph distillation for action detection with privileged information. arXiv preprint arXiv:1712.00108, 2017.
- [Misra et al., 2016] Ishan Misra, C Lawrence Zitnick, and Martial Hebert. Shuffle and learn: unsupervised learning using temporal order verification. In ECCV, pages 527- 544, 2016.
- [Noroozi and Favaro, 2016] Mehdi Noroozi and Paolo Favaro. Unsupervised learning of visual representations by solving jigsaw puzzles. In ECCV, pages 69-84, 2016.
- [Pathak et al., 2016] Deepak Pathak, Philipp Krahenbuhl, Jeff Donahue, Trevor Darrell, and Alexei A Efros. Con- text encoders: Feature learning by inpainting. In CVPR, pages 2536-2544, 2016.
- [Purushwalkam and Gupta, 2016] Senthil Purushwalkam and Abhinav Gupta. Pose from action: Unsupervised learning of pose features based on motion. In ECCV, 2016.
- [Romero et al., 2015] Adriana Romero, Nicolas Ballas, Samira Ebrahimi Kahou, Antoine Chassang, Carlo Gatta, and Yoshua Bengio. Fitnets: Hints for thin deep nets. In ICLR, 2015.
- [Simonyan and Zisserman, 2015] Karen Simonyan and An- drew Zisserman. Very deep convolutional networks for large-scale image recognition. In ICLR, 2015.
- [Soomro et al., 2012] Khurram Soomro, Amir Roshan Za- mir, and Mubarak Shah. Ucf101: A dataset of 101 human actions classes from videos in the wild. arXiv preprint arXiv:1212.0402, 2012.
- [Vapnik and Izmailov, 2015] Vladimir Vapnik and Rauf Iz- mailov. Learning using privileged information: similarity control and knowledge transfer. 16(20232049):55, 2015.
- [Wang and Gupta, 2015] Xiaolong Wang and Abhinav Gupta. Unsupervised learning of visual representations using videos. In ICCV, pages 2794-2802, 2015.
- [Yosinski et al., 2014] Jason Yosinski, Jeff Clune, Yoshua Bengio, and Hod Lipson. How transferable are features in deep neural networks? In NIPS, pages 3320-3328, 2014.
- [Zagoruyko and Komodakis, 2017] Sergey Zagoruyko and Nikos Komodakis. Paying more attention to attention: Im- proving the performance of convolutional neural networks via attention transfer. In ICLR, 2017.
- [Zhang et al., 2017] Richard Zhang, Phillip Isola, and Alexei A. Efros. Split-brain autoencoders: Unsupervised learning by cross-channel prediction. In CVPR, pages 1057-1068, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Video representation learning aims to capture discriminative features from video data and is a critical premise for classification problem. In the last decade, supervised methods have achieved remarkable success in a variety of areas, showing extraordinary performance on representation learning. However, heavy reliance on well-labeled data limits the scalability of these methods as building large-scale labeled datasets is time-consuming and costly. Furthermore, learning from manual annotations is inconsistent with biology, as living organisms develop their visual systems without the requirement for millions of semantic labels. Hence, there is a growing interest in unsupervised learning, and self-supervised learning, one of the most promising unsupervised representation learning paradigms, is gaining momentum.
∗Corresponding author.
In contrast to supervised methods, self-supervised learning exploits structural information of the raw visual data as supervisory signals to yield transferable representation without manual annotations. Concretely, machine is asked to solve an auxiliary task by leveraging self-supervision rather than labels, and this process can result in useful representation. The core hypothesis behind this idea is that solving these tasks need high-level semantic understanding of data, which forces self-supervised models to learn powerful representation.
Self-supervised learning is especially potential in video processing area since video is an information-intensive media that can provide plentiful contextual supervisory cues by nature. While various types of auxiliary strategies in video [Agrawal et al., 2015; Wang and Gupta, 2015; Jayaraman and Grauman, 2016; Fernando et al., 2017] have shown impressive performance, there are two main limitations of these works. First, they commonly resort to a single task without accounting for complementarity among different task-specific features. Empirically, solving different tasks in video need different features and these features can complement each other to form a comprehensive understanding of video semantics. Second, in order to achieve better performance, researchers tend to adopt deeper and wider models for representation embedding at the expense of high computational and memory cost. As video data in real-world workflows is of huge volume, efficiency issue must be addressed before practical application of classification approaches.
In this paper, we argue that heterogeneous video representations learned from different auxiliary tasks in an ad-hoc fashion are not orthogonal among each other, which can be incorporated into a more robust feature-to-class semantics. In analogy to biological intelligence, humans can improve performance on a task via transferring knowledge learned from other tasks and, intuitively, a general-purpose representation is strong enough to handle tasks in different scenarios. In light of above analysis, we propose to learn video representation for classification problem with a Divide and Conquer manner: (1) Instead of designing one versatile model for capturing discriminating features from different aspects simultaneously, we distill knowledge from multiple teacher models that are adept at specific aspects to the student model; (2) The student model is expected to be lighter since redundancy of knowledge from teachers is reduced after distillation. To this end, we propose a graph-based distillation framework, which bridges the advance of self-supervised learning and knowledge distillation for both exploiting complementaries among different self-supervised tasks and model compression. The main contributions of this paper are as follows:
(1) We propose logits graph (Gl) to distill softened prediction knowledge of teachers at classifier level, where we formalize logits graph distillation as a multi-distribution joint matching problem, and adopt Earth Mover (EM) distance as criteria to measure complementary gain flowing among the vertices of Gl. (2) We propose representation graph (Gr) to distill internal feature knowledge from pairwise ensembled representations yield by compact bilinear pooling, which tackles the challenge of heterogeneity among different features, as well as performs as an adaptation method to assist logits distillation.
Attributed to the above two distillation graphs, student model can incorporate complementary knowledge from multiple teachers to form a comprehensive video representation. Furthermore, distillation mechanism makes sure that student model works with fewer parameters than teachers, which has lower computational complexity and memory cost.
We conduct comprehensive experiments on 3 widely-used video classification datasets, which validate that the proposed approach not only helps learn better video representation but also improve efficiency for video classification.
2 RelatedWork
2.1 Self-supervised Learning
Self-supervised learning is a recently introduced unsupervised paradigm, its key contribution is answering the question that how to effectively evaluate the performance of models trained without manual annotations. Typically, works in this area design tasks which are not directly concerned, such "auxiliary" tasks are difficult enough to ensure models can learn high-level representations. Nowadays, various selfsupervised methods have been studied in computer vision, owing to image/video can provide rich structural information for developing auxiliary tasks.
Previous auxiliary tasks in single image domain involve asking networks to inpaint images with large missing regions [Pathak et al., 2016], colorize grayscale images [Zhang et al., 2017] and solve jigsaw puzzles by predicting relative position of patches [Noroozi and Favaro, 2016], etc. Compared to images, videos contain more abundant spatiotemporal information to formulate self-supervision. For example, temporal continuity among frames can be leveraged to build a sequence order verification or sorting task [Misra et al., 2016; Fernando et al., 2017; Lee et al., 2017]. Wang et al. [2015] finds corresponding patch pairs via visual tracking and use the constraint that similarity of matching pairs is larger than that of random pairs for training guidance. Analogously, Dinesh et al. [2016] proposes temporally close frames should have similar features, as well as features change over time should be smooth. In addition, as shown in [Agrawal et al., 2015], ego-motion can also be utilized as meaningful supervision for visual representation learning. Our work is based on four self-supervised approaches in video (see section 3).
2.2 Knowledge Distillation
Knowledge distillation (KD) [Hinton et al., 2015] aims to utilize the logits, i.e., pre-softmax activations of trained classifiers (i.e., teacher models), to form softened probabilities that convey information of intra- and inter-class similarities. These extra supervisions (aka soft targets) can be combined with original one-hot labels (aka hard targets) to guide a lighter model (i.e., student model) to learn a more generalizable representation. After [Hinton et al., 2015], a surge of variants emerge to mine different forms of knowledge implied in teacher models. FitNets [Romero et al., 2015] treats internal feature maps of ConvNet as hints that can provide explanation of how a teacher solves specific problems. Sergey et al. [2017] propose learning to mimic the attention maps of teacher model can be helpful. Besides knowledge that teacher learned from single sample, the relationships across different samples are also valuable for student training [Chen et al., 2017]. In this paper, we distill knowledge of multiple teachers from both logits prediction and internal feature, denoted by logits distillation and representation distillation respectively.
Lopez-Paz et al. [2016] propose generalized distillation (GD) to combine KD with privileged information [Vapnik and Izmailov, 2015]. This technique distills knowledge from privileged information learned by teacher model at training stage, aiming at boosting student model at test stage where supervision from teacher is totally absent. More recently, [Luo et al., 2017] considers multi-modal data as privileged information and extends GD paradigm to a graph-based form. In this paper, we advocate that self-supervised tasks could be powerful privileged information which can supply student model with expertise from multiple views of video semantics, and internal feature distillation should be leveraged to further assist softened logits distillation as an adaptation method.
3 Self-supervised Tasks
Under the principle of maximizing complementarity, we first implement four self-supervised methods in video, including frame sorting [Lee et al., 2017], learning from egomotion [Agrawal et al., 2015], tracking [Wang and Gupta, 2015], and learning from frame predicting that we design in this work inspired by [Lotter et al., 2017]. For better readability, we denote them using abbreviations as πS, πM, πT and πP, respectively. πS formulates the sequence sorting task as a multi-class classification problem. Taking symmetry of some actions (e.g., opening/closing a door) into account, there are n!/2 possible permutations for each n-tuple of frames. πM captures camera transformation between two adjacent frames that the agent receives when it moves and trains model to determine whether two given frames are temporally close. πT tracks similar patches in video and measures distance of them in representation space. πP predicts the subsequent frames of video, and we adopt a neuroscience inspired architecture named PredNet [Lotter et al., 2017] as visual encoder.
We give the insights about the complementarity among these tasks as follows: (1) Self-supervised models can be mathematically divided into generative (e.g., πP) and discriminative (e.g., other three tasks) categories, and features extracted by them represent two complementary aspects of video understanding, like the imagination and judgment aspects in human understanding. (2) πS and πP force machine to capture temporal information in video, while πM and πT focus on identifying visual elements or their parts, in which spatial feature is more useful. (3) Video contains both local and holistic feature that conveyed by short- and long-term clips, respectively. In our case, πM and πT are adept at utilizing local information, while πS and πP are committed to capture holistic feature in video.
4 Graph Distillation Framework
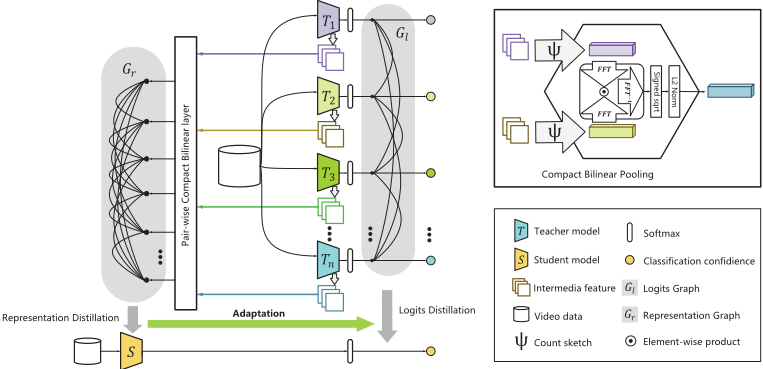
The proposed framework is illustrated in Figure 1. We distill knowledge of self-supervised teacher models from two perspectives, namely soft probability distribution and internal representation. In this section, we first formalize the problem, then elaborate two components of the proposed approach.
4.1 ProblemFormalization
To formalize the problem, assume Dtr = {(xi, yi)}|Dtr| i=1 and Dte = {(xi, yi)}|Dte| i=1 denote the training set with |Dtr| samples and the test set with |Dte| samples, respectively. xi ∈ Rd is the video clip and yi ∈ [1, c] represents the label for c-class video classification problem. Π = {πS, πM, πT , πP} is the set of self-supervised tasks in section 3 and Ft = {f (i) t }|Ft| i=1 is the set of teacher functions learned from Π. Our goal is learning a lighter student function f ⋆ s with aid of Ft under the principle of empirical risk minimization (ERM):
where Fs is the function class of fs : Rd → [1, c], ℓ is the loss function and Ω is the regularizer. Notably, ft and fs in this paper are deep convolutional neural networks unless otherwise specified (see section 5.1).
4.2 Logits Graph Distillation
In vanilla knowledge distillation, the loss in Eq. (1) is composed with two parts:
where ℓh denotes the loss stems from true one-hot labels (i.e., hard targets) and ℓs denotes the imitation loss that comes from softened predictions (i.e., soft targets), λ ∈ (0, 1) is the hyperparameter which balances ℓh and ℓs. In practice, ℓh is typically the cross entropy loss:
where I is the indicator function and σ is the softmax operation σ(zi) = expzi ∑ck=1 expzk . Softened prediction qi in imitation loss of Eq. (2) is defined as qi = σ(ft(xi)/T ) in which ft(xi) is the class-probability prediction on xi produced by teacher ft, T is the temperature and a higher value for T produces a softer probability distribution over the classes.
Our logits graph Gl extends unidirectional distillation above to distilling logits knowledge from multiple selfsupervised tasks dynamically. Gl performs as a directed graph in which each vertex vm represents a self-supervised teacher and the edge en→m ∈ [0, 1] denotes the information weight from vn to vm. Given the video sample xi, the corresponding total imitation loss in logits graph distillation is calculated by
where ℓlogit n→m means the distillation loss flowing on edge en→m, U is the universe set that contains all vertices of Gl and V(vm) is the set of vertices that point to vm. F i t represents the logits output of teachers on sample xi. As depicted in Figure 2, we treat distillation in Gl as a multi-distribution matching problem, where teachers dynamically adjust their logits distribution according to complementary gain (CG) received from their neighbors, and CG is based on the imitation feedback of student when it distills knowledge from different teachers. Take single teacher-student pair for example, we use Earth Mover (EM) distance to measure ℓlogit (xi, f (k) t ) as:
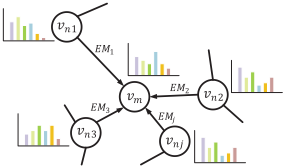
where P(k) t and Ps denote the space of probability belong to f (k) t and fs, respectively. Φ(P(k) t , Ps) represents the set of all joint distributions of γ(µ, η) whose marginals are respectively P(k) t and Ps. µ(xi) distills softened logits from f (k) t with temperature Tk, where k means applying different temperature for different teachers. η(xi) is output probability of the student network. We implement Gl using adjacency matrix where element Gl[m][n] equals to em→n, and distillation is trained by minimizing the sum of Eq. (3) and Eq. (4) over all training samples iteratively.
The closest work to our Gl is multi-modal graph distillation (MMGD) [Luo et al., 2017] which distills knowledge from multi-model data, and there are mainly two differences between them. (1) We formalize logits distillation frommultiple teachers as a multi-distribution joint matching problem. Instead of cosine distance, we apply EM distance to measure the logits distribution discrepancy between teacher and student. Mathematically, teacher models are devoted to mapping visual characteristics of various video samples in logits distribution supported by low dimensional manifolds, where EM distance is proved to be more useful [Arjovsky et al., 2017]. Besides, EM distance can describe intra-class and inter-class variability more adequately than cosine distance, resulting in more refined knowledge distillation to capture subtle complementarity of teachers. (2) Moreover, we propose a novel feature distillation graph Gr to assist this distribution matching process (section 4.3) and experimental results indicate that our Gl can benefit much more from Gr than MMGD method.
4.3 Representation Graph Distillation
Besides logits distribution, we hypothesize that intermediate feature of different teacher models can also be leveraged via graph-based distillation. The core difficulty stems from the heterogeneous nature of these task-specific features. To tackle this challenge, we propose to pairwise ensemble the original features via compact bilinear pooling [Gao et al., 2016] and adopt the bilinear features as vertices of representation distillation graph Gr, which is the second component in Fig 1. There exist three insights behind this idea: (1) It is reasonable that the internal features of ConvNets reflect certain activation and attention patterns of neurons, and bilinear pooling allows all elements of heterogeneous feature vectors to interact with each other in a multiplicative fashion, which captures the salient information with more complementarity. (2) In the view of feature domain adaptation, bilinear pooling maps original features to a smoother representation space, where their distributions are more homologous and discrepancy among them are easier to measure. (3) Furthermore, since the high level prediction distribution of models is based on their internal representation, aligning at feature level also performs as a powerful adaptation method which assists distillation learning in Gl.
Assume R ∈ R|C×S| denotes the feature vector with C channels and spatial size S, where S = H ×W. Each vertex Vk of Gr is yield by invoking compact bilinear pooling on feature pairs (Rm,Rn):
where Ψ : R|C×S| → Re represents Count Sketch projection function [Charikar et al., 2002] and e ≪ |C × S| as Ψ projects the outer product to a lower dimensional space. ⊗ and ⊙ are outer product and element-wise product, respectively. h ∈ {1, · · ·, e}|C×S| and s ∈ {-1, 1}|C×S| are two randomly initialized vectors for invocation of Ψ. ∗ means convolution and Eq. (7) utilizes the theorem that elementwise product in the frequency domain equals to convolution in time domain, which can yield a more compact feature vector. Then the bilinear feature Ψ is passed through a signed squareroot (z = sign(Ψ)√|Ψ|) and ℓ2 normalization (Vk = z/ ‖ z ‖2), where ∀k ∈ {1, C 2 |Π| } and combinatorics C 2 |Π| is the vertex number of Gr. For instance, there will be 6 vertices in Gr after pairwise ensemble of 4 teacher features for each video sample.
Similar to Gl, Gr is defined as a adjacency matrix but the edge of Gr is a vector E ∈ R1×b rather than a scalar, where b is the dimension of vertex V . We distill the bilinear feature with temperature Tk as softened representation distribution:
and use Maximum Mean Discrepancy (MMD) to meause the distillation loss:
where Rs denotes the feature map in a certain layer of student model and R(p) s is the feature vector at channel p. Dk is the softened distribution of k-th vertex in Gr, Cs and Ck are channel numbers of student model and Dk, respectively.
K is kernel function which maps features to higher dimensional Reproducing Kernel Hilbert Space (RKHS), and we use Gaussian Kernel: K(a, b) = exp(- ‖a-b‖22 2σ2 ) in practice. Note that, softmax operation in Eq. (9) ensures each sample has the same scale and it is unnecessary for Dk as Eq. (8) have already performed it.
Let Mℓr is the matrix whose element is ℓr and T ∈ R1×C2 |Π| is the temperature vector, the total loss of Gr is calculated by
The reasons why MMD is used in Gr lie in two aspects: (1) Feature distillation matches activation distribution of teachers, where MMD can be used to measure the distribution discrepancy between teachers and student. In contrast, matching instance-level features directly (without MMD) is hard to make sense as it ignores the statistical dependence of different instances. (2) Internal activations describe different salient patterns of video and MMD loss acts as a regularizer to encourage knowledge transfer in feature selectivity.
5 Experiments
In this work we use conventional transfer learning paradigm for evaluating the utility of student model on video classification. We first train the teacher models for privileged information learning on auxiliary tasks, then transfer the knowledge from teachers to student via the proposed graph distillation framework. Experimental details are described in the sequel.
5.1 Architectures
We first re-implement three self-supervised methods in the literature based on VGG-19 [Simonyan and Zisserman, 2015], for training teacher model from πS , πM and πT , respectively. Then we introduce PredNet [Lotter et al., 2017] as a selfsupervised model for learning from πP. For notation convenience, we use TS, TM, TT , and TP to denote the models for these tasks. All models are customized with a slight modification for meeting the demand in our experiments. In particular, we respectively extend channels to 96 and 128 for conv1 and conv2 in VGG-19, and change the filter size of conv1 to 11×11 as better performance have shown in practice. For πS, πM and πT , siamese-style architectures are conducted for pairwise feature extraction and base visual encoders share parameters. More specifically, TS concatenates convolutional feature over pairs of all frames to be sorted in first fc layer, followed by a classical fc classifier. TM is composed with a base-CNN (BCNN) and a top-CNN (TCNN), in which TCNN takes the output pair of BCNN for transform analysis between two frames. TT is a siamese-triplet network in order to judge the similarity of patches in a triple. TP is a ConvLSTMmodel where each layer consists of representation module (R), target module (A), prediction module ( ˆ A) and error term (E). We conduct a 4-layers version of it and use the output of R in top layer as representation. For the sake of model compression and acceleration, we choose AlexNet [Krizhevsky et al., 2012] as student model S for video classification task.
5.2 Implementation Details
All models are implemented using PyTorch 1 . For the selfsupervised model training, we basically follow the settings in original papers and we encourage the reader to check them for more details. For the graph distillation training, we train the model for 350 epochs using Adam optimizer with momentum 0.9. The batch size is set to 128 and we initialize the learning rate to 0.01 and decay it every 50 epochs by a factor of 0.5. Trade-off hyperparameter λ is set to 0.6.
Another vital issue in practice is how to choose the layer of different networks for feature distillation in Gr. In other words, we expect to quantify the transferability of features from each layer of teacher models. Inspired by [Yosinski et al., 2014], we measure 1) the specialization of layer neurons to original self-supervised tasks at the expense of performance on the classification task and 2) the optimization difficulties related to splitting teacher networks between coadapted neurons, and we finally choose conv4 of both teachers (VGG-19 and PredNet) and student (AlexNet) as the distillation layer, whose feature maps have 256 output channels.
5.3 Datasets
Datasets in our experiments contain two branches, i.e., auxiliary datasets for self-supervised learning and target datasets for video classification. For the former, we use the same datasets as original works. For the latter, we evaluate our framework on three popular datasets, namely UCF101 [Soomro et al., 2012], HMDB51 [Kuehne et al., 2013] and CCV [Jiang et al., 2011], which contain 13k, 6.7k and 9.3k videos with 101, 51 and 20 categories, respectively.
5.4 Results
Table 1 compares our framework to several state-of-theart unsupervised methods for video classification. Obviously, our approach outperforms the previous methods by a large margin, and more importantly, it beats its ImageNetsupervised counterpart (AlexNetpre) for the first time.
The results indicate that (1) knowledge learned from different self-supervised tasks is complementary and it can be transferred via graph distillation to form a more comprehensive video semantics. Distillation encourages each teacher to agree with the predictions and patterns other teachers would have learned, which improves the robustness of the student model on video classification. (2) Knowledge from models which trained on ImageNet in a supervised fashion is insufficient for capturing all the details of video, leading to suboptimal performance on classification task.
| Methods | UCF101 | HMDB51 | CCV |
|---|---|---|---|
| AlexNetran | 47.8 | 16.3 | 39.2 |
| AlexNetpre | 66.9 | 28.0 | 60.8 |
| Wang et al. [2015] | 40.7 | 15.6 | 34.3 |
| Misra et al. [2016] | 50.9 | 19.8 | 44.7 |
| Senthil et al. [2016] | 55.4 | 23.6 | 46.4 |
| Lee et al. [2017] | 56.3 | 22.1 | 48.8 |
| Basura et al. [2017] | 60.3 | 32.5 | 58.1 |
| Ours (Gl+Gr) | 68.9 | 35.1 | 62.6 |
1 http://pytorch.org/
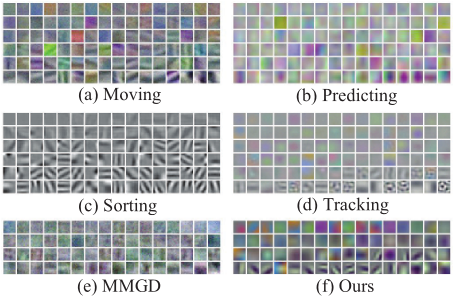
Representation learned by Student
Qualitatively, we demonstrate the quality of the features learned by student model through visualizing its low-level first layer filters (conv1). As exhibited in Figure 3, there are both color detectors and edge detectors in the conv1 filters of our distilled model. Its filters are sharper and of more varieties than its counterpart learned fromMMGD, and tend to be fully utilized when compared to those of the teachers.
5.5 Ablation Studies
We conduct comparison with several baseline methods to evaluate the effectiveness of each component in our proposal. After fine-tuning the self-supervised teacher models for video classification individually, we fuse their confidence scores (model fusion). We also feed the spliced feature of them to a linear classifier (model ensemble). For the conventional knowledge distillation (KD) baseline, we average the confidence scores of teacher models that equipped with KD. Gl and Gr are respectively compared with MMGD and single feature distillation (uniform version of feature distillation). Moreover, in order to verify the mutual promotion between Gl and Gr, we further compare the performance of two combination, i.e., MMGD+Gr and Gl+Gr (ours).
| Methods | UCF101 | HMDB51 | CCV |
|---|---|---|---|
| Models fusion | 57.9 | 19.4 | 45.2 |
| Models ensemble | 58.3 | 23.5 | 47.1 |
| KD (uniform) | 60.1 | 24.3 | 48.1 |
| Logits graph (MMGD) | 62.5 | 27.2 | 49.7 |
| Logits graph (Gl) | 65.3 | 30.9 | 52.6 |
| Feature distill (uniform) | 61.7 | 28.4 | 56.3 |
| Feature graph distill (Gr) | 66.4 | 33.4 | 58.0 |
| MMGD+Gr | 67.0 | 34.2 | 58.9 |
| Gl+Gr | 68.9 | 35.1 | 62.6 |
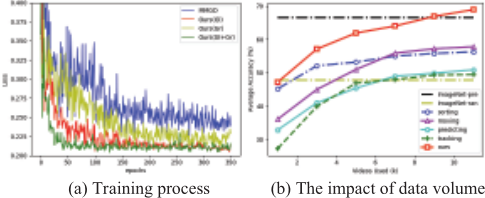
As shown in Table 2, graph-based distillation methods outperform the ordinary solutions that in the first three lines. The comparison between row 4 and row 5 suggests that our formalization of logits graph distillation is more effective than MMGD. The comparison between row 6 and row 7 reveals Gr helps model to learn the complementarity of different selfsupervised tasks. Results in the last two lines verify that Gl benefits much more from Gr than MMGD since Gr performs as a powerful adaptation method to assist the probability distribution matching. Moreover, the training process of distillation shown in Figure 4 (a) suggests that Gr can boost Gl not only in accuracy but also in training efficiency, which further verify the effectiveness of the two components.
5.6 Comparison with SupervisedMethods
Although our approach has not yet yielded video representations as powerful as those learned by supervised methods, it shows advance of integrating complementary video semantics from different self-supervised models. One of the most significant advantages of our approach is that it can utilize massive video data on the web economically, and as displayed in Figure 4 (b), the performance of distilled model increases steadily as the training data for self-supervised tasks grows. We believe learning video representation in such divide and conquer manner is potential as it integrates complementary semantic from various models at expert level. Moreover, attributed to the knowledge distillation, our framework dramatically reduces the number of model parameters and inference time, since top performing models for video classification has a much higher computational and memory cost than student.
6 Conclusion
In this paper, we have proposed a graph-based distillation framework for representation learning in video classification. Our framework distills both logits knowledge and internal feature knowledge from teacher models, which utilizes the complementarity of different video semantics from multiple self-supervised tasks. We view logits distillation as a multidistribution joint matching problem, and pairwise ensemble features via compact bilinear pooling for feature distillation.
Experiments on 3 video datasets verify that our approach can learn better video representation with less capacity.
Acknowledgments
This work was supported by National Natural Science Foundation of China under Grant 61771025 and Grant 61532005.
@inproceedings{ijcai2018p158,
  title     = {Better and Faster: Knowledge Transfer from Multiple Self-supervised Learning Tasks via Graph Distillation for Video Classification},
  author    = {Zhang, Chenrui and Peng, Yuxin},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {1135--1141},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/158},
  url       = {https://doi.org/10.24963/ijcai.2018/158},
}
TY - CPAPER TI - Better and Faster: Knowledge Transfer from Multiple Self-supervised Learning Tasks via Graph Distillation for Video Classification AU - Zhang, Chenrui AU - Peng, Yuxin T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 1135 EP - 1141 DO - 10.24963/ijcai.2018/158 UR - https://doi.org/10.24963/ijcai.2018/158 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





