
Exploiting Images for Video Recognition with Hierarchical Generative Adversarial Networks
Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence. Main track. Pages 1107-1113.
https://doi.org/10.24963/ijcai.2018/154
Keywords
- Computer Vision: Action Recognition
- Machine Learning: Transfer, Adaptation, Multi-task Learning
- Machine Learning: Unsupervised Learning
Abstract
Existing deep learning methods of video recognition usually require a large number of labeled videos for training. But for a new task, videos are often unlabeled and it is also time-consuming and labor-intensive to annotate them. Instead of human annotation, we try to make use of existing fully labeled images to help recognize those videos. However, due to the problem of domain shifts and heterogeneous feature representations, the performance of classifiers trained on images may be dramatically degraded for video recognition tasks. In this paper, we propose a novel method, called Hierarchical Generative Adversarial Networks (HiGAN), to enhance recognition in videos (i.e., target domain) by transferring knowledge from images (i.e., source domain). The HiGAN model consists of a \emph{low-level} conditional GAN and a \emph{high-level} conditional GAN. By taking advantage of these two-level adversarial learning, our method is capable of learning a domain-invariant feature representation of source images and target videos. Comprehensive experiments on two challenging video recognition datasets (i.e. UCF101 and HMDB51) demonstrate the effectiveness of the proposed method when compared with the existing state-of-the-art domain adaptation methods.
- Akaho, 2006
- S Akaho. A kernel method for canonical cor- relation analysis. arXiv preprint cs/0609071, 2006.
- [Bousmalis et al., 2017] K Bousmalis, N Silberman, D Do- han, D Erhan, and D Krishnan. Unsupervised pixel-level domain adaptation with generative adversarial networks. In CVPR, 2017.
- [Busto and Gall, 2017] PP Busto and J Gall. Open set do- main adaptation. In ICCV, 2017.
- [Carlucci et al., 2017] FM Carlucci, L Porzi, B Caputo, E Ricci, and SR Bulo. Autodial: Automatic domain align- ment layers. In ICCV, 2017.
- [Chen et al., 2016] WY Chen, TM Hsu, YH Tsai, YC Wang, and MS Chen. Transfer neural trees for heterogeneous do- main adaptation. In ECCV, pages 399-414, 2016.
- [Duan et al., 2012a] L Duan, D Xu, and SF Chang. Exploit- ing web images for event recognition in consumer videos: A multiple source domain adaptation approach. In CVPR, pages 1338-1345, 2012.
- [Duan et al., 2012b] L Duan, D Xu, and I Tsang. Learning with augmented features for heterogeneous domain adap- tation. arXiv preprint arXiv:1206.4660, 2012.
- [Gan et al., 2016] C Gan, C Sun, L Duan, and B Gong. Webly-supervised video recognition by mutually voting for relevant web images and web video frames. In ECCV, pages 849-866, 2016.
- [Goodfellow et al., 2014] I Goodfellow, J Pouget-Abadie, M Mirza, B Xu, D Warde-Farley, S Ozair, A Courville, and Y Bengio. Generative adversarial nets. In NIPS, pages 2672-2680, 2014.
- [He et al., 2016] K He, X Zhang, S Ren, and J Sun. Deep residual learning for image recognition. In CVPR, pages 770-778, 2016.
- [Jia et al., 2014] Y Jia, E Shelhamer, J Donahue, S Karayev, J Long, R Girshick, S Guadarrama, and T Darrell. Caffe: Convolutional architecture for fast feature embedding. In ACM MM, pages 675-678, 2014.
- [Kingma and Ba, 2014] D Kingma and J Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Long et al., 2014] M Long, J Wang, G Ding, J Sun, and PS Yu. Transfer joint matching for unsupervised domain adaptation. In CVPR, pages 1410-1417, 2014.
- [Long et al., 2015a] M Long, Y Cao, J Wang, and M Jor- dan. Learning transferable features with deep adaptation networks. In ICML, pages 97-105, 2015.
- [Long et al., 2015b] M Long, J Wang, J Sun, and S Yu Philip. Domain invariant transfer kernel learning. TKDE, 27(6):1519-1532, 2015.
- [Long et al., 2016] M Long, H Zhu, J Wang, and MI Jor- dan. Unsupervised domain adaptation with residual trans- fer networks. In NIPS, pages 136-144, 2016.
- [Long et al., 2017] M Long, H Zhu, J Wang, and MI. Jordan. Deep transfer learning with joint adaptation networks. In ICML, pages 2208-2217, 2017.
- [Mao et al., 2016] X Mao, Q Li, H Xie, R YK Lau, and Z Wang. Multi-class generative adversarial networks with the l2 loss function. arXiv preprint arXiv:1611.04076, 2016.
- [Sankaranarayanan et al., 2017] S Sankaranarayanan, Y Balaji, CD Castillo, and R Chellappa. Generate to adapt: Aligning domains using generative adversarial networks. arXiv preprint arXiv:1704.01705, 2017.
- [Shi et al., 2010] X Shi, Q Liu, W Fan, SY Philip, and R Zhu. Transfer learning on heterogenous feature spaces via spectral transformation. In ICDM, pages 1049-1054. IEEE, 2010.
- [Soomro et al., 2012] K Soomro, A Roshan Zamir, and M Shah. Ucf101: A dataset of 101 human actions classes from videos in the wild. arXiv preprint arXiv:1212.0402, 2012.
- [Sun and Saenko, 2016] B Sun and K Saenko. Deep coral: Correlation alignment for deep domain adaptation. In ECCV 2016 Workshops, 2016.
- [Sun et al., 2016] B Sun, J Feng, and K Saenko. Return of frustratingly easy domain adaptation. In AAAI, volume 6, page 8, 2016.
- [Tanisik et al., 2016] G Tanisik, C Zalluhoglu, and N Ikizler- Cinbis. Facial descriptors for human interaction recogni- tion in still images. PR, 73:44-51, 2016.
- [Tran et al., 2015] D Tran, L Bourdev, R Fergus, L Torre- sani, and M Paluri. Learning spatiotemporal features with 3d convolutional networks. In ICCV, pages 4489-4497, 2015.
- [Tsai et al., 2016] YH Tsai, YR Yeh, and YC Wang. Learn- ing cross-domain landmarks for heterogeneous domain adaptation. In CVPR, pages 5081-5090, 2016.
- [Wang and Mahadevan, 2011] C Wang and S Mahadevan. Heterogeneous domain adaptation using manifold align- ment. In IJCAI, volume 22, page 1541, 2011. IJCAI
- [Xu et al., 2013] X Xu, IW Tsang, and D Xu. Soft margin multiple kernel learning. TNNLS, 24(5):749-761, 2013.
- [Xu et al., 2016] Y Xu, X Fang, J Wu, X Li, and D Zhang. Discriminative transfer subspace learning via low-rank and sparse representation. TIP, 25(2):850-863, 2016.
- [Yao et al., 2011] B Yao, X Jiang, A Khosla, AL Lin, L Guibas, and Li FF. Human action recognition by learn- ing bases of action attributes and parts. In ICCV, pages 1331-1338, 2011.
- [Zhang et al., 2017] J Zhang, Y Han, J Tang, Q Hu, and J Jiang. Semi-supervised image-to-video adaptation for video action recognition. TCYB, 47(4):960-973, 2017.
- [Zhu et al., 2017] JY Zhu, T Park, P Isola, and AA. Efros. Unpaired image-to-image translation using cycle- consistent adversarial networks. In ICCV, 2017.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Video recognition is an active research area because of its wide applications such as anomalous events detection, action retrieval, human behavior analysis and so forth. Thanks to the success of deep neural networks, the performance of video recognition has been dramatically improved. However, training deep video classifiers requires collecting and labeling a large number of videos, which is often time-consuming and labor-intensive. On the other hand, images are much easier and cheaper to collect and annotate, and there are also many existing labeled image datasets which can be utilized. Furthermore, the computational cost of learning deep classifiers of images is much less than that of videos, so it would be beneficial a lot to transfer knowledge from source images to target videos [Duan et al., 2012a; Zhang et al., 2017; Gan et al., 2016].
∗Corresponding author: Xinxiao Wu
However, applying the images trained classifier to video data directly introduces the domain shift problem, where the variations in data between source and target significantly degrade the recognition performance at test time. To solve this problem, many domain adaptation methods have been well explored. A rich line of prior work has focused on learning shallow features by obtaining a symmetric transformation and minimizing a distance metric of domain discrepancy [Akaho, 2006; Wang and Mahadevan, 2011; Duan et al., 2012a; Shi et al., 2010; Duan et al., 2012b; Tsai et al., 2016; Zhang et al., 2017]. Recently, studies have shown that deep neural networks can learn more transferable features for domain adaptation [Chen et al., 2016; Long et al., 2015a; 2016; 2017]. In order to represent videos more appropriately, spatiotemporal features that are totally different from image representations with different feature dimensions and physical meanings are usually extracted, which makes the problem worse.
To tackle these issues aforementioned, inspired by recent advances in generative adversarial networks (GANs) [Goodfellow et al., 2014], we propose a new approach referred to as Hierarchical Generative Adversarial Networks (HiGAN) to transfer knowledge from images to videos by learning domain-invariant feature representations between them. As illustrated in Figure 1(a), our approach mainly consists of two components: a two-level hierarchical conditional GAN model and a domain adaptation model. The domain adaptation model is adopted to learn a common feature representation between source images and target video frames, called image-frame feature. The two-level HiGAN is designed to have a low-level conditional GAN and a high-level conditional GAN. The low-level conditional GAN is built to connect videos and their corresponding video frames by learning a mapping function from frame features to video features in the target domain. The high-level conditional GAN, on the other hand, is modeled to bridge the gap between source images and target videos by formulating a mapping function from video features to image-frame features. Therefore, any classifiers trained on the source image domain can be effectively transferred to the target video domain for recognition, with the help of the transformable features between them. In HiGAN, the Correlation Alignment (CORAL) Loss [Sun and Saenko, 2016] is utilized to minimize the difference in second-order statistics between the generated features and the real features.
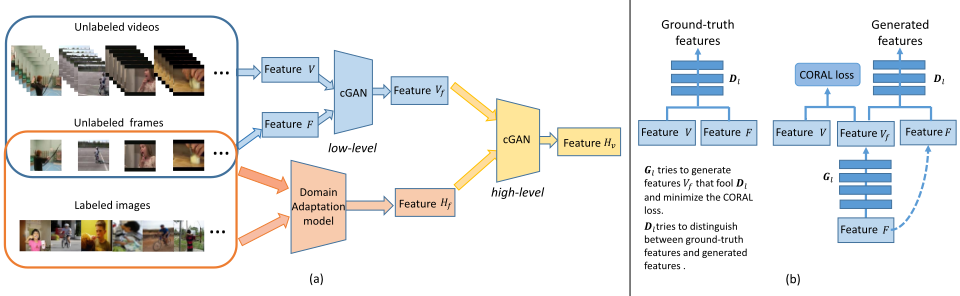
It is worth emphasizing that, by exploiting the correspondence between a video and its related frames, the projected video features, which keep the temporal motion of videos, can be learned with the absence of any paired image-video training examples in an unsupervised scenario. The experiments conducted on the UCF101 and HMDB51 datasets demonstrate that our method can achieve better results than the current state-of-the-art domain adaptation methods.
2 RelatedWork
To harness the information from large-scale image datasets, several works use images as auxiliary training data for video recognition [Duan et al., 2012a; Zhang et al., 2017; Gan et al., 2016]. In [Duan et al., 2012a], they proposed a new multiple domain adaptation method for event recognition by leveraging a large number of loosely labeled web images from different sources. In [Gan et al., 2016], they jointly exploited source images and source videos for labeling-free video recognition, and proposed a mutually voting approach to filter noisy source images and video frames. In [Zhang et al., 2017], they presented a classifier of image-to-video adaptation, which borrows the knowledge adapted from images, and utilizes the heterogeneous features of unlabeled videos to enhance the performance of action recognition. Different from these methods, our method takes the temporal information of videos into consideration without extracting keyframes from videos.
When transferring knowledge between different domains, the domain shift will cause the classifier learned from the source domain to perform poorly on the target domain. Numerous domain adaptation methods have been well explored where the key focus is to learn domain-invariant feature representations. A common strategy is to find a mapping function that would align the source distribution with the target domain [Long et al., 2014; 2015b; Sun et al., 2016; Xu et al., 2016; Busto and Gall, 2017; Akaho, 2006; Wang and Mahadevan, 2011; Shi et al., 2010; Duan et al., 2012b; Tsai et al., 2016]. Recently, deep neural networks have been exploited for domain adaptation [Long et al., 2015a; 2016; Chen et al., 2016; Long et al., 2017; Carlucci et al., 2017], In [Long et al., 2015a; 2016; 2017], Long et al. embedded domain-adaptation modules into deep networks in which all the layers corresponding to task-specific features are adapted in a layerwise manner. These methods focus on the imageto-image adaptation. In [Chen et al., 2016], the architecture of Transfer Neural Trees has been presented, which jointly solves the cross-domain feature adaptation and classification between heterogeneous domains in a semi-supervised scenario. In contrast, our method can transfer knowledge between images and videos in an unsupervised scenario.
Generative Adversarial Networks (GANs) [Goodfellow et al., 2014] are a class of artificial intelligence algorithms that are implemented by a system of two competing models: a generative model and a discriminative model. These two networks compete with each other in a two-player minimax game: the generator is learning to produce as realistic as possible samples at confusing the discriminator, and the discriminator is learning to get as correct as possible results at distinguishing generated samples from real data. GANs have achieved impressive progress in domain adaptation [Bousmalis et al., 2017; Sankaranarayanan et al., 2017]. In [Sankaranarayanan et al., 2017], they proposed an approach that brings the source and target distributions closer in a learned joint feature space. In [Bousmalis et al., 2017], they presented a new approach that learns a transformation in the pixel space from one domain to another. Different from these homogeneous domain adaptation methods based on single GAN, our hierarchical GAN method can effectively learn a common feature representation shared by heterogeneous domains.
3 Hierarchical Generative Adversarial Networks
3.1 Model
Given a source domain with a set of labeled images and a target domain with a set of unlabeled videos that share the same categories, our goal is to learn a common feature representation shared by source and target domains, on which the classifier built from the source domain adapts well to the target domain. Since a video is composed of a sequence of frames, we assume that a short video clip has a relationship with any frames in it, which provides a natural correlation between frame features and video features. On the other hand, video frames are a collection of images, which could be easily adapted to the source image domain. We explore the image-to-video adaptation by leveraging the relationship among source images, target video clips and their corresponding frames.
Image-Frame Feature. Let Ds = {xis , yis }ns i=1 represent a labeled dataset of ns images from the source domain and Dt = {xjt }nt j=1 denote an unlabeled dataset of nt videos from the target domain. We divide each video into several clips with the same length, building up an unlabeled video clip domain Dv = {xkv }nv k=1 , where nv is the number of video clips in total. For each clip, a frame is randomly selected and all the selected frames compose an unlabeled video frame domain Df = {xkf }nv k=1 . Since both of Ds and Df are image collections, we adopt a state-of-the-art deep domain adaptation model (i.e. JAN [Long et al., 2017]) to learn the common feature (called image-frame feature) of source images and target frames. In the common imageframe feature space, the source images and the target frames are represented by Hs = [h1s , h2s , · · · , hns s ] ∈ Rns×dh and Hf = [h1f , h2f , · · · , hnv f ] ∈ Rnv×dh , respectively, where dh is the feature dimension.
Frame-to-VideoMapping. For theDv, we extract the C3D feature [Tran et al., 2015] to describe the target video clips as V = [v1 , v2 , · · · , vnv ] ∈ Rnv×dv , where dv is the feature dimension. For the Df , we employ the ResNet [He et al., 2016] to extract deep features of target frames as F = [f 1 , f 2 , · · · , f nv ] ∈ Rnv×df , where df is the feature dimension. Generally speaking, frame features and video features are from two heterogeneous feature spaces, which means dv ̸= df . Considering the correspondence between a video frame and its related video clip, we get a collection of nv instances of video-frame pairs, denoted as P = {pk}nv k=1 with pk = (vk , f k ). We aim at learning a mapping function from video frames to their related video clips. Specifically, the frame features F are projected to video clip features V as V f = Gl(F ; θGl ), where Gl(·; θGl ) is the mapping function and V f = [v1 f , v2 f , · · · , vnv f ] ∈ Rnv×dv indicates the generated video feature from F .
Video-to-Image Mapping. For each frame xkf , it can be represented by two different features vk f ∈ V f and hkf ∈
Hf , thus we have a collection of nv two heterogeneous features pairs, expressed as Q = {qk}nv k=1 with qk = (hkf , vk f ). Given Q, a projection H′f = Gh(V f ; θGh ) from V f to Hf can be learned. Here, Gh(·; θGh ) is the mapping function and H′f is the generated image-frame feature from V f . Note that Hf and Hs share the same feature space learned by JAN model. In fact, V f and V also come from the same video feature space. Consequently, Gh(·; θGh ) can be actually considered as the projection from videos to images, and the video clip features V can be projected to the image-frame space as Hv = Gh(V ; θGh ), where Hv = [h1v , h2v , · · · , hkv ] ∈ Rnv×dh indicates the generated imageframe feature from V . Followed by averaging the clip features of each video, we obtain the final features for videos, denoted as Ht = [h1t , h2t , · · · , hnt t ] ∈ Rnt×dh , which can be directly compared against source image features Hs.
Motivated by the success of GANs in multiple fields, we propose a HiGAN model where the low-level GAN and the high-level GAN are designed to learn the mapping functions Gl and Gh, respectively. Our whole objective includes two terms. One is the adversarial loss [Goodfellow et al., 2014] for matching the distribution of generated features to the data distribution in the original domain. The other is the CORAL loss [Sun and Saenko, 2016] for minimizing the difference in second-order statistics between the synthesized features and the original features.
3.2 Loss
Adversarial Loss. For the mapping function Gl associated with the discriminator Dl, we denote the data distribution as V ∼ Pdata(V ) and F ∼ Pdata(F), then the objective is formulated as:
where Gl attempts to generate video features Gl(F) that resemble the video features from V , while Dl tries to distinguish between generated features Gl(F), and ground-truth features V . In other words, Gl aims at minimizing this objective against an adversary Dl that tries to maximize it, formulated by minGl maxDl LGAN(Dl,Gl,F, V ). We introduce a similar adversarial loss for Gh and Dh , given by minGh maxDh LGAN (Dh, Gh, V f , Hf ).
CORAL Loss. It has been proven that the GAN objective combined with another loss could produce significant good results [Zhu et al., 2017]. In our method, we introduce the CORAL loss [Sun and Saenko, 2016] to minimize the difference in second-order statistics between the generated features and the real features. The CORAL Loss is simple, effective and can be easily integrated into a deep learning architecture.
For the generator Gl associated with Dl, V is the real features and V f is the synthesized features. Suppose Ev and Evf denote the feature covariance matrices. The CORAL loss as the distance between the second-order statistics (covariance) of V and V f is expressed as follows:
where ‖ · ‖2F denotes the squared matrix Frobenius norm. The covariance matrices EV and EVf are calculated by
where 1 is a column vector with all elements equal to 1.
For the generator Gh associated with Dh, we introduce a similar CORAL loss as well:
3.3 Objective
In order to prevent the learned parameters from overfitting, we introduce the regularization term:
where W lD Dl , W lG Gl , W lD Dh and W lG Gh represent the layer-wise parameters of networks. LD and LG denote layer numbers of discriminator and generator, respectively. Based above, the whole objective becomes
where λ1, λ2, λ3 and λ4 are weight parameters that control the relative importance of adversarial loss and CORAL loss, respectively.
3.4 Algorithm
To learn the optimal feature representations, the generator G and the discriminator D compete with each other in a twoplayer minimax game, jointly minimizing the adversarial loss in Eq. (1) and the CORAL loss in Eq. (2). We aim to solve:
The algorithm of HiGAN is summarized in Algorithm 1.
Algorithm 1: Hierarchical Generative Adversarial Networks
Input: The source image domain Ds, the target video domain Dt, the video clip domain Dv, the video frame domain Df , the deep features V of Dv, the deep features F of Df
Output: The deep features Hs of Ds and Ht of Dt
- 1 Train the JANmodel with Ds and Df to learn features Hs and Hf of Ds and Df , respectively.
- 2 Learn the mapping function Gl(·; θGl ) with deep features F and V via Eq. (8), and calculate the new deep feature Vf of Df .
- 3 Learn the mapping function Gh(·; θGh ) with deep features V f and Hf by Eq. (9), and calculate the new deep feature Hv of Dv .
- 4 Average the clip features Hv of each video to obtain the features Ht of Dt.
- 5 ReturnHs andHt.
4 Experiments
4.1 Datasets
To evaluate the performance of our method, we conduct the experiments on two complex video datasets, i.e., UCF101 [Soomro et al., 2012] and HMDB51 [Yao et al., 2011]. For the UCF101 as the target video domain, the source images come from the Stanford40 dataset [Yao et al., 2011]. For the HMDB51 as the target video domain, the source image domain consists of Standford40 dataset and HII dataset [Tanisik et al., 2016], denoted by EADs dataset.
Stanford40 and UCF101 (S→U): The UCF101 is a dataset of action videos collected from YouTube with 101 action categories. The Stanford40 dataset include diverse action images with 40 action categories. We choose 12 common categories between these two datasets.
EADs and HMDB51 (E→H): The HMDB51 dataset has 51 classes, containing 6766 video sequences. The EADs dataset consists of Stanford40 and HII datasets. The HII dataset has 10 action images and each class contains at least 150 images, forming a total of 1972 images. The 13 shared categories between the EDAs and the HMDB51 datasets are adopted in our experiment.
4.2 Experiment Setup
We split each target video into 16-frame clips without overlap, and all the clips from all the target videos construct the video-clip domain. The deep feature of each video clip is the 512D feature vector from the pool5 layer of 3D CoveNets [Tran et al., 2015] which are trained on a large-scale video dataset. For each video clip, we randomly sample one frame and all the frames from all the video clips compose the videoframe domain. The deep feature of frames is the 2048D vector extracted from the pool5 layer of ResNet [He et al., 2016]. We utilize the JAN [Long et al., 2017] method based on the ResNet to get the domain-invariant image-frame features between source images and target video frames from the pool5 layer of JAN with the dimension of 2048D.
Implementation details. To model the two generators in HiGAN, we deploy four-layered feed-forward neural networks activated by relu function, (i.e., 2048 → 1024 → 1024 → 1024 → 512 for Gl(f; θGl ) and 512 → 1024 → 1024 → 2048 → 2048 for Gh(vf ; θGh )). In terms of two discriminators, we both utilize three fully connected layers ( 2560 → 1280 → 640 → 1) activated by relu function, except for the last layer.
In practice, we replace the negative log likelihood objective by a least square loss [Mao et al., 2016], which performs more stably during training and generates higher quality results.
Since the adversarial losses and the CORAL losses have different orders of magnitude according to the experiments, and the low-level conditional GAN and the high-level one have very similar network structures, we set λ2 = λ4 = 100, λ1 = λ3 = 1 in Eq. (8) and Eq. (9) for all the experiments, to somehow balance the two types of losses. We employ the Adam solver [Kingma and Ba, 2014] with a batch size of 64. All the networks were trained from scratch with the learning rate of 0.00002 for the low-level conditional GAN and 0.000008 for high-level conditional GAN.
Related methods. We evaluate the effectiveness of our approach by investigating whether our generated features of source images and target videos are more transferable than other domain adaptation methods, that is, whether the recognition accuracy on the target videos could be improved. Specifically, the compared methods are: 1) MKL [Xu et al., 2013]; TJM [Long et al., 2014]; TKL [Long et al., 2015b]; CORAL [Sun et al., 2016]; LRSR [Xu et al., 2016]; ATI [Busto and Gall, 2017]; KCCA [Akaho, 2006]; HEMAP [Shi et al., 2010]; DAMA [Wang and Mahadevan, 2011]; HFA [Duan et al., 2012b]; CDLS [Tsai et al., 2016], which are traditional shallow domain adaptation methods, and 2) ResNet [He et al., 2016]; DAN [Long et al., 2015a]; RTN [Long et al., 2016]; JAN [Long et al., 2017]; DAL [Carlucci et al., 2017], which are deep domain adaptation methods. The MKL is considered as a traditional baseline method which directly uses source classifiers in the target domain. Similarly, the ResNet is taken as a deep baseline method. As fair comparison with identical evaluation setting, the image-frame (i.e., JAN) features of source images are taken as source features in the traditional shallow domain adaptation methods. For all the methods, we use the accuracy for performance evaluation.
Note that MKL, TJM, TKL, CORAL, LRSR and ATI can only handle the homogeneous domain adaptation problem, when the data from the source and target domains are with the same type of feature. Therefore, for these methods, each target video is represented by the mean of the image-frame features of all the frames.
For the traditional heterogeneous domain adaptation methods of KCCA, HEMAP, DAMA, HFA and CDLS, the C3D feature is adopted to describe the target videos. Considering that all these methods require the labeled training data in the target domain, we randomly choose three videos per class as the labeled target data and take the rest videos as the test data. For each dataset, we repeat the sampling for 5 times and report the average results.
| Method | S→U | E→H |
|---|---|---|
| MKL [Xu et al., 2013] | 0.889 | 0.392 |
| TJM [Long et al., 2014] | 0.898 | 0.314 |
| TKL [Long et al., 2015b] | 0.902 | 0.391 |
| CORAL [Sun et al., 2016] | 0.904 | 0.398 |
| LRSR [Xu et al., 2016] | 0.893 | 0.380 |
| ATI [Busto and Gall, 2017] | 0.905 | 0.330 |
| HiGAN (no labeled video) | 0.954 | 0.446 |
| KCCA [Akaho, 2006] | 0.853 | 0.366 |
| HEMAP [Shi et al., 2010] | 0.432 | 0.213 |
| DAMA [Wang and Mahadevan, 2011] | 0.860 | 0.438 |
| HFA [Duan et al., 2012b] | 0.885 | 0.459 |
| CDLS [Tsai et al., 2016] | 0.885 | 0.435 |
| HiGAN (three labeled videos) | 0.967 | 0.526 |
| Method | S→U | E→H |
|---|---|---|
| ResNet [He et al., 2016] | 0.814 | 0.385 |
| DAN [Long et al., 2015a] | 0.842 | 0.395 |
| RTN [Long et al., 2016] | 0.838 | 0.402 |
| JAN [Long et al., 2017] | 0.914 | 0.409 |
| DAL [Carlucci et al., 2017] | 0.826 | 0.426 |
| HiGAN | 0.954 | 0.446 |
Regarding the deep methods of ResNet, DAN, RTN, JAN, DAL, since they only take images as input, the source images and target video frames are utilized to train the networks. The output scores (from the last fc layer) of all the frames are further averaged to determine the class label of the video. All the deep methods are implemented based on the Caffe framework [Jia et al., 2014] and fine-tuned from Caffe-provided models of ResNet, which are pre-trained on the ImageNet 2012 dataset. We fine-tune all convolutional and pooling layers and train the classifier layer via back propagation.
4.3 Results
Comparison with existing domain adaptation methods. Table 1 and Table 2 show the recognition accuracies of traditional shallow domain adaptation methods and deep domain adaptation methods, respectively. From them, we can notice that our method achieves the best performance compared with other state-of-the-art methods for both datasets, which explicitly demonstrates the effectiveness of transferring knowledge from images to videos for video recognition. The more detailed observations are as follows.
(1) When videos are represented by C3D features which are different from source image features, the traditional heterogeneous methods substantially perform worse than the traditional homogeneous methods on the S→U dataset, even though they have some labeled videos in the target domain. This shows that it is a quite challenging task to conduct domain adaptation between images and videos when they are respectively represented by different features. Compared with Method HiGAN Adversarial Table 3: Ablation study: classification performance of S→U and them, our proposed HiGAN can achieve better performance owing to the strengths of taking video frames as a bridge to obtain the common feature shared by heterogeneous images
(2) When there are no labeled data in the target domain,
0.5
0.6
1
both traditional methods and deep methods are better than
the baseline methods (i.e., MKL and ResNet) on the S→U
dataset, which indicates that these adaptation methods can
improve action recognition performance, but the improve-
ment is not significant. On the E→H dataset, traditional
methods slightly underperform the baseline MKL. A possible explanation is that the huge difference between source images and target video frames on the E→H dataset leads to the negative transfer. On the other hand, deep transfer learning methods are better than the baseline ResNet, which verifies that deep networks are better at addressing negative transfer issue. Compared with them, our proposed HiGAN gains performance improvement on both datasets, which demonstrates that our method can attain respectable performances even though there is a huge difference between source images and target videos.
Analysis of the loss function. In Table 3, we assess the individual effect of the advesarial loss and the CORAL loss in HiGAN, with respect to the recognition accuracies in two datasets. We develop two variants of our HiGAN: one with the adversarial loss but without the CORAL loss, the other with the CORAL loss but without the adversarial loss. The two variants are referred to as HiGAN Adversarial and HiGAN CORAL, respectively. Removing the adversarial loss substantially degrades results, as does removing the CORAL loss. We therefore conclude that both terms are critical to our results.
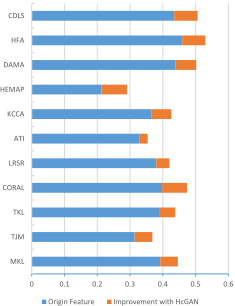
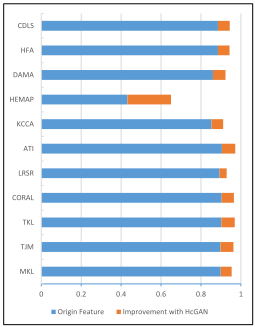
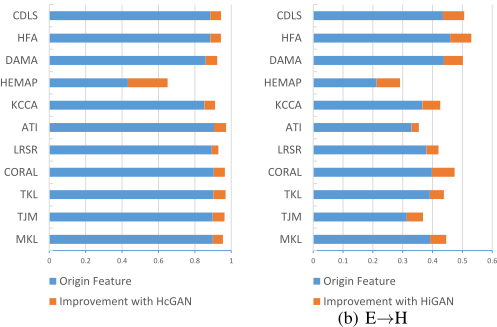
Effectiveness of the HiGAN features for traditional domain adaptation. To validate the performance improvement of the proposed HiGAN features for video recognition, we compare it with the original features (i.e., JAN and C3D) used in the traditional shallow domain adaptation methods. Additional experiments are conducted with different features. Figure 2 (a) and (b) demonstrate the accuracy improvements on the S→U and E→H datasets, respectively. We can observe that, the recognition result could be improved with our proposed HiGAN features for both datasets.
Effectiveness of exploring images by HiGAN for video recognition. We also explore whether it is beneficial to transfer knowledge from images for video recognition by comparing our HiGAN features and the C3D features on the
0.6
| Method | UCF101 | HMDB51 |
|---|---|---|
| C3D [Tran et al., 2015] | 0.940 | 0.657 |
| HiGAN | 0.980 | 0.740 |
Table 4: Comparison between our method and C3D on the video recognition.
UCF101 and the HMDB51 datasets with the chosen categories. The experiments are separately done on the three train/test splits, and the result is averaged across three test splits. From table 4, it is interesting to notice that with the same training samples, our method can significantly improve the video recognition accuracy on both datasets, which validates the benefits of exploring related images for video recognition.
5 Conclusion
We have proposed a new Hierarchical Generative Adversarial Networks approach to transfer knowledge from images to videos. By taking advantage of these two-level adversarial learning with the CORAL loss, our method is capable of learning a domain-invariant feature representation between source images and target videos. Thus the image classifiers trained on the domain-invariant features can be effectively adapted to videos. We conduct experiments on two datasets and the results validate the effectiveness of our method.
The future work includes exploiting large-scale Web images for video recognition which will further improve the recognition accuracy. We also plan to extend our method to multiple source domain adaptation.
Acknowledgments
This work was supported in part by the Natural Science Foundation of China (NSFC) under grant No. 61673062 and No.
61472038.
@inproceedings{ijcai2018p154,
  title     = {Exploiting Images for Video Recognition with Hierarchical Generative Adversarial Networks},
  author    = {Yu, Feiwu and Wu, Xinxiao and Sun, Yuchao and Duan, Lixin},
  booktitle = {Proceedings of the Twenty-Seventh International Joint Conference on
               Artificial Intelligence, {IJCAI-18}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Jérôme Lang},
  pages     = {1107--1113},
  year      = {2018},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2018/154},
  url       = {https://doi.org/10.24963/ijcai.2018/154},
}
TY - CPAPER TI - Exploiting Images for Video Recognition with Hierarchical Generative Adversarial Networks AU - Yu, Feiwu AU - Wu, Xinxiao AU - Sun, Yuchao AU - Duan, Lixin T2 - Proceedings of the Twenty-Seventh International Joint Conference on Artificial Intelligence, IJCAI-18 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2018 SP - 1107 EP - 1113 DO - 10.24963/ijcai.2018/154 UR - https://doi.org/10.24963/ijcai.2018/154 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





