
POPPONENT: Highly accurate, individually and socially efficient opponent preference model in bilateral multi issue negotiations (Extended Abstract)
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Journal track. Pages 5100-5104.
https://doi.org/10.24963/ijcai.2017/730
Keywords
- Knowledge Representation, Reasoning, and Logic: Preferences
- Agent-based and Multi-agent Systems: Agreement Technologies: Negotiation and Contract-Based Systems
- Knowledge Representation, Reasoning, and Logic: Preference modelling and preference-based reasoning
- Machine Learning: Learning Preferences or Rankings
Abstract
In automated bilateral multi issue negotiations, two intelligent automated agents negotiate on behalf of their owners over many issues in order to reach an agreement. Modeling the opponent can excessively boost the performance of the agents and increase the quality of the negotiation outcome. State of the art models accomplish this by considering some assumptions about the opponent which restricts their applicability in real scenarios. In this paper, a less restricted technique where perceptron units (POPPONENT) are applied in modelling the preferences of the opponent is proposed. This model adopts a Multi Bipartite version of the Standard Gradient Descent search algorithm (MBGD) to find the best hypothesis, which is the best preference profile. In order to evaluate the accuracy and performance of this proposed opponent model, it is compared with the state of the art models available in the Genius repository. This results in the devised setting which approves the higher accuracy of POPPONENT compared to the most accurate state of the art model. Evaluating the model in the real world negotiation scenarios in the Genius framework also confirms its high accuracy in relation to the state of the art models in estimating the utility of offers. The findings here indicate that the proposed model is individually and socially efficient. This proposed MBGD method could also be adopted in similar practical areas of Artificial Intelligence.
- [Baarslag et al., 2012] Tim Baarslag, Koen Hindriks, Catholijn Jonker, Sarit Kraus, and Raz Lin. The first auto- mated negotiating agents competition (anac 2010). In New Trends in agent-based complex automated negotiations, pages 113-135. Springer, 2012.
- [Baarslag et al., 2013] Tim Baarslag, Mark Hendrikx, Koen Hindriks, and Catholijn Jonker. Predicting the performance of opponent models in automated negotiation. In Web Intelligence (WI) and Intelligent Agent Technologies (IAT), 2013 IEEE/WIC/ACM International Joint Conferences on, volume 2, pages 59-66. IEEE, 2013.
- [Baarslag et al., 2014] Tim Baarslag, Koen Hindriks, Mark Hendrikx, Alexander Dirkzwager, and Catholijn Jonker. Decoupling negotiating agents to explore the space of nego- tiation strategies. In Novel Insights in Agent-based Complex Automated Negotiation, pages 61-83. Springer, 2014.
- [Baarslag et al., 2016] Tim Baarslag, Mark JC Hendrikx, Koen V Hindriks, and Catholijn M Jonker. Learning about the opponent in automated bilateral negotiation: a com- prehensive survey of opponent modeling techniques. Au- tonomous Agents and Multi-Agent Systems, 30(5):849-898, 2016.
- [Baarslag, 2016] Tim Baarslag. Measuring the performance of online opponent models. In Exploring the Strategy Space of Negotiating Agents, pages 111-127. Springer, 2016.
- [Fujita et al., 2013] Katsuhide Fujita, Takayuki Ito, Tim Baarslag, Koen Hindriks, Catholijn Jonker, Sarit Kraus, and Raz Lin. The second automated negotiating agents competition (anac2011). In Complex Automated Negotia- tions: Theories, Models, and Software Competitions, pages 183-197. Springer, 2013.
- [Hindriks and Tykhonov, 2008] Koen Hindriks and Dmytro Tykhonov. Opponent modelling in automated multi-issue negotiation using bayesian learning. In Proceedings of the 7th international joint conference on Autonomous agents and multiagent systems-Volume 1, pages 331-338. Interna- tional Foundation for Autonomous Agents and Multiagent Systems, 2008.
- [Ikrashi and Fujita, 2014] Masanori Ikrashi and Katsuhide Fujita. Compromising strategy using weighted counting in multi-times negotiations. In Advanced Applied Informat- ics (IIAIAAI), 2014 IIAI 3rd International Conference on, pages 453-458. IEEE, 2014.
- [Lin et al., 2014] Raz Lin, Sarit Kraus, Tim Baarslag, Dmytro Tykhonov, Koen Hindriks, and Catholijn M Jonker. Genius: An integrated environment for supporting the design of generic automated negotiators. Computational Intelligence, 30(1):48-70, 2014.
- [Nassiri-Mofakham et al., 2008] Faria Nassiri-Mofakham, Nasser Ghasem-Aghaee, Mohammad Ali Nematbakhsh, and Ahmad Baraani-Dastjerdi. A personality-based simulation of bargaining in e-commerce. Simulation & gaming, 39(1):83-100, 2008.
- [Nassiri-Mofakham et al., 2009] Faria Nassiri-Mofakham, Mohammad Ali Nematbakhsh, Nasser Ghasem-Aghaee, and Ahmad Baraani-Dastjerdi. A heuristic personality- based bilateral multi-issue bargaining model in electronic commerce. International Journal of Human-Computer Studies, 67(1):1-35, 2009.
- [Rubinstein, 1982] Ariel Rubinstein. Perfect equilibrium in a bargaining model. Econometrica: Journal of the Econo- metric Society, pages 97-109, 1982.
- [Sycara and Zeng, 1997] Katia Sycara and Daniel D Zeng. Benefits of learning in negotiation. In Proceedings of the AAAI National Conference on Artificial Intelligence. Menlo Park, California, pages 36-41, 1997.
- [van Krimpen et al., 2013] Thijs van Krimpen, Daphne Looije, and Siamak Hajizadeh. Hardheaded. In Complex Automated Negotiations: Theories, Models, and Software Competitions, pages 223-227. Springer, 2013.
- [Witten et al., 2016] Ian H Witten, Eibe Frank, Mark A Hall, and Christopher J Pal. Data Mining: Practical machine learning tools and techniques. Morgan Kaufmann, 2016.
- [Yaakov and Ilany, 2015] Gal Yaakov and Litan Ilany. The fourth automated negotiation competition. Next frontier in agent-based complex automated negotiation. Studies in computational intelligence, 596:129-136, 2015.
- [Zafari and Moser, 2016] Farhad Zafari and Irene Moser. Feature-aware factorised collaborative filtering. In Pro- ceedings of the Australasian Joint Conference on Artificial Intelligence, pages 561-569. Springer, 2016.
- [Zafari and Moser, 2017a] Farhad Zafari and Irene Moser. Modelling socially-influenced conditional preferences over feature values in recommender systems based on factorised collaborative filtering. Expert Systems with Applications, Accepted, 2017.
- [Zafari and Moser, 2017b] Farhad Zafari and Irene Moser. Proposing a highly accurate hybrid component-based fac- torised preference model in recommender systems. In Pro- ceedings of the 26th International Joint Conference on Artificial Intelligence (IJCAI), 2017. IJCAI
- [Zafari and Nassiri-Mofakham, 2016a] Farhad Zafari and Faria Nassiri-Mofakham. Bravecat: iterative deepening distance-based opponent modeling and hybrid bidding in nonlinear ultra large bilateral multi issue negotiation do- mains. In Recent Advances in Agent-based Complex Auto- mated Negotiation, pages 285-293. Springer, 2016.
- [Zafari and Nassiri-Mofakham, 2016b] Farhad Zafari and Faria Nassiri-Mofakham. Popponent: Highly accurate, in- dividually and socially efficient opponent preference model in bilateral multi issue negotiations. Artificial Intelligence, 237:59-91, 2016.
- [Zafari et al., 2015] Farhad Zafari, Faria Nassiri-Mofakham, and Ali Zeinal Hamadani. Dopponent: A socially efficient preference model of opponent in bilateral multi issue nego- tiations. Journal of Computing and Security, 1(4):283-292, 2015.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Negotiation is the science and art of resolving any kind of disputes and reaching consensus among human parties. In an automated bilateral multi-issue version of negotiations, intelligent computer agents engage in a cooperative process on behalf of their beneficiaries with different and sometimes contradicting interests, with the objective of achieving an agreement on one or more issues. Recently, with the emergence of ANAC (an annual international Automated Negotiating Agents Competition) [Baarslag et al., 2012; Fujita et al., 2013], many new negotiation strategies have been developed. Most of the existing sophisticated negotiation strategies typically consist of a set of fixed modules. In general, three main components are distinguished in a negotiating agent which work together within a BOA framework to accomplish the whole negotiation task [Baarslag et al., 2014]: Bidding Strategy (BS), which decides which offer will be sent to the opponent as the next proposal, Opponent Model (OM), which constructs a model of the preference profile of the opponent through a learning technique, and Acceptance Strategy (AC), which receives the incoming offer from the opponent and the outgoing offer chosen by the bidding strategy component, and determines whether the incoming offer is acceptable for the agent or not.
∗This paper is an extended abstract of an article in the Artificial Intelligence journal [Zafari and Nassiri-Mofakham, 2016b].
Despite the variety in opponent modelling techniques, most of the current models rely on a small and common set of learning techniques [Baarslag et al., 2016]. Moreover, since in a single negotiation session all bids (i.e., training examples) are not available at the same time, traditional learning techniques are not easily applied. An opponent model that is able to learn incrementally and update itself once the new training examples (i.e., offers) arrive during a negotiation session is of necessity. Another problem in the negotiation setting is that the training instances lack the output variable (i.e., the variable which contains the utility values of the received bids in the opponent's view). Therefore, specific opponent models are required that are capable of modeling the preferences of the opponent with no need for the value of the output variable. In order to overcome this limitation, all the existing opponent models use a subset of assumptions to extract the preferences of the opponent [Zafari and NassiriMofakham, 2016b]. Another difficulty with modeling an opponent's preferences in bilateral negotiations is related to the time factor. The post event analysis of ANAC tournaments also confirms that the computational complexity of the opponent models and the poor accuracy are the two main factors that degrade the performance of the agents applying these models [Baarslag, 2016]. In particular, the time factor is of paramount importance in online opponent models. In these models, the participating agents usually exchange a limited number of offers before the negotiation deadline is met, therefore, they do not contain enough information to accurately train an opponent model [Hindriks and Tykhonov, 2008;
Sycara and Zeng, 1997]. Consequently, the ability of the model to extract the most information possible from the training bids it receives is highly essential. Therefore, a proper opponent model should function based on the least assumptions, be efficient, extract the most information fromminimum number of bids, and embrace incremental training capability. To learn the issue weight values and individual utility function captured by opponent models, a two layered architecture would be essential. To overcome the aforementioned difficulties, in this paper, a new opponent preference model based on perceptron units is proposed in bilateral multi issue negotiation domains. Moreover, to be more applicable in real world negotiations, fewer and more realistic assumptions than those of the state of the art models are applied in this study. This is obtained by proposing an opponent model named POPPONENT, based on an adapted version of the standard gradient decent search [Zafari and Moser, 2016; Zafari and Moser, 2017b; Zafari and Moser, 2017a] (named the Multi Bipartite Gradient Decent Search). The model shows great success in the practical AI area of modelling the opponent preferences in bilateral multi issue negotiations with incomplete information, and the proposed Multi Bipartite Gradient Decent Search method used to train the model can be conveniently adopted in the similar AI problems.
2 Negotiation Setting
The negotiation setting here is in accordance with the setting employed by the state of the art models in the field of bilateral automated negotiations and the setting of the ANAC 2010-2013 [Baarslag et al., 2012; Fujita et al., 2013; Lin et al., 2014; Baarslag et al., 2013; Yaakov and Ilany, 2015; Zafari et al., 2015] 1 . Automated agents alternatively exchange offers and compete against each other to reach a joint agreement on a set of issues in bilateral negotiations. The issues and possible values for each issue constitute a domain. For each domain there could be two preference profiles (one for each side of the negotiation) which together with the domain construct a negotiation scenario. The interaction between negotiating parties is regulated by a negotiation protocol that defines the rules of how and when proposals can be exchanged. In this setting, the alternating offers protocol is applied [Rubinstein, 1982]. Negotiation is bilateral, that is, exactly two parties are negotiating over one or a set of issues. Each issue is associated with a set of possible values. The agents repeatedly exchange offers in successive rounds, so as to reach a mutually acceptable outcome. The negotiation deadline is reached after a specified number of N rounds are passed. This type of negotiation setting is commonly referred to as a round based setting. Each agent tries to take advantage of the other party for gaining a maximum utility for its own. A negotiation break-off causes both negotiating parties to obtain their reservation values. Therefore, the agents try to reach an agreement before the deadline. A negotiation session takes place in a negotiation scenario, which consists of a negotiation domain (or, alternatively, an outcome space) and two preference profiles (or, alternatively, utility space) one for each negotiating agent. The negotiation domain W specifies all possible offers -→w that the agents can send or receive. Each offer or possible outcome is a vector < w1, ...,wn >, where each component is the mapping of every issue i to a value wi ∈ {vi1, ,vimi }, where, mi is the number of possible values for issue i, i = 1, ...,n [Fujita et al., 2013]. A preference profile {< -→w ,U(-→w ) > |-→w ∈ W}, on the other hand, consists of a utility function U(-→w ) which maps each possible offer -→w ∈ W to a value in the [0,1] range based on the overall relative value of that offer for the agent. In multi-issue negotiations, the common assumption is that the utility of an offer can be computed as a weighted sum of the utilities associated with the values for each issue [Nassiri-Mofakham et al., 2008; Nassiri-Mofakham et al., 2009]. Accordingly, in the negotiation setting here, the agents use the linear additive utility function shown in Equation (1) , defined by a set of weights wi, and the corresponding evaluation functions or evaluation values evali(wi), i = 1, ...,n for the issue value wi of a given offer -→w .
1 In 2014, another setting has been added for negotiations under nonlinear utilities and in ultra large domains [Zafari and NassiriMofakham, 2016a]. ANAC 2015 and 2016 considered multi-party negotiations
Unlike the negotiation domain which is publicly known for both the negotiating parties, the preference profile is private for each agent, so the agents are not aware of the weights and evaluation values associated with the preference profile of one another. This negotiation setting is online, meaning that the agent is only allowed to use the offers exchanged during a single negotiation session to model the preferences of the opponent. Unlike offline opponent models, where negotiation information from different negotiation sessions is used, in online models [van Krimpen et al., 2013] no history of the previous negotiations is provided for the opponent model.
3 POPPONENT Algorithm
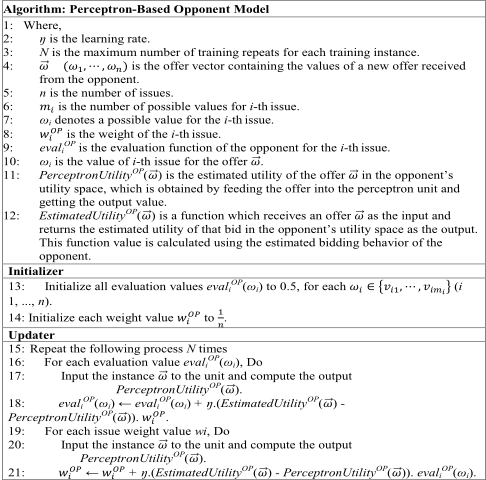
The preference profile of the opponent in linear scenarios is learnt using the multi bipartite incremental gradient descent search [Zafari and Nassiri-Mofakham, 2016b]. This algorithm learns the issue priorities or weight values w OP 1 through w OP n and the evaluation values eval OP i (wi) for all possible values wi ∈ vi1, ...,vimi (where, mi is the number of possible values for issue i) and all negotiation issues i (i = 1, ...,n) in that negotiation domain.
This proposed algorithm implements the multi bipartite incremental gradient descent search and applies two parameters of h and N as the input. Parameter h represents the learning rate which determines the step size in the gradient descent search. Parameter N represents the number of training repeats for each training instance. This algorithm includes two separate functions of initializer and updater. The first function is invoked just once when the model is generated and the essential parameters of the proposed model, most importantly the preference profile of the opponent (that is, the issue weights w OP i and evaluations eval OP i (wi) for issue values) is initialized. By trying different initial points, it is realized that 0.5, the midpoint in the hypothesis space, is the best point for initializing eval OP i (wi) values for each wi ∈ vi1, ...,vimi , i = 1, ...,n
(Algorithm: line 13). Similarly, for the weight values wi, equal weights 1 n are chosen for all issues (Algorithm: line 14). The second function receives an offer vector -→w which specifies the issue values for all the negotiation issues of a new offer recently received from the opponent. That is, as soon as a new offer is received from the opponent, this function is invoked to update the model based on this newly received bid. It updates the estimated preference profile of the opponent by adjusting eval OP i (wi) and wi values (Algorithm: Lines 18 and 21). Whenever a new offer is received from the opponent, the perceptron learning delta rules (Algorithm: lines 18 and 21) are repeated N times. The EstimatedUtility OP (w) is a function which receives an offer as the input and returns the estimated utility value of that offer in the opponent's utility space as the output. In this algorithm, instead of updating each eval OP i (wi) and w OP i value after calculating all Dwi and Deval OP i values when all training examples are met, each eval OP i (wi) and w OP i value is modified using training delta rules right after each single training instance is met in an incremental manner (Algorithm: Lines 18, 21). Therefore, this algorithm can easily be applied in more realistic negotiation scenarios in which training examples (opponent offers) are gradually met one at a time. The POPPONENT algorithm is as follows:
This proposed model is a supervised algorithm, thus it needs output labels for training instances. The problem of preference modelling in bilateral multi issue negotiations through supervised learning methods can be separated into two sub-problems: 1) estimating the utility values of the opponent's offer history (the history of the offers received from the opponent through the negotiation session) and 2) extracting the estimated utility function (or the preference profile) of the opponent from the opponent's offer history. By solving the first problem, now the opponent's offer history contains all the estimated offer utilities for each offer in the opponent's offer history. The EstimatedUtility OP (-→w ) function which deals with the first sub-problem, can be estimated according to the perceived bidding behavior of the opponent. In this article, four different values - three constant (0.6, 0.8, and 1) and one adaptive method (named P6, P8, P1, AP, respectively) are applied in order to estimate the utilities of the offers proposed by the opponent. For the fourth value, we use the adaptive method where the agent estimates the bids that the opponent will offer in future, based on the opponent's bid history [Ikrashi and Fujita, 2014; Witten et al., 2016]. The computational complexity of POPPONENT Algorithm is linear (O(n)).
4 Experiments
To evaluate the proposed model, two separate experimental settings are applied for assessing its accuracy and performance, in real world negotiation examples, compared to the available opponent models from Genius repository [Lin et al., 2014]. In the following sections, we present the experimental results obtained in these two experimental settings (for the details, please see [Zafari and Nassiri-Mofakham, 2016b]). The models used in these experiments are abbreviated in Table 1.
| Abbreviation | Opponent Model | Abbreviation | Opponent Model |
|---|---|---|---|
| P6 | Perceptron Based Model (Constant 0.6) | SF | Smith Frequency Model |
| P8 | Perceptron Based Model (Constant 0.8) | FF | The Fawkes Frequency Model |
| P1 | Perceptron Based Model (Constant 1) | IHB | IAMHaggler Bayesian Model |
| AP | Adaptive Perceptron Based Model | PIHB | Perfect IAMHaggler Bayesian Model |
| PP | Perfect Perceptron Based Model | NRB | The Negotiator Reloaded Bayesian Model |
| LGF | AgentLG Frequency Model | SB | Scalable Bayesian Model |
| XF | AgentX Frequency Model | PSB | Perfect Scalable Bayesian |
| CKF | CUHKAgent Frequency Model | OM | Opposite Model |
| HHF | HardHeaded Frequency Model | NM | No Model |
| IXF | InoxAgent Frequency Model | PM | Perfect Model |
| NF | Nash Frequency Model | WM | Worst Model |
4.1 Experiment I
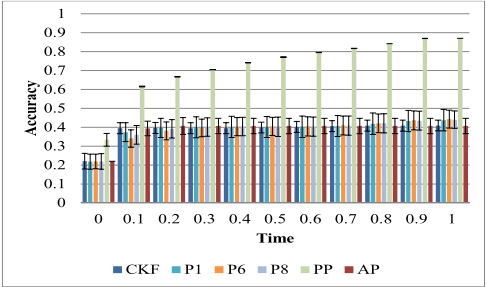
The first setting evaluates the accuracy of POPPONENT model through the Pearson Correlation measure. The experimental setting applied by [Baarslag et al., 2013] for automated bilateral multi issue negotiations is applied to evaluate the accuracy of POPPONENT model versus the state of the art opponent models. According to this setting, 5 variations of POPPONENT are compared with a total of 15 opponent models. In this experiment, the agents employing these opponent models negotiate against a category of opponent agents with different bidding strategies in a number of negotiation domains. The average accuracies of top performing opponent models against all opponent agents are depicted in Fig. 1, where at the perfect information state (PP), the proposed model outperforms the state of the art models by a large margin. As observed, the other three variations of POPPONENT (i.e., P6, P8, and P1 except PP) outperform the state of the art models with respect to the average accuracy over all opponents.
4.2 Experiment II
In the second Experiment, the proposed model is evaluated by measuring the real performance of the agents applying this model in 7 domains (Table 2) of real world experimental negotiation scenarios. A similar setting to the one applied by the ANAC organizers [Baarslag et al., 2013] is designed here. To accomplish this, a BOA framework is applied to embed each opponent model into an agent framework, the bidding strategy of which (together with its associated acceptance strategy) is chosen from the state of the art agents. In this setting, two sets of negotiation agents compete with each other in a tournament. The first set of agents are constructed using the top performing ANAC agents and some of the classic agents without an opponent component, and the second set is comprised of the same set of agents, except that they are equipped with one of the opponent models from Table 1. Then, the average performance of each opponent model is assessed by measuring the average performance of the agents that employed that opponent model. Six performance measures of Avg. utility, Avg. time of agreement, Avg. Pareto Distance of Agreement, Avg. Kalai Distance of Agreement, Avg. Nash Distance of Agreement and Avg. Percentage of Pareto Bids are applied for this purpose. The results of the Experiment II indicate that POPPONENT is the most accurate model compared with other models available. This is consistent with the results of the first experiment, where it is found that the accuracy of POPPONENT exceeds state of the art models. Moreover, we also found that POPPONENT (AP) and IXF models are the only two models which can outperform all other models in at least one domain with respect to all performance/accuracy measures. Both Experiments I and II reveal that POPPONENT is undoubtedly the most accurate model among all its counterparts. The experiments also revealed that POPPONENT achieves the highest performance in the Grocery domain for the average utility measure (through AP), the highest performance in the Travel and ItexVsCypress domains for the average time of agreements measure (through AP), the highest performance in the ItexVsCypress for the Nash and Kalai distance measures (through AP), the highest performance in the Grocery domain for the Pareto distance measure (through AP), the best performance in the Supermarket, Travel, Thompson, Energy, Camera, and ItexVsCypress, for the Pearson Correlation measures (through P1), and the best performing model in the Thompson domain for the percentage of Pareto bids measure (through P1). These results are tabulated in Tables 2 and 3.
| Domain | Utility | Pearson | Nash | Pareto | Kalai | Time | Pareto Bids % |
|---|---|---|---|---|---|---|---|
| Supermarket | IXF | P1 | IXF | XF | IXF | XF | XF |
| Travel | IXF | P1 | IXF | IXF | IXF | AP | XF |
| Thompson | IXF | P1 | CKF | IXF | CKF | CKF | P1 |
| Grocery | AP | IXF | CKF | AP | CKF | SF | LGF |
| Energy | HHF | P1 | IXF | HHF | IXF | IXF | XF |
| Camera | LGF | P1 | CKF | LGF | CKF | LGF | LGF |
| ItexVsCypress | IXF | P1 | AP | IXF | AP | AP | IXF |
| Average | IXF | P1 | IXF | IXF | IXF | LGF | XF |
| domain | LGF | CKF | SF | XF | HHF | IXF | AP | P1 |
|---|---|---|---|---|---|---|---|---|
| Supermarket | 0.57351 | 0.56896 | 0.56965 | 0.58600 | 0.56570 | 0.58087 | 0.57105 | 0.56914 |
| Travel | 0.64750 | 0.64959 | 0.64961 | 0.63896 | 0.65197 | 0.65680 | 0.65050 | 0.63812 |
| Thompson | 0.53872 | 0.53833 | 0.54093 | 0.52814 | 0.53756 | 0.54132 | 0.53514 | 0.51591 |
| Grocery | 0.69604 | 0.69729 | 0.69707 | 0.69128 | 0.69576 | 0.69842 | 0.69872 | 0.68984 |
| Energy | 0.29733 | 0.29924 | 0.30033 | 0.29410 | 0.30118 | 0.30060 | 0.29713 | 0.29507 |
| Camera | 0.64786 | 0.64721 | 0.64752 | 0.64748 | 0.64571 | 0.64487 | 0.64604 | 0.64294 |
| ItexVsCypress | 0.51422 | 0.51391 | 0.50999 | 0.50219 | 0.50970 | 0.51686 | 0.51194 | 0.51212 |
| Average | 0.55931 | 0.55922 | 0.55930 | 0.55545 | 0.55823 | 0.56282 | 0.55865 | 0.55188 |
| (a) | ||||||||
|---|---|---|---|---|---|---|---|---|
| domain | LGF | CKF | SF | XF | HHF | IXF | AP | P1 |
| Supermarket | 0.44280 | 0.44910 | 0.44739 | 0.43696 | 0.45441 | 0.43562 | 0.44697 | 0.46811 |
| Travel | 0.39598 | 0.38980 | 0.39015 | 0.40976 | 0.38841 | 0.38193 | 0.39648 | 0.42069 |
| Thompson | 0.45737 | 0.45601 | 0.45792 | 0.48016 | 0.46114 | 0.45777 | 0.46587 | 0.51565 |
| Grocery | 0.19560 | 0.19460 | 0.19555 | 0.20918 | 0.19901 | 0.19479 | 0.19683 | 0.21527 |
| Energy | 0.42718 | 0.42482 | 0.42490 | 0.43164 | 0.41975 | 0.41926 | 0.42461 | 0.43989 |
| Camera | 0.19557 | 0.19388 | 0.19417 | 0.20283 | 0.20141 | 0.20339 | 0.20003 | 0.21167 |
| ItexVsCypress | 0.43756 | 0.43987 | 0.44361 | 0.46226 | 0.44274 | 0.43921 | 0.43722 | 0.46152 |
| Average | 0.36458 | 0.36401 | 0.36481 | 0.37611 | 0.36670 | 0.36171 | 0.36686 | 0.39040 |
| (b) | ||||||||
|---|---|---|---|---|---|---|---|---|
| domain | LGF | CKF | SF | XF | HHF | IXF | AP | P1 |
| Supermarket | 0.41536 | 0.42271 | 0.42228 | 0.41394 | 0.42882 | 0.41037 | 0.42476 | 0.44646 |
| Travel | 0.39598 | 0.38980 | 0.39015 | 0.40976 | 0.38841 | 0.38193 | 0.39648 | 0.42069 |
| Thompson | 0.45737 | 0.45601 | 0.45792 | 0.48016 | 0.46114 | 0.45777 | 0.46587 | 0.51565 |
| Grocery | 0.19560 | 0.19460 | 0.19555 | 0.20918 | 0.19901 | 0.19479 | 0.19683 | 0.21527 |
| Energy | 0.42614 | 0.42373 | 0.42371 | 0.43042 | 0.41841 | 0.41807 | 0.42309 | 0.43843 |
| Camera | 0.18981 | 0.18925 | 0.18979 | 0.19740 | 0.19492 | 0.19699 | 0.19606 | 0.20576 |
| ItexVsCypress | 0.43756 | 0.43987 | 0.44361 | 0.46226 | 0.44274 | 0.43921 | 0.43722 | 0.46152 |
| Average | 0.35969 | 0.35943 | 0.36043 | 0.37188 | 0.36192 | 0.35702 | 0.36290 | 0.44646 |
| domain | LGF | CKF | SF | (c) XF | HHF | IXF | AP | P1 |
|---|---|---|---|---|---|---|---|---|
| Supermarket | 0.18723 | 0.19696 | 0.19526 | 0.17587 | 0.20295 | 0.18226 | 0.19171 | 0.19903 |
| Travel | 0.16681 | 0.16109 | 0.16081 | 0.17579 | 0.15901 | 0.15325 | 0.16314 | 0.17902 |
| Thompson | 0.19026 | 0.19176 | 0.18976 | 0.20422 | 0.19091 | 0.18927 | 0.19636 | 0.22859 |
| Grocery | 0.04910 | 0.04786 | 0.04864 | 0.05976 | 0.05101 | 0.04842 | 0.04783 | 0.06303 |
| Energy | 0.24504 | 0.23955 | 0.23858 | 0.24820 | 0.23492 | 0.23516 | 0.23789 | 0.24679 |
| Camera | 0.01860 | 0.01934 | 0.01873 | 0.02099 | 0.02142 | 0.02351 | 0.02164 | 0.02824 |
| ItexVsCypress | 0.16812 | 0.16979 | 0.17448 | 0.18650 | 0.17425 | 0.16660 | 0.17245 | 0.18098 |
| Average | 0.14645 | 0.14662 | 0.14661 | 0.15305 | 0.14778 | 0.14264 | 0.14729 | 0.16081 |
| (d) | ||||||||
|---|---|---|---|---|---|---|---|---|
| domain | LGF | CKF | SF | XF | HHF | IXF | AP | P1 |
| Supermarket | 0.70826 | 0.75850 | 0.74139 | 0.72082 | 0.73243 | 0.73035 | 0.82177 | 0.85347 |
| Travel | 0.58626 | 0.60839 | 0.62381 | 0.57311 | 0.62180 | 0.61342 | 0.68417 | 0.69942 |
| Thompson | 0.57681 | 0.67709 | 0.60411 | 0.63678 | 0.60775 | 0.60503 | 0.68074 | 0.76582 |
| Grocery | 0.79901 | 0.82462 | 0.82527 | 0.79673 | 0.83744 | 0.84908 | 0.84719 | 0.84206 |
| Energy | 0.69150 | 0.73543 | 0.71033 | 0.67537 | 0.70041 | 0.69513 | 0.68027 | 0.85217 |
| Camera | 0.80180 | 0.80536 | 0.80717 | 0.64470 | 0.82206 | 0.81622 | 0.82146 | 0.84243 |
| ItexVsCypress | 0.76850 | 0.80785 | 0.76880 | 0.76072 | 0.76023 | 0.75148 | 0.86250 | 0.89247 |
| Average | 0.70459 | 0.74532 | 0.72584 | 0.68689 | 0.72602 | 0.72296 | 0.77116 | 0.82112 |
(e)
Table 3: Average performance of models in terms of a) Utility, b) Nash Distance, c) Kalai Distance, d) Pareto Distance, and e) Pearson Correlation in Experiment II
5 Conclusion
In this paper, a new opponent preference model called POPPONENT is proposed. The experiments also reveal that the accuracy of P1, P6, and P8 exceeds the accuracy of the most accurate state of the art model. Evaluating the performance of POPPONENT also indicated that it overcomes the most accurate state of the art opponent models. In particular, the results indicated that POPPONENT works better in medium to large and more distributed negotiation domains and overcomes all the state of the art models in at least one domain for all the measures.
@inproceedings{ijcai2017p730,
  title     = {POPPONENT: Highly accurate, individually and socially efficient opponent preference model in bilateral multi issue negotiations (Extended Abstract)},
  author    = {Zafari, Farhad and Nassiri-Mofakham, Faria},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {5100--5104},
  year      = {2017},
  month     = {8},
  note      = {Journal track},
  doi       = {10.24963/ijcai.2017/730},
  url       = {https://doi.org/10.24963/ijcai.2017/730},
}
TY - CPAPER TI - POPPONENT: Highly accurate, individually and socially efficient opponent preference model in bilateral multi issue negotiations (Extended Abstract) AU - Zafari, Farhad AU - Nassiri-Mofakham, Faria T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 5100 EP - 5104 DO - 10.24963/ijcai.2017/730 UR - https://doi.org/10.24963/ijcai.2017/730 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





