
Exploiting Causality for Selective Belief Filtering in Dynamic Bayesian Networks (Extended Abstract)
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Journal track. Pages 5085-5089.
https://doi.org/10.24963/ijcai.2017/727
© 2017 International Joint Conferences on Artificial Intelligence
Keywords
- Uncertainty in AI: Bayesian Networks
- Planning and Scheduling: POMDPs
- Knowledge Representation, Reasoning, and Logic: Belief Change
- Uncertainty in AI: Approximate Probabilistic Inference
Abstract
Dynamic Bayesian networks (DBNs) are a general model for stochastic processes with partially observed states. Belief filtering in DBNs is the task of inferring the belief state (i.e. the probability distribution over process states) based on incomplete and uncertain observations. In this article, we explore the idea of accelerating the filtering task by automatically exploiting causality in the process. We consider a specific type of causal relation, called passivity, which pertains to how state variables cause changes in other variables. We present the Passivity-based Selective Belief Filtering (PSBF) method, which maintains a factored belief representation and exploits passivity to perform selective updates over the belief factors. PSBF is evaluated in both synthetic processes and a simulated multi-robot warehouse, where it outperformed alternative filtering methods by exploiting passivity.
- [Albrecht and Ramamoorthy, 2016] Stefano V. Albrecht and Subramanian Ramamoorthy. Exploiting causality for selec- tive belief filtering in dynamic Bayesian networks. Journal of Artificial Intelligence Research, 55:1135-1178, 2016.
- [Albrecht and Stone, 2017] Stefano V. Albrecht and Peter Stone. Reasoning about hypothetical agent behaviours and their parameters. In Proceedings of the 16th International Conference on Autonomous Agents and Multiagent Systems, pages 547-555, 2017.
- [Bonet and Geffner, 2016] Blai Bonet and Hector Geffner. Factored probabilistic belief tracking. In Proceedings of the 25th International Joint Conference on Artificial Intelli- gence, pages 3045-3052, 2016. IJCAI
- [Boyen and Koller, 1998] Xavier Boyen and Daphne Koller. Tractable inference for complex stochastic processes. In Proceedings of the 14th Conference on Uncertainty in Arti- ficial Intelligence, pages 33-42, 1998.
- [Dean and Kanazawa, 1989] Thomas Dean and Keiji Kanazawa. A model for reasoning about persistence and causation. Computational Intelligence, 5:142-150, 1989.
- [Doucet et al., 2000] Arnaud Doucet, Nando De Freitas, Kevin Murphy, and Stuart Russell. Rao-Blackwellised par- ticle filtering for dynamic Bayesian networks. In Proceed- ings of the 16th Conference on Uncertainty in Artificial Intelligence, pages 176-183, 2000.
- [Gordon et al., 1993] Neil J. Gordon, David J. Salmond, and Adrian F.M. Smith. Novel approach to nonlinear/non- Gaussian Bayesian state estimation. In IEE Proceedings F (Radar and Signal Processing), volume 140, pages 107- 113, 1993.
- [Kaelbling et al., 1998] Leslie P. Kaelbling, Michael L. Littman, and Anthony R. Cassandra. Planning and act- ing in partially observable stochastic domains. Artificial intelligence, 101(1):99-134, 1998.
- [Koller and Friedman, 2009] Daphne Koller and Nir Fried- man. Probabilistic Graphical Models: Principles and Tech- niques. The MIT Press, 2009.
- [Murphy and Weiss, 2001] Kevin Murphy and Yair Weiss. The factored frontier algorithm for approximate inference in DBNs. In Proceedings of the 17th Conference on Uncer- tainty in Artificial Intelligence, pages 378-385, 2001.
- [Murphy, 2002] Kevin P. Murphy. Dynamic Bayesian Net- works: Representation, Inference and Learning. PhD thesis, University of California, Berkeley, 2002.
- [Pearl, 2000] Judea Pearl. Causality: Models, Reasoning, and Inference. Cambridge University Press, 2000.
- [Vlasselaer et al., 2016] Jonas Vlasselaer, Wannes Meert, Guy Van den Broeck, and Luc De Raedt. Exploiting lo- cal and repeated structure in dynamic Bayesian networks. Artificial Intelligence, 232:43-53, 2016.
- [Wurman et al., 2008] Peter R. Wurman, Raffaello D'Andrea, and Mick Mountz. Coordinating hundreds of cooperative, autonomous vehicles in warehouses. AI Magazine, 29(1):9, 2008.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Often, the key to developing efficient filtering methods is to identify structure in the For any action CWi or CCWi, the variable ✓ there is a subset of state variables that directly affect xi (i.e. xi's parents in the DBN representing the action) such that
Dynamic Bayesian networks (DBNs) [Dean and Kanazawa, 1989] are a general model for stochastic processes with partially observed states (cf. Figure 1a). Belief filtering in DBNs is the task of inferring the belief state, i.e. the probability distribution over process states, based on incomplete and uncertain observations. This can be a costly operation in processes with large state spaces, requiring efficient approximate methods [Koller and Friedman, 2009; Murphy, 2002]. of DBNs as representations of actions in partially observed decision processes, such as POMDPs (Kaelbling, Littman, & Cassandra, 1998; Sondik, 1971) and their many variants. DBNs can be used to represent the e↵ects of actions on the decision process, by specifying how variables interact and what information the decision maker observes. In many cases, decision processes exhibit high degrees of causal structure (Pearl, 2000), by which we mean that a change in one part of the process may cause a change in another part. Our experience with such processes is that this causal structure may be used to make the filtering task more tractable, because it can tell us that beliefs need only be revised for certain aspects of the values only if the corresponding preceding varia orientation of joint j -1 causes a changed orient are absolute). Note that this also accounts for ch the arrows: the orientation of joint 3 changes if t 1 causes joint 2 to change, which in turn causes Further examples of passivity can be seen in in the "blocks" planning domain (e.g. Pasula, Z shows the arm holding blocks B and A, with A o in this subset changed its value. Passivity occurs naturally in many planning domains, such as in the robot arm shown in Figure 1b. If we assume that the joint orientations are absolute (e.g. θi = 0◦ means that joint i points exactly to the right), then the action of turning joint i leaves variables θj̸=i passive, because they change their values only if the corresponding preceding variable θj-1 changed its value. How can passivity be exploited to accelerate the filtering
joint movements or unreliable sensor readings fo
propagated over time. (We defer a detailed discussion of such methods to Section 2.)
process which can be leveraged for inference. In this article, we are interested in the application modified by the action. However, the variables xi may change its value only if at least one of the variables
passive with respect to the joint orientations since
changed. Furthermore, there is a causal chain fr
task? In the robot arm example, if we choose to rotate joint 3,
then the fact that joints 1 and 2 are passive means that they are
unaffected by this action. Thus, it seems redundant to revise
block A (XA), since A's position will change if
beliefs for the orientations of joints 1 and 2. However, this
is precisely what current filtering methods do. (See the full
How can passivity be exploited to accelerate t
fact that the state variables are passive means t
such that xi may change its value only if at least one of the variables in this subset changed its value. It is worth pointing out that passivity occurs naturally and frequently in many planning domains, especially in robotic and other physical systems (Mainzer, 2010). The unchanged, depending on which action we choos 3, then the fact that joints 1 and 2 are passive me Thus, it seems redundant to revise beliefs for t this is precisely what current filtering methods More concretely, assume we use a factored beli P(✓2, ✓3) and choose to rotate ✓3 in any directio to update the factor P(✓2, ✓3), since ✓3 changes i The purpose of this article is to formalise and evaluate the idea of automatically exploiting causal structure for efficient belief filtering in DBNs, using passivity as a concrete example of a causal relation. We present the Passivity-based Selective Belief Filtering (PSBF) method, which maintains a factored belief representation and exploits passivity to perform selective
article for a discussion of related work.)
the variables ✓1, ✓2 are both passive. Since the p
In this article, we are interested in the application of DBNs as representations of actions in partially observed decision processes, such as POMDPs [Kaelbling et al., 1998] and their many variants. Decision processes often exhibit high degrees of causal structure [Pearl, 2000], by which we mean that a change in one part of the process may cause a change in another part. Such causal structure may be used to make the filtering task more tractable, because it can tell us that beliefs need only be revised for certain aspects of the process. For example, if the variable x2 in Figure 1a changes its value only if variable x1 changed its value (i.e. a change in x1 causes a process state. For example, if the variable x2 in Figure 1 changes its value only if variable x1 changed its value (i.e. a change in x1 causes a change in x2), then it seems intuitive to use this causal relation when deciding whether to revise one's belief about x2. Unfortunately, current filtering methods do not take such causal structure into account. We refer to the above type of causal relation (between x1 and x2) as passivity. Intuitively, we say that a state variable xi is passive in a given action if, when executing that action, there is a subset of the state variables that directly a↵ect xi (i.e. xi's parents in the DBN) following example1 illustrates this in a simple robot arm:
∗This paper is an extended abstract of an article in the Journal of
Artificial Intelligence Research [Albrecht and Ramamoorthy, 2016]. 1. We mark the end of an example with a solid black square. updates over the belief factors. PSBF produces exact belief
✓
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence (IJCAI-17)
states under certain assumptions and approximate belief states otherwise. Our method is evaluated in both synthetic processes and a simulated multi-robot warehouse, where it outperformed alternative filtering methods by exploiting passivity.
2 Technical Preliminaries
We consider a decision process which, at each time t, is in a state st ∈ S and an agent is choosing an action at . After executing at in st , the process transitions into state st+1 ∈
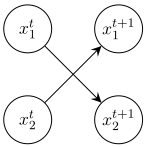
S with probability T at(st , st+1 ) and the agent receives an observation ot+1 ∈ O with probability Ωat(st+1 , ot+1 ). We assume factored representations of states and observations, However, while it may seem intuitive that clause (ii) be sufficient for passivity, there are in fact processes in which clause (ii) alone does not suffice. In other words, clause (ii) is necessary but not sufficient for passivity. We illustrate this in the following example: set Φa,i ⊆ pata (xt+1 i ) \ {xti } such that: (i) ∀xtj ∈ Φa,i : (xt+1 j , xt+1 i ) ∈ Ea
The agent chooses action at based on its belief state bt , which is defined as a probability distribution over the state space S of the process. Belief filtering is the task of updating the belief state bt → bt+1 based on the observation ot+1 . the value of xt1 (i.e. x1 and x2 swap their values at each time step). In this process, both state variables satisfy clause (ii) of Definition 3: If we set x01 = x02 (i.e. same initial values), then T a (st , st+1 ) is positive only for states st = st+1 , and hence (5) is true. If we set x01 6= x02 , then T a (st , st+1 ) is positive only for states st , st+1 with sti 6= st+1 i , i 2 {1, 2}, and hence (5) j i A state variable which is not passive is called active. Clause (i) requires that there is an edge from xt+1 j to xt+1 i
S = X1 × ... × Xn and O = Y1 × ... × Ym, with finite domains Xi, Yj . We write si to denote the value of Xi in state s, and analogously for oj and Yj. Example 3 (Non-example of passivity). Consider a process with two binary state variables, x1, x2, and a single action, a, shown in Figure 4. (We omit the observation variables for clarity.) The dynamics of the process are such that xt+1 1 takes the value of xt2 and xt+1 2 takes and (ii) for any two states st and st+1 with T a (st , st+1 ) > 0 : (∀xtj ∈ Φa,i : stj = st+1 ) ⇒ sti = st+1
⌅
A dynamic Bayesian network [Dean and Kanazawa, 1989] for action a, denoted ∆a , is an acyclic directed graph (cf. Figure 1a) consisting of: is trivially true since its premise is false. Despite satisfying clause (ii), the state variables xt+1 1 and xt+1 2 from Example 3 are in for all xtj ∈ Φa,i. As an example, see Figure 1a in which we assumed that the variable xt+1 2 was passive with respect to the variable xt1 . Clause (ii) defines the core semantics of passiv-
- State variables Xt={xt1 , ..., xtn }, Xt+1={xt+1 1 , ..., xt+1 n } with xti , xt+1 i ∈ Xi, representing the process states at time t and t + 1, respectively. fact not passive, for the following two reasons: Firstly, passivity is a causal relation and as such it must imply a causal order (Pearl, 2000). However, there is no causal order between x1 and x2, because there is no edge between xt+1 1 and xt+1 2 . Secondly, passivity means that a variable may change its value only if another variable with respect to which it is passive (a ity by requiring that xt+1 i remain unchanged if all variables in Φa,i remain unchanged. Note that this means that the distribution Pa for xt+1 i may specify any deterministic or stochastic behaviour if the variables in Φa,i change their values.
- Observation variables Y t+1={yt+1 1 , ..., yt+1 m } with yt+1 j ∈ Yj , representing the observation at time t + 1. variable in Φa,i) changed its value. In other words, whether or not a passive variable xt+1 i may change its value depends on both the past values of Φa,i (at time t) and the new values To clarify the role of clause (i), consider the "non-example" shown in Figure 2 (observation variables omitted for clarity).
- Directed edges Ea ⊆ (Xt × Xt+1 ) ∪ (Xt+1 × Xt+1 ) ∪ (Xt+1 × Y t+1 ) ∪ (Y t+1 × Y t+1 ), specifying dependencies between variables. of Φa,i (at time t +1). However, the variables in Example 3 only depend on the values at time t, hence their own values at time t+1 are predetermined and do not depend on whether the variables in Φa,i change values. The first issue, namely that of the causal order, can be addressed by adding the correThe dynamics of the process are such that binary variables x1 and x2 swap their values at each time step. It is easy to verify that both state variables satisfy clause (ii). However, note that these variables are in fact not passive. Passivity is a causal re-
The functions T a and Ωa are defined via Ea and Pa as Therefore, clauses (i) and (ii) together define the formal meaning of passivity. changed its value. However, the variables in the example depend only on values at time t. Clause (i) resolves these issues
- Conditional probability distributions Pa(z | paa(z)) for each variable z ∈ Xt+1 ∪ Y t+1 , specifying the probability that z assumes a certain value given a specific assignment to its parents paa(z) = {z′ | (z′ , z) ∈ Ea}. We also define pata (z) = Xt ∩ paa(z) and pat+1 a (z) =Xt+1 ∩ paa(z). sponding edges in Xt+1 . For instance, in Example 3 we could add an edge from xt+1 1 to xt+1 2 to establish a causal order. However, this does not generally solve the second issue, which is that every passive variable xt+1 i must depend on both past and new values of the variables in Φa,i. In other words, xt+1 i must be both inter-correlated as well as intra-correlated with the variables in Φa,i. The former is given by definition (since every variable in Φa,i is a parent of xt+1 i ) and the latter is precisely what is required by clause (i) in Definition 3. lation and as such it must imply a causal order [Pearl, 2000]. However, there is no causal order between x1 and x2, because there is no edge between xt+1 1 and xt+1 2 . Moreover, passivity means that a variable may change its value only if another variable with respect to which it is passive (a variable in Φa,i)
Ωa (s′ , o) = m∏ j=1 Pa (yt+1 j = oj | paa(yt+1 j ) ←↩ (s′ , o)) extracted from the process dynamics without additional information, and with no additional assumptions regarding the representation of variable distributions. In order to determine if a passive variables based on their conditional probability tables. 4 Passivity-based Selective Belief Filtering
where we use the notation paa(xt+1 i ) ←↩ (s, s′ ) to specify that the parents of xt+1 i in Xt and Xt+1 assume their corresponding values from s and s′ , respectively.
3 Passivity
A state variable xt+1 i is called passive in action a if there exists a subset of xt+1 i 's parents in Xt (in the DBN ∆a ) such that xt+1 i may change its value only if at least one of the variables in this subset changed its value. Formally:
Definition 1 (Passivity). Let action a be specified by DBN ∆a . A state variable xt+1 i is called passive in ∆a if there exists a
1146 Passivity-based Selective Belief Filtering (PSBF) uses a twostep update in which the belief state is first propagated through the process dynamics (transition step bt →ˆbt+1 ) and then conditioned on the observation (observation step ˆbt+1 →bt+1 ). We focus on the transition step in this abstract since this is where passivity is exploited, and leave the details of the observation step to the full article.
4.1 Belief State Representation
PSBF uses a factored belief state b(s)=∏Kk=1 bk(sk) in which each belief factor bk is a probability distribution defined over the set S(Ck) = ×xt+1 i ∈Ck Xi for a cluster Ck ⊆Xt+1 , such that C1 ∪ ... ∪CK = Xt+1 . The clustering should be such that strongly correlated variables are in a common cluster while independent or weakly correlated variables are in different clusters [Boyen and Koller, 1998]. Clusters can be specified manually or generated automatically using methods such as the ones described in Section 6.1 of the full article. See Example 4 in the full article for example clusterings.
4.2 Exploiting Passivity in Transition Step
The idea behind PSBF is to exploit passivity to perform selective updates over the belief factors bk in the transition step. To do this, we require a procedure which performs the transition step independently for each factor. We obtain such a procedure by introducing two assumptions:
The first assumption, (A1), states that the clusters must be uncorrelated (i.e. there are no edges in Xt+1 between clusters), and the second assumption, (A2), states that the clusters must be disjoint. Note that neither assumption implies the other.
Assuming (A1) and (A2), we can perform the transition step bt →ˆbt+1 independently for each belief factor as
where η1 is a normalisation constant and
The assumptions (A1)/(A2) guarantee that the transition step is performed exactly. They can be violated to obtain approximate belief states, and the full article discusses the various roles of these assumptions.
Given this procedure, we can exploit passivity to perform selective updates over the belief factors bk. Theorem 1 provides the formal foundation:
Theorem 1. If (A1) and (A2) hold, and if all xt+1 i ∈ Ck are passive in ∆at , then
How does Theorem 1 translate into situations in which (A1)/(A2) are violated? The key assumption is (A1). We can enforce (A1) by modifying the distributions Pa of xt+1 i ∈ Ck to marginalise out variables in pat+1 at (xt+1 i ) which are not in Ck, for all clusters Ck. However, this modification may cause xt+1 i to lose its passivity property, in the sense that it may no longer satisfy the clauses in Definition 1. Consequently, we would always have to perform the transition step for Ck, even if the unmodified variables in Ck are all passive.
Theorem 1 states that if the clusters C1, ..., CK are disjoint and uncorrelated, and if all variables in cluster Ck are passive in ∆at , then the transition step for the corresponding belief factor btk → ˆbt+1 k can be skipped without loss of information.
To alleviate this effect, one can check if there is a chance that the unmodified variables in the cluster change their values. It can be shown that this is the case whenever there is a causal path from any active variable to a variable in the cluster:
Definition 2 (Causal path). A causal path in ∆a , from an active variable xt+1 i to another variable xt+1 j , is a sequence 〈x(1) , x(2) , ..., x(Q) 〉 such that x(1) = xt+1 i , x(Q) = xt+1 j , and for all 1 ≤ q < Q :
- (ii) x(q+1) is passive in ∆a with respect to x(q)
Intuitively, a causal path defines a chain of causal effects (such as between joints 1 and 3 in Figure 1b): since the active variable x(q) may have changed its value and x(q+1) is passive with respect to x(q) , x(q+1) may also have changed its value, etc. Hence, in the absence of observing these changes, the mere existence of a causal path from x(1) to x(Q) is reason to revise our beliefs about x(Q) . Thus, as a general update rule, we can skip the transition step btk → ˆbt+1 k if all unmodified variables in Ck are passive in ∆at , and if there is no causal path from any active variable in ∆at to any variable in Ck.
See the full article for a procedure which implements this rule, as well as discussions of computational complexity and approximation errors of PSBF.
5 Experimental Evaluation
The PSBF method was evaluated in synthetic processes with varying sizes and degrees of passivity, as well as a simulation of a multi-robot warehouse system.
5.1 Synthetic Processes
Synthetic processes of four sizes were generated: S (10,3), M (20,6), L (30,9), XL (40,12), where brackets show the number of binary state/observation variables. Each process consisted of two action DBNs which were chosen randomly at each time step. A passivity of p% means that p% of state variables were made passive. We used three automatic clustering methods, called 〈pc〉, 〈moral〉, 〈modis〉.
PSBF was compared to a selection of alternative methods: PF [Gordon et al., 1993]; RBPF [Doucet et al., 2000]; BK [Boyen and Koller, 1998]; and FF [Murphy and Weiss, 2001]. For comparison, PF/RBPF/FF were configured to approximate the speed or accuracy of PSBF/BK.
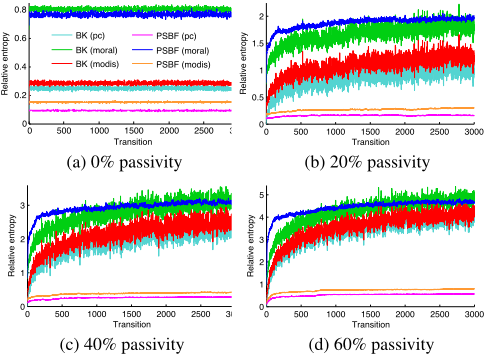
Figure 3 shows the relative entropy from exact belief state to PSBF/BK, which achieved the highest accuracy among the tested methods. The results show that PSBF produced a higher or comparable accuracy to BK. They exhibited the same convergent behaviour in relative entropy, showing that the approximation error due to the factorisation was bounded (as discussed in the full article). The relative entropy of both methods increased with the degree of passivity in the process. This is since a higher passivity implies a higher determinacy and, therefore, lower mixing rates, which are a crucial factor in the error bounds of PSBF and BK.
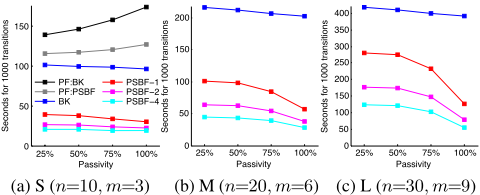
Figure 4 shows computation times (RBPF/FF omitted due to low accuracy results). PSBF was able to minimise the time requirements by exploiting passivity, where the savings grew with both the degree of passivity and the size of the process. While PSBF outperformed BK in our tests, their difference decreased for lower degrees of passivity. With low passivity, PSBF often performed full transition and observation steps, which can be costly operations in large processes. Additionally, the computational overhead of modifying variable distributions and detecting skippable belief factors did not amortise as effectively in large processes with low passivity.
5.2 Multi-robot Warehouse
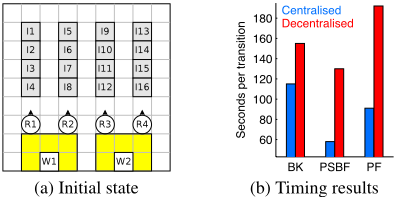
We demonstrate how passivity can occur naturally in a more complex system, and how PSBF can exploit this to accelerate the filtering task. To this end, we simulated a multi-robot warehouse in the style of Kiva [Wurman et al., 2008], in which the robots' task is to transport goods. Figure 5a shows the initial state of the simulation. Each robot can perform actions such as moving, turning, and loading pods. Actions and observations have some uncertainty. Each robot maintains a list of tasks such as "Bring inventory pod I to workstation W", which are assigned via task auctions. We used two heuristic control modes (centralised and decentralised) to plan actions for robots. See the full article for specifications of DBNs, clusterings, and algorithm configurations.
Figure 5b shows the time per transition of PSBF, BK, and PF, averaged over 20 different simulations with 100 transitions each. PSBF outperformed BK on average by 49%/17% and PF by 36%/32% in the centralised/decentralised control mode, respectively. In many cases, PSBF updated less than half of the belief factors, which resulted in significant savings. PSBF's relative savings were smaller in the decentralised mode since its corresponding DBNs had a lower passivity.
The number of states in the warehouse simulation (≈ 1045 ) was too large to compare the accuracy of the tested methods in terms of relative entropy. Instead, we compared their accuracy based on the results of the task auctions and the number of completed tasks in each simulation. In the centralised mode, the algorithms generated over 95% identical task auctions and completed 15.7 (BK), 15.5 (PSBF), and 15.2 (PF) tasks on average. In the decentralised mode, they generated over 93% identical auctions and completed 12.1 (BK), 12.2 (PSBF), and 11.7 (PF) tasks on average. These differences were not statistically significant, indicating that PSBF achieved an accuracy similar to that of BK and PF.
6 Conclusion
Our work demonstrates the potential of exploiting causal structure to render the belief filtering task more tractable. In particular, our experiments support the hypothesis that factored beliefs and passivity can be a useful combination in large processes. This insight is relevant for complex processes with high degrees of causality, such as robots used in homes and offices, where the filtering task may constitute a major impediment due to the often very large state space.
There are several directions for future work. For example, it would be useful to know if the definition of passivity could be relaxed while retaining the ability to perform selective updates, and whether the idea of selective inference could be extended to other methods that use factored beliefs. In this work, the selective inference was determined by the parameterisation of the process. An interesting alternative is to frame the selection as a decision problem [Albrecht and Stone, 2017]. Ultimately, the key to developing efficient filtering methods is to identify and exploit structure in the process, such as passivity and other recent examples [Bonet and Geffner, 2016; Vlasselaer et al., 2016]. A grand challenge will be to unite such structural exploitation under one theory of inference.
Acknowledgments
The authors acknowledge the support of the German National Academic Foundation, the UK Engineering and Physical Sciences Research Council (EP/H012338/1), and the European Commission (TOMSY 270436).
@inproceedings{ijcai2017p727,
  title     = {Exploiting Causality for Selective Belief Filtering in Dynamic Bayesian Networks (Extended Abstract)},
  author    = {Albrecht, Stefano V. and Ramamoorthy, Subramanian},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {5085--5089},
  year      = {2017},
  month     = {8},
  note      = {Journal track},
  doi       = {10.24963/ijcai.2017/727},
  url       = {https://doi.org/10.24963/ijcai.2017/727},
}
TY - CPAPER TI - Exploiting Causality for Selective Belief Filtering in Dynamic Bayesian Networks (Extended Abstract) AU - Albrecht, Stefano V. AU - Ramamoorthy, Subramanian T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 5085 EP - 5089 DO - 10.24963/ijcai.2017/727 UR - https://doi.org/10.24963/ijcai.2017/727 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





