
Bridging the Gap between Observation and Decision Making: Goal Recognition and Flexible Resource Allocation in Dynamic Network Interdiction
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 4477-4483.
https://doi.org/10.24963/ijcai.2017/625
Keywords
- Planning and Scheduling: Activity and Plan Recognition
- Uncertainty in AI: Approximate Probabilistic Inference
- Uncertainty in AI: Sequential Decision Making
- Multidisciplinary Topics and Applications: Multidisciplinary Topics and Applications
Abstract
Goal recognition, which is the task of inferring an agent’s goals given some or all of the agent’s observed actions, is one of the important approaches in bridging the gap between the observation and decision making within an observe-orient-decide-act cycle. Unfortunately, few researches focus on how to improve the utilization of knowledge produced by a goal recognition system. In this work, we propose a Markov Decision Process-based goal recognition approach tailored to a dynamic shortest-path local network interdiction (DSPLNI) problem. We first introduce a novel DSPLNI model and its solvable dual form so as to incorporate real-time knowledge acquired from goal recognition system. Then a Markov Decision Process-based goal recognition model along with its dynamic Bayesian network representation and the applied goal inference method is proposed to identify the evader’s real goal within the DSPLNI context. Based on that, we further propose an efficient scalable technique in maintaining action utility map used in fast goal inference, and develop a flexible resource assignment mechanism in DSPLNI using knowledge from goal recognition system. Experimental results show the effectiveness and accuracy of our methods both in goal recognition and dynamic network interdiction.
- [Ahlberg et al., 2007] Simon Ahlberg, Pontus Hörling, Kata- rina Johansson, Karsten Jöred, Hedvig Kjellström, Chris- tian Mårtenson, Göran Neider, Johan Schubert, Pon- tus Svenson, Per Svensson, et al. An information fu- sion demonstrator for tactical intelligence processing in network-based defense. Information Fusion, 8(1):84-107, 2007.
- [Avrahami-Zilberbrand and Kaminka, 2005] Dorit Avrahami-Zilberbrand and Gal A Kaminka. Fast and complete symbolic plan recognition. In IJCAI, pages 653-658, 2005. IJCAI
- [Baker et al., 2009] Chris L Baker, Rebecca Saxe, and Joshua B Tenenbaum. Action understanding as inverse planning. Cognition, 113(3):329-349, 2009.
- [Bayrak and Bailey, 2008] Halil Bayrak and Matthew D Bai- ley. Shortest path network interdiction with asymmetric information. Networks, 52(3):133-140, 2008.
- [Boyd, 1987] John R Boyd. Organic design for command and control. A discourse on winning and losing, 1987.
- [Bui et al., 2002] Hung Hai Bui, Svetha Venkatesh, and Ge- off West. Policy recognition in the abstract hidden markov model. Journal of Artificial Intelligence Research, 17:451-499, 2002.
- [Cappanera and Scaparra, 2011] Paola Cappanera and Maria Paola Scaparra. Optimal allocation of protective resources in shortest-path networks. Transportation Science, 45(1):64-80, 2011.
- [Chen and others, 2003] Zhe Chen et al. Bayesian filtering: From kalman filters to particle filters, and beyond. Statis- tics, 182(1):1-69, 2003.
- [Endsley and Garland, 2000] Mica R Endsley and Daniel J Garland. Situation awareness analysis and measurement. CRC Press, 2000.
- [Fulkerson and Harding, 1977] Delbert Ray Fulkerson and Gary C Harding. Maximizing the minimum source-sink path subject to a budget constraint. Mathematical Pro- gramming, 13(1):116-118, 1977.
- [Geib and Goldman, 2001] Christopher W Geib and Robert P Goldman. Plan recognition in intrusion detection systems. In DARPA Information Survivability Confer- ence & Exposition II, 2001. DISCEX'01. Proceedings, volume 1, pages 46-55. IEEE, 2001.
- [Hofmann and Williams, 2007] Andreas G Hofmann and Brian C Williams. Intent recognition for human-robot in- teraction. In Interaction Challenges for Intelligent Assis- tants, pages 60-61, 2007.
- [Israeli and Wood, 2002] Eitan Israeli and R Kevin Wood. Shortest-path network interdiction. Networks, 40(2):97- 111, 2002.
- [Laporte et al., 2010] Gilbert Laporte, Juan A Mesa, and Federico Perea. A game theoretic framework for the robust railway transit network design problem. Transportation Research Part B: Methodological, 44(4):447-459, 2010.
- [Liao et al., 2007] Lin Liao, Donald J Patterson, Dieter Fox, and Henry Kautz. Learning and inferring transportation routines. Artificial Intelligence, 171(5-6):311-331, 2007.
- [Litman and Allen, 1987] Diane J Litman and James F Allen. A plan recognition model for subdialogues in con- versations. Cognitive science, 11(2):163-200, 1987.
- [Lofberg, 2005] Johan Lofberg. Yalmip: A toolbox for mod- eling and optimization in matlab. In Computer Aided Con- trol Systems Design, 2004 IEEE International Symposium on, pages 284-289. IEEE, 2005.
- [Lunday and Sherali, 2010] Brian J Lunday and Hanif D Sherali. A dynamic network interdiction problem. Infor- matica, 21(4):553-574, 2010.
- [Pynadath and Wellman, 1998] David V Pynadath and Michael P Wellman. Generalized queries on probabilistic context-free grammars. IEEE Transactions on Pattern Analysis and Machine Intelligence, 20(1):65-77, 1998.
- [Ramırez and Geffner, 2011] Miquel Ramırez and Hector Geffner. Goal recognition over pomdps: Inferring the in- tention of a pomdp agent. In IJCAI, pages 2009-2014. IJCAI/AAAI, 2011. IJCAI
- [Scaparra and Church, 2008] Maria P Scaparra and Richard L Church. A bilevel mixed-integer program for critical infrastructure protection planning. Computers & Operations Research, 35(6):1905-1923, 2008.
- [Simaan and Cruz, 1973] Marwaan Simaan and Jose B Cruz. On the stackelberg strategy in nonzero-sum games. Jour- nal of Optimization Theory and Applications, 11(5):533- 555, 1973.
- [Sukthankar et al., 2014] Gita Sukthankar, Christopher Geib, Hung Hai Bui, David Pynadath, and Robert P Goldman. Plan, activity, and intent recognition: Theory and practice. Newnes, 2014.
- [Synnaeve and Bessiere, 2012] Gabriel Synnaeve and Pierre Bessiere. Special tactics: A bayesian approach to tacti- cal decision-making. In Computational Intelligence and Games (CIG), 2012 IEEE Conference on, pages 409-416. IEEE, 2012.
- [Xiao et al., 2014] Kaiming Xiao, Cheng Zhu, Weiming Zhang, Xiangyu Wei, and Songchao Hu. Stackelberg net- work interdiction game: nodal model and algorithm. In Game Theory for Networks (GAMENETS), 2014 5th In- ternational Conference on, pages 1-5. IEEE, 2014.
- [Yin et al., 2016] Quanjun Yin, Shiguang Yue, Yabing Zha, and Peng Jiao. A semi-markov decision model for recog- nizing the destination of a maneuvering agent in real time strategy games. Mathematical Problems in Engineering, 2016, 2016.
- [Yue et al., 2016] Shiguang Yue, Kristina Yordanova, Frank Krüger, Thomas Kirste, and Yabing Zha. A decentral- ized partially observable decision model for recognizing the multiagent goal in simulation systems. Discrete Dy- namics in Nature and Society, 2016, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The ability to recognize the plans and goals of other agents enables humans, AI agents or command and control systems to reason about what the others are doing, why they are doing it, and what they will do next [Sukthankar et al., 2014]. Till now, plan or goal recognition systems work well in many applications like human-robot interaction [Hofmann and Williams, 2007], dialogue understanding [Litman and Allen, 1987] and system intrusion detection [Geib and Goldman, 2001], still domains like game AI and Command and Control system need more than plain recognition results. For example in [Synnaeve and Bessiere, 2012], though having accurate prediction of the opponent's technology level, they placed only a 4th in the 2012 StarCraft AI competition due to their inability to adapt to the prediction effectively. This shows the great impact of information fusion level on the final decision-making quality besides the accuracy and efficiency of goal recognition. A motivation of our work is to provide an application framework of using plan recognition technique to orient observed information to decision making. According to the Observe-Orient-Decide-Act (OODA) theory developed by [Boyd, 1987]:
∗Kai Xu and Kaiming Xiao are both first authors of this paper.
"The second O, orientation - as the repository of our genetic heritage, cultural tradition, and previous experiences - is the most important part of the OODA loop since it shapes the way we observe, decide and act."
Because of its importance, the orientation has been researched on for several decades in forms of intelligence processing [Ahlberg et al., 2007] and situational awareness [Endsley and Garland, 2000].
Network interdiction is one of classic decision-making problems applied in domains involving critical infrastructure protection [Scaparra and Church, 2008], public transportation [Laporte et al., 2010] and public security [Cappanera and Scaparra, 2011]. Traditionally, the act of network interdiction is most often modeled in the form of a static two-player, two-stage, master-slave game with perfect information (i.e., a Stackelberg game), in which an interdictor allocates interdiction resources, followed by the subsequent decisions made by an evader to move through the network from a source to a terminus [Lunday and Sherali, 2010]. However, the above-mentioned assumptions are not valid in real-life scenarios where the evader's possible termini are neither single nor static. In this work, we seek to orient the knowledge generated by goal recognition system into the decision-making process of the indicator, and thus allow a dynamic shortestpath local network interdiction.
Our first contribution is to introduce a novel Dynamic Shortest-Path Local Network Interdiction (DSPLNI) model so as to incorporate useful real-time knowledge acquired from goal recognition system. As the problem is a typical bilevel mixed-integer program (BLMIP), a BLMIP solvable dual form is then proposed as the DSPLNI's reformulation. The second contribution is to introduce a Markov Decision Process-based goal recognition model, its dynamic Bayesian network representation and the applied goal inference method.
Further, we propose a scalable technique in maintaining action utility map for fast goal inference. This is mainly designed to get and update action utilities more efficiently under the dynamic changing network environment. Lastly, a flexible resource assignment mechanism in DSPLNI using knowledge from goal recognition results is developed, where a heuristic named Subjective Confidence is introduced to allocate the interdiction resource more effectively at each network confrontation stage.
2 Background and RelatedWork
2.1 Model-based Goal Recognition
The goal recognition problem has been formulated and addressed in many ways, as a matching problem over a suitable AND/OR graph [Avrahami-Zilberbrand and Kaminka, 2005], a parsing problem over grammar [Pynadath and Wellman, 1998], a probabilistic inference task over a dynamic Bayesian network [Bui et al., 2002; Liao et al., 2007] and an inverse planning problem over planning models [Baker et al., 2009; Ramırez and Geffner, 2011].
Among those approaches, two formulations solve the goal recognition or plan recognition problem from different perspectives. One focuses on constructing a suitable library of plans or policies, while another one replaces that by an agent action model and a set of possible goals [Ramırez and Geffner, 2011]. The advantages of the latter formulation are twofold: one is that plenty of existing model-based planners could be leveraged on; the other one lies in the fact that the model itself reflects people's understanding of behavior patterns of the recognizing target. This is especially helpful when people have little knowledge to construct a full library of plans or policies needed by the first formulation, while still capturing some facts or patterns of agent behaviors from daily observation or common solutions. Hidden Markov Models (HMMs) are widely used in goal recognition. [Bui et al., 2002] proposed an Abstract Hidden Markov Model (AHMM) to recognize an agent's behavior in dynamic, noisy, uncertain domains, and across multiple levels of abstraction. Comparing to the HMM, Markov Decision Process (MDP) can describe agent actions and interactions between agents and the environment. [Baker et al., 2009] consider the goal recognition problem over a MDP setting where actions are assumed to be stochastic and states fully observable. [Ramırez and Geffner, 2011] extend their work to Partially Observable MDP settings where states are partially observable. [Yin et al., 2016; Yue et al., 2016] further extend to a Semi-MDP setting where durative actions break the Markov property and a Decentralized POMDP setting in multi-agent problem domain.
2.2 Shortest Path Network Interdiction
The network interdiction problem has been examined for several decades within the context of a variety of modeling approaches, optimization objectives, and solution techniques. The network interdiction problem that we focus on is Maximizing the Shortest Path (MXSP) [Fulkerson and Harding, 1977]. It is also frequently referred to as the Shortest Path Network Interdiction (SPNI) problem. SPNI is the interdictor's problem: subject to a limited interdiction budget, interdict arcs in a network to maximize the shortest path length between specified nodes s and t [Israeli and Wood, 2002]. It could be viewed as a bilevel mixed-integer program (BLMIP), which is a special case of a static Stackelberg game [Simaan and Cruz, 1973].
3 Dynamic Shortest-Path Local Network Interdiction
In order to make reliable and high-quality decisions in the real-life network interdiction game, real-time knowledge acquired through goal recognition should be properly used in the decision-making process. The usage of goal recognition in network interdiction are twofold: one is that the objective function of game players is defined as the expectation of the shortest path length, which overcomes the barrier that evader's real goal is usually uncertain for interdictor; the other one is embodied in the local resource allocation strategy which allows interdictor to allocate resources in both temporal and geographical dimension.
3.1 Model Formulation
In previous studies, interdictor is assumed to know the exact location of the source and terminus of evader [Israeli and Wood, 2002; Bayrak and Bailey, 2008; Xiao et al., 2014]. Thus he/she can first allocate resources in the road network, after which evader select the shortest path to traverse; hence, interdictor can make a once-for-all decision to gain an optimal reward.
Unfortunately, this assumption is invalid in real-life scenarios where evader's goals and actions are subtle, deceptive and even confusing for interdictor. Before introducing novel model, we first claim assumptions which are different from those in previous MXSP model [Israeli and Wood, 2002]:
- Evader's current location (i.e., current source) is observable, while the information of its goal (i.e., final terminus) is uncertain for interdictor. Meanwhile, evader may change its final terminus midway for deception or other possible purpose.
- The confrontation between evader and interdictor is assumed as a multi-stage process. In each stage, interdictor assigns some resources and allocates them to the local area of evader's current location based on the knowledge of recognition results and subjective confidence, and accordingly evader re-plan the shortest path.
These assumptions are closer to the reality, and the mathematical-programming formulation of Dynamic Shortest-Path Local Network Interdiction (DSPLNI) is modified as follows:
Problem: Maximize the expectation shortest s - g path length in a directed network by interdicting arcs,
Indices:
i ∈ N, nodes in G (s is the current source node, g1, . . . , gm are the potential termini),
k = (i, j) ∈ A, arcs in G,
k ∈ FS(i)(k ∈ RS(i)), arcs directed out of (into) node i,
Data:
τ = 1, 2, . . . , T, stages of the confrontation process,
0 ≤ ck < ∞, nominal length of arc k (vector form c),
0 ≤ dk < ∞, added integer delay if arc k is interdicted (vector form d),
rk > 0, resource required to interdict arc k (vector form r),
R, total amount of interdiction resource,
Rτ , total amount of interdiction resource assigned to stage τ ,
probabilistic distribution over the possible goals g1, · · · , gm,
Variables: xk = 1 if arc k is interdicted by the interdictor; else xk = 0,
yk = 1 if arc k is traversed by the evader; else yk = 0.
The formulations is:
where X = {x ∈ {0, 1}|A| |rT x ≤ Rτ}. Additional comments are as follows:
- In each stage τ , the goal of interdictor is to maximize the expectation length of the shortest path of evader from s to potential termini g1, · · · , gm.
- Eq. (1) is the flow-balance constraint when the probabilistic distribution over potential termini g1, · · · , gm is obtained from goal recognition.
- Interdictor assigns a certain amount of resource Rτ , and then selects a set of arcs in FS(s) to interdict guaranteed by constraints in Eq. (2) and Eq. (3), after which evader re-plan the path to traverse.
3.2 Reformulation and Algorithm
The problem of DSPLNI is a typical BLMIP, which cannot be solved directly using MIP approaches; thus a proper reformulation is necessary for the optimal solution. Here we propose a dual reformulation of DSPLNI. We first reformulate [DSPLNI-P] as follows:
where D = diag(d1, · · · , d|A|), Eq. (5) is the vectorform of flow-balance constraint of Eq. (1), b = (1, 0, · · · , 0, -p(g1), · · · , -p(gm))T .
Since the inner minimization of DSPLNI is a standard shortest-path model, linear dual theory can be used to get the dual of it. We first fix the outer variable x, and then take the dual of the inner minimization in [DSPLNI-P1], after which release x and make some simple modifications. The final reformulated MIP results:
where X = {x ∈ {0, 1}|A| |rT x ≤ Rτ }, ⃗π is the vector form of dual variables. Hence, [DSPLNI-D], a simple MIP, can be solved directly using a standard LP-based branch-and-bound algorithm.
4 MDP-based Goal Recognition
4.1 Model Formalization and Goal Inference
In standard definition of MDP, there is no concept of goal or joint goal. The MDP defines the states which consist of all information needed for making decisions. When formalizing a model for goal recognition, the original definition of states should be further decomposed into inner and external states, corresponding to the agent goal and outside environment respectively. Thus, the action selection is determined by all inner and external states. Besides, it should also satisfy situations when goal is terminated as goal achievement or halfway interruption. Thus, the model is a combination of three parts: a) the standard MDP; b) the agent goal and c) the goal termination variable. Thus our MDP-based model is a tuple < s0, S, G, e, A, Pa(s′ |s), O > given by
- an initial state s0,
- a non-empty state space S,
- a non-empty set of goal states G ⊆ S,
- a goal termination variable e for e = {0, 1},
- a set of actions A,
- probabilities Pa(s′ |s) for a ∈ A, s, s′ ∈ S, and
- a non-empty observation set O.
Essentially, the model is a dynamic Bayesian network, in which all causalities could be depicted. We introduce a full DBN structure depicting two time slices is presented in Figure 1. The behaviors of system evolution are described using functions or parameters.
- state transition function T : S×A×S→[0, 1] is Psτ = p(sτ |sτ-1, aτ ),
- observation function S×O→[0, 1] is Poτ = p(oτ |sτ ),
- agent action policy Paτ = p(aτ |sτ-1, gτ ),
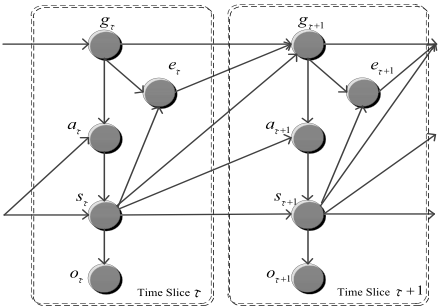
- goal transition probability Pgτ = p(gτ |eτ-1, gτ-1),
- goal termination probability Peτ = p(eτ |gτ , sτ ).
Recognizing the evader's goal is an inference problem trying to find the real goal behind agent actions based on observations online. In essence, the task is to compute the posterior distribution P(gτ |oτ) of goal gτ given observation oτ . This could be achieved either by accurate inference or by approximate methods. Accurate inference, however, is not scalable when state space of the domain problem becomes large, nor can it tackle partially missing or noisy data. Widely applied in sequential state estimation, particle filter is a kind of approximate inference methods designed to handle non-Gaussian, nonlinear and high-dimensional problems [Chen and others, 2003]. In this work, the MDP or agent action model is assumed to be known by both the evader and the indicator, except for the current goal gτ of the evader. Instead, the set of possible goals is given along with the priors P(G). Similar assumptions also exist in [Ramırez and Geffner, 2011] in which the posterior goal probabilities P(G|O) is obtained from Bayes rule P(G|O) = αP(O|G)P(G) where α is a normalizing constant. In particle filter however, a posterior distribution is empirically represented using a weighted sum of Np samples [Chen and others, 2003] drawn from the proposal distribution:
where g(i) τ are assumed to be i.i.d drawn from q(gτ |oi). The importance weights W (i) τ should be updated recursively
As we use simplest sampling, the q(g(i) τ |g(i) 0:τ-1 , oτ) is set to be p(g(i) τ |g(i) τ-1 ), which could be computed directly using the agent action model:
Thus the gτ in Eq. (13) would be sampled from p(g(i) τ |g(i) τ-1 ). As the observation oτ only depends on sτ , the importance weights W (i) τ can be updated by
4.2 Action UtilityMapMaintenance
Many model-based goal recognition [Baker et al., 2009; Ramırez and Geffner, 2011; Yin et al., 2016] share a key assumption, that if the agent is pursuing the goal G, the probability P(a|b,G) of choosing action a in the state b is given by the Boltzmann policy P(a|b,G) = α′ exp{βQG(a, b)} where α′ is a normalizing constant, β captures a 'soft rationality' assumption. In this work, we formulate this assumption as p(vi|vτ , gτ ) = α′ exp(βugτ (vτ , vi)) where ugτ (vτ , vi) is the utility of agent in the vertex vτ choosing vi under the goal gτ at the confrontation stage τ. In SPNI, we define ugτ (vτ , vi) = 1/(rvτ ,vi +rvi,gτ ), where the rvτ ,vi is the nominal integer length of arc ck where k = (τ, i) and rvi,gτ is the shortest path length from vi to the target gτ computed by the Dijkstra algorithm. However, this value has to be recomputed continuously as we interdict the network. In this section, we prove that only a small portion of vτ whose utilities need to be updated.
Theorem 1. Given the network G and a fixed target g, let T<s,g>(Ns,As) be the shortest path trace of a source-target pair < s, g >, where Ns = {1, 2, . . . , ns} and As = {(i, i + 1)|i ∈ Ns/ns}. For any v ∈ Ns, there exists at least one T<v,g>(Nv, Av) in the v-g shortest path set S, in which the Av satisfies Av ⊆ As.
Proof. Assuming there is no T<v,g>(Nv,Av) in the v - g shortest path set S where Av ⊆ As, then any element T ′<v,g> from vertex v to g in S satisfies T ′<v,g> ≤ T<v,g>. According to the properties of shortest path network, T<s,v>+T ′<v,g> ≤ T<s,g> . Thus the T<v,g>(Nv,Av) is not the shortest path of the pair < v, g >.
Based on Theorem 1, we propose a dynamic action utility map maintenance algorithm and improve the scalability of our goal inference method. Four basic steps are shown as follows. It should be noted that, Step 3 not only updates elements v in updateSet, but also updates those vertexes locating along the way from v to the entering vertex of the corresponding interdicted arc.
Input: Evader possible terminus set Ter, action trace map Mapτ-1, the network adjacent matrix NetAdjτ-1, the interdiction result XGτ and the filtering result particleτ ,
Output: Mapτ ,
Step 1: Find all unique agent positions of particles: PosSet; Update NetAdjτ-1 to get NetAdjτ using XGτ ;
Step 2: Check all positions in PosSet, find those whose traces in Mapτ-1 containing interdicted arcs in XGτ to get the updateSet;
Step 3: Get updated trace map Mapτ using
Mapτ-1, NetAdjτ , Ter and updateSet.
4.3 Resource Assignment
Now, we introduce the flexible resource assignment in each confrontation stage. It is assumed that a total amount of resource R is available during the whole process of interdiction. Therefore, the resource needs to be dynamically assigned to each stage for the purpose of high utilization levels. For goal recognizer, we refer to the level of certainty of some specific facts as the agent's subjective confidence (SC) of those facts. In this paper, we use SC to compute the Rτ . In particle system, the SC could be represented using the weighted variance of estimated distribution of goals,
where ωiτ is the weight of particle xiτ and ˆ gτ is the estimated goal distribution. This benchmark was frequently used to evaluate the performance of two goal inference algorithms [Chen and others, 2003].
According to the definition of SC, its value would be at the maximum before any observation comes in. In particle system, this happens just after all particles are initialized according to goal priors. For example, when the particles are sampled randomly with three possible termini, the upper bound of the SC V arupper = 2/3. Based on that, we compute Rτ linearly at each confrontation stage τ using
where H is estimated as the remaining number of arcs that the evader needs to traverse to the estimated terminus.
5 Experiments
We conducted extensive experiments on the basis of a synthetic evader action data upon a real road network. The empirical test results show the effectiveness of our goal recognition method, and also verify the practical implications of those methods for solving scalable multi-terminus SPNI.
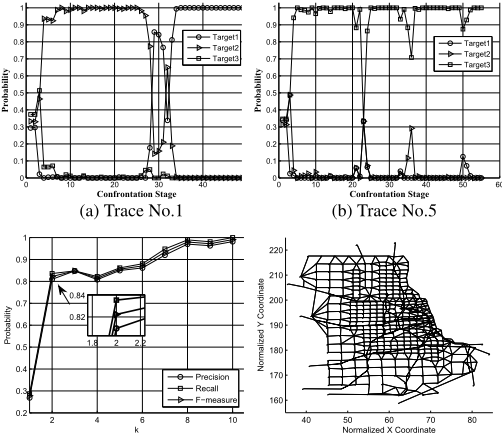
The experiment settings are as follows. The program was written in Matlab script and is run in a computer with an Intel i7 CPU (3.40 GHz) and 8 GB memory. The road network we select is Chicago Sketch Road Network [Lunday and Sherali, 2010], as in Figure 2 (d), consisting 933 vertexes and 2950 edges. The evader has one starting point and three predefined possible destination which would be selected with equal probability at the beginning. We simplify the goal termination function as follows: if evader reaches its terminus, then the goal is achieved, otherwise it changes the goal with a probability of 0.01 for every state. The observation, containing the evader's current position, of the recognizer would be missing with a probability of 0.2. The computation of the SPNI is formulated into a BLMIP and solved using the MIP solvers of CPLEX 11.5 and YALMIP toolbox of MATLAB [Lofberg, 2005]. The Np of the particle system is set to 300. We omit the nontrivial details due to lack of space.
5.1 Tests on Goal Recognition
We run the agent decision model repeatedly and collect a test dataset consisting of 100 labeled traces with each trace possessing an average of 41.12 steps. There are approximately 44% traces where the evader's goal is changed at least once during half way. To show the details of the recognition results, we randomly select two specific traces (No.1, No.5) from the test dataset.
| Trace No. | Duration Targets | Goal Interrupted | |
| 1 | τ ∈ [1, 26] | Target 2 | Yes |
| τ ∈ [27, 49] | Target 1 | No | |
| 5 | τ ∈ [1, 55] | Target 3 | No |
(c) Precision, Recall and F-measure (d) Chicago sketch roadmap
Figure 2: Experimental results for Goal Recognition
As shown in Table 1, the evader in trace No.1 selected Target 2 to be its first terminus before changed it to Target 1 at τ = 27 and eventually achieved the goal at τ = 49, while the evader in trace No.5 kept its initial goal (Target 3) till the end. Recognition results are shown in Figure 2. In Figure 2 (a), the probability of the real goal (Target 2) increases quickly during the initial period. When the goal is changed at τ = 27, our method responds very fast and the correct estimate maintains except for a misleading observation at τ = 32. In Figure 2 (b), the estimate of the real terminus keeps its dominance till the end. Our inference method is further evaluated in Figure 2 (c) by statistic metrics of precision, recall and F-measure, which are frequently used to measure overall accuracy of the recognizer [Sukthankar et al., 2014]. As to evaluate traces with different lengths, the paper applies the method in [Yue et al., 2016], and partitions the traces into k stages. All three metrics proved the effectiveness of our method.
5.2 Comparison of MXSP and DSPLNI
In this section, we further compare the interdiction results of our DSPLNI and the MXSP model in [Israeli and Wood, 2002]. Parameters, including the initial terminus of evader, the arcs' nominal length c, added integer delays d and the total interdiction resource R, remain the same between each two comparative cases. We also control the evader changing its initial terminus to a predefined one at a fixed time step.
Resource Allocated per step/R
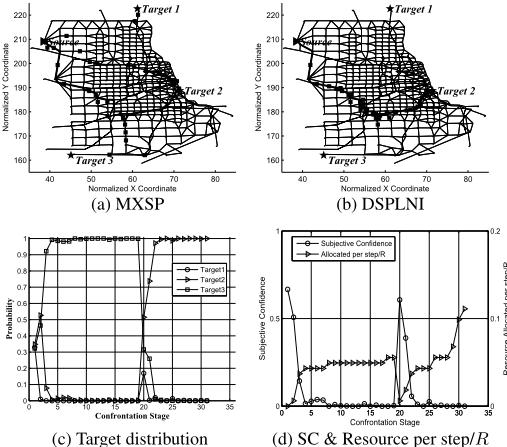
In our first test, there are three possible termini for evader and the initial target is set to be Target 3 and be changed to Target 2 when τ = 20. The detailed network interdiction in two SPNI models is shown in Figure 3, where the interdicted arcs are labeled in the middle by a solid square and the actual paths evaders selected are depicted by the bold lines. As is illustrated in Figure 3 (a), MXSP only deploys its resource according to the initial distribution of all possible termini once and for all. While using goal estimation in Figure 3 (c) and subjective confidence in Figure 3 (d), the behavior of the dynamic DSPLNI is much more concentrated and effective as in Figure 3 (b). It also shows the relationship between the resource allocation per step and the subjective confidence. During the early prediction when τ < 4 and the goal changes by approximately τ = 20, the subjective confidence is at a high position accompanied with low resource allocation as in Figure 3 (d).
The models are also tested under different resource constraints in two scenarios. In this test, we exclude the randomness within the agent action model. In both scenarios, the evader chose the first goal as Target 2, while in the second scenario, goals were changed from Target 2 to Target 3 at τ = 10. The base lengths of the maximum shortest path under no network interdiction in two scenarios are 1335 and 2525 respectively. Uncertainty still exists in DSPLNI model because of approximate goal inference. As shown in Figure
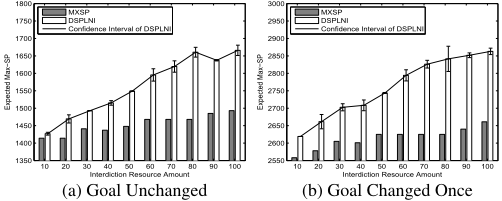
4, our method shows its uniqueness in tackling the multi-goal situations. This superiority is further consolidated when the evader changes its goal dynamically.
| Goal Unchanged | Goal Changed Once | |||
|---|---|---|---|---|
| Model | Exp L | v.s.% | Exp L | v.s.% |
| base length | 1383.8 | / | 2628.5 | / |
| DSPLNI | 1677.7 | 92.0 | 2903.6 | 95.0 |
| MXSP | 1521.8 | 2741.6 | ||
We further compare the performance of two models with action randomness. Compared to R=100 case in Figure 4, the expected length increases as we add in randomness. The tests are conducted for 100 times under two goal settings. When goals stay unchanged, approximately 92% of results in DSPLNI are better than the corresponding ones in MXSP. This number further increases to 95% under goal-changing situations. Besides, the expectations of the maximum shortest path of DSPLNI are larger than those of MXSP under both situations.
6 Conclusion
We have tested the ability of goal recognition in bridging the gap between observation and decision making in the shortest-path network interdiction problem. Experimental results show the effectiveness and accuracy of our methods both in goal recognition and dynamic network interdiction. The framework above from the goal recognition to decision making is simple but inspiring, especially in many real-time decision making tasks where little amount of historical data is available.
Acknowledgments
The work is sponsored by the National Natural Science Foundation of China under Grants No.61473300 and No.71571186.
@inproceedings{ijcai2017p625,
  title     = {Bridging the Gap between Observation and Decision Making: Goal Recognition and Flexible Resource Allocation in Dynamic Network Interdiction},
  author    = {Xu, Kai and Xiao, Kaiming and Yin, Quanjun and Zha, Yabing and Zhu, Cheng},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {4477--4483},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/625},
  url       = {https://doi.org/10.24963/ijcai.2017/625},
}
TY - CPAPER TI - Bridging the Gap between Observation and Decision Making: Goal Recognition and Flexible Resource Allocation in Dynamic Network Interdiction AU - Xu, Kai AU - Xiao, Kaiming AU - Yin, Quanjun AU - Zha, Yabing AU - Zhu, Cheng T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 4477 EP - 4483 DO - 10.24963/ijcai.2017/625 UR - https://doi.org/10.24963/ijcai.2017/625 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





