
Tensor Completion with Side Information: A Riemannian Manifold Approach
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 3539-3545.
https://doi.org/10.24963/ijcai.2017/495
Keywords
- Machine Learning: Learning Preferences or Rankings
- Machine Learning: Machine Learning
Abstract
By restricting the iterate on a nonlinear manifold, the recently proposed Riemannian optimization methods prove to be both efficient and effective in low rank tensor completion problems. However, existing methods fail to exploit the easily accessible side information, due to their format mismatch. Consequently, there is still room for improvement. To fill the gap, in this paper, a novel Riemannian model is proposed to tightly integrate the original model and the side information by overcoming their inconsistency. For this model, an efficient Riemannian conjugate gradient descent solver is devised based on a new metric that captures the curvature of the objective. Numerical experiments suggest that our method is more accurate than the state-of-the-art without compromising the efficiency.
- [Absil et al., 2009] P-A Absil, Robert Mahony, and Rodolphe Sepulchre. Optimization algorithms on matrix manifolds. Prince- ton University Press, 2009.
- [Acar et al., 2011] Evrim Acar, Tamara G. Kolda, and Daniel M. Dunlavy. All-at-once optimization for coupled matrix and tensor factorizations. In MLG'11, 2011.
- [Bell and Koren, 2007] Robert M Bell and Yehuda Koren. Lessons from the netflix prize challenge. Acm Sigkdd Explorations Newsletter, 9(2):75-79, 2007.
- [Beutel et al., 2014] Alex Beutel, Partha Pratim Talukdar, Abhi- manu Kumar, Christos Faloutsos, Evangelos E Papalexakis, and Eric P Xing. Flexifact: Scalable flexible factorization of coupled tensors on hadoop. In ICDM, pages 109-117. SIAM, 2014.
- [Chen et al., 2013] Shouyuan Chen, Michael R Lyu, Irwin King, and Zenglin Xu. Exact and stable recovery of pairwise interaction tensors. In NIPS, 2013.
- [Filipović and Jukić, 2015] Marko Filipović and Ante Jukić. Tucker factorization with missing data with application to low-n-rank tensor completion. Multidimensional systems and signal processing, 26(3):677-692, 2015.
- [Foster et al., 2006] David H Foster, Kinjiro Amano, Sérgio MC Nascimento, and Michael J Foster. Frequency of metamerism in natural scenes. Journal of the Optical Society ofAmerica A, 23:2359-2372, 2006.
- [Jain and Oh, 2014] Prateek Jain and Sewoong Oh. Provable tensor factorization with missing data. In Advances in Neural Informa- tion Processing Systems, pages 1431-1439, 2014.
- [Kasai and Mishra, 2016] Hiroyuki Kasai and Bamdev Mishra. Low-rank tensor completion: a riemannian manifold precondi- tioning approach. In ICML, 2016.
- [Kolda and Bader, 2009] Tamara G Kolda and Brett W Bader. Ten- sor decompositions and applications. SIAM review, 51(3):455- 500, 2009.
- [Kressner et al., 2014] Daniel Kressner, Michael Steinlechner, and Bart Vandereycken. Low-rank tensor completion by rieman- nian optimization. BIT Numerical Mathematics, 54(2):447-468, 2014.
- [Liu et al., 2013] Ji Liu, Przemyslaw Musialski, Peter Wonka, and Jieping Ye. Tensor completion for estimating missing values in visual data. IEEE Transactions on Pattern Analysis and Machine Intelligence, 35(1):208-220, 2013.
- [Liu et al., 2014] Yuanyuan Liu, Fanhua Shang, Hong Cheng, James Cheng, and Hanghang Tong. Factor matrix trace norm minimization for low-rank tensor completion. In Proceedings of the 2014 SIAM International Conference on Data Mining, pages 866-874. SIAM, 2014.
- [Liu et al., 2015] Qiang Liu, Shu Wu, and Liang Wang. Cot: Con- textual operating tensor for context-aware recommender systems. In AAAI, pages 203-209, 2015.
- [Liu et al., 2016] Yuanyuan Liu, Fanhua Shang, Wei Fan, James Cheng, and Hong Cheng. Generalized higher order orthogonal iteration for tensor learning and decomposition. IEEE trans- actions on neural networks and learning systems, 27(12):2551- 2563, 2016.
- [Mishra and Sepulchre, 2014] Bamdev Mishra and Rodolphe Sepulchre. R3mc: A riemannian three-factor algorithm for low-rank matrix completion. In Decision and Control (CDC), 2014 IEEE 53rd Annual Conference on, pages 1137-1142. IEEE, 2014.
- [Mishra and Sepulchre, 2016] Bamdev Mishra and Rodolphe Sepulchre. Riemannian preconditioning. SIAM Journal on Optimization, 26(1):635-660, 2016.
- [Mishra, 2014] Bamdev Mishra. A Riemannian approach to large- scale constrained least-squares with symmetries. PhD thesis, Universite de Liege, Liege, Belgique, 2014.
- [Narita et al., 2011] Atsuhiro Narita, Kohei Hayashi, Ryota Tomioka, and Hisashi Kashima. Tensor factorization using auxiliary information. In Joint European Conference on Ma- chine Learning and Knowledge Discovery in Databases, pages 501-516. Springer, 2011.
- [Rai et al., 2015] Piyush Rai, Yingjian Wang, and Lawrence Carin. Leveraging features and networks for probabilistic tensor decom- position. In AAAI, pages 2942-2948, 2015.
- [Romera-Paredes and Pontil, 2013] Bernardino Romera-Paredes and Massimiliano Pontil. A new convex relaxation for tensor completion. In Advances in Neural Information Processing Systems, pages 2967-2975, 2013.
- [Romera-Paredes et al., 2013] Bernardino Romera-Paredes, Hane Aung, Nadia Bianchi-Berthouze, and Massimiliano Pontil. Mul- tilinear multitask learning. In Proceedings of the 30th Inter- national Conference on Machine Learning, pages 1444-1452, 2013.
- [Sato and Iwai, 2015] Hiroyuki Sato and Toshihiro Iwai. A new, globally convergent riemannian conjugate gradient method. Op- timization, 64(4):1011-1031, 2015.
- [Smith et al., 2016] Shaden Smith, Jongsoo Park, and George Karypis. An exploration of optimization algorithms for high performance tensor completion. In Proceedings of the 2016 ACM/IEEE conference on Supercomputing, 2016.
- [Wang et al., 2015] Yichen Wang, Robert Chen, Joydeep Ghosh, Joshua C Denny, Abel Kho, You Chen, Bradley A Malin, and Jimeng Sun. Rubik: Knowledge guided tensor factorization and completion for health data analytics. In Proceedings of the 21th ACM SIGKDD International Conference on Knowledge Discov- ery and Data Mining, pages 1265-1274. ACM, 2015.
- [Xu et al., 2015] Yangyang Xu, Ruru Hao, Wotao Yin, and Zhixun Su. Parallel matrix factorization for low-rank tensor completion. Inverse Problems & Imaging, 9(2), 2015.
- [Ye and Lim, 2014] Ke Ye and Lek-Heng Lim. Distance be- tween subspaces of different dimensions. arXiv preprint arXiv:1407.0900, 2014.
- [Yuan and Zhang, 2015] Ming Yuan and Cun-Hui Zhang. On ten- sor completion via nuclear norm minimization. Foundations of Computational Mathematics, pages 1-38, 2015.
- [Zhang and Aeron, 2016] Zemin Zhang and Shuchin Aeron. Exact tensor completion using t-svd. IEEE Transactions on Signal Pro- cessing, 2016.
- [Zhang et al., 2014] Xiaoqin Zhang, Zhengyuan Zhou, Di Wang, and Yi Ma. Hybrid singular value thresholding for tensor com- pletion. In AAAI, pages 1362-1368, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Low Rank Tensor Completion (LRTC) problem, which aims to recover a tensor from its linear measurements, arises naturally in many artificial intelligence applications. In hyperspectral image inpainting, LRTC is applied to interpolate the unknown pixels based on the partial observation [Xu et al., 2015]. In recommendation tasks, LRTChelps users find interesting items [Liu et al., 2015]. In computational phenotyping, one adopts LRTC to discovery phenotypes in heterogeneous electronic health records [Wang et al., 2015].
Euclidean Models: LRTC can be formulated by a variety of optimization models over the Euclidean space. Amongst them, convex models that encapsulate LRTC as a regression problem penalized by a tensor nuclear norm are the most popular and well-understood [Romera-Paredes and Pontil, 2013; Zhang et al., 2014]. Though most of them have sound theoretical guarantees [Zhang and Aeron, 2016; Chen et al., 2013; Yuan and Zhang, 2015], in general, their solvers are ill-suited for large tensors because these procedures involve Singular Value Decomposition (SVD) of huge matrices per iteration [Liu et al., 2013]. Another class of Euclidean models is formulated as the decomposition problem that factorizes a low rank tensor into small factors [Jain and Oh, 2014;
∗Corresponding author
Filipovi´c and Juki´c, 2015; Xu et al., 2015]. Many solvers for such decomposition based model have been proposed, and low per-iteration computational cost is illustrated [Beutel et al., 2014; Liu et al., 2014; Smith et al., 2016].
Riemannian Models: LRTC can also be modeled by optimization constrained on Riemannian manifolds [Kressner et al., 2014; Kasai and Mishra, 2016], which is easily handled by many manifold based solvers [Absil et al., 2009]. Empirical comparison has shown that Riemannian solvers use significantly less CPU time to recover the underlying tensor in contrast to the Euclidean solvers [Kasai and Mishra, 2016]. The main reason resides in that they avoid SVD of huge matrices by explicitly exploiting the geometrical structure of LRTC, which makes them more suitable for massive problem.
Of all the Riemanian models, two search spaces, fix multilinear rank manifold [Kressner et al., 2014] and Tucker manifold [Kasai and Mishra, 2016], are usually employed. The former is a sub-manifold of Euclidean space, and the latter is a quotient manifold induced by the Tucker decomposition. Generally, quotient manifold based solvers have higher convergence rates because it is usually easier to design a pre-conditioner for them [Kasai and Mishra, 2016; Mishra and Sepulchre, 2016].
Side Information: In the Euclidean models of LRTC, side information has been proved to be helpful in improving the accuracy [Narita et al., 2011; Acar et al., 2011; Beutel et al., 2014]. One common form of the side information is the feature matrix, which measures the statistical properties of tensor modes [Kolda and Bader, 2009]. For example, in Netflix tasks, feature matrix can be built from the demography of users [Bell and Koren, 2007]. Another form is the similarity matrix, which quantifies the resemblance between two entities of a tensor mode. For instance, the social network generates the similarity matrix by utilizing the correspondence between users [Rai et al., 2015]. In practice, these two matrices can be transformed to each other, and we only consider the feature matrix case.
However, as far as we know, side information has not been incorporated in any Riemannian model for LRTC. The first difficulty lies in the model design. Fusing the side information into the Riemannian model inevitably compromises the integrity of the low rank tensor due to the compactness of the manifold. The second difficulty results from the solver design. Incorporating the side information may aggravate the ill-conditioning of LRTC problem and degenerates the convergence significantly.
Contributions: To address these difficulties, a novel Riemannian LRTC method is proposed from the perspective of both model and solver designs. By exploring the relation between the subspace spanned by the tensor fibers and the column space of the feature matrix, we explicitly integrate the side information in a compact way. Meanwhile, a first order solver is devised under the manifold optimization framework. To ease the ill-conditioning, we design a novel metric based on an approximated Hessian of the cost function. The metric implicitly induce an adaptive preconditioner for our solver. Empirical studies illustrate that our method achieves much more accurate solutions within comparable processing time than the state-of-the-art.
2 Notations and Preliminaries
In this paper, we only focus on the 3rd order tensor, but generalizing our method to higher order is straight forward. We use the notation X ∈ Rn×m to denote a matrix, and the notation X ∈ Rn1×···×nd to denote a d-th order tensor. We also denote by X(i1, · · · , id) the element in position (i1, · · · , id) of X. For many cases, we use abbreviation like {Oi}3i=1 to denote the sequence O1,O2,O3.
Mode-k Fiber and matricization: A fiber of a tensor is obtained by varying one index while fixing the others, i.e. X(i1, · · · , ik-1, :, ik+1, · · · , id) is the mode-k fiber of a d-th order tensor X. A mode-k matricization X(k) ∈ Rnk×(n1···nk-1nk+1···nd) of a tensor X is obtained by arranging the mode-n fibers of X so that each of them is a column of X(k) [Kolda and Bader, 2009] The mode-k product of tensor X and matrix A is denoted by X ×k A, whose mode-k matricization can be expressed as (X ×k A)(k) = AX(k). Inner product and norm: The inner product of two tensors with the same size is defined by 〈X,Y〉 = ∑i1,··· ,id X(i1, · · · , id)Y(i1, · · · , id). The Frobenius norm of a tensor X is defined by ‖X‖F = √〈X,X〉.
Multi-linear rank and Tucker decomposition: The multilinear rank rankvec (X) of a tensor X ∈ Rn1×n2×n3 is defined as a vector (rank(X(1)), rank(X(2)), rank(X(3))). If rankvec (X) = (r1, r2, r3), tucker decomposition factorizes X into a small core tensor G ∈ Rr1×r2×r3 and three matrices Ui ∈ Rni×ri with orthogonal columns, that is X = G×3i=1 Ui. Note that, the tucker decomposition of a tensor is not unique. In fact, if X = G ×3i=1 Ui, we can easily obtain X =H×3i=1 Vi, withH= G×3i=1 O⊤i , Vi =UiOi, where Oi ∈ Rri×ri is any orthogonal matrix. Thus, we obtain the equivalent class
We denote [G, {Ui}3i=1 ] by [X], when X = G ×3i=1 Ui. Usually, [X] is called the Tucker representation of X, while X is call the tensor representation of [X]. We also use X to denote a specific decomposition of X , additionally X ∈ [X ].
2.1 Search Space of RiemannianModels
The Tucker manifold that we used in our Riemannian model is a quotient manifold induced by the Tucker decomposition.
In order to lay the ground for Tucker manifold, we first describe its counterpart, the fix multi-rank manifold, which will be helpful in understanding the whole derivation.
A fixed multi-linear rank manifold Fr consists of tensors with the same fixed multi-linear rank. Specifically
To define the Tucker manifold, we first define a total space
in which S(ri, ni) is the Stiefel manifold of ni × ri matrices with orthogonal columns. Then, we can depict the Tucker manifold of multi-linear rank r as follows.
The Tucker manifold is a quotient manifold of the total space (1). We use the abstract quotient manifold, rather than the concrete total space, as search space because the nonuniqueness of the Tucker decomposition is undesirable for optimization. Note that such non-uniqueness will introduce more local optima into the minimization. The relation of manifold Fr and Mr/ ∼ is characterized as follows.
Proposition 1. The quotient manifold Mr/ ∼ is diffeomorphic to the fix multi-linear rank manifold Fr, with diffeomorphism ρ(·) from Fr to Mr/ ∼ defined by ρ(X) = [G, {Ui}3i=1] where [G, {Ui}3i=1] is the tucker representation of X.
This proposition says that each tensor X ∈ Fr can be represented by a unique equivalent class [G, {Ui}3i=1 ] ∈ M/ ∼ and vice-versa.
2.2 Vanilla Riemannian Tensor Completion
The purest incarnation of Riemannian tensor completion model is the Riemannian model over the fix multi-linear rank manifold. Let R ∈ Rn1×n2×n3 be a partially observed tensor. Let Ω be the set which contains the indices of observed entries. The model can be expressed as:
with PΩ maps X to the sparsified tensor PΩ(X), where PΩ(X)(i1, i2, i3) = X(i1, i2, i3) if (i1, i2, i3) ∈ Ω, and PΩ(X)(i1, i2, i3) = 0 otherwise.
Another popular model, Tucker model, is based on the quotient manifold Mr/ ∼, which can be expressed as:
with ρ defined in Prop. 1.
Note that since the dawn of Riemannian framework for LRTC, a quandary exists: on one hand, sparse measurement limits the capacity of the solution; on the other hand, rich side information can not be incorporated into this framework. In many artificial intelligence applications, demands for high accuracy further exacerbates such dilemma.
3 RiemannianModel with Side Information
We focus on the case that the side information is encoded in feature matrices Pi ∈ Rni×ki . Suppose R ∈ Fr has tucker factors (G, {Ui}3i=1 ).Without loss of generality, we assume that ki ≥ ri and Pi has orthogonal columns.
In the ideal case, we assume that
Such relation means that the feature matrices contain all the information in the latent space of the underlying tensor. Equivalently, there exists a matrix Wi such that Ui = PiWi. However, in practice, due to the existence of noise, one can only expect such relation to hold approximately, i.e. Ui ≈ PiWi. Incorporating such relation to a tensor completion model via penalization, we have the following formulation
where L(G, {Ui}3i=1 ) = ‖PΩ(G ×3i=1 Ui -R)‖2F /2. Fixing G and Ui, with respect toWi, (6) has a close form solution
Since minx,y l(x, y) = minx l(x, y(x)) where y(x) = argminy l(x, y), one can substitute (7) into the above problem and obtain the following equivalence
Although the cost function is already smooth over the total space Mr, due to its invariance over the equivalent class [G, {Ui}3i=1 ], there can be infinite local optima, which is extremely undesirable. Indeed, if (G, {Ui}3i=1 ) is a local optimal of the objective, then so is every point in the infinite set [G, {Ui}3i=1 ]. One way to reduce the number of local optima is to mathematically treated the entire set [G, {Ui}3i=1 ] as a point. Consequently, we redefine the cost by ˜ f([G, {Ui}3i=1 ]) = f(G, {Ui}3i=1 ) and obtain the following Remainnian optimization problem over the quotient manifold Mr/ ∼:min
Remark 1. In Riemannian optimization literature, problem (8) is called the lifted representation of problem (9) over the total space [Absil et al., 2009]. This model is closely related to the Laplace regularization model [Narita et al., 2011]. Concretely, they share the same form:
The difference lies in that Li is a projection matrix in our case, while, in the Laplace regularization model, Li is a Laplacian matrix.
Remark 2. Since each [X] ∈ Mr/ ∼ has a unique tensor representation in X ∈ Fr, we show that the abstract model (9) can be represented as a concrete model over the manifold Fr. Specifically, the following Proposition interprets the proposed model as an optimization problem with a regularizer that encourages the mode-i space of the estimated tensor close to span(Pi).
Proposition 2. if [X] is a critical point of problem (9) then its tensor representation X is a critical point of the following problem.
where dist(·, ·) is the Chodal distance [Ye and Lim, 2014] between two subspaces. And vice versa.
4 Riemannian Conjugate Gradient Descent
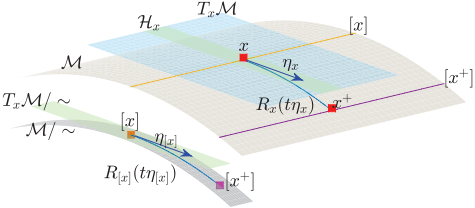
We depict the optimization framework for quotient manifolds in Fig. 1. Under this framework, we solve the proposed problem (9) by Riemannian Conjugate Gradient descent (CG). With the details specified later, we list our CG solver for problem (9) in Alg. 1, where the CG direction is composed in the Polak-Ribiere+ manner with the momentum weight β(k) computed by Flecher-Reeves formula [Absil et al., 2009], and Tk(·) is the projector of horizontal space HX (k) . The convergence property of CGSI (Alg. 1) to a stationary point follows the general analysis of CG method [Sato and Iwai, 2015]. To represent CGSI in concrete tensor formulations, four items must be specified: the Riemannian metric 〈·, ·〉X , the Riemannian gradient gradf(X), the retraction RX (·), and the projector onto horizontal space TX .
4.1 Metric Tuning
Riemannian metric 〈·, ·〉X of Mr is an inner product defined over each tangent space TX Mr. A high-quality Riemannian solver for a quotient manifold should be equipped with
Algorithm 1 CGSI: a Riemannian CG method
| Require: Initializer X (0) = (G(0) , {U(0) i }3i=1) and tolerance ϵ | |
| 1: 2: | k = 0; η(-1) = (0, {0}3i=1); |
| 3: | |
| repeat | |
| 4: | compute current Riemannian gradient ξ(k) = gradf(X (k) ); |
| 5: | compose CG direction η(k) = -ξ(k) +β(k)Tk(η(k-1) ); choose a step size tk > 0; |
| 6: | update by retraction X (k+1) = ); |
| 7: | RX (k) (tkη(k) |
| 8: | k = k +1; |
| 9: | until 〈ξ(k-1) , ξ(k-1) 〉X (k-1) ≤ ϵ; |
| 10: | return X (k) . |
a well-tuned metric, because (1) the metric determines the differential structure of the quotient manifold, and more importantly (2) it implicitly endows the solver with a preconditioner, which heavily affects the convergent rate [Mishra and Sepulchre, 2014; Mishra, 2014].
From the perspective of preconditioning, it seems that the best candidate is the Newton metric 〈η, ξ〉X = D2 f(X)[η, ξ]∀η, ξ ∈ TX Mr where D2 f(X) is the second order differential of the cost function. However, under such metric, computing the search direction involves solving a large system of linear equations, which precludes the Newton metric from the application to huge datasets. Therefore, we propose to use the following alternative:
where g(X) is a scaled approximation to the original cost function, and D2 b g(X) is the block approximation of its second derivative, specifically g(X) ≜ 12 ‖G ×31 Ui -R‖2F + ∑3i=1 αiN 2 trace(UTi (Ii -PiPTi )Ui) with N = n1n2n3.
Our metric is more scalable than Newton metric. The following Proposition indicates that the scale gradient induced by this metric can be computed with O(∑3i=1 nikiri + r3 i ) additional operations.
Proposition 3. Suppose that the cost function f(·) has Euclidean gradient ∇f(X) = (∇Gf, {∇Ui f}3i=1). Then its scaled gradient ˜∇f(X) under the metric (11) can be computed by:
The final proposition suggests that the proposed metric makes the representation of solvers in the total space possible.
Proposition 4. The quotient manifoldMr/ ∼ admits a structure of Riemannian quotient manifold, if Mr is endowed with the Riemannian metric defined in (11).
| Projector | Formulation |
|---|---|
| ΨX (ZG , {Zi}3i=1 ) projection of an ambient vector (ZG , {Zi}3i=1 ) onto TX Mr | (ZG, {Zi - ViSiG-1 i -WiSiG-1 αi }3i=1 ) where Si is the solution of : ⎧⎪⎨⎪⎩ sym(VT i ViSiG-1 i -U⊤i Zi) = - sym(WT i WiSiG-1 αi ) Si = S⊤i |
| ΠX (ηX ) Projection of a tangent vector ηX of total space onto HX | (ηG + ∑ 1≤i≤3 G ×i Ωi, {ηi - UiΩi}3i=1 ) where (Ω1,Ω2,Ω3) is the solution of ⎧⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎨⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎪⎩ skw(VT i ViΩiGi +GiΩi +W⊤ i WiΩiGαi ) -G(i)(Iji ⊗ Ωki )G(i)⊤ -G(i)(Ωji ⊗ Iki )G(i)⊤ = skw(V⊤ i ηiGi +W⊤ i ηiGαi ) + skw(G(i)(ηG )⊤(i) ) Ω⊤i = -Ωi∀i ∈ {1, 2, 3} |
4.2 Other Optimization Related Items
Projectors: To derive the optimization related items, two orthogonal projectors, ΨX (·) and ΠX (·), are required. The former projects a vector onto the tangent space TX Mr, and the latter is a projector from the tangent space onto the horizontal space HX . The orthogonality of both projectors is measured by the metric (11). For lack of space, the mathematical derivation is deferred to a long version of this paper.
Riemannian Gradient: According to [Absil et al., 2009], the Riemannian gradient can be computed by projecting the scaled gradient onto tangent space, specifically
Retraction: We use the retraction defined by
where uf(·) extracts the orthogonal component from a matrix. Such retraction is proposed by [Kasai and Mishra, 2016]. In the long version of this paper, we give rigorous analysis to prove that the above retraction is compatible with the proposed metric.
5 Experiments
We validate the effectiveness of the proposed solver CGSI by comparing it with the state-of-the-art. The baseline can be partitioned into three classes. The first class contains Riemannian solvers including GeomCG [Kressner et al., 2014], FTC [Kasai and Mishra, 2016], and gHOI [Liu et al., 2016]. The second class consists of Euclidean solvers that take no account of the side information, including AltMin [RomeraParedes et al., 2013] and HalRTC [Liu et al., 2013]. The third class comprises of two methods that incorporate side information, including RUBIK [Wang et al., 2015] and TFAI
| AltMin | FTC | GeomCG | gHOI | HalRTC | RUBIK | TFAI | CGSI | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| data | OS | NRSE | Time(s) | NRSE | Time | NRSE | Time | NRSE | Time | NRSE | Time | NRSE | Time | NRSE | Time | NRSE | Time |
| S1 | 3 5 7 9 | 0.161 0.156 0.156 0.156 | 183 0.091 307 0.067 429 0.060 550 0.046 | 52 76 100 126 | 0.113 0.077 0.056 0.044 | 61 93 124 151 | 0.115 0.103 0.092 0.078 | 65 109 152 195 | 0.080 0.078 0.077 0.077 | 177 177 177 178 | 0.086 0.085 0.085 0.085 | 197 194 195 198 | 0.161 0.159 0.159 0.156 | 164 273 382 479 | 0.062 0.040 0.039 0.036 | 77 100 110 126 | |
| S2 | 3 5 7 9 | 0.173 0.166 0.166 0.166 | 183 0.093 306 0.082 428 0.073 578 0.062 | 50 76 101 125 | 0.114 0.076 0.064 0.056 | 61 92 123 154 | 0.125 0.100 0.091 0.073 | 65 103 152 197 | 0.066 0.066 0.057 0.057 | 173 171 172 171 | 0.061 0.061 0.061 0.060 | 197 196 197 197 | 0.173 0.171 0.169 0.169 | 165 203 386 433 | 0.048 0.043 0.040 0.038 | 83 96 110 130 | |
| S3 | 3 5 7 9 | 0.033 0.033 0.033 0.033 | 226 0.041 346 0.030 486 0.023 587 0.019 | 68 99 124 156 | 0.044 0.029 0.021 0.021 | 181 251 389 386 | 0.043 0.037 0.033 0.031 | 187 308 177 491 | 0.034 0.033 0.031 0.029 | 174 177 177 172 | 0.062 0.061 0.059 0.034 | 189 185 187 189 | 0.063 0.062 0.057 0.033 | 131 209 210 229 | 0.025 0.021 0.018 0.017 | 83 108 131 143 | |
| S4 | 3 5 7 9 | 0.033 0.033 0.033 0.033 | 238 359 486 600 | 0.031 0.015 0.012 0.012 | 78 0.036 108 0.015 128 0.012 170 0.012 | 181 254 391 398 | 0.038 0.031 0.021 0.018 | 193 293 177 492 | 0.047 0.032 0.029 0.026 | 172 171 177 177 | 0.034 0.037 0.027 0.024 | 182 183 180 192 | 0.033 0.033 0.033 0.033 | 155 247 181 231 | 0.012 0.012 0.011 0.010 | 105 118 131 144 | |
| S5 | 3 5 7 9 | 0.059 0.059 0.059 0.059 | 236 362 483 603 | 0.051 0.041 0.034 0.028 | 75 0.077 104 0.051 137 0.037 166 0.029 | 180 254 325 400 | 0.169 0.113 0.089 0.065 | 187 289 398 494 | 0.086 0.076 0.047 0.042 | 169 171 173 173 | 0.126 0.059 0.054 0.058 | 180 183 190 192 | 0.062 0.061 0.061 0.061 | 99 128 181 229 | 0.024 0.022 0.021 0.021 | 104 114 128 142 | |
| S6 | 3 5 7 9 | 0.090 0.090 0.090 0.090 | 237 356 489 600 | 0.067 76 0.039 105 0.039 130 0.039 165 | 0.057 0.040 0.040 0.040 | 181 251 325 396 | 0.132 0.095 0.095 0.095 | 189 298 394 501 | 0.095 0.083 0.083 0.083 | 177 177 178 178 | 0.090 0.081 0.081 0.081 | 180 180 181 183 | 0.091 0.091 0.091 0.091 | 170 213 300 383 | 0.036 0.034 0.034 0.034 | 107 119 136 143 | |
| S7 | 3 5 7 9 | 0.071 0.072 0.072 0.072 | 245 0.073 377 0.034 581 0.028 603 0.027 | 82 102 161 170 | 0.069 0.032 0.028 0.027 | 181 225 336 400 | 0.075 0.064 0.052 0.041 | 193 293 452 494 | 0.077 0.069 0.062 0.057 | 172 172 171 173 | 0.069 0.067 0.064 0.058 | 181 180 181 183 | 0.072 0.072 0.072 0.072 | 165 203 302 183 | 0.031 0.028 0.026 0.026 | 119 158 157 189 | |
| S8 | 3 5 7 9 | 0.039 0.039 0.039 0.039 | 236 0.030 354 0.018 701 0.013 853 0.012 | 74 107 102 112 | 0.042 0.019 0.013 0.012 | 181 247 381 502 | 0.050 0.038 0.030 0.026 | 187 293 234 369 | 0.071 0.061 0.031 0.027 | 174 174 181 175 | 0.034 0.040 0.030 0.031 | 179 182 182 183 | 0.040 0.045 0.060 0.039 | 131 213 363 502 | 0.013 0.012 0.011 0.011 | 103 114 169 180 | |
[Narita et al., 2011]. All the experiments are performed in Matlab on the same machine with 3.0 GHz Intel E5-2690 CPU and 128GB RAM.
5.1 Hyperspectral Image Inpainting
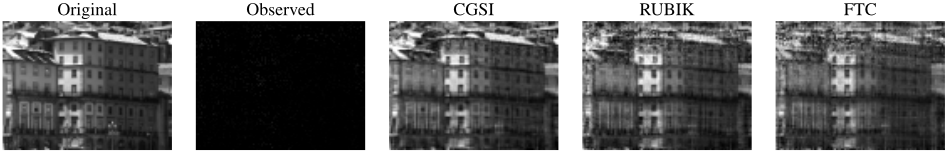
A hyperspectral image is a tensor whose the slices are photographs of the same scene under different wavelets. We adopt the dataset provided in [Foster et al., 2006] which contains images about eight different rural scenes taken under 33 various wavelets. To make all methods in our baseline applicable to the completion problem, we resize each hyperspectral images to a small dimension such that n1 = 306, n2 = 402, and n3 = 33. Empirically, we treat these graphs as tensors of rank r = (30, 30, 6). The observed pixels, or the training set, are sampled from the tensors uniformly at random. And the sample size is set to |Ω| = OS×p in which OS is so-called Over-Sampling ratio and p = ∑3i=1 (niri - r2 i ) + r1r2r3 is the number of free parameters in a size n tensor with rank r. In addition to the observed entries, the mode-1 feature matrix is constructed by extracting the top(r1 + 10) singular vectors from a matrix of size n1 × 10r1 whose columns are sampled from the mode-1 fibers of the hyperspectral graphs. The recovery accuracy is measured by Normalized Root mean Square Error (NRSE) [Kressner et al., 2014]. All the compared methods are terminated when the training NRSE is less than 0.003 or iterate more than 300 epochs. We report the NRSE and CPU time of the compared methods in Tab. 2. From the table, we can see that the proposed method has much higher accuracy than the other solvers in our baseline. The empirical results also indicate that the sparser the observed pixels are the higher CGSI's improvement is on the recovery accuracy. The visual results of the 27th slices of recovered hyperspectral images of scene 7 are illustrated in Fig. 2.
5.2 Recommender System
In recommendation tasks, two datasets are considered: MovieLens 10M (ML10M) and MovieLens 20M (ML20M). Both datasets contain the rating history of users for items at specific moments. For both datasets, we partition the samples into 731 slices in terms of time stamp. Those slices have the identical time intervals. Accordingly, the completion tasks for the two datasets are of sizes 71567 × 10681 × 731 and 138493×26744×731 respectively. In addition to the rating history, both datasets contain two extra files: one describes the genres of each movie, and the other contains tags of each movie. We construct a corpus that contains the text description of all movies from the genres descriptions and all the tags. The feature matrix is extracted from the above corpus by the latent semantic analysis (LSA) method. The processing is efficient since LSA is implemented via randomized SVD.
| AltMin | FTC | GeomCG | gHOI | TFAI | CGSI | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| dataset | rank | RMSE | Time | RMSE | Time | RMSE | Time | RMSE | Time | RMSE | Time | RMSE | Time |
| ML10M | (4,4,4) (6,6,6) (8,8,8) (10,10,10) | 0.982 0.968 1.010 1.147 | 924 1830 3123 4963 | 0.824 0.814 0.822 0.824 | 236 535 928 1631 | 0.835 0.826 0.833 0.843 | 307 679 1135 2220 | 1.076 1.262 1.062 1.094 | 467 1035 1734 2788 | 1.011 0.9948 0.993 0.992 | 426 942 1617 2522 | 0.823 0.814 0.810 0.807 | 178 434 754 1067 |
| ML20M | (4,4,4) (6,6,6) (8,8,8) (10,10,10) | 1.061 1.089 1.092 1.092 | 690 3451 5890 9418 | 0.822 0.808 0.812 0.818 | 466 982 1725 3161 | 0.829 0.822 0.828 0.834 | 601 1309 2271 4308 | 1.050 1.057 1.045 1.054 | 918 1869 3363 5795 | 1.029 1.008 1.004 1.025 | 797 1644 3144 5394 | 0.818 0.805 0.804 0.799 | 363 1107 1739 2813 |
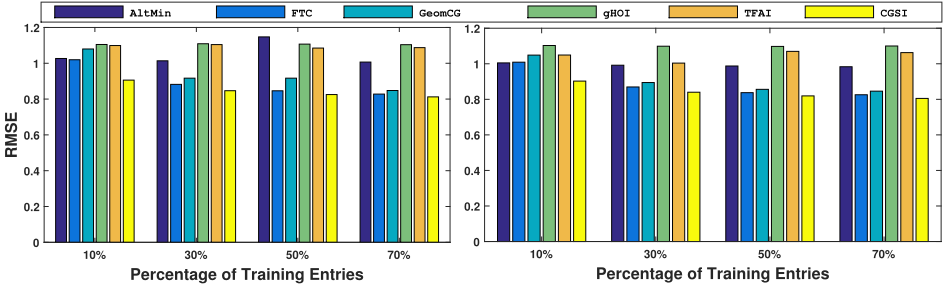
Various empirical studies are conducted to validate the performance of the proposed method. In the first scenario, we record the CPU time and the Root Mean Square Error (RMSE) outputted by the compared algorithms under different choices of multi-linear rank. In this scenario, for both datasets, 80% samples are chosen as training set, and the rest are left for testing. The results are listed in Tab. 3, which suggests that the proposed method outperforms all other solvers in terms of accuracy. For ML10M, our method uses significantly less CPU time than its competitors. In Fig. 3, we report another scenario, in which the percentage of training samples are varied from 10% to 70% and the rank parameter is fixed to (10, 10, 10). Experimental results in this figure indicate that our method has the lowest RMSE.
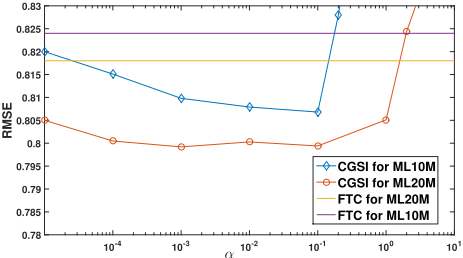
To show the impact of parameter α on the performance of our method, we depict the relation between RMSE and α in Fig. 4, where the rank parameter is set to (10, 10, 10), and percentage of training samples is set to 80%. From this Figure we can see that our method has higher accuracy than the vanilla Riemannian model's solver FTC for a wide range of parameter choices.
6 Conclusion
In this paper, we exploit the side information to improve the accuracy of Riemannian tensor completion. A novel Riemannian model is proposed. To solve the model efficiently, we design a new Riemannian metric that implicitly induce an adaptive preconditioner for the solving procedure. Then, we devise a Riemannian conjugate gradient descent method using the well-tuned metric. Empirical results show that our solver outperforms the state-of-the-art.
Acknowledgments
This work is partially supported by National Natural Science Foundation of China (Grant No: 61472347, 61672376, and 61672449).
@inproceedings{ijcai2017p495,
  title     = {Tensor Completion with Side Information: A Riemannian Manifold Approach},
  author    = {Zhou, Tengfei and Qian, Hui and Shen, Zebang and Zhang, Chao and Xu, Congfu},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {3539--3545},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/495},
  url       = {https://doi.org/10.24963/ijcai.2017/495},
}
TY - CPAPER TI - Tensor Completion with Side Information: A Riemannian Manifold Approach AU - Zhou, Tengfei AU - Qian, Hui AU - Shen, Zebang AU - Zhang, Chao AU - Xu, Congfu T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 3539 EP - 3545 DO - 10.24963/ijcai.2017/495 UR - https://doi.org/10.24963/ijcai.2017/495 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





