
Weighted Double Q-learning
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 3455-3461.
https://doi.org/10.24963/ijcai.2017/483
Keywords
- Uncertainty in AI: Markov Decision Processes
- Machine Learning: Reinforcement Learning
Abstract
Q-learning is a popular reinforcement learning algorithm, but it can perform poorly in stochastic environments due to overestimating action values. Overestimation is due to the use of a single estimator that uses the maximum action value as an approximation for the maximum expected action value. To avoid overestimation in Q-learning, the double Q-learning algorithm was recently proposed, which uses the double estimator method. It uses two estimators from independent sets of experiences, with one estimator determining the maximizing action and the other providing the estimate of its value. Double Q-learning sometimes underestimates the action values. This paper introduces a weighted double Q-learning algorithm, which is based on the construction of the weighted double estimator, with the goal of balancing between the overestimation in the single estimator and the underestimation in the double estimator. Empirically, the new algorithm is shown to perform well on several MDP problems.
- [Bellman, 1957] Richard Bellman. Dynamic Programming. Princeton University Press, 1957.
- [Bertsekas, 2007] Dimitri P. Bertsekas. Dynamic Program- ming and Optimal Control. Athena Scientific, Belmont, MA, 2007.
- [Brafman and Tennenholtz, 2001] Ronen I. Brafman and Moshe Tennenholtz. R-max -a general polynomial time algorithm for near-optimal reinforcement learning. In In- ternational Joint Conference on Artificial Intelligence (IJ- CAI), pages 953-958, 2001. IJCAI
- [D'Eramo et al., 2016] Carlo D'Eramo, Alessandro Nuara, and Marcello Restelli. Estimating the maximum expect- ed value through Gaussian approximation. In Internation- al Conference on Machine Learning (ICML), pages 1032- 1040, 2016.
- [Ernst et al., 2005] Damien Ernst, Pierre Geurts, and Louis Wehenkel. Tree-based batch mode reinforcement learn- ing. Journal of Machine Learning Research, 6(1):503- 556, 2005.
- [Kearns and Singh, 1999] Michael J. Kearns and Satinder P. Singh. Finite-sample convergence rates for Q-learning and indirect algorithms. In Advances in Neural Information Processing Systems (NIPS), pages 996-1002, 1999.
- [Kochenderfer, 2015] Mykel J. Kochenderfer. Decision Making Under Uncertainty: Theory and Application. MIT Press, 2015.
- [LeCun et al., 2015] Yann LeCun, Yoshua Bengio, and Ge- offrey Hinton. Deep learning. Nature, 521:436-444, 2015.
- [Lee and Powell, 2012] Donghun Lee and Warren B. Pow- ell. An intelligent battery controller using bias-corrected Q-learning. In AAAI Conference on Artificial Intelligence (AAAI), pages 316-322, 2012.
- [Lee et al., 2013] Donghun Lee, Boris Defourny, and War- ren B. Powell. Bias-corrected Q-learning to control max- operator bias in Q-learning. In IEEE Symposium on Adap- tive Dynamic Programming and Reinforcement Learning (ADPRL), pages 93-99, 2013.
- [Littman, 2015] Michael L. Littman. Reinforcement learn- ing improves behaviour from evaluative feedback. Nature, 521:445-451, 2015.
- [Mnih et al., 2015] Volodymyr Mnih, Koray Kavukcuoglu, David Silver, Joel Veness Andrei A. Rusu, Marc G. Belle- mare, Alex Graves, Martin Riedmiller, Andreas K. Fid- jeland, Georg Ostrovski, Stig Petersen, Charles Beattie, Amir Sadik, Ioannis Antonoglou, Helen King, Dharshan Kumaran, Daan Wierstra, Shane Legg, and Demis Has- sabis. Human-level control through deep reinforcement learning. Nature, 518:529-533, 2015.
- [Strehl et al., 2006] Alexander L. Strehl, Lihong Li, Eric Wiewiora, John Langford, and Michael L. Littman. PAC model-free reinforcement learning. In International Con- ference on Machine Learning (ICML), pages 881-888, 2006.
- [Sutton and Barto, 1998] Richard S. Sutton and Andrew G. Barto. Reinforcement Learning: An Introduction. MIT Press, Cambridge, MA, 1998.
- [van Hasselt et al., 2016] Hado van Hasselt, Arthur Guez, and David Silver. Deep reinforcement learning with dou- ble Q-learning. In AAAI Conference on Artificial Intelli- gence (AAAI), pages 2094-2010, 2016.
- [van Hasselt, 2010] Hado van Hasselt. Double Q-learning. In Advances in Neural Information Processing Systems (NIPS), pages 2613-2621, 2010.
- [van Hasselt, 2011] Hado van Hasselt. Insights in Reinforce- ment Learning. PhD thesis, Center for Mathematics and Computer Science, Utrecht University, 2011.
- [Watkins, 1989] Christopher J. C. H. Watkins. Learning from Delayed Rewards. PhD thesis, King's College, University of Cambridge, 1989.
- [Wiering and van Otterlo, 2012] Marco Wiering and Martijn van Otterlo, editors. Reinforcement Learning: State of the Art. Springer, New York, 2012.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Sequential decision problems under uncertainty are often framed as Markov decision processes (MDPs) [Kochenderfer, 2015; Bertsekas, 2007]. Reinforcement learning is concerned with finding an optimal decision making strategy in problems where the transition model and rewards are not initially known [Littman, 2015; Wiering and van Otterlo, 2012; Sutton and Barto, 1998]. Some reinforcement learning algorithms involve building explicit models of the transitions and rewards [Brafman and Tennenholtz, 2001], but other "modelfree" algorithms learn the values of different actions directly.
One of the most popular model-free algorithms is Qlearning [Watkins, 1989]. The original Q-learning algorithm inspired several improvements, such as delayed Q-learning [Strehl et al., 2006], phased Q-learning [Kearns and Singh, 1999], fitted Q-iteration [Ernst et al., 2005], bias-corrected Q-learning [Lee and Powell, 2012; Lee et al., 2013], and weighted Q-learning [D'Eramo et al., 2016].
This paper focuses on an enhancement known as double Q-learning [van Hasselt, 2010; 2011], a variant designed
Mykel J. Kochenderfer
Stanford University Stanford, CA 94305 USA mykel@stanford.edu
to avoid the positive maximization bias when learning the action values. The algorithm has recently been generalized from the discrete setting to use deep neural networks [LeCun et al., 2015] as a way to approximate the action values in high dimensional spaces [van Hasselt et al., 2016]. Double Q-learning, however, can lead to a bias that results in underestimating action values.
The main contribution of this paper is the introduction of the weighted double Q-learning algorithm, which is based on the construction of the weighted double estimator, with the goal of balancing between the overestimation in the single estimator and underestimation in the double estimator. We present empirical results of estimators of the maximum expected value on three groups of multi-arm bandit problems, and compare Q-learning and its variants in terms of the action-value estimate and policy quality on MDP problems.
2 Background
The MDP framework can be applied whenever we have an agent taking a sequence of actions in a system described as a tuple (S,A, T,R, γ), where S is a finite set of states, A is a finite set of actions, T : S × A × S → [0, 1] is a state-transition model, where T (s, a, s′ ) gives the probability distribution over state s′ after the agent executes action a in state s, R : S × A → R is a reward function, where R(s, a) gives the reward obtained by the agent after executing action a in state s, and γ ∈ [0, 1) is a discount factor that trades off the importance of immediate and delayed rewards.
An MDP policy is a mapping from S to A, denoted by π : S → A. The goal of solving an MDP is to find an optimal policy π∗ that maximizes V π : S → R, the value of a state s under policy π, defined as
A similar state-action value function is Qπ : S × A → R, where Qπ (s, a) is the value of starting in state s, taking action a, and then continuing with the policy π. The optimal statevalue function Q∗ (s, a) in the MDP framework satisfies the Bellman optimality equation [Bellman, 1957]:
We can use Q∗ to define π∗ (s) ∈ arg maxa∈A Q∗ (s, a).
3 Estimators of theMaximumExpected Value
This section considers the problem of finding an approximation for maxi E{Xi}, the maximum expected value of the set of N random variables X = {X1, X2, . . . , XN}. We first describe two existing methods, the single estimator and the double estimator, and then introduce our new weighted double estimator method.
3.1 Single Estimator
Let µ = {µ1, µ2, . . . , µN} be a set of unbiased estimators such that E{µi} = E{Xi}, for all i. Assume that D = ∪Ni=1Di is a set of samples, where Di is the subset containing at least one sample for the variable Xi, and the samples in Di are i.i.d. The single estimator method uses the value maxi µi(D) as an estimator of maxi E{Xi}, where µi(D) = 1 |Di | ∑d∈Di d is an unbiased estimator for the value of E{Xi}. However, maxi E{µi(D)} ≥ maxi E{Xi}, and the inequality is strict if and only if P(j /∈ argmaxi µi(D)) > 0 for any j ∈ argmaxi E{Xi} [van Hasselt, 2010]. This implies that there will be a positive maximization bias if we use the maximum of the estimates as an estimate of the maximum of the true values. Such a biased estimate can happen when all variables in X are i.i.d. The overestimation in the single estimator method is due to the same samples are both used to determine the maximizing action and to estimate its value.
3.2 Double Estimator
To avoid maximization bias in the single estimator, Hasselt proposed the double estimator approach [van Hasselt, 2010]. One of the key ideas is to divide the sample set D into two disjoint subsets, DU and DV . Let µU = {µU1 , µU2 , . . . , µUN } and µV = {µV1 , µV2 , . . . , µVN } be two sets of unbiased estimators such that E{µUi } = E{µVi } = E{Xi} for all i. The two sample subsets are used to learn two independent estimates, µUi (D) = 1 |DU i | ∑d∈DU i d and µVi (D) = 1 |DV i | ∑d∈DV i d, each an estimate of the true value E{Xi} for all i. The value µUi (D) is used to determine the maximizing action a∗ ∈ argmaxi µUi (D), and the other is used to provide the estimate of its value, µVa∗(D). This estimate will then be unbiased in the sense that E{µVa∗(D)} = E{Xa∗}. However, since E{Xa∗} ≤ maxi E{Xi}, we have E{µVa∗(D)} ≤ maxi E{Xi}. The inequality is strict if and only if P(a∗ /∈ argmaxi E{Xi}) > 0 [van Hasselt, 2010]. This implies that there will be a negative bias if we use µVa∗ as an estimate of the maximum of the true values when the variables have different expected values and overlapped distributions. When the variables are i.i.d., the double estimator is unbiased because all expected values are equal and P(a∗ ∈ argmaxi E{Xi}) = 1.
3.3 Weighted Double Estimator
Our weighted double estimator method provides a way of constructing a set of estimators that balances the overestimation of the single estimator and the underestimation of the double estimator. Mathematically, we write it as follows:
Algorithm 1 Q-learning
- 1: Initialize Q, s
- 2: loop
- 3: Choose action a from state s based on Q and some exploration strategy (e.g., ϵ-greedy)
- 4: Take action a, observe r, s′
- 5: a∗ ← argmaxa Q(s′ , a)
- 6: δ ← r +γQ(s′ , a∗ ) -Q(s, a)
- 7: Q(s, a) ←Q(s, a) +α(s, a)δ
- 8: s ← s′
where β ∈ [0, 1] and a∗ ∈ argmaxi µUi (D). Thus, µWDE (D) equals the result of the single estimator when β = 1, and the double estimator when β = 0.
Now we consider how to construct the function β. Assume that the variable Xi follows the distribution Hi, i.e., Xi ∼ Hi. Denote the Kullback-Leibler divergence between the two distributions Hi and Hj as KL(Hi ‖ Hj). When maxi,j KL(Hi ‖ Hj) = 0, the variables Xi in X are i.i.d. To make µWDE (D) be an unbiased estimate for maxi E{Xi}, β should be set to 0. Similarly, when maxi,j KL(Hi ‖ Hj) is small, we will want to also set β to a small value. We hypothesize that KL(Ha∗ ‖ HaL ), where aL ∈ argmini µUi (D), can serve as an approximation to maxi,j KL(Hi ‖ Hj), because Xa∗ and XaL are the two variables with the biggest difference in terms of the expected values in the sample subset DU . Since the distributions of variables are unavailable, we further use |E{Xa∗} - E{XaL }| to approximateKL(Ha∗ ‖ HaL ). Since |µVa∗(D)- µVaL (D)| is an unbiased estimator of |E{Xa∗} - E{XaL }|, we define β as follows:
where c ≥ 0. Because there exists one β∗ ∈ [0, 1] such that β∗E{µUa∗ (D)} + (1 - β∗ )E{µVa∗ (D)} = maxi E{Xi}, and, for any β∗ ∈ [0, 1], there is a corresponding c∗ ∈ [0,+∞) such that β∗ = E{β(D, c∗ )}, we can conclude that there always exists one c∗ ∈ [0,+∞) such that µWDE (D, c∗ ) is an unbiased estimator of maxi E{Xi}. Note that even if c is a constant, Eq. (4) can ensure that the more similar the distributions that variables follow, the closer the gap between β(D, c) and 0 is. Tuning parameter β directly cannot achieve this. Selecting c is discussed in a later section.
4 Q-learning and Its Variants
This section first describes Q-learning and double Q-learning, and then presents the weighted double Q-learning algorithm.
4.1 Q-learning
Q-learning is outlined in Algorithm 1. The key idea is to apply incremental estimation to the Bellman optimality equation. Instead of using T and R, it uses the observed immediate reward r and next state s′ to obtain the following update rule:
Algorithm 2 Double Q-learning
- 1: Initialize QU , QV , s
- 2: loop
- 3: Choose a from s based on QU and QV (e.g., ϵ-greedy in QU + QV )
- 4: Take action a, observe r, s′
- 5: Choose (e.g. random) whether to update QU or QV
- 6: if chose to update QU then
- 7: a∗ ← arg maxa QU (s′ , a)
- 8: δ ← r + γQV (s′ , a∗ ) - QU (s, a)
- 9: QU (s, a) ←QU (s, a) +αU (s, a)δ
- 10: else if chose to update QV then
- 11: a∗ ← arg maxa QV (s′ , a)
12:
δ ← r + γQU (s′ , a∗ ) - QV (s, a)
- 13: QV (s, a) ←QV (s, a) +αV (s, a)δ
- 14: s ← s′
where α(s, a) ∈ [0, 1] is the learning rate. Q-learning can be interpreted as using the single estimator method to estimate the maximum expected value of Q(s′ , a′ ), maxa′ E{Q(s′ , a′ )}. Here, maxa′ Q(s′ , a′ ) is the single estimator. Since maxa′ Q(s′ , a′ ) is an unbiased sample drawn from a distribution with mean E{maxa′ Q(s′ , a′ )}, and E{maxa′ Q(s′ , a′ )} ≥ maxa′ E{Q(s′ , a′ )}, the estimator maxa′ Q(s′ , a′ ) has a positive bias. Hence, Q-learning can suffer from overestimation of action values.
4.2 Double Q-learning
Double Q-learning, as shown in Algorithm 2, uses the double estimator method to estimate the maximum expected value of the Q function for the next state, maxa′ E{Q(s′ , a′ )}. It stores two Q functions, QU and QV , and uses two separate subsets of experience samples to learn them. The action selected to execute in line 3 is calculated based on the average of the two Q values for each action and the ϵ-greedy exploration strategy. In lines 5 to 13, with the same probability, each Q function is updated using a value from the other Q function for the next state. In line 7, the action a∗ is the maximizing action in state s′ based on the value function QU . However, in line 8, as opposed to Q-learning, the value QV (s′ , a∗ ) but not the value QU (s′ , a∗ ) is used to update QU . Since QV was updated with a different set of experience samples, QV (s′ , a∗ ) is an unbiased estimate for the value of the action a∗ in the sense that E{QV (s′ , a∗ )} = E{Q(s′ , a∗ )}. Similarly, the value of QU (s′ , a∗ ) in line 12 is also unbiased. However, since E{QV (s′ , a∗ )} ≤ maxa E{QV (s′ , a)} and E{QU (s′ , a∗ )} ≤ maxa E{QU (s′ , a)}, both estimators, QV (s′ , a∗ ) and QU (s′ , a∗ ), sometimes have negative biases. This results in double Q-learning underestimating action values in some stochastic environments.
4.3 Weighted Double Q-learning
Weighted double Q-learning, as outlined in Algorithm 3, combines Q-learning and double Q-learning. The key difference between Algorithm 2 and Algorithm 3 is that Algorithm 3 uses lines 8 to 10 to replace line 8, and uses lines 14 to 16 to replace line 12 in Algorithm 2. These changes
Algorithm 3 Weighted Double Q-learning
- 1: Initialize QU , QV , s
- 2: loop
- 3: Choose a from s based on QU and QV (e.g., ϵ-greedy in QU + QV )
- 4: Take action a, observe r, s′
- 5: Choose (e.g. random) whether to update QU or QV
- 6: if chose to update QU then
- 7: a∗ ← arg maxa QU (s′ , a)
- 8: aL ← arg mina QU (s′ , a)
- 9: βU ← |QV (s′ ,a∗ )-QV (s′ ,aL)| c+|QV (s′ ,a∗ )-QV (s′ ,aL)|
11: QU (s, a) ←QU (s, a) +αU (s, a)δ
- 12: else if chose to update QV then
13:
14:
15:
16:
a∗ ← arg maxa QV (s′ , a)
aL ← arg mina QV (s′ , a)
βV ← |QU (s′ ,a∗ )-QU (s′ ,aL)|
c+|QU (s′ ,a∗ )-QU (s′ ,aL)|
δ ← r + γ[βV QV (s′ , a∗ ) + (1 - βV )QU (s′ , a∗ )] -
QV (s, a)
make weighted double Q-learning use different δ values in updating both QU and QV . We denote
where
Equations (6) and (7) are the corresponding forms of Eqs. (3) and (4) in the MDP setting, respectively. From Eq. (6) we see that weighted double Q-learning uses a linear combination of both QU (s′ , a∗ ) and QV (s′ , a∗ ). Thus, QU,WDE represents a trade-off between the overestimation of Q-learning and the underestimation of double Q-learning. A similar update is used for QV , using a∗ , QU , and QV .
By using the proof techniques in the convergence in the limit of double Q-learning [van Hasselt, 2010], we can also prove that weighted double Q-learning converges to the optimal policy. Intuitively, this is what one would expect based on the following two observations: (1) both Q-learning and double Q-learning converge to the optimal function Q∗ under similar conditions; and (2) weighted double Q-learning spans a spectrum that has the Q-learning algorithm at one end and the double Q-learning algorithm at the other.
5 Experiments
In this section, we first present empirical results of estimators of the maximum expected value on three groups of multi-arm bandit problems. Then, we present empirical comparisons of Q-learning and its variants in terms of the action-value estimate and policy quality on the game of roulette, four MDP problems modified from a 3×3 grid world problem [van Hasselt, 2010], and six intruder monitoring problems.
In some domains, we also compared the performance of the bias-corrected Q-learning algorithm and the weighted Qlearning algorithm, two recent proposed algorithms that address the overestimation issue for Q-learning. Bias-corrected Q-learning asymptotically cancels the max-operator bias in Q-learning by subtracting to each Q-value a bias correction term that depends on the standard deviation of the reward and on the number of actions [Lee et al., 2013]. Weighted Qlearning estimates the maximum action values by a weighted estimator that computes a weighted mean of all the sample means [D'Eramo et al., 2016].
Algorithms with a polynomial learning rate, αt(s, a) = 1/nt(s, a)m with m = 0.8, was shown to have better performance than ones with a linear learning rate, αt(s, a) = 1/nt(s, a) [van Hasselt, 2010]. This paper focuses on empirical results of Q-learning, biased-corrected Q-learning and weighted Q-learning with parameter m = 0.8, and both double Q-learning and weighted double Q-learning with parameters mU = 0.8 and mV = 0.8 in the two learning rates αU t (s, a) = [1/nUt (s, a)]mU and αV t (s, a) = [1/nVt (s, a)]mV , where the variables nUt (s, a) and nVt (s, a) store the number of updates in QU (s, a) and QV (s, a), respectively. The action-selection strategy in all algorithms was ϵ-greedy with ϵ(s) = 1/nt(s)0.5 , where nt(s) is the number of times state s has been visited.
5.1 Multi-armBandits
Our experiments are conducted on three groups of multi-arm bandit problems: (G1) E{Xi} = 0, for i ∈ {1, 2, . . . ,N}; (G2) E{X1} = 1 and E{Xi} = 0 for i ∈ {2, 3, . . . ,N}; and (G3) E{Xi} = iN , for i ∈ {1, 2, . . . ,N}. Here, E{Xi} represents the expected reward of selecting the ith action, and N is the number of actions. Thus, maxi E{Xi} = 0 in G1, and maxi E{Xi} = 1 in G2 and G3.
In each N-arm bandit experiment, we repeated the following procedure 100 times: generate µi from N(E{Xi}, 1) for all i and then generate 1000 samples di from N(µi, 1). Thus, |Di| = 1000. The single estimator (SE) method computes µi(D) = 1 |Di | ∑d∈Di d, and then uses the average of maxi µi(D) in the 100 repetitions as the single estimator of maxi E{Xi}. The double estimator (DE) method and the weighted double estimator (WDE) method first divide Di into two independent sample subsets, DU i and DV i , with |DU i | = |DV i | = 500. Then, the DE method computes µVa∗(D) = 1 |DV a∗ | ∑d∈DV a∗ d, where a∗ ∈ argmaxi µUi (D) as the double estimator; the WDE method also computes µVa∗(D) as in the DE method, but uses the weighted average β(D, c)µUa∗(D)+(1-β(D, c))µVa∗(D) in the 100 repetitions as the weighted double estimator.
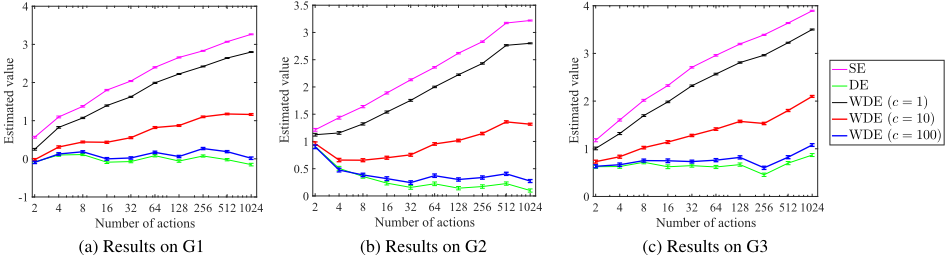
Figure 1 shows empirical results for the estimated values and standard errors of different estimators for maxi E{Xi} on the three groups of multi-arm bandit problems. For the weighted double estimator method, we report the results with the input parameter c = 1, 10, 100. From this figure, we see that on all domains, as N increases from 2 to 1024, the degree of overestimation in the single estimator increases. In addition, the larger the value of c, the closer it is to the double estimator; the closer the value of c is to 0, the closer it is to the single estimator.
This figure shows that there is no fixed best value of c, even with problems with a fixed number of actions. For example, when N = 128 on the G1 domain, the best c is +∞; on G2 the best c is around 10; and on G3 the best c is larger than 10. Although there is always a c∗ ∈ [0,+∞) such that µWDE (D, c∗ ) is an unbiased estimator of maxi E{Xi} on each multi-arm bandit problem, the value of c∗ appears to be different among problems with different characteristics. Hence, we want to set c adaptively based on the characteristics of the problem.
We observed that the number of actions clearly influences the degree of overestimations in the single estimator; however, a similar effect does not appear with the double estimator. As a result, the estimation errors in the weighted double estimator are affected by the number of actions. The empirical relationship between c in WDQ and N appears loglinear. This suggests to us that c ∝ log2 N.
Table 1 shows the maximum difference between the expected value of the best action and the expected values of other actions, denoted ∆ = E{Xi∗}-maxj̸=i∗ E{Xj} E{Xi∗}-mini E{Xi} where E{Xi∗} = maxi E{Xi} (assume that ∆ = 0 when E{Xi∗} - mini E{Xi} = 0). As ∆ becomes small, the double estimator tends to decrease the error caused by its underestimation, as opposed to the single estimator, which suggests setting c ∝ 1∆ .
| Group (→) | G1 | G3 | G2 |
|---|---|---|---|
| Difference (∆) | 0 | 1/128 | 1 |
| Single estimator | 2.66 | 2.19 | 1.62 |
| Double estimator | -0.06 | -0.33 | -0.86 |
The domain G2 is an extreme case where only one action has the highest expected reward and all other actions have the lowest expected reward. In this case, DE has the largest estimation error, and the proportion of estimation error size between DE and SE is about 12 ≈ 0.86 1.62 . In all other cases, the proportion should be less than 12 . This suggests that 13 should be an upper bound of β(D, c) due to 13 / 23 = 12 , and therefore, β(D, c) ∈ [0, 1 3 ].
Based on the above analysis, we define c as a heuristic function with the following form:
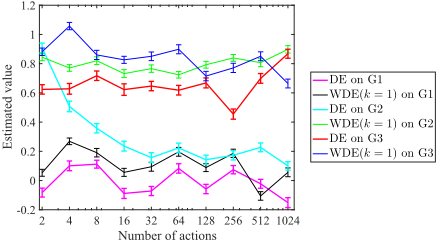
where 10-6 is used to avoid the value of the denominator ∆ becoming too close to 0, 2|µVa∗(D) - µVaL (D)| is used to make β(D, c) ∈ [0, 1 3 ], and k is a constant independent of the characteristics of the problem that has to be determined empirically. In this paper, we set k = 1 because it leads to a much lower estimation error than DE on G2 and G3, as shown in Fig. 2. The average errors of WDE(k = 1) are 0.10, 0.20, 0.16 on G1, G2, and G3, respectively, while the corresponding estimation errors are 0.01, 0.70, 0.35 in DE.
5.2 Roulette
Roulette is a bandit problem with 171 arms, consisting of 170 betting actions with an expected payout of $0.947 per dollar and one walk-away action yielding $0. Each betting action has an expected loss of $-0.053 per play based on the assumption that a player bets $1 every time. We recorded the mean action values over all betting actions as found by Q-learning (Q), bias-corrected Q-learning (BCQ), weighted Q-learning (WQ), double Q-learning (DQ), and weighted double Q-learning (WDQ) with different values of parameter c, and a heuristic value, denoted c(k = 1) and defined by Eq. (8). Each trial involves a synchronous update of all actions. As the value of c increases, the degree of overestimation decreases. After 100, 000 trials, WDQ valued all betting actions $12.87, $2.93, $-0.11, $0.00 when c = 1, 10, 100, c(k = 1), respectively. The estimates of the expected profit in all betting actions in WDQ(k = 1), WDQ(c = 100), BCQ, WQ, and DQ after 100, 000 trials are very close to the expected loss $-0.053, all with absolute biases smaller than $0.10.
5.3 GridWorld
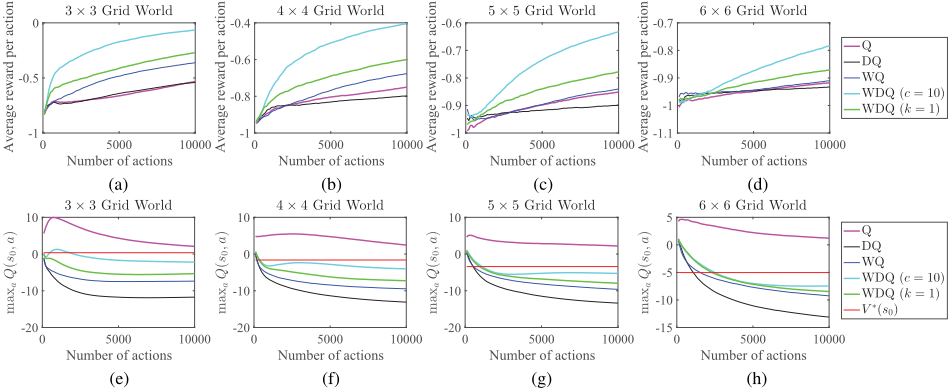
An n×n grid world problem has n2 states (one state per cell in the grid) and four actions: {north, south, east, west}. Movement to adjacent squares is deterministic, but a collision with the edge of the world results in no movement. The initial state s0 corresponds to the bottom left cell, and the goal state sg corresponds to the top right cell. The agent receives a random reward of -30 or +40 for any action ending an episode from the goal state and a random reward of -6 or +4 for any action at a non-goal state. Since an episode starting from s0 consists of 2(n - 1) + 1 actions given an optimal policy, the optimal average reward per action is 5-2(n-1) 2(n-1)+1 = 7-2n 2n-1 . With a discount factor of γ = 0.95, V ∗ (s0) = 5γ 2(n-1) - ∑2n-3 i=0 γ i . Figure 3 shows the results of Q-learning and its variants on four n × n grid world problems.
In contrast with Hasselt's grid world problem, we assume stochastic reward at the goal state. Such a setting makes underestimating action values at the goal states negatively impact performance in DQ. In additon, the random reward at non-goal states makes the overestmates at non-goal states negatively impact performance in Q. As a result, both the Q and DQ agents often estimate that the action values at the goal state are lower than some action values at other states and do not move towards the goal state. Consequently, they performed poorly on all problems, as shown in Figure 3 (ad). WDQ(c = 10) and WDQ(k = 1) 1 performed significantly better because their estimates of the maximum action values were much closer to the true values, e.g., at the initial state s0 as shown in Figure 3 (e-h). On this domain, setting c to 10 is empirically a better choice in terms of the action-value estimate and policy quality than setting it adaptively by using Eq. (8), in part due to the shortcomings of approximating the constant in a bandit setting and deploying it in an MDP setting. We leave the design of a more effective heuristic to find an appropriate value of c in MDPs as a future research topic.
Figure 3 also shows the performance of WQ on the grid world domain. In terms of the average reward per action, WQ performs better than Q and DQ, but worse than WDQ(c = 10) and WDQ(k = 1). Compared with other methods, WDQ shows less max-operator bias.
5.4 Intruder Monitoring
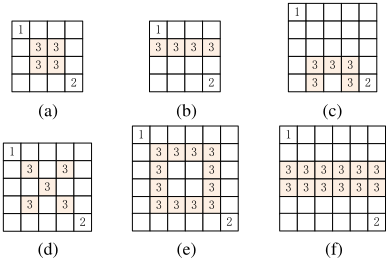
An intruder monitoring task involves guarding danger zones using a camera so that if an intruder moves to a danger zone, the camera points at that location. An n × n grid task has n4 states. Each state corresponds to a unique position of the camera and intruder. At each time step, a camera or intruder has five actions to choose: {north, south, east, west, stay}. All movements are deterministic. The policy in the intruder is uniform random, but this is unknown to the camera. The system receives a reward of -10 for every visit of the intruder to a danger zone with no camera present, +100 when there is a camera present, and 0 otherwise. The discount factor γ is 0.95. Figure 4 shows the maps of six intruder monitoring problems. From Table 2 we can see that on these problems WDQ is robust and can perform better than both Q and DQ even when there is no randomness in the reward function. Compared with BCQ, WDQ can usually generate better policies due to its more accurate estimate of the maximum over action values. Since the only uncertainty is the behavior of the intruder, the small estimation errors in both Q and DQ sometimes have no significant negative impact in performance, making the improvement achieved by WDQ(c): WDQ(c = 10), WDQ(k): WDQ(k = 1)
1 On this domain, c = 10 and k = 1 are not the best parameter values, and c = 8 and k = 2 can yield better empirical results.
| Problems | Q | DQ | BCQ | WDQ(c) | WDQ(k) |
|---|---|---|---|---|---|
| Fig. 4 (a) | 12.02 | 12.07 | 11.95 | 12.15 | 12.30 |
| Fig. 4 (b) | 14.35 | 14.48 | 14.35 | 14.69 | 14.72 |
| Fig. 4 (c) | 8.52 | 8.65 | 8.54 | 8.75 | 8.79 |
| Fig. 4 (d) | 8.32 | 8.31 | 8.33 | 8.58 | 8.53 |
| Fig. 4 (e) | 10.61 | 10.48 | 10.67 | 10.78 | 10.79 |
| Fig. 4 (f) | 9.64 | 9.54 | 9.75 | 9.82 | 9.95 |
WDQ appear not as significant as on the grid world domain.
6 Conclusion
This paper presented a weighted double Q-learning algorithm to avoid the overestimation bias of action values inherent in regular Q-learning and the underestimation bias of action values inherent in double Q-learning. The parameter c is used to control the importance weight of the single and double estimates. We proposed a heuristic for selecting c based on insights from the empirical results in multi-arm bandit problems and used it to set the parameter adaptively. Empirically, we found that the new algorithm reduces the estimation error and performs well on a variety of MDP problems. In the future, it would be interesting to analyze the performance of weighted double Q-learning when using value function approximation on Atari video games [van Hasselt et al., 2016; Mnih et al., 2015].
Acknowledgments
This work was supported by National Natural Science Foundation of China (61502323), High School Natural Foundation of Jiangsu (16KJB520041), and Collaborative Innovation Center of Novel Software Technology and Industrialization.
@inproceedings{ijcai2017p483,
  title     = {Weighted Double Q-learning},
  author    = {Zhang, Zongzhang and Pan, Zhiyuan and Kochenderfer, Mykel J.},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {3455--3461},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/483},
  url       = {https://doi.org/10.24963/ijcai.2017/483},
}
TY - CPAPER TI - Weighted Double Q-learning AU - Zhang, Zongzhang AU - Pan, Zhiyuan AU - Kochenderfer, Mykel J. T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 3455 EP - 3461 DO - 10.24963/ijcai.2017/483 UR - https://doi.org/10.24963/ijcai.2017/483 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





