
Fast Stochastic Variance Reduced ADMM for Stochastic Composition Optimization
Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence. Main track. Pages 3364-3370.
https://doi.org/10.24963/ijcai.2017/470
Keywords
- Machine Learning: Machine Learning
- Machine Learning: Learning Theory
Abstract
We consider the stochastic composition optimization problem proposed in \cite{wang2017stochastic}, which has applications ranging from estimation to statistical and machine learning. We propose the first ADMM based algorithm named com SVR ADMM, and show that com SVR ADMM converges linearly for strongly convex and Lipschitz smooth objectives, and has a convergence rate of $O(\logS/S)$, which improves upon the $O(S^{-4/9})$ rate in \cite{wang2016accelerating} when the objective is convex and Lipschitz smooth. Moreover, com SVR ADMM possesses a rate of $O(1/\sqrt{S})$ when the objective is convex but without Lipschitz smoothness. We also conduct experiments and show that it outperforms existing algorithms.
- [Alexander and Baptista, 2004] Gordon J Alexander and Alexandre M Baptista. A comparison of var and cvar constraints on portfolio selection with the mean-variance model. Management science, 50(9):1261-1273, 2004.
- [Allen-Zhu, 2016] Zeyuan Allen-Zhu. Katyusha: Acceler- ated variance reduction for faster sgd. ArXiv e-prints, abs/1603.05953, 2016.
- [Boyd et al., 2011] Stephen Boyd, Neal Parikh, Eric Chu, Borja Peleato, and Jonathan Eckstein. Distributed opti- mization and statistical learning via the alternating direc- tion method of multipliers. Foundations and Trends R in Machine Learning, 3(1):1-122, 2011.
- [Dai et al., 2016] Bo Dai, Niao He, Yunpeng Pan, Byron Boots, and Le Song. Learning from conditional dis- tributions via dual kernel embeddings. arXiv preprint arXiv:1607.04579, 2016.
- [Gabay and Mercier, 1976] Daniel Gabay and Bertrand Mercier. A dual algorithm for the solution of nonlinear variational problems via finite element approximation. Computers & Mathematics with Applications, 2(1):17-40, 1976.
- [Glowinski and Marroco, 1975] Roland Glowinski and A Marroco. Sur l'approximation, par éléments finis d'ordre un, et la résolution, par pénalisation-dualité d'une classe de problèmes de dirichlet non linéaires. Revue franc ¸aise d'automatique, informatique, recherche opérationnelle. Analyse numérique, 9(2):41-76, 1975.
- [Golub and Van Loan, 2012] Gene H Golub and Charles F Van Loan. Matrix computations, volume 3. JHU Press, 2012.
- [Hien et al., 2016] Le Thi Khanh Hien, Canyi Lu, Huan Xu, and Jiashi Feng. Accelerated stochastic mirror descent al- gorithms for composite non-strongly convex optimization. arXiv preprint arXiv:1605.06892, 2016.
- [Johnson and Zhang, 2013] Rie Johnson and Tong Zhang. Accelerating stochastic gradient descent using predictive variance reduction. In Advances in Neural Information Processing Systems, pages 315-323, 2013.
- [Lian et al., 2016] Xiangru Lian, Mengdi Wang, and Ji Liu. Finite-sum composition optimization via variance reduced gradient descent. arXiv preprint arXiv:1610.04674, 2016.
- [Ouyang et al., 2013] Hua Ouyang, Niao He, Long Tran, and Alexander G Gray. Stochastic alternating direction method of multipliers. ICML (1), 28:80-88, 2013.
- [Qian and Zhou, 2016] Chao Zhang Hui Qian and Ze- bang Shen Tengfei Zhou. Accelerated stochastic admm for empirical risk minimization. arXiv preprint arXiv:1611.04074, 2016.
- [Shapiro et al., 2014] Alexander Shapiro, Darinka Dentcheva, et al. Lectures on stochastic programming: modeling and theory, volume 16. Siam, 2014.
- [Sutton and Barto, 1998] Richard S Sutton and Andrew G Barto. Reinforcement learning: An introduction, vol- ume 1. MIT press Cambridge, 1998.
- [Suzuki and others, 2013] Taiji Suzuki et al. Dual averag- ing and proximal gradient descent for online alternating direction multiplier method. In ICML (1), pages 392-400, 2013.
- [Wang and Banerjee, 2013] Huahua Wang and Arindam Banerjee. Online alternating direction method (longer ver- sion). arXiv preprint arXiv:1306.3721, 2013.
- [Wang et al., 2016a] Mengdi Wang, Ethan X Fang, and Han Liu. Stochastic compositional gradient descent: Algo- rithms for minimizing compositions of expected-value functions. Mathematical Programming, 161(1-2):419- 449, 2016.
- [Wang et al., 2016b] Mengdi Wang, Ji Liu, and Ethan X. Fang. Accelerating stochastic composition optimization. In Advances In Neural Information Processing Systems, pages 1714-1722, 2016.
- [Yu and Huang, 2017] Yue Yu and Longbo Huang. Fast stochastic variance reduced admm for stochastic composi- tion optimization. arXiv preprint arXiv:1705.04138, 2017.
- [Zhang et al., 2011] Xiaoqun Zhang, Martin Burger, and Stanley Osher. A unified primal-dual algorithm framework based on bregman iteration. Journal of Scientific Comput- ing, 46(1):20-46, 2011.
- [Zheng and Kwok, 2016a] Zheng and Kwok. Fast-and-light stochastic admm. arXiv preprint arXiv:1604.07070, 2016. IJCAI
- [Zheng and Kwok, 2016b] Shuai Zheng and James T Kwok. Stochastic variance-reduced admm. arXiv preprint arXiv:1604.07070, 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recently, [Wang et al., 2016a] proposed the stochastic composition optimization of the following form:
Here x 2 Rq , Eifi = Ei¶fi(x)♦, (f ◦ g)(x) , f(g(x)) denotes the composite function, and i↪ j are random variables. Problem (1) has been shown in [Wang et al., 2016a] to include several important applications in estimation and machine learning.
In this paper, we focus on extending the formulation to include linear constraints, and consider the following variant of Problem (1):
A 2 Rp⇥q , B 2 Rp⇥l , gj : Rq 7! Rr and fi : Rr 7! R are continuous functions, and R(!) : Rl 7! R is a closed convex function. The reason to consider the specific form of Problem (2) is as follows. (i) In practice, random variables such as i and j are obtained from problem-dependent data sets. Thus, they often only take values in a finite set with certain frequencies (captured by the first term in the objective (2)). (ii) Such problems often require the solutions to satisfy certain regularizing conditions (imposed by the term R(!) and constraint (3)). Note here that the uniform distribution of i and j (the 1n and 1m ) in (2) is not critical. In Section 4, we show that our algorithm is also applicable under other distributions.
1.1 Motivating Examples
We first present a few motivating examples of formulation (2). The first example is a risk-averse learning problem discussed in [Wang et al., 2016b], which can be formulated into the following mean-variance minimization problems, i.e.,
Here h✏(x) is the loss function w.r.t variable x and is parameterized by random variable ✏, and Var✏(x) , E✏¶[h✏(x) - E✏h✏(x)]2 ♦ denotes its variance. We see that this example is of the form (2), where E✏h✏(x) plays the role of the regularizer and the variance term is the composition functions. There are many other problems that can be formulated into the mean-variance optimization as in (4), e.g., portfolio management [Alexander and Baptista, 2004].
The second motivating example is dynamic programming [Sutton and Barto, 1998; Dai et al., 2016]. In this case, one can often approximate the value of each state by an inner product of a state feature φs and a target variable w. Then, the policy learning problem can be formulated into minimizing the Bellman residual as follows:
where P ⇡ s↪s0 denotes the transition probabilities under a policy ⇡, and γ denotes the discounting factor. Note that this problem also has the form of Problem (2).
The third example is multi-stage stochastic programming [Shapiro et al., 2014]. For example, a two-stage optimization scenario often requires solving the following problem:
Here x↪ y are decision variables, v↪ u are the corresponding random variables, and the function U is the utility function.
In this case, the expectation Eu♣v(·) is the inner function and miny(·) is the outer function in Problem (2).
From these examples, we see that formulation (2) is general and includes important applications. Thus, it is important to develop fast and robust algorithms for solving (2).
1.2 RelatedWorks
The stochastic composition optimization problem was first proposed in [Wang et al., 2016a], where two solution algorithms, Basic SCGD and accelerated SCGD, were proposed. The algorithms were shown to achieve a sublinear convergence rate for convex and strongly convex cases, and were also shown to converge to a stationary point in the nonconvex case. Later, [Wang et al., 2016b] proposed a proximal gradient algorithm called ASC-PG to improve the convergence rate when both inner and outer functions are smooth. However, the convergence rate is sublinear and their results do not include the regularizer when the objective functions are not strongly convex. In [Lian et al., 2016], the authors solved the finite sample case of stochastic composition optimization and obtained two linear-convergent algorithms based on the stochastic variance reduction gradient technique (SVRG) proposed in [Johnson and Zhang, 2013]. However, the algorithms do not handle the regularizer either.
The ADMM algorithm, on the other hand, was first proposed in [Glowinski and Marroco, 1975; Gabay and Mercier, 1976] and later reviewed in [Boyd et al., 2011]. Since then, several ADMM-based stochastic algorithms have been proposed, e.g., [Ouyang et al., 2013; Suzuki and others, 2013; Wang and Banerjee, 2013]. However, these algorithms all possess sublinear convergence rates. Therefore, several recent works tried to combine the variance reduction scheme and ADMM to accelerate convergence. For instance, SVRGADMM was proposed in [Zheng and Kwok, 2016a]. It was shown that SVRG-ADMM converges linearly when the objective is strongly convex, and has a sublinear convergence rate in the general convex case. Another recent work [Zheng and Kwok, 2016b] further proved that SVRG-ADMM converges to a stationary point with a rate O( 1 T ) when the objective is nonconvex. In [Qian and Zhou, 2016], the authors used acceleration technique in [Allen-Zhu, 2016; Hien et al., 2016] to further improve the convergence rate of SVRG-ADMM. However, all aforementioned variancereduced ADMM algorithms cannot be directly applied to solving the stochastic composition optimization problem.
1.3 Contribution
In this paper, we propose an efficient algorithm called comSVR-ADMM, which combines ideas of SVRG and ADMM, to solve stochastic composition optimization. Our algorithm is based on the SVRG-ADMM algorithm proposed in [Zheng and Kwok, 2016a], which does not apply to composite optimization problems. We consider three different objective functions in Problem (2), and show that our algorithm achieves the following performance.
- ÷ When F(x) is strongly convex and Lipschitz smooth, and R(!) is convex, our algorithm converges linearly. This convergence rate is comparable with those of com-
SVRG-1 and com-SVRG-2 in [Lian et al., 2016]. However, com-SVRG-1 and com-SVRG-2 do not take the commonly used regularization penalty into consideration. Experimental results also show that com-SVRADMM converges faster than com-SVRG-1 and comSVRG-2.
- ÷ When F(x) is convex and Lipschitz smooth, and R(!) is convex, com-SVR-ADMM has a sublinear rate of O( log(S+1) S ), where S is the number of outer iterations. 1 This result outperforms the O(S-4◁9 ) convergence rate of ASC-PG in [Wang et al., 2016b]. 2
- ÷ When F(x) and R(!) are general convex functions (not necessarily Lipschitz smooth), com-SVR-ADMM achieves a rate of O( 1 pS ). To the best of our knowledge, this is the first convergence result for stochastic composite optimization with general convex problems without Lipschitz smoothness.
1.4 Notation
For vector x and a positive definite matrix G, the G-norm of vector x is defined as ♣♣x♣♣G = pxT Gx. For a matrix X, ♣♣X♣♣ denotes its spectral norm, σmax(X)↪ σmin(X) denote its largest and smallest eigenvalue, respectively. X denotes the pseudoinverse of X. ˜rR(!) denotes a noisy subgradient of nonsmooth R(!). For a function g(x) : Rq 7! Rr , @g(x) 2 Rr⇥q denotes its Jacobian matrix. rfik (g(x)) denotes the gradient of fik (·) at point y = g(x).
2 Algorithm
Recall that the stochastic composition problem we want to solve has the following form:
where F(x) , 1n nP i=1 fi( 1m mP j=1 gj(x)). For clarity, we denote
Our proposed procedure adopts the ADMM scheme. At every iteration the primal variables (x↪ !) are obtained by minimizing the following augmented Lagrangian equation parameterized with ⇢ > 0, i.e.,
The update of dual variable λ is similar to that under gradient descent with the stepsize equaling ⇢. We also based our algorithm on a sampling oracle as in [Wang et al., 2016b]. Specifically, we assume a stochastic first-order oracle, which, Algorithm 1 com-SVR-ADMM for strongly convex stochastic composition optimization
1 The number of inner iterations is constant.
2 Note that ASC-PG is not based on SVRG and does not have inner loops.
- 1: Input: K, M, N, ⌘, ⇢, ˜x0 , ˜!0 , ˜λ0 = -(AT ) rF(˜x0 );
- 2: for s = 1↪ 2↪ ▷▷▷ do
- 3: ˜x = ˜xs-1 , x0 = ˜xs-1 , !0 = ˜!s-1 , λ0 = ˜λs-1 ;
- 6: for k = 0 to K - 1 do
- 8: uniformly sample Nk and calculate ˆ g(xk ) using (9); (2N queries)
- 9: uniformly sample ik, jk and calculate r ˆ Fik (xk ) using (8); (4 queries)
- 12: end for
- 14: end for
- 15: Output: ˜xs , ˜ws .
if queried, returns a noisy gradient/subgradient or function value of fi(·) and gj(·) at a given point.
In the following sections, we introduce the stochastic variance reduced ADMM algorithm for solving stochastic compositional optimization (com-SVR-ADMM). We present com-SVR-ADMM in three different scenarios, i.e., strongly convex and Lipschitz smooth, general convex and Lipschitz smooth, and general convex. Algorithm 1 shows how comSVR-ADMM is used in the strongly convex case, while Algorithm 2 is for the second and third cases.
2.1 Compositional Stochastic Variance Reduced ADMM for Strongly Convex Functions
As in SVRG, com-SVR-ADMM has K inner loops inside each outer iteration. At every outer iteration, we need to keep track of a reference point ˜x (Step 3 in Algorithm 1) for computing g(˜x) defined as
and evaluate @g(˜x), which is the Jacobian matrix of g(x) at point ˜x. The updates of !k+1 and λk+1 are the same as those in batch ADMM [Boyd et al., 2011]. The main difference lies in the update for xk+1 , in that we use a stochastic sample ik and replace Fik (x) with its first-order approximation, and then approximate rFik (xk ) by
Here ik, jk are uniformly sampled from ¶1↪ 2↪ ▷▷▷↪ n♦ and ¶1↪ ▷▷▷↪m♦, respectively. ˆ g(xk ) is an estimation of g(xk ) defined as follows:
where Nk is a mini-batch and is obtained by uniformly and randomly sampling from ¶1↪ ▷▷▷↪m♦ for N times (with replacement) and Nk[j] is the jth element of Nk. In step 10 of Algorithm 1, we add a proximal term 1 2⌘ ♣♣x-xk ♣♣22 to control the distance between the next point xk+1 and the current point xk . The parameter ⌘ is a constant and plays the role of stepsize as in [Ouyang et al., 2013].
Note that our estimated gradient rˆ Fik (xk ) is biased due to the composition objective function and its form is the same as com-SVRG-1 in [Lian et al., 2016]. However, we remark that our algorithm is not a trivial extension of com-SVRG1 due to the existence of linear constraint and Lagrangian dual variable. Moreover, com-SVR-ADMM can handle regularization penalty while com-SVRG-1 cannot. Also, the update of ˜λs uses the pseudoinverse of A. In the common case when A is sparse, one can use the efficient Lanczos algorithm [Golub and Van Loan, 2012] to compute A . Note that step 10 in Algorithm 1 often involves computing AT A. The memory complexity for this step can be alleviated by algorithms proposed in recent works, e.g., [Zheng and Kwok, 2016a; Zhang et al., 2011].
2.2 Compositional Stochastic Variance Reduced ADMM for General Convex Functions
In this section, we describe how com-SVR-ADMM handles general convex composition problems with Lipschitz smoothness. Without strong convexity, we need to make subtle changes. As shown in Algorithm 2, besides changes in variable initialization and output, another key difference is the approximation of rFik (x), where we use g(xk ) instead of ˆ g(xk ), i.e.,
Note that in the cases of interest (see Assumption 1 below), the approximated gradient rˆ Fik (xk ) is unbiased. The next change is the stepsize for updating x. In step 10 of Algorithm 2, we use a positive definite matrix Gk in the proximal term. 3 Therefore, the stepsize depends on two parameters: ⌘s and Gk, as shown in (11), where s and k are the iteration counters for outer and inner iteration, respectively. Here LF is a parameter of Lipschitz smoothness and will be specified in our assumptions in next section.
3 The corresponding proximal term of Algorithm 1 can be viewed to have Gk = I.
Algorithm 2 com-SVR-ADMM for general convex stochastic composition optimization
- 1: Input: S, K, N, ⌘s, ⇢, ˜x0 = ˆx0 , ˆ!0 , ˆλ0 , ˆG0 = I;
- 2: for s = 1↪ 2↪ ▷▷▷↪ S do
- 4: g(˜x) = 1m Pmj=1 gj(˜x); (m queries) 5: evaluate rF(˜x); (m + n queries)
- 9: uniformly sample ik, jk and calculate r ˆ Fik (xk ) using (10); (4 queries)
- 8: calculate g(xk ) = 1m Pmj=1 gj(xk ); (m queries)
- 12: end for
- 14: end for
That is, Gk is nonincreasing for k = 0↪ 1↪ ▷▷▷↪K. Then, according to the definition of G-norm and (11), we have:
where ⌘s↪k = ⌘s co(Gk) and co(Gk) = a if Gk = aI, and a is a scalar. Therefore, ⌘s↪k serves as the stepsize [Ouyang et al., 2013], and it can be verified that ⌘s↪k satisfies the following properties:
That is, ⌘s↪k changes from s (s+1)LF to 1 LF in stage s. Note that even though ⌘s↪k is not a constant, it still has a reasonable value and does not need to vanish. This feature is helpful for convergence acceleration.
2.3 General Convex Functions without Lipschitz Smoothness
In the previous two sections, we present the procedures of com-SVR-ADMM for the strongly convex and general convex settings, both under the Lipschitz smooth assumption of F(x). In this section, we further investigate the case when the smooth condition is relaxed. We still use Algorithm 2, except that the values ⌘s and Gk are changed to
Therefore, using the same technique in (12), it can be verified that ⌘s↪k in this setting changes from ps s+1 to 1 ps+1 in stage s and decreases to zero. Note that in this case, the number of oracle calls at each step is the same as that in section 2.2.
Although the algorithm we proposed appears similar to the SVRG-ADMM algorithm in [Zheng and Kwok, 2016a], it is very different due to the composition nature of the objective function (which is not considered in SVRG-ADMM) and the stochastic variance reduced gradients in (8) and (10). These differences make it impossible to directly apply SVRG-ADMM and require a very different analysis for the new algorithm. Readers interested in the full proofs can refer to our technical report [Yu and Huang, 2017].
3 Theoretical Results
In this section, we analyze the convergence performance of com-SVR-ADMM under the three cases described in section 2. Below, we first state our assumptions. Note that the assumptions are not restrictive and are commonly made in the literature, e.g., [Wang et al., 2016b; Ouyang et al., 2013; Wang et al., 2016a; Zheng and Kwok, 2016b].
Assumption 1. (i) For each i 2 ¶1↪ ▷▷▷↪ n♦, Fi is convex and continuously differentiable, R(!) is convex (can be nonsmooth). Moreover, there exists an optimal primal-dual solution (x⇤ ↪ !⇤ ↪ λ⇤ ) for Problem (2).
(ii) The feasible set X for x is bounded and denote D = maxx↪y2X ♣♣x - y♣♣.
(iii) For randomly sampled ik 2 ¶1↪ ▷▷▷↪ n♦, jk 2 ¶1↪ ▷▷▷↪ m♦ and 8x, we assume the following unbiased properties:
Assumption 2. F is strongly convex with parameter θF > 0, i.e., 8x,
Assumption 3. Matrix A has full row rank.
Assumption 4. There exists a positive constant LF , such that 8i 2 ¶1↪ ▷▷▷↪ n♦, 8j 2 ¶1↪ ▷▷▷↪ m♦ and 8x, y, we have
Assumption 5. For each i 2 ¶1↪ ▷▷▷↪ n♦, fi is Lipschitz smooth with positive parameter Lf , that is, 8x↪ y, we have
Assumption 6. For every j 2 ¶1↪ ▷▷▷↪m♦, @gj(x) is bounded, and for all x↪ y, 9 CG↪ LG > 0 that satisfy
For clarity, we also use the following notations used in the theorems:
It can be verified that G(u) is always non-negative due to the convexity of F(x) and R(!). The following theorem and corollary show that Algorithm 1 has a linear convergence rate.
Proposition 1. Under Assumption 4, we have 8i 2 ¶1↪ ▷▷▷↪ n♦ and 8x↪ y:
i.e., each Fi is Lipschitz smooth. Moreover, it implies ♣♣rF (x) - rF (y)♣♣ LF ♣♣x - y♣♣.
Theorem 1. Under Assumptions 1, 2, 3, 4, 5 and 6, if 0 < ⌘ 1◁LF , then under Algorithm 1,
where (denote σ(N) = p1◁N)
Corollary 1. Suppose the conditions in Theorem 1 hold. Then, there exist positive ⇥(1) constants K (number of inner iterations) and N (mini-batch size) such that γ1↪ γ2 > 0↪ γ = γ2◁γ1 < 1. Thus, Algorithm 1 converges linearly.
From Corollary 1, if we want to achieve E[G(˜us )] ✏, 8✏ > 0, the number of steps we need to take is roughly s ≥ log( G(˜u0 ) ✏ )◁ log( 1 γ ). In each iteration, we need 2m + n + K(2N + 4) oracle calls. Therefore, the overall query complexity is O((m + n + KN) log 1✏ ). For comparison, the query complexity is O((m + n + 4 ) log(1◁✏)) for comSVRG-1 and O((m + n + 3 ) log(1◁✏)) for com-SVRG-2 [Lian et al., 2016], where is a parameter related to condition number. We will see in simulations in section 4 that the overall query complexity of com-SVR-ADMM is lower than com-SVRG-1 and com-SVRG-2.
Now we prove the convergence property of com-SVRADMM under Assumptions 1 and 4.
Theorem 2. Under Assumptions 1 and 4 , if ⌘s and Gk are chosen as in (11), under Algorithm 2,
where ⇤ > 0.
From Theorem 2, we see that com-SVR-ADMM has an O( log(S+1) S ) convergence rate under the general convex and Lipschitz smooth condition. It improves upon the convergence rate O(S-4◁9 ) in the recent work [Wang et al., 2016b]. In Theorem 2, we consider both the convergence property of function value and feasibility violation. Since G(u) and ♣♣A¯x +B¯!♣♣ are both non-negative, each term has an O( log(S+1) S ) convergence rate.
In the following theorem, we show that our algorithm exhibits O( 1 pS ) convergence rate for both the objective value and feasibility violation, when the objective is a general convex function.
Assumption 7. The gradients/subgradients of all fi, Fi, gj and R(!) are bounded and ♣♣rFi(x)♣♣ CF , CF > 0. Moreover, B is invertible and A↪ B are bounded.
Theorem 3. Under Assumptions 1 and 7, denote
chosen as in (14), there exists a positive ⇥(1) constant ⇢ such that, under Algorithm 2,
where ⇤, C1, C3, C4 are positive constants.
The reason for the introduction of ¯ z is similar to the step taken in [Ouyang et al., 2013], and is due to the lack of Lipschitz smooth property. This result implies an O( 1 pS ) convergence rate for both objective value and feasibility violation.
4 Experiments
In this section, we conduct experiments and compare comSVR-ADMM to existing algorithms. We consider two experiment scenarios, i.e., the portfolio management scenario from [Lian et al., 2016] and the reinforcement learning scenario from [Wang et al., 2016b]. Since the objective functions in both scenarios are strongly convex and Lipshitz smooth, we only provide results for Algorithm 1.
4.1 PortfolioManagement
Portfolio management is usually formulated as meanvariance minimization of the following form:
where ri 2 RN for i 2 ¶1↪ ▷▷▷↪ n♦, N is the number of assets, and n is the number of observed time slots. Thus, ri is the observed reward in time slot i. We compare our proposed comSVR-ADMM with three benchmarks: com-SVRG-1, comSVRG-2 from [Lian et al., 2016], and SGD. In order to compute the unbiased stochastic gradient of SGD, we first enumerate all samples in the data set of g to calculate g(x) and
@g(x), then evaluate @g(x)rfi(g(x)) for a random sample i. Using the same definition of gj(x) and fi(y) and the same parameters generation method as [Lian et al., 2016], we set the regularization to R(x) = θ2 ♣♣x♣♣22 , where θ > 0.
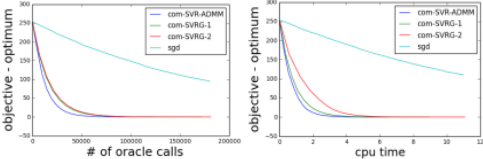
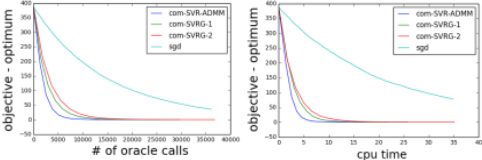
The experimental results are shown in Figure 1 and Figure 2. Here the y-axis represents the objective value minus optimal value and the x-axis is the number of oracle calls or CPU time. We set N = 200, n = 2000. cov is the parameter used for reward covariance matrix generation [Lian et al., 2016]. In Figure 1, cov = 2, and cov = 10 in Figure 2. All shared parameters in the four algorithms, e.g., stepsize, have the same values. We can see that all SVRG based algorithms perform much better than SGD, and com-SVR-ADMM outperforms two other linear convergent algorithms.
4.2 Reinforcement Learning
Here we consider the problem (6), which can be used for onpolicy learning [Wang et al., 2016b]. In our experiment, we assume there are finite states and the number of states is S. ⇡ is the policy in consideration. P ⇡ s↪s0 is the transition probability from state s to s0 given policy ⇡, γ is a discount factor, φs 2 Rd is the feature of state s. Here we use a linear product hφs↪wi to approximate the value of state s. Our goal is to find the optimal w 2 Rd .
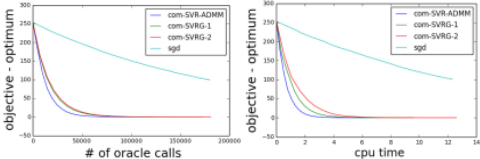
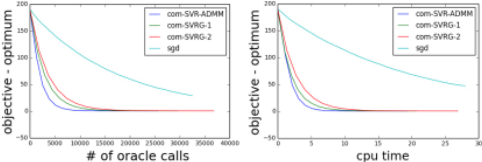
Figure 4: On-policy learning experiment with S = 200, d = 200. The other parameter values is the same as Figure 3.
We use the following specifications for oracles gs0 (w) and fs(y):
Note here gs0(w) 2 R2S , and y[i] denote the i-th element of vector y. All shared parameters in four algorithms have the same values. Note here that the calculation of E[g(w)] is no longer under uniform distribution. We use the given transition probability. In this experiment, the transition probability is randomly generated and then regularized. The reward is also randomly generated. In addition, we include a regularization term R(w) = θ2 ♣♣w♣♣22 with θ > 0. The results are shown in Figure 3 and Figure 4. It can be seen that our proposed com-SVR-ADMM achieves faster convergence compared to the benchmark algorithms.
5 Conclusion
In this paper, we propose an ADMM-based algorithm, called com-SVR-ADMM, for stochastic composition optimization. We show that when the objective function is strongly convex and Lipschitz smooth, com-SVR-ADMM converges linearly. In the case when the objective function is convex (not necessarily strongly convex) and Lipschitz smooth, comSVR-ADMM improves the theoretical convergence rate from O(S-4◁9 ) in [Wang et al., 2016b] to O( log S S ). When the objective is only assumed to be convex, com-SVR-ADMM has a convergence rate of O( 1 pS ). Experimental results show that com-SVR-ADMM outperforms existing algorithms.
Acknowledgements
This work was supported in part by the National Natural Science Foundation of China Grants 61672316, 61303195, the Tsinghua Initiative Research Grant, and the China youth 1000-talent grant.
@inproceedings{ijcai2017p470,
  title     = {Fast Stochastic Variance Reduced ADMM for Stochastic Composition Optimization},
  author    = {Yu, Yue and Huang, Longbo},
  booktitle = {Proceedings of the Twenty-Sixth International Joint Conference on
               Artificial Intelligence, {IJCAI-17}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Carles Sierra},
  pages     = {3364--3370},
  year      = {2017},
  month     = {8},
  note      = {Main track},
  doi       = {10.24963/ijcai.2017/470},
  url       = {https://doi.org/10.24963/ijcai.2017/470},
}
TY - CPAPER TI - Fast Stochastic Variance Reduced ADMM for Stochastic Composition Optimization AU - Yu, Yue AU - Huang, Longbo T2 - Proceedings of the Twenty-Sixth International Joint Conference on Artificial Intelligence, IJCAI-17 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2017 SP - 3364 EP - 3370 DO - 10.24963/ijcai.2017/470 UR - https://doi.org/10.24963/ijcai.2017/470 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





