
Robust Online Optimization of Reward-Uncertain MDPs
Proceedings of the Twenty-Second International Joint Conference on Artificial Intelligence. Pages 2165-2170.
https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-361
© 2011 International Joint Conferences on Artificial Intelligence
Abstract
Imprecise-reward Markov decision processes (IRMDPs) are MDPs in which the reward function is only partially specified (e.g., by some elicitation process). Recent work using minimax regret to solve IRMDPs has shown, despite their theoretical intractability, how the set of policies that are nondominated w.r.t. reward uncertainty can be exploited to accelerate regret computation. However, the number of nondominated policies is generally so large as to undermine this leverage. In this paper, we show how the quality of the approximation can be improved online by pruning/adding nondominated policies during reward elicitation, while maintaining computational tractability. Drawing insights from the POMDP literature, we also develop a new anytime algorithm for constructing the set of nondominated policies with provable (anytime) error bounds. These bounds can be exploited to great effect in our online approximation scheme.
- David Avis. lrs: A revised implementation of the re- verse search vertex enumeration algorithm. In Polytopes- Combinatorics and Computation, pages 177-198. Birkhauser- Verlag, 2000.
- Andrew Bagnell, Andrew Ng, and Jeff Schneider. Solving un- certain Markov decision problems. Technical Report CMU- RI-TR-01-25, Carnegie Mellon University, Pittsburgh, 2003.
- Ralphen Becker, Shlomo Zilberstein, Victor R. Lesser, and Claudia V. Goldman. Solving transition independent decen- tralized Markov decision processes. Journal of Artificial Intel- ligence Research, 22:423-455, 2004.
- Jennifer Boger, Pascal Poupart, Jesse Hoey, Craig Boutilier, Geoff Fernie, and Alex Mihailidis. A planning system based on Markov decision processes to guide people with dementia through activities of daily living. IEEE Transactions on Infor- mation Technology in Biomedicine, 10(2):323-333, 2006.
- Craig Boutilier, Relu Patrascu, Pascal Poupart, and Dale Schu- urmans. Constraint-based optimization and utility elicitation using the minimax decision criterion. Artifical Intelligence, 170(8-9):686-713, 2006.
- Hsien-Te Cheng. Algorithms for Partially Observable Markov Decision Processes. PhD thesis, University of British Columbia, Vancouver, 1988.
- Erick Delage and Shie Mannor. Percentile optimization in un- certain Markov decision processes with application to efficient exploration. In Proceedings of the Twenty-fourth International Conference on Machine Learning (ICML-07), pages 225-232, Corvallis, OR, 2007.
- Simon French. Decision Theory. Halsted, New York, 1986.
- G. Iyengar. Robust dynamic programming. Mathematics of Operations Research, 30(2):1-21, 2005.
- Brendan McMahan, Geoffrey Gordon, and Avrim Blum. Plan- ning in the presence of cost functions controlled by an adver- sary. In Proceedings of the Twentieth International Conference on Machine Learning (ICML-03), pages 536-543, Washing- ton, DC, 2003.
- Andrew Ng and Stuart Russell. Algorithms for inverse rein- forcement learning. In Proceedings of the Seventeenth Inter- national Conference on Machine Learning (ICML-00), pages 663-670, Stanford, CA, 2000.
- Arnab Nilim and Laurent El Ghaoui. Robust control of Markov decision processes with uncertain transition matrices. Opera- tions Research, 53(1):780-798, 2005.
- Marek Petrik and Shlomo Zilberstein. A bilinear programming approach for multiagent planning. Journal of Artificial Intelli- gence Research, 35(1):235-274, 2009.
- Martin L. Puterman. Markov Decision Processes: Discrete Stochastic Dynamic Programming. Wiley, New York, 1994.
- Kevin Regan and Craig Boutilier. Regret-based reward elici- tation for Markov decision processes. In Proceedings of the Twenty-fifth Conference on Uncertainty in Artificial Intelli- gence (UAI-09), pages 454-451, Montreal, 2009.
- Kevin Regan and Craig Boutilier. Robust policy computation in reward-uncertain MDPs using nondominated policies. In Proceedings of the Twenty-fourth AAAI Conference on Artifi- cial Intelligence (AAAI-10), pages 1127-1133, Atlanta, 2010.
- Kevin Regan and Craig Boutilier. Eliciting additive reward functions for Markov decision processes. In Proceedings of the Twenty-second International Joint Conference on Artificial Intelligence (IJCAI-11), Barcelona, 2009. To appear. IJCAI
- Leonard J. Savage. The Foundations of Statistics. Wiley, New York, 1954.
- Huan Xu and Shie Mannor. Parametric regret in uncertain Markov decision processes. In 48th IEEE Conference on De- cision and Control, pages 3606-3613, Shanghai, 2009.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
The use of Markov decision processes (MDPs) to model decision problems under uncertainty requires the specification of a large number of model parameters to capture both system dynamics and rewards. This specification remains a key challenge: while dynamics can be learned from data, residual uncertainty in estimated parameters often remains; and reward specification typically requires sophisticated human judgement to assess relevant tradeoffs. For this reason, considerable attention has been paid to finding robust solutions to MDPs whose parameters are imprecisely specified (e.g., computing robust policies, in the maximin sense, given transition probability uncertainty [2; 9; 12]).
Recently, techniques for computing robust solutions for imprecise reward MDPs (IRMDPs) have been proposed [7; 15; 19]. The specification of rewards can be especially problematic, since reward functions cannot generally be learned from experience (except for the most simple objectives involving observable metrics). Reward assessment requires the translation of general user preferences, and tradeoffs with respect to the relative desirability of states and actions, into precise quantities-an extremely difficult task, as is welldocumented in the decision theory literature [8]. Furthermore, this time-consuming process may need to be repeated for different users (with different preferences).
Fortunately, a fully specified reward function is often not needed to make optimal (or near-optimal) decisions [15]. IRMDPs are defined as MDPs in which the reward function lies in some set R (e.g., reflecting imprecise bounds on reward parameters). In this paper, we address the problem of fast, online computation of robust solutions for IRMDPs. We use minimax regret as our robustness criterion [15; 16; 19]. While solving IRMDPs using this measure is NP-hard [19], several techniques have been developed that allow the solution of small IRMDPs. Of particular note are methods that exploit the set Γ of nondominated policies, i.e., those policies that are optimal for some element of R [16; 19]. Unfortunately, these methods scale directly with the number of dominated policies; and Γ is often too large to admit good computational performance. A subset ˜Γ of the nondominated set can be used as an approximation, and, if specific bounds on the approximation quality of that set are known, error bounds on the minimax solution can be derived [16]; but methods for producing a suitable approximate set with the requisite bounds are lacking.
We develop an approach for approximating minimax regret during elicitation by adjusting the subset ˜Γ online. It allows us to make explicit tradeoffs between the quality of the approximation and the efficiency of minimax regret computation. In online elicitation of rewards, the feasible reward set R shrinks as users respond to queries about their preferences. This means that some undominated policies in ˜Γ become dominated and can be ignored, thus improving online computational efficiency. This, in turn, permits further nondominated policies to be added to ˜Γ, allowing for improvement in decision quality. To support online elicitation and computation, we also develop a new algorithm for constructing the set ˜Γ in an anytime fashion that provides an upper bound on minimax regret. This algorithm is based on insights from Cheng's [6] linear support method for POMDPs.
We first review relevant background on MDPs, IRMDPs and minimax regret. We then discuss how nondominated policies exploited online during reward elicitation, and develop the nondominated/region vertex (NRV) algorithm for generating nondominated policies for IRMDPs. We evaluate our methods on random MDPs and a "real-world" MDP for cognitive assistance.
2 Imprecise RewardMDPs
We assume an infinite horizon MDP 〈S,A, {Psa}, γ, β, r〉, with finite state set S, finite action set A, transition distributions Psa(·) over states (given action a taken in state s), discount factor γ, initial state distribution β, and reward function r : S × A → R. A policy π maps states to actions, and its value is given by V π = ∑s1∈S β(s1)E [∑∞i=1 γ i-1 r(si, π(si)) | π] (where expectation is taken over the state sequence induced by π). We seek an optimal policy π∗ s.t. V ∗ = V π∗ ≥ V π , ∀π.
A policy π induces occupancy frequencies f π (s, a), giving the total discounted probability of being in state s and taking action a. Given f π , the policy can be recovered via π(s, a) = f π (s, a)/ ∑a′ f π (s, a′ ). Because of this direct correspondence, we treat occupancy frequencies and policies interchangeably in what follows. For ease of exposition we use the following vector notation: r is an |S||A| vector with entries r(s, a); f is an |S||A| vector with entries f (s, a); and P is an |S||A| × |S| transition matrix. Define matrix E to be identical to P with 1 subtracted from each self-transition probability Psa(s). The set of valid occupancy probabilities for a fixed MDP is given by F ≡ {f | γE⊤f + β = 0} [14]. We can express the optimal value function in terms of occupancy frequencies: V ∗ = argmaxf∈F f · r.
Specification of reward functions often requires sophisticated human judgements and tradeoffs to be made regarding the precise value of specific states and actions. To minimize the burden of reward elicitation, it is often desirable to elicit only partial reward information [15; 16]. We can model this using an imprecise reward MDP (IRMDP) 〈S,A, {Psa}, γ, β,R〉, in which the reward function r is replaced by feasible reward set R. Intuitively, any reward function r ∈ R might represent the user's preferences, with R determined using some form of preference assessment or elicitation. We restrict attention in what follows to the case where R is a bounded convex polytope defined by linear constraint set {r | Ar ≤ b} and denote the number of constraints by |R|. Such linear constraints arise naturally in reward assessment: a priori bounds on plausible reward values from a domain expert; user responses to elicitation queries comparing reward, policies or trajectories [16]; or policy observation (as in inverse reinforcement learning [11]).
To compute robust policies w.r.t. R we use the minimax regret criterion [5; 18], recently adopted for IRMDPs [16; 19]. Let f be an occupancy frequency (induced by some policy) and r a reward function. Define R(f , r) = maxg∈F g · r - f · r to be the regret of policy f w.r.t. r. Regret measures the difference in value between f and the optimal policy given r. Define pairwise max regret to be PMR(f , g,R) = maxr∈R g · r - f · r; i.e., the maximum value difference between g and f over all possible rewards. Define:
MR(f ,R) is the max regret of a policy f with respect to the feasible reward set R. This is simply the worst case loss over all possible realizations of reward. MMR(R) is the minimax regret of a feasible reward set R, and the occupancy frequency f that minimizes max regret (and the corresponding policy) is the minimax optimal policy. This definition can be interpreted as a game in which a decision maker chooses policy f to minimize loss relative to the optimal policy and an adversary chooses the reward r to maximize this loss given f . The minimax regret criterion compares favorably to the maximin robustness measure also used in the robust MDP literature [9; 10; 12]. While maximin value is more computationally tractable, it leads to conservative policies since the policy is being optimized against the worst case realization of reward. Minimax regret offers a more intuitive measure of performance by assessing the loss of a policy (relative to the optimal policy) given an instantiation of reward, and is empirically a much more effective driver of elicitation than maximin [15].
Several recent approaches to computing minimax regret rely on the concept of policies being nondominated w.r.t. reward polytope R [16; 19]. Formally, we say f is nondominated w.r.t. R iff
Let ΓR denote the set of all nondominated policies w.r.t. to R; we omit the subscript when R is clear from context.
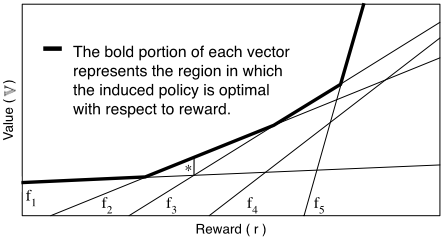
We define V(r) = maxf∈F f · r to be the optimal value obtainable when r ∈ R is the true reward. Since policy value is linear in r, V is piecewise linear and convex (PWLC). Since dominated policies f cannot contribute to this value, we can define VΓ(r) = maxf∈Γ f · r, and immediately see that V = VΓ. Fig. 1 illustrates this for a simplified 1-D reward, with nondominated policy set Γ = {f1, f2, f3, f5} (f4 is dominated, i.e., optimal for no point in reward space).
Given a subset ˜Γ ⊆ Γ of nondominated policies, the function V˜Γ approximates the optimal value function. The Verror of this approximation at point r is:
Define the (global) V-error of the approximation as whole:
In Fig. 1, an asterisk marks the point defining (global) V-error of the approximate set ˜Γ = {f1, f3, f5}, which omits f2 from the nondominated set Γ (the marked, dashed line indicates the magnitude of this error).
While computing minimax regret for IRMDPs is NP-hard [19], several techniques have been proposed for its computation [19; 15; 16]. For example, one can exploit the observation that the adversarial policy (or "witness") g in Eq. 2 must be nondominated [19; 16]; defining
we immediately obtain that MMR(R) = MMR(Γ,R). In [16] this observation is exploited in a simple constraint generation procedure for minimax regret and is shown to outperform other algorithms on small, randomMDPs. The method solves a series of linear programs (LPs):
where GEN is a set of constraints corresponding to a subset of possible adversarial choices of r (and the corresponding optimal policies w.r.t. r). Were GEN to contain all vertices of polytope R, this LP would capture minimax regret exactly. However, since most of these constraints will not be binding at the optimal solution, constraint generation is used. Given the solution f to a relaxed problem with subset GEN, we find the most violated constraint, i.e., the 〈r, g〉-pair that maximizes the regret of f . If no violated constraint exists, then f is the minimax optimal policy.
Since the adversarial policy must lie in the nondominated set Γ, we can find the most violated constraint by solving a small LP for each g ∈ Γ:
The g with the largest objective value determines the maximally violated constraint. This approach is very efficient if the set of nondominated policies is small. However, this is not often the case. A sufficiently small set ˜Γ ⊂ Γ can be substituted to efficiently approximate minimax regret. If we can bound the V-error εV( ˜Γ,R), then the error in minimax regret using this approximate set is bounded by εV( ˜Γ, R); i.e., MMR(Γ, R) - MMR( ˜Γ, R) ≤ εV( ˜Γ,R) [16]. Furthermore, the true max regret of the approximately optimal policy ˜f induced by ˜Γ is bounded: MR(˜f , R) - MMR(Γ, R) ≤ 2εV( ˜Γ,R). Existing approaches to generating nondominated policies do not admit a bound on V-error [16]; to address this, we develop an anytime algorithm in Sec. 4 that generates nondominated policies to directly minimize V-error (with suitable bounds).
Algorithm 1: Online Adjustment during Elicitation
Initialization:
˜Γ0 ← initial nondominated policies (computed offline)
mdp ← the parameters of our MDP model R0 ← initial reward polytope τ ← acceptable level of regret Elicitation:
foreach step t ≥ 1 do
mmr, f , g, r ← ComputeMMR(mdp,Rt-1, ˜Γt-1) response ← SelectAndAskQuery(f , g, r,mdp) Rt ← Refine(response, Rt-1)
˜Γt ← Prune(Rt,˜Γt-1) ∪ Add(Rt, ˜Γt-1)
if mmr < τ then
terminate and return minimax optimal policy f
3 Online Optimization
We now describe how one can best exploit an approximate set ˜Γ of nondominated policies, adjusting this set online to compute increasingly accurate approximations of minimax regret during reward elicitation. During elicitation, the feasible reward set R shrinks as more information is gleaned about the actual reward (e.g., as users respond to queries or behavior is observed). If R′ ⊂ R is the refinement of R given by this additional information, then ΓR′ ⊆ ΓR, i.e., policies that were nondominated w.r.t. R may become dominated when the feasible reward set is reduced to R′ . Since the computational performance of constraint generation using Γ is tightly tied to its size, pruning away newly dominated policies can offer tremendous speed up in minimax regret computation.
Pruning of ΓR′-or its approximation ˜Γ-can be realized as follows: for each f ∈ ˜Γ, we solve a small LP to find a reward point at which f is nondominated:
If the objective δ is negative, then f is dominated and can be pruned from ˜Γ. While pruning can speed up online computation, it can also be used to "create space" to add new nondominated policies to the approximate set ˜Γ. Thus we can improve the quality of the approximation by adding new policies to ˜Γ, while maintaining the same online computational overhead by keeping the size of ˜Γ roughly constant through the effective use of pruning. Adding new policies is a simple matter of running further iterations of a nondominated policy generation algorithm with suitable anytime behavior: we develop just such an algorithm in the next section. 1
These considerations lead to the following online optimization algorithm. Offline (prior to elicitation), we compute an initial approximate set ˜Γ0 of nondominated policies given the prior feasible reward set R0. The size of ˜Γ0 is determined by the demands of efficient online minimax regret computation. At iteration t, minimax regret is computed for Rt-1 using ˜Γt-1 (note that most elicitation schemes require the minimax optimal solution to generate new queries or decide when to terminate the elicitation process in any case [5; 15]). The new set Rt is formed (incorporating constraints given by the query response), and the set ˜Γt is constructed by: (a) pruning policies in ˜Γt-1 that are dominated relative to Rt; and (b) adding new nondominated policies to ˜Γt-1 to improve approximation quality. Alg. 1 outlines how pruning and addition can be integrated into an elicitation algorithm.
1 The entire set Γ could also be computed offline, and policies selectively added as elicitation proceeds.
Many variants of this scheme exist. The pruning and addition of policies need not be done in real time, but can take place in some parallel background process. Minimax regret w.r.t. Rt can be computed using a "lagging" set ˜Γt-k without detriment: error would be determined by the error of the lagging approximate set. And update of ˜Γ can take place asynchronously: whenever a set of update operations has been "completed" relative to any Rt-k, it can be used at stage t.
4 Nondominated Region Vertex Algorithm
The ability to add the most "relevant" new policies to the approximate set ˜Γ in our online procedure allows error in minimax regret to be reduced significantly while maintaining good online computational performance. We now describe a principled anytime algorithm for generating an approximate set ˜Γ which directly minimizes value function error. Our algorithm is an adaptation of Cheng's [6] classic linear support method for POMDPs: rather than computing nondominated α-vectors over belief states, we compute policies that are nondominated w.r.t. uncertain reward. We note that unlike the heuristic technique for generating approximation sets ˜Γ proposed in [16], our algorithm comes with theoretical bounds on error, without which we could not offer the user a guarantee on maximum regret during elicitation.
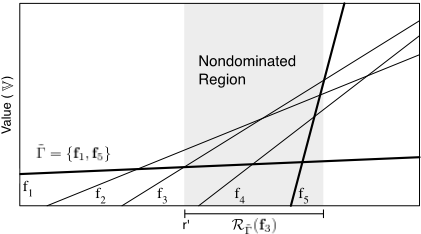
Given an approximate set ˜Γ, let R˜Γ (f) be the nondominated region of policy f w.r.t. ˜Γ:
i.e., that region of R for which f is the best policy in ˜Γ. Fig. 2 illustrates the nondominated region R˜Γ (f3) of policy f3 with respect to the approximate set ˜Γ = {f1, f5} (depicted in bold). The nondominated region R˜Γ (f) for any f ∈ ˜Γ is a bounded, convex polytope. Furthermore, the error function εV( ˜Γ, r) is convex over any such region (since error is defined as the difference between V, which is PWLC, and V˜Γ , which is linear over R˜Γ (f )). Hence the maximum of εV( ˜Γ, r) over the region R˜Γ (f) must lie at a vertex of R˜Γ (f). For example, in Fig. 2 the maximum over R˜Γ (f3) is found at the vertex labelled r′ . As a consequence, the maximum error must lie at the vertex of the nondominated region of some f ∈ ˜Γ:
Lemma 1. The reward that maximizes εV( ˜Γ,R) is found at the vertex of the nondominated region RΓ(f) for some f ∈ ˜Γ.
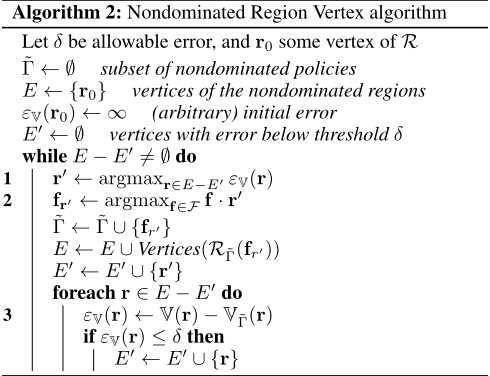
The nondominated region/vertex (NRV) algorithm exploits this fact by computing error only at vertices of such regions, and adding (optimal) policies to ˜Γ only for those vertices with maximal error. The algorithm (Alg. 2) begins with an initial nondominated policy f (optimal for some arbitrary r ∈ R) in ˜Γ. It adds a policy by: (a) computing E˜Γ , the set of vertices of the nondominated regions of ˜Γ; (b) computing the optimal policy fr for each r ∈ E˜Γ ; and (c) selecting the policy that offers the greatest improvement, i.e., such that the error rfr - maxg∈˜Γ rg is maximal. The selected policy is added to ˜Γ and the process repeated until the maximum error at any vertex falls below an acceptable threshold (or some other termination criterion is met). We can show:
Theorem 1. The NRV algorithm with error threshold δ outputs a set ˜Γ satisfying εV( ˜Γ, R) ≤ δ.
As in [6], many efficiencies are exploited that enhance the high-level description in Alg. 2. For example, caching is used to eliminate duplication in computing max error (see line 1), finding the optimal policy (line 2) and computing error at each new vertex (line 3). 2 Secondary information generated by NRV can also be leveraged. By storing the vertex r at which each policy f ∈ ˜Γ was found to be optimal, we can quickly determine whether f remains nondominated by testing whether r remains feasible. If r ∈ R′ (i.e., satisfies the new constraints that refine R), then f remains nondominated. If r /∈ R′ , then we resort to LP (6).
2 Further implementation details can be found in forthcoming technical report. We use the LRS backward search algorithm for vertex enumeration [1] and CPLEX 11.1.1 to solve LPs.
Related Work A connection exists between our approach to identifying nondominated policies and work on solving a restricted class of decentralized MDPs (DEC-MDPs) that feature transition and observation independence [3]. In this setting agents can be viewed as having nearly independent "local MDPs" that are coupled only by a joint reward function. The goal in this work is to cooperatively maximize cumulative reward. Several recent approaches for solving such DEC-MDPs involve identifying the set of policies for each agent that are nondominated with respect to the space of potential policies chosen by the other agents [3; 13]. With some adaptation, our NRV algorithm could be used to solve transition independent DEC-MDPs. Likewise the successive approximation algorithm for DEC-MDPs [13]- which iteratively finds policies that are nondominated with respect to another agent's policies and admits an anytime error bound-could potentially be adapted to generating policies that are nondominated with respect to reward.
5 Empirical Evaluation
We test the NRV algorithm on small MDPs and compare it to πWitness, an existing method for generating nondominated policies [16]. We test both methods on small, randomly generated IRMDPs with factored, additive reward functions. A state s = 〈x1, x2, . . . , x7〉 is composed of 7 binary variables, yielding |S| = 128. We use two different reward functions: the first r(s) = r1(x1) + r2(x2) + r3(x3) with dimension 6; and the second r(s) = r1(x1)+r2(x2)+r3(x3)+r4(x4) with dimension 8. For each MDP we generate a transition model where each (s, a)-pair has log2 |S| random, nonzero transition probabilities. The imprecise reward polytope R is generated as follows: 1) for each (s, a) we select an underlying "true" reward r(s, a) uniformly from a predefined range; 2) we generate the uncertain interval of random size (normally distributed); and 3) we randomly (uniformly) place the interval "around" the true reward r(s, a). We generate 20 MDPs for each reward dimension, and run each algorithm to completion, generating all nondominated policies.
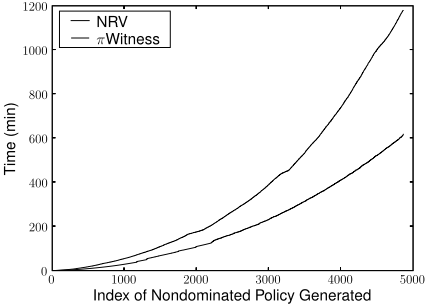
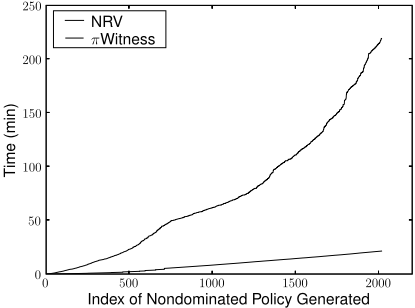
Figs. 3 and 4 show the average runtime of each algorithm. While NRV is more efficient than πWitness on small MDPs, the performance gap narrows as reward dimensionality increases. The most striking advantage of NRV is the availability of an error bound εV( ˜Γ,R) at each iteration. Fig. 5(a) shows that the error εV drops quickly with each added nondominated policy (note the log scale). For example, εV( ˜Γ, R) is reduced to well under 1.0% of its initial value (i.e., when ˜Γ = ∅) after only 500 policies, and to nearly 0.1% after 2000 policies. A small set ˜Γ of nondominated policies can be used to quickly approximate minimax regret as discussed above. We note that ˜Γ can usually be computed only once (offline), prior to elicitation. Minimax regret, conversely, needs to be computed repeatedly and online, since it is integral to many elicitation schemes. Thus offline computation of a small ˜Γ with small error can greatly enhance online performance. For this reason, the extensive offline computation required for computing nondominated sets is not necessarily problematic. However, we can do even more with NRV when allowing approximation in an online setting.
We now examine how NRV, used in conjunction with constraint generation for fast, approximate solution of minimax regret, works in the context of our online optimization scheme. Recall our online model provides the ability to improve the quality of an approximate solution during elicitation, while maintaining tractability. We demonstrate this potential in a specific elicitation setting.
Reward elicitation can proceed using a variety of queries. In our tests, we use bound queries of the form "Is r(s, a) ≥ b?" for simplicity. 3 The choice of query-i.e., which (s, a)- pair to ask about and the parameter b-is dictated by the current solution (CS) heuristic [5; 15]. Let the gap for any (s, a)- pair be
3 More complex queries and methods for MDP reward elicitation are addressed in [17].
CS queries the point (s, a) with the largest weighted gap f(s, a)Δ(s, a), with weight given by occupancy frequency f(s, a) in the current solution f to the minimax regret problem. The bound b is selected to be the midpoint of the gap Δ(s, a). A (yes or no) response to the bound query imposes a linear constraint on R.
Each step of elicitation involves the following: 1) Minimax regret is computed w.r.t. the current reward polytope R; 2) the minimax regret solution is used to select a query using the CS heuristic; 3) the query response is used to refine R. Elicitation terminates once max regret τ reaches an acceptable level. When a nondominated set ˜Γ is used to approximate the minimax optimal policy, we simply require that MMR( ˜Γ, R) + εV( ˜Γ,R) ≤ τ (w.r.t. the current reward polytope R). Online optimization improves solution quality and decreases εV, thus admitting faster termination of elicitation.
We examine our online method in a realistic elicitation scenario using a variant of the COACH MDP, which models a system that provides cognitive assistance for persons with dementia to enable them to complete activities of daily living [4]. Very roughly, the goal is to guide a person through a common task (e.g., hand-washing) by providing verbal or visual cues, while allowing the individual to maintain as much independence as possible. We assume a general task of ℓ steps. The system can issue prompts at increasing levels of intrusiveness, or can call a caregiver (e.g., therapist or family member) to assist the person in task completion. This results in action space A = {0, 1, . . . , k} where 0 indicates no prompt was issued, level k - 1 indicates the strongest, most intrusive prompt and level k indicates that the caregiver was called. The state is defined by three variables S = 〈T, D, F〉 where T = {0, 1, . . . , ℓ} is the number of tasks steps successfully completed by the person, D = {0, 1, 2, 3, 4, 5+} is the delay (time taken during the the current step); and F = {0, 1, . . . , k} tracks whether a prompt at a specific level was attempted at the current step and failed to immediately get the person to the next step. The dynamics express the following intuitions. The no-prompt action will cause a "progress" transition to the next step (setting delay and failed-prompt to zero), or a "stall" transition (same step with delay increased by one). The probability of reaching the next step with action a = n is higher than a = n - 1 since more intrusive prompts have a better chance of facilitating progress; however, progress probability decreases as delay increases. Reaching the next step after prompting is less likely if a prompt has already failed at the current step.
The reward function is r(〈t, d, f〉, a) = rgoal(t) + rprogress(d = 0) + rdelay(d) + rprompt(a), where: rgoal(t) is a large positive reward when t = ℓ for completing the task and is zero when t < ℓ; rprogress(d = 0) is a (small) positive reward for progressing to step t (indicated by d being reset to zero); rdelay(d) is a small negative reward for delay in completing a step; and rprompt(a) is the negative cost associated with prompting the person. The precise values of the rewards are not known but must be elicited from a caregiver. We set ℓ = 14, k = 6 and create an IRMDP by setting initial reward bounds to construct R in a manner similar to the random IRMDPs discussed in the previous section. The resulting IRMDP has size |S||A|=3012 and reward dimensionality |R|=12. We use the NRV algorithm generate ˜Γ with the following criterion in mind. We wish to allow for interactive response times during elicitation, so we choose the size of ˜Γ so that MMR( ˜Γ,R) takes no more than one second to compute. This results in ˜Γ containing less than 5% of all nondominated policies. We further assume that during elicitation there are ten seconds available while waiting for a user response to perform online optimization (pruning and addition) of ˜Γ. During elicitation we compute minimax regret using: a static set ˜Γ with error εV; and a dynamic set ˜Γ′ with decreasing error ε′V, optimized online by pruning and adding policies during the ten-second period provided by response latency.
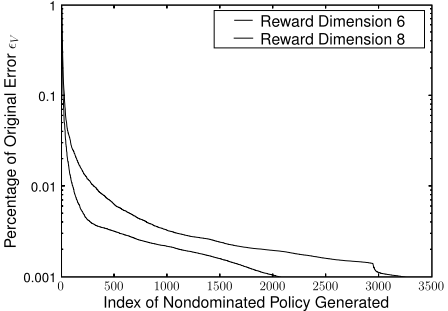
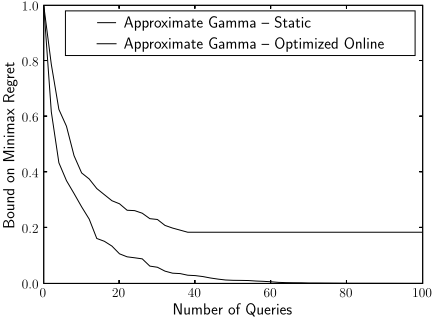
Fig. 6 shows the upper bounds MMR( ˜Γ, R) + εV( ˜Γ, R) and MMR( ˜Γ′ , R)+ εV( ˜Γ′ , R) on max regret produced by the static set and online-optimized set, respectively; it is shown as the percentage of the initial upper bound on minimax regret prior to the start of elicitation. We see that online optimization of the nondominated set provides a tremendous benefit in terms of elicitation. First, without online adjustment of ˜Γ, it is impossible to find the optimal policy: indeed, the static set stalls after roughly 40 queries with minimax regret that is still roughly 18% of the initial regret level. Online online optimization of ˜Γ allows discovery of the optimal policy with approximately 60 queries (this is about 5 simple bound queries per reward parameter). Just as importantly, if an approximately optimal policy is desired, the online-optimized ˜Γ reduces minimax regret to 20% of its initial levels with only about 12 queries on average, while the static approach requires almost 35 queries. In this example, a small ˜Γ with less than 5% of all nondominated policies enables effective reward elicitation, quickly reducing the approximation error to zero if ˜Γ is optimized online. This demonstrates the power of our online approach. A very small set of nondominated policies is needed for fast online computation; but a static set of the required size does not admit an approximation of suitable quality. Pruning newly dominated policies during elicitation and adding new policies using NRV allows one to maintain online feasibility while reducing provable max regret to zero, while supporting effective elicitation (both in terms of number of queries and interactive response time).
6 Discussion and Conclusion
We have presented a method for computing approximate, robust solutions to imprecise-reward MDPs (IRMDPs) in the context of online reward elicitation. The NRV algorithm generates approximate sets of nondominated policies with provable error bounds, which can be leveraged to efficiently approximate minimax regret using existing constraint generation methods. We also showed how online optimization of the nondominated set, as reward knowledge is refined, allows regret to quickly decrease to zero with only a small fraction of all nondominated policies. Our empirical results demonstrate the value of our online approach. Taken together these results remove a significant computational barrier to online reward elicitation for MDPs.
Future research includes developing more general queries, suited to the sequential nature of MDPs, while remaining intuitive and cognitively tractable to users; for example, the use of additive reward models to support elicitation has recently been explored [17]. Other possibilities include policy or trajectory comparisons, which ask a user to assess their relative preference for two state-action sequences (or distributions over these). Since trajectories often contain extraneous information that is irrelevant to reward, trajectory "summaries" which count reward-bearing events could be used. Other potential queries remain to be explored, providing a richer vocabulary for eliciting MDP reward functions, and easing their adoption by practitioners.
Acknowledgements: Thanks to the reviewers for their helpful suggestions. This research was supported by NSERC.
@inproceedings{ijcai2011p361,
  title     = {Robust Online Optimization of Reward-Uncertain MDPs},
  author    = {Regan, Kevin and Boutilier, Craig},
  booktitle = {Proceedings of the Twenty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-11}},
  publisher = {AAAI Press/International Joint Conferences on Artificial Intelligence},
  editor    = {Toby Walsh},
  pages     = {2165--2170},
  year      = {2011},
  month     = {7},
  doi       = {10.5591/978-1-57735-516-8/IJCAI11-361},
  url       = {https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-361},
}
TY - CPAPER TI - Robust Online Optimization of Reward-Uncertain MDPs AU - Regan, Kevin AU - Boutilier, Craig T2 - Proceedings of the Twenty-Second International Joint Conference on Artificial Intelligence, IJCAI-11 PB - AAAI Press/International Joint Conferences on Artificial Intelligence PY - 2011 SP - 2165 EP - 2170 DO - 10.5591/978-1-57735-516-8/IJCAI11-361 UR - https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-361 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





