
DetH*: Approximate Hierarchical Solution of Large Markov Decision Processes
Proceedings of the Twenty-Second International Joint Conference on Artificial Intelligence. Pages 1928-1934.
https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-323
© 2011 International Joint Conferences on Artificial Intelligence
Abstract
This paper presents an algorithm for finding approximately optimal policies in very large Markov decision processes by constructing a hierarchical model and then solving it approximately. It exploits factored representations to achieve compactness and efficiency and to discover connectivity properties of the domain. We provide a bound on the quality of the solutions and give asymptotic analysis of the runtimes; in addition we demonstrate performance on a collection of very large domains. Results show that the quality of resulting policies is very good and the total running times, for both creating and solving the hierarchy, are significantly less than for an optimal factored MDP solver.
- [Barry et al., 2011] J. Barry, L. Kaelbling, and T. Lozano- Pérez. Hierarchical Solution of Large Markov Decision Processes. Technical report, Massachusetts Institute of Technology, 2011.
- [Bertsekas and Tsitsiklis, 1996] Dimitri P. Bertsekas and John N. Tsitsiklis. Neuro-Dynamic Programming. Athena Scientific, Belmont, Massachusetts, 1996.
- [Bonet and Geffner, 2009] Blai Bonet and Hector Geffner. Solving POMDPs: RTDP-Bel vs. Point-based Algorithms. In 21st Int. Joint. Conf. on Artificial Intelligence (IJCAI), Pasadena, California, 2009. IJCAI
- [Bonet and Givan, 2006] Blai Bonet and Bob Givan. Non- Deterministic Planning Track of the 2006 Interna- tional Planning Competition. www.ldc.usb.ve/ %7ebonet/ipc5, 2006. Link
- [Dai and Goldsmith, 2007] Peng Dai and Judy Goldsmith. Topological value iteration. In Twentieth International Joint Conference on Artificial Intelligence, pages 1860- 65, Hyderabad, India, January 2007.
- [Dai et al., 2009] Peng Dai, Mausam, and Daniel S. Weld. Focused topological value iteration. In Nineteenth Inter- national Conference on Automated Planning and Schedul- ing, pages 82-89, Thessaloniki, Greece, September 2009.
- [Dietterich, 1998] Thomas G. Dietterich. The MAXQ Method for Hierarchical Reinforcement Learning. In ICML, pages 118-126, San Francisco, 1998.
- [Hoey et al., 1999] Jesse Hoey, Robert St-Aubin, Alan J Hu, and Craig Boutilier. Spudd: Stochastic planning using de- cision diagrams. In Uncertainty in Artificial Intelligence, Stockholm, Sweden, 1999.
- [Mehta et al., 2008] Neville Mehta, Soumya Ray, Prasad Tadepalli, and Thomas Dietterich. Automatic Discovery and Transfer of MAXQ Hierarchies. In ICML-08, Helin- ski, Finland, 2008.
- [Sanner and McAllester, 2005] S. Sanner and D. McAllester. Affine algebraic decision diagrams and their application to structured probabilistic inference. In Nineteenth Interna- tional Joint Conference on Artificial Intelligence, 2005.
- [Sanner et al., 2010] S. Sanner, W. Uther, and K. V. Del- gado. Approximate dynamic programming with affine adds. In Ninth International Conference on Autonomous Agents and Multiagent Systems, Toronto, Canada, 2010.
- [St-Aubin et al., 2000] Robert St-Aubin, Jesse Hoey, and Craig Boutilier. Apricodd: Approximate policy construc- tion using decision diagrams. In Neural Information Pro- cessing Systems, Denver, CO, 2000.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Our goal is to find good, though not necessarily optimal, solutions for large, factored Markov decision processes. We present an approximate algorithm, DetH*, which applies two types of leverage to the problem: it shortens the horizon using an automatically generated temporal hierarchy and it reduces the effective size of the state space through state aggregation.
DetH* uses connectivity heuristics to break the state space into a number of macro-states. It then assumes that transitions between these macro-states are deterministic, allowing it to quickly compute a top-level policy mapping macro-states to macro-states. Once this policy has been computed, DetH* solves for policies in each macro-state independently. We are able to construct and solve these hierarchies significantly faster than solving the original problem.
We represent factored MDPs compactly as algebraic decision diagrams (ADDs) as done by the SPUDD algorithm [Hoey et al., 1999]. In order to maintain efficiency in large problems, our algorithm is composed of operations on ADDs and BDDs and so avoids ever enumerating the states in the domain. We make use of the independencies in the domain dynamics that are revealed by the structure of the ADD representation, and we use the SPUDD algorithm to solve the MDPs that constitute the individual macro-states. SPUDD naturally reduces the size of the effective state space by aggregating sets of states with the same value.
∗This work was supported in part by ONR MURI grant N0001409-1-1051 and in part by AFOSR grant AOARD-104135.
There are two important related lines of work, focusing either on factoring or on decomposition of large MDPs. Improvements on factored MDP solvers continue to treat the MDP as a single problem, but find more compact [Sanner and McAllester, 2005; Sanner et al., 2010] or approximate [StAubin et al., 2000] representations. Recent work on topological and focused topological value iteration [Dai and Goldsmith, 2007; Dai et al., 2009] is similar to ours in that it decomposes a large MDP based on the connectivity of the states. However, TVI and FTVI cannot exploit a factored representation and, in a well-connected domain, they are not guaranteed to find any hierarchy at all. FTVI has been run successfully on some smaller factored problems, but requires knowledge of an initial state to reduce the state space size. Moreover, the size of the value function output by TVI or FTVI is necessarily the size of the optimal value function and, therefore, these cannot be run in domains where the representation of the optimal value function is prohibitively large. By relaxing the requirement that the algorithm output the optimal policy, we can find a good approximate policy even in some large problems where the optimal value function is not compactly representable. Our work is also similar to MAXQ [Dietterich, 1998; Mehta et al., 2008] in that it uses a temporal hierarchy to reduce the size of the state space. However, unlike the original MAXQ algorithm, we are able to construct the hierarchy automatically. Although the work of Mehta et al. proposes a method for automatically creating MAXQ hierarchies, the hierarchy creation is costly and only worthwhile if it transfers to many domains.
We begin by introducing our hierarchical model of an MDP. We then discuss how DetH* creates and solves this model and conclude by presenting results on a set of large domains.
2 Hierarchical Model
In this paper, we restrict ourselves to creating and solving hierarchical models with only two levels and for simplicity explain only the two level hierarchy model. However, the extension to multi-level hierarchies is straightforward.
An MDP can be described as M = 〈S,A, T,R〉 where S is a finite set of states, A is a finite set of actions, T is the transition model with T(x, a, x′ ) specifying the probability of a transition to state x′ given that the system starts in state x and selects action a, and R is the reward model with R(x) specifying the real-valued reward of state x. In addition, we assume a pre-specified set of goal states, G ⊂ S. Goal states are zero-reward absorbing states: for every g ∈ G and a ∈ A, T(g, a, g) = 1 and R(g) = 0. Further, we assume that all other reward values are strictly negative. We solve this problem under the undiscounted total reward criterion, making it a 'negative stochastic shortest path' problem. Any discounted MDP can be transformed into an 'equivalent' negative stochastic shortest path problem, which can then be solved to produce the optimal policy for the original MDP [Bertsekas and Tsitsiklis, 1996; Bonet and Geffner, 2009].
A factored MDP is an MDP and a set of state variables X = {X1 , ..., Xn }. For each variable Xi , we assume a finite set of possible values ΩXi = {Xi1 , ...,Ximi }. A state of the MDP is specified by a single assignment to each state variable; the value of variable Xi in state x ∈ S is given by xi . We represent the transition model using a collection of ADDs in the manner of SPUDD; for each action and for each value of each variable, Xi j , an ADD specifies the probability that Xi will have value Xi j on the next time-step. The reward is represented as a single ADD.
A (two level) hierarchical model of a factored MDP consists of a factored MDP and a set of macro-states, U, which partition the state space. Each macro-state in U is a set of states of the original MDP (primitive states), represented as a binary decision diagram (BDD). U must contain a single macro-state g = G, called the goal macro-state, which is exactly the set of primitive goal states. Given a macro-state u, we say that a variable value Xi j ∈ u if there exists some primitive state x ∈ u with xi = Xi j . A hierarchical policy π = {πU , πS} consists of an upper-level policy πU and a lower-level policy πS. The policy πU maps each macro-state u ∈ U to another macro-state u′ ∈ U, signifying that when the system is in a primitive state contained in u it should attempt to move to some primitive state in u′ . The policy πS is a standard MDP policy, represented as an ADD, mapping the primitive states to primitive actions.
3 DetH* Overview
The DetH* algorithm takes as input an MDP represented using ADDs and outputs a hierarchical policy. The input representation is the same that of SPUDD. The algorithm works in three stages:
- It computes a set of macro-states, U, for the MDP that partition the state space. We discuss the clustering algorithm used to create these macro-states in Section 5.
- It computes an upper-level policy πU mapping each macro-state in U to another macro-state in U. We explain this algorithm in Section 4.
- It uses πU to break the original, large MDP into many smaller sub-MDPs. Specifically, for each macro-state u ∈ U, it creates a sub-MDP by setting all states in πU(u) to have the fixed value 0 and setting all states
not in u or πU(u) to have a fixed value -Δ where Δ is large. No other modifications are made to the original transition and reward model of the MDP and any factored MDP solver can be used to solve for a policy in this sub-MDP. Since the macro-states partition the state space, πS is just the union of the policies of the subMDPs.
We begin by describing step 2 of DetH* as it will motivate the choices we make in designing the clustering algorithm.
4 Solving the Hierarchical FactoredMDP
The solver takes as input a hierarchical model of a Markov decision process (MDP) and outputs a policy, πU on the macrostates of the hierarchy. We will discuss how to find the hierarchical model in Section 5.
4.1 Algorithm
To find πU, we approximate the transitions between macrostates as being deterministic. Given a function C(u, u′ ), representing the cost to transition from macro-state u ∈ U to macro-state u′ ∈ U, DetH* uses Dijkstra's algorithm to find a shortest path, 〈u, v1, v2, ..., g〉, for each macro-state u ∈ U to g. It sets πU(u) = v1.
Cost Model
To model the cost C(u, u′ ) of transitioning from macro-state u to u′ , we assume that, at the primitive level, any action a ∈ A taken in state x ∈ S with goal of ending in state x′ ∈ S does make a transition to x′ with probability T(x, a, x′ ), but that with the remaining probability mass, it stays in state x. Executing such an action a repeatedly will, in expectation, take 1/T(x, a, x′ ) steps to move to state x′ , each of which incurs cost -R(x). We can select whichever action would minimize this cost, yielding a deterministic cost estimate at the primitive level of
If there is no action that causes a transition from x to x′ then the cost of transitioning between the two is infinite. This cost model is unlikely to reflect the exact dynamics of the domain, but it allows us to incorporate both the transition probabilities and reward into the cost calculation in an efficiently computable manner.
Let U(x) be the macro-state containing x (since the macrostates are a partition, U is a function). We define d(x, x′ ) as the shortest distance, using C as a cost measure, from x to x′ considering only states in U(x) and U(x′ ). For macro-state u′ , let du′ (x) = minx′∈u′ d(x, x′ ), the shortest distance from some primitive state x to some x′ ∈ u′ considering only states in U(x) and u′ . We define C(u, u′ ) as the average over the du′ (x) for x ∈ u:
Given two macro-states, u and u′ , we can calculate C(u, u′ ) using Dijkstra's algorithm to find du′ (x). Because of the factored representation, du′ (x) is likely to be identical for many x ∈ u and we can use ADD operations to treat all states with the same du′ (x) compactly.
Approximate Cost Model
Even using ADDs, the representation of the cost C tends to grow exponentially quickly, so we approximate C by assigning the same distance value to all primitive states within u that can reach πU(u) in the same minimum number of actions.
Specifically, we break u into the set of sub-macro-states {u1, ..., uz(u,u′ )} such that for x ∈ uj , x can reach some substate of u′ with non-zero probability in j actions and no fewer. The quantity z(u, u′ ) is the smallest j such that all sub-states in u that can reach some sub-state in u′ with non-zero probability can do so in j actions or fewer. If some sub-states of u cannot reach a sub-state of u′ , they are not included in the sub-macro-states. We approximate the cost C of transitioning from sub-macro-state uj to uj-1 as the average cost of transitioning from a state in uj to a state in uj-1:
which can be calculated efficiently using ADD operations. Note that since all x ∈ uj can reach some state in u′ in j actions and no fewer and all x′ ∈ uj-1 can reach some state in u′ in j - 1 actions and no fewer, every state in uj has a non-zero transition probability to some state in uj-1 and C(uj, uj-1) is finite. Letting u0 = u′ , this gives us the approximation of C, C ′ :
Solver
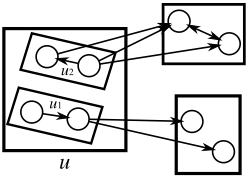
Given C ′ , we could simply use Dijkstra's algorithm on the macro-states to find πU. However, consider the case of the hierarchy shown in Figure 1. In this hierarchy, there is a macro-state u ∈ U that is made up of two distinct sets of primitive states, u1 and u2, such that there is no macro-state u′ ∈ U such that all sub-states of u can reach some sub-state of u′ . Therefore, whatever the value of πU(u), there will be some primitive state x ∈ u such that x cannot reach a substate of πU(u). This could result in an infinite negative value for x under πS even if the optimal value function is finite everywhere. To avoid this, when calculating C ′ (u, u′ ), we calculate C ′ for only those sub-states uR ⊆ u that can reach some sub-state of u′ . If, after the cost calculation, u′ is on the current path-to-goal for uR, we split u into uR and u \ uR. This allows us to guarantee the following:
Theorem 1: Let π∗ be the optimal policy for an MDP M and let πS be the policy found by DetH* on any hierarchy and VπS be the associated value function. Provided that for all x ∈ S, VπS (x) > -Δ, then for any x ∈ S, if x has a nonzero probability of reaching some goal state under π∗ , then x will also have a non-zero probability of reaching some goal state under πS.
Proof: Proof of all theorems in this paper can be found in the associated technical report [Barry et al., 2011].
Corollary 2: Let V ∗ be the optimal value function for an MDP M and let πS be the policy found by DetH* on any hierarchy and VπS be the associated value function. Provided that for all x ∈ S, VπS (s) > -Δ, if V ∗ is finite for all x ∈ S, VπS will be finite for all x ∈ S.
We can also give an asymptotic upper bound on the running time of the solver. We do this in terms of the set of macro-states H, which is the set of macro-states after running the solver. For state x, we define T(x) = πU(U(x)) to be the target macro-state from U(x). The bound relies on three quantities: |H|, the number of macro-states after running the solver, Z = maxh∈H z(h, T(h)), the maximum number of actions required for any primitive state x to move from U(x) to its target macro-state T(x), and B, the size of the largest BDD representation of a set of states seen while creating or solving the hierarchy.
Theorem 3: The running time of the upper level solver is O(|H|2ZB2 ).
Proof Sketch: The running time of the upper level solver is dominated by |H|2 calculations of C ′ . Calculating C ′ requires O(|Z|) calls to C, each of which takes O(B2 ).
4.2 Accuracy
Dietterich (1998) introduced the terms hierarchically and recursively optimal for discussing the polices associated with a hierarchy. These criteria assume a fixed hierarchy with known sub-goals at lower levels, which allows the problem to be solved bottom-up, with higher levels guaranteeing optimality subject to the quality of solutions at levels below. In DetH*, we do not assume that appropriate subgoals are known in advance; we must determine them, top-down, and so the resulting policies will not generally be hierarchically or recursively optimal. However, we can still bound the suboptimality of the resulting policy.
We define O(x) = {x′ |x′ ̸∈ (U(x)∪T (x))} to be the "out" set of primitive states neither in the macro-state of x nor its target. Let B∗ x,x′ be the probability that the first primitive state not in U(x) reached under π∗ is x′ . Similarly BπS x,x′ is the probability that the first primitive state not in U(x) reached under πS is x′ .
Algorithm 1 Input: g: the goal macro-state Output: A set of g-connected macro-states.
SIMPLE-CLUSTER(g) 1 U ← {g} 2 while ∃ unclustered states that can reach the goal 3 for each macro-state u created on the last iteration 4 // all unclustered states that reach u in 1 step n ← REGRESS(u, unclustered, 1) 5 U ←U ∪ n 6 U ←U∪macro-state consisting of any unclustered states 7 return UDai and Goldsmith (2007) showed that dividing a domain into macro-states and solving each macro-state separately can result in an optimal solution. The error that DetH* incurs arises from two differences between the set of macro-states it uses and the topologically sorted set proposed by Dai and Goldsmith. Drift measures error due to coercing the process to stay within a macro-state until exiting to the target macrostate, rather than moving to an out state:
Heterogeneity measures the error incurred from having a suboptimal arrival distribution over primitive states in the target macro-state:
Theorem 4: Provided that for all x ∈ S, VπS (x) > -Δ,
Because for any x in G, E(x) = 0, error in the other primitive states can be characterized by backward induction on the graph defined by πU .
In constructing a hierarchical model, we can attempt to reduce the drift term by creating macro-states that the optimal policy would prefer not to exit, or to exit by chance. We can attempt to reduce the heterogeneity term by creating macrostates whose primitive states have similar values.
5 Creating the Hierarchical Model
Given a factored MDP, we create a hierarchical model with the goal that it be solvable both accurately and efficiently.
g-Connected Clustering
We wish to create a set of macro-states U which require very little splitting during solution, which will occur if there already exists a policy on U for which Theorem 1 holds. To this end we define the property of g-connectedness:
Definition 5: A set of macro-states U with goal macro-state g is g-connected under policy πU if
- For all u ∈ U, if u contains any primitive state that can reach a goal state under the optimal policy, u can reach g under πU .
Algorithm2 Input: g: the goal macro-state, Υ: themaximum number of macro-states Output: A hierarchy for use with the DetH* solver.
CLUSTER(g, Υ) 1 // First create a large number of initial macro-states U, r ← SPLIT(g, Υ, 1) 2 while ∃ unclustered states that can reach the goal 3 for each macro-state u created on the last iteration 4 // all unclustered states that reach u in ≤ r steps n ← REGRESS(u, unclustered, r) 5 for Xi ∈ X 6 // Reduce drift by adding states 7 n ← GROW(n, unclustered, Xi ) 8 U ←U ∪ n 9 U ←U∪macro-state containing any unclustered states 10 return U SPLIT(g, Υ, r) 1 U ← {S \ g}, split ←True 2 while split and |U| < Υ 3 split ← False, U ′ ← {} 4 for u ∈ U 5 // the subset of u that can reach g in ≤ r steps N ← {REGRESS(g, u, r)} 6 for Xi ∈ X 7 N ′ ← {} 8 for n ∈ N 9 P ←partition of n s.t. for Xi j ∈ nl, all Xik i-reachable by Xi j through n are in nl. 10 if ∀nj, nk ∈ P s.t. ∀Xim ∈ nj,Xip ∈ nk, Xim cannot i-reach Xip 11 // Exogenous variable. P ← {n} 12 if |P| > Υ, return SPLIT(g, Υ, r + 1) 13 if |P| > 1, split ←True 14 for each nj ∈ P 15 nj ← GROW(nj , unclustered, Xi ) 16 N ′ ←N ′ ∪ {nj} 17 N ←N ′ 18 U ′ ←U ′ ∪N 19 U ←U ′ 20 return U ∪ {g}, r GROW(u, Q, Xi ) 1 u′ ←empty macro-state 2 for x ∈ u 3 u′ ← u′ ∪ {x′ ∈ Q|x′i can i-reach xi through Q∪ u in less than maxj |ΩXj |/2 steps, x′i ∈ u, and for j ̸= i, x′j = xj } 4 return u′- For all u ∈ U, every sub-state of u can reach some substate of πU(u) without leaving u.
U is g-connected if there exists some policy under which it is g-connected.
For example, the set of macro-states shown in Figure 1 is not g-connected because, to fulfill the second condition of the definition, a policy must map u to u and this cannot fulfill the first condition.
The function REGRESS(ug, ua, i) returns all states in ua that can reach some state in ug in i steps or fewer. Therefore, a simple method for creating g-connected clusters is to repeatedly call REGRESS as shown in Algorithm 1.
Theorem6: SIMPLE-CLUSTER creates g-connected macrostates.
Proof Sketch: By induction over Uk, the set of macro-states after the kth call to REGRESS.
Base Case: U0 = {g} is trivially g-connected.
Induction Step: Let πUk-1 be a policy under which Uk-1 is g-connected. Assume we regress macro-state uk-1 on iteration k creating macro-state uk. For v ∈ Uk-1, let πUk (v) = πUk-1 (v). Set πUk (uk) = uk-1. Since all substates of uk can reach some sub-state of uk-1 by definition of REGRESS, it follows by induction that πUk is a policy under which Uk is g-connected.
Improving Clustering
SIMPLE-CLUSTER usually returns a small number of large macro-states so that solving each macro-state is costly. In addition, although the macro-states are g-connected, once πU is determined, each macro-state may still have a significant heterogeneity and drift error, decreasing the accuracy of the solution. To improve efficiency, we would like to make more macro-states; to improve accuracy, we would like to decrease their drift and heterogeneity.
However, attempting to decrease drift and heterogeneity while using exact reachability on primitive states is very expensive in large domains. We use the factored structure of the transition model to define an efficiently-computable approximate notion of connectivity by considering the connectivity of each state variable separately.
Define a variable value Xi j to be adjacent to a variable value Xik if Xi j = Xik or there exist states x, x′ ∈ S with xi = Xik and x′i = Xi j and action a ∈ A such that T (x, a, x′ ) > ϵ where ϵ is a small (possibly zero) user-defined constant. Only variable values of the same variable can be adjacent.
Definition 7: Primitive state x′ ∈ S is i-adjacent (independently adjacent) to state x ∈ S if, for all Xi ∈ X, x′i is adjacent to xi . Amacro-state u′ ∈ U is i-adjacent to a macrostate u ∈ U if there exist primitive states x′ ∈ u′ and x ∈ u such that x′ is i-adjacent to x. An element (variable value or state) j is i-reachable from an element i if j is i-adjacent to i or j is i-reachable from some element k that is i-adjacent to i. A set of macro-states is ig-connected if they are g-connected under i-adjacency.
Note that the existence of a ∈ A such that T(x, a, x′ ) > ϵ is sufficient for x′ to be i-adjacent to x, but not necessary. In most domains many more states will be i-adjacent than are actually adjacent. While the solver will be most efficient when ig-connectedness implies actual g-connectedness, all of the results of Section 4 hold for any hierarchy input to the solver.
Pseudo-code for creating improved ig-connected clusters is shown in Algorithm 2. CLUSTER addresses the problems of few macro-states, drift, and heterogeneity in two ways.
Improving Drift: The GROW function adds to eachmacrostate a large number of primitive states that can easily i-reach the macro-state u in an attempt to reduce the drift error in later created macro-states by ensuring that states that can easily ireach u are part of u. The limit of maxi |ΩXi |/2 is in place on line 3 of GROW to keep all states from being placed into the same macro-state in well connected domains.
Improving Heterogeneity: The SPLIT function creates several initial macro-states, which addresses the problem of few macro-states and heterogeneity. Since each macro-state created in SPLIT will be regressed separately on line 4 of CLUSTER, the splits made in this function will propagate, creating a much larger number of macro-states than if we simply called REGRESS repeatedly. 1
The SPLIT function essentially splits a macro-state based on i-reachability so that the resulting macro-states contain only those primitive states which can i-reach each other. Primitive states that can easily i-reach one another are likely to have similar values, addressing the issue of heterogeneity. Because we use i-reachability, we can consider each variable separately, which allows this computation to be performed efficiently. The procedure for splitting a macro-state into partitions containing only primitive states that can i-reach each other is shown on lines 6-9 of SPLIT.
However, we found that splitting macro-states only on ireachability created far too many macro-states if there were many variables in the domain whose values were not wellconnected. We use the check on line 10 to identify variables with large numbers of values that cannot reach each other. The partition formed on line 9 of SPLIT only considers reachability through the current macro-state n. Line 10 checks if there is a path between two partitions through the entire domain, although there may not be one in n. If the partitions could never reach one another then we do not split the macro-state. This check is an attempt to identify exogenous variables, variables over which the agent has no control. These variables often have values set a priori that never change so splitting on them creates a large number of macrostates. Moreover, for many values of an exogenous variable, the value function is the same over a short horizon. Therefore, there is no need to split on the values of an exogenous variable; it will neither improve the homogeneity of the macrostate nor the efficiency of the solution at the bottom level.
Even attempting to avoid splitting on exogenous variables, it is possible that SPLIT creates too many macro-states, In this case, we redo SPLIT on line 12 by forming a macro-state that contains all primitive states that can reach a goal state in two steps rather than one. This larger macro-state is likely to split into fewer partitions.
Because we consider each variable individually, after partitioning and growing the macro-states, it is possible that repeating the process will give us an even more refined set of macro-states. Therefore, we repeat the process until convergence is reached or we have a maximum number of macrostates.
1 In a very large domain, it is possible that better clusters could be created by splitting later macro-states as well, but, in general, this will create so many macro-states that the factors of |H| in the running time of the solver will have a noticeable impact on running time. We found that just splitting the first macro-state worked well on all domains we tried.
Theorem 8: The macro-states created by CLUSTER are igconnected and partition the state space.
Proof Sketch: In SPLIT, we initially call REGRESS on the full set of non-goal states. Subsequently, we partition the states and then only add to them states that have not yet been added to a macro-state. Similarly, during the main loop of CLUSTER, we only consider the set of states not yet clustered when we REGRESS and GROW macro-states. Therefore, the resulting macro-states partition the state space.
By Theorem 6, repeatedly calling REGRESS creates gconnected clusters. Now consider the GROW(u, Q, Xi ) function where u is some macro-state belonging to a g-connected set of macro-states U and let πU be some policy under which U is g-connected. The call to GROW creates a new set of macro-states U ′ = (U \u)∪u′ where u′ = GROW(u, Q, Xi ), which we claim is ig-connected. For v ∈ (U \ u), let πU ′(v) = πU(v) if πU(v) ̸= u and u′ otherwise. Set πU ′(u′ ) = πU(u). Since u ⊆ u′ , for macro-state v ∈ U, all sub-states of v can i-reach some sub-state of πU ′ (v) without leaving v. Now consider u′ . For each x ∈ u′ , either x ∈ u or x can i-reach some x′ ∈ u without leaving u′ by line 3 of GROW. Therefore, for all x ∈ u′ , x can i-reach some substate of πU ′(u′ ) and U ′ is ig-connected under πU ′ .
The proof that SPLIT creates ig-connected macro-states is similar. An induction over the calls to REGRESS, SPLIT, and GROW completes the full proof.□
In practice, to save computation time, we break the igconnectivity slightly: we always let Q = S for the GROW function and compute the partition afterwards by subtracting earlier created macro-states from later ones. We also estimate reachability for the variable values by assuming that all values can only reach one sink and therefore that all values that reach the same sink should be put in the same partition.
Theorem 9: The running time of CLUSTER is O(|H|ZB2 ).
Let |VH| be the size of the largest value function, in terms of the ADD representation, that SPUDD constructs during the solution of any macro-state in stage 3 of DetH*, and IH be the largest number of iterations SPUDD requires in any macro-state. Then
Theorem 10: The total running time for DetH* is bounded by O(|H|2ZB2 ) + O(|H|IHB|VH |).
Proof Sketch: The running time of CLUSTER is dominated by the running time of the upper level solver. For each macrostate, each iteration of SPUDD is bounded by O(B|VH|) so stage 3 is bounded by O(|H|IHB|VH|).
Efficiency Advantage of DetH*: The effect of DetH* is to break the solution of one large SPUDD problem into many smaller problems. Although the number of iterations, IH, that SPUDD requires is not easily evaluated in the infinite horizon case, intuitively it should be approximately upper bounded by the number of states with different values, which can be upper bounded |VH|, giving us a running time of O(|VH|2 ) for SPUDD. Therefore, we expect that the divide-and-conquer approach of DetH* will show an improvement in the same manner as topological value iteration improves value iteration. However, because of the manner in which we create sub-MDPs, the running time improvement is likely to be even more significant. For each sub-MDP, we only allow the values of the states in that sub-MDP to change, fixing the rest at 0 or -Δ. This can exponentially decrease the size of the resulting value function as shown in Figure 2. Therefore, in almost all cases, |VH| ≪ |V |, the largest value function SPUDD considers in solving the flat problem, and DetH* can solve problems for which the representation of the optimal value function (or even some intermediate value function) is too large to be machine-representable. Unfortunately, there are pathological cases in which, by forcing states in u to choose actions that will push them towards πU(u), we can have |VH| > |V |, but we expect that these cases are very rare in practice. An example of such a pathological case can be found in Barry et al., 2011.
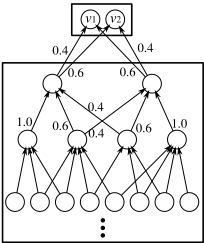
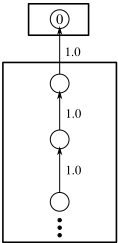
Figure 2: An MDP in which |VH| ≪ |V ∗ |. Here sets of primitive states with different values are shown as small circles and macro-states are shown by the rectangles. Actions are shown as arrows with the probability of transition written on the edge (to avoid clutter, we assume all rewards are -1). To find the optimal solution, two distinct values of the top macro-state must be considered, as shown in (a), which leads to an exponential explosion in the number of different values in the bottom macro-state. Therefore, both the SPUDD and (F)TVI would be unable to solve this problem. However, DetH* solves the bottom macro-state by assuming all values in the top macro-state are zero as shown in (b). Therefore, it is able to aggregate many more states together, resulting in a much smaller representation of the value function in the bottom macro-state.
6 Results
We compared DetH* against SPUDD 3.6.2, which is a stateof-the-art optimal solver for factored domains. In order to illustrate our point about using any solver at the bottom level, we used two different variable orderings of primed variables relative to unprimed variables. The SPUDD default ordering is shown as Order2, while an ordering which places all primed variables above unprimed variables is shown as Order1. Since one of DetH*'s major advantages over SPUDD is shortening the horizon, we also compared to SPUDDO , an idealized version of SPUDD with a horizon oracle that knew in advance the best time/accuracy trade-off for running SPUDD. Because we solve using an undiscounted model, in domains where not all states can reach a goal state, SPUDD will never terminate. In these domains, we attempted to pick a horizon that gave the optimal policy (listed under SPUDD) and then tried to find the shortest horizon that gave a reasonable approximate policy (listed under SPUDDO ). In some domains we showed that running SPUDD to anything less than convergence resulted in infinitely bad policies since a state that could reach a goal state under the optimal policy could no longer reach a goal state under the approximate policy. In these domains, we report that SPUDDO was unable to find a good policy. We ran the algorithms on instances of five domains:
| Domain | SPUDD | SPUDDO | DetH* | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Name | Variables | Actions | Order1 | Order2 | Order1 | Order2 | Order1 Time | Order2 Time | Value | ||||
| Time | Value | Time | Value | Time | Value | Time | Value | ||||||
| factory | 25 | 15 | 156.6 (50) | -17.2 | 41.3 (50) | -17.2 | 119.2 (40) | - | 31.7 (40) | - | 19.0 | 7.9 | -18.5 |
| tire50 | 25 | 166 | 34.8 (6) | 0.77 | 23.8 (50) | 0.83 | 1.5 (5) | 0.75 | 0.2 (6) | 0.77 | 27.7 | 12.0 | 0.75 |
| tire80 | 27 | 254 | 127.3 (6) | 0.64 | 268.9 (50) | 0.73 | 1.0 (5) | 0.62 | 0.3 (6) | 0.64 | 52.8 | 32.2 | 0.63 |
| tire90 | 33 | 291 | 1556.0 (6) | 0.70 | 2063.9 (50) | 0.76 | 12.2 (5) | 0.67 | 0.5 (6) | 0.70 | 85.3 | 48.4 | 0.69 |
| tire110 | 45 | 364 | - (6) | - | > 105 (50) | - | 6415.8 (5) | 0.74 | 0.6 (5) | 0.74 | 266.2 | 126.8 | 0.75 |
| tire120 | 45 | 391 | - (6) | - | > 105 (50) | - | 38.6 (5) | 0.67 | 0.5 (5) | 0.67 | 7328.8 | 108.0 | 0.66 |
| elev10-8 | 20 | 3 | 57.3 | -18.6 | 18.3 | -18.6 | 31.4 (25) | -18.6 | 10.6 (25) | -18.6 | 7.8 | 7.7 | -18.9 |
| elev10-10 | 24 | 3 | 485.2 | -20.1 | 256.2 | -20.1 | 219.7 (25) | -20.1 | 71.3 (25) | -20.1 | 8.7 | 6.2 | -20.8 |
| elev10-12 | 28 | 3 | 3921.1 | -24.9 | 923.3 | -24.9 | 1614.4 (30) | - | 390.8 (30) | - | 104.9 | 95.0 | -25.7 |
| trash3-40 | 51 | 4 | 236.5 | -15.4 | 2.3 | -15.4 | 231.0 (29) | - | 2.1 (29) | - | 2.0 | 1.2 | -16.8 |
| trash3-50 | 61 | 4 | 344.3 | -17.9 | 3.2 | -17.9 | 324.7 (30) | - | 2.6 (30) | - | 3.1 | 1.9 | -19.9 |
| trash3-60 | 71 | 4 | 421.6 | -19.9 | 4.4 | -19.9 | 378.5 (30) | - | 2.7 (30) | - | 3.6 | 2.4 | -23.0 |
| trash3-90 | 102 | 4 | 823.5 | -27.7 | 7.8 | -27.7 | 791.6 (50) | - | 7.4 (50) | - | 10.5 | 5.8 | -33.0 |
| trash5-40 | 51 | 4 | 19496.8 | -17.2 | 23.5 | -17.2 | 19254.3 (30) | - | 16.5 (30) | - | 2.1 | 1.4 | -18.0 |
| trash5-60 | 71 | 4 | 35642.7 | -22.3 | 37.4 | -22.3 | 34751.1 (30) | - | 16.8 (30) | - | 4.2 | 2.7 | -24.4 |
| surv3-3 | 17 | 11 | 54.9 | -7.2 | 18.9 | -7.2 | 0.2 (4) | -7.5 | 0.05 (4) | -7.5 | 1.9 | 1.9 | -10.0 |
| surv3-5 | 24 | 25 | - | - | - | - | 100.4 (4) | -5.5 | 1.4 (4) | -5.5 | 57.6 | 101.0 | -8.3 |
| surv4-5 | 29 | 28 | - | - | - | - | 4458.7 (4) | -5.6 | 2.7 (4) | -5.6 | 129.8 | 217.0 | -8.4 |
| survA2-9 | 29 | 13 | - | - | - | - | - (6) | - | 1228.3 (6) | -5.7 | 1868.2 | 2294.0 | -6.3 |
| survA2-10 | 29 | 13 | - | - | - | - | - (6) | - | - (6) | - | 6876.6 | 9393.5 | -6.4 |
- factory: A version of the builder domain distributed with SPUDD modified very slightly to have negative rewards and goal states. Many states cannot reach a goal state, but all states that can reach a goal state have a finite optimal value.
- tire: A version of the PPDDL Tireworld domain [Bonet and Givan, 2006] adapted to the SPUDD language. We chose roads mostly randomly but in such a way that we guaranteed a path from every location to the goal location. Every location had a 25% chance of having a spare tire. Almost all states can reach some state that cannot reach the goal. Therefore, comparing values is not very
informative and, instead, we compare the fraction of the time the policy was able to reach a goal state. The size of this domain is approximately controlled by the number of locations; this is shown as tire#locations.
- elev: The elevator domain distributed with SPUDD scaled up and slightly modified to have negative rewards and goal states. The size of this domain is controlled by the number of floors and the number of people waiting for an elevator; this is shown as elev#floors-#people.
- trash: An example domain involving a robot moving trash bags either by hand or with a cart [Barry et al., 2011]. The size of this domain is controlled by the number of intervening locations between the bags and the cart and the number of bags; this is shown as trash#locations-#bags.
- surv/survA: Surveillance domains in which an autonomous agent is trying to take a picture of an interesting location [Barry et al., 2011]. Locations become interesting or not interesting non-deterministically, partly depending on the current location of the agent. The world is divided into neighborhoods, which are far apart, and locations within a neighborhood, which are close together. Once an agent leaves a neighborhood it cannot return. The size of these domains is controlled by the number of neighborhoods and the number locations; this is shown as surv#neighborhoods-#locations.
Evaluation: For each problem, we randomly chose 1000 transient states and, for each algorithm, averaged the values of 1000 trials of the policy starting at each of the states. A
state was determined not to be able to reach a goal state if, during policy evaluation, its value fell below -500.
As shown in Table 1, DetH* runs significantly faster than SPUDD on all domains and never runs out of memory. In addition, it is clear that, as claimed, using a faster solver on the macro-states also decreases the time DetH* requires. In all domains where SPUDD was able to run to completion, Order2 was faster than Order1 for both SPUDD and DetH*.
DetH* also runs significantly faster than SPUDDO in all big domains except surv using Order2 and tire. In both of these domains, a correct guess of a good short horizon can give an accurate answer to the whole MDP so quickly that the overhead of solving many sub-MDPs is unjustified. However, finding this horizon is not possible in general. In the tire domain, the first few iterations are very fast so it would be possible to test a large number of them and find that 5 or 6 iterations gives a good performance faster than DetH* can solve the problem. However, in the surv domains, the increase in running time tends to be very non-linear. Four or five iterations may be run very quickly and then the sixth may take a very long time. Therefore, it is not clear how to find a good horizon in this domain. As the rest of Table 1 attests, simply running SPUDD for a fixed amount of time, but not to convergence will not always give good performance (for example, in the elev domain).
7 Conclusion
There have been many adaptations to SPUDD, from the suggestions of optimization in the original paper [Hoey et al., 1999], to approximating value functions [St-Aubin et al., 2000], to using affine ADDs [Sanner et al., 2010]. All of these adaptations can be applied to DetH* since it can use any solver for the sub-MDPs. In addition, the COST and REGRESS functions used in clustering and solving require the same ADD operations as a SPUDD Bellman backup. Thus any optimization, such as pre-multiplying action ADDs or using affine ADDs, that decrease the running time of those operations will also be expected to decrease the time required for DetH*'s clustering and upper-level solving. The real power of DetH* lies in its ability to break the problem of solving a large MDP into many smaller MDPs. Any advance in the solving of those small MDPs will be reflected directly in the running time of DetH*.
Planning in very large MDPs is difficult because of long horizons, uncertainty in outcomes and large state spaces. The DetH* algorithm addresses each of these. By constructing a temporal hierarchy, DetH* reduces a single long-horizon planning problem to several planning problems with much shorter horizons, considerably reducing planning time. Uncertain planning problems can always be simplified by making a deterministic approximation, but sometimes this simplification comes at a great cost. DetH* makes only a limited deterministic approximation, taking care to model stochasticity in the domain in the short horizon by solving MDPs at the leaf nodes of the hierarchy, but summarizing the cost of longer-term decisions with their expectations. A combination of the shortened horizon and the use of ADD representations significantly reduces the effective state-space size of the remaining MDPs to be solved. The combination of these strategies results in accurate, but still efficient, decisions and we have shown empirically that DetH* can find good approximate policies very quickly.
@inproceedings{ijcai2011p323,
  title     = {DetH*: Approximate Hierarchical Solution of Large Markov Decision Processes},
  author    = {Barry, Jennifer L. and Kaelbling, Leslie Pack and Lozano-Perez, Tomas},
  booktitle = {Proceedings of the Twenty-Second International Joint Conference on
               Artificial Intelligence, {IJCAI-11}},
  publisher = {AAAI Press/International Joint Conferences on Artificial Intelligence},
  editor    = {Toby Walsh},
  pages     = {1928--1934},
  year      = {2011},
  month     = {7},
  doi       = {10.5591/978-1-57735-516-8/IJCAI11-323},
  url       = {https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-323},
}
TY - CPAPER TI - DetH*: Approximate Hierarchical Solution of Large Markov Decision Processes AU - Barry, Jennifer L. AU - Kaelbling, Leslie Pack AU - Lozano-Perez, Tomas T2 - Proceedings of the Twenty-Second International Joint Conference on Artificial Intelligence, IJCAI-11 PB - AAAI Press/International Joint Conferences on Artificial Intelligence PY - 2011 SP - 1928 EP - 1934 DO - 10.5591/978-1-57735-516-8/IJCAI11-323 UR - https://doi.org/10.5591/978-1-57735-516-8/IJCAI11-323 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





