
Spectral Kernel Learning for Semi-Supervised Classification
Proceedings of the Twenty-First International Joint Conference on Artificial Intelligence. Pages 1150-1154.
© 2009 International Joint Conferences on Artificial Intelligence
Abstract
Typical graph-theoretic approaches for semi-supervised classification infer labels of unlabeled instances with the help of graph Laplacians. Founded on the spectral decomposition of the graph Laplacian, this paper learns a kernel matrix via minimizing the leave-one-out classification error on the labeled instances. To this end, an efficient algorithm is presented based on linear programming, resulting in a transductive spectral kernel. The idea of our algorithm stems from regularization methodology and also has a nice interpretation in terms of spectral clustering. A simple classifier can be readily built upon the learned kernel, which suffices to give prediction for any data point aside from those in the available dataset. Besides this usage, the spectral kernel can be effectively used in tandem with conventional kernel machines such as SVMs. We demonstrate the efficacy of the proposed algorithm through experiments carried out on challenging classification tasks.Wei Liu, Buyue Qian, Jingyu Cui, Jianzhuang Liu
- [Asuncion and Newman, 2007] A. Asuncion and D. J. Newman. {UCI} Machine Learning Repository. University of California, Irvine, http://www.ics.uci.edu/∼mlearn/MLRepository.html, 2007. Link
- [Belkin et al., 2006] M. Belkin, P. Niyogi, and V. Sindhwani. Manifold regularization: a geometric framework for learn- ing from examples. Journal of Machine Learning Re- search, 7:2399-2434, 2006.
- [Bengio et al., 2004] Y. Bengio, J. F. Paiement, P. Vincent, O. Delalleau, N. L. Roux, and M. Ouimet. Out-of-sample extensions for lle, isomap, mds, eigenmaps, and spectral clustering. In NIPS 16, 2004.
- [Boyd and Vandenberge, 2004] S. Boyd and L. Vanden- berge. Convex Optimization. Cambridge University Press, Cambridge, UK, 2004.
- [Chapelle et al., 2006] O. Chapelle, B. Schölkopf, and A. Zien. Semi-Supervised Learning. The MIT Press, Cam- bridge, MA, 2006.
- [Chung, 1997] F. Chung. Spectral Graph Theory. CBMS Regional Conference Series in Mathematics, American Mathematical Society, 1997.
- [Hein and Maier, 2007] M. Hein and M. Maier. Manifold de- noising. In NIPS 19, 2007.
- [Hoi et al., 2006] S. Hoi, M. Lyu, and E. Chang. Learning the unified kernel machines for classification. In Proc. KDD, 2006.
- [Kondor and Lafferty, 2002] R. I. Kondor and J. Lafferty. Diffusion kernels on graphs and other discrete input spaces. In Proc. ICML, 2002.
- [Lanckriet et al., 2004] G. Lanckriet, N. Cristianini, P. Bartlett, L. E. Ghaoui, and M. Jordan. Learning the kernel matrix with semidefinite programming. Journal of Machine Learning Research, 5:27-72, 2004.
- [Ng et al., 2002] A. Y. Ng, M. I. Jordan, and Y. Weiss. On spectral clustering: Analysis and an algorithm. In NIPS 14, 2002.
- [Saerens et al., 2004] M. Saerens, F. Fouss, L. Yen, and P. Dupont. The principal components analysis of a graph, and its relationships to spectral clustering. In Proc. ECML, 2004.
- [Schölkopf and Smola, 2002] B. Schölkopf and A. J. Smola. Learning with Kernels: Support Vector Machines, Reg- ularization, Optimization, and Beyond. The MIT Press, Cambridge, MA, 2002.
- [Sindhwani et al., 2005] V. Sindhwani, P. Niyogi, and M. Belkin. Beyond the point cloud: from transductive to semi-supervised learning. In Proc. ICML, 2005.
- [Zhang and Ando, 2006] T. Zhang and R. Ando. Analysis of spectral kernel design based semi-supervised learning. In NIPS 18, 2006.
- [Zhou et al., 2004] D. Zhou, O. Bousquet, T. Lal, J. Weston, and B. Schölkopf. Learning with local and global consis- tency. In NIPS 16, 2004.
- [Zhu et al., 2003] X. Zhu, Z. Ghahramani, and J. Lafferty. Semi-supervised learning using gaussian fields and har- monic functions. In Proc. ICML, 2003.
- [Zhu et al., 2005] X. Zhu, J. Kandola, Z. Ghahramani, and J. Lafferty. Nonparametric transforms of graph kernels for semi-supervised learning. In NIPS 17, 2005.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
A hot stream of broad research interests in recent years is semi-supervised learning (SSL) [Chapelle et al., 2006] which deals with the situations of sparse labeled data together with abundant unlabeled data and utilizes both labeled and unlabeled data in algorithms. SSL has been proved effective in a lot of practical cases, since it is often cheap to obtain unlabeled data by an automatic procedure or scripts but quite expensive to identify the labels of data. Incorporating unlabeled data into learning tasks, SSL triggers a wide range of real-world machine learning applications where labeled samples are very scarce.
Current research on semi-supervised learning is mostly attracted by semi-supervised classification. A family of graphbased approaches [Belkin et al., 2006][Sindhwani et al., 2005][Zhou et al., 2004][Zhu et al., 2003][Zhu et al., 2005], founded on spectral graph theory [Chung, 1997], either put forward new semi-supervised kernels or propose new graphbased regularization frameworks with labeled and unlabeled data. Although graph-based semi-supervised learning has been studied extensively, so far there are few comprehensive techniques to integrate graph-theoretic regularization and nonparametric kernel learning effectively together for classification tasks. To this end, we present a flexible as well as scalable algorithm for learning spectral kernels through taking advantage of regularization methodology and nonparametric kernel construction piloted by graph Laplacians.
2 RelatedWork
It is pointed out in [Sindhwani et al., 2005] that establishing data-dependent kernels will be more and more important for supervised or semi-supervised learning tasks. As a paradigm, building kernels with graph Laplacians receives increasing attention in the contexts of clustering [Saerens et al., 2004] and classification [Zhang and Ando, 2006]. [Saerens et al., 2004] shows that the average commute time between any two data points can be computed using the pseudoinverse L+ of the graph Laplacian matrix L. It turns out that L+ is a valid kernel and can be utilized for kernel k-means clustering and SVM classification. We call L+ the graph Laplacian kernel or Laplacian kernel in what follows.
Since the nature of L+ is parametric with respect to the eigenspectrum of L, we herewith refer to it as the parametric spectral kernel. Another parametric spectral kernel proposed in the early work [Kondor and Lafferty, 2002] is the Laplacian diffusion kernel exp(-αL). As opposed to the parametric kernels, we would desire to obtain more flexible kernels in order to avoid tedious selection among different parametric families. This objective motivates a novel topic of kernel learning, namely nonparametric kernel learning. For example, [Lanckriet et al., 2004] uses kernel-target alignment to learn nonparametric kernel matrices in a supervised mode. The seminal works [Zhu et al., 2005][Hoi et al., 2006] conduct semi-supervised kernel alignment.
These optimization problems involved in kernel alignment are generally solved using semidefinite programming (SDP) [Boyd and Vandenberge, 2004]. However, the computational complexity of SDPs has restricted their applications to small scale problems, and thus prevented nonparametric kernel learning from being applicable to large scale problems, e.g., large scale semi-supervised learning. Alternatively, [Zhu et al., 2005] and [Hoi et al., 2006] show that these optimization problems can be more efficiently solved by quadratically constrained quadratic programming (QCQP) or quadratic programming (QP). Nonetheless, a significant limitation for all these nonparametric kernel approaches is that they only support transductive settings and cannot be extended to unseen data points.
3 Regularized Spectral Kernels
[Zhou et al., 2004] proposed a transductive inference algorithm to impose label smoothness along graphs, which coordinates the local and global consistency within the label propagation process. Suppose we have a data set X = {x1, · · · , xl, xl+1 · · · , xn} ⊂ Rd of which the first l points belonging to c classes are labeled as yi ∈ Y = {1, · · · , c} and the rest points are unlabeled. Intuitively, we define a labeling function f : X → R to assign a discrete label to each data point according to particular class, i.e., f(xi) = k if and only if xi belongs to the kth class.
Given l labeled examples, we define a class indicator matrix as C ∈ Rn×c in which Cik = 1 if yi = k ∈ Y and Cik = 0 otherwise. We intend to seek a real-valued matrix F ∈ Rn×c to express a full classification on the entire dataset X so that the exact labeling is launched by
Let us construct an undirected, weighted graph G(V,W) that exposes the underlying manifold structure of the data. Each data point in X corresponds to a node in V . An edge is established between two nodes vi and vj if the corresponding two points xi and xj are among k nearest neighbors of each other. For convenience, we adopt the trick proposed in [Hein and Maier, 2007] to construct G as a k-nearest neighbor (k-NN) graph. Let us define a distance function h(x) = ‖x - x(k) ‖ where x(k) is the kth nearest neighbor of x in X . The weight matrix W ∈ Rn×n associated with G is formed subsequently as
and Wij = 0 otherwise. Note that we set Wii = 0 to avoid self-loops. We further denote the diagonal degree matrix D ∈ Rn×n with Dii = ∑nj=1 Wij .
The regularization framework proposed by [Zhou et al., 2004] can learn a global classification as
where 0 < α < 1 is the regularization parameter and S = D-1/2WD-1/2 symmetrically normalizes W. The calculated matrix F ∗ stacks the final class assignment.
Now we revisit Zhou et al.'s approach from the perspective of kernels, still exploiting the expression of eq. (3). The graph Laplacian matrix L = D - W is the central ingredient of spectral graph theory [Chung, 1997]. In this paper, we choose the normalized graph Laplacian L = D-1/2LD-1/2 = I -S and perform eigenvalue decomposition on it, yielding the eigensystem {(λi, vi)}ni=1 such that L = V ΛV T , where
0 ≤ λ1 ≤ λ2 · · · ≤ λn, Λ = diag(λ1, · · · , λn), and V = [v1, · · · , vn]. Then we can rewrite eq. (3) as follows
where Θ is a diagonal matrix with entries in the diagonal being θi = 1-α 1-α+αλi . Because λi ∈ [0, 2] [Chung, 1997], we have θ1 ≥ θ2 ≥ · · · ≥ θn ≥ 0. Hence the matrix Kr = V ΘV T ∈ Rn×n is positive semidefinite and herewith behaves as a kernel matrix.
Specially, we call Kr the regularized spectral kernel since it is derived from the regularization framework and also built upon spectral transformation of L, i.e., Λ → Θ. By engaging Kr , it is not difficult to translate eq. (1) into
which is a multi-class classifier directly derived from the regularized kernel matrix.
4 Transductive Spectral Kernels
In this section, we describe how to learn an effective datadependent kernel for semi-supervised learning. Prior work on producing data-dependent kernels may be roughly classified into two categories: (i) choosing parametric families of Laplacian kernels, and (ii) learning a nonparametric kernel matrix over the seen data points alone. Here we present a new algorithm for learning a nonparametric spectral kernel based on the spectral decomposition of the graph Laplacian.
Our kernel learning algorithm introduces a universal procedure allowing: (1) to compute similarities between nodes in an undirected, weighted graph in a nonparametric mode, (2) to maintain a similarity gap between nodes with different labels in the graph, and (3) to compute similarities between an unseen node 1 and any node in the graph. Computing similarities between node pairs including unseen ones enables searching the data point which is most relevant (i.e., similar) to a given point, thus making clustering or classification feasible. This paper focuses on the application of such a technique to semi-supervised classification.
Motivated by the Laplacian kernel [Saerens et al., 2004][Zhang and Ando, 2006] and its nonparametric spectral transform [Zhu et al., 2005], we have the following theorem.
Theorem 1. If a positive semidefinite matrix L ∈ Rn×n has an eigensystem {(λi, vi)}ni=1 (0 ≤ λ1 ≤ · · · ≤ λn), then the family of matrices K = ∑ni=1 μivivT i (μi ≥ 0) produces nonparametric kernels with K as kernel matrices.
Proof. Because μi ≥ 0 and
1 An unseen node or data point means a data point not in the dataset X .
where U = diag(μ1, · · · , μn), K is certainly positive semidefinite and thus a valid kernel matrix. ■
The elicited kernel matrix K is a linear combination of a set of basic kernels {Ki = vivT i }ni=1 . So far, we are able to formulate the problem of nonparametric kernel learning into finding a nonparametric spectral transform τ : λi → μi such that optimizing K can be transferred to optimizing the spectral coefficients {μi}.
4.1 Spectral Constraints
[Zhu et al., 2005] imposed a decreasing order on the spectral coefficients μi = τ(λi) for the sake of encouraging smooth components of the target kernel. The smaller λi, the more Ki should be favored in K, which motivates the order constraints
The regularized spectral kernel also satisfies the decreasing spectral order since θ1 ≥ θ2 ≥ · · · ≥ θn. Nonetheless, a lot of order constraints may not suit the task at hand, resulting in overly constrained kernels. Hence, we only impose these constraints over the more smooth components of K that correspond to the m smallest eigenvalues {λi}mi=1 (m < n) of the graph Laplacian L with λi ̸= 1. Why the condition λi ̸= 1 is imposed will be investigated in Subsection 4.3.
Following [Hoi et al., 2006], we adopt the decaying constraints
η ≥ 1 is introduced as a decay factor that is an important parameter to control the decaying rate of spectral coefficients and influence the outcome performance of the learned kernel K.
4.2 Learning with Linear Programming
The target spectral kernel is herewith generated by
in which ¯ V = [v1, · · · , vm] and ¯U = diag(μ1, · · · , μm). Eq. (9) discloses a spectral embedding ¯U 1 2 ¯ V T ∈ Rm×n for the raw sample matrix X = [x1, · · · , xn] ∈ Rd×n. We denote the spectral embedding as Φ = [φ1, · · · , φn] = ¯U 1 2 ¯ V T and have φTi φj = Kij. φi is exactly them-dimensional spectral representation of xi through eigen-decomposingL. This type of spectral embedding originates from the well-know spectral clustering algorithm [Ng et al., 2002]. Now, we hope that the spectral embedding is sufficiently smooth over the graph G, and then form the smoothness measure as
where tr(.) stands for the matrix trace operator. Importantly, minimizing Q1(K) encourages the smoothness of the spectral embedding Φ, which is actually embodied in the desired spectral kernel K = ΦT Φ.
Let us set up two sets S and D to capture pairwise similarities and dissimilarities. Formally, we set S = {(i, j)|xi and xj share the same label (yi = yj, i ̸= j)} and D = {(i, j)|xi and xj are differently labeled (yi ̸= yj)}. By engaging eq. (10) and the idea of soft margin introduced by SVMs [Sch¨olkopf and Smola, 2002], we suggest a convex optimization criterion as follows
where ⌈x⌉+ = max(x, 0) denotes the hinge loss as used in SVMs and β > 0 is the trade-off parameter. The two competing terms in the above equation are both critical to achieving a good spectral kernel under transductive settings. The first one penalizes large variations of the kernel matrix along the graph G, while the second one penalizes a small gap between the total similarity among the same labeled points and the total similarity among the differently labeled points.
Furthermore, minimizing Q(K) is equivalent to minimizing the leave-one-out classification error on the labeled instances when using eq. (5) as the classifier. Therefore, the kernel we are pursuing truly incorporates semi-supervised information as opposed to the Laplacian kernel, the regularized spectral kernel, and the other composite kernels, all of which are unsupervised in terms of construction mechanism.
It is not difficult to show Q1(K) = tr(LK) = ∑mi=1 λiμi. 2 Let form an indicator matrix as E = (eij)ij = [e1, · · · , en] ∈ Rn×n where eij = 1 if (i, j) ∈ S, eij = -1 if (i, j) ∈ D, and eij = 0 otherwise. The target kernel matrix with the spectral constraints can hitherto be put forward as the solution to the following linear program
where ξi's are introduced as slack variables.
Let vec(P ) denote the column vectorization of a matrix P and let M = [vec(K1), · · · , vec(Km)] ∈ Rn2×m. Rewrite M = [M T 1 , · · · , M T n ]T in which Mi ∈ Rn×m, and then define an l × m matrix as
2 Let U = diag(μ1, · · · , μm, 0, · · · , 0) and then tr(LK) = tr(V ΛV T V UV T ) = tr(ΛU) = Pmi=1 λiμi.
Table 1: The semi-supervised classification algorithm via learning a transductive spectral kernel.
Algorithm. Semi-Supervised Classification Using TSK
- Step 1. Construct a k-NN graph G(V, W) upon samples X = {x1, · · · , xn} ⊂ Rd from c classes, and compute the normalized graph Laplacian L.
- Step 2. Solve the sparse eigenvalue problem Lv = λv and retain the m < n smallest eigenvalues {λi} and corresponding eigenvectors {vi} such that λ1 ≤ · · · ≤ λm and λi ̸= 1.
- Step 3. Solve the linear program eq. (14) and obtain the TSK K = ∑mi=1 μivivT i .
- Step 4. For each unlabeled point xi, infer its label as f (xi) = arg max1≤k≤c ∑yj=k Kij . For an unseen point x, use eq. (19) to predict its label as f (x) = arg max1≤k≤c ∑yj=k Kx,j .
Consequently, the linear program eq. (12) can be succinctly rewritten as follows
where λ = [λ1, · · · , λm]T , μ = [μ1, · · · , μm]T , ξ = [ξ1, · · · , ξl]T , 1 = [1, · · · , 1]T ∈ Rl , and Γ ∈ R(m-1)×m with nonzero entries being Γii = 1 and Γi,i+1 = -η (1 ≤ i ≤ m - 1).
Since all of the objective function and the constraints are linear with respect to [μT , ξ T ]T ∈ Rm+l , the linear program eq. (14) is substantially efficient. Linear programming is one of the most thoroughly studied algorithmic fields and many excellent software packages are available for it. We opt for MATLAB to solve this linear program.
After the optimal kernel matrix is learned, we are capable of setting up a classifier like eq. (5). The only change is to replace the regularized spectral kernel Kr in eq. (5) with the learned nonparametric kernel K which is referred to as the transductive spectral kernel (TSK) as it carries out transductive inference via introducing the hinge loss in eq. (11). We depict the algorithm for learning a TSK along with semisupervised classification in Table 1. This algorithm can readily be implemented via invoking a sparse eigenvalue solver and a linear program both of which scale well to hundred thousands of data points including the labeled and unlabeled ones.
4.3 Out-of-Sample Extension
Whatever the theme of learning is, it must be clearly stated that the issues surrounding the learning paradigm are universal, and not just customized to available samples. Since previous nonparametric kernels are rather restrictive to seen points, we show that we can overcome the limitation of non-inductive inference associated with previous nonparametric kernel approaches. By investigating the structure of K, we find out for each pair of points xi and xj in the dataset it holds that
where vit denotes the ith entry of the eigenvector vt and ¯ Vi. = [vi1, · · · , vim] is the ith row vector of the matrix ¯ V ∈ Rn×m. In order to classify an unseen point x, we have to know
for all xj's. The kernel function K(, ) should be induced from the seen point cloud as well as the learned kernel matrix K. Eq. (16) reveals that induction can be achieved once the spectral representation ¯ Vx. ∈ R1×m of an unseen point x is known, in other words, semi-supervised induction can be realized by utilizing the out-of-sample extension trick of spectral clustering. Fortunately, the formalized out-of-sample extension for spectral clustering has been presented in [Bengio et al., 2004], which we use to derive
where the inductive weights Wx,i = W(x, xi) are similarly computed using eq. (2), and Dxx is thus computed by Dxx = ∑ni=1 Wx,i. Let wx = [Wx,1/√DxxD11, · · · , Wx,n/√DxxDnn]T ∈ Rn and then simplify eq. (17) as
where ¯Λ = diag(λ1, · · · , λm) ∈ Rm×m.
By doing so, we are able to predict the label for any unseen point x by
where ¯ Vx. is induced from the point cloud residing on the dataset X, while ¯ V and ¯U has been learned in Step 2 and Step 3 of the presented algorithm, respectively. Finally, we augment the inductive inference eq. (19) in Table 1.
To verify the inductive inference formula eq. (19) as well as guarantee the generalization capability of the TSK K, we claim the following theorem which shows that the TSK used in either transductive or inductive setting is definitely positive semidefinite.
Theorem 2. If λi ̸= 1 for 1 ≤ i ≤ m, the expanded symmetric matrix ˜K = (K(xi, xj))n+s i,j=1 based on n seen samples {x1, · · · , xn} and s new samples {xn+1, · · · , xn+s} is still a kernel matrix.
Proof. After learning the kernel matrix K = ¯ V ¯U ¯ V T on the available dataset, we have to infer ¯ V(n+1). , · · · , ¯ V(n+s). for the coming s new samples to compute ˜K. Corresponding to each new point xn+t, we first obtain the induced weight vector wt (t = 1, · · · , s) and afterwards form a matrix J = [w1, · · · , ws] ∈ Rn×s .
When 1 ≤ i, j ≤ n, ˜Kij = Kij . When n < i ≤ n + s and 1 ≤ j ≤ n, we apply eq. (18) to derive
When 1 ≤ i ≤ n and n < j ≤ n + s, we also have
When n < i, j ≤ n + s, we can arrive in
Hence, we complete the expanded matrix ˜K by
where Q ∈ R2m×2m is symmetric and has 2m eigenvalues of {μi + μi (1-λi)2 }mi=1 and m 0's. Because μi ≥ 0 and λi ̸= 1, Q is positive semidefinite; consequently, ˜K is also positive semidefinite and becomes a valid kernel matrix. ■
5 Experimental Results
In this section, we conduct experiments on real-world datasets to testify our algorithm which we notate as TSK for semi-supervised learning (SSL) using transductive spectral kernels. We compare it with the state-of-the-art SSL algorithms: the Gaussian fields and harmonic functions [Zhu et al., 2003], the local and global consistency [Zhou et al., 2004], and LapSVM [Belkin et al., 2006]. By applying SVM as the final classifier, we also contrast TSK with two competitive spectral kernels, the order-constrained spectral kernel, abbreviated as "OSK" [Zhu et al., 2005], and the fast-decay spectral kernel, abbreviated as "DSK" [Hoi et al., 2006].
In detail, we use four UCI datasets [Asuncion and Newman, 2007] and the WebKB dataset [Sindhwani et al., 2005] as our experimental testbeds. Table 2 describes the fundamental information about these benchmark datasets. Empirically, we fix η = 2 throughout all our experiments.
| DATASET | # FEATURES | # SAMPLES | # CLASSES |
| HEART | 13 | 270 | 2 |
|---|---|---|---|
| IONOSPHERE | 34 | 351 | 2 |
| SONAR | 60 | 208 | 2 |
| WINE | 13 | 178 | 3 |
| WEBKB | 4840 | 1051 | 2 |
5.1 UCI Datasets
We experiment seven methods on four UCI datasets: HEART, IONOSPHERE, SONAR and WINE. The input features are normalized to range [0, 1]. Results are averaged over 20 random selection of 20 labeled data points of which there is one sample at least for each class. We construct k-NN graphs with k = 6 for all datasets. For HEART and WINE, we take m = 10 eigenvectors for spectral kernel learning. For IONOSPHERE and SONAR, we take m = 30 eigenvectors. The width of the RBF kernel for LapSVM and the initial kernel for DSK learning are set by cross validation. For the harmonic function method, the consistency method, and LapSVM, we also construct the same k-NN graph using eq. (2), which facilitates fair comparison with our method.
| CRR (%) | HEART | IONOSPHERE | SONAR | WINE |
|---|---|---|---|---|
| harmonic | 59.86±4.07 | 76.83±6.84 | 60.82±6.35 | 67.78±3.20 |
| consistency | 60.30±3.68 | 70.17±9.07 | 62.18±6.03 | 68.39±3.03 |
| TSK | 64.06±4.42 | 77.89±6.37 | 68.38±4.56 | 72.28±1.24 |
| LapSVM | 73.66±1.60 | 82.95±1.84 | 68.24±1.28 | 93.77±1.10 |
| OSK+SVM | 65.88±1.69 | 83.04±2.10 | 64.68±1.57 | 92.72±1.32 |
| DSK+SVM | 76.30±1.33 | 88.55±1.32 | 71.76±1.07 | 95.63±0.45 |
| TSK+SVM | 78.40±1.30 | 90.25±2.10 | 72.80±0.95 | 96.34±0.33 |
The classification results are shown in Table 3. It can be clearly observed that transductive classification accuracy on the unlabeled samples achieved by TSK consistently outperforms those achieved by the harmonic and consistency methods. TSK+SVM consistently outperforms the other three kernel machines. These results validate that our method uses information from labeled and unlabeled data pertinently to improve the performance of nonparametric kernels.
5.2 WebKB Dataset
WebKB dataset is a subset of web documents of the computer science departments at four universities. This dataset extensively used for semi-supervised learning experiments consists of two categories: course and non-course. For each document, there are two representations: the textual content of the webpage (which we will call page representation) and the anchortext on links on other webpages pointing to the webpage (link representation). We generate bag-of-words feature vectors for both representations. For the page representation, 3000 features were selected according to information gain. For the link representation, 1840 features were generated with no feature selection. The columns of the documentword matrix were scaled based on inverse document frequency weights (IDF) for each word and the resulting term frequency (TF)-IDF feature vectors were length normalized.
We use the two categories as two classes, and their two representations, page and link, for two groups of experiments. This time the cosine kernel is adopted for running SVM. The same 100-NN graph for the harmonic method, the consistency method, and our method is constructed. The regularization parameter α in the consistency method and RSK is fixed at 0.99. We set the number of basic kernels m to 800. We uniformly divide this WebKB dataset into two disjoint sets of which 80% data are used for transductive setting and the rest for inductive setting. In the transductive setting, we compare TSK with 1NN, SVM, the harmonic method, and the consistency method. Otherwise in the inductive setting, we compare TSK with 1NN, SVM, and the regularized spectral kernel (RSK) stated in Section 3 which is a parametric spectral kernel and may be thought as an inductive version of the consistency method.
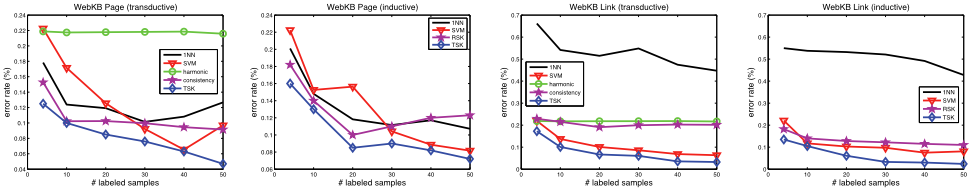
Fig. 1 displays comparative results over WebKB. Our TSKbased SSL algorithm is clearly superior to the other algorithms whether in the transductive setting or in the inductive setting.
6 Conclusion
We have proposed an algorithm that efficiently learns a nonparametric kernel called a transductive spectral kernel (TSK) which allows to compute similarities between any pair of seen samples in the available dataset, in the meantime maintain a similarity gap between any pair of seen samples taking different labels, and induce similarities between an unseen sample and any seen sample. A simple yet effective multi-class classifier can be constructed from TSK directly. In addition, TSK works well in conceit with conventional kernel machines such as SVMs. Experiments performed on real-world datasets validate that the learned spectral kernel is quite beneficial to semi-supervised classification.
Acknowledgements
This work was supported by two grants from the Research Grants Council of the Hong Kong SAR, China (Project No. CUHK 414306 and 415408).
@inproceedings{ijcai2009p194,
  title     = {Spectral Kernel Learning for Semi-Supervised Classification},
  author    = {Liu, Wei and Qian, Buyue and Cui, Jingyu and Liu, Jianzhuang},
  booktitle = {Proceedings of the Twenty-First International Joint Conference on
               Artificial Intelligence, {IJCAI-09}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Craig Boutilier},
  pages     = {1150--1154},
  year      = {2009},
  url       = {https://ijcai.org/proceedings/2009/194},
}
TY - CPAPER TI - Spectral Kernel Learning for Semi-Supervised Classification AU - Liu, Wei AU - Qian, Buyue AU - Cui, Jingyu AU - Liu, Jianzhuang T2 - Proceedings of the Twenty-First International Joint Conference on Artificial Intelligence, IJCAI-09 PB - International Joint Conferences on Artificial Intelligence PY - 2009 SP - 1150 EP - 1154 UR - https://ijcai.org/proceedings/2009/194 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





