
Generalization Error of Linear Neural Networks in an Empirical Bayes Approach
Proceedings of the Nineteenth International Joint Conference on Artificial Intelligence. Pages 804-809.
© 2005 International Joint Conferences on Artificial Intelligence
Abstract
It is well known that in unidentifiable models, the Bayes estimation has the advantage of generalization performance to the maximum likelihood estimation. However, accurate approximation of the posterior distribution requires huge computational costs. In this paper, we consider an empirical Bayes approach where a part of the parameters are regarded as hyperparameters, which we call a subspace Bayes approach, and theoretically analyze the generalization error of three-layer linear neural networks. We show that a subspace Bayes approach is asymptotically equivalent to a positivepart James-Stein type shrinkage estimation, and behaves similarly to the Bayes estimation in typical cases.
- [Akaike, 1974] H. Akaike. A new look at statistical model. IEEE Trans. on Automatic Control, 19:716-723, 1974.
- [Akaike, 1980] H. Akaike. Likelihood and bayes procedure. In J. M. Bernald, Bayesian statistics, pages 143-166, Valencia, Italy, 1980. University Press.
- [Aoyagi and Watanabe, 2004] M. Aoyagi and S. Watanabe. The generalization error of reduced rank regression in bayesian esti- mation. In Proc. of ISITA, pages 1068-1073, Parma, Italy, 2004.
- [Attias, 1999] H. Attias. Inferring parameters and structure of latent variable models by variational bayes. In Proc. of UAI, 1999.
- [Baldi and Hornik, 1995] P. F. Baldi and K. Hornik. Learning in lin- ear neural networks: a survey. IEEE Trans. on Neural Networks, 6:837-858, 1995.
- [Efron and Morris, 1973] B. Efron and C. Morris. Stein's estima- tion rule and its competitors-an empirical bayes approach. J. of Am. Stat. Assoc., 68:117-130, 1973.
- [Fukumizu, 1999] K. Fukumizu. Generalization error of linear neu- ral networks in unidentifiable cases. In Proc. of ALT, pages 51- 62. Springer, 1999.
- [Ghahramani and Beal, 2000] Z. Ghahramani and M. J. Beal. Graphical models and variational methods. In Advanced Mean Field Methods. MIT Press, 2000.
- [Hinton and van Camp, 1993] G. E. Hinton and D. van Camp. Keeping neural networks simple by minimizing the description length of the weights. In Proc. of COLT, 1993.
- [James and Stein, 1961] W. James and C. Stein. Estimation with quadratic loss. In Proc. of the 4th Berkeley Symp. on Math. Stat. and Prob., pages 361-379, Berkeley:University of Califor- nia, 1961.
- [Kass and Steffey, 1989] R. E. Kass and D. Steffey. Approxi- mate bayesian inference in conditionally independent hierarchi- cal models (parametric empirical bayes models). J. of the Am. Stat. Assoc., 84:717-726, 1989.
- [MacKay, 1995] D. J. C. MacKay. Developments in probabilistic modeling with neural networks-ensemble learning. In Proc. of the 3rd Ann. Symp. on Neural Networks, pages 191-198, 1995.
- [Nakajima and Watanabe, 2005a] S. Nakajima and S. Watanabe. Generalization performance of subspace bayes approach in lin- ear neural networks. Submitted to IEICE Trans., 2005.
- [Nakajima and Watanabe, 2005b] S. Nakajima and S. Watanabe. Variational bayes solution of linear neural networks and its gen- eralization error and training error. Submitted to ICML, 2005.
- [Reinsel and Velu, 1998] G. C. Reinsel and R. P. Velu. Multivariate Reduced-Rank Regression. Springer, 1998.
- [Watanabe and Amari, 2003] S. Watanabe and S. Amari. Learning coefficients of layered models when the true distribution mis- matches the singularities. Neural Computation, 15:1013-1033, 2003.
- [Watanabe, 2001] S. Watanabe. Algebraic information geometry for learning machines with singularities. Advances in NIPS, 13:329-336, 2001.
- Watcher, 1978
- K. W. Watcher. The strong limits of random matrix spectra for sample matrices of independent elements. Ann. Prob., 6:1-18, 1978.
- [Yamazaki and Watanabe, 2003] K. Yamazaki and S. Watanabe. Singularities in mixture models and upper bounds of stochastic complexity. Neural Networks, 16(7):1029-1038, 2003.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Unidentifiable parametric models, such as neural networks, mixture models, and so on, have a wide range of applications. These models have singularities in the parameter space, hence the conventional learning theory of the regular statistical models does not hold. Recently, generalization performance of some unidentifiable models has been theoretically clarified. In the maximum likelihood (ML) estimation, which is asymptotically equivalent to the maximum a posterior (MAP) estimation, the generalization error of linear neural networks was proved to be greater than that of the regular models whose dimension of the parameter space is the same when the model is redundant to learn the true distribution [Fukumizu, 1999]. On the other hand, in the Bayes estimation, the generalization error of neural networks, linear neural networks, mixture models, and so on was proved to be less than that of the regular models [Watanabe, 2001; Aoyagi and Watanabe, 2004; Yamazaki and Watanabe, 2003].
However, the Bayes posterior distribution can seldom be exactly realized. Furthermore, Markov chain Monte Carlo (MCMC) methods, often used for approximation of the posterior distribution, require huge computational costs. As an alternative, the variational Bayes approach, where the correlation between parameters and the other parameters, or the correlation between the parameters and the hidden variables is neglected, was proposed [Hinton and van Camp, 1993; MacKay, 1995; Attias, 1999; Ghahramani and Beal, 2000]. 1
In this paper, we consider another alternative, which we call a subspace Bayes (SB) approach. An SB approach is an empirical Bayes (EB) approach where a part of the parameters of a model are regarded as hyperparameters. If we regard the parameters of one layer as hyperparameters, we can analytically calculate the marginal likelihood in some threelayer models. Consequently, what we have to do is only to find the hyperparameter value maximizing the marginal likelihood. The computational costs of an SB approach is thus much less than that of posterior distribution approximation by MCMC methods. At first in this paper, we prove that in threelayer linear neural networks, an SB approach is equivalent to a positive-part James-Stein (JS) type shrinkage estimation [James and Stein, 1961]. Then, we clarify its generalization error, also considering delicate situations, the most important situations in model selection problems and in statistical tests, when the Kullback-Leibler divergence of the true distribution from the singularities is comparable to the inverse of the number of training samples. 2 We conclude that an SB approach provides as good performance as the Bayes estimation in typical cases.
In Section 2, neural networks and linear neural networks are briefly introduced. The framework of the Bayes estimation, that of an EB approach, and that of an SB approach are described in Section 3. The significance of singularities for generalization performance and the importance of analysis of delicate situations are explained in Section 4. The SB solution and its generalization error are derived in Section 5. Discussions and conclusions follow in Section 6 and in Section 7, respectively.
2 Linear Neural Networks
Let x ∈ RM be an input (column) vector, y ∈ RN an output vector, and w a parameter vector. A neural network model can be described as a parametric family of maps {f (·; w) : RM ↦→ RN }. A three-layer neural network with H hidden units is defined by
1 We have just derived the variational Bayes solution of linear neural networks and clarified its generalization error and training error in [Nakajima and Watanabe, 2005b].
2 We have also clarified the training error, which is put into [Nakajima and Watanabe, 2005a].
where w = {(ah, bh) ∈ RM × RN ; h = 1, . . . ,H} summarizes all the parameters, ψ(·) is an activation function, which is usually a bounded, non-decreasing, antisymmetric, nonlinear function like tanh(·), and t denotes the transpose of a matrix or vector. Assume that the output is observed with a noise subject to NN(0, σ2 IN), where Nd(µ,Σ) denotes the d-dimensional normal distribution with average vector µ and covariance matrix Σ, and Id denotes the d×d identity matrix. Then, the conditional distribution is given by
In this paper, we focus on linear neural networks, whose activation function is linear, as the simplest multilayer models. 3 A linear neural network model (LNN) is defined by
where A = (a1, . . . , aH)t is an H ×M input parameter matrix and B = (b1, . . . , bH) is an N × H output parameter matrix. Because the transform (A,B) ↦→ (TA, BT -1) does not change the map for any non-singular H × H matrix T , the parameterization in Eq.(3) has trivial redundancy. Accordingly, the essential dimension of the parameter space is given by
We assume that H ≤ N ≤ M throughout this paper.
3 Framework of Learning Methods
3.1 Bayes Estimation
Let X n = {x1, . . . , xn} and Y n = {y1, . . . , yn} be arbitrary n training samples independently and identically taken from the true distribution q(x, y) = q(x)q(y|x). Themarginal conditional likelihood of a model p(y|x, w) is given by
where φ(w) is the prior distribution. The posterior distribution is given by
and the predictive distribution is defined as the average of the model over the posterior distribution as follows:
The generalization error, a criterion of generalization performance, is defined by
3 A linear neural network model is not a toy but an useful model, known as a reduced-rank regression model, in many applications [Reinsel and Velu, 1998].
where
is the Kullback-Leibler (KL) divergence of the predictive distribution from the true distribution, and 〈·〉q(Xn ,Y n) denotes the expectation value over all sets of n training samples.
3.2 Empirical Bayes Approach and Subspace Bayes Approach
We often have little information about the prior distribution, with which an EB approach was originally proposed to cope. We can introduce hyperparameters in the prior distribution; for example, when we use a prior distribution that depends on a hyperparameter τ1 such as
the marginal likelihood, Eq.(5), also depends on τ1. In an EB approach, τ1 is estimated by maximizing the marginal likelihood or by a slightly different way [Efron and Morris, 1973; Akaike, 1980; Kass and Steffey, 1989]. Extending the idea above, we can introduce hyperparameters also in a model distribution. What we call an SB approach is an EB approach where a part of the parameters of a model are regarded as hyperparameters. In the following sections, we analyze two versions of SB approach: in the first one, we regard the output parameter matrix B of the map, Eq.(3), as a hyperparameter and then marginalize the likelihood in the input parameter space (MIP); and in the other one, we regard the input parameter matrix A, instead of B, as a hyperparameter and then marginalize in the output parameter space (MOP).
4 Unidentifiability and Singularities
We say that a parametric model is unidentifiable if the map from the parameter to the probability distribution is not oneto-one. A neural network model, Eq.(1), is unidentifiable because the model is independent of ah when bh = 0, or vice versa. The continuous points denoting the same distribution are called the singularities, because the Fisher information matrix on them degenerates. When the true model is not on the singularities, asymptotically they do not affect prediction, and therefore, the conventional learning theory of the regular models holds. On the other hand, when the true model is on the singularities, they significantly affect generalization performance as follows: in the ML estimation, the extent of the set of the points denoting the true distribution increases its neighborhoods and hence the flexibility of imitating noises, and therefore, accelerates overfitting; while in the Bayes estimation, the large entropy of the singularities increases the weights of the distributions near the true one, and therefore, suppresses overfitting. In LNNs, the former property appears as acceleration of overfitting by selection of the largest singular value components of a random matrix, and in the SB approaches of LNNs, the latter property appears as James-Stein type shrinkage, as shown in the following sections.
Suppression of overfitting accompanies insensitivity to the true components with small amplitude. There is a trade-off, which would, however, be ignored in asymptotic analysis if we would consider only situations when the true model is distinctly on the singularities or not. Therefore, in this paper, we also consider delicate situations when the KL divergence of the true distribution from the singularities is comparable to the inverse of the number of training samples, n-1 , which are important situations in model selection problems and in statistical tests with finite number of samples for the following reasons: first, that there naturally exist a few true components with amplitude comparable to n-1/2 when neither the smallest nor the largest model is selected; and secondly, that whether the selected model involves such components essentially affects generalization performance.
5 Theoretical Analysis
5.1 Subspace Bayes Solution
By ‖ we, hereafter, distinguish the hyperparameter τ from the parameter w, for example, p(y|x,w‖τ ). Assume that the variance of a noise is known and equal to unity. Then, the conditional distribution of an LNN in the MIP version of SB approach is given by
We use the following prior distribution:
Note that we can similarly prepare p(y|x,B‖A) and φ(B) for the MOP version. We assume that the true conditional distribution is p(y|x,A∗‖B∗ ), where B∗A∗ is the true map with rank H ∗ ≤ H. We denote by ∗ the true value of a parameter as above, and by a hat an estimator of a parameter, for example, ˆ A, ˆbh, etc.. For simplicity, we assume that the input vector is orthonormalized so that ∫ xxt q(x)dx = IM . Consequently, the central limit theorem leads to the following two equations:
where Q(X n) is an M × M symmetric matrix and R(X n, Y n) is an N ×M matrix. Hereafter, we abbreviate Q(X n) as Q, and R(X n, Y n) as R.
Let γh be the h-th largest singular value of the matrix RQ-1/2 , ωah the corresponding right singular vector, and ωbh the corresponding left singular vector. We find from Eq.(14) that γh for H ∗ < h ≤ H is of order O(n-1/2 ). Hence, combining with Eq.(13), we get
where -∞ < ρ ∈ R < ∞ is an arbitrary constant. The SB estimator, defined as the expectation value over the SB posterior distribution, is given by the following theorem:
Theorem 1 Let L = M in the MIP version or L = N in the MOP version, and L′h = max(L, nγ 2h). The SB estimator of the map of an LNN is given by
(The proof is given in Appendix A.)
Because the independence between A and B makes the posterior distribution localized, the following lemma holds.
Lemma 1 The predictive distribution in the SB approaches can be written as follows:
where ˆ V = IN + O(n-1 ), and | · | denotes the determinant of a matrix.
(Proof) The predictive distribution is written as follows:
where 〈·〉p denotes the expectation value over a distribution p. Since ( ˆB ˆ A - B∗A∗ ) = O(n-1/2 ) in the SB approaches, we can expand the predictive distribution as follows:
where v = √n( ˆB ˆ A-B∗A∗ )x is an N-dimensional vector of order O(1). Calculating the expectation value and expanding the logarithm of Eq.(19), we arrive at Lemma 1. (Q.E.D.)
Comparing Eq.(16) with the ML estimator
[Baldi and Hornik, 1995], we find that the SB estimator of each component is asymptotically equivalent to a positivepart JS type shrinkage estimator. Moreover, by virtue of Lemma 1, we can substitute the model at the SB estimator for the predictive distribution with asymptotically insignificant impact on generalization performance. Therefore, we conclude that the SB approach is asymptotically equivalent to the shrinkage estimation. Note that the variance of the prior distribution, Eq.(12), asymptotically has no effect upon prediction and hence upon generalization performance, as far as it is a positive, finite constant. We call L the degree of shrinkage. Remember that we can modify all the theorems in this paper for the ML estimation only by letting L = 0.
5.2 Generalization Error
Using the singular value decomposition of the true map B∗A∗ , we can transform arbitrary A∗ and B∗ without change of the map into a matrix with its orthogonal row vectors and another matrix with its orthogonal column vectors, respectively. Accordingly, we assume the above orthogonalities without loss of generality. Then, Lemma 1 implies that the KL divergence, Eq.(9), with a set of n training samples is given by
where
is the contribution of the h-th component. Here tr(·) denotes the trace of a matrix. We denote by Wd(m,Σ,Λ) the ddimensional Wishart distribution with m degrees of freedom, scale matrix Σ, and noncentrality matrix Λ, and abbreviate as Wd(m, Σ) the central Wishart distribution.
Theorem 2 The generalization error of an LNN in the SB approaches can be asymptotically expanded as
where the coefficient of the leading term, called the generalization coefficient in this paper, is given by
Here θ(·) is the indicator function of an event, γ ′2 h is the h-th largest eigenvalue of a random matrix subject to WN-H∗ (M - H ∗ , IN-H∗ ), and 〈·〉q({γ ′2 h }) denotes the expectation value over the distribution of the eigenvalues.
(Proof) According to Theorem 1, the difference between the SB and the ML estimators of a true component with a positive singular value is of order O(n-1 ). Furthermore, the generalization error of the ML estimator of the component is the same as that of the regular models because of its identifiability. Hence, from Eq.(4), we obtain the first term of Eq.(23) as the contribution of the first H ∗ components. On the other hand, we find from Eq.(15) and Theorem 1 that for a redundant component, identifying RQ-1/2 with R affects the SB estimator only of order O(n-1 ), which, hence, does not affect the generalization coefficient. We say that U is the general diagonalized matrix of an N ×M matrix T if T is singular value decomposed as T = ΩbUΩa, where Ωa and Ωb are an M × M and an N × N orthogonal matrices, respectively. Let D be the general diagonalized matrix of R, and D′ the (N - H ∗ ) × (M - H ∗ ) matrix created by removing the first H ∗ columns and rows from D. Then, the first H ∗ diagonal elements of D correspond to the positive true singular value components and D′ consists only of noises. Therefore, D′ is the general diagonalized matrix of n-1/2R′ , where R′ is an (N - H ∗ ) × (M - H ∗ ) random matrix whose elements are independently subject to N1(0, 1), so that R′R′t is subject to WN-H∗ (M - H ∗ , IN-H∗ ). The redundant components imitate n-1/2R′ . Hence, using Theorem 1 and Eq.(22), we obtain the second term of Eq.(23) as the contribution of the last (H -H ∗ ) components. Thus, we complete the proof of Theorem 2. (Q.E.D.)
5.3 Large Scale Approximation
In a similar fashion to the analysis of the ML estimation in [Fukumizu, 1999], the second term of Eq.(23) can be analytically calculated in the large scale limit when M, N, H, and H ∗ go to infinity in the same order. We define the following scalars: α = N ′/M ′ = (N-H ∗ )/(M-H ∗ ), β = H ′/N ′ = (H - H ∗ )/(N - H ∗ ), and κ = L/M ′ = L/(M - H ∗ ). Let W be a random matrix subject to WN ′ (M ′ , IN ′ ), and {u1, . . . , uN ′} the eigenvalues of M ′-1W. The measure of the empirical distribution of the eigenvalues is defined by
where δ(u) denotes the Dirac measure at u. In the large scale limit, the measure, Eq.(24) , converges almost everywhere to
where um = (√α - 1)2 and uM = (√α + 1)2 [Watcher, 1978]. Calculating moments of Eq.(25), we obtain the following theorem:
Theorem 3 The generalization coefficient of an LNN in the large scale limit is given by
where
and st = max ((κ(1 + α))/2√α, J -1 (2παβ; 0)). Here J -1 (·; k) denotes the inverse function of J (s; k).
5.4 Delicate Situations
In ordinary asymptotic analysis, one considers only situations when the amplitude of each component of the true model is zero or distinctly-positive. Also Theorem 2 holds only in such situations. However, as mentioned in the last paragraph of Section 4, it is important to consider delicate situations when the true map B∗A∗ has tiny but non-negligible singular values such that 0 < √nγ ∗ h <∞. Theorem 1 still holds in such situations by replacing the second term of Eq.(16) with o(n-1/2 ). We regard H ∗ as the number of distinctly-positive true singular values such that γ ∗ h-1 = o(√n). Without loss of generality, we assume that B∗A∗ is a non-negative, general diagonal matrix with its diagonal elements arranged in non-increasing order. Let R′′∗ be the true submatrix created by removing the first H ∗ columns and rows fromB∗A∗ . Then, D′ , defined in the proof of Theorem 2, is the general diagonalized matrix of n-1/2R′′ , where R′′ is a random matrix such that R′′R′′t is subject toWN-H∗ (M -H ∗, IN-H∗ , nR′′∗R′′∗ ). Therefore, we obtain the following theorem:
Theorem 4 The generalization coefficient of an LNN in the general situations when the true map B∗A∗ may have delicate singular values such that 0 < √nγ ∗ h < ∞ is given by
where γ ′′ h , ω′′ ah , and ω′′ bh are the h-th largest singular value of R′′ , the corresponding right singular vector, and the corresponding left singular vector, respectively, of which 〈·〉q(R′′ ) denotes the expectation value over the distribution.
6 Discussions
6.1 Comparison with theML Estimation and with the Bayes Estimation
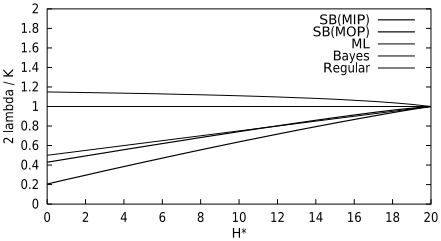
Figure 1 shows the generalization coefficients of an LNN with M = 50 input, N = 30 output, and H = 20 hidden units. The horizontal axis indicates the true rank H ∗ . The vertical axis indicates the coefficients normalized by the parameter dimension K, given by Eq.(4). The lines correspond to the generalization coefficients of the SB approaches, clarified in this paper, that of the ML estimation, clarified in [Fukumizu, 1999], that of the Bayes estimation, clarified in [Aoyagi and Watanabe, 2004], and that of the regular models, respectively. 4 The results in Fig. 1 have been calculated in the large scale approximation, i.e., by using Theorem 3. We have also numerically calculated them by creating samples subject to the Wishart distribution and then using Theorem 2, and thus found that the both results almost coincide with each other so that we can hardly distinguish. We see in Fig. 1 that the SB approaches provide as good performance as the Bayes estimation, and that the MIP, moreover, has no greater generalization coefficient than the Bayes estimation for arbitrary H ∗ , which might seem to be inconsistent with the proved superiority of the Bayes estimation to any other learning method when we use the true prior distribution. This suspicion is cleared by consideration of delicate situations in the following.
4 In the regular models, the normalized generalization coefficient is always equal to one, which leads to the penalty term of Akaike's information criterion [Akaike, 1974].
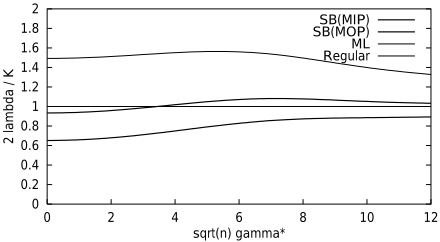
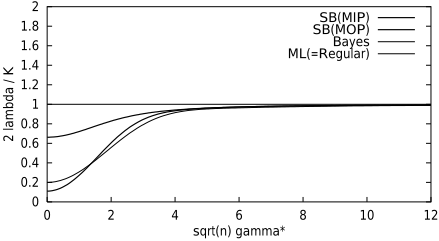
Using Theorem 4, we can numerically calculate the SB, as well as the ML, generalization error in delicate situations when the true distribution is near the singularities. Figure 2 shows the coefficients of an LNN with M = 50 input, N = 30 output, and H = 5 hidden units on the assumption that the true map consists of H ∗ = 1 distinctly-positive component, three delicate components whose singular values are identical to each other, and the other one null component. The horizontal axis indicates √nγ ∗ , where γ ∗ h = γ ∗ for h = 2, . . . , 4. The Bayes generalization error in delicate situations was previously clarified [Watanabe and Amari, 2003], but unfortunately, only in single-output (SO) LNNs, i.e., N = H = 1. 5 Figure 3 shows the coefficients of an SOLNN with M = 5 input units on the assumption that H ∗ = 0 and the true singular value of the one component, indicated by the horizontal axis, is delicate. We see in Fig. 3 that the SB approaches have a property similar to the Bayes estimation, suppression of overfitting by the entropy of the singularities. We also see that in some delicate situations, the MIP is worse than the Bayes estimation, which shows consistency with the superiority of the Bayes estimation. We conclude that in typical cases, the suppression by the singularities in the MIP is comparable to, or sometimes stronger than, that in the Bayes estimation.
5 An SOLNN is regarded as a regular model at a view point of the ML estimation because the transform b1a1 ↦→ w ∈ CAM makes the model linear and hence identifiable, and therefore, the ML generalization error is identical to that of the regular models. Nevertheless, an SOLNN has a property of unidentifiable models at a view point of the Bayesian learning methods, as shown in Fig. 3.
It would be more fortunate if any of the SB approaches, which require much less computational costs than MCMC methods, would always provide comparable generalization performance to the Bayes estimation. However, the SB approaches have also a property similar to the ML estimation, acceleration of overfitting by selection of the largest singular values of a random matrix. Because of selection from a large number of random variables subject to non-compact support distribution, the (H -H ∗ ) largest eigenvalues of a randommatrix subject to WN-H∗ (M - H ∗ , IN-H∗ ) are much greater than L when (M - H ∗ ) > (N - H ∗ ) ≫ (H - H ∗ ). Therefore, the eigenvalues {γ ′2 h } in Theorem 2 go out of the effective range of shrinkage, and consequently, the SB approaches approximate the ML estimation in such atypical cases. Actually, the generalization coefficient of an LNN in the case that M = N = 80, H = 1, H ∗ = 0 is 2λ/K∼ 1.04, which is greater than that of the regular models, though in the Bayes estimation, the generalization coefficient never exceeds that of the regular models [Watanabe, 2001].
6.2 Relation to Shrinkage Estimation
The relation between an EB approach in a linear model and the JS estimator, into which the SB estimator, Eq.(16), in an SOLNN is changed by letting L = (M - 2), was discussed in [Efron and Morris, 1973]. Based on the EB approach, the JS estimator can be derived as the solution of an equation with respect to an unbiased estimator of the hyperparameter τ -2 1 , introduced in Section 3.2. The similarity between the JS and the SB estimators is natural because in an SOLNN, the transform b1a1 ↦→ w ∈ RM makes not only the model linear but also the prior distribution as Eq.(10).
We focus on SOLNNs in this paragraph. In Fig. 3, the SB approaches and the Bayes estimation seem to be superior to the ML estimation regardless of the true distribution. The following asymptotic expansion of the generalization coefficient with respect to √nγ ∗ 1 provides a clue when it occurs:
where ξ is the coefficient of the leading term when γ ∗ 1 increases to be distinctly-positive. The sign of ξ indicates the direction of approach to the line 2λ = M, which corresponds to the generalization coefficient of the regular models. It was found that ξ = (M - 1)(M - 3) in the Bayes estimation, which leads to the conjecture that the Bayes estimation would be superior to the ML estimation when M ≥ 4 [Watanabe and Amari, 2003]. Similarly expanding Eq.(27), we get ξ = M (M - 4) in the MIP, as well as ξ = (2M - 5) in the MOP, which leads to the conjecture that the MIP when M ≥ 5, as well as the MOP when M ≥ 3, would be superior to the ML estimation. We have found that the numerical calculation by using Theorem 4 supports the conjecture above [Nakajima and Watanabe, 2005a]. We also find that ξ = (M - 2)2 in the JS estimation, which is consistent with its proved superiority to the ML estimation when M ≥ 3.
6.3 Relation to Variational Bayes Approach
The generalization error of the variational Bayes (VB) approach in LNNs has just been clarified [Nakajima and Watanabe, 2005b]. In the parameter subspace corresponding to the redundant components, the VB posterior distribution extends with its variance of order 1 in the larger dimension parameter subspace either input one or the output one; while the SB posterior distribution extends with its variance of order 1 in the parameter space, not in the hyperparameter space, as we find from Eqs. (30) and (37) in Appendix A. Consequently, the VB approach is asymptotically equivalent to the MIP version of SB approach.
6.4 Future Works
A future work can be consideration of the effect of nonlinearity of the activation function, ψ(·) in Eq.(1). We expect that the non-linearity would extend the range of basis selection and hence increase the generalization error.
7 Conclusions
We have introduced a subspace Bayes (SB) approach, an empirical Bayes approach where a part of the parameters are regarded as hyperparameters, and derived the solution of two versions of SB approach in three-layer linear neural networks. We have also clarified its generalization error and concluded that the SB approaches have a property similar to the Bayes estimation and provide as good performance as the Bayes estimation in typical cases.
Acknowledgments
The authors would like to thank the reviewers who gave us meaningful advice, which motivates us to add Section 4 and some comments in other sections. They also would like to thank Kazuo Ushida, Masahiro Nei, and Nobutaka Magome of Nikon Corporation for encouragement to research.
A Proof of Theorem 1
First, we will prove in the MIP version. Given an arbitrary map BA, we can have A with its orthogonal row vectors and B with its orthogonal column vectors by using the singular value decomposition. Just in that case, the prior probability, Eq.(12), is maximized. Accordingly, we assume without loss of generality that the optimum value of B consists of its orthogonal column vectors. Consequently, the marginal (conditional) likelihood, as well as the posterior distribution, factorizes as
Then, substituting Eqs.(11) and (12) into Eq.(5), as well as Eq.(6), we can easily derive the marginal likelihood, as well as the posterior distribution, of each component as follows:
where Sh = (‖bh‖2Q + n-1 IM). Let F ′ (Y n|X n‖bh) = F (Y n|X n‖bh)+const., where F (Y n|X n‖bh) is the stochastic complexity, i.e., the negative log marginal likelihood, of the h-th component. Then, we get
Hereafter, separately considering the components imitating the positive true ones and the redundant components, we will minimize Eq.(31). We abbreviate F ′ (Y n|X n‖bh) as F ′ (bh).
For a positive true component, h ≤ H ∗, the corresponding observed singular value γh of RQ-1/2 is of order 1 with probability 1. Then, from Eq.(31), we get
To minimize Eq.(32), the leading, second term dominates the determination of the direction cosine of bh and leads to bh = ‖bh‖(ωbh + O(n-1 )). The first and the third terms determine the norm of bh because the second term is independent of it. Thus, we get the optimal hyperparameter value as follows:
Because the average of ah over the posterior distribution, Eq.(30), is ˆah = S-1 h Rt bh, we obtain the SB estimator for the positive true component of the map BA as follows:
On the other hand, for a redundant component, h > H ∗ , Eq.(15) allows us to approximate Eq.(31) as follows:
Then, we find that the direction cosine of bh, determined by the second term of Eq.(35), is approximated by ωbh with accuracy O(n-1/2 ). After substituting γ 2h‖bh‖2 (1+ O(n-1/2)) for bthRRt bh, we get the following extreme condition by partial differentiation of Eq.(35) with respect to the norm of bh:
We find that Eq.(36) has no solution if γh is less than √M/n. Therefore, using the fact that Eq.(35) diverges to infinity with arbitrary n if ‖bh‖ → ∞, we get the optimum hyperparameter value as follows:
Thus, we obtain the SB estimator of the redundant component as follows:
Selecting the largest singular value components minimizes Eq.(31). Hence, combining Eqs.(34) and (38), and then using Eq.(15), we obtain the SB estimator in Theorem 1. We can also derive the SB estimator in the MOP version in exactly the same way. (Q.E.D.)
@inproceedings{ijcai2005p79,
  title     = {Generalization Error of Linear Neural Networks in an Empirical Bayes Approach},
  author    = {Nakajima, Shinichi and Watanabe, Sumio},
  booktitle = {Proceedings of the Nineteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-05}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Leslie Pack Kaelbling and Alessandro Saffiotti},
  pages     = {804--809},
  year      = {2005},
  url       = {https://ijcai.org/proceedings/2005/79},
}
TY - CPAPER TI - Generalization Error of Linear Neural Networks in an Empirical Bayes Approach AU - Nakajima, Shinichi AU - Watanabe, Sumio T2 - Proceedings of the Nineteenth International Joint Conference on Artificial Intelligence, IJCAI-05 PB - International Joint Conferences on Artificial Intelligence PY - 2005 SP - 804 EP - 809 UR - https://ijcai.org/proceedings/2005/79 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





