
Multiple-Goal Reinforcement Learning with Modular Sarsa(0)
Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence. Pages 1445-1446.
© 2003 International Joint Conferences on Artificial Intelligence
Abstract
We present a new algorithm, GM-Sarsa(O), for finding approximate solutions to multiple-goal reinforcement learning problems that are modeled as composite Markov decision processes. According to our formulation different sub-goals are modeled as MDPs that are coupled by the requirement that they share actions. Existing reinforcement learning algorithms address similar problem formulations by first finding optimal policies for the component MDPs, and then merging these into a policy for the composite task. The problem with such methods is that policies that are optimized separately may or may not perform well when they are merged into a composite solution. Instead of searching for optimal policies for the component MDPs in isolation, our approach finds good policies in the context of the composite task.
- [Humphrys, 1996] M. Humphrys. Action selection methods using reinforcement learning. In From Animals to Animals 4: Proceedings of the Fourth International Conference on Simulation of Adaptive Behavior, pages 135-144, Cam- bridge, MA, 1996.
- [Karlsson, 1997] J. Karlsson. Learning to Solve Multiple Goals. PhD thesis, University of Rochester, 1997.
- [Rurnmery and Niranjan, 1994] G. A. Rummery and M. Ni- ranjan. On-line Q-learning using connectionist systems. Technical Report CUED/F-INFENG/TR 166, Cambridge University Engineering Department, 1994.
- [Singh and Cohn, 1998] S. Singh and D. Cohn. How to dy- namically merge markov decision processes. In Advances in Neural Information Processing Systems, volume 10, 1998.
- [Singh and Sutton, 1996] S. Singh and R. Sutton. Reinforce- ment learning with replacing eligibility traces. Machine Learning, 22( 1-3), 1996.
- [Singh eta!., 2000] S. Singh, T. Jaakkola, M. L. Littman, and C. Szepesvari. Convergence results for single-step on-policy reinforcement-learning algorithn1s. Machine Learning, 2000.
- [Sprague and Ballard, 2003] N. Sprague and D. Ballard. Multiple-goal reinforcement learning with modular sarsa(O). Technical Report 798, University of Rochester Computer Science Department, 2003.
- [Sutton, 1996] R. Sutton. Generalization in reinforcement learning: Successful examples using sparse coarse cod- ing. In Advances in Neural Information Processing Sys- tems, volume 8, 1996.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Traditional reinforcement learning algorithms can success fully solve small, single-goal tasks. The main challenge in the area of reinforcement learning is scaling up to larger and more complex problems. The scaling problem takes a num ber of forms. We may have a problem that has a very large state space, a problem that is best described as a set of hi erarchically organized goals and subgoals, or a problem that requires the learning agent to address several tasks at once. It is the last form of scaling that this paper is concerned with.
The naive approach to learning to solve composite tasks is to create a state space that includes all of the information that is relevant to each sub-task. The agent would then learn in this joint space, receiving reward when any of the sub-goals are accomplished. The problem with this approach is that it suffers from the curse of dimensionality; as additional state dimensions are added for each new sub-task, the size of the joint state space grows exponentially.
A more promising approach to this sort of multiple-goal problem is to use the well known Q-learning algorithm to train one learning module to handle each of the sub-goals. The internal Q-values of the different learning modules can
Dana Ballard
Computer Science Department University of Rochester Rochester, NY 14627 dana@cs. rochester. edu
then be used to fairly distribute control among the mod ules. This approach has been independently explored in [Humphrys, 1996] and [Karlsson, 1997]. It is attractive in its simplicity, and it has shown good empirical performance in a number of domains.
In this paper we will highlight a previously unrecognized problem with existing modular Q-learning algorithms. Exist ing algorithms learn component policies that may be highly sub-optimal in the context of the composite task, because they do not take into account the fact that the component mod ules are forced to share control. We will show how to fix this problem by replacing the Q-learning with the closely re lated Sarsa(O) learning rule. The resulting algorithm shows improved performance on a large sample problem.
2 The problem formalized
The underlying formalism for many reinforcement learning algorithms is the Markov decision process. An MDP, denoted Misdescribed by a 4-tuple (S, A, T, R), where Sis the state space, A is the action space, and T( s, a, s') is the transition function that indicates the probability of arriving in state s' when action a is taken in states. The reward function R(s, a) denotes the expected one-step payoff for taking action a in state s. The goal of reinforcement learning algorithms is to discover an optimal policy 1r* ( s) that maps states to actions so as to maximize discounted long term reward.
Here we consider the problem of discovering a joint pol icy for a set of N MDP's { Mi}f". Throughout we will use subscripts to distinguish the MDPs. These MDP's each have a distinct state space, but they share a common action space, and are required to execute the same action on each time step. This model is intended to map to the case of a single agent that is simultaneously faced with a set of different goals.
The N component MDPs implicitly define a larger com posite MDP. Formally, the goal is to find the optimal policy for this composite MDP. The optimal composite policy is de fined as the policy that maximizes summed discounted reward across the component MDPs.
The state space of the composite MDP is the cross prod uct of the state spaces of the component MDPs: s = sl X 82 x ... x S N. The composite reward function is defined as: R( s, a) = L~ 1 R; ( Si, a). In the case where the component MDPs are independent, the composite transition function can be written as: T( s, a, s') = 11: 1 Ti(si , a, s~) . In the case where the component MDPs are not independent, the exact composite transition function will depend on on the particu lar dependencies between the models.
In theory, there is no reason that the composite MDP could not be solved directly using the traditional Q-learning algo rithm. However, this is generally not practical because the size of the composite state space may grow exponentially with the number of component MDPs.
3 Modular Q-Learning
Humphrys and Karlsson [Humphrys, 1996; Karlsson, 1997] independently developed similar approaches to the problem of multiple-goal reinforcement learning. The idea is that a separate learning module is created for each component MDP. The agent takes actions in the environment, and each module i is trained with the standard Q-learning update rule:
Where ri is the immediate reward, a is the learning rate parameter, and l' is a discount factor applied to future re wards. In single goal reinforcement learning problems, these Q-values are used only to rank order the actions in a given state. The key observation here is that the Q-values can also be used in multiple-goal problems to indicate the degree of preference that modules have for different actions. There are several possible ways these values can be used to select a compromise action to execute. The different approaches will be referred to as action selection mechanisms.
Karlsson's suggestion, which he calls "greatest mass", is to generate an overall Q-value as a simple sum of the Q-values of the individual modules: Q(s , a) = 'L:~1 Qi(si, a). The action with the maximum summed value is then chosen to execute. We will refer to this approach as GM-Q for greatest mass Q-learning.
Humphrys considers the greatest mass approach, but raises the objection that the action with the highest sum may not be particularly good for any of the modules, with the result that no module is able to reach its goal. He explores several winner-take-all alternatives that constrain the chosen action to be optimal for at least one module. For a given state s each of the N modules promotes its own action with a value Wi(si)· The module with the largest W value is then allowed to execute its preferred action.
The simplest method for generating theW-values, which we will refer to as Top-Q, is to set Wi (si) = maxa Qi(si, a), thus giving control to the module with the highest Q-value in the current state. This method suffers from the draw back that the module with the highest Q-value may have no preference over what action is chosen, while another module stands to lose a great deal if its action is not selected. The method sometimes exhibits reasonable performance, but this is strongly dependent on the structure of the reward functions.
A better alternative, referred to as negotiated W-learning, is to grant control to the module that stands to lose the most long term reward if it is not selected. This module can be discovered by examining the Q-values for the current state. Refer to [Humphrys, 1996] for a detailed description of the algorithm.
3.1 The problem with modular Q-learning
Q-learning has some attractive qualities as a basis for multiple-goal reinforcement learning. Chief of these is the fact that it is an off-policy learning method. This means that Q-learning for a single MDP is guaranteed to converge to the optimal solution regardless of what policy is followed during training, as long as each state-action pair is visited infinitely often in the limit. This fact makes it easy to prove conver gence results for the composite reinforcement learning algo rithms introduced above. In particular, it is easy to see that each module is guaranteed to converge to the optimal policy and value function for its own MDP. Since the action selec tion mechanisms generate a policy deterministically from the component value functions, the composite policy is also guar anteed to converge, although there is no guarantee concerning the quality of the composite solution.
Unfortunately, the off-policy character of Q-learning is also a serious limitation. The difficulty is that the one-step value updates for each module are computed under the as sumption that all future actions will be chosen optimally for that MDP. This assumption is not valid under the action selec tion mechanisms described above; future actions will repre sent some compromise policy in which the different modules share control. This means that the computed Q-values do not converge to the actual expected return under the composite policy. Instead, the max in equation (1) results in Q-values with a positive bias.
4 Modular Sarsa(O)
A possible solution is to the problem of positive bias is to replace Q-learning with an on-policy learning algorithm. In particular we will explore the use of Sarsa(O) [Rummery and Niranjan, 1994; Singh and Sutton, 1996; Sutton, 1996]. The update rule for Sarsa(O) is:
This update rule is virtually identical to that for Q-learning except that the max over Q-values on the right has been re placed with the Q-value of the state action pair that is actu ally observed on the next step. For the case of single MDPs Sarsa(O) has been proved to converge to the optimal policy as long as the exploration rate is asymptotically decayed to ward zero according to an appropriate schedule [Singh eta!., 2000].
The key observation for our purposes is that, since Sarsa(O) is an on-policy method, it does not suffer from the problem of positive bias. Since updates are based on the actions that are actually taken, rather than on the best possible action, we expect Sarsa(O) based modules to discover Q-values that are closer to the true expected return under the composite policy.
Any of the action selection mechanisms from Section 3 could be recast to use Sarsa(O) rather than Q-learning to train the modules. However, we focus on the method of greatest mass. We refer to the resulting algorithm as GM-Sarsa(O). Recall that the goal is to maximize the summed reward across all of the component MDPs. Assuming that we have trust worthy utility estimates from each of the modules, it makes sense to choose the action that has the highest summed util ity across all of the modules. By definition, this is the action that will lead to the greatest summed long term reward. This reasoning did not hold under Q-learning, because the utility estimates were inaccurate under the composite policy.
Thus far we have no convergence proof for the GM Sarsa(O) algorithm. Refer to the associated technical report [Sprague and Ballard, 2003] for a discussion of the possible convergence characteristics.
5 Examples
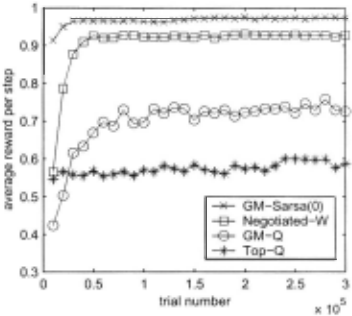
Figure 1 demonstrates the performance of GM-Sarsa(O) on a sample composite task (the task is adapted from [Singh and Cohn, 1998]). The goal of the agent in this task is to gather stationary food items while avoiding a predator in a 5 x 5 grid. There are three food items present at all times.
The agent moves in any of the eight possible directions at each time step. A random move is made with a probability of .I. If the agent contacts any ofthe food items it receives a reward of 1.0, and the item is randomly moved to a new posi tion. The agent receives a reward of .5 for every time step that it avoids the predator. The predator moves deterministically one position toward the agent on every other time step.
The positions of the food items as well as the positions of the agent and predator result in 25 5 ::::::! 10 million distinct states. This is too large for a monolithic tabular learning al gorithm to be practical. The task is a good candidate for a modular reinforcement learning algorithm because it can be decomposed into several small MDPs. One MDP describes the agent's interaction with the predator, and three MDPs describe the interaction with the food items. Each of these component MDPs has 25 2 = 625 states. Figure 1 shows the performance of GM-Sarsa(O) as well as the three Q-learning based algorithms from Section 3 on this task. Of the four algorithms, GM-Sarsa(O) exhibits the best performance.
6 Conclusion
We have presented a method for learning approximately opti mal policies for a certain class of composite Markov decision processes. Empirical results demonstrate that our approach performs better than a number of existing algorithms. Future work will focus on proving convergence results for our algo rithm. A longer version of this paper, including a discussion of related work is available as [Sprague and Ballard, 2003].
Acknowledgments
This material is based upon work supported by a grant from the Department of Education under grant number P200A000306, a grant from the National Institutes of Health under grant number 5P41RR09283 and a grant from the Na tional Science Foundation under grant number E I A-0080 124. Any opinions, findings, and conclusions or recommendations expressed in this material are those of the authors and do not necessarily reflect the views of the above mentioned institu tions.
@inproceedings{ijcai2003p231,
  title     = {Multiple-Goal Reinforcement Learning with Modular Sarsa(0)},
  author    = {Sprague, Nathan and Ballard, Dana H.},
  booktitle = {Proceedings of the Eighteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-03}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Georg Gottlob and Toby Walsh},
  pages     = {1445--1446},
  year      = {2003},
  url       = {https://ijcai.org/proceedings/2003/231},
}
TY - CPAPER TI - Multiple-Goal Reinforcement Learning with Modular Sarsa(0) AU - Sprague, Nathan AU - Ballard, Dana H. T2 - Proceedings of the Eighteenth International Joint Conference on Artificial Intelligence, IJCAI-03 PB - International Joint Conferences on Artificial Intelligence PY - 2003 SP - 1445 EP - 1446 UR - https://ijcai.org/proceedings/2003/231 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





