
Sequence Extrapolation
Proceedings of the Thirteenth International Joint Conference on Artificial Intelligence. Machine Learning. Pages 1120-1126.
© 1993 International Joint Conferences on Artificial Intelligence
Abstract
We study sequence extrapolation as a machinelearning problem. Input examples come from a stream of data elements of a single type {integers, strings, etc.). Stream values are presented in order; the problem is to construct a hypothesis that explains the given values and predicts the subsequent ones. We define a new representation language for streams called elementary stream descriptions and present a unified algorithm that learns elementary streams over a generous family of data types that includes integers, lists, and strings. The algorithm has been implemented and an application targeted.
- [Dewdney, 1986] A. K. Dewdney. Computer recreations. Sci- entific American, pages 14-21, 1986.
- [Dietterich and Michalski, 1986] T . Diet- terich and R. Michalski. Learning to predict sequences. In R. S. Michalski et al., editor, Machine Learning: An AI Approach, Vol. II. Morgan Kaufmann, 1986.
- [Gallier, 1986] J. Gallier. Logic for Computer Science: Foun- dation& of Automatic Theorem Proving. Harper and Row, 1986.
- [Hedrick, 1976] C. Hedrick. Learning production systems from examples. Artificial Intelligence, 7:21-49, 1976.
- [Kotovsky and Simon, 1973] K. Kotovsky and H. Simon. Empirical tests of a theory of human acquision of concepts for sequential patterns. Cognitive Psychology, 4:399-424, 1973.
- [Laird and Saul, 1992] P. Laird and R. Saul. The extrapola- tion of elementary sequences. Technical Report FIA-92-31 , NASA Ames Research Center, AI Research Branch, 1992.
- [Laird et al., 1993] P. Laird, R. Saul, and P. Dunning. A model of sequence extrapolation. (submitted), 1993.
- [Laird, 1992] P. Laird. Discrete sequence prediction and its applications. In Proc., 9th National Conference on Artifi- cial Intelligence. AAAI, 1992.
- Michalski et al., 1987) R. Michalski, H. Ko, and K. Chen. Qualitative prediction: the SPARC/G methodology for in- ductively describing and predicting discrete processes. In Current !&sues in Expert Systems. Academic Press, 1987.
- [Muggleton and Feng, 1992] S. Muggleton and C . Feng. Ef- ficient induction of logic programs. In Inductive Logic Pro- gramming, pages 281-298. Academic Press, 1992.
- [Pazzani and Kibler, 1992] M. Pazzani and D. Kibler. The utility of knowledge in inductive learning. Machine Learn- ing, 9:57-98, 1992.
- [Persson, 1966] S. Persson. Some Sequence Extrapolation Programs: A study of representation and modeling in in- quiry sylltem. PhD thesis, University of California, Berke- ley, 1966. Also printed as Stanford University Computer Science Department Technical Report # CS50, 1966.
- [Pivar and Finkelstein, 1964] M. Pivar and M. Finkelstein. Automation, using LISP, of induction on sequences. In E. Berkeley and D. Bobrow, editors, The Programming Language LISP. Information International, Inc., 1964.
- [Quinlan, 1990] R. Quinlan. Learning logical definitions from relations. Machine Learning, 5:239-266, 1990.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
Introduction
Learning from experience to predict sequences of dis crete symbols is a fundamental problem in machine learning. The problem can be treated statistically as one of learning a time-dependent probability distribu tion [Laird, 1992], analytically as one of learning a time series {f(t) I t > 0}, or (in this paper) as one of se quence extrapolation, where the task is to form a rule for computing the n'th value from its predecessors. As a motivating example, try to state a rule that accounts for the following sequence of strings and use it to predict the next one: *· !··?, !!·!··??, ! !!*!!*!**???, .... We present an algorithm that extrapolates many sequences (including this one) over a large class of datatypes. Eas ily understood and implemented, the algorithm improves the assortment of ad hoc techniques used heretofore.
In prior work, psychologists have studied in some detail the way humans infer rules for Thurstone sequences-sequences of alphabetic letters (e.g., ''A C B D C E . .. ' ') in which the alphabetic ordering pro vides the fundamental relationship from which the rule is formed. Programs that implement models of human performance on this task have also been used to test cognitive theories (e.g., [Kotovsky and Simon, 1973]).
For nearly thirty years programmers have tried to write powerful sequence extrapolation programs. For example, Pivar and Finkelstein [1964] described a Lisp program that extrapolates integer sequences based on the so-called method of differences. Feenstra (cited in [Dewdney, 1986]) later extended the method with some clever heuristics and was able to achieve an "IQ" of about 160 on a published test. Evidently the method of differ ences is promising for extrapolating integer sequences but hard to extend to datatypes other than integers.
· Email: lairdlptol .. y. are. nasa. goY
t Email: aaullptoleay. are. nasa. goY
In a little known but interesting study, Persson [Pers son, 1966] constructed several sequence extrapolation programs and sought a method for automating the task of constructing a representation in which the extrapola tion problem is easy. His strategy was to look for fea tures common to extrapolation problems over different data types and to view the task, not as solving a series of unrelated problem instances, but as learning to solve the general problem more effectively as more instances are solved.
In other related work of note, Hedrick [Hedrick, 1976) used semantic nets to chart relationships among ob jects in an effort to find a method applicable to se quences of objects over several datatypes. His work, however, seems not to have been continued. Dietterich, Michalski and others [Dietterich and Michalski, 1986; Michalski et a/., 1987]built several programs to play the game Eleusis. In this problem the extrapolation rule is nondeterministic in that the next item in the sequence is not uniquely determined (e.g., the rule "alternating even and odd integers" admits many possible sequences).
In recent years, as machine learning research has con centrated on a small number of core problems, interest in sequence extrapolation has subsided. With this paper we hope to revive interest in the problem by (1) giving an elegant algorithm that solves a significant family of extrapolation problems, and (2) showing how it applies to inductive concept learning.
Preliminary Concepts
To motivate our algorithm, let us note some features of the way humans do sequence extrapolation.
- One usually constructs several hypotheses of about the same complexity that explain the first few val ues of the sequence. As new values arrive, these hypotheses are modified or replaced as needed by more complex hypotheses.
- A small number of unexplained initial values form
- the seed for computing the remainder of the se quence.
- Whether extrapolating sequences of integers, strings, lists, or whatever, we apply largely the same strategy. Indeed, type-independent extrapolation has been a recurring (but elusive) theme in the lit erature.
- Probably the most striking characteristic is how few examples are needed before we have a hypothesis in whose ability to predict future values we have high confidence. Whereas statistical models of machine learning suggest that thousands of examples should be required to learn a nontrivial family of functions, three or four values in sequence often suffice to learn complex rules within a very large family. (Consider the motivating example above.)
- One can estimate one's confidence that a given hy pothesis will correctly predict the next value, based on how well the hypothesis has performed previ ously. When the confidence is sufficiently high, one may even question an input value that disagrees with the prediction and put more faith in the hy pothesis than in the data.
Example 1 The sequence (2, 3, 5, 8, ... ) over the natu rals.
The rule Zn = Zn-1 + Zn-2 explains both the 5 and the 8, taking 2 and 3 as initial values, and predicts 13 next. The rule Zn = Zn-1 + n predicts 3, 5, and 8, taking only 2 as an initial value, and predicts 12 next. Both rules are simple and both predictions, reasonable. A more compli cated hypothesis like Zn = -Zn-1 +z~_2 +2zn-3-while consistent-would not yet be considered.
Example 2 Over the alphabet { J, K}, the sequence of strings (J, KJK, KJKKJKJ, KJKKJKJKJKKJKJKJK, ... ).
Although this appears more difficult than the preceding example, notice that the third string Z3 can be formed by concatenating two occurrences of z2 to one of z1, and this rule correctly predicts z4 · Note the similarity in the rules: Zn = Zn-1 · Zn-1 · Zn-2 (strings) and Zn = Zn-1 + Zn-1 + Zn-2 (naturals).
Example 3 Over the domain of "dotted" pairs (ordered binary trees), the sequence:
Some aspects of this sequence are immediately predictable-e.g., that each value is (zn · Yn) whose left part Zn is a pair (zn-1 · Xn-d, and that the right part Yn is of the form (?? · b). But the "??" part corresponds to the sequence nil, ( c ·a), c, ... , and no predictable pat tern is yet emergent. The fourth value in this sequence, therefore, will likely be
where "??" indicates a part that cannot yet be predicted.
Constructive Datatypes
We require that our extrapolation algorithm apply to many datatypes, not just integers or strings. Let us adopt a fairly conventional formalism for datatypes, but with one added restriction. Let n be a finite set of for mal operations called constructors. Each constructor is assigned a fixed integer arity designating the number of formal arguments it takes. The subset of arity zero con structors is assumed to be nonempty and represents the constants, or generators, for the type. The set of expres sions over n includes the generators and is closed under application of the constructors n.
A type D is a family of equivalence relations over n that is compatible with the operations. Thus if d; and e; are equivalent expressions (1 ~ i ~ n) and f is an n-ary operation inn, then f(d1, ... ' dn) is equivalent to f(el! ... 1 en)·
Examples of familiar datatypes are:
- Strings over the alphabet A = {a, b}, where the only constructor (apart from constants a and b) is the associative binary function 0 concatenating two strings. (Formally, 0 consists of AU{ 0 }.) The two expressions (a 0 b) 0 c and a 0 (b 0 c) are equiva lent strings since the string operation is associative.
- Dotted pairs over the set A = {a, b}. The construc tor (·) makes a pair out of two values. Typical ex pressions include a, b, (b ·b), (a· (b ·a)), etc.
- Non-negative integers generated from { 0, 1} by the binary constructors + (addition) and * (multiplica tion). Both constructors are associative and com mutative.
- Thurstone domain: The letters A, B, ... , Z to gether with the constructors successor and predeces sor, e.g., successor(A) = B and predecessor(B) = A.
One says a constructive datatype is freely generated (e.g., [Gallier, 1986]) if each value can be constructed from the generators by exactly one sequence of opera tions. Dotted pairs, for example, are freely generated, but strings and integers are not: the string abc can be constructed (ab)c or a(bc), and 4 can be constructed as 2 + 2, 3 + 1, etc.
We define a partial ordering ~ on the expressions of the type D as follows: generators are the minimal el ements; and if y = f( ... , z;, ... ) for some constructor f E n, then y ~ Xj for all i. We call a datatype con structive if~ extends to a partial ordering on the equiva lence classes. On the non-negative integers, for example, this rules out multiplication by zero: Since 1 = 1 + 0, 1 ~ 0; but 0 = 0 X 1, so 0 ~ 1; thus ~ is not a partial ordering. Disallowing multiplication by zero makes this a constructive type.
Our algorithm, given below, applies to all construc tive types and even to composite types (e.g., pairs of strings). We assume that datatypes are recursively dis tinguishable, so that, for example, there is no confusion between the integer 123 and the string "123".
Streams
A stream is a semi-infinite sequence (s1, s2, ··· ) of val ues, all of the same datatype. The first element s1
is called the head, and (s2, 831 ··· ) is called the tail. We shall formalize sequence extrapolation as learning a stream, and to that end we define a new representation language for streams. This language defines our bias for the learning problem; the definition is intentionally crafted so that an efficient learning algorithm can be de vised.
Note that the constructors for a typeD can be applied to streams of type D: e.g., if S = (s11 ··· ) and T = (tt, ... ) are integer streams, then so is S + T = (s1 + t1, ... ). Note also the constant stream a = (a, a, ... ) for aE A.
Before giving the formal definition, we offer a simple example of a stream definition. Over the naturals with addition, the stream E = (1, 3, 5, ... ) of odd naturals can be defined by the following equations: E = ( 1 I F), F = E + 2. The first equation states that Eisa stream whose head is the number 1 and whose tail is the stream F. F, which is (3, 5, 7, ... ), is defined recursively as E+2.
Definition 1 An elementary description (of type D) of a stream S is a block of one or more equations. The block has one of the following three forms:
- (initial-value definition) S = (v I T), where v is an item of type D, followed by an elementary descrip tion ofT. (Intuitively v represents the head and T, the tail of the stream S.)
- (functional definition) S = f(Tt, ... , T~:), where f is a constructor of arity k ~ 0, followed by elementary descriptions of Tt, ... , T1:. (Intuitively this repre sents the stream S as a function f of the streams Ji.)
- (equality definition) S = U, where U is the name of a stream in the parent hierarchy of S (see below). (This defines the stream S recursively in terms of another stream U.)
S is said to be the parent stream of T (in an initial value definition) and of 7i (1 :::; i :::; k) (in a functional definition). The parent hierarchy ofT (11, etc.) consists of S, the parent of S, its parent, and so on. A stream U named in an equality definition of S must belong to the parent hierarchy of S. I
For example, over strings the description 81 = { aba I S2}, S2 = c 0 S3, S3 = St denotes the stream { aba, caba, ccaba, .. . }. Over the naturals the Fibonacci sequence is given by S1 = {1 I S2}, 82 = {1 I Sa}, Sa = S4 + Ss, S4 = St, Ss = S2. The streams of Ex amples 1 through 3 (except "??") all have elementary descriptions.
The language we have defined so far still allows non sensical definitions, e.g., Q = R + 1, R = Q. To elim inate these, we require that descriptions satisfy the following additional condition. Define a relation ::J1 such that if T occurs on the right-hand side of a functional or equality definition of a stream S, then S ::J1 T. Let ;;;;! be the reflexive, transitive closure of ::J1· An elemen tary description for S is called proper if for no name T is T :::lt T and if;;;;! is a partial order. (In the preceding example, Q;;;;! Rand R;! Q, so that the definition is not proper.)
The semantics of an elementary description assigns to each S; in the definition a model stream (S;] as follows.
- If S = (v IT), then [S] is the stream whose head is v and whose tail is [T).
- If S = U, then [S] = (U].
- If S = /(T1, ... , T~c), then [S] is the stream /((Tt] ·... I (T~:]).
Theorem An elementary stream description of S has a unique model (S] if the definition is proper. Improper definitions may have no model, one model, or multiple models.
Example 4 The following definition for X of type pair is proper: X = (a I Y), Y = (Z ·A), Z = X, A = a. The stream (model) corresponding to the name X is (a, (a· a), ((a· a)· a), ... ). The stream Y is the tail of X. The stream names are ordered such that Y ;;;;! Z ;! X andY;;;;! A. Note that X 1! Y.
A stream S that can be represented by an elementary description is called an elementary stream. The main re sult of this paper is an algorithm that learns elementary streams over any constructive datatype.
Induction Spaces
Our algorithm keeps several active hypotheses for the input stream and eliminates hypotheses as soon as they conflict with the input examples. The key to the algo rithm's efficiency is the way it stores sets of hypotheses, particularly functional hypotheses. Consider Example 3 above. One of the hypotheses for this sequence is the functional hypothesis (L · R), where L is the stream a, (a·a),((a·a)·(a·a)), ... and R is the stream b, ((c·a)·b), (c ·b), .... If there are nL hypotheses for L and nR hy potheses for R, then we would have to store nLnR stream hypotheses if we represented them individually. Instead, the algorithm keeps one set for L, another for R, and the functional hypothesis ( L · R) for the stream. In this way it stores only nL + nR + 1 hypotheses;
We adopt the following representation. Let S be an input stream we want to learn. We maintain a set of hypotheses for S in different formats (initial-value for mat , equality format, etc.); this set is called an induc tion space. Hypotheses are the elements of the induc tion space. A hypothesis for S is a 3-tuple consisting of a datatype, a confirmed length (equal to the number of input values of S with which the hypothesis has agreed so far), and one of the following formats:
- initial-value format: a hypothesis in the form (s1 I 'It), where s1 is equal to the head of the stream and 1t is the name of an "induction space" (defined below) for the set of possible tail streams.
- functional format: a hypothesis in the form /('Itt, ... , 1t~:), where f is a constructor of arity k ~ 0 in n and the 'It; are the names of induction spaces.
- equality format: a hypothesis of the form U that is the name of another induction space.
- unknown format: This is a special placeholder with a confirmed length of zero representing a stream
whose first element has not yet been presented. We denote this hypothesis by D.
One hypothesis has just one format, but for the stream S there may be several hypotheses with different for mats. An induction space (or space) is a collection of hypotheses in different forms for the same stream. We assign to each induction spaces assigned a name ("S" for the input stream and arbitrary names for its substreams); without confusion we may assign to the space the same name given to the corresponding stream. Spaces also are assigned a datatype, a parent induction space, and a confirmed length equal to that of the hy potheses in the space (such lengths are all equal).
Example 5 On the dotted-pairs domain suppose the first element of an input stream S1 is (a· b). The al gorithm to follow will create an induction space sl for sl with type "pair"' confirmed length 1, and two hy potheses: an initial-value hypothesis ((a· b) I S 2}, and a functional hypothesis (S3 · S4 ). The induction space S2 will eventually contain hypotheses for the tail of sl' but since no examples of this tail stream are available, this induction space s2 is initialized to D, with a confirmed length of zero. The induction spaces S3 and S4 contain hypotheses for the left half and right half of S1, respec tively. The first example of S3 is "a", so this induction space contains two hypotheses: the initial-value hypoth esis (a I S5) (where S5 is initially 0) and the constant functional hypothesis a= (a, a, ... ). s4 is like s3, but with bin place of a. (This example is continued below.)
The Sequence Extrapolation Algorithm
The algorithm receives the sequence (s1, s2, ... ) of val ues of a stream S and incrementally constructs an induc tion space of consistent descriptions of S. The algorithm also calls upon a halting criterion that determines when to stop and declare success. Note that values of only the stream S are given the algorithm: any substreams that are part of the elementary description of S are inferred by the algorithm.
Hypotheses for S are developed in the induction space called MAIN-SPACE, initially consisting of only D. The algorithm ensures that a proper partial order is main tained among stream names in the induction space by assigning a numerical value called the delay to each new stream symbol and ensuring that equality forms refer only to symbols with smaller delay. Finally, this algo rithm assumes that the elements in the input stream are presented without any errors, and that the elements be long to a freely generated datatype (a restriction which we remove subsequently).
The output is an induction space of hypotheses con sistent with the input stream from which elementary de scriptions may be extracted.
The Extrapolation Algorithm:
- Initialize MAIN-SPACE to {D}. The confirmed length is zero, and the delay is one. The assigned name is that of the input stream (here: S).
- For i := 1, 2, 3 ... until the termination condition holds: Set MAIN-SPACE :=
EXTEND( MAIN-SPACE, si, i), where Si =the i'th value of the input stream S. Increment the con firmed length of MAIN-SPACE by one.
3. Output MAIN-SPACE.
The EXTEND Routines: Let 'H. be a space, x an in put item, and i ~ 0. The procedure EXTEND('H., x, i) replaces each hypothesis H E 1-l by zero or more hy potheses formed by extending H to account for the value z:
For each hypothesis H E 1-l, 'H. : = ( 1-l - { H}) U EXTEND-HYP(H, z, i, 'H.)
The routine EXTEND-HYP(H, x, i, 'H.) is defined by cases on H:
- Case: His D.
Return the following set of hypotheses, each with a confirmed length of one:
- The initial-value stream (x I 1-l'). The tail stream is assigned a fresh name 1-l', a confirmed length of zero, and a delay one more than that of 1-l. It is initialized to contain only the hy pothesis 0.
- The existing stream name U, provided U is in the parent hierarchy of 1-l, the delay of U is less than that of 1-l, and its initial element u1 is equal to x .
- The functional hypothesis /(1-ll, ... , 1-lk ), k ~ o, where 1 X = f(xl , ... ,xk), f E n is a constructor, and x :/; xi for any j. Each 1-lj is a new space initialized to contain only D and immediately extended by calling EXTEND('H.j, Xj, 1). 1-l is the parent space of each 'Hj, and the delay of each 1-lj is equal to that of 1-l.
- Case: H is an initial-value hypothesis. Let H = (v I 1-l'}; return the set { (v I EXTEND('H.', x, i- 1))}. Increase the confirmed length of H by one.
- Case: H is U, the name of another stream. If x = Ui, return {H} with a confirmed length of i; otherwise, return the empty set (in effect, deleting H as a hypothesis).
- Case: H is a functional hypothesis. Let H = f(1-l 1 , ··· , 'H.k ), k ~ 0. If there exist no val ues x 11 ·· · Xk such that x = f(xl, . . . , Xk) and x :/;Xi (for any i), return the empty set (in effect, deleting H as a hypothesis). Else, let x = f(xl, ... , xk)i re turn, with a confirmed length of i, the hypothesis f(EXTEND('H.l, Xi! i ), .. . , EXTEND('H.k, Xk, i)).
Example 5 (Continued) Suppose the second value of S1 is (a· a). The algorithm revises the space S1 and its subsidiaries as follows:
1 The expression x = f('H.t, ... , 'H.~c) is unique, since by as sumption the type is freely generated. See "Non-freely Gen erated Types", below.
Note that the space S2 (the tail stream of St) has been extended to two hypotheses: an initial-value and a functional hypothesis (S1 · Ss). The first value of S1 and of S8 is a. Note also that the constant stream b has been eliminated from the space s4 since it is inconsistent with the value a in the second half of the second example. Finally, observe that Sa occurs as an equality hypothesis in the space S5 because the parent space of Ss is Sa and the first element of Sa is a. Sa is not a hypothesis in the space S6 because Sa is not in the parent chain for S6.
Non-freely Generated Types. The preceding algo rithm breaks input values Si into functional components Si = f(si,, ... , si.) in order to find functional hypothe ses. When datatypes are not freely generated, there may be more than one way to do so-e.g., the integer 4 can be written 1 + 3 or 2 + 2 or 3 + 1. In such cases the preced ing algorithm can be viewed as non-deterministic: if an external oracle were available to tell it which functional form A+B was the "right" one, the algorithm would re quire no modification. Lacking such an oracle, however, the algorithm must consider all possible constructions.
Our approach is retain the single functional hypothe sis f(A, B) but replace each of the spaces A and B by a tree of spaces representing the ways of constructing the example. Consider the integer stream (3, 4, ... ), for ex ample. These first two values actually represent six pos sible pairs of examples to a functional form like A + B: for the left halfstream A= (a11a2, ··· ), a1 could be 1 or 2 and a2 could be 1, 2, or 3; and forB = (b1 , b2, ... ), the corresponding values of b1 would be 2 or 1 and, for b2, 3, 2, or 1. Thus instead of the single hypothesis of the form A+ B, we must maintain six. Not all of these hypotheses will remain consistent with the subsequent examples. For lack of space we cannot give the full algo rithm here, but the main point is that when the datatype is not freely generated, the same algorithm applies with some additional bookkeeping. Naturally, however, the number of hypotheses grows much more rapidly than it does for freely generated types.
Latency
Consider the following two descriptions of the stream s1 = (1, 2, 3, ... ),
The first description assumes only the first value as an initial value and predicts all the rest, whereas the second description assumes the first two values as initial val ues and predicts the rest. Ordinarily we prefer the first for reasons of economy (Occam's razor). The latency of a description measures the amount of assumption built into it-higher latency means that more initial values are required before the hypothesis can begin making predic tions.
Definition 2 Let S be a proper elementary description. The latency A(S) is defined recursively as follows.
- If S = (v I T), then .X(S) = 1 + .X(T).
- If S = f(T1, ... ,T~c) (k ~ 0), then A(S) = max1<i<k A(7i) if k > 0, or 1 if k = 0. In particular, if S is a-constant stream, then .X(S) = 1.
- If S = U, then A(S) = 1. I
Example 6 In the following definition for X of type pair over the generators {a, b},
the latency .X(X) is 2, and A(Y) = A(Z) = A(W) = 1. I
We may want to extract from an induction space the hypotheses of minimum latency. Induction spaces are in tentionally structured so that extracting the hypotheses of smallest latency is easily accomplished with a simple branch-and-bound algorithm. For example, in the space of Example 5 after the second instance (a·a) has arrived, there are two hypotheses of minimum latency (A = 2): (1) sl = ((a. b) I S2), S2 = (S7. Ss), and s7 = Ss =a; and (2) sl = (Sa . S4), Sa = a, s4 = (b I S6), s6 = a. Both hypotheses assume all or part of the first example as an initial value and predict the remaining values.
An Application for Sequence Extrapolation
Is the extrapolation algorithm practical, and if so, for what applications? We have implemented the algorithm in Common Lisp taking full advantage of the object oriented features for handling different datatypes. We also use lazy evaluation to delay exploring a hypothe sis until all lower-latency hypotheses in the space have been ruled out. The implementation confirms what we have also proved theoretically elsewhere [Laird and Saul, 1992]: that the algorithm is efficient (polynomial in the size of the input examples) for freely generated datatypes and streams of bounded latency, but inefficient for non freely generated types and for unbounded latency.
An application where sequence extrapolation can play a significant role is inductive concept learning, the task of formulating a general concept from examples and coun terexamples. An area of active research, inductive pro gramming has been applied to such problems in biology, structural engineering, and qualitative modeling, with modest success.
Most approaches (such as FOCL [Pazzani and Kibler, 1992], FOIL [Quinlan, 1990], GOLEM [Muggleton and Feng, 1992], etc.) depend exclusively on generalization from ground examples. While this approach sometimes works well, it requires an enormous number of examples and searches through many possible generalizations. At the same time, these methods throw away much of the structure available in the examples. As a very simple ex ample, imagine an arithmetic concept Delta(X, Y) de fined by the following examples:
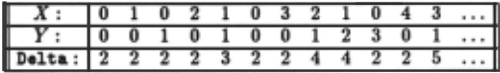
| X: | 0 1 0 2 1 0 3 2 1 0 4 3 . . . |
| Y: | 0 0 1 0 1 0 0 1 2 3 0 1 ... |
| Delta: | 2 2 2 2 3 2 2 4 4 2 2 5 ... |
The structure of this concept becomes much more discernible if arranged so that the sequential patterns emerge:
| y | 0 | 1 | 2 | 3 |
|---|---|---|---|---|
| X: | ||||
| 0 | 2 | 2 | 2 | 2 |
| 1 | 2 | 3 | 4 | 5 |
| 2 | 2 | 4 | 6 | 8 |
| 3 | 2 | 5 | 8 | 11 |
Almost immediately we can recognize that (for all in tegers X) Delta(X, 0) = 2, Delta(X, 1) = Delta(X - 1, 1) + 1, Delta( X, 2) = Delta( X - 1, 2) + 2, .... Our sequence extrapolation algorithm can easily find each of these patterns. Then by generalizing from the patterns Delta(X, 0), Delta(X, 1), Delta(X, 2), etc., instead of from the ground examples, we see that
with an initial value of Delta(O, Y) = 2. Fewer than twenty examples have sufficed to infer a simple hypoth esis for the concept. Surely this is more akin to the way humans infer concepts than the methods based solely on massive generalization.
Concluding Observations
Sequence extrapolation can be formalized as a prob lem of learning streams from their initial values. We have shown how the family of elementary streams over constructive datatypes can be effectively learned, using the Extrapolation Algorithm.
While elementary streams are a reasonably expres sive family and many common sequences are elemen tary, many more sequences (e.g., the primes) are not elementary streams. The primary value of this work is to demonstrate that sequence extrapolation can be stud ied in much greater generality than heretofore, and that there exists a simple and efficient algorithm for at least an interesting class of sequences.
Elsewhere [laird and Saul, 1992; Laird et al., 1993] we analyze the algorithm and prove it correct. As noted above, its complexity depends on the latency of the tar get stream and on whether the datatype is freely gen erated. We have also developed a model that quantifies how one's confidence in a hypothesis grows with contin ued success in predicting sequence values.
Empirically one finds that very few input values (e.g., five to ten) are needed to identify an elementary stream. Unfortunately, the sample size analysis turns out to be quite difficult in general, but for one particular datatype we have calculated the sample size bound exactly. For this case the sample size is, indeed, very small-unlike statistical concept learning, where even very constrained concept classes require hundreds or thousands of exam ples.
We have also studied the problem of sequence extrap olation when the input values may contain errors. We hope to be able to report these results and some appli cations in the future .
Acknowledgments
The inspiration for this work came from Peter S. Dunning, who first discovered some intriguing relationships between string sequences and integer sequences. The authors thank Peter Dunning, Peter Friedland, Mike Lowry, Steve Minton, David Thompson, and Richard Waters for their suggestions.
@inproceedings{ijcai1993p155,
  title     = {Sequence Extrapolation},
  author    = {Laird, Philip D. and Saul, Ronald},
  booktitle = {Proceedings of the Thirteenth International Joint Conference on
               Artificial Intelligence, {IJCAI-93}},
  publisher = {International Joint Conferences on Artificial Intelligence},
  editor    = {Ruzena Bajcsy},
  pages     = {1120--1126},
  year      = {1993},
  note      = {Machine Learning},
  url       = {https://ijcai.org/proceedings/1993/155},
}
TY - CPAPER TI - Sequence Extrapolation AU - Laird, Philip D. AU - Saul, Ronald T2 - Proceedings of the Thirteenth International Joint Conference on Artificial Intelligence, IJCAI-93 PB - International Joint Conferences on Artificial Intelligence PY - 1993 SP - 1120 EP - 1126 UR - https://ijcai.org/proceedings/1993/155 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





