
Action-Gradient Monte Carlo Tree Search for Non-Parametric Continuous (PO)MDPs
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 4474-4482.
https://doi.org/10.24963/ijcai.2026/498
Keywords
- Planning and Scheduling: Planning under uncertainty
- Planning and Scheduling: POMDPs
- Machine Learning: Model-based and model learning reinforcement learning
Abstract
Online planning in continuous state, action, and observation spaces remains challenging for autonomous systems. While Monte Carlo Tree Search (MCTS) scales effectively via sampling, most continuous (PO)MDP solvers do not exploit gradient-based action optimization. We propose Action-Gradient MCTS (AGMCTS), a framework that combines global tree search with local gradient-based action refinement, while maintaining consistent value estimates. We provide three key theoretical contributions: (1) an action score gradient theorem for particle belief states; (2) the Multiple Importance Sampling (MIS) Tree that supports frequent action-branch updates by reusing prior samples without introducing estimator drift; and (3) tractable action score gradients for smooth generative models using the Area Formula. Empirical results demonstrate that AGMCTS outperforms state-of-the-art sample-based solvers in multiple challenging continuous MDP and POMDP benchmarks.
- [Åström, 1965] Karl Johan Åström. Optimal control of Markov processes with incomplete state information i. Journal of mathematical analysis and applications, 10:174-205, 1965.
- [Azizzadenesheli et al., 2018] Kamyar Azizzadenesheli, Yisong Yue, and Animashree Anandkumar. Policy gradi- ent in partially observable environments: Approximation and convergence. arXiv preprint arXiv:1810.07900, 2018.
- [Baxter and Bartlett, 2001] Jonathan Baxter and Peter L Bartlett. Infinite-horizon policy-gradient estimation. jour- nal of artificial intelligence research, 15:319-350, 2001.
- [Browne et al., 2012] Cameron B Browne, Edward Pow- ley, Daniel Whitehouse, Simon M Lucas, Peter I Cowl- ing, Philipp Rohlfshagen, Stephen Tavener, Diego Perez, Spyridon Samothrakis, and Simon Colton. A survey of Monte Carlo tree search methods. IEEE Transactions on Computational Intelligence and AI in games, 4(1):1-43, 2012.
- [Couëtoux et al., 2011] Adrien Couëtoux, Jean-Baptiste Hoock, Nataliya Sokolovska, Olivier Teytaud, and Nicolas Bonnard. Continuous upper confidence trees. In International conference on learning and intelligent optimization, pages 433-445. Springer, 2011.
- [Doucet et al., 2001] Arnaud Doucet, Nando de Freitas, and Neil Gordon, editors. Sequential Monte Carlo Methods In Practice. Springer-Verlag, New York, 2001.
- [Egorov et al., 2017] Maxim Egorov, Zachary N Sunberg, Edward Balaban, Tim A Wheeler, Jayesh K Gupta, and Mykel J Kochenderfer. POMDPs.jl: A framework for se- quential decision making under uncertainty. The Journal of Machine Learning Research, 18(1):831-835, 2017.
- [Ernst et al., 2005] Damien Ernst, Pierre Geurts, and Louis Wehenkel. Tree-based batch mode reinforcement learning. Journal of Machine Learning Research, 6, 2005.
- [Farhi and Indelman, 2021] Elad I. Farhi and Vadim Indel- man. iX-BSP: Incremental belief space planning. arXiv preprint arXiv:2102.09539, 2021.
- Herbert Federer. Geometric measure theory, volume 153 of Grundlehren Math. Wiss. Springer, Cham, 1969.
- [Hoerger et al., 2024] Marcus Hoerger, Hanna Kurniawati, Dirk Kroese, and Nan Ye. Adaptive discretization using Voronoi trees for continuous POMDPs. The International Journal of Robotics Research, 43(9):1283-1298, 2024.
- [Hong et al., 2024] Mao Hong, Zhengling Qi, and Yanxun Xu. A policy gradient method for confounded POMDPs. In The Twelfth International Conference on Learning Rep- resentations, 2024.
- [Kaelbling et al., 1998] Leslie Pack Kaelbling, Michael L. Littman, and Anthony R. Cassandra. Planning and act- ing in partially observable stochastic domains. Artificial intelligence, 101(1):99-134, 1998.
- [Kim et al., 2020] Beomjoon Kim, Kyungjae Lee, Sungbin Lim, Leslie Kaelbling, and Tomás Lozano-Pérez. Monte Carlo tree search in continuous spaces using Voronoi opti- mistic optimization with regret bounds. In AAAI Conf. on Artificial Intelligence, volume 34, pages 9916-9924, 2020.
- [Kingma and Ba, 2015] Diederik P. Kingma and Jimmy Ba. Adam: A method for stochastic optimization. In Yoshua Bengio and Yann LeCun, editors, 3rd International Con- ference on Learning Representations, ICLR 2015, San Diego, CA, USA, May 7-9, 2015, Conference Track Pro- ceedings, 2015.
- [Kloek and Van Dijk, 1978] Teun Kloek and Herman K Van Dijk. Bayesian estimates of equation system parame- ters: an application of integration by Monte Carlo. Econo- metrica: Journal of the Econometric Society, pages 1-19, 1978.
- [Kocsis and Szepesvári, 2006] Levente Kocsis and Csaba Szepesvári. Bandit based Monte-Carlo planning. In Eu- ropean conference on machine learning, pages 282-293. Springer, 2006.
- [Kong et al., 1994] Augustine Kong, Jun S. Liu, and Wing Hung Wong. Sequential imputations and Bayesian missing data problems. Journal of the American Statistical Association, 89(425):278-288, 1994.
- [Kujanpää et al., 2024] Kalle Kujanpää, Amin Babadi, Yi Zhao, Juho Kannala, Alexander Ilin, and Joni Pajari- nen. Continuous Monte Carlo graph search. In Intl. Conf. on Autonomous Agents and Multiagent Systems (AAMAS), pages 1047-1056, 2024.
- [Kurniawati, 2022] Hanna Kurniawati. Partially observable Markov decision processes and robotics. Annual Review of Control, Robotics, and Autonomous Systems, 5(1):253- 277, 2022.
- [Lauri et al., 2022] Mikko Lauri, David Hsu, and Joni Pa- jarinen. Partially observable Markov decision processes in robotics: A survey. IEEE Transactions on Robotics, 39(1):21-40, 2022.
- [Lee et al., 2020] Jongmin Lee, Wonseok Jeon, Geon- Hyeong Kim, and Kee-Eung Kim. Monte-Carlo tree search in continuous action spaces with value gradients. In Proceedings of the AAAI conference on artificial intel- ligence, volume 34, pages 4561-4568, 2020.
- [Leurent and Maillard, 2020] Edouard Leurent and Odalric- Ambrym Maillard. Monte-Carlo graph search: the value of merging similar states. In Sinno Jialin Pan and Masashi Sugiyama, editors, Asian Conference on Machine Learn- ing (ACML 2020), pages 577 -592, Bangkok, Thailand, November 18-20 2020.
- [Lev-Yehudi et al., 2026] Idan Lev-Yehudi, Michael Novit- sky, Moran Barenboim, Ron Benchetrit, and Vadim Indel- man. Value gradients with action adaptive search trees in continuous (PO)MDPs. arXiv preprint arXiv:2503.12181, 2026.
- [Lim et al., 2021] Michael H Lim, Claire J Tomlin, and Zachary N Sunberg. Voronoi progressive widening: ef- ficient online solvers for continuous state, action, and ob- servation POMDPs. In 2021 60th IEEE conference on de- cision and control (CDC), pages 4493-4500. IEEE, 2021.
- [Lim et al., 2023] Michael H Lim, Tyler J Becker, Mykel J Kochenderfer, Claire J Tomlin, and Zachary N Sunberg. Optimality guarantees for particle belief approximation of POMDPs. Journal of Artificial Intelligence Research, 77:1591-1636, 2023.
- [Madani et al., 2003] Omid Madani, Steve Hanks, and Anne Condon. On the undecidability of probabilistic planning and related stochastic optimization problems. Artificial In- telligence, 147(1-2):5-34, 2003.
- [Mern et al., 2021] John Mern, Anil Yildiz, Zachary Sun- berg, Tapan Mukerji, and Mykel J Kochenderfer. Bayesian optimized Monte Carlo planning. In Proceedings of the AAAI Conference on Artificial Intelligence, volume 35, pages 11880-11887, 2021.
- [Metelli et al., 2020] Alberto Maria Metelli, Matteo Papini, Nico Montali, and Marcello Restelli. Importance sampling techniques for policy optimization. J. Mach. Learn. Res., 21(141):1-75, 2020.
- [Morere et al., 2018] Philippe Morere, Roman Marchant, and Fabio Ramos. Continuous state-action-observation POMDPs for trajectory planning with Bayesian optimisa- tion. In 2018 IEEE/RSJ international conference on intel- ligent robots and systems (IROS), pages 8779-8786. IEEE, 2018.
- [Negro, 2022] Luigi Negro. Sample distribution theory using coarea formula. Communications in Statistics-Theory and Methods, pages 1-26, 2022.
- [Novitsky et al., 2025] Michael Novitsky, Moran Baren- boim, and Vadim Indelman. Previous knowledge uti- lization in online anytime belief space planning. IEEE Robotics and Automation Letters (RA-L), 2025.
- [Owen, 2013] Art B. Owen. Monte Carlo theory, methods and examples. https://artowen.su.domains/mc/, 2013. Link
- [Papadimitriou and Tsitsiklis, 1987] Christos H. Papadim- itriou and John N. Tsitsiklis. The complexity of Markov decision processes. Mathematics of operations research, 12(3):441-450, 1987.
- [Platt et al., 2010] Robert Platt, Jr., Russ Tedrake, Leslie Pack Kaelbling, and Tomás Lozano-Pérez. Belief space planning assuming maximum likelihood observations. In Robotics: Science and Systems (RSS), pages 587-593, Zaragoza, Spain, 2010.
- [Porta et al., 2006] Josep M. Porta, Nikos Vlassis, Matthijs T.J. Spaan, and Pascal Poupart. Point-based value iteration for continuous POMDPs. J. of Machine Learning Research, 7:2329-2367, 2006.
- [Schulman et al., 2016] John Schulman, Philipp Moritz, Sergey Levine, Michael I. Jordan, and Pieter Abbeel. High-dimensional continuous control using generalized advantage estimation. In Intl. Conf. on Learning Repre- sentations (ICLR), 2016.
- [Silver and Veness, 2010] David Silver and Joel Veness. Monte-Carlo planning in large POMDPs. In Advances in Neural Information Processing Systems (NeurIPS), pages 2164-2172, 2010.
- [Silver et al., 2014] David Silver, Guy Lever, Nicolas Heess, Thomas Degris, Daan Wierstra, and Martin Riedmiller. Deterministic policy gradient algorithms. In International conference on machine learning, pages 387-395. Pmlr, 2014.
- [Singh and Sutton, 1996] Satinder P Singh and Richard S Sutton. Reinforcement learning with replacing eligibility traces. Machine learning, 22:123-158, 1996.
- [Sunberg and Kochenderfer, 2018] Zachary Sunberg and Mykel Kochenderfer. Online algorithms for POMDPs with continuous state, action, and observation spaces. In Proceedings of the International Conference on Automated Planning and Scheduling, volume 28, 2018.
- [Sutton et al., 1999] Richard S Sutton, David McAllester, Satinder Singh, and Yishay Mansour. Policy gradient methods for reinforcement learning with function approx- imation. Advances in neural information processing sys- tems, 12, 1999.
- [Veach and Guibas, 1995] Eric Veach and Leonidas J Guibas. Optimally combining sampling techniques for Monte Carlo rendering. In Proceedings of the 22nd annual conference on Computer graphics and interactive techniques, pages 419-428. ACM, 1995.
- [Wu et al., 2021] Chenyang Wu, Guoyu Yang, Zongzhang Zhang, Yang Yu, Dong Li, Wulong Liu, and Jianye Hao. Adaptive online packing-guided search for POMDPs. Advances in Neural Information Processing Systems, 34:28419-28430, 2021.
- [Ye et al., 2017] Nan Ye, Adhiraj Somani, David Hsu, and Wee Sun Lee. DESPOT: Online POMDP planning with regularization. JAIR, 58:231-266, 2017.
- [Yee et al., 2016] Timothy Yee, Viliam Lisý, and Michael Bowling. Monte Carlo Tree Search in continuous action spaces with execution uncertainty. In Subbarao Kambham- pati, editor, IJCAI, pages 690-697, 2016. IJCAI
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Planning under uncertainty is central to AI and robotics, where state, action, and observation spaces are often continuous [Lauri et al., 2022]. Markov Decision Processes (MDPs) and Partially Observable Markov Decision Processes (POMDPs) model such problems, but exact solutions are generally intractable [Papadimitriou and Tsitsiklis, 1987; Madani et al., 2003], motivating efficient approximation.
Online solvers compute actions on demand from the current state or belief [Kurniawati, 2022], often via tree search such as Monte Carlo Tree Search (MCTS) [Silver and Veness, 2010] and Determinized Sparse Partially Observable Tree (DESPOT) [Ye et al., 2017]. Earlier continuous-POMDP offline methods often used fixed-dimensional parametric beliefs, e.g., Gaussian beliefs [Porta et al., 2006]; recent continuous MDP/POMDP online methods improve scalability via progressive widening, including Double Progressive Widening (DPW) for MDPs and POMCPOW/PFT-DPW for POMDPs [Cou¨etoux et al., 2011; Sunberg and Kochenderfer, 2018].
Most sampling-based continuous POMDP planners keep sampled actions fixed. VG-UCT [Lee et al., 2020] refines continuous-MDP actions, but does not correct value-estimate drift after action updates. Action-Gradient MCTS (AGMCTS) integrates gradient steps into global MCTS via MIS, and is the first such hybrid strategy for non-parametric continuous POMDPs with sample-based beliefs.
1.1 Contributions
Theoretical. We derive an action score gradient theorem for MDPs and POMDPs in online tree search with importance weighting. We introduce the Multiple Importance Sampling (MIS) Tree and its action update operation, allowing frequent gradient steps while maintaining value-estimate consistency. We also compute action score gradients tractably for smooth generative models via the Area Formula.
Algorithmic. We present AGMCTS (Algorithm 1), blending MCTS action exploration with online gradient refinement for MDPs/POMDPs under DPW or alternative continuousaction selection heuristics.
Experimental. Across continuous MDP and POMDP benchmarks, AGMCTS variants show notable gains in most domains and competitive performance overall.
1.2 RelatedWork
Online Optimization in MCTS. Lee et al. [2020] have proposed VG-UCT for integrating gradient steps into MCTS in continuous MDPs. Their Lipschitz-continuous transition and reward setting gives a deterministic-MDP convergence result; we give estimator gradients under weaker assumptions and address value-estimate drift from action updates.
Black-box optimization methods have been used to bias action selection in MCTS to more promising regions, e.g. Voronoi optimistic optimization (VOO) [Kim et al., 2020] and Voronoi progressive widening (VPW) [Lim et al., 2021; Hoerger et al., 2024], kernel regression [Yee et al., 2016] and Bayesian optimization [Morere et al., 2018; Mern et al., 2021] methods. These complement AGMCTS by improving action proposals rather than refinements.
(PO)MDP Action-Gradients. An action-gradient corresponds to the single-step gradient of a policy with a deterministic immediate action. Policy gradients in POMDPs typically assume stochastic policies [Baxter and Bartlett, 2001], memory-less policies [Azizzadenesheli et al., 2018], or finite action spaces [Hong et al., 2024], while we handle belief-dependent policies with continuous actions. Silver et al. [2014] studied deterministic policies in MDPs; we extend to non-parametric POMDPs.
Information Reuse in Planning. Leurent and Maillard [2020] considered information sharing in discrete MDPs by merging similar states. Novitsky et al. [2025] have introduced previous knowledge utilization in POMDPs via Multiple Importance Sampling (MIS) [Veach and Guibas, 1995]. We reuse samples across sibling action branches via the MIS Tree, avoiding retrieval from an external belief database. POMDP planning has used MIS for sample reuse, e.g. [Farhi and Indelman, 2021], mainly to compute observation likelihoods. AdaOps and CMCGS cluster values of similar observations/states [Wu et al., 2021; Kujanp¨a¨a et al., 2024], whereas we recompute value estimates under updated actions.
2 Background
MDPs and POMDPs. We consider MDPs in the form ⟨S,A, pT , r, γ, L, b0⟩. The state and action spaces are S ⊆ Rns and A ⊆ Rna . The transition model pT (s′ |s, a) is the probability of arriving at state s′ when taking action a ∈ A at state s ∈ S. The reward function r(s, a, s′ ) ∈ R gives the immediate reward of transitioning from state s to s′ by taking action a, and the expected reward is r(s, a) ≜ Es′ |s,a[r(s, a, s′ )]. The discount factor is γ ∈ (0, 1]. The MDP starts at time 0 and terminates after L ∈ N ∪ {∞} steps, and if L = ∞ then we assume γ < 1. The initial state is drawn from the distribution s0 ∼ b0.
We assume π = (πt)Lt=0 is a (possibly time-dependent) deterministic policy, but we note our theoretical results generalize to stochastic policies as well. The value function of a policy π at time t is the expected sum of discounted rewards until the horizon: V π t (st) ≜ Est+1:L|st,π [∑Li=t γ i-t r(si, πi(si), si+1)]. We denote nextstep variables with primes, e.g. s′ follows s. We define the action-value function as Qπt (s, a) ≜ Es′ |s,a[r(s, a, s′ ) + γV π t+1 (s′ )]. Our goal is to compute a policy that maximizes the value function, i.e. find π∗ ∈ argmaxπ V π 0 (s0).
A POMDP adds ⟨O, pO⟩ to the MDP tuple. The observation space is O ⊆ Rno , and the observation model pO(o|s) is the conditional probability of receiving an observation o ∈ O at s ∈ S. Similarly to Sunberg and Kochenderfer [2018], we assume that we can both sample from and evaluate pO(o|s).
A history at time t is defined as a sequence of b0, followed by actions taken and observations received until t: Ht ≜ (b0, a0, o1, . . . , at-1, ot). In partially observable settings, the agent has to maintain a probability distribution of the current state given past actions and observations, known as the belief. The belief at time t is bt(st) ≜ p(st|Ht). We define Ht ≜ (b0, a0, o1, . . . , at-1), i.e. the history until time t without the last measurement, and correspondingly the propagated belief b-t (st) ≜ p(st|Ht ). It has been shown that optimal decision-making can be made given the belief, instead of considering the entire history [Kaelbling et al., 1998], meaning a POMDP is an MDP on the belief space [ ˚Astr¨om, 1965]. Policies and value functions extend fromMDPs to POMDPs by equivalent definitions on beliefs as states.
Importance Sampling. Importance Sampling (IS) [Kloek and Van Dijk, 1978] is a technique in Monte-Carlo (MC) estimation where a proposal distribution q is used to generate samples. The IS estimator for g(x) = Ex∼p[f(x)] is ˆ gq = N -1 ∑Ni=1 ρpq (xi )f(xi ), for importance ratios ρpq (x) ≜ p(x)/q(x). The IS estimator ˆ gq is unbiased if q(x) = 0 implies p(x) = 0. Often, the self-normalized IS (SNIS) estimator is formulated when we only have access to an unnormalized version of p, or for variance reduction purposes, and is given by ˜ gq = (∑Ni=1 ρpq (xi ))-1 ∑Ni=1 ρpq (xi )f(xi ). While biased, under weak assumptions it is consistent [Owen, 2013, 9.2]. We denote SNIS estimators throughout with ˜ [·].
MIS [Veach and Guibas, 1995] is a method to leverage several sampling methods {qi}ni=1 , by calculating a weighted average of IS estimators with ni samples each: The corresponding MIS estimator is ˆ gMIS = ∑ni=1 n-1 i ∑ni j=1 wi(xi,j )ρpqi (xi,j )f(xi,j ). If the weights wi satisfy requirements: (MIS-I) ∑ni=1 wi(x) = 1 whenever f(x) ̸= 0; (MIS-II) wi(x) = 0 whenever qi(x) = 0; then ˆ gMIS is unbiased. Many weighting strategies exist; the balance heuristic wi(x) = niqi(x)/ ∑k nkqk(x), has its variance provably bounded from the optimal weighting strategy for independent samples. Analogously to SNIS, self-normalized MIS (SN-MIS) can be defined as ˜ gMIS = β-1 ∑ni=1 ∑ni j=1 wi(xi,j )ρpqi (xi,j )f(xi,j ) for β = ∑ni=1 ∑ni j=1 wi(xi,j )ρpqi (xi,j ) [Metelli et al., 2020].
Particle Beliefs. Particle filters are often used to represent a belief non-parametrically [Doucet et al., 2001, 1.3.2]. We denote particle beliefs with ¯b. The particle belief of J particles is the ordered set of state-weight pairs ¯b = ((sj , λj ))Jj=1 (following [Lim et al., 2023]), and is defined as the discrete distribution p(s|¯b) = ∑Jj=1 λj · δ(s - sj )/∑Jj=1 λj . For computational simplicity, we assume throughout the paper that the bootstrap filter is used to update particle beliefs [Doucet et al., 2001, 1.3.2]. At each time step, the bootstrap filter advances sampled particles using the transition model, reweights them based on the observation model, and resamples to avoid weight degeneracy [Kong et al., 1994].
MCTS and DPW. MCTS is an algorithm used to quickly explore large state spaces [Browne et al., 2012]. It iteratively repeats four steps to build a search tree that approximates the action-values, using a best-first strategy: (1) Selection: Starting from the root node, descend recursively until a node to which children can be added is found; (2) Expansion: A new node is added as a child, according to an action expansion strategy; (3) Simulation: A simulation is run from the new node according to the rollout (default) policy; (4) Backpropagation: The simulation result is backpropagated through the selected nodes to update the action-values. Often UCT [Kocsis and Szepesv´ari, 2006] is used at selection to balance between exploration of new actions and exploitation of promising ones. Double Progressive Widening (DPW) [Cou¨etoux et al., 2011] is a technique to limit the branching factor from being infinite in continuous settings. The number of children of a node is artificially limited to kN α for N visitations, for fixed k > 0 and 0 < α < 1.
3 Action Gradients andMIS Trees
Here we present the theoretical basis of AGMCTS. We derive action score gradients for local refinement, introduce MIS Trees for consistent value estimates, and discuss density computation for smooth black-box simulators.
3.1 (PO)MDP Action Score Gradients
In POMDPs the posterior belief transition probability p(b′ |b, a) is generally intractable. We approach the belief update structure via the propagated belief density:
The propagated belief b′- is obtained after action a but before observation o′ . Exact beliefs make p(b′-|b, a) a Dirac delta because b′- is deterministic in (b, a); for particle beliefs ¯b, ¯b′- it is non-degenerate because particles are sampled through stochastic transitions:
Lemma 1. Let ¯b = ((sj , λj ))Jj=1 , ¯b′- = ((s′-,j , λ′-,j ))Jj=1 be ordered particle beliefs. The probability that ¯b′- is a propagated belief in the bootstrap filter, given ¯b and action a, is:
whenever λ′-,j = λj for all j = 1, . . . , J, and zero otherwise. When p(¯b′-|¯b, a) > 0 it holds that:
We use this to introduce importance ratios over the future propagated belief ¯b′- rather than the posterior belief ¯b′ .
In tree search, after updating action a to ˘a, we estimate Qπt (s, ˘a) by reusing samples fromQπt (s, a) instead of recomputing the subtree. Because repeated updates create samples from multiple proposals, we use IS/MIS. Equations (4)-(5) give the single-proposal action-reuse form:
where ρpT q (s′ ) ≜ pT (s′ |s, ˘a)/q(s′ |s, ˘a), and ρpq (¯b′-) ≜ p(¯b′-|¯b, ˘a)/q(¯b′-|¯b, ˘a) are the importance ratios. The ratios require proposal support to cover target support. We use q(s′ |s, ˘a) := pT (s′ |s, a), reusing samples from the previous action a, but generally other choices are possible too. In Section 3.2, we extend Equations (4)-(5) to an MIS setting with multiple proposals, where assumptions (MIS-I) and (MIS-II) suffice for unbiasedness (Section 2).
We introduce our main results of action score gradients.
Theorem 1. Assume: (i) ρpT q (s′ ), ρpq (¯b′-) are well-defined; (ii) r, V are bounded; (iii) there exist integrable gr, gT w.r.t. the MDP/POMDP measures such that ∥∇ar∥ ≤ gr and ∥∇a log pT∥ ≤ gT . For POMDPs, assume the assumptions of Lemma 1 hold. Then, the action score gradient satisfies:
where B(s) (resp. B(¯b)) is any baseline independent of ˘a for estimator variance reduction [Schulman et al., 2016], e.g. B(s) = V π t (s).
The proof follows policy-gradient arguments [Sutton et al., 1999]. We give all proofs in the Appendix [Lev-Yehudi et al., 2026]. The result allows computing action gradients with samples taken from the proposal q. The gradient favors immediate reward and likely high-value successors; since s′ is integrated out, V π t+1 (s′ ) has no direct ˘a-gradient. Compared with recursive estimates like VG-UCT [Lee et al., 2020], these score gradients are branch-local in the MIS Tree, and apply to belief-dependent policies via Equation (1).
3.2 MIS Trees for Action-Adaptive MCTS
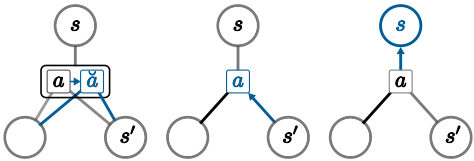
We introduce the MIS Tree, a novel search-tree whose action-value estimates are MIS estimators. It supports standard backpropagation plus action update: replacing an action label while reusing previous successor states for a consistent updated action-value estimate. Figure 1 illustrates these operations. We formulate the MIS Tree recursively over state nodes s and action nodes (s, a). For POMDPs, we use a particle-filter tree (PFT) [Sunberg and Kochenderfer, 2018], replacing s by ordered particle belief states ¯b throughout.
Each state node s has a set of child actions As ≜ {ai }i. Each action node (s, a) has a set of child successor states Ssa ≜ {s′,i }i. The visitation counts of state and action nodes are n(s) and n(s, a). We store for each successor s′,i the proposal action aiprop , namely the action under which s′,i was originally sampled. This stored proposal action may differ from the current action label a after action updates. We also store the value estimate ˆ V (s′,i ), defined by:
Algorithm 1 AGMCTS. Highlighted lines mark AGMCTS-specific MIS and action-optimization steps.
procedure SIMULATE(s, d) 1: if d = 0 then 2: v ←ROLLOUT(s) {Rollout until terminal state} 3: UPDATETERMINAL(s, v) {Eq. (17)} 4: return v 5: a ←ACTIONPROGWIDEN(s) {Vanilla or VPW} 6: addBranch ←ACTIONOPT (s, a, d) 7: if |Ssa| ≤ ko · n(s, a)αo OR addBranch then 8: s′ , r ∼ G(s, a) {¯b′-,¯b′ , r ∼ G(¯b, a) in POMDPs} 9: Ssa ←Ssa ∪ {s′ } 10: v ← ROLLOUT(s′ , d-1) 11: else 12: s′ ∼ Unif(Ssa), r ←REWARD(s, a, s′ ) 13: v ← SIMULATE(s′ , d-1) 14: UPDATEMIS(s, a, s′ , r) {Eqs. (15), (16), (18)} procedure ACTIONOPT(s, a, d) 1: addBranch ←FALSE 2: for all k = 1, . . . ,Kopt do 3: gqa ← ˆ∇a ˜Q(s, a) {Eq. (21)} 4: ˘a ← OPT(s, a, gqa ) {Adam/other} 5: ˘a ←CLIPNORM(˘a, T max da ) 6: ACTIONUPDATE(s, a, ˘a) {Eq. (11)-(14), (18)} 7: addBranch ← addBranch ∨ (∀s′,i ∈ Ss˘a : ρi˘a (s′,i ) ≤ T add ρ ) 8: return addBranchThe visitation counts satisfy:
Here, n(s′ )+1 ≜ n(s′ ) + 1 is the post-expansion count contribution of successor s′ . The +1 accounts for the initial rollout value stored when the successor node is created, while n(s′ ) counts later visits. For action nodes, ˆQ(s, a) ≜ ˆ r(s, a) + γ ˆ Vf (s, a), where ˆ r estimates immediate reward and ˆ Vf estimates next-step value. Our key observation is that this decomposition lets action update recompute ˆ Vf from older successor samples and their stored value estimates.
Generally in MIS, each proposal distribution qi has ni samples. In our situation, we assume that each s′,i ∈ Ssa was sampled from pT (·|s, aiprop ), with its associated single value estimate V (s′,i ). Therefore, we adapt the MIS definition to combine successor-specific estimators, based on the associated proposal action, branch importance ratio ρia (s′ ) and MIS weights wi(s′ ):
and for POMDPs ρia (¯b′ ) ≜ p(¯b′-|¯b, a)/p(¯b′-|¯b, aiprop ). Analogously, replace ˆ V (s′,i ) with r(s, a, s′,i ) to obtain ˆ r(s, a).
The following theorem shows that the MIS conditions suffice for unbiasedness of the MIS Tree:
Theorem2. If wi(s′ ) satisfy requirements (MIS-I) and (MISII) (see Section 2), then the MIS Tree yields unbiased value and action-value estimates for a given tree structure.
The MIS balance heuristic requires O(|Ssa|) density evaluations per recursive sample update [Novitsky et al., 2025]. For efficiency, we use self-normalized MIS (SNMIS) [Metelli et al., 2020] with naive weights wi(s′ ) ∝ n(s′,i )+1, which we found to perform well in practice:
Using SN-MIS, all MCTS operations are O(1) except O(|Ssa|) action update. We give full MIS Tree derivations, numerically stable log-likelihood forms, and analogous immediate-reward updates in the Appendix.
Action Update. Action update replaces (s, a) by (s, ˘a), recomputes all ratios, (12), (13), and immediate rewards in O(|Ssa|) time.
In POMDPs, the explicit computation of the new transition likelihood p(¯b′-|¯b, ˘a) via (2) requires J evaluations of the transition density, for J particles in ¯b and ¯b′-, which may be computationally expensive. As p(¯b′-|¯b, ˘a) is a product of probabilities, a direct MC estimate based on a subset of particles results in a large bias. We resort to estimating changes in log p(¯b′-|¯b, ˘a). For small ∥˘a - a∥ we approximate 1
and due to Equation (3) being a sum, it admits an unbiased MC estimate by subsampling particles.
Action Backpropagation. Let s′,i be an updated node. Hence, we updated n(s′,i ) to n′ (s′,i ) and ˆ V (s′,i ) to ˆ V ′ (s′,i ). We update n(s, a) by (9) and perform
Assuming a general n′ (s′ ) also supports cases where we delete branches in the tree, i.e. n′ (s′ ) < 1. For state expansion, the same equations apply by initializing n(s′ ) = 0.
State Backpropagation. Let s be a state node. If s is at the maximum tree depth, ˆ V (s) is based only on rollouts. We update the running average with the new rollout value v′ ,
If s is not a terminal state, let its recently updated action-value child be (s, a), with updated n′ (s, a) and ˜Q′ (s, a). We update n′ (s) by (9) and perform
1 This is obtained by the first-order approximation f(x + δx) ≈ f (x) + ∇f (x)T δx, applied to log ρia(s′ ) where δa = ˘a - a.
3.3 Densities of Smooth Generative Models via the Area Formula
Thus far we have assumed computable pT (s′ |s, a) and ∇a log pT (s′ |s, a). In practice, many simulators provide instead s′ = f(s, a, ξ) with noise ξ ∼ pξ(·|s, a) ∈ Rnξ . If nξ = ns and ξ ↦→ f(s, a, ξ) is bijective and differentiable, the change-of-variables formula states that for s′ = f(s, a, ξ ∗ ):
where Dξf is the Jacobian matrix of f w.r.t. ξ. However, it is often the case that nξ < ns and ξ ↦→ f(s, a, ξ) is an embedding into an nξ-dimensional manifold rather than a bijection. Then pT (s′ |s, a) is a density with respect to the induced manifold measure, not Lebesgue measure, and the Area Formula [Federer, 1969, Theorem 3.2.3] applies. Negro [2022] gives the following locally Lipschitz form for f and the induced density pT :
Theorem 4.1. [Negro, 2022] If f is locally Lipschitz, and it holds that rank(Dξf) = nξ a.e., then the induced probability measure over s′ is absolutely continuous w.r.t. the Hausdorff measure Hnξ on Rns , and its Radon-Nikodym derivative is
We further discuss these assumptions in the Appendix. Robotics simulators often integrate continuous-time dynamics with stochasticity injected at the input or output. In both cases below, once pT is computable, ∇a log pT follows by chain rule and automatic differentiation.
Input Noise to Simulator. Let the input noise be described by the function h(s, a, ξ) = (˜ s, ˜a). The simulator then produces a successor state via s′ = f(˜ s, ˜a). If for a new action ˘a there exists a unique ξ ∗ satisfying h(s, ˘a, ξ ∗ ) = (˜ s, ˜a), i.e. such that the input to the simulator remains unchanged, then we can evaluate the sensitivity of the output state with respect to the noise: Dξf(s, ˘a, ξ ∗ ) = D(˜ s,˜a)f · ∂h ∂ξ |s,˘a,ξ∗ . Moreover, the Jacobian matrix D(˜ s,˜a)f can be cached from the original sample (s, a, ξ, s′ ), allowing to compute the density without requiring additional simulator queries.
Noise in Simulator Output. Let the simulator output be h(s, a), and the next state be given by s′ = g(h(s, a), ξ). If we can find all ξ ∗ such that s′ = g(h(s, ˘a), ξ ∗ ), then we compute the Jacobian via Dξf(s, ˘a, ξ ∗ ) = ∂g ∂ξ |h(s,˘a),ξ∗, requiring a single forward simulation h(s, ˘a) for all ξ ∗ .
4 AGMCTS Algorithm
AGMCTS combines MCTS with frequent action-gradient optimization, and correcting online value estimates via MIS. It uses a forward simulator G(s, a) with assumed access to pT and pO, controls branching via DPW, and extends to POMDPs via ordered particle-belief states like PFTDPW [Sunberg and Kochenderfer, 2018]. Algorithm 1 keeps the standard simulation loop; highlighted components add ACTIONOPT and MIS action update before expansion so gradients influence expansion. We detail the implementation in the Appendix.
Monte Carlo Gradient Estimation. In POMDPs, we estimate (3) with K∇ b state particles via ∇a log p(¯b′-|¯b, a) ≈ (J/K∇ b ) ∑K∇ b l=1 ∇a log pT (s-,jl |sjl , a), where indices jl are sampled uniformly from [1, . . . , J], and J is the particle count of ¯b and ¯b′-. We choose a baseline function of the current value estimate B(s) = ˆ V (s) (B(¯b) = ˆ V (¯b) in POMDPs), effectively estimating advantage gradients. As we linearize the weight updates as in Equation (14), ∇aρia (s′,i ) has to be computed for all s′,i ∈ Ssa. To save computations, we sum over all successor states s′ ∈ Ssa when computing ˆ∇ ˜Q(s, a):
and we cache ∇a log pT (s′,i |s, a) for later action updates.
Gradient Optimization. We used Adam [Kingma and Ba, 2015] for its step-size normalization, which is crucial for high-variance gradients. We perform Kopt consecutive gradient updates to control the accuracy-compute trade-off, and additional clipping of ∥˘a - a∥ to T max da to stabilize updates.
Threshold for Adding Successor Nodes. If ρi˘a (s′,i ) < T add ρ for all s′,i ∈ Ss˘a, we force a new successor sample, with optional low-relevance deletion.
Action Sampling Heuristics. We use uniform action sampling and Voronoi progressive widening (VPW) [Lim et al., 2021]; VPW biases samples through Voronoi partitions, demonstrating that AGMCTS can benefit from different action proposal mechanisms.
5 Experiments
We evaluate AGMCTS on continuous MDP/POMDP benchmarks. MDP baselines are DPW/VPW; POMDP baselines are PFT-DPW/PFT-VPW and POMCPOW/VOMCPOW from POMDPs.jl [Egorov et al., 2017]. AGMCTS also uses POMDPs.jl. VPW and result analysis follow the codebase of [Lim et al., 2021]; we give additional hyperparameters, result tables, and implementation details in the Appendix.
5.1 Benchmark Domains
dD-Continuous Light-Dark POMDP. This domain generalizes the Light-Dark POMDP [Platt et al., 2010] to arbitrary dimension d and combines a narrow goal-centered reward peak, a surrounding moat penalty, a non-Gaussian initial belief, and observation noise that changes sharply across the state space. Here S = O = Rd , b0 = Sd-1 0.5 , goal sg = (0d-1, 2.5), beacon sb = (2.5, 0d-1), γ = 0.99, terminal radius Tg = 0.2, and horizon L = 6. Actions lie in B1.5(0d), transitions are s′ ∼ N(s + a, σ2T I) with σT = 0.025, and observations are relative beacon measurements o ∼ N(s - sb, σO(∥s - sb∥)2 I) with σO(x) = min{15, 0.01(x+x8 )}. The reward depends only on the successor state and combines three terms: a sharp positive bump at the goal, a surrounding moat penalty that discourages random wandering near the target, and a small quadratic distance penalty. With ∆g = ∥s′ - sg∥, the constants are Rgoal = 10, Rmoat = 2, and Rdist = 0.02, giving Rgoale- 12 (∆g/(0.5Tg))2 - Rmoate- 12 ((∆g-5Tg)/Tg)2 - Rdist∆2g . Rollouts move toward sg but add N(0, 0.12 I) action noise, providing a noisy goaldirected default policy. We benchmark d = 2, 3, 4.
Two-Agent dD-Continuous Light-Dark POMDP. This variant uses S = O = R2d , and A = B1.5(0d) × B1.5(0d). Each agent has the same transition and individual reward structure, with the positive goal term obtained only when both agents are within Tg. The observation model couples the agents: agent 1 observes its relative beacon position, while agent 2 observes its relative position to agent 1 with the same distance-dependent covariance. Thus agent 2 receives position information through agent 1 rather than directly through the fixed beacon, while the reward grants success jointly. We benchmark d = 2.
Mountain Car and Hill Car MDP/POMDP. These domains are based on Mountain Car [Singh and Sutton, 1996] and Car on the Hill [Ernst et al., 2005]; S = R2 is position and velocity, and A = [-amax, amax] accelerates/brakes the car while avoiding the left boundary. In POMDPs, velocity is unobserved and z ∼ N(x, 0.032 ). These domains have momentum dynamics and threshold termination: the car may move away from the goal to gain speed, while overshooting the safe speed range causes termination. The reward is 100 at x ≥ xmax, -100 at x < xmin or |v| ≥ vmax, and -0.1 otherwise; γ = 0.99. Rollouts use the standard momentum heuristic, pushing with amax when v > 0 and -amax otherwise, which provides a useful but myopic default. Our modified Mountain Car instance uses xmin = -1.5, xmax = 0.5, vmax = 0.05, amax = 1.0, horizon L = 200, v′ =
v + 0.001˜a - 0.0025 cos(3x), and x′ = x + v′ . Hill Car uses horizon L = 30 and integrates nonlinear continuoustime dynamics for ∆t = 0.1, with the same noisy-clamped action interface used for AGMCTS density evaluation.
The two car domains differ in where complexity appears. Mountain Car has a long horizon under a tight velocity bound, so momentum-building policies can terminate by exceeding the speed limit. Hill Car has a shorter horizon, but each transition is obtained by integrating nonlinear continuoustime dynamics. In both domains, additive action-input noise ξ ∼ N(0, 0.12 ) is clamped as ˜a = clip(a + ξ, -amax, amax) before simulation, yielding transition distributions with continuous interior components and discrete clipping masses.
Lunar Lander MDP/POMDP. We use Lunar Lander as in [Mern et al., 2021; Lim et al., 2021], with state (x, y, θ, ˙x, ˙y, ω) and action (Fx, T, δ) ∈ [0, 15] × [-5, 5] × [-1, 1]. Actions couple translation, orientation, and angular rate through the thrust direction and torque, and rewards combine threshold penalties with a landing reward. Here T is main thrust, Fx corrective thrust, and δ the offset producing torque τ = -δFx. With m = 1, I = 10, and ∆t = 0.4, the deterministic model computes fx = cos θFx - sinθT, fy = cos θT +sinθFx, ˙x′ = ˙x+fx∆t, ˙y′ = ˙y+(fy-9)∆t, ω′ = ω + τ∆t/I, x′ = x + ˙x∆t, y′ = y + ˙y∆t, and θ′ = θ + ω∆t. Gaussian output noise with scales (0.1, 0.1, 0.01) is added to ˙x′ , ˙y′ , and ω′ , so transition densities are computed by solving for the output-noise variables under the Area Formula. In the POMDP variant, o = (˜ω, ˜˙x, ˜h) with noise scales (1.0, 0.01, 0.1) and ˜h centered at y/ cos θ. Rewards are -1000 if x ≥ 15 or θ ≥ 0.5, 100 - x - ˙y2 if y ≤ 1, and -1 otherwise. We use γ = 0.99 and horizon L = 35. The state distribution is a Gaussian with mean (0, 50, 0, 0, -10, 0), and the rollout is a proportional stabilizer (-0.1 ˙x,-0.1 ˙y, 0) under noisy partial observations.
| Domain | Setting | DPW | VPW | AG-DPW | AG-VPW |
|---|---|---|---|---|---|
| 2D Light-Dark | POMDP | .027 | .027 | .316 | .191 |
| 3D Light-Dark | POMDP | .068 | .073 | .315 | .154 |
| 4D Light-Dark | POMDP | .151 | .155 | .302 | .318 |
| 2-2D Light-Dark | POMDP | .160 | .173 | .447 | .464 |
| Mountain Car | MDP | .016 | .016 | .148 | .152 |
| POMDP | .042 | .044 | .928 | .904 | |
| Hill Car | MDP | .026 | .029 | .744 | 1.028 |
| POMDP | .360 | .347 | 1.636 | 1.109 | |
| Lunar Lander | MDP | .008 | .009 | .203 | .216 |
| POMDP | .103 | .102 | .504 | .508 |
| POMDP domain | POMCPOW | VOMCPOW |
| 2D Light-Dark | .033 | .033 |
|---|---|---|
| 3D Light-Dark | .060 | .063 |
| 4D Light-Dark | .141 | .170 |
| 2-2D Light-Dark | .141 | .169 |
| Mountain Car | .116 | .134 |
| Hill Car | .348 | .297 |
| Lunar Lander | .136 | .144 |
5.2 Performance Evaluation
We tune hyperparameters with cross-entropy maximization at the maximum simulation budget. This includes UCT/DPW parameters, and Adam step size for AG variants, while other AG settings are manual. VPW Voronoi parameters use reasonable values from [Lim et al., 2021]. The CE procedure runs 50 iterations; each iteration samples 150 parameter settings, evaluates each on 40 seeds, and refits a smoothed Gaussian proposal from the 30 elite settings. All reported means use 1000 shared seeds. Maximum planning budgets are 500 simulations for Light-Dark and Car domains and 1000 for Lunar Lander. These simulation-budget comparisons intentionally hold the number of model queries fixed, giving a clearer test of whether action-gradient refinement improves the same underlying tree-search procedures rather than conflating this effect with implementation-dependent wall-clock costs. For wall-clock matching, POMCPOW receives a larger state-trajectory budget matched to PFT-DPW runtime.
Transition-density computations match the domain structure: closed-form Gaussian densities in Light-Dark, clipped input-noise inversion in Car domains, and output-noise inversion in Lunar Lander. AG variants use Kopt ∈ {2, 3} Adam updates with linearized importance-weight updates (14).
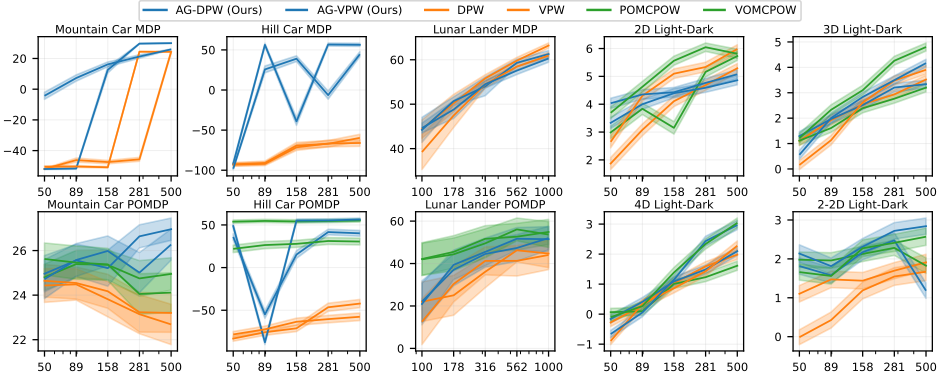
Figure 2 shows mean performance per planning budget. At maximum budget, an AG variant was preferable to its matched non-AG DPW/VPW-family baseline in 6/10 scenarios (all Hill/Mountain Car, 4D and 2x2D Light-Dark). Against matched baselines (AG-DPW vs. DPW, AG-VPW vs. VPW, and the corresponding PFT variants), AG improved significantly in 10/20 cases, was insignificant in 7/20, and underperformed in 3/20.
By best algorithm per scenario, AGMCTS led in Mountain/Hill Car MDPs, was best or statistically tied in 5/7 POMDPs, and underperformed in 2/7. Overall, it was competitive with the wall-clock-matched POMCPOW/VOMCPOW baselines and often improved over PFTDPW/PFT-VPW. The largest gains appear in the Mountain/Hill Car domains, while Light-Dark and Lunar Lander show more mixed outcomes. The results suggest that AGMCTS is effective in domains where small action changes can lead to large changes in states and rewards, as in the very long-horizon Mountain Car or very narrow goal in the LightDark POMDPs. The performance difference in Lunar Lander is mostly insignificant, which may be due to the combination of large action dimensionality and sparse rewards, reducing gradient signal quality.
On the other hand, AG variants were 10-35× slower than DPW/VPW in MDPs and 2-20× slower than PFTDPW/VPW in POMDPs, as shown in Table 1. AG variants have higher per-simulation cost because action updates revise successor weights and evaluate transition-density terms; these single-threaded timings therefore report implementation cost rather than a wall-clock optimum, since particle-belief updates in AGMCTS and PFT-DPW can be parallelized over particles. Thus, the practical trade-off is whether improved action quality per model query offsets this density and gradient overhead within an application-relevant latency budget.
6 Conclusions
We introduced action-gradient continuous-POMDP tree search with MIS-consistent action-branch updates. Using the Area Formula to obtain transition log-probabilities, AGMCTS improved several continuous MDP/POMDP benchmarks and was competitive overall, showing that online gradient refinement can strengthen MCTS. Future work includes convergence analysis and faster, less tuning-sensitive general planning algorithms.
Practical Considerations. AGMCTS requires transitiondensity access and tuning in addition to the per-simulation overhead. These costs should be weighed against application latency and modeling constraints.
Acknowledgments
This work was supported by the Israel Ministry of Innovation, Science and Technology.
@inproceedings{ijcai2026p498,
  title     = {Action-Gradient Monte Carlo Tree Search for Non-Parametric Continuous (PO)MDPs},
  author    = {Lev-Yehudi, Idan and Novitsky, Michael and Barenboim, Moran and Benchetrit, Ron and Indelman, Vadim},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {4474--4482},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/498},
  url       = {https://doi.org/10.24963/ijcai.2026/498},
}
TY - CPAPER TI - Action-Gradient Monte Carlo Tree Search for Non-Parametric Continuous (PO)MDPs AU - Lev-Yehudi, Idan AU - Novitsky, Michael AU - Barenboim, Moran AU - Benchetrit, Ron AU - Indelman, Vadim T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 4474 EP - 4482 DO - 10.24963/ijcai.2026/498 UR - https://doi.org/10.24963/ijcai.2026/498 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





