
Computing Coverage-Based Prime Implicant Explanations for Tree-Based Models
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 4143-4151.
https://doi.org/10.24963/ijcai.2026/461
Keywords
- Machine Learning: Classification
- Machine Learning: Explainable/Interpretable machine learning
Abstract
Coverage-based prime implicant explanations are formal explanations offering a number of valuable assets, especially in terms of faithfulness and generality. Unfortunately, deriving a coverage-based prime implicant explanation for an instance is computationally hard in the general case (the problem of identifying such an explanation being at the second level of the polynomial hierarchy).
In this paper, we focus on the computation of a coverage-based prime implicant explanation for an instance given a tree-based model. We show that the specific nature of the domain theory linking the Boolean conditions in such models makes the problem computationally easier. We present a greedy algorithm to derive coverage-based prime implicant explanations when dealing with a tree-based model. We also present an empirical evaluation showing that this algorithm is efficient enough to be used in many practical cases.
- [Achterberg, 2009] Tobias Achterberg. Scip: solving con- straint integer programs. Mathematical Programming Computation, 1(1):1-41, 2009.
- [Arrieta et al., 2020] Alejandro Barredo Arrieta, Natalia Díaz-Rodríguez, Javier Del Ser, Adrien Bennetot, Siham Tabik, Alberto Barbado, Salvador García, Sergio Gil- López, Daniel Molina, Richard Benjamins, Raja Chatila, and Francisco Herrera. Explainable artificial intelligence (XAI): concepts, taxonomies, opportunities and chal- lenges toward responsible AI. Information Fusion, 58:82- 115, 2020.
- [Audemard et al., 2013] Gilles Audemard, Jean-Marie Lagniez, and Laurent Simon. Improving glucose for incremental SAT solving with assumptions: Application to MUS extraction. In Proceedings of SAT'13, pages 309-317, 2013.
- [Audemard et al., 2022] Gilles Audemard, Steve Bellart, Louenas Bounia, Frédéric Koriche, Jean-Marie Lagniez, and Pierre Marquis. Trading complexity for sparsity in random forest explanations. In Proceedings of AAAI'22, pages 5461-5469, 2022.
- [Audemard et al., 2023] Gilles Audemard, Jean-Marie Lagniez, Pierre Marquis, and Nicolas Szczepanski. Computing abductive explanations for boosted trees. In Proceedings of AISTATS'23, pages 4699-4711, 2023.
- [Audemard et al., 2024] Gilles Audemard, Jean-Marie Lagniez, Pierre Marquis, and Nicolas Szczepanski. Deriv- ing provably correct explanations for decision trees: The impact of domain theories. In Proceedings of IJCAI'24, pages 3688-3696, 2024. IJCAI
- [Audemard et al., 2026] Gilles Audemard, Sylvie Coste-Marquis, Pierre Marquis, Mehdi Sabiri, and Nicolas Szczepanski. Computing coverage-based prime implicant explanations for tree-based mod- els. https://archive.softwareheritage.org/swh:1:dir: 46ffd51e87f2b334be056aaeed27eef32a0e281a, 2026. Link
- [Bodria et al., 2023] Francesco Bodria, Fosca Giannotti, Riccardo Guidotti, Francesca Naretto, Dino Pedreschi, and Salvatore Rinzivillo. Benchmarking and survey of expla- nation methods for black box models. Data Mining and Knowledge Discovery, 37(5):1719-1778, 2023.
- [Breiman et al., 1984] Leo Breiman, Jerome Friedman, R.A. Olshen, and Charles J. Stone. Classification and Regres- sion Trees. Wadsworth, 1984.
- [Breiman, 2001] Leo Breiman. Random forests. Machine Learning, 45(1):5-32, 2001.
- [Chen and Guestrin, 2016] Tianqi Chen and Carlos Guestrin. XGBoost: A scalable tree boosting system. In Proceedings of KDD'16, page 785-794, 2016.
- [Cooper and Amgoud, 2023] Martin C. Cooper and Leila Amgoud. Abductive explanations of classifiers under con- straints: Complexity and properties. In Proceedings of ECAI'23, pages 469-476, 2023.
- [Cooper and Amgoud, 2024] Martin C. Cooper and Leila Amgoud. Abductive explanations of classifiers un- der constraints: Complexity and properties. CoRR, abs/2409.12154, 2024.
- [Cooper and Marques-Silva, 2023] Martin C. Cooper and Joao Marques-Silva. Tractability of explaining classifier decisions. Artificial Intelligence, 316:103841, 2023.
- [Cui et al., 2015] Zhicheng Cui, Wenlin Chen, Yujie He, and Yixin Chen. Optimal action extraction for random forests and boosted trees. In Proceedings of KDD'15, pages 179- 188, 2015.
- [Freund and Schapire, 1997] Yoav Freund and Robert E. Schapire. A decision-theoretic generalization of on-line learning and an application to boosting. Journal of Com- puter and System Sciences, 55(1):119-139, 1997.
- [Friedman, 2001] Jerome H. Friedman. Greedy function ap- proximation: A gradient boosted machine. The Annals of Statistics, 29(5):1189-1232, 2001.
- [Guidotti et al., 2019] Riccardo Guidotti, Anna Monreale, Salvatore Ruggieri, Franco Turini, Fosca Giannotti, and Dino Pedreschi. A survey of methods for explaining black box models. ACM Computing Surveys, 51(5):93:1-93:42, 2019.
- [Gunning, 2019] David Gunning. DARPA's explainable ar- tificial intelligence (XAI) program. In Proceedings of IUI'19, 2019.
- [Hsieh et al., 2024] Weiche Hsieh, Ziqian Bi andChuanqi Jiang, Junyu Liu, Benji Peng, Sen Zhang, Xuanhe Pan, Ji- awei Xu, Jinlang Wang, Keyu Chen, Pohsun Feng, Yizhu Wen, Xinyuan Song, Tianyang Wang andMing Liu, Jun- jie Yang, Ming Li, Bowen Jing, Jintao Ren, Junhao Song, Hong-Ming Tseng, Yichao Zhang, Lawrence K.Q. Yan, Qian Niu, Silin Chen, Yunze Wang, and Chia Xin Liang. A comprehensive guide to explainable AI: From classical models to LLMs. CoRR, abs/2412.00800, 2024.
- [Ignatiev et al., 2019] Alexey Ignatiev, Nina Narodytska, and Joao Marques-Silva. On validating, repairing and re- fining heuristic ML explanations. CoRR, abs/1907.02509, 2019.
- [Ignatiev et al., 2020] Alexey Ignatiev, Nina Narodytska, Nicholas Asher, and Joao Marques-Silva. On relat- ing 'why?' and 'why not?' explanations. CoRR, abs/2012.11067, 2020.
- [Ignatiev et al., 2022] Alexey Ignatiev, Yacine Izza, Peter J. Stuckey, and Joao Marques-Silva. Using MaxSAT for ef- ficient explanations of tree ensembles. In Proceedings of AAAI'22, pages 3776-3785, 2022.
- [Miller, 2019] Tim Miller. Explanation in artificial intelli- gence: Insights from the social sciences. Artificial Intelli- gence, 267:1-38, 2019.
- [Molnar, 2019] Christoph Molnar. Interpretable Machine Learning -A Guide for Making Black Box Models Explain- able. Leanpub, 2019.
- [Nauta et al., 2023] Meike Nauta, Jan Trienes, Shreyasi Pathak, Elisa Nguyen, Michelle Peters, Yasmin Schmitt, Jörg Schlötterer, Maurice van Keulen, and Christin Seifert. From anecdotal evidence to quantitative evaluation meth- ods: A systematic review on evaluating explainable AI. ACM Computing Surveys, 55(13s), 2023.
- [Parmentier and Vidal, 2021] Axel Parmentier and Thibaut Vidal. Optimal counterfactual explanations in tree ensem- bles. In Proceedings of ICML'21, volume 139, 2021.
- [Pedregosa et al., 2011] Fabian Pedregosa, Gaël Varoquaux, Alexandre Gramfort, Vincent Michel, Bertrand Thirion, Olivier Grisel, Mathieu Blondel, Peter Prettenhofer, Ron Weiss, Vincent Dubourg, Jake Vanderplas, Alexandre Pas- sos, David Cournapeau, Matthieu Brucher, Matthieu Per- rot, and Édouard Duchesnay. Scikit-learn: Machine learn- ing in Python. Journal of Machine Learning Research, 12:2825-2830, 2011.
- [Quinlan, 1986] J. R. Quinlan. Induction of decision trees. Machine Learning, 1(1):81-106, 1986.
- [Schapire and Freund, 2014] Robert E. Schapire and Yoav Freund. Boosting: Foundations and Algorithms. MIT Press, 2014.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
During the last decade, the rise of ML-driven AI techniques has led to outstanding advancements across numerous fields. However, the most accurate ML models are black boxes: their decision-making processes are opaque [Molnar, 2019]. To deal with the demand for more transparency in AI systems, eXplainable AI (XAI) methods have been developed in recent years [Gunning, 2019]. In particular, many notions of explanations suited to various ML models and inputs (tabular data, images, texts, etc.) have been pointed out so far (see [Hsieh et al., 2024; Bodria et al., 2023; Arrieta et al., 2020; Guidotti et al., 2019; Molnar, 2019] for surveys).
In the following, we focus on coverage-based prime implicant explanations [Cooper and Amgoud, 2024; Cooper and Amgoud, 2023] in the specific case of tree-based models f used for binary classification. Coverage-based prime implicant explanations are abductive explanations that are local and post-hoc explanations. As such, they are about the prediction made by an already trained ML model f for a given input instance x. They aim to answer the "why?" question [Miller, 2019; Ignatiev et al., 2020] by identifying a subset t of the characteristics of x such that every instance sharing those characteristics is ensured to be classified by the ML model f in the same way as x.
While no consensus exists about what a "good" explanation should be [Miller, 2019; Molnar, 2019], many criteria can be considered for evaluating the quality of an explanation (see e.g., [Nauta et al., 2023]). Coverage-based prime implicant explanations [Cooper and Amgoud, 2024; Cooper and Amgoud, 2023] are faithful explanations that take advantage of a domain theory Σf not only for ensuring that explanations comply with it, but also for the sake of generality: only explanations that are as general as possible given Σf , i.e., that are implied by other explanations when Σf is assumed, are selected. [Cooper and Amgoud, 2024; Cooper and Amgoud, 2023] have shown that ignoring some consequences of Σf (especially, dependency constraints among features) may lead to the generation of superfluous abductive explanations and to exponentially many redundant abductive explanations. Coverage-based prime implicant explanations do not suffer from these impediments.
However, there is a price to be paid, and this price is computational: though deciding whether a given term is an abductive explanation is coNP-complete [Cooper and MarquesSilva, 2023] in general, deciding whether it is a coveragebased prime implicant explanation is Πp2 -complete in general [Cooper and Amgoud, 2024; Cooper and Amgoud, 2023]. While an algorithm for computing a coverage-based prime implicant explanation for a given instance has been presented in the appendix of [Cooper and Amgoud, 2024], as far as we know, this algorithm has not been implemented so far. As a consequence, given the high complexity of the problem, the question of the practical efficiency of the computation of such explanations remains open.
In this paper, we present a greedy algorithm for computing coverage-based prime implicant explanations when dealing with a tree-based model f (a decision tree [Breiman et al., 1984], a random forest [Breiman, 2001] or a boosted tree [Freund and Schapire, 1997]). We show that the specific nature of the domain theory linking the Boolean conditions in such models makes the problem computationally easier (only polynomially many calls to an NP oracle are needed). We also present an empirical evaluation of this algorithm and a comparison with our implementation of the algorithm given in [Cooper and Amgoud, 2024]. This evaluation shows that the computation of coverage-based prime implicant explanations for tree-based models is practical enough to deal with "mildly complex" tree-based models (i.e., based on hundreds of Boolean conditions). As expected, experiments also show that our algorithm is much more efficient than the generalpurpose algorithm for coverage-based prime implicant explanations presented in [Cooper and Amgoud, 2024] when applied to such tree-based models.
The rest of the paper is organized as follows. Formal preliminaries are given in Section 2. Our algorithm for computing coverage-based prime implicant explanations for treebased models is presented in Section 3. Experiments are reported in Section 4. The proofs of the results presented in the paper, as well as additional empirical results and the code used in our experiments are furnished as a supplementary material available from [Audemard et al., 2026].
2 Formal Preliminaries
Classification and tree-based models. Let A = {A1, . . . , An} be a finite set of attributes, where each attribute is Boolean, categorical, or numerical. An instance x over A is a vector from D1 × . . . × Dn. Its set of characteristics indicates for each Ai ∈ A the value x takes in Di. X is the set of all instances. A classifier f over A is a mapping from X to a finite set L of classes. A binary classifier f over A is a mapping from X to L = {0, 1}. An instance x ∈ X is positive when f(x) = 1 and it is negative when f(x) = 0.
A decision tree (resp. regression tree) over A [Breiman et al., 1984; Quinlan, 1986] is a binary tree T , each of whose internal nodes (aka decision nodes) is labelled with a Boolean condition over Ai ∈ A, and each leaf is labelled by an element of L (resp. a decimal floating-point number).
Decision trees (DTs), sets of decision trees (alias random forests (RFs)), and sets of regression trees (alias boosted trees (BTs)) can be used for solving binary classification problems.
The value T(x) of T on an input instance x ∈ X is given by the label of the leaf reached from the root. When T is a decision tree, this value is 1 when the leaf reached is a 1-leaf (i.e., a leaf labelled by 1) and it is 0 when the leaf reached is a 0-leaf (i.e., a leaf labelled by 0). The unique path characterising the leaf that is met is defined as follows: at each decision node go to the left (resp. right) child if the Boolean condition labelling the node is evaluated to 0 (resp. 1) for x.
A random forest over A [Breiman, 2001] is an ensemble RF = {T1, · · · , Tm}, where each Ti (i ∈ [m]) is a decision tree over A, and such that the value RF(x) is given by
A boosted tree over A [Freund and Schapire, 1997; Friedman, 2001; Schapire and Freund, 2014] is an ensemble BT = {T1, · · · , Tm}, where each Ti (i ∈ [m]) is a regression tree over A, and such that the value BT(x) is given by
Let B = {B1, . . . ,Bm} be the set of Boolean conditions occurring in a tree-based model f (a decision tree, a random forest or a boosted tree over A). Those conditions can also be viewed as Boolean attributes. Therefore f can also be considered as a Boolean function over B. The Boolean attributes in B are not always pairwise independent because several conditions can be generated from a single numerical or categorical attribute from A. A domain theory Σf is a propositional formula over B indicating how the corresponding attributes occurring in f are logically connected. Accordingly, beyond X, another set of instances can be considered given f: the subset XB of {0, 1}m containing Boolean vectors that correspond to the truth assignments over B satisfying Σ. Every instance x ∈ X corresponds to a unique instance xB ∈ XB and this instance xB is such that f(xB) = f(x). Unlike X that is (in general) infinite, XB is a finite set.
Considering instances over Boolean attributes B = {B1, . . . , Bm} that are connected by a domain theory Σf , treebased models f can thus be viewed as Boolean functions mapping the truth assignments x fromXB, i.e., the truth assignments over B that satisfy Σ (aka the models of Σ), to a Boolean value that is 1 when x is a positive instance and 0 when it is a negative instance. Furthermore, every instance x = (x1, . . . , xm) from XB can be viewed and be represented as a canonical term tx (i.e., a conjunctively-interpreted set of literals over B in which every variable occurs once) such that tx = ∧mi=1 x∗i where x∗i = xi (i ∈ [m]) when the ith coordinate of x is 1 and x∗i = xi when the ith coordinate of x is 0.
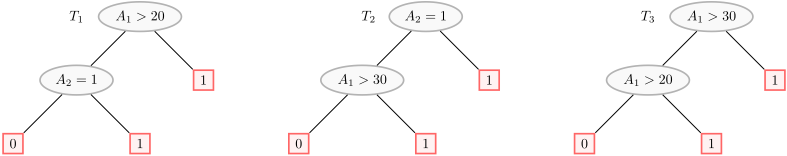
Example 1. As a matter of illustration, Figure 1 presents a very simple random forest RF = {T1, T2, T3} over A = {A1, A2}, where A1 is a numerical attribute (say, the annual income in $k of a loan applicant) and A2 is a Boolean attribute (indicating whether the applicant holds a permanent position). The instance x = (33, 1) from X is such that T (x) = 1.
contains three Boolean conditions. The two conditions B1 = (A1 > 20) and B2 = (A1 > 30) about A1 are obviously not independent: they are logically connected by a domain theory Σf equivalent to B2 ⇒ B1. x = (23, 1) (and more generally, every instance from X for which B1, B2, and B3 hold) corresponds to the instance xB = (1, 1, 1) from XB. It is easy to check that f is equivalent to the CNF formula B1 ∨ B2 ∨ B3.
Abductive explanations. Abductive explanations are local explanations that aim to explain why the instance at hand has been classified as such by the ML model f. Formally, an abductive explanation for x ∈ XB given f is a subset t of tx such that every instance x′ ∈ XB such that t ⊆ tx′ satisfies f(x′ ) = f(x). Such explanations t offer correctness guarantees in the sense that any instance x′ covered by t is ensured to be classified by f in the same way as x.
Let Σf , α, β be three formulae over B. We note α |=Σf β precisely when Σf ∧ α |= β and α ≡Σf β precisely when α |=Σf β and β |=Σf α. When α |=Σf β holds, we say that β is at least as general as α modulo Σf . When α ≡Σf β holds, α and β are equivalent modulo Σf .
To clarify the landscape of abductive explanations, Table 1 summarizes the hierarchy of the core concepts used in this paper. Starting from base explanations (wAXp), domain constraints are added (wAXpc), minimality is enforced (AXp/AXpc), and finally, coverage is maximized modulo the domain theory Σf (CPI-Xp/mCPI-Xp).
Definition 1. Let f be a Boolean function over a set B of Boolean conditions, x an instance from XB. Let f ∗ = f if f(x) = 1 and f ∗ = ¬f if f(x) = 0. Let t be a term over B:
- t is an abductive explanation (wAXp) for x given f iff t ⊆ tx and t |= f ∗ ;
- t is a subset-minimal abductive explanation (AXp) for x given f iff t is an abductive explanation for x given f and no proper subset of t is an abductive explanation for x given f ;
- Let Σf be a formula over B (a domain theory, representing constraints over the Boolean conditions occurring in f) such that tx |= Σf holds:
- t is an abductive explanation (wAXpc) for x given f and Σf iff t ⊆ tx and t |=Σf f ∗ ;
- t is a subset-minimal abductive explanation (AXpc) for x given f and Σf iff t is an abductive explanation for x given f and Σf and no proper subset of t is an abductive explanation for x given f and Σf ;
- t is a coverage-based prime implicant explanation (CPI-Xp) for x given f and Σf iff t ⊆ tx, t |=Σf f ∗ and if there exists t′ ⊆ tx such that t′ |=Σf f ∗ and t |=Σf t′ , then t ≡Σf t′ ;
- t is a minimal coverage-based prime implicant explanation (mCPI-Xp) for x given f and Σf iff t is a coverage-based prime implicant explanation for x given f and Σf and no proper subset of t is a coverage-based prime implicant explanation for x given f and Σf .
| Acronym | Concept Definition |
|---|---|
| wAXp | Abductive explanation (implicant) |
| AXp | Subset-minimal abductive explanation (prime implicant) |
| wAXpc | Abductive explanation modulo Σf |
| AXpc | Subset-minimal abductive explanation modulo Σf |
| CPI-Xp | Coverage-based prime implicant expl. (modulo Σf ) |
| mCPI-Xp | Minimal coverage-based prime implicant expl. |
Example 2 (Example 1 cont'ed). Let us recall that B = {B1, B2, B3}, f ≡ B1 ∨ B2 ∨ B3 and that Σf = B2 ⇒ B1.
- Consider first the instance x = (1, 1, 1). We have f (x) = 1. tx = {B1, B2, B3} is a wAXp (and a wAXpc) for x given f, but not an AXp. {B1}, {B2}, and {B3} are the AXps for x given f. They are also the AXpcs for x given f and Σf . Among them {B1} and {B3} are the CPI-Xps and the mCPI-Xps for x given f and Σf .
- Consider now the instance x′ = (0, 0, 0). We have f(x′ ) = 0. tx′ = {B1,B2,B3} is the unique AXp for x′ given f, but it is not an AXpc for x′ given f and Σf . {B1,B3} is the unique AXpc for x′ given f and Σf . It is also the unique CPI-Xp and mCPI-Xp for x′ given f and Σf .
mCPI-Xps of minimal size can be arbitrarily larger than AXps (or AXpcs) of minimal size. Unlike what happens with AXps, the generality criterion may conflict with the interpretability one. Indeed, minimal-size wAXps are AXps, thus are as general as possible while being more interpretable than other wAXps. Contrastingly, CPI-Xps (and even mCPI-Xps) are (by definition) more general than other wAXps but they can be less interpretable (they may contain many more characteristics).
3 Computing CPI-Xps
In order to derive CPI-Xps suited to tree-based models, we present a greedy algorithm CPI-Xp-TBM (see Algorithm 1). This algorithm leverages the specific nature of the domain theory Σf linking the Boolean conditions in tree-based models to make the search for CPI-Xps more efficient.
CPI-Xp-TBM takes as input an instance x ∈ XB. The goal is to explain the classification of x achieved by the binary classifier f over B. Here f is a tree-based model (a decision tree, a random forest, or a boosted tree). Another part of the input is the domain theory Σf associated with f:
is the conjunction of the domain theories ΣfAi associated with the primitive attributes from A. Each ΣfAi (Ai ∈ A) is defined as follows. When Ai is a numerical attribute such that the set of conditions about Ai occurring in f is {Ai > v1 i , . . . ,Ai > vc(i) i } where vc(i) i > . . . > v1 i (i.e., there are c(i) thresholds considered for Ai), ΣfAi is given by the following CNF formula based on the Boolean variables B1 i , . . . ,Bc(i) i from B, where each Bj i (j ∈ [c(i)]) stands for Ai > vj i :
When Ai is a categorical attribute such that the set of conditions about Ai occurring in f is {Ai = v1 i , . . . ,Ai = vc(i) i }, ΣfAi is given by the following CNF formula based on the Boolean variables B1 i , . . . ,Bc(i) i from B, where each Bj i (j ∈ [c(i)]) stands for Ai = vj i :
Thus, when Ai is a numerical attribute, ΣfAi is a chain of implications that simply reflects the linear ordering over the threshold values vj i for Ai that have been found by the learning algorithm used to generate f. When Ai is a categorical attribute, ΣfAi is a mutual exclusion constraint that states that the values found for Ai by the learning algorithm used to generate f are mutually exclusive. Accordingly, the (running) domain of each categorical attribute Ai is considered as open: it is not assumed that the sole possible values for Ai are in {v1 i , . . . , vc(i) i } (v1 i , . . . , vc(i) i are those values found when f was learned but this does not preclude the existence of other possible values for Ai, especially because such values do not necessarily occur in the training set used to learn f). Finally, the Boolean attributes Ai from A do not give rise to any specific domain theory: ΣfAi is the empty CNF formula, represented by the Boolean constant always true ⊤.
It can be easily checked that the domain theory Σf associated with a tree-based model f is decomposable: whenever Ai and Aj are two distinct attributes from A, then {B1 i , . . . ,Bc(i) i } ∩ {B1 j , . . . , Bc(j) j } = ∅.
In order to compute a CPI-Xp for x ∈ XB given f and Σf , a space of explanation candidates is explored:
Definition 2. An explanation candidate t for x ∈ XB is a subset of literals from tx.
Given that x satisfies Σf , every explanation candidate t for x is consistent with Σf .
Explanation candidates (when viewed up to equivalence modulo Σf ) are ordered by the generality relation |=Σ that is a (partial) ordering, i.e., a reflexive, transitive, and antisymmetric relation. If t and t′ are two explanation candidates for x ordered by the strict part of this ordering, i.e., such that t |=Σf t′ and t′ ̸|=Σf t hold, we say that t′ is a (strict) generalisation of t given Σf .
When looking for a CPI-Xp for x given f and Σf , the exploration of the space of explanation candidates can be guided by |=Σf . To define the exploration strategy, the following notion of Ai-part of an explanation candidate will be useful:
Definition 3. The Ai-part of an explanation candidate t for x ∈ XB is the subset tAi of literals ℓ from t that are about Ai ∈ A, i.e., the variable of ℓ corresponds to a condition Ai > vj i or Ai = vj i (j ∈ [c(i)]).
Algorithm 1 CPI-Xp-TBM
Require: x an instance fromXB satisfying Σ, f a tree-based classifier over B, Σf a formula over B (the corresponding domain theory).
Ensure: a CPI-Xp cx for x given f and Σf .
1: f ∗ ← (f(x) = 1) ? f : f 2: t ← tx 3: cx ← ∅ 4: for each Ai ∈ A do 5: t′ ← tAi 6: while true do 7: if t′ = ∅ then 8: exit-while 9: else 10: found ← false 11: gs ← msg(t′ , Σf ) 12: for each g ∈ gs do 13: gs ← gs \ {g} 14: if imp(cx ∪ g ∪ ⋃j>i tAj , f ∗ , Σf ) then 15: t′ ← g 16: found ← true 17: exit-for 18: if notfound then 19: cx ← cx ∪ t′ 20: exit-while 21: return cxBecause the domain theories ΣfAi (Ai ∈ A) are based on Boolean variables that are pairwise disjoint, it is easy to show that the generality relation |=Σf over explanation candidates can be decomposed over the primitive attributes:
Proposition 1. Let t, t′ be two explanation candidates for x ∈XB. We have t |=Σf t′ if and only if ∀Ai ∈ A, tAi |=Σf t′Ai if and only if ∀Ai ∈ A, tAi |=ΣfAi t′Ai .
CPI-Xp-TBM is an iterative algorithm: each primitive attribute Ai from A is considered in sequence, and the Ai-part of the explanation candidate tx is generalised as much as possible in a greedy fashion, i.e., while the resulting explanation is a wAXpc for x given f and Σf .
CPI-Xp-TBM takes advantage of two main functions: msg and imp. imp is used to achieve implicant tests and the goal of msg is to guide the search for a CPI-Xp for x given f and Σf by deriving at each step the most specific generalisations of the current explanation candidate:
Definition 4. Given Σf , a most specific generalisation of an explanation candidate t for x is an explanation candidate t′ for x such that t |=Σf t′ , t′ ̸|=Σf t and for every explanation candidate t′′ for x such that t |=Σf t′′ and t′′ ̸|=Σf t, if t′′ |=Σf t′ , then t′ |=Σf t′′ .
In the set msg(t,Σf ) of the most specific generalisations of t given Σf , only one representative per equivalence class modulo Σf must be kept. This set is empty precisely when t = ∅ because of the specific nature of Σf when f is a tree ensemble.
Due to the decomposability of Σf , a most specific generalisation msg(t, Σf ) of an explanation candidate can be characterised by computing a most specific generalisation of one of its parts:
Proposition 2. Let Ai ∈ A be such that ∃t′Ai ∈ msg(tAi , Σf ). Then ⋃Aj∈A|j̸=i tAj ∪ t′Ai is a most specific generalisation of the explanation candidate t for x given Σf .
The decomposability of Σf and the specific nature of each ΣfAi (Ai ∈ A) ensures that msg(tAi ,Σf ) can be computed in time polynomial in the size of tAi plus the size of ΣfAi :
Proposition 3. Let t be an explanation candidate for x ∈ XB and let Ai ∈ A.
- When Ai is numerical, ΣfAi = ∧c(i) j=2 (¬Bj i ∨Bj-1 i ) has the form of a chain of implications. Let M = max ({j ∈ [c(i)] | Bj i ∈ t}) if tAi contains a positive literal and let m = min({j ∈ [c(i)] | Bj i ∈ t}) if tAi contains a negative literal. Let G+ = {BM-1 i } if M ̸= 1 and G+ = ∅ if M = 1, and let G- = {Bm+1 i } if m ̸= c(i) and G- = ∅ if m = c(i).
- If tAi contains a positive literal and a negative literal, then msg(tAi ,Σf ) = {(tAi \ {BM i }) ∪ G+, (tAi \ {Bm i }) ∪G-}.
- If tAi contains a positive literal and no negative literals, then msg(tAi ,Σf ) = {(tAi \ {BM i }) ∪ G+}.
- If tAi contains no positive literals and a negative literal, then msg(tAi ,Σf ) = {(tAi \ {Bm i }) ∪ G-}.
- When Ai is categorical, ΣfAi = ∧j,k∈[c(i)]|j̸=k (¬Bj i ∨ ¬Bk i ) has the form of a mutual exclusion constraint.
- If tAi contains a positive literal Bj i , then msg(tAi , Σf ) = {{Bk i | k ∈ [c(i)] \ {j}}}.
- If tAi does not contain any positive literal then msg(tAi , Σf ) = {tAi \ {Bj i } | Bj i ∈ tAi }.
A second important component of CPI-Xp-TBM is the implicant test imp. Indeed, when such a test fails, i.e., when an explanation candidate t is not an abductive explanation for x given f and Σf , it is useless to consider any explanation candidate that generalises t.
Deciding whether an explanation candidate t is an abductive explanation (i.e., determining whether t is an implicant of f ∗ modulo Σf ) amounts to testing the inconsistency of Σf ∧ t ∧ f ∗ . This can be done using various kinds of solvers (for instance, an SMT solver [Ignatiev et al., 2019], a MIP solver [Cui et al., 2015; Parmentier and Vidal, 2021], a SAT solver [Audemard et al., 2022] or a MaxSAT solver [Ignatiev et al., 2022] can be used).
Exploring in a greedy fashion the set of most specific generalisations of the current explanation candidate t (starting with t = tx) until the implicant test fails ensures that no relevant part of the search space is left unexplored for generating a CPI-Xp for x given f and Σf . Algorithm 1 is explained in the following example.
Example 3 (Example 1 cont'ed). Suppose that x = (1, 1, 1). Since f(x) = 1, we have f ∗ = f. At start (line 2), t is equal to {B1 = (A1 > 20),B2 = (A1 > 30),B3 = (A2 = 1)}. Suppose that A2 is processed before A1 in the main for-loop (line 4). One first looks for the most specific generalisations of t′ = tA2 = {B3 = (A2 = 1)} given Σf . Since msg(t′ ,Σf ) = {∅}, there is a single generalisation of t′ to be considered at line 12 (the inner for-loop), namely ∅. Since {B1 = (A1 > 20),B2 = (A1 > 30)} is an implicant of f ∗ modulo Σf , t′ is set to ∅ at line 15. Then one looks for the most specific generalisations of t′ = ∅. Since t′ = ∅, the test at line 7 leads to leave the while-loop. At that stage, cx is still equal to ∅.
Then A1 is processed in the main for-loop. One first looks for the most specific generalisations of t′ = tA1 = {B1 = (A1 > 20),B2 = (A1 > 30)} given Σf . Since msg(t′ ,Σf ) = {{B1 = (A1 > 20)}}, there is a single generalisation of t′ to be considered at line 12 (the inner for-loop), namely {B1 = (A1 > 20)}. Since {B1 = (A1 > 20)} is an implicant of f ∗ modulo Σf , t′ is set to {B1 = (A1 > 20)} at line 15. Then one looks for the most specific generalisations of t′ = {B1 = (A1 > 20)}. Since msg(t′ , Σf ) = {∅}, there is a single generalisation of t′ to be considered at line 12 (the inner for-loop), namely ∅. Since ∅ is not an implicant of f ∗ modulo Σf , found remains false, so that cx is updated to {B1 = (A1 > 20)} (line 19). Finally, since t′ = ∅, the test at line 7 leads to leave the while-loop. At that stage, cx is equal to {B1 = (A1 > 20)}. Since every attribute Ai ∈ A has been processed in the main for loop, cx = {B1 = (A1 > 20)} is returned at line 21.
Proposition 4. CPI-Xp-TBM is correct w.r.t. its specification: it always terminates and returns a CPI-Xp for x given f and Σf .
For each attribute Ai ∈ A, the number of calls to the implicant test imp at line 14 is upper bounded by c(i), thus linear in the number of Boolean conditions in B that are about Ai. Therefore, the total number of calls to the implicant test is linear in the number of Boolean conditions in B. Given that the implicant test can be achieved in time polynomial in |f| + |Σf | when f is a decision tree [Audemard et al., 2024], CPI-Xp-TBM is a polynomial-time algorithm when f is a decision tree. In the case of random forests or boosted trees, the implicant test is coNP-complete, making unlikely the existence of a (deterministic) polynomial-time algorithm for it. Thus, CPI-Xp-TBM does not run in polynomial time when such models are considered as input. However, if one is ready to lose a bit of generality in the explanations in order to ensure a polynomial-time behaviour of CPI-Xp-TBM (thus, to improve its scalability), a way consists in replacing the test imp(cx ∪ g ∪ ⋃j>i tAj , f ∗ , Σf ) by a lower approximation of it that can be evaluated efficiently. Such polynomialtime approximations exist for random forests (resp. boosted trees) leading to the characterisation of abductive explanations called majoritary (resp. tree-specific) explanations (see [Audemard et al., 2022; Audemard et al., 2023] for details). The resulting explanations would not be CPI-Xps in general but the fact that they are abductive (wAXpc) would be guaranteed.
| Dataset | |D| | |A| | |BDT | | |BRF | | |BBT | |
|---|---|---|---|---|---|
| arrowhead 0 vs 1 | 146 | 249 | 11.1 | 880.6 | 90.2 |
| arrowhead 0 vs 2 | 146 | 249 | 6.9 | 595.3 | 68.2 |
| arrowhead 1 vs 2 | 130 | 249 | 9.6 | 789.6 | 83.2 |
| australian | 690 | 38 | 71.8 | 1563.1 | 427.2 |
| balance 0 vs 1 | 625 | 4 | 16.6 | 28.0 | 16.0 |
| balance 0 vs 2 | 337 | 4 | 16.5 | 28.0 | 16.0 |
| balance 1 vs 2 | 576 | 4 | 18.5 | 28.0 | 16.0 |
| bank | 4521 | 48 | 221.4 | 5327.3 | 833.9 |
| biodegradation | 1055 | 41 | 106.7 | 5716.1 | 854.2 |
| breast-tumor | 286 | 37 | 55.8 | 115.5 | 71.5 |
| bupa | 345 | 5 | 43.7 | 420.7 | 150.3 |
| cleveland nominal | 303 | 23 | 40.4 | 576.8 | 187.1 |
| cnae | 1080 | 856 | 15.7 | 554.3 | 24.2 |
| compas | 6172 | 11 | 45.3 | 69.2 | 43.8 |
| contraceptive | 1473 | 21 | 80.2 | 109.5 | 75.4 |
| dexter | 600 | 20000 | 36.3 | 7907.2 | 388.8 |
| divorce | 170 | 54 | 2.8 | 119.3 | 15.2 |
| german | 1000 | 58 | 42.4 | 530.7 | 166.2 |
| melb data 0 vs 1 | 13580 | 61 | 712.0 | 28394.0 | 2172.6 |
| melb data 0 vs 2 | 13580 | 61 | 644.0 | 23285.0 | 2028.4 |
| melb data 1 vs 2 | 13580 | 61 | 581.6 | 24101.6 | 2044.6 |
Our algorithm CPI-Xp-TBM (Algorithm 1) differs from the general-purpose procedure introduced in [Cooper and Amgoud, 2024] in several key aspects. While the latter is designed for any classifier and relies on a counter-example search strategy to iteratively replace weak explanations with strictly more general ones, our approach specifically exploits the structural properties of tree-based models and their associated domain theories. This specialization reduces the computational complexity from Πp2 -completeness in the general case to a problem solvable with only polynomially many calls to an NP oracle when dealing with tree ensembles.
Finally, as this is the case for the CPI-Xps derived using the algorithm presented in [Cooper and Amgoud, 2024], it is easy to show that the CPI-Xps that are generated by Algorithm 1 are not necessarily minimal ones. However, we know that for every CPI-Xp t for x given f and Σf , there exists a mCPI-Xp tmin ⊆ t for x given f and Σf such that tmin ≡Σf t. The point is that tmin can be easily extracted from t using a greedy "deletion-based" algorithm (see [Cooper and Amgoud, 2024] for details).
4 Experiments
Empirical protocol. In our experiments, we considered 21 datasets for binary classification, coming from standard repositories: UCI (https://archive.ics.uci.edu/ml/index.php), openML (https://www.openml.org/), and UCR (https://www. timeseriesclassification.com/). Instances of these datasets are based on primitive attributes of various types (numerical, categorical, Boolean) forming a set A.
Categorical attributes have been one-hot encoded and numerical attributes have been binarized on-the-fly by the learning algorithm used to generate the classifier f, given by a tree-based model f .
Decision trees and random forests f have been learned using the version 1.6.1 of the Scikit-Learn library [Pedregosa et al., 2011]. All hyperparameters are set to their default values. As for decision trees, the Gini impurity is used as the splitting criterion, and no maximum depth is enforced (nodes are expanded until all leaves are pure or contain fewer than 2 samples). Regarding random forests, 100 trees per forest are generated, and the same default node expansion strategy is applied (nodes are expanded until all leaves are pure or until all leaves contain less than min samples split samples, set to 2). Finally, regarding boosted trees, we used the XGBoost implementation (version 1.7.3) [Chen and Guestrin, 2016] with its default configuration: the model consists of 100 boosting rounds, a learning rate of 0.3, and a maximum tree depth of 6. For every dataset, a 10-fold cross validation process has been performed: for each model under consideration, 10 classifiers have been learned from a training set representing a specific subset (picked up uniformly at random) of 9 10 of the total number of instances in the dataset. For each classifier, 10 instances satisfying the corresponding domain theory Σf have been generated, leading to 100 instances per dataset.
| Cooper-Amgoud | CPI-Xp-TBM | |||||
|---|---|---|---|---|---|---|
| Dataset | Time | Std | TO% | Time | Std | TO% |
| arrowhead 0 vs 1 | 0.004 | 0.004 | 0 | 0.007 | 0.006 | 0 |
| arrowhead 0 vs 2 | 0.003 | 0.005 | 0 | 0.005 | 0.006 | 0 |
| arrowhead 1 vs 2 | 0.005 | 0.006 | 0 | 0.010 | 0.008 | 0 |
| australian | 7.541 | 11.774 | 38 | 0.071 | 0.026 | 0 |
| balance 0 vs 1 | 0.496 | 1.674 | 0 | 0.011 | 0.007 | 0 |
| balance 0 vs 2 | 0.100 | 0.082 | 0 | 0.015 | 0.009 | 0 |
| balance 1 vs 2 | 0.109 | 0.092 | 0 | 0.011 | 0.006 | 0 |
| bank | - | - | 100 | 0.909 | 0.326 | 0 |
| biodegradation | 13.565 | 13.393 | 59 | 0.129 | 0.040 | 0 |
| breast-tumor | 5.899 | 7.560 | 87 | 0.055 | 0.020 | 0 |
| bupa | 9.961 | 14.395 | 30 | 0.020 | 0.009 | 0 |
| cleveland nominal | 1.094 | 3.656 | 2 | 0.019 | 0.008 | 0 |
| cnae | 0.008 | 0.006 | 0 | 0.019 | 0.009 | 0 |
| compas | 1.073 | 0.462 | 96 | 0.097 | 0.071 | 0 |
| contraceptive | - | - | 100 | 0.248 | 0.111 | 0 |
| dexter | 0.067 | 0.027 | 0 | 0.540 | 0.161 | 0 |
| divorce | 4.8e-04 | 0.002 | 0 | 0.001 | 0.002 | 0 |
| german | 0.853 | 1.779 | 1 | 0.025 | 0.010 | 0 |
| melb data 0 vs 1 | - | - | 100 | 12.773 | 5.071 | 0 |
| melb data 0 vs 2 | - | - | 100 | 8.835 | 3.438 | 0 |
| melb data 1 vs 2 | - | - | 100 | 7.635 | 2.746 | 0 |
The implicant test imp(cx ∪ g ∪ ⋃j>i tAj , f ∗ , Σf ) is one of the core components of Algorithm 1. In our implementation of imp, we use a SAT encoding when f is a decision tree or a random forest (extra variables that are existentially quantified are used in the latter case) to exploit highly optimized Boolean logic; a MIP encoding (close to those presented in [Cui et al., 2015; Parmentier and Vidal, 2021]) is used when f is a boosted tree to natively and efficiently handle its continuous linear sum constraints (∑i Ti(x) > 0). Based on those encodings, the implicant tests achieved in the experiments are performed, respectively, using the Glucose 3.0 SAT solver [Audemard et al., 2013] and the SCIP solver [Achterberg, 2009] (via the OR-Tools wrapper).
For each classifier f and instance x, the time spent by CPI-Xp-TBM to generate one CPI-Xp for x given f and Σf has been measured. Similar measurements have also been achieved using this time our implementation of the generic algorithm Cooper-Amgoud for deriving CPI-Xps, as presented in [Cooper and Amgoud, 2024]. To make a fair comparison between the two algorithms, the implicant test required by Cooper-Amgoud has been implemented using the same function imp as used in CPI-Xp-TBM. A timeout of 60 seconds has been considered for each computation.
| Cooper-Amgoud | CPI-Xp-TBM | |||||
|---|---|---|---|---|---|---|
| Dataset | Time | Std | TO% | Time | Std | TO% |
| arrowhead 0 vs 1 | - | - | 100 | 0.358 | 0.066 | 0 |
| arrowhead 0 vs 2 | - | - | 100 | 0.229 | 0.030 | 0 |
| arrowhead 1 vs 2 | - | - | 100 | 0.344 | 0.075 | 0 |
| australian | - | - | 100 | 9.322 | 10.520 | 4 |
| balance 0 vs 1 | 0.801 | 1.124 | 3 | 0.126 | 0.044 | 0 |
| balance 0 vs 2 | 0.881 | 1.829 | 0 | 0.067 | 0.029 | 0 |
| balance 1 vs 2 | 0.474 | 0.560 | 0 | 0.069 | 0.026 | 0 |
| bank | - | - | 100 | 22.095 | 15.734 | 19 |
| biodegradation | - | - | 100 | 12.971 | 12.383 | 9 |
| breast-tumor | - | - | 100 | 0.208 | 0.078 | 0 |
| bupa | - | - | 100 | 0.417 | 0.369 | 0 |
| cleveland nominal | - | - | 100 | 0.539 | 0.343 | 0 |
| cnae | 47.111 | 6.233 | 56 | 1.553 | 1.747 | 0 |
| compas | 0.562 | 0.282 | 98 | 0.660 | 0.220 | 0 |
| contraceptive | 0.669 | 0 | 99 | 0.576 | 0.144 | 0 |
| dexter | - | - | 100 | 53.148 | 5.610 | 88 |
| divorce | 12.044 | 16.095 | 28 | 0.053 | 0.020 | 0 |
| german | - | - | 100 | 24.449 | 14.761 | 21 |
| melb data 0 vs 1 | - | - | 100 | 31.444 | 10.406 | 84 |
| melb data 0 vs 2 | - | - | 100 | 40.995 | 12.747 | 98 |
| melb data 1 vs 2 | - | - | 100 | 47.999 | 8.358 | 77 |
Empirical results. Table 2 summarizes the characteristics of the datasets used in our experiments. Column |D| reports the total number of instances, while |A| represents the count of primitive features. |BDT |, |BRF | and |BBT | denote respectively the average number of binary features occurring in the decision trees, random forests and boosted trees that have been generated. In our approach, combinatorial hardness is driven by the number of primitive features and resulting Boolean conditions rather than the number of instances.
Performance comparisons are then detailed in the subsequent tables. Table 3 focuses on DTs, comparing our approach (CPI-Xp-TBM) against the generic algorithm proposed by Cooper and Amgoud. It reports for each dataset the average computation time (Time, in seconds) and the corresponding standard deviation (Std). Only the instances (out of the 100 instances generated for the dataset) for which the approach terminated in due time have been considered in the computation of Time and Std. Table 3 also reports the percentage of instances reaching the 60-second timeout (TO%). Finally, Tables 4 and 5 present similar measurements for RFs and for BTs, respectively.
The results show that for each dataset used in the experiments and each of the three tree-based models under consideration, Cooper-Amgoud never succeeded in solving more instances than CPI-Xp-TBM within 60 seconds. When the computations succeeded, Cooper-Amgoud turned out to be slightly more efficient on average than CPI-Xp-TBM only for a couple of datasets when f is a DT, while CPI-Xp- TBMwas more efficient than Cooper-Amgoud in all the remaining cases when f is an RF or a BT. This comparison highlights the robustness of our approach, particularly in the cases of RFs and BTs where the increased number of implicant tests and the computational cost of those tests cause the generic method to timeout for the majority of datasets and instances tested. Thus, in our experiments, the computation of a CPI-Xp using Cooper-Amgoud succeeded in due time (60 seconds) for 61.29% of the instances tested in the DT case, 19.81% in the RF case, and 29.43% in the BT case. In contrast, CPI-Xp-TBM maintains quite a high efficiency across "mildly more complex" tree-based models (i.e., based on hundreds of Boolean conditions). Consequently, the computation of a CPI-Xp using CPI-Xp-TBM succeeded in due time for 100% of the instances tested in the DT case, 80.95% in the RF case, and 75.52% in the BT case. Timeouts in CPIXp-TBM are entirely due to the calls to the imp oracle: while our approach reduces the number of oracle calls, each implicant test remains inherently intractable for RFs and BTs.
| Cooper-Amgoud | CPI-Xp-TBM | |||||
|---|---|---|---|---|---|---|
| Dataset | Time | Std | TO% | Time | Std | TO% |
| arrowhead 0 vs 1 | 24.448 | 17.465 | 54 | 2.173 | 1.090 | 0 |
| arrowhead 0 vs 2 | 18.062 | 14.061 | 33 | 3.626 | 3.280 | 0 |
| arrowhead 1 vs 2 | 35.251 | 15.191 | 68 | 4.380 | 3.337 | 0 |
| australian | - | - | 100 | 31.036 | 15.979 | 57 |
| balance 0 vs 1 | 30.909 | 11.031 | 24 | 2.743 | 1.513 | 0 |
| balance 0 vs 2 | 19.741 | 10.944 | 1 | 1.288 | 0.677 | 0 |
| balance 1 vs 2 | 17.363 | 10.908 | 9 | 1.175 | 0.758 | 0 |
| bank | - | - | 100 | 30.431 | 14.107 | 79 |
| biodegradation | - | - | 100 | 37.484 | 11.428 | 54 |
| breast-tumor | - | - | 100 | 9.652 | 9.702 | 2 |
| bupa | 35.478 | 0 | 99 | 9.848 | 8.914 | 0 |
| cleveland nominal | 30.909 | 0 | 99 | 12.332 | 7.765 | 0 |
| cnae | 10.895 | 7.026 | 0 | 3.124 | 1.700 | 0 |
| compas | 30.484 | 14.459 | 96 | 7.487 | 8.057 | 0 |
| contraceptive | - | - | 100 | 18.288 | 13.203 | 4 |
| dexter | - | - | 100 | 26.592 | 11.159 | 4 |
| divorce | 3.419 | 0.853 | 0 | 1.411 | 0.152 | 0 |
| german | 36.192 | 0 | 99 | 28.240 | 14.940 | 21 |
| melb data 0 vs 1 | - | - | 100 | 46.492 | 8.703 | 96 |
| melb data 0 vs 2 | - | - | 100 | 36.364 | 0 | 99 |
| melb data 1 vs 2 | - | - | 100 | 51.927 | 9.313 | 98 |
5 Conclusion
We presented a greedy algorithm that exploits the specific domain theory of tree-based models to efficiently derive CPIXps. Unlike what happens when the domain theory under consideration is not constrained, our algorithm requires only polynomially many calls to the implicant test. An empirical evaluation across tree ensembles confirms that our approach scales better than the existing general-purpose algorithm for deriving CPI-Xps.
Several perspectives for further research can be envisioned. One of them is to look for alternative conditions on the domain theory that would be sufficient to preserve the correctness of the algorithm. Another perspective is to exploit local CPI-Xps as building blocks for deriving more global explanations via set-cover algorithms.
Acknowledgements
Many thanks to the anonymous reviewers for their numerous comments and insights. This work has benefited from the support of the AI Chair EXPEKCTATION (ANR-19-CHIA0005-01) and of the France 2030 MAIA Project (ANR22-EXES-0009) of the French National Research Agency (ANR).
@inproceedings{ijcai2026p461,
  title     = {Computing Coverage-Based Prime Implicant Explanations for Tree-Based Models},
  author    = {Audemard, Gilles and Coste-Marquis, Sylvie and Marquis, Pierre and Sabiri, Mehdi and Szczepanski, Nicolas},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {4143--4151},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/461},
  url       = {https://doi.org/10.24963/ijcai.2026/461},
}
TY - CPAPER TI - Computing Coverage-Based Prime Implicant Explanations for Tree-Based Models AU - Audemard, Gilles AU - Coste-Marquis, Sylvie AU - Marquis, Pierre AU - Sabiri, Mehdi AU - Szczepanski, Nicolas T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 4143 EP - 4151 DO - 10.24963/ijcai.2026/461 UR - https://doi.org/10.24963/ijcai.2026/461 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





