
When and How to Adapt: Subject Shifts Detection and Prototype-Guided Correction for Online EEG Decoding
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 3755-3763.
https://doi.org/10.24963/ijcai.2026/418
Keywords
- Humans and AI: Human-computer interaction
- Humans and AI: Brain sciences
- Humans and AI: Applications
Abstract
Online EEG decoding is pivotal for real-world Brain-Computer Interfaces (BCIs) but confronts significant challenges arising from continuous distribution shifts, including both inter- and intra-subject variations. Existing Unsupervised Continual Domain Adaptation (UCDA) methods typically rely on rigid hard boundaries such as subject switch labels or fixed batch sizes to trigger adaptation. Meanwhile, some online EEG decoding methods that utilize detected shifts as soft boundaries are ill-suited for unsupervised scenarios and lack effective distribution alignment strategies. To address these issues, we propose a novel Prototype-driven online EEG Decoding framework (PRED). PRED incorporates a Subject Shift Detector (SSD) based on policy stability to reliably identify latent domain shifts unsupervisedly, thereby constructing adaptive soft boundaries. Furthermore, we design a Prototype-guided Shift Correction (PSC) mechanism that leverages a multi-granular memory structure to guide distribution alignment while preserving semantic stability. Experiments on three public datasets confirm that PRED achieves superior plasticity and stability, and demonstrates significant futurity, i.e., the capability of forward transfer to a subject's future samples.
- [Aljundi et al., 2019] Rahaf Aljundi, Min Lin, Baptiste Gou- jaud, and Yoshua Bengio. Gradient based sample selection for online continual learning. Advances in neural informa- tion processing systems, 32, 2019.
- [Amin et al., 2019] Syed Umar Amin, Mansour Alsulaiman, Ghulam Muhammad, Mohamed Amine Mekhtiche, and M Shamim Hossain. Deep learning for eeg motor imagery classification based on multi-layer cnns feature fusion. Fu- ture Generation computer systems, 101:542-554, 2019.
- [Baddeley, 2010] Alan Baddeley. Working memory. Current biology, 20(4):R136-R140, 2010.
- [Berners-Lee et al., 2022] Alice Berners-Lee, Ting Feng, Delia Silva, Xiaojing Wu, Ellen R Ambrose, Brad E Pfeif- fer, and David J Foster. Hippocampal replays appear af- ter a single experience and incorporate greater detail with more experience. Neuron, 110(11):1829-1842, 2022.
- [Caccia et al., 2021] Lucas Caccia, Rahaf Aljundi, Nader Asadi, Tinne Tuytelaars, Joelle Pineau, and Eugene Belilovsky. New insights on reducing abrupt representa- tion change in online continual learning. arXiv preprint arXiv:2104.05025, 2021.
- [Cai et al., 2021] Zhipeng Cai, Ozan Sener, and Vladlen Koltun. Online continual learning with natural distribution shifts: An empirical study with visual data. In Proceedings of the IEEE/CVF international conference on computer vi- sion, pages 8281-8290, 2021.
- [Chen et al., 2023] Jingjing Chen, Xiaobin Wang, Chen Huang, Xin Hu, Xinke Shen, and Dan Zhang. A large finer-grained affective computing eeg dataset. Scientific Data, 10(1):740, 2023.
- [Chen et al., 2025] Bojian Chen, Xinmin Zhang, Changqing Shen, Qi Li, and Zhihuan Song. Couda: Continual unsu- pervised domain adaptation for industrial fault diagnosis under dynamic working conditions. IEEE Transactions on Industrial Informatics, 2025.
- [Cho et al., 2023] Wonguk Cho, Jinha Park, and Taesup Kim. Complementary domain adaptation and generaliza- tion for unsupervised continual domain shift learning. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 11442-11452, 2023.
- [De Lange and Tuytelaars, 2021] Matthias De Lange and Tinne Tuytelaars. Continual prototype evolution: Learn- ing online from non-stationary data streams. In Proceed- ings of the IEEE/CVF international conference on com- puter vision, pages 8250-8259, 2021.
- [Diykh et al., 2016] Mohammed Diykh, Yan Li, and Peng Wen. Eeg sleep stages classification based on time domain features and structural graph similarity. IEEE Transac- tions on Neural Systems and Rehabilitation Engineering, 24(11):1159-1168, 2016.
- [Duan et al., 2023] Tiehang Duan, Zhenyi Wang, Gian- franco Doretto, Fang Li, Cui Tao, and Donald Adjeroh. Replay with stochastic neural transformation for online continual eeg classification. In 2023 IEEE international conference on bioinformatics and biomedicine (BIBM), pages 1874-1879. IEEE, 2023.
- [Duan et al., 2024a] Tiehang Duan, Zhenyi Wang, Fang Li, Gianfranco Doretto, Donald A Adjeroh, Yiyi Yin, and Cui Tao. Online continual decoding of streaming eeg signal with a balanced and informative memory buffer. Neural Networks, 176:106338, 2024.
- [Duan et al., 2024b] Tiehang Duan, Zhenyi Wang, Li Shen, Gianfranco Doretto, Donald A Adjeroh, Fang Li, and Cui Tao. Retain and adapt: Online sequential eeg classification with subject shift. IEEE Transactions on Artificial Intelli- gence, 5(9):4479-4492, 2024.
- [Eldele et al., 2021] Emadeldeen Eldele, Mohamed Ragab, Zhenghua Chen, Min Wu, Chee Keong Kwoh, Xiaoli Li, and Cuntai Guan. Time-series representation learning via temporal and contextual contrasting. arXiv preprint arXiv:2106.14112, 2021. IJCAI
- [Herman et al., 2008] Pawel Herman, Girijesh Prasad, Thomas Martin McGinnity, and Damien Coyle. Com- parative analysis of spectral approaches to feature extraction for eeg-based motor imagery classification. IEEE Transactions on Neural Systems and Rehabilitation Engineering, 16(4):317-326, 2008.
- [Jenke et al., 2014] Robert Jenke, Angelika Peer, and Martin Buss. Feature extraction and selection for emotion recog- nition from eeg. IEEE Transactions on Affective comput- ing, 5(3):327-339, 2014.
- [Jia et al., 2020] Ziyu Jia, Youfang Lin, Jing Wang, Rong- hao Zhou, Xiaojun Ning, Yuanlai He, and Yaoshuai Zhao. Graphsleepnet: Adaptive spatial-temporal graph convolu- tional networks for sleep stage classification. In Ijcai, vol- ume 2021, pages 1324-1330, 2020. IJCAI
- [Jin et al., 2024] Jiarui Jin, Zongnan Chen, Honghua Cai, and Jiahui Pan. Affective eeg-based person identification with continual learning. IEEE Transactions on Instrumen- tation and Measurement, 73:1-16, 2024.
- [Khalighi et al., 2016] Sirvan Khalighi, Teresa Sousa, José Moutinho Santos, and Urbano Nunes. Isruc-sleep: A comprehensive public dataset for sleep researchers. Computer methods and programs in biomedicine, 124:180-192, 2016.
- [Li et al., 2019] Jinpeng Li, Shuang Qiu, Yuan-Yuan Shen, Cheng-Lin Liu, and Huiguang He. Multisource transfer learning for cross-subject eeg emotion recognition. IEEE transactions on cybernetics, 50(7):3281-3293, 2019.
- [Li et al., 2024a] Dan Li, Hye-Bin Shin, Kang Yin, and Seong-Whan Lee. Domain-incremental learning frame- work for continual motor imagery eeg classification task. In 2024 46th Annual International Conference of the IEEE Engineering in Medicine and Biology Society (EMBC), pages 1-5. IEEE, 2024.
- [Li et al., 2024b] Qiwei Li, Yuxin Peng, and Jiahuan Zhou. Progressive prototype evolving for dual-forgetting mitiga- tion in non-exemplar online continual learning. In Pro- ceedings of the 32nd ACM International Conference on Multimedia, pages 2477-2486, 2024.
- [Li et al., 2025] Dan Li, Hye-Bin Shin, and Kang Yin. Per- sonalized continual eeg decoding: Retaining and transfer- ring knowledge. In 2025 13th International Conference on Brain-Computer Interface (BCI), pages 1-4. IEEE, 2025.
- [Lopez-Paz and Ranzato, 2017] David Lopez-Paz and Marc'Aurelio Ranzato. Gradient episodic memory for continual learning. Advances in neural information processing systems, 30, 2017.
- [Mermillod et al., 2013] Martial Mermillod, Aurélia Bugaiska, and Patrick Bonin. The stability-plasticity dilemma: Investigating the continuum from catastrophic forgetting to age-limited learning effects, 2013.
- [Pan et al., 2023] Tongjie Pan, Yalan Ye, Hecheng Cai, Shudong Huang, Yang Yang, and Guoqing Wang. Mul- timodal physiological signals fusion for online emotion recognition. In Proceedings of the 31st ACM international conference on multimedia, pages 5879-5888, 2023.
- [Rolnick et al., 2019] David Rolnick, Arun Ahuja, Jonathan Schwarz, Timothy Lillicrap, and Gregory Wayne. Expe- rience replay for continual learning. Advances in neural information processing systems, 32, 2019.
- [Saporta et al., 2022] Antoine Saporta, Arthur Douillard, Tuan-Hung Vu, Patrick Pérez, and Matthieu Cord. Multi- head distillation for continual unsupervised domain adap- tation in semantic segmentation. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 3751-3760, 2022.
- [Schalk et al., 2004] Gerwin Schalk, Dennis J McFarland, Thilo Hinterberger, Niels Birbaumer, and Jonathan R Wol- paw. Bci2000: a general-purpose brain-computer interface (bci) system. IEEE Transactions on biomedical engineer- ing, 51(6):1034-1043, 2004.
- [Schulman et al., 2015] John Schulman, Sergey Levine, Pieter Abbeel, Michael Jordan, and Philipp Moritz. Trust region policy optimization. In International conference on machine learning, pages 1889-1897. PMLR, 2015.
- [She et al., 2023a] Qingshan She, Tie Chen, Feng Fang, Jianhai Zhang, Yunyuan Gao, and Yingchun Zhang. Im- proved domain adaptation network based on wasserstein distance for motor imagery eeg classification. IEEE Trans- actions on Neural Systems and Rehabilitation Engineer- ing, 31:1137-1148, 2023.
- [She et al., 2023b] Qingshan She, Chenqi Zhang, Feng Fang, Yuliang Ma, and Yingchun Zhang. Multisource associate domain adaptation for cross-subject and cross- session eeg emotion recognition. IEEE Transactions on Instrumentation and Measurement, 72:1-12, 2023.
- [Squire et al., 2015] Larry R Squire, Lisa Genzel, John T Wixted, and Richard G Morris. Memory consolida- tion. Cold Spring Harbor perspectives in biology, 7(8):a021766, 2015.
- [Taufique et al., 2021] Abu Md Niamul Taufique, Chowd- hury Sadman Jahan, and Andreas Savakis. Conda: Con- tinual unsupervised domain adaptation. arXiv preprint arXiv:2103.11056, 2021.
- [Taufique et al., 2022] Abu Md Niamul Taufique, Chowd- hury Sadman Jahan, and Andreas Savakis. Unsupervised continual learning for gradually varying domains. In Pro- ceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 3740-3750, 2022.
- [Taufique et al., 2023] Abu Md Niamul Taufique, Chowd- hury Sadman Jahan, and Andreas Savakis. Continual un- supervised domain adaptation in data-constrained envi- ronments. IEEE Transactions on Artificial Intelligence, 5(1):167-178, 2023.
- [Wang et al., 2022] Qin Wang, Olga Fink, Luc Van Gool, and Dengxin Dai. Continual test-time domain adaptation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 7201-7211, 2022.
- [Wang et al., 2024a] Jing Wang, Xiaojun Ning, Wei Xu, Yunze Li, Ziyu Jia, and Youfang Lin. Multi-source se- lective graph domain adaptation network for cross-subject eeg emotion recognition. Neural Networks, 180:106742, 2024.
- [Wang et al., 2024b] Yanshuo Wang, Jie Hong, Ali Cher- aghian, Shafin Rahman, David Ahmedt-Aristizabal, Lars Petersson, and Mehrtash Harandi. Continual test-time do- main adaptation via dynamic sample selection. In Pro- ceedings of the IEEE/CVF Winter Conference on Applica- tions of Computer Vision, pages 1701-1710, 2024.
- [Wang et al., 2025] Jing Wang, Zhiyang Feng, Xiaojun Ning, Youfang Lin, Badong Chen, and Ziyu Jia. Two- stream dynamic heterogeneous graph recurrent neural net- work for multi-label multi-modal emotion recognition. IEEE Transactions on Affective Computing, 2025.
- [Ye and Bors, 2024] Fei Ye and Adrian G Bors. Online task- free continual generative and discriminative learning via dynamic cluster memory. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 26202-26212, 2024.
- [Zhou et al., 2023] Rushuang Zhou, Zhiguo Zhang, Hong Fu, Li Zhang, Linling Li, Gan Huang, Fali Li, Xin Yang, Yining Dong, Yuan-Ting Zhang, et al. Pr-pl: A novel prototypical representation based pairwise learn- ing framework for emotion recognition using eeg signals. IEEE Transactions on Affective Computing, 15(2):657- 670, 2023.
- [Zhou et al., 2025] Yangxuan Zhou, Sha Zhao, Jiquan Wang, Haiteng Jiang, Shijian Li, Tao Li, and Gang Pan. Brainuicl: An unsupervised individual continual learning framework for eeg applications. In The Thirteenth Inter- national Conference on Learning Representations, 2025.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Electroencephalography (EEG) is a cornerstone of BrainComputer Interfaces (BCI) due to its non-invasiveness and high temporal resolution. Deep learning has significantly advanced EEG decoding in tasks such as motor imagery [Herman et al., 2008; Amin et al., 2019], emotion recognition [Jenke et al., 2014; Wang et al., 2025], and sleep staging [Diykh et al., 2016; Jia et al., 2020]. However, with the proliferation of wearable EEG devices and real-time HumanComputer Interaction (HCI) systems, the research focus is shifting from offline paradigms to online reasoning and updating to cope with the distribution shifts of data streams in the temporal dimension [Li et al., 2025], making robust online EEG decoding pivotal for practical applications.
*Corresponding author
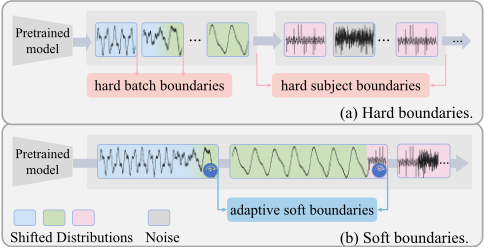
Online EEG data streams exhibit significant distribution shifts characterized by both intra-subject time-varying variations in long-term monitoring of wearable devices and intersubject variations in multi-user deployment scenarios such as clinical assistance or human-computer interaction [Duan et al., 2024a]. This compounded continuous distribution shifts coupled with the absence of real-time labeling makes online EEG decoding essentially an Unsupervised Continual Domain Adaptation (UCDA) problem.
Several existing methods [Taufique et al., 2021; Taufique et al., 2022; Chen et al., 2025] have investigated the adaptation and generalization capabilities of models in UCDA scenarios. For instance, Zhou et al. [2025] proposed an Unsupervised Individual Continual Learning (UICL) framework, demonstrating favorable plasticity (i.e., the model's ability to adapt to new online subject distributions) and stability (i.e., the model's ability to generalize to the generalization set). However, as shown in Figure 1, relying exclusively on subject switch labels as hard boundaries to trigger adaptation completely overlooks intra-subject shifts, failing to update the model in time to improve online performance. While methods depending on fixed batch sizes as hard boundaries [Wang et al., 2022; Cai et al., 2021; Ye and Bors, 2024] struggle to balance adaptability and responsiveness: small batch updates are prone to noise-driven overfitting, while large batch updates often lead to adaptation lag, rendering the model ineffective against rapid or sudden distribution shifts. Therefore, autonomously capturing distribution shifts from streaming data to determine when to adapt (i.e., soft boundaries) remains a critical challenge in realistic online scenarios.
Furthermore, some online EEG decoding methods [Duan et al., 2024a; Duan et al., 2024b] attempt to detect soft boundaries by directly monitoring distribution changes in data representations, subsequently triggering adaptation. However, these methods still rely on target domain labels, making it impossible to accurately align the shifted target distribution with learned knowledge in the absence of ground truth guidance. Meanwhile, other approaches [Wang et al., 2022; Zhou et al., 2025] introduce only pseudo-labels, which act as unstable anchors, to guide the optimization process. When the model yields high-confidence incorrect predictions, forcing alignment with these noisy pseudo-labels causes errors to accumulate temporally, gradually dismantling the established semantic space and leading to severe negative transfer. Therefore, even if existing methods have partially alleviated the issue of adaptation timing, how to adapt in an effective and stable manner remains a key challenge.
To address the aforementioned challenges in real online scenarios, we propose a novel Prototype-driven online EEG Decoding framework (PRED). Operating in a plug-and-play manner, PRED enables the model to adaptively identify subject distribution shifts within online EEG data streams and perform shift correction, thereby achieving superior plasticity and stability. Furthermore, we explore a unique property of soft boundaries in online scenarios, namely futurity (i.e., the model learns a partial sample of a new subject and then improves its ability to generalize to future samples of that subject), which has been overlooked in current research. To this end, we design two novel modules: a Subject Shift Detector (SSD) based on policy stability [Schulman et al., 2015] and a Prototype-guided Shift Correction (PSC) mechanism. Specifically, the SSD determines when to adapt by monitoring the relative cumulative deviation between the current classification policy and a reference classification policy. Upon detection of a significant shift, the PSC module is triggered. It leverages a multi-granular memory structure containing prototypes to perform experience replay and guide the correction of distribution shifts, enhancing the model's adaptability. Simultaneously, PSC maintains the semantic distribution anchored by prototypes to prevent performance deterioration caused by overfitting. The contributions of this paper are as follows:
- We design a Subject Shift Detector based on policy stability, which can reliably detect distribution shifts in online scenarios, thereby automatically determining the appropriate soft boundary for adaptation.
- We propose a Prototype-guided Shift Correction mechanism that not only enhances the model's rapid adaptation to new subject distributions but also improves the stability of model updates.
- We validate PRED on three public EEG decoding task datasets verified that PRED copes well with real online
scenarios, achieving better plasticity and stability as well as exploring futurity in online settings.
2 RelatedWork
2.1 Domain Adaptation
To address the issue of cross-domain discrepancy, researchers have proposed numerous methods based on domain adaptation [She et al., 2023b; She et al., 2023a; Eldele et al., 2021]. For instance, PR-PL [Zhou et al., 2023] combines prototypical representation with pairwise learning to mitigate label noise and individual differences. A multi-source transfer learning framework [Li et al., 2019] rapidly adapts models from existing subjects to new subjects utilizing a small amount of calibration data via source selection and style transfer mapping. Additionally, MSGDAN [Wang et al., 2024a] combines dynamic graph alignment with a source selection mechanism to extract robust subject-invariant representations.
While these methods achieve effective adaptation for individual subjects, they neglect intra-subject variations. As a result, their direct application to real-world online scenarios with continuous subject distribution shifts often leads to cumulative errors.
2.2 Unsupervised Continual Domain Adaptation
Unsupervised Continual Domain Adaptation (UCDA) has garnered significant research attention to address the challenge of continuous domain shifts [Taufique et al., 2021; Taufique et al., 2023; Saporta et al., 2022; Cho et al., 2023]. For instance, UCL-GV [Taufique et al., 2022] employs contrastive loss to better align the distribution discrepancy between the buffer and the continuous stream of target batches. BrainUICL [Zhou et al., 2025] introduces a novel unsupervised individual continual learning paradigm, effectively balancing plasticity and stability [Mermillod et al., 2013] during the adaptation process to new subjects. CoUDA [Chen et al., 2025] leverages prototype contrastive learning and source-anchored knowledge distillation to achieve continual domain adaptation for industrial fault diagnosis. Furthermore, CoTTA [Wang et al., 2022] reduces error accumulation via weight and augmentation averaging, while preventing catastrophic forgetting by stochastically restoring neurons to source weights.
The aforementioned UCDA methods typically trigger adaptations via rigid hard boundaries, such as subject switch labels or fixed batch sizes. Consequently, they suffer from adaptation lag and susceptibility to noise, making it difficult to effectively enhance online performance in real-world scenarios.
2.3 Online EEGDecoding
Recently, several studies have also focused on continuous EEG decoding to address cross-subject discrepancies [Duan et al., 2023; Jin et al., 2024; Li et al., 2024a]. OMHGL [Pan et al., 2023] fuses multimodal physiological signals via hypergraphs to capture high-order correlations and updates projections online to adapt to individual differences. To adaptively capture the soft boundary for triggering adaptation, MUDVI [Duan et al., 2024a] employs kernel-based shift detection to identify changes in subject distribution and a memory buffer to mitigate forgetting. Similarly, AMBM [Duan et al., 2024b] utilizes bayesian change point detection to trigger adaptation and bi-level mutual information maximization for knowledge retention.
Nevertheless, current online EEG decoding methods still rely on target domain labels and lack direct and effective distribution alignment strategies, rendering them ill-suited for realistic unsupervised online scenarios.
3 Preliminaries
Formally, let DS = {X iS , Y iS }NS i=1 , DT = {X iT }NT i=1 , and DG = {X iG, Y iG}NG i=1 denote the labeled source, unlabeled online target, and labeled generalization domains, comprising NS, NT , and NG subjects, respectively. In realistic online scenarios, we partition the data stream by detecting soft boundaries via the subject shift detector. We define the i-th incremental segment X i I as the samples collected between the (i-1)-th and i-th detected soft boundaries, forming the incremental domain DI = {X i I }NI i=1 with NI identified segments. The source pre-trained model M0 is continuously updated on DI , yielding a sequence of models M0 → · · · → MNI .
4 Methodology
Drawing inspiration from rehearsal-based continual learning methodologies [Lopez-Paz and Ranzato, 2017; Aljundi et al., 2019; Rolnick et al., 2019], this work leverages a multigranular memory structure to implement a replay mechanism, thereby mitigating catastrophic forgetting. As illustrated in Figure 2, the model Mi-1, derived from the preceding incremental segment X i-1 I , continues to perform online EEG decoding. Upon the detection of a significant subject shift (i.e., a soft boundary), the prototype-guided shift correction mechanism is triggered to yield the adapted model Mi, which subsequently proceeds to the next iteration cycle.
Our proposed method functions as a plug-and-play online EEG decoding framework. The underlying model architecture comprises an encoder network f(·), a projection head g(·), and a classifier φ(·). An input sample x is mapped to a vector representation z via the encoder and the projection head, which is subsequently processed by the classifier to obtain the prediction vector ˆ y:
4.1 Multi-granular Memory Structure
In neuroscience, the human memory system is organized into distinct functional hierarchies. Working memory acts as a temporary workspace for short-term retention [Baddeley, 2010], while the hippocampus facilitates consolidation by replaying experiences to integrate information [BernersLee et al., 2022]. Ultimately, these memories evolve into stable and generalizable long-term knowledge within the neocortex [Squire et al., 2015]. Mimicking this biological mechanism, we implement a Multi-granular Memory Structure (MMS): the Online buffer (Bo) for short-term data retention, the Replay buffer (Br) for consolidating information via replay, and the Prototype buffer (Bp) for storing abstract prototypes as long-term memory. This architecture effectively combines rapid adaptation with long-term generalization to mitigate catastrophic forgetting.
The specific update process of the MMS is as follows: During the initialization phase prior to online decoding, we compute the mean vector representation of samples for each class in DS to serve as prototypes:
where nc denotes the number of samples belonging to class c in DS, and I is the indicator function. This yields the prototype set Bp = {Pc}Nc c=1 , containing Nc prototypes. Before adaptation is triggered, online data and their prediction vectors are stored in Bo = {xo, ˆ yo}No o=1 in a First-In-FirstOut (FIFO) manner, subject to the constraint that the capacity No remains less than the maximum capacity Nmax. When adaptation is triggered, samples equal in quantity to Bo are class-balanced sampled from DS to form Br = {xr, yr}No r=1 . Together with Bo and Bp, Br is utilized for shift correction. Following adaptation, Bo and Br are cleared, and Bp is updated using an Exponential Moving Average (EMA):
where the replay prototype P r c is the mean vector representation of samples in class c from Br, and the online prototype P o c is the mean vector representation of high-confidence samples in class c from Bo that satisfy max(ˆ yo) > ξ1. The parameters α ∈ [0, 1) and β ∈ [0, 1) represent the smoothing coefficient for prototype updates and the weight of the replay prototypes, respectively. Given that the number of samples available for sampling in Br is limited and Bo stores only a small amount of online data, the resulting storage cost is acceptable for online scenarios with continuous data streams.
4.2 Subject Shift Detector
Statistical shift detection is often prone to false positives due to task-irrelevant noise. Inspired by the trust-region constraint in TRPO [Schulman et al., 2015], we design a Subject Shift Detector based on policy stability. By monitoring the relative cumulative deviation between the current and reference policies, this method identifies significant shifts. This taskoriented design circumvents the noise sensitivity inherent in pure data-level detection.
We regard the output probability distribution qt(y|xt) of the classifier φ(·) for sample xt at time step t as the current classification policy under state xt:
By calculating the cosine similarity between the sample feature zt and the class prototypes in Bp, followed by normalization, we obtain the prototype similarity distribution pt(y|xt) as the historical reference policy:
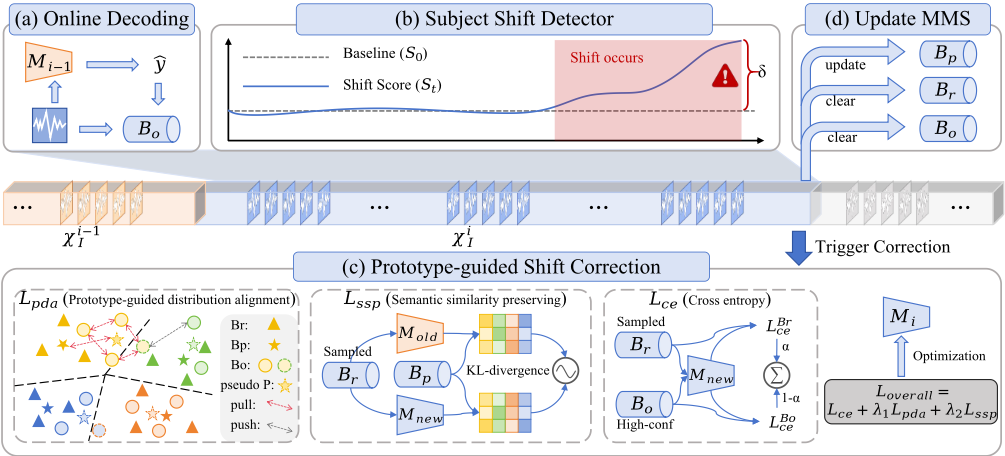
where τ denotes the temperature coefficient. The reference distribution is not a static obsolete policy, but rather a prior that updates gradually over time. This enables the detector to remain sensitive to short-term abrupt changes while accommodating acceptable long-term distribution drift. We employ the Kullback-Leibler (KL) divergence to compute the instantaneous deviation Dt between the current policy and the reference policy:
Given that the instantaneous deviation is susceptible to noise interference, we employ an EMA to derive the smoothed deviation St:
where γ ∈ [0, 1) represents the smoothing coefficient. To accommodate variations across different subject distributions, we estimate the baseline S0 as the mean deviation calculated over the initial k samples of each detection phase:
Shift correction is triggered when St S0 - 1 > δ, indicating that the policy shift has exceeded the boundaries of the trust region. Here, the relative threshold δ ensures that the detector focuses on relative deviation rather than relying on an absolute scale.
4.3 Prototype-guided Shift Correction
Prototype-guided distribution alignment. While prototypes can serve as effective alignment anchors [De Lange and Tuytelaars, 2021; Li et al., 2024b], online distribution shifts often cause samples to temporarily deviate towards mismatched prototypes in the feature space, making direct alignment to the nearest prototype prone to misalignment and noise amplification. We propose a prototype-guided strategy that clusters samples with similar prototype similarity distributions and identifies the target prototype via intra-cluster voting. By leveraging group structural consistency to suppress individual noise, this method ensures robust prototypeguided distribution alignment under distribution shifts.
First, we calculate the prototype similarity distribution pi for sample xi ∈ Bo according to Eq. 5. This distribution not only characterizes the prediction tendency of the reference policy but also implicitly reflects the sample's relative position within the feature space. Consequently, samples sharing similar pi are treated as potential intra-cluster neighbors, and a clustering-like effect is achieved via contrastive loss. Specifically, we construct the positive set Ci = {xj ∈ Bo \ {xi} | cos(pi, pj) > ξ2}, where samples with similarity to pi exceeding the threshold ξ2 are grouped into the same cluster. The contrastive loss Lcon is defined as:
Concurrently, we utilize the high-confidence pseudo-labels within the cluster for class determination, defining the predicted class ˜ yi of the cluster Ci via majority voting:
Subsequently, we define the pseudo-prototype ˜ Pi as the feature centroid of Ci and align it with its corresponding true prototype, yielding the alignment loss:
By combining the components of the prototype-guided distribution alignment strategy, the total loss is formulated as:
Semantic similarity preserving. To prevent overfitting to outlier subject distributions during the model update process, which could disrupt the original discriminative structure and hinder subsequent recovery or lead to continuous performance degradation, it is imperative to preserve the semantic distribution throughout the update phase. Specifically, we denote the model undergoing the update process (comprising the encoder and projection head) and the model prior to triggering adaptation as gnew(fnew(·)) and gold(fold(·)), respectively. For each replay sample xr ∈ Br, we obtain its corresponding new and old vector representations, znew r and zold r :
Subsequently, utilizing Eq. 5, we derive pnew r and pold r to represent the new and old semantic distributions, respectively. We employ the KL divergence to enforce consistency in the semantic distribution during model updates, thereby formulating the semantic similarity preserving loss:
Overall loss function. In addition to the aforementioned losses, we incorporate a weighted cross-entropy loss targeting both the replay buffer Br and the online buffer Bo:
Here, the weighting parameter is set to be consistent with the weight β. Consequently, the overall objective function is formulated as:
where λ1 and λ2 denote the hyperparameters weighting the respective loss terms. By integrating prototype-guided distribution alignment and semantic similarity preserving, this overall loss function ultimately achieves robust correction of subject distribution shifts.
| Dataset | # Subj. | # Chan. | Rate(Hz) | # Classes | Window (s) |
|---|---|---|---|---|---|
| Physionet-MI | 105 | 64 | 160 | 4 | 4 |
| FACED | 123 | 32 | 128 | 9 | 10 |
| ISRUC | 100 | 8 | 100 | 5 | 30 |
5 Experiments
5.1 Datasets
We evaluate PRED on three large-scale datasets (>100 subjects each) spanning Motor Imagery, Emotion Recognition, and Sleep Staging: Physionet-MI [Schalk et al., 2004], FACED [Chen et al., 2023], and ISRUC [Khalighi et al., 2016]. As outlined in Table 1, this scale enables rigorous simulation of challenging long-term online decoding scenarios.
5.2 Experimental Settings and Implementation
Following the protocol established in BrainUICL [Zhou et al., 2025], we partition each dataset into a source domain, an online target domain, and a generalization domain in a 3:5:2 ratio, with the initial model M0 pre-trained on the source domain. The online target domain is utilized to simulate data streams for evaluating the model's plasticity and futurity, while the stability of each incremental model is assessed on the generalization domain after adapting to each incremental segment.
Specifically, during online EEG decoding, an incremental segment X i-1 I is delineated when the model Mi-2 detects a new subject distribution and triggers adaptation. Consequently, the subsequent incremental segment X i I is highly likely to contain future samples originating from the same subject distribution. Compared to the preceding model Mi-2, the model Mi-1, having adapted to X i-1 I , is expected to exhibit superior forward transfer on X i I . We define this property as the model's futurity. In addition, the further performance enhancement of Mi on X i I subsequent to adaptation is termed plasticity, reflecting the capability for rapid adaptation to new subject distributions. To ensure a fair comparison, we utilize Global ACC (GACC) and Global Macro-F1 (GMF1) to measure plasticity and futurity, calculated based on the concatenation of predictions and labels across all incremental segments partitioned by either hard or soft boundaries (i.e., ∪NI i=1 ˆ Y i I and ∪NI i=1Y i I ). Furthermore, stability on the generalization domain is evaluated via Average Anytime Accuracy (AAA) [Caccia et al., 2021] and Average Anytime MacroF1 (AAF1). Here, AAAi and AAF1i denote the mean ACC and mean MF1, respectively, of the sequence of incremental models {M0,M1, . . . ,Mi} on the generalization domain. The specific formulation is as follows:
and AAF1 is defined analogously using the MF1 score, where i indexes the i-th incremental segment; YG and ˆ Y jG represent the ground-truth labels of the generalization domain and the predictions generated by model Mj , respectively. Subsequent experiments are conducted over 5 independent runs with the subject input order in the online target domain randomly shuffled (without altering data partitions), and statistical results are reported.
| Plasticity | Futurity | Stability | ||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| GACC | GMF1 | GACC | GMF1 | AAA | AAF1 | |||||||||||||
| Dataset | M0 | Mi | ∆(↑) | M0 | Mi | ∆(↑) | Mi-2 | Mi-1 | ∆(↑) | Mi-2 | Mi-1 | ∆(↑) | M0 | MNI | ∆(↑) | M0 | MNI | ∆(↑) |
| Physionet-MI | 46.41 | 49.43 | 3.02 | 45.51 | 49.55 | 4.04 | 48.62 | 49.33 | 0.71 | 48.74 | 49.43 | 0.69 | 49.89 | 51.75 | 1.86 | 48.87 | 51.46 | 2.59 |
| FACED | 34.91 | 42.02 | 7.11 | 35.11 | 42.53 | 7.42 | 40.02 | 41.21 | 1.19 | 40.58 | 41.74 | 1.16 | 38.59 | 42.81 | 4.22 | 38.74 | 43.07 | 4.33 |
| ISRUC | 69.76 | 74.32 | 4.56 | 64.86 | 72.37 | 7.51 | 71.84 | 73.17 | 1.33 | 69.80 | 71.12 | 1.32 | 73.22 | 74.92 | 1.70 | 69.23 | 73.01 | 3.78 |
| Metric | UCDA | UDA | |||||||
|---|---|---|---|---|---|---|---|---|---|
| PRED- soft | PRED- hard | BrainUICL | CoUDA | DSS | COTTA | UCL-GV | PR-PL | TS-TCC | |
| Physionet-MI GACC GMF1 AAA AAF1 | 49.43±0.16 49.55±0.20 51.75±0.35 51.46±0.42 | 48.64±0.10 48.71±0.19 50.35±0.29 50.18±0.35 | 48.56±0.28 47.49±0.37 50.02±0.33 49.69±0.46 | 46.60±0.18 46.46±0.17 50.45±0.04 50.46±0.04 | 46.29±0.25 45.07±0.41 49.84±0.20 48.44±0.34 | 47.26±0.23 45.66±0.28 50.01±0.01 47.86±0.01 | 45.87±0.20 44.60±0.22 49.23±0.15 47.92±0.26 | 45.28±0.11 42.13±0.11 47.42±0.04 44.38±0.05 | 43.93±1.05 44.12±1.04 45.66±0.50 44.27±0.60 |
| FACED GACC GMF1 AAA AAF1 | 42.02±0.24 42.53±0.26 42.81±0.15 43.07±0.15 | 41.18±0.36 41.61±0.33 42.16±0.16 42.42±0.17 | 40.19±0.37 39.67±0.36 40.79±0.17 40.98±0.16 | 39.18±0.20 39.60±0.24 40.10±0.04 40.33±0.04 | 35.75±0.37 35.69±0.36 37.91±0.13 37.88±0.12 | 37.74±0.18 37.63±0.16 37.22±0.02 37.05±0.02 | 36.71±0.12 36.66±0.08 38.90±0.12 38.81±0.11 | 35.84±0.17 35.13±0.15 37.60±0.03 37.66±0.04 | 34.47±0.39 34.44±0.40 36.90±0.31 36.75±0.33 |
| ISRUC GACC GMF1 AAA AAF1 | 74.32±0.33 72.37±0.34 74.92±0.36 73.01±0.31 | 73.78±0.36 71.74±0.33 74.46±0.35 72.43±0.37 | 73.97±0.61 69.78±0.60 74.25±0.26 70.37±0.43 | 73.30±0.37 67.47±0.45 73.83±0.50 67.26±0.75 | 70.73±0.41 64.95±0.39 71.67±0.42 66.22±0.48 | 70.05±0.32 64.20±0.64 73.17±0.34 67.94±0.64 | 70.91±0.24 66.42±0.20 71.62±0.14 67.13±0.18 | 72.32±0.11 66.48±0.10 71.47±0.03 66.03±0.03 | 65.48±1.50 60.91±1.65 66.59±1.40 61.75±1.77 |
PRED is implemented in PyTorch using the Adam optimizer. For adaptation, the learning rate is set to 5 × 10⁻⁶ with 10 epochs. The online memory capacity Nmax is set to the average number of samples per subject in the dataset. The coefficients α, β, γ, and threshold ξ1, ξ2 are all set to 0.9. The Subject Shift Detector uses k = 20 and δ = 0.05, while loss weights λ1 and λ2 are set to 0.1 and 0.5, respectively.
5.3 Overview Performance
As presented in Table 2, we evaluated the PRED framework across three datasets. Specifically, for the i-th incremental segment X i I , we assessed performance using models at four distinct temporal stages: M0, Mi-2, Mi-1, and Mi. Additionally, we evaluated the performance of the most recently updated model on the generalization domain following each adaptation step. Here, M0 denotes the initial pre-trained model; Mi-2 represents the model prior to any exposure to the new subject's distribution; Mi-1 signifies the model that has learned from historical samples of the new subject distribution but has not yet encountered the future samples contained within X i I ; and Mi corresponds to the model fully adapted to the current incremental segment X i I . Finally, MNI represents the final model resulting from continuous adaptation to the entire online data stream. Regarding plasticity, the updated Mi consistently exhibits performance improvements compared to Mi-1. This improvement is even more pronounced when compared to M0. Regarding futurity, by learning from a limited number of samples from the new subject distribution, Mi-1 achieves substantial gains relative to Mi-2. Regarding stability, unlike certain domain incremental models that merely mitigate forgetting rates, our approach further enhances generalization capabilities on the generalization domain through online decoding learning, and eventually significantly outperforms M0 .
5.4 Comparison with Other Methods
Under the hard boundary setting, we implemented several UDA and UCDA baselines, including TS-TCC [Eldele et al., 2021], PR-PL [Zhou et al., 2023], UCL-GV [Taufique et al., 2022], COTTA [Wang et al., 2022], DSS [Wang et al., 2024b], CoUDA [Chen et al., 2025], and BrainUICL [Zhou et al., 2025], while evaluating two variants of PRED: PREDhard (using hard boundaries) and PRED-soft (using soft boundaries). As Futurity is not applicable under the hard boundary setting and the initial model remains consistent, we exclusively report plasticity (measured via GACC and GMF1 of Mi) and stability (measured via AAA and AAF1 of MNI ).
Table 3 shows PRED outperforms all baselines in both plasticity and stability. UDA baselines performed poorest due to their inability to handle continuous adaptation, while other UCDA methods fared better by accounting for continual domain shifts. PRED-hard outperforms baselines on most metrics in all three datasets, leveraging prototype-guided subject distribution alignment and semantic preservation to boost adaptability and generalization. PRED-soft further elevates performance, as the soft boundaries identified by the SSD facilitate timely adaptation to subject shifts. This mechanism avoids negative transfer from non-task noise, ultimately striking a superior balance between plasticity and stability.
| Plasticity | Futurity | Stability | ||||||||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Method | GACC | GMF1 | GACC | GMF1 | AAA | AAF1 | ||||||||||||
| M0 | Mi | ∆(↑) | M0 | Mi | ∆(↑) | Mi-2 | Mi-1 | ∆(↑) | Mi-2 | Mi-1 | ∆(↑) | M0 | MNI | ∆(↑) | M0 | MNI | ∆(↑) | |
| Base | 69.76 | 71.87 | 2.11 | 64.86 | 69.83 | 4.97 | 71.11 | 71.51 | 0.40 | 68.61 | 69.25 | 0.64 | 73.22 | 73.79 | 0.57 | 69.23 | 71.58 | 2.35 |
| Base+Lpda | 69.76 | 73.37 | 3.61 | 64.86 | 71.48 | 6.62 | 71.36 | 72.06 | 0.70 | 69.27 | 70.16 | 0.89 | 73.22 | 74.51 | 1.29 | 69.23 | 72.63 | 3.40 |
| Base+Lssp | 69.76 | 73.08 | 3.32 | 64.86 | 71.34 | 6.48 | 71.72 | 72.41 | 0.69 | 69.90 | 70.62 | 0.72 | 73.22 | 74.48 | 1.26 | 69.23 | 72.65 | 3.42 |
| RSID | 69.76 | 73.31 | 3.55 | 64.86 | 71.62 | 6.76 | 72.06 | 72.79 | 0.73 | 70.15 | 71.05 | 0.90 | 73.22 | 73.93 | 0.71 | 69.23 | 72.05 | 2.82 |
| BOCPD | 69.76 | 73.01 | 3.25 | 64.86 | 71.18 | 6.32 | 71.42 | 71.99 | 0.57 | 69.39 | 70.16 | 0.77 | 73.22 | 73.76 | 0.54 | 69.23 | 71.83 | 2.60 |
| PRED | 69.76 | 74.32 | 4.56 | 64.86 | 72.37 | 7.51 | 71.84 | 73.17 | 1.33 | 69.80 | 71.12 | 1.32 | 73.22 | 74.92 | 1.70 | 69.23 | 73.01 | 3.78 |
5.5 Ablation Study
We conducted a two-fold ablation study on ISRUC, focusing on the contributions of the loss functions and the superiority of the subject shift detector (Table 4).
Ablation of loss terms. We evaluated variants including Base (Lce only), Base + Lpda, and Base + Lssp. Results indicate that Lssp significantly enhances stability by constraining semantic consistency to prevent overfitting, which subsequently bolsters plasticity and futurity. Meanwhile, Lpda excels in plasticity by improving structural consistency and prototype alignment. The full PRED integrates both, creating a synergistic effect: Lpda ensures rapid adaptation to shifts, while Lssp guarantees stable updates, collectively achieving optimal performance across all metrics.
Ablation of the subject shift detector. We compared our SSD against RSID [Duan et al., 2024a] and BOCPD [Duan et al., 2024b]. SSD outperforms both across all metrics. Unlike RSID and BOCPD, which rely on data-level detection and are thus susceptible to noise-induced false positives and subsequent negative transfer, SSD triggers only on significant policy deviations. By effectively filtering task-irrelevant statistical drifts, SSD ensures more reliable soft boundaries.
5.6 Visualization
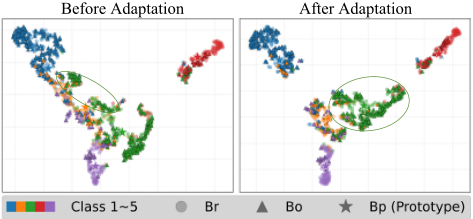
Visualization of feature adaptation dynamics. We visualized feature distribution evolution on ISRUC via t-SNE (Figure 3). The left panel reveals significant shifts between online data (Bo) and established memory (Br,Bp) upon SSD triggering (e.g., the green Class 3), validating the detector's sensitivity to subject shifts and the correctness of the soft boundaries. The right panel demonstrates that PSC successfully realigns shifted samples into clusters with clearer boundaries.
0
10
20
30
40
50
60
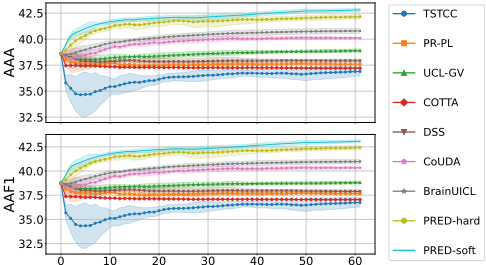
Figure 4: The AAA and AAF1 curves of PRED and baselines on FACED. These curves represent the performance of incremental models on the generalization domain, with shaded areas indicating the 95% confidence interval. Note that for PRED-soft, the curve is fitted to visualize the trend, as the specific timing of adaptation triggers varies across different input sequences.
This effective correction mechanism underpins PRED's superior plasticity and futurity.
Visualization of stability evolution. Figure 4 illustrates that the AAA and AAF1 curves for PRED exhibit a significant upward trend that gradually stabilizes, where PREDsoft displays better stability than PRED-hard. Enabled by the SSD to identify inter- and intra-subject shifts for precise soft boundary definition, PRED achieves effective adaptation and improved generalization. Compared to baseline methods, PRED exhibits superior stability.
6 Conclusion
We presented PRED, a novel prototype-driven framework for online reliable soft boundary detection and effective shift correction. By integrating the Subject Shift Detector (SSD) and Prototype-guided Shift Correction (PSC), PRED effectively solves the fundamental problem of when and how to adapt in unsupervised data streams. Specifically, SSD reliably identifies latent distribution shifts based on policy stability (when), while PSC leverages multi-granular memory structure to guide robust alignment (how). Extensive experiments across three public datasets demonstrate that PRED achieves a superior balance between plasticity and stability, and notably, exhibits significant futurity, paving the way for more realistic and autonomous BCI systems.
Acknowledgments
This work was supported by the National Natural Science Foundation of China (No. 62576027).
@inproceedings{ijcai2026p418,
  title     = {When and How to Adapt: Subject Shifts Detection and Prototype-Guided Correction for Online EEG Decoding},
  author    = {Zhang, Shaoqi and Jin, Xiyuan and Ning, Xiaojun and Chen, Yilin and Wang, Jing},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {3755--3763},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/418},
  url       = {https://doi.org/10.24963/ijcai.2026/418},
}
TY - CPAPER TI - When and How to Adapt: Subject Shifts Detection and Prototype-Guided Correction for Online EEG Decoding AU - Zhang, Shaoqi AU - Jin, Xiyuan AU - Ning, Xiaojun AU - Chen, Yilin AU - Wang, Jing T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 3755 EP - 3763 DO - 10.24963/ijcai.2026/418 UR - https://doi.org/10.24963/ijcai.2026/418 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





