
Fairly Dividing Non-identical Random Items: Just Sample or Match
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 3444-3451.
https://doi.org/10.24963/ijcai.2026/383
Keywords
- AI: Game Theory and Economic Paradigms
- Multidisciplinary Topics and Applications: Economics
- Machine Learning: Game Theory
- Game Theory and Economic Paradigms: Fair division
Abstract
We study the question of existence and fast computation of fair and efficient allocations of indivisible resources among agents with additive valuations. As such allocations may not exist for arbitrary instances, we ask if they exist for typical or random instances, meaning when the utility values of agents for the resources are drawn from certain distributions. In this paper, we extend the previously studied formal models of this problem to non-identical items. We assume that every item is associated with a distribution U_j, and every agent's utility value for the item is drawn independently from U_j. We show that envy-free fair and maximum social welfare efficient allocations exist with high probability in the asymptotic setting, meaning when the number of agents n and items m are large. Further, we show that when m = Ω(n log n), then by only sampling O(log m) or O((log m)^2) utility values per item instead of all the n, we can compute these allocations in Õ(m) time. Finally, we simulate our algorithms on randomly generated instances and show that even for small instances, we suffer small multiplicative losses in the fairness and efficiency guarantees and converge to fully optimal guarantees quickly.
- [Amanatidis et al., 2017] Georgios Amanatidis, Evangelos Markakis, Afshin Nikzad, and Amin Saberi. Approxi- mation algorithms for computing maximin share alloca- tions. ACM Transactions on Algorithms (TALG), 13(4):1- 28, 2017.
- [Amanatidis et al., 2023] Georgios Amanatidis, Haris Aziz, Georgios Birmpas, Aris Filos-Ratsikas, Bo Li, Hervé Moulin, Alexandros A Voudouris, and Xiaowei Wu. Fair division of indivisible goods: Recent progress and open questions. Artificial Intelligence, 322:103965, 2023.
- [Bai and Gölz, 2022] Yushi Bai and Paul Gölz. Envy-free and pareto-optimal allocations for agents with asymmet- ric random valuations. In Proceedings of the Thirty-First International Joint Conference on Artificial Intelligence, IJCAI-2022, page 53-59. International Joint Conferences on Artificial Intelligence Organization, July 2022. IJCAI
- [Bai et al., 2022] Yushi Bai, Uriel Feige, Paul Gölz, and Ariel D Procaccia. Fair allocations for smoothed utilities. In Proceedings of the 23rd ACM Conference on Economics and Computation, pages 436-465, 2022.
- [Dickerson et al., 2014] John Dickerson, Jonathan Goldman, Jeremy Karp, Ariel Procaccia, and Tuomas Sandholm. The computational rise and fall of fairness. Proceedings of the AAAI Conference on Artificial Intelligence, 28(1), Jun. 2014.
- [Erdős and Renyi, 1964] Paul Erdős and Alfred Renyi. On random matrices. Magyar Tud. Akad. Mat. Kutató Int. Közl, 8:455-461, 1964.
- [Esseen, 1942] Carl-Gustav Esseen. On the Liapunoff limit of error in the theory of probability. Arkiv för Matematik, Astronomi och Fysik, 28A(9):1-19, 1942.
- [Farhadi et al., 2019] Alireza Farhadi, Mohammad Ghodsi, Mohammad Taghi Hajiaghayi, Sebastien Lahaie, David Pennock, Masoud Seddighin, Saeed Seddighin, and Hadi Yami. Fair allocation of indivisible goods to asymmetric agents. Journal of Artificial Intelligence Research, 64:1- 20, 2019.
- [Hoeffding, 1963] Wassily Hoeffding. Probability inequali- ties for sums of bounded random variables. Journal of the American Statistical Association, 58(301):13-30, March 1963.
- [Karr, 1993] Alan F. Karr. Probability. Springer New York, New York, NY, 1993.
- [Kurokawa et al., 2016] David Kurokawa, Ariel Procaccia, and Junxing Wang. When can the maximin share guaran- tee be guaranteed? In Proceedings of the AAAI Conference on Artificial Intelligence, volume 30, 2016.
- [Li et al., 2024] Zihan Li, Pasin Manurangsi, Jonathan Scar- lett, and Warut Suksompong. Complexity of round-robin allocation with potentially noisy queries. In International Symposium on Algorithmic Game Theory, pages 520-537. Springer, 2024.
- [Manurangsi and Suksompong, 2017] Pasin Manurangsi and Warut Suksompong. Asymptotic existence of fair divi- sions for groups. Mathematical Social Sciences, 89:100- 108, 2017.
- [Manurangsi and Suksompong, 2020] Pasin Manurangsi and Warut Suksompong. When do envy-free allocations exist? SIAM Journal on Discrete Mathematics, 34(3):1505-1521, January 2020.
- [Manurangsi and Suksompong, 2021] Pasin Manurangsi and Warut Suksompong. Closing gaps in asymptotic fair divi- sion. SIAM Journal on Discrete Mathematics, 35(2):668- 706, 2021.
- [Manurangsi and Suksompong, 2025] Pasin Manurangsi and Warut Suksompong. Asymptotic fair division: Chores are easier than goods. In James Kwok, editor, Proceedings of the Thirty-Fourth International Joint Conference on Ar- tificial Intelligence, IJCAI-25, pages 3988-3995. Interna- tional Joint Conferences on Artificial Intelligence Organi- zation, 8 2025. Main Track.
- [Manurangsi et al., 2025] Pasin Manurangsi, Warut Suk- sompong, and Tomohiko Yokoyama. Asymptotic analysis of weighted fair division. In James Kwok, editor, Proceed- ings of the Thirty-Fourth International Joint Conference on Artificial Intelligence, IJCAI-25, pages 3979-3987. In- ternational Joint Conferences on Artificial Intelligence Or- ganization, 8 2025. Main Track. IJCAI
- [Suksompong, 2016] Warut Suksompong. Asymptotic exis- tence of proportionally fair allocations. Mathematical So- cial Sciences, 81:62-65, 2016.
- [Zeng and Psomas, 2020] David Zeng and Alexandros Pso- mas. Fairness-efficiency tradeoffs in dynamic fair division. In Proceedings of the 21st ACM Conference on Economics and Computation, pages 911-912, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Fair and efficient allocation of indivisible resources is a central area at the intersection of economics, algorithmic game theory and computational social choice ([Amanatidis et al., 2023] surveys the most popular directions and seminal results). In this paper, we focus on the particular problem of dividing typical or random instances (initiated in [Dickerson et al., 2014]), where agent utilities for the resources are drawn from certain distributions rather than being arbitrary. We assume that we are given oracle access to a distribution Uj (that has minimal technical assumptions described in Section 1.1) corresponding to every item j. Every agent's value for item j is sampled independently from its distribution Uj. This model reasonably captures several real world allocation scenarios. For example, while distributing assets among companies, every company's value for a particular asset would be similar, and can be assumed to belong to some natural distribution with bounded upper and lower values. The same is true for resources like public housing, rent, or time to serve online server requests. If we can guarantee, with high probability, the existence of fair and economically efficient allocations for random instances drawn in this way, and further give computationally efficient algorithms to find these, then we would essentially be able to quickly resolve such real world fair allocation problems with high probability. As there are simple counterexamples to show that fair and efficient allocations may not always exist (consider 2 items and 1 agent), existence with high probability is a strong guarantee. This implication is a compelling reason to pursue this direction of research and the motivation for this paper as well.
The setting of random instances was initiated in [Dickerson et al., 2014]. They studied the formal model of identical goods, where the distributions for the utilities of all the items are identical. In the initial work, they proved the existence of envy-free fair allocations when the number of items m is asymptotically large compared to the number of agents n, that is m = Ω(n logn). Their work was followed up by [Manurangsi and Suksompong, 2020] and [Manurangsi and Suksompong, 2021] for the same setting of identical distributions. They closed the gaps in our understanding this setting, and proved tight existence results for fair allocations.
In this paper, we extend this series of works by modelling the class of non-identical distributions, where every item is associated with its own distinct distribution, and show several existence results. First, we show that envy-free fair allocations exist when the number of items m is larger than the number of agents n, that is, m = Ω(n log n) (Theorem 1.1). For small m, when m = O(n), we show envy-fair allocations exist when m ≥ 5n and n divides m (Theorem 3.2), and proportional allocations exist when n ≤ m ≤ 2n and the means of all the item distributions are at most 1/2 (Theorem 3.1), or when m ≥ cn for some constant c, that depends on an upper bound of the means of all the item distributions (Theorem 1.4). The overarching techniques to prove these results are similar as the identical case, but the analysis is far more involved. The assumption of identical distributions provides strong symmetry assumptions that are critically used in prior work. The most similar and straightforward is the case for large m = Ω(n log n). As in the identical case, we show that there is a gap between the expected utility of an item to an agent who gets the item and that to an agent who does not get it. These values are now different for each item in our nonidentical case. We can easily show that there is a gap between the means of these expected values across all items. We then essentially perform the same analysis as the identical case in [Dickerson et al., 2014], by replacing the identical expected values in that analysis by these means of the non-identical expected values.
The linear regime m = Θ(n) is more involved. In the identical items setting, [Manurangsi and Suksompong, 2020; Manurangsi and Suksompong, 2021] reduce the existence problem of envy-free allocations to the existence of certain many-to-one matchings in certain random bipartite graphs called the Erd˝os-R´enyi graphs. In these graphs, every edge exists with the same probability. Standard known results from combinatorics show when such matchings exist in these graphs. The identical items fair allocation case reduces to this exact problem, hence the known results directly prove the envy-free results. Our non-identical model reduces to a random graph where edges correspond to non-identical itemdependent existence probabilities, and is no longer standard Erd˝os-R´enyi. After constructing this graph, our main technical step is to extend the standard combinatorics result to this heterogenous setting. This yields our envy-free fairness results for linear m ≥ 5n.
Now we overview our proportionality results. For the m ≥ cn case, we follow a similar framework as [Manurangsi and Suksompong, 2021]. First, by a simple pigeonhole principle argument, we prove the sufficiency of the condition on the means of the distributions. For the case when this condition is satisfied, we design a two-stage matching algorithm to constructively prove that a proportional allocation exists. In the first stage, the algorithm constructs a bipartite graph that connects every agent i with any good j only if ui(j) ≥ τj, where τj is carefully chosen so that Pr[ui(j) ≥ τj ] is exactly log n+ω(1)/n. Our extended proofs for the Erd˝os-R´enyi graphs then imply the existence of certain many-to-one matchings. Now, for the case where m > 1.9n, we show by simple concentration bounds that this matching is already proportional. When m ≤ 1.9n, we need a tighter analysis. This is the most technically involved part of our paper. The difficulty of this case is intuitive, as when m is large, every agent gets a large number of items. Even with non-identical items, the process of combining a large number of them provides some identical measures, like the mean of the expected utility across all items. These measures can be placeholders for the metrics used in the identical items analysis, and make similar proofs go through. We prove a stronger version of the standard Berry-Esseen theorem, extending it to independent but not necessarily identically distributed summands; using this, we show that at most 0.6n agents remain without a proportional share after the first stage. For these agents, we construct a residual graph with the remaining agents and items and use this to complete a proportional allocation.
Other works on the random instances model inspired us to investigate our model in two further ways. [Bai and G¨olz, 2022] extended research on the randommodel to the asymmetric agents case, where each agent was associated with a distinct distribution and drew utilities for all the items independently from their own distribution. They also additionally explore Pareto optimality, a notion of economic efficiency. We also investigated economic efficiency, and observed that our algorithm for large number of items m = Ω(n logn) case assigns every item to an agent who draws the highest value for it, hence gives Pareto optimality by design. Second, [Manurangsi and Suksompong, 2021] study efficient computation of these allocations. They show that an envy-free allocation can be obtained with a round robin algorithm for m = Ω(n log n/ log log n). [Li et al., 2024] perform a detailed analysis of the round robin algorithm, and show that it has complexity O(mn +mlogm) when agent preferences are uniform, identical and random. These works inspired us to study efficient computation. This seems especially important as the existence results are for the asymptotic regime. Our algorithm for the m = Ω(n log n) case has O(mn) time complexity, as for every one of the m items, we draw from their distributions n times, to decide which agent receives it. Note that there is a natural lower bound of O(m) for this problem, as every item needs to be processed once to decide which agent it gets assigned to. We explore if we can match this lower bound. We considered the natural extension to sampling algorithms, where instead of drawing all the n values, we sample a few agents and give the item to the agent who drew the highest utility among these. We show three trade-off results between time and fairness guarantees: by sampling ˜O(m) samples, we obtain 0.8-approximate fair and 0.9-approximately efficient allocations, with high probability (Theorem 1.3). These guarantees can be improved for the more restricted class of discrete distributions (Theorem 1.2), or by drawing more samples (Theorem 4.1).
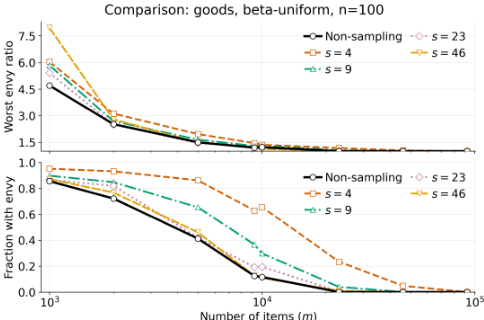
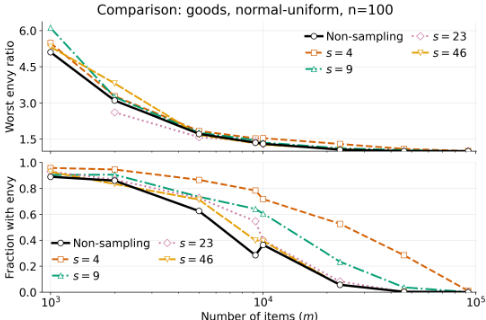
We now describe our final set of observations. We empirically evaluated both the non-sampling and sampling algorithm on finite instances to understand how quickly the asymptotic behavior manifests. Note that our proofs for the linear m = O(n) case are non-constructive, hence there is no method to experimentally simulate these, hence we simulate our algorithm used in the m = Ω(n log n) case. For various values of m and for n = 100, we sampled utilities from either the beta, truncated normal, or uniform distributions. The details of our set up are in Section 5. For each instance, we run our algorithm, and record three parameters, (i) envy ratios that capture how much any agent values someone else's set compared to their own, (ii) the fraction of agents who have envy, and (iii) the highest welfare ratio, to understand how much we sacrifice in the total efficiency, to reduce time complexity by sampling. We observed that the envy ratio remains between 4 and 9 when m is small compared to n, but vanishes when m is about 100 times higher than n. We also found that in practice, after sampling about 5 lnn values for every item, the sampling and non-sampling algorithms become nearly indistinguishable in terms of the allocations they yield. Finally, the economic efficiency with the sampling algorithm remains higher than 0.85 times that of the non-sampling one, even when we sample as low as 4 samples per item, and goes to above 0.95 times for 23 or more samples.
Other related work. There are several other works that study the random model. The case of identical undesirable resources or chores is studied by [Manurangsi and Suksompong, 2025]. They showed stronger positive results and proved that the chores case was easier than goods. [Manurangsi et al., 2025] explore a general setting with random identical distributions for utilities, but with weighted agents where each agent has a scalar value called a weight assigned to them. In this problem, fairness notions are generalized to capture the idea that agents receive utilities proportional to their weights. Related works studying similar models are [Bai et al., 2022], which studies fairness in an interesting smoothed utilities model, and [Zeng and Psomas, 2020], which studies fair and efficient allocations in online settings and asymmetric agents, and give non-asymptotic results. A series of works studies other notions of fairness with identical items and symmetric agents. [Amanatidis et al., 2017] study maximin share fairness with uniform distributions, [Suksompong, 2016] study proportionality, and [Manurangsi and Suksompong, 2017] study group envy-free fairness, when items are assigned to groups of agents instead of individually. [Kurokawa et al., 2016] studied this problem for maximin share fairness in the more general case of asymmetric agents. [Farhadi et al., 2019] study maximin fairness in the setting with asymmetric agent distributions and weighted agents.
In the remaining paper, we discuss our main results for each case, large and small number of goods - Theorem 3.1 for a proportional allocation when there are n ≤ m ≤ 2n goods in Section 3, Theorem 3.2 for envy-free allocations with small number of goods in Section 3.2, and Theorem 4.1, our sampling algorithm for large number of items with continuous distributions and bounded means in Section 4. We also describe our empirical evaluations in Section 5. An extended version of this paper with the remaining results can be accessed at: https://arxiv.org/abs/2512.17238.
Theorem 1.1. [Large number of goods] When the number of goods is large, that is, n = O(m/ logm), then, with probability (1 - 1/m) , an envy-free and maximum social welfare allocation exists as m → ∞.
We write n = O(m/ log m) and m → ∞ to emphasize that the result holds even with a finite number of agents as long as the number of items goes to infinity.
Theorem 1.2. [Sampling from discrete distributions] Suppose the utility of each good for every agent is drawn from a discrete distribution with finite support in [0, 1]. Let m = Ω (n log n) and the number of sampled agents for each good s = 2 logm αmin . Then, with high probability, a maximum social welfare and envy-free online allocation of goods exists as n → ∞.
Theorem 1.3. [Sampling with constant approximation] For the allocation problem as described in Section 1.1, let m = Ω (n log n) and the number of sampled agents for each good s = 20 logm αmin . Then, with high probability, a 0.9-approx. maximum social welfare and 0.8-approx. envy-free online allocation of goods exists as n → ∞.
Theorem 1.4. [Proportionality for linearly many goods] Let c < 1 be such that E[Uj] ≤ c for all j ∈ M. If r = ⌈2 ·
3+c 1-c ⌉ and m ≥ rn, then with high probability, a proportional allocation exists as n → ∞.
1.1 Our Model
Fair allocation problem. We consider the problem of dividing m indivisible and non-identical items among n agents, according to certain fairness and efficiency notions (defined shortly). We assume the items are goods, meaning they are non-negatively valued by all the agents. Formally, let N = {1, . . . , n} be the set of agents and M = {1, . . . , m} be the set of goods. For each (i, j) ∈ (N ×M), ui(j) ∈ [0, 1] denotes the utility of good j for agent i. The utilities are assumed to be additive, that is, for all M ′ ⊆ M, ui(M ′ ) = ∑j∈M ′ ui(j). The solution of the fair allocation problem is an allocation or a partition of M into n disjoint subsets. Formally, we denote an allocation by A = (A1, . . . , An), where Ai is the bundle or subset of M allocated to agent i. Thus ∪iAi = M and Ai ∩ Ai′ = ϕ for all i and i′ ∈ N. In this paper, we will study the setting where each utility ui(j) is sampled randomly from a known distribution Uj, described below.
Distributions of utilities. For each good j ∈ M, we assume that there exists a distribution Uj supported on [0, 1], such that ui(j) ∼ Uj independently for each i ∈ N. Computationally, we assume a black box for each Uj that allows us to sample once from the distribution in O(1) time. The distributions have the following properties. Each Uj is non-atomic, i.e., PrX∼Uj [X = x] = 0 for all x ∈ [0, 1]. Further, every Uj is (αj , βj )-PDF bounded, meaning the density function of each Uj has value between αj and βj at every point in its support, for some constants αj, βj > 0. Here the αj and βj may be distinct for each j ∈M.
Fairness and efficiency notions. We study the existence and computability of the following three types of allocations. An allocation A is envy-free if for all pairs of agents i, i′ ∈ N, it holds that ui(Ai) ≥ ui(Ai′). The envy of any agent i towards another agent i′ is max{0, ui(Ai′) - ui(Ai)}. An allocation A is proportional if for all agents i ∈ N, it holds that ui(Ai) ≥ ui(M)/n. Finally, an allocation A has maximum social welfare if it maximizes the sum of agent values for their own shares. Formally, if A is the set of all allocations of M, then A ∈ argmaxA ∑i ui(Ai). We also consider equivalent approximation notions for these. An allocation A is c-approximate envy-free (c < 1) if for all pairs of agents i, i′ ∈ N, it holds that ui(Ai) ≥ c · ui(Ai′). Finally, an allocation A has c-approximate maximum social welfare (c < 1) if some allocation A′ has maximum social welfare and ∑i ui(Ai) ≥ c · ∑i ui(A′i ).
2 Matchings in RandomBipartite Graphs
We now discuss the random graphs and their properties used in analyzing the case of small number of items.
Let G(nL, nR, p) denote the distribution of random bipartite graphs with nL left vertices, nR right vertices, and p being the probability that there exists an edge between any pair of left and right vertices. A graph sampled from this distribution is called an Erd˝os-R´enyi random bipartite graph. The following result is classical and well-known.
Lemma 2.1. [Erd˝os and Renyi, 1964]. Let G ∼ G(n, n, p) such that p = (logn+ω(1))/n. Then, with high probability, G contains a perfect matching.
We prove an extension to Lemma 2.1 where the probability of edges depends on the right vertices.
Theorem 2.1. Let G ∼ G(n, n, {pj}j∈[n]) be a random bipartite graph, say G = ({li}i∈[n], {rj}j∈[n],E). Each edge (li, rj) ∈ E independently with probability pj. Define pmin := minj∈[n] pj. If pmin ≥ (logn+ω(1))/n, then with high probability G contains a perfect matching.
Proof. Given G, define a new random bipartite graph G′ = ({li}i∈[n], {ri}i∈[n],E′ ) as follows. If (li, rj) ∈ E, then keep the edge (li, rj) in G′ with probability pmin/pj, and remove it with probability 1 - pmin/pj. Observe that for each (li, rj), Pr[(li, rj) ∈ E′ ] = Pr[(li, rj) ∈ E]Pr[(li, rj) ∈ E′ | (li, rj) ∈ E] = pj · pmin/pj = pmin.
Thus, G′ is a random bipartite graph where each edge is included independently with constant probability pmin. Since pmin ≥ (log n+ω(1))/n, from Lemma 2.1, G′ contains a perfect matching with high probability. Further, E′ ⊆ E, so G also has a perfect matching with high probability.
Next, we state the following known result, which proves some sufficient conditions that random graphs must have to satisfy Hall's condition for perfect matchings.
Lemma 2.2. [Manurangsi and Suksompong, 2021]. Let G = (A, B, E) be a graph sampled from the Erd˝os-R´enyi random bipartite graph distribution G(n, q, p), where p ≥ 0.5 and 0.9n ≤ q ≤ n. Then with high probability, for every S ⊆ A of size at most 0.6n, we have |ZG(S)| ≥ |S|, where ZG(S) is the set of vertices adjacent to S in graph G.
Finally, we talk about right saturated r-matchings.
Definition 2.1. An r-matching of a bipartite graph G = (L,R,E) is a subset of edges E′ ⊆ E such that the subgraph G′ = (L, R, E′ ) has degree at most r for vertices in L and degree at most 1 for vertices in R.
Definition 2.2. A right-saturated r-matching of a bipartite graph G = (L,R,E) is a subset of edges E′ ⊆ E such that the subgraph G′ = (L,R,E′ ) has degree at most r for vertices in L and degree exactly 1 for vertices in R. It is said to be perfect if the subgraph G′ has degree exactly r for vertices in L and degree exactly 1 for vertices in R
Lemma 2.3. Let G ∼ G(n, m, p) such that p = (log n+ω(1))/n and m = rn. Then, with high probability, G contains a perfect r-matching.
A simple graph construction, where the new graph contains r copies of all the left vertices in G, followed by showing that each set of left vertices forms a perfect matching with the right vertices, suffices to prove the lemma. A similar reduction, by adding n - m dummy right vertices and edges to these independently with probability p, helps to prove the following.
Lemma 2.4. Let G ∼ G(n, m, p) such that p = (log n+ω(1))/n and n > m. Then, with high probability, G contains a right saturated matching.
Algorithm 1 Proportional Algorithm for n ≤ m ≤ 2n
1: Input: N,M, {ui}i∈N 2: M 0 := first n items inM, M 1 :=M \M 0 . 3: τj ← 1- 1.1 logn αjn , ∀j ∈M 4: E≥τ ← {(i, j) ∈ N ×M 0 | ui(j) ≥ τj} 5: if G≥τ(N,M 0 ,E≥τ) has perfect matching then 6: (M 0 1 , . . . ,M 0 n ) ← any perfect matching of G≥τ 7: N vio ← {i ∈ N | ui(M 0 i ) < ui(M) n } 8: Efix ← {(i, j)∈N vio×M1 |ui(j)≥ ui(M) n -ui(M0 i )} 9: if Gfix (N vio ,M1 ,Efix ) has |N vio | size matching then 10: (M 1 1 , . . . ,M 1 n ) ← any such matching 11: return (M 0 1 ∪M 1 1 , . . . ,M 0 n ∪M 1 n ) 12: end if 13: end if3 Small Number of Goods
3.1 Proportionality for Small Number of Goods
Theorem 3.1. [Proportionality for small number of goods] For goods, if n ≤ m ≤ 2n and for all j, Uj has mean at most 1/2, then, with high probability, a proportional allocation always exists as n → ∞.
The assumption that each distribution Uj has a mean at most 1/2 is crucial to ensure the existence of a proportional allocation for all n ≤ m ≤ 2n with high probability. Suppose instead Uj has mean 1/2+εj for some constant εj > 0, and set m = 2n - 1. Then, the expected utilities satisfy E[ui(M)] = n (1+ 1n ∑j εj - o(1)). By standard Chernoff and union bounds, with high probability, all agents simultaneously have ui(M) > n. In such cases, no proportional allocation exists since at least one agent must receive at most one item (by the pigeonhole principle), but each item has value at most 1, contradicting proportionality.
Proof. Consider the graph G≥τ = {N,M 0 ,E≥τ} defined in the first stage of Algorithm 1 with τj = 1 - 1.1 log n αjn . Since Theorem 2.1 immediately implies that a perfect matching exists in G≥τ with high probability, we will assume that this is the case from now on. Also, using Hoeffding's inequality [Hoeffding, 1963], we can show that
holds with high probability. Hence, we will also assume this from now on. Now, let q = m - n (so 0 ≤ q ≤ n). We make two cases based on the value of q.
Case 1: q < 0.9n. For sufficiently large n, we have from equation (1), ui(M) n ≤ 0.996 and for sufficiently large n, τj > 0.996. Hence, τj > ui(M) n , ∀j ∈ M for all i ∈ N. Hence, running only the first part of the algorithm gives a proportional allocation, i.e., the partial allocation (M 0 1 , . . . ,M 0 n ) is already proportional.
Case 2: q ≥ 0.9n. Define G1≥ 0.5 β = (N,M 1 , E1≥ 0.5 β ) such that (i, j) ∈ E1≥ 0.5 β if and only if ui(j) ≥ 0.5 βj . Let ZG(S)
denote the set of vertices adjacent to the vertices of the set S in graph G. We define two events E1 and E2 as follows. E1 occurs when |N vio | ≤ 0.6n, and E2 occurs when ∀S ⊆ N
We first prove that if E1 and E2 hold with high probability, then the algorithm outputs a proportional allocation. For sufficiently large n, ui(M) n = 1 + o(1) (using equation (1)) and 1 + o(1) < 0.5 βj + τj. Now, if E1 and E2 hold, due to Hall's Marriage Theorem, there exists a matching from N vio to M 1 that uses all vertices in N vio . And since ui(M) n < 0.5 βj + τj, ∀i ∈ N and ∀j ∈ M, the matching in G1≥ 0.5 β from N vio to
M 1 also is a matching in Gfix . The algorithm thus outputs a proportional allocation. Thus, proving that E1 and E2 hold with high probability suffices. We now proceed to show this.
Let fj denote the probability distribution function of Uj. Since fj(x) ≤ βj, ∀x ∈ [0, 1], Pr[ui(j) ≥ 0.5/βj ] ≥ 0.5. Hence, for G1≥ 0.5 β , Lemma 2.2, directly implies that E2 holds with high probability if E1 holds.
For showing E1, let Xj = ui(j) - µj. Thus E[Xj] = 0 and E[X2 j ] = σ2 j , where σj is the standard deviation of the distribution Uj . Also define ρj = E[|Xj |3 ]. Thus, E[X2 j ] = ∫ 1-µj -µj x2 fj(x)dx. Since αj ≤ fj(x) ≤ βj for every x ∈ [-µj , 1 - µj ],
Now, since µj ∈ [0, 1/2], we have 1/4 ≤ 1-3µj +3µ2j ≤ 1, which means αj
Now, consider the quantity ∑j ρj (∑j σ2 j )2 . By Lyapunov's moment inequality (see [Karr, 1993] Corollary 4.37, p.120), we have E[|Xj |3 ] ≤ E[X2 j ]3/2 = √E[X2 j ] E[X2 j ], so
where the first inequality follows from Lyapunov's inequality and the third inequality follows from equation (2). Thus
where αmin and βmax represent minj∈M(αj) and maxj∈M(βj) respectively. Now, we know that Pr[ui(M) ≤
nmin(τj)] ≥ Pr[∑mj=1 ui(j) ≤ m2 min(τj)] because m ≤ 2n. Rearranging the terms gives us Pr[ ui(M) n ≤ min(τj)] ≥ Pr[∑mj=1 Xj ≤ m2 min(τj) - ∑mj=1 µj]. Now ∑ µj ≤ m/2, as every distribution Uj has a mean at most 1/2, thus,
Now, let's define Sm = X1+···+Xm √σ2 1 +···+σ2m and let FS denote the cumulative distribution function of Sm. Let tn = - 1.1m log n 2n αmin 1 √σ2 1 +···+σ2m . Then
and using equation (2), tn ≥ - 1.1m log n 2n αmin 1 √mαmin/12 and t ≤ 0. Note also that tn tends to 0 as n gets sufficiently large.
Now, by [Esseen, 1942], for independent (not necessarily identically distributed) summands, we can say that, supx |FS(x) - Φ(x)| ≤ C0 · ∑j ρj (∑j σ2 j )3/2 , where Φ represents the PDF of the standard normal distribution. Hence, FS(tn) ≥ Φ(tn) - C0 · ∑j ρj (∑j σ2 j )3/2 . Using equation (3), FS(tn) ≥ Φ(tn) - C0 · 4√3βmax mαmin . Since, αmin and βmax are finite quantities, for sufficiently large n (and thus also m), and as tn tends to 0, the above equation becomes FS(tn) ≥ Φ(tn) - 0.04 ≥ 0.49 - 0.04. Thus, using equation (4), we get Pr [ ui(M) n ≤min(τj)] ≥ 0.45 for all agents i ∈ N, so each agent has at most 0.55 probability of being present in N vio . Hence, using standard concentration inequalities, |N vio | ≤ 0.6n with high probability.
Thus, the algorithm outputs a proportional allocation with high probability in both cases. This concludes our proof.
3.2 Envy-freeness for Small Number of Goods
Theorem 3.2. [Envy-freeness for small number of goods] When m ≥ 5n and m is divisible by n, then with high probability, an envy-free allocation exists as n → ∞.
Proof. Let m = xn for some x ∈ Z≥0. Let αmin = minj∈M αj and βmax = maxj∈M βj .
Construct a bipartite graph G = (N,M,E) where edges are given by:E = {(i, j) ∈ N ×M : ui(j) ≥ τj}
where τj := 1- 1.1 logn αjn and τ :=minj∈M τj = 1- 1.1 logn αminn . Let τ ′ := 1- 1 n4/x+ε for some ε > 0 (say ϵ = 0.1) and x ≥ 5. The graph G is an Erd˝os-R´enyi random graph with edge probabilities at least logn+ω(1) n , so by Lemma 2.3 with high probability, there exists a perfect x-matching corresponding to an allocation {A1, . . . , An} such that:
Now fix any pair i, i′ ∈ N. The probability that more than x2 goods in Ai have ui′ (j) > τ ′ is bounded by:
By union bound over all i, i′ ∈ N:
Hence, with high probability:
We want this to be at least 0. Thus,
For sufficiently large n, and x strictly greater than 4, 1 n4/x+ε ≥ 2.2 logn αminn .
The allocation (A1, . . . , An) is thus envy-free.
4 Large Number of Goods
We will assume the sampling model as follows. We assume that for each good j ∈ M, we sample a set Sj ⊂ N of s agents at random (uniformly). We assign each j to the agent in Sj who draws the highest value for it. We will show that this simple algorithm gives strong envy-free and maximum social welfare guarantees. Our model is as discussed in Section 1.1, with the following additional mild constraint. As long as we are guaranteed a constant upper bound (say µ < 1) on the means of the distributions of the goods, that is, µj < 1 for all goods j, we have the following result.
Theorem 4.1. [Sampling with near optimal guarantees] Let m = Ω(n log n) and the number of sampled agents for each good s = 2(logm)2 αmin . If, for all goods j, E[Uj] ≤ µ for some constant µ < 1, then, with high probability, a (1 - 1 log n )- approx. maximum social welfare and envy-free online allocation of goods exists as n → ∞.
Proof. For any good j,
By union bound over all goods,
where the last inequality is due to the chosen value of s. Thus, with high probability, for all goods, there is always at least one agent in the sampled set of agents that has value greater than or equal to 1 - 1 logn ≥ µ+1 2 (for sufficiently large n). Hence, the allocation is (1 - 1 log n )- maximum social welfare by construction. If good j is allocated to agent i (that is j ∈ Ai), we also know that with high probability ui(j) ≥ µ+1 2 . This in turn implies that, with high probability, E [ui(j)|j ∈ Ai] ≥ µ+1 2 . We now show that the allocation is EF with high probability. Define for fixed i ∈ N, j ∈ M:
Then ui(Ai) = ∑j∈M Xj i . Moreover,
Using linearity of expectation,
Now, define for i, i′ ∈ N, i ̸= i′ , and j ∈M:
Then ui(Ai′ ) = ∑j∈M Y j ii′ . Furthermore,
(since E [ui(j) | j /∈ Ai] ≤ µj ≤ µ, where the first inequality holds from the proof of Theorem 1.2.
Let Z j ii′ ∈ [0, 1] be such that E[Z j ii′ ] = µn , and Z j ii′ stochastically dominates Y j ii′ . Then, ∑j∈M E[Z j ii′ ] = µ· mn . Let Eii′ be the event that agent i envies agent i′ , i.e., ∑j∈M Y j ii′ > ∑j∈M Xj i . This occurs only if either of the two conditions below occur:
Let ϵ = 1-µ 2(µ+1) < 1, so ϵ < 1-µ 4µ also holds.
Since Xj i andZ j ii′ are independent across j, using Chernoff bounds:
Choose m large enough such that n ≤ ϵ2 3 · µ · m ln(2m3 ) (since m = Ω(n log n)). By the union bound:
Allocation A is EF if and only if no event Eii′ occurs. The probability that A is not EF is at most:
Thus, the probability that A is not EF vanishes as m → ∞ (n → ∞ and m = Ω(n log n)).
5 Empirical Results
We empirically evaluate both the non-sampling and sampling algorithm on finite instances to understand how quickly the asymptotic behaviour manifests. For each experiment, we fix n = 100 agents and vary the number of items m from 103 to 105 . Each item is associated with a distinct distribution drawn from one of these classes.
beta uniform mixture. For each item j, and for all agents i, ui(j) is drawn from the following distributions:
- a Beta(α, β) distribution, with α, β resampled independently for every item, or
- a Uniform[a, b] distribution, with a, b likewise resampled per item.
normal uniform mixture. For each item j, and for all agents i, ui(j) is drawn from the following distributions:
- a truncated (values are truncated to [0, 1] and then normalized so that Pr([0, 1]) = 1 for the distribution) Normal(µ, σ2 ) value, with (µ, σ) resampled independently per item, or
- a Uniform[a, b] value as above.
Agent utilities are then drawn from the item distributions, and allocations computed as per the maximum welfare producing algorithm. We record three quantities for each allocation: the worst envy ratio (the maximum envy relative to their own set's value over all agents), the fraction of agents with any envy, and the welfare ratio comparing sampled and nonsampled allocations. Each experimental point represents the average of these values over multiple independent trials.
Envy behaviour. Across all distributions, envy drops rapidly as m increases (Figures 1 and 2). Worst envy ratios begin between roughly 4-9 at m = 103 but approach 1 by about m = 5 × 10⁴ . The fraction of agents with any envy similarly falls to zero as m grows. Sampling introduces the expected trade-off: small s leads to higher envy at moderate m, but as soon as s ≥ 23 ≈ 5 lnn, it becomes nearly indistinguishable from the non-sampling algorithm.
Welfare under sampling. The welfare ratio between sampled and non-sampled allocations remains high throughout Even with s = 4, the ratio stays above 0.85, and for s = 23 or 46 it consistently exceeds 0.95 across all values of m. The ratio is essentially flat in m, indicating that the efficiency impact depends primarily on s.
From these observations, we can conclude that the sampling algorithm reaches the guarantees of the non-sampling algorithm for large m, thus offers a practical and scalable alternative for large fair division instances.
Acknowledgments
This work was supported by the NRF grant NRF-NRFI090005.
@inproceedings{ijcai2026p383,
  title     = {Fairly Dividing Non-identical Random Items: Just Sample or Match},
  author    = {Kale, Aprup and Garg, Navya and Kulkarni, Rucha},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {3444--3451},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/383},
  url       = {https://doi.org/10.24963/ijcai.2026/383},
}
TY - CPAPER TI - Fairly Dividing Non-identical Random Items: Just Sample or Match AU - Kale, Aprup AU - Garg, Navya AU - Kulkarni, Rucha T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 3444 EP - 3451 DO - 10.24963/ijcai.2026/383 UR - https://doi.org/10.24963/ijcai.2026/383 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





