
Computing Better Approximate Pure Nash Equilibria in Payoff-maximization Potential Games
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 3402-3409.
https://doi.org/10.24963/ijcai.2026/378
Keywords
- AI: Constraint Satisfaction and Optimization
- AI: Search
- Game Theory and Economic Paradigms: Noncooperative games
- AI: Game Theory and Economic Paradigms
Abstract
Potential games are a fundamental class of games in which pure Nash equilibria are guaranteed to exist, yet computing such equilibria is computationally intractable for several subclasses. This has led to extensive research on computing approximate pure Nash equilibria. In this paper, we study payoff-maximization potential games.
For these games, strong approximation guarantees are known only for restricted subclasses, most notably Pd--Flip games. We show that standard approaches based on unilateral improvement moves can fail to provide any finite approximation guarantee even for simple extensions of Pd--Flip games. To overcome this limitation, we propose an algorithmic framework based on coordinated moves by small groups of players, whose approximation guarantee and number of moves are controlled by two natural game parameters, the stretch and the spread, which are bounded for broad classes of games of interest. In the special case of Pd--Flip games, our framework can be configured to recover the existing algorithm, matching its approximation guarantee and the number of moves performed.
- 2: δ := (β + γ)(β + 2)|N |γ 1 ; 3: ∆ := |N |δσ 2 ; 4: for i ← 1 to |N | do 5: ûi := maxx∈S i ui([s I -i , x]); 6: end for 7: b0 := maxi∈N ûi; 8: m := ⌈log ∆ b0⌉ + 1; 9: for r ← 1 to m -1 do 10: br := ∆ 2 br-1; 11: end for 12: bm := 0; 13: B1 := {i ∈ N | ûi ∈ [b1, b0]}; : Br := {i ∈ N | ûi ∈ [br, br-1)}, for every r ∈ {2, . . . , m}; 15: s ← s I ; 16: τ ← ⟨s I ⟩; /* Phase 0 */ 17: while ∃ a k-group T ⊆ B1 that has a (1 + γ)-improving move do 18: Let r * ∈ arg maxr∈S T uT ([s T , r]); 19: s ← [s T , r * ]; 20: τ ← τ ⊕ s; 21: end while /* Phases 1, 2, . . . , m -1 */ 22: for r ← 1 to m -1 do 23: while ∃ a k-group T such that either T ⊆ Br+1 and T has a (1 + γ)-improving move or T ⊆ Br+1∪Br and T has a (β + γ)-improving move do 24: Let r * ∈ arg maxr∈S T uT ([s T , r]); 25: s ← [s T , r * ]; 26: τ ← τ ⊕ s; 27: end while 28: end for 29: return τ ;
- Phase r ∈ {1, . . . , m-1} (lines 23-27). The algorithm con- siders the two consecutive blocks B r and B r+1 and repeat- edly performs the following updates. If there exists a k-group T ⊆ B r+1 having a (1 + γ)-improving move, or a k-group T ⊆ B r ∪ B r+1 having a (β + γ)-improving move, then the strategy of T is updated to an optimal strategy. At the end of phase r, the resulting strategy profile is a (β+γ)-approximate k-optimal strategy for B r ∪ B r+1 and a (1 + γ)-approximate k-optimal strategy for B r+1 . References [Babichenko and Tamuz, 2016] Yakov Babichenko and Omer Tamuz. Graphical potential games. Journal Economic Theory, 163:889-899, 2016.
- [Balcan et al., 2013] Maria-Florina Balcan, Avrim Blum, and Yishay Mansour. Circumventing the price of anar- chy: Leading dynamics to good behavior. SIAM Journal of Computing, 42(1):230-264, 2013.
- [Bhalgat et al., 2010] Anand Bhalgat, Tanmoy Chakraborty, and Sanjeev Khanna. Approximating pure Nash equilib- rium in cut, party affiliation, and satisfiability games. In Proceedings of the 11th ACM Conference on Electronic Commerce (EC), pages 73-82, 2010.
- [Caragiannis and Fanelli, 2019] Ioannis Caragiannis and Angelo Fanelli. On approximate pure Nash equilibria in weighted congestion games with polynomial latencies. In Proceedings of the 46th International Colloquium on Automata, Languages, and Programming (ICALP), pages 133:1-133:12, 2019.
- [Caragiannis and Jiang, 2023] Ioannis Caragiannis and Zhile Jiang. Computing better approximate pure Nash equilib- ria in cut games via semidefinite programming. In Pro- ceedings of the 55th Annual ACM Symposium on Theory of Computing (STOC), pages 710-722, 2023.
- [Caragiannis et al., 2011] Ioannis Caragiannis, Angelo Fanelli, Nick Gravin, and Alexander Skopalik. Efficient computation of approximate pure Nash equilibria in congestion games. In Proceedings of the 52th Annual IEEE Symposium on Foundations of Computer Science (FOCS), pages 532-541, 2011.
- [Caragiannis et al., 2015] Ioannis Caragiannis, Angelo Fanelli, Nick Gravin, and Alexander Skopalik. Ap- proximate pure Nash equilibria in weighted congestion games: Existence, efficient computation, and structure. ACM Transactions on Economics and Computation, 3(1):2:1-2:32, 2015.
- [Caragiannis et al., 2017] Ioannis Caragiannis, Angelo Fanelli, and Nick Gravin. Short sequences of improve- ment moves lead to approximate equilibria in constraint satisfaction games. Algorithmica, 77(4):1143-1158, 2017.
- [Christodoulou et al., 2012] George Christodoulou, Va- hab S. Mirrokni, and Anastasios Sidiropoulos. Conver- gence and approximation in potential games. Theoretical Computer Science, 438:13-27, 2012.
- [Fabrikant et al., 2004] Alex Fabrikant, Christos H. Pa- padimitriou, and Kunal Talwar. The complexity of pure nash equilibria. In László Babai, editor, Proceedings of the 36th Annual ACM Symposium on Theory of Comput- ing, pages 604-612, 2004.
- [Feldotto et al., 2017] Matthias Feldotto, Martin Gairing, Grammateia Kotsialou, and Alexander Skopalik. Com- puting approximate pure Nash equilibria in Shapley value weighted congestion games. In Proceedings of the 11th International Conference on Web and Internet Economics (WINE), pages 191-204, 2017.
- [Giannakopoulos et al., 2022] Yiannis Giannakopoulos, Georgy Noarov, and Andreas S. Schulz. Computing approximate equilibria in weighted congestion games via best-responses. Mathematics of Operations Research, 47(1):643-664, 2022.
- [Hammersley and Clifford, 1971] John Michael Hammers- ley and Peter Clifford. Markov fields on finite graphs and lattices. 1971.
- [Johnson et al., 1988] David S. Johnson, Christos H. Pa- padimitriou, and Mihalis Yannakakis. How easy is lo- cal search? Journal of Computer and System Sciences, 37(1):79-100, 1988.
- [Koller and Friedman, 2009] Daphne Koller and Nir Fried- man. Probabilistic Graphical Models -Principles and Techniques. MIT Press, 2009.
- [Li and Marden, 2013] Na Li and Jason R. Marden. Design- ing games for distributed optimization. IEEE Journal of Selected Topics in Signal Processing, 7(2):230-242, 2013.
- [Marden et al., 2009] Jason R. Marden, Gürdal Arslan, and Jeff S. Shamma. Cooperative control and potential games. IEEE Transactions on Systems, Man, and Cybernetics, 39(6):1393-1407, 2009.
- [Monderer and Shapley, 1996] Dov Monderer and Lloyd S. Shapley. Potential games. Games and Economic Behavior, 14(1):124-143, 1996.
- [Pearce and Tambe, 2007] Jonathan P. Pearce and Milind Tambe. Quality guarantees on k-optimal solutions for dis- tributed constraint optimization problems. In Proceedings of the 20th International Joint Conference on Artificial In- telligence (IJCAI), pages 1446-1451, 2007. IJCAI
- [Ui, 2000] Takashi Ui. A Shapley value representation of po- tential games. Games and Economic Behavior, 31(1):121- 135, 2000.
- [Vijayalakshmi and Skopalik, 2020] Vipin Ravindran Vijay- alakshmi and Alexander Skopalik. Improving approximate pure nash equilibria in congestion games. In Proceedings of the 16th International Conference on Web and Internet Economics (WINE), pages 280-294, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Potential games [Monderer and Shapley, 1996] are a fundamental class of games in which pure Nash equilibria are guaranteed to exist. A defining feature of these games is the existence of a potential function that exactly captures individual incentives: whenever a player unilaterally changes strategy, the resulting change in the potential equals the change in that player's payoff. As a consequence, any sequence of unilateral improvement moves, where a player switches to a strategy with higher payoff, converges to a strategy profile that locally maximizes the potential function, and hence to a pure Nash equilibrium.
Beyond their elegant theoretical properties, potential games play a central role in modern AI. [Babichenko and Tamuz, 2016] establish a tight correspondence between graphical potential games and positive Markov Random Fields (MRFs) [Koller and Friedman, 2009]. In this correspondence, the game's potential function coincides exactly with the MRF's log-potential, as implied by the HammersleyClifford theorem [Hammersley and Clifford, 1971]. Consequently, pure Nash equilibria of the game coincide with local maxima of the MRF's log-potential, and thus with locally most probable configurations of the MRF. This connection establishes a direct bridge between equilibrium computation and probabilistic inference, enabling techniques from one domain to be systematically applied to the other.
Another important application area of potential games is distributed optimization. In this context, potential games provide a natural framework for modeling systems in which agents optimize local payoffs aligned with a global objective. [Marden et al., 2009] and [Li and Marden, 2013] show that many coordination tasks in multi-agent systems, such as consensus and coverage, can be formulated as potential games, where simple decentralized learning dynamics converge to Nash equilibria that are provably efficient, and in some cases globally optimal.
Given their wide-ranging applications, a fundamental computational question is how to efficiently compute a pure Nash equilibrium in a potential game. Although a pure Nash equilibrium is guaranteed to exist and can be reached through any sequence of improving steps, this simple approach may require exponential time in the worst case. More generally, the problem of computing a pure Nash equilibrium in potential games is PLS-complete even for many natural subclasses (e.g., [Fabrikant et al., 2004; Johnson et al., 1988]). This has led to considerable interest in computing approximate pure Nash equilibria. Informally, an α-approximate pure Nash equilibrium is a strategy profile in which no player can improve its payoff by more than a multiplicative factor α ≥ 1. A pure Nash equilibrium corresponds to the case α = 1. The goal of this line of research is to design polynomial-time algorithms that compute equilibria with the smallest possible approximation factor.
Prior work on approximate equilibrium computation has considered both payoff-maximization and cost-minimization potential games. The former have been studied through Pd-FLIP games [Bhalgat et al., 2010; Caragiannis et al., 2017], a well-structured subclass of constraint satisfaction games, in which players seek to satisfy as many Boolean constraints as possible. The latter have been studied through congestion games with polynomial latencies [Caragiannis et al., 2011; Caragiannis et al., 2015; Feldotto et al., 2017; Caragiannis and Fanelli, 2019; Vijayalakshmi and Skopalik, 2020; Giannakopoulos et al., 2022], in which players seek to minimize individual latency costs. Algorithms for both classes share a similar high-level structure, consisting of suitably scheduled sequences of unilateral improvement moves. However, the analysis techniques diverge significantly between the two settings, reflecting the different nature of their objectives. Throughout the paper, the term potential game refers to a payoff-maximization potential game. The qualifiers payoffmaximization and cost-minimization are used only when a distinction between the two settings is required.
Constraint satisfaction games (see Example 1 for a formal definition) form a restricted subclass of potential games, characterized by binary strategies, with each player's payoff given by the number of satisfied Boolean constraints in which it participates. Within this class, the literature has focused on Pd-FLIP games [Bhalgat et al., 2010; Caragiannis et al., 2017], which impose strong structural properties: each constraint has arity at most d, and any unsatisfied constraint can be satisfied by changing the strategy of any participating player. Leveraging these properties, approximate pure Nash equilibria can be computed through suitably scheduled sequences of unilateral improvement moves, with both the approximation guarantee and the number of required moves bounded by a polynomial in the number of players and d. More precisely, the approximation guarantee is quantified by the worst-case ratio between the maximum potential value and the potential value of a sufficiently accurate approximate pure Nash equilibrium, that is, one that is close enough to an exact equilibrium. Beyond the Pd-FLIP setting, however, such a guarantee becomes arbitrarily weak: even in simple potential games (see Example 2), approximate pure Nash equilibria may have very low potential values relative to the maximum potential value, no matter how accurate they are, resulting in an arbitrarily large approximation guarantee.
In this work, we move beyond the restrictive Pd-FLIP setting and develop a general framework for computing approximate pure Nash equilibria in arbitrary potential games. To this end, we adopt the characterization of potential games introduced by [Ui, 2000], which expresses payoffs in terms of a family of interaction functions over subsets of players. Building on this representation, we propose an algorithmic scheme that extends the phase-based improvement approach of [Caragiannis et al., 2017] to the general setting.
To achieve meaningful approximation guarantees beyond the Pd-FLIP setting, we introduce a novel approach: the use of coordinated moves by small groups of players, rather than unilateral moves. Such moves are essential to escape lowquality local optima and to obtain meaningful approximation guarantees in general potential games, where standard unilateral improvement dynamics provably fail (a formal treatment of group moves is deferred to Section 3).
The major contribution of this work is an algorithm (Algorithm 1) that, given as input a potential game G, an initial state, an integer group-size parameter k ≥ 1, and an accuracy parameter γ ∈ (0, 1], and instantiated with parameters β, σ ≥ 1 satisfying β ≥ Stretchk1+γ (G) and σ ≥ Γ(G), constructs a sequence of moves by groups of at most k players, each improving the "payoff" of the participating group by a factor greater than 1 + γ, leading from the given initial state to a (β + 3γ)-approximate pure Nash equilibrium (Theorem 3). Here, Stretchk1+γ (G) and Γ(G) denote two gamedependent parameters, called the (1 + γ, k)-stretch and the spread of the game, respectively. Informally, the (1 + γ, k)- stretch captures the worst-case ratio between the maximum potential value of the game and the potential value of any state from which no group of at most k players can improve its "payoff" by a factor greater than 1 + γ. The spread, instead, captures the worst-case ratio between the maximum payoff attainable by a player and the minimum payoff that the player can guarantee for itself regardless of the strategies chosen by the other players. The length of the resulting sequence of moves is polynomial in β, σ, and the logarithm of the maximum payoff attainable by any player.
We further show (Theorem 4) that the last state of the sequence of moves constructed by the algorithm satisfies a stronger stability property: it is stable against coordinated moves by any group of at most k players aiming to improve its "payoff" by a factor greater than β+3γ. This stronger notion of stability is not guaranteed by the algorithm of [Caragiannis et al., 2017] for Pd-FLIP games, which only ensures stability with respect to unilateral moves.
Finally, we establish (Theorem 5) an explicit upper bound on the (1 + γ, k)-stretch of every potential game G of degree d ≥ 2 (the largest arity among its interaction functions), valid for every γ ≥ 0 and every integer k ≥ d, so that the algorithm's parameter β can be safely set to this bound. We remark that this latter result is closely related to the quality guarantees for k-optimal solutions in distributed constraint optimization problems (DCOPs) derived by [Pearce and Tambe, 2007].
When applied to Pd-FLIP games with k = 1, our algorithm recovers the same approximation guarantee and the same bound on the length of the sequence of moves as the algorithm of [Caragiannis et al., 2017].
2 Preliminaries
Strategic Games. A strategic game G is a tuple ⟨N, (Si)i∈N, (ui)i∈N⟩, where N is the finite and non-empty set of players, and each Si is the finite and non-empty set of strategies of player i. Every player i is associated with a payoff function ui : SN →R, where SN = S1×S2×. . .×S|N| represents the set of strategy profiles (or states) of G. The class of all strategic games is denoted by SG. The notation SG+ ⊂ SG refers to the class of potential games with nonnegative payoffs, while SG++ ⊂ SG+ denotes the subclass of games satisfying the following property: for every player i and every choice of strategies of the other players, there exists a strategy that guarantees player i a strictly positive payoff. Note that this condition is weaker than requiring that every player receives a strictly positive payoff in every state.
Notation for Strategy Profiles. The notion of strategy profiles extends naturally to any subset of players. Consider a strategic game ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG. For every nonempty subset P ⊆ N, SP = ∏j∈P Sj denotes the set of strategy profiles (or simply strategies) of P . Recall that, when P = N, SP corresponds to the set of states of G. Moreover, S{i} coincides with Si. For completeness, S∅ = {⊥}. Elements of SP are denoted by bold lowercase letters such as s, r, x, y, z.
Additional notation is introduced to represent strategy profiles in a more expressive and concise manner. For every subset Q ⊆ P ⊆ N and s ∈ SP , let sQ ∈ SQ be the restriction of s to Q; that is, sQ retains only the components of s corresponding to the players in Q. Note that if Q = ∅, then sQ =⊥. For every P ⊆ N, s ∈ SN\P , and s′ ∈ SP , let [s, s′ ] ∈ SN denote the state defined as follows: if P ̸= ∅ and P ̸= N, then [s, s′ ] = ¯s ∈ SN, where ¯s{j} = s{j} for every j ∈ N\P, and ¯s{j} = s′ {j} for every j ∈ P; if P = ∅, then [s, s′ ] = [s, ⊥] = s; and if P = N, then [s, s′ ] = [⊥, s′ ] = s′ . To simplify the notation for sP and SP , the subscript i is used in place of {i}, and P is used in place of N\P. *
Moves and Trajectories. Consider a strategic game G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG. For every player i ∈ N and pair of states s, ¯s ∈ SN, with s ̸= ¯s, the ordered pair (s, ¯s), where ¯s = [s i, s′ ] for some s′ ∈ Si, represents a move (i.e., a strategy change) by player i from s. The move is said to be α-improving, for α ≥ 1, if ui(¯s) > αui(s); in this case, s′ is called an α-improving strategy for player i at s. Note that an α-improving move (strategy) is also an α′ -improving move (strategy), for every α > α′ ≥ 1.
A trajectory τ starting at state s0 and ending at state sh is a sequence τ = ⟨s0 , s1 , . . . , sh ⟩ of h+1 ≥ 1 states such that, if h ≥ 1, the pair (st , st+1 ) is a move by some player, for every t ∈ {0, 1, . . . , h - 1}. The length of τ is defined as h ≥ 0. If h ≥ 1, the trajectory τ is called α-improving if every move in the sequence is α-improving.
Approximate Equilibria. Consider a strategic game G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG+. † For any α ≥ 1, a state s ∈ SN is called an α-approximate pure Nash equilibrium of G if no α-improving move exists from s, i.e., for every i ∈ N and every s′ ∈ Si, it holds that ui([s i, s′ ]) ≤ αui(s). If α = 1, s is simply called a pure Nash equilibrium. The set of all α-approximate pure Nash equilibria of G is denoted by Eα (G) ⊆ SN. Observe that the relation Eα′ (G) ⊆ Eα (G) holds for every α ≥ α′ ≥ 1.
Definition 1 ([Monderer and Shapley, 1996]). A strategic game G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG is called a potential game if there exists a potential function V : SN → R
for every i ∈ N, s ∈ SN, s′ ∈ Si. The class of potential games is denoted by PG.
A key property of a potential game G with potential function V is that E1 (G) ̸= ∅, meaning that at least one pure Nash equilibrium exists. Indeed, from equation (1), we know that V strictly increases along any 1-improving trajectory. Therefore, no state can appear more than once in such a trajectory.
* Hence, Si = S{i} and S P = SN\P . The same simplifications apply to sP .
† The presence of both negative and non-negative payoffs renders the notion of approximate pure Nash equilibrium meaningless.
Since the set of states SN is finite, it follows that every improving trajectory visits only finitely many states, and thus has finite length. Consider an improving trajectory of maximal length (i.e., it cannot be extended further). By definition, its final state admits no further 1-improving moves and is therefore a pure Nash equilibrium.
The theorem below characterizes potential games.
Theorem 1 ([Ui, 2000]). G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG is a potential game if and only if there exist interaction functions {ΨP | ΨP : SP → R, P ∈ I}, where I ⊆ 2N+ ‡ is a collection of interaction sets, such that
for every i ∈ N and s ∈ SN. A potential function of G is given by V (s) = ∑T∈I ΨT (sT ).
Building on the structural characterization provided by Theorem 1, we introduce the representation of potential games adopted throughout the paper, together with the notions of arity and degree.
Our representation of potential games. Motivated by the characterization given in Theorem 1, throughout the paper we consider potential games represented explicitly by a family of interaction functions. Formally, a game in PG is specified by a tuple
where I ⊆ 2N+ is a collection of interaction sets, and for each P ∈ I, the function ΨP : SP → R is an interaction function as described in Theorem 1. Throughout the paper, only the components of the tuple G that are relevant to the context are specified. Whenever a component of the tuple is not needed, it will be denoted by a placeholder ·. For instance, the notation G = ⟨N, ·, ·, (Si)i∈N, (ui)i∈N⟩ is used when the interaction structure and the interaction functions are not explicitly needed. The symbol PG+ ⊂ PG denotes the class of potential games whose interaction functions are nonnegative, while PG++ ⊂ PG+ denotes the subclass of games satisfying the following property: for every player i and every choice of strategies of the other players, there exists a strategy that guarantees player i a strictly positive payoff. Note that PG++ ⊂ SG++.
Arity and game degree. Consider a potential game G = ⟨·, I, (ΨP )P∈I, ·, ·⟩ ∈ PG. The arity of an interaction function ΨP , with P ∈ I, is the number of players involved in the interaction, i.e., |P|. The degree of the game G is the maximum arity over all interaction functions, i.e., maxP∈I |P|.
The following example introduces constraint satisfaction games and their Pd-FLIP subclass, two canonical examples of potential games, and illustrates how they can be naturally expressed in terms of the interaction functions of Theorem 1.
Example 1 (Constraint Satisfaction Games [Bhalgat et al., 2010; Caragiannis et al., 2017]). A constraint satisfaction game is a strategic game G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG in which each player i has a binary strategy set Si = {true, false}. The game is additionally specified by a family C of Boolean constraints (also called clauses) over the set of players. Each constraint C ∈ C involves a subset of players N(C) ⊆ N and is defined as a Boolean function C : SN(C) → {true, false}. The quantity |N(C)| is called the arity of C. Given a strategy profile s ∈ SN, a constraint C is said to be satisfied if C(sN(C)) = true, and unsatisfied otherwise. Each constraint C is associated with a positive weight wC > 0. Its value under s is defined as valueC(sN(C)) = wC if C is satisfied, and valueC(sN(C)) = 0 otherwise. The payoff of player i under s is then given by ui(s) = ∑C∈C, i∈N(C) valueC(sN(C)).
‡ 2N+ denotes the family of all non-empty subsets of N.
Constraint satisfaction games are potential games, which implies that the players' payoffs can be expressed in terms of the interaction functions of Theorem 1. Indeed, it suffices to set I = {N(C) | C ∈ C} and ΨN(C)(sN(C)) = valueC(sN(C)) for every C ∈ C. Thus, each clause corresponds naturally to an interaction set, and its value to the associated interaction function.
Pd-FLIP games form a subclass of constraint satisfaction games such that (i) every constraint has arity at most d ≥ 1, and (ii) every unsatisfied constraint C can be satisfied by changing the strategy of any player in N(C). Consequently, every Pd-FLIP game has degree at most d and belongs to PG++. Two notable subclasses of Pd-FLIP games are cut games and party affiliation games, which have been extensively studied in the algorithmic game theory literature (see, e.g., [Balcan et al., 2013; Bhalgat et al., 2010; Caragiannis and Jiang, 2023; Christodoulou et al., 2012; Fabrikant et al., 2004]).
3 Approach Overview and Contribution
This section outlines the key ingredients of our algorithm.
Existing algorithms for computing approximate pure Nash equilibria in both payoff-maximization (Pd-FLIP games) and cost-minimization potential games (congestion games with polynomial latencies) largely adhere to an algorithmic paradigm introduced in the seminal work by [Caragiannis et al., 2011; Caragiannis et al., 2015] for congestion games with polynomial latencies. The key idea is to deterministically schedule players' improving moves in order to obtain a polynomial-length trajectory from any initial state to an approximate pure Nash equilibrium.
For both Pd-FLIP games and congestion games with polynomial latencies, the quality of approximation achieved by this approach is captured by the notion of (1+γ)-stretch. For Pd-FLIP games, the (1 + γ)-stretch is defined as the maximum ratio between the optimal potential value and the potential at any (1+γ)-approximate pure Nash equilibrium, for arbitrarily small γ > 0. The corresponding notion for congestion games with polynomial latencies is obtained by reversing the ratio. We formalize in Definition 4 a generalized notion of stretch for potential games, extending the notion used for Pd-FLIP games to arbitrary potential games and allowing coordinated deviations of groups of up to k players, rather than only unilateral deviations. Notably, the stretch as defined for Pd-FLIP games corresponds exactly to the case k = 1 in our framework.
The success of this approach for Pd-FLIP games naturally raises the question of whether the same paradigm can yield meaningful guarantees for arbitrary potential games. Even if the scheduling framework could be extended beyond Pd-FLIP games, its approximation guarantee would still be governed by the (1 + γ)-stretch. Unfortunately, this leads to a severe limitation: in general potential games, the (1 + γ)- stretch can be unbounded. Example 2 exhibits a simple potential game for which the ratio between the optimal potential value and the potential at any pure (1+γ)-approximate Nash equilibrium can grow arbitrarily large.
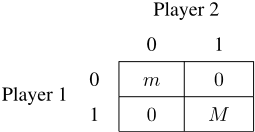
Example 2. For any pair M > m > 0 and any γ ≥ 0, consider a potential game with two players, N = {1, 2}, sharing the same strategy set {0, 1}. There is a unique interaction set {1, 2} and the corresponding interaction function Ψ{1,2} is defined as: Ψ{1,2}(0, 1) = Ψ{1,2}(1, 0) = 0, Ψ{1,2}(0, 0) = m, and Ψ{1,2}(1, 1) = M. Figure 1 illustrates the potential values of this game. Observe that this game does not belong to the class of Pd-FLIP games, since the interaction function takes two distinct positive values m and M, whereas in Pd-FLIP games each constraint contributes a unique positive value when satisfied. The state (0, 0) is a (1 + γ)-approximate pure Nash equilibrium with potential value m, while the state (1, 1) maximizes the potential function with value M. Thus, the maximum potential value is M, the potential of the worst (1 + γ)-approximate pure Nash equilibrium is m, and their ratio can be made arbitrarily large.
It is worth noting that the bounds for cut games, initially studied in [Caragiannis et al., 2017], were refined in [Caragiannis and Jiang, 2023]. Similarly, the approximation bounds for congestion games with polynomial latencies, established in [Caragiannis et al., 2011; Caragiannis et al., 2015], were later improved in [Feldotto et al., 2017] and [Giannakopoulos et al., 2022]. All these results build on the framework introduced in [Caragiannis et al., 2011; Caragiannis et al., 2015] and exploit structural properties specific to the underlying games. However, such techniques are often difficult to generalize and differ substantially from the general-purpose approach developed in this work.
Motivated by the observation illustrated in Example 2, this work proposes a new approach to computing approximate equilibria in potential games. Like previous methods, this approach deterministically schedules sequences of improving moves; however, in contrast to classical techniques that rely on unilateral moves, it allows coordinated moves by groups of up to k ≥ 1 players. That is, in each step, a group of at most k players simultaneously change their strategies in order to increase the "payoff" of the group as a whole, naturally extending the notion of individual improvement to collective improvement. It is important to emphasize that these group moves are algorithmically designed and, unlike individual improvement steps, are not necessarily incentive-compatible, i.e., a move by a group of players that improves the "payoff" of the group may reduce the payoff of some of the players involved.
This approach is motivated by two key insights. First, a strong connection exists between the task of computing approximate equilibria with strong guarantees and that of identifying strategy profiles with near-optimal potential values. Indeed, approximation guarantees obtained through the stretch are fundamentally tied to how close the potential at equilibrium is to the optimal potential value. This connection was originally established in [Caragiannis et al., 2011; Caragiannis et al., 2015] and is further reinforced by our framework. Second, allowing coordinated moves by groups of players enables the algorithm to escape low-potential states and reach higher-potential configurations more effectively. This effect is illustrated in Example 2, where a joint move allows players to bypass a poor equilibrium and reach a globally better state. As we will formally show, when the size of the deviating groups is sufficiently large, the resulting sequence of moves converge to approximate equilibria with provably better approximation guarantees.
To formally capture the notion of an "improving" move by a group of players, we extend the standard definition of payoff to arbitrary subsets of players (Definition 3). Our group payoff function is designed so as to coincide with the individual payoff (as formulated by Theorem 1) when the group consists of a single player, and with the potential function when the group includes all players. Crucially, we prove (Theorem 2) that the proposed group payoff preserves and generalizes the defining property of exact potential games. Specifically, for every move performed by a group Q, the induced variation of the payoff of Q is exactly reflected in the payoff variation of every superset P ⊇ Q, including the set of all players, whose payoff coincides with the potential function.
Definition 2. Let Ω be a finite non-empty set, and let F be a family of non-empty subsets of Ω. For any subset A ⊆ Ω, the set of A-hitting sets of F is defined as
Definition 3. Let G = ⟨N, I, (ΨP )P∈I, (Si)i∈N, (ui)i∈N⟩ ∈ PG. For every non-empty group of players P ⊆ N and every state s ∈ SN, the payoff of P in s is defined as
Note that u{i}(s) = ui(s) and uN(s) is a potential of G.
The next subsection generalizes the notions of moves and trajectories (i.e., sequences of moves) to groups of players. The resulting definitions include as special cases the corresponding concepts introduced in Section 2 for individual players.
Moves and Trajectories by Group of Players. Consider a potential game G = ⟨N, (Si)i∈N , (ui)i∈N⟩ ∈ PG. Any group of at most k ≥ 1 players is called a k-group. For every group P ⊆ N and strategy profiles s, ¯s ∈ SN, with s ̸= ¯s, the ordered pair (s, ¯s), where ¯s = [s P , s′ ] for some s′ ∈ SP , represents a move (i.e., a strategy change) by P from s. The move is said to be α-improving, for α ≥ 1, if uP (¯s) > αuP (s); in this case, s′ is called an α-improving strategy for P at s. Note that an α-improving move (strategy) is also an α′ -improving move (strategy), for every α > α′ ≥ 1.
A trajectory τ starting at state s0 and ending at state sh is a sequence τ = ⟨s0 , s1 , . . . , sh ⟩ of h+1 ≥ 1 states such that, if h ≥ 1, the pair (st , st+1 ) is a move by some group, for every t ∈ {0, 1, . . . , h - 1}. The length of τ is defined as h ≥ 0. If h ≥ 1, the trajectory τ is called α-improving if every move in the sequence is α-improving. If (sh , sh+1 ) is a move by some group from sh , then τ ⊕sh+1 denotes the extended trajectory ⟨s0 , s1 , . . . , sh , sh+1 ⟩.
The next theorem generalizes the defining property of potential games (1). Specifically, by setting Q = {i} and P = N in the theorem, we obtain (1).
Theorem 2. Let G = ⟨N, I, (ΨP )P∈I, (Si)i∈N, (ui)i∈N⟩ ∈ PG. Then, for every Q ⊆ P ⊆ N, s ∈ SN, and s′ ∈ SQ, we have
Proof. Let ¯s = [s Q, s′ ], then
where the third equality follows from the fact that ΨT (¯sT ) = ΨT (sT ) for every T ⊆ N that does not intersect Q.
The algorithm proposed in this work (Algorithm 1, presented in Section 4) extends the approach of [Caragiannis et al., 2017] for Pd-FLIP games to the broader class PG++. When applied to a game G, the algorithm deterministically schedules moves by groups of at most k players, starting from an initial state provided as input, thereby generating a trajectory that converges to an approximate pure Nash equilibrium.
The algorithm is parameterized by two values, β and σ, which are assumed to be known upper bounds on two key quantities associated with G: the (1 + γ, k)-stretch, denoted by Stretchk1+γ (G), and the spread, denoted by Γ(G) (these two quantities are formally defined and analyzed later in this section). The approximation guarantee achieved by the algorithm depends on β, whereas both β and σ affect the length of the resulting trajectory. Applying the algorithm to a specific class of games requires selecting suitable values of β and σ, obtained from upper bounds on the corresponding stretch and spread. Some examples of such bounds will be discussed later in this section. The following theorem formalizes the above.
Theorem 3. For every input consisting of a potential game G = ⟨N, I, (ΨP )P∈I, (Si)i∈N, (ui)i∈N⟩ ∈ PG++, an initial state sI ∈ SN, an integer k ≥ 1, and an accuracy parameter γ ∈ (0, 1], Algorithm 1, instantiated with parameters β, σ ≥ 1 such that β ≥ Stretchk1+γ (G) and σ ≥ Γ(G), constructs a (1+γ)-improving trajectory from sI to a (β +3γ)- approximate pure Nash equilibrium. The length of the trajectory is polynomial in β, σ, and the logarithm of the maximum payoff attainable by any player.
Theorem 3 guarantees that the final state returned by Algorithm 1 is an approximate pure Nash equilibrium. In fact, the algorithm ensures a stronger form of stability against coordinated moves by groups of at most k players. Formalizing this stronger guarantee requires introducing the notion of αapproximate k-optimal strategy profile, which is also central to the notion of stretch introduced later in this section.
α-Approximate k-Optimal Strategy Profiles. Consider a potential game G = ⟨N, ·, ·, (Si)i∈N, (ui)i∈N⟩ ∈ PG++. For every non-empty P ⊆ N, y ∈ S P , α ≥ 1, and integer k ≥ 1, a strategy x ∈ SP for P is called an α-approximate k-optimal strategy (given y) if no k-group Q ⊆ P has an α-improving move from the state [x, y], i.e., for every s′ ∈ SQ, uQ([[x, y] Q, s′ ]) ≤ αuQ([x, y]). If α = 1 and k ≥ |P |, then x is simply called an optimal strategy (given y), i.e., x ∈ argmaxz∈SP uP ([z, y]). The set of all α-approximate k-optimal strategies for P given y ∈ S P is denoted by S kα (G, P | y) ⊆ SP . The set of all optimal strategies for P given y ∈ S P is denoted by O(G, P | y) ⊆ SP . To simplify the notation, when P = N, S kα (G) is used in place of S kα (G, N |⊥) and denotes the set of α-approximate k-optimal states of G; similarly, O(G) is used in place of O(G,N |⊥) and denotes the set of optimal states of G.
We are now ready to formalize the stronger stability guarantee achieved by Algorithm 1.
Theorem 4. The final state of the trajectory produced by Algorithm 1 is a (β + 3γ)-approximate k-optimal strategy profile of G.
The remainder of this section is devoted to formally defining the notions of stretch and spread, and to deriving upper bounds on these quantities.
We begin with the notion of (α, k)-stretch. Informally, it captures the worst-case ratio between the maximum potential of the game and the potential of an α-approximate k-optimal strategy profile.
Definition 4. Let G = ⟨N, ·, ·, (Si)i∈N, (ui)i∈N⟩ ∈ PG++. For every non-empty P ⊆ N, y ∈ S P , α ≥ 1, and integer k ≥ 1, define
where x∗ is any strategy in O(G, P | y). The (α, k)-stretch of G is defined as
In Theorem 5, we establish an upper bound on Stretchk1+γ (G) in terms of the number of players, the degree d of the game, and the parameters k and γ, for every k ≥ d ≥ 2 and γ ≥ 0. The assumption k ≥ 2 is essential, since no finite upper bound exists when k = 1 (as shown in Example 2) unless additional restrictions are imposed on the class of games. This explains why moves by groups of size at least two are necessary to obtain meaningful approximation guarantees.
The proof of Theorem 5 closely follows the analysis of [Pearce and Tambe, 2007] for bounding the quality of k-optimal solutions in distributed constraint optimization problems (DCOPs). This connection highlights a strong parallel between approximate equilibria in potential games and locally optimal solutions in DCOPs.
The bound established in the theorem is expressed in terms of the falling factorial, defined as follows. For every integer t ≥ 1 and every real x ≥ 0, xt = x(x-1)(x-2) · · · (x-t+1) if x ≥ t, and xt = 0 otherwise.
Theorem 5. Let G = ⟨N, ·, ·, ·, ·⟩ ∈ PG+ be a potential game of degree d ≥ 2. For every γ ≥ 0 and integer k ≥ d, we have
The upper bound in Theorem 5 is tight, as follows from Proposition 2 of [Pearce and Tambe, 2007], which provides a matching lower bound for k-optimal solutions in DCOPs.
We now specialize Theorem 5 to the case d = 2, obtaining the following bound.
Corollary 1. Let G = ⟨N, ·, ·, ·, ·⟩ ∈ PG+ be a potential game of degree 2. For every γ ≥ 0 and integer k ≥ 2, we have
For completeness, we also recall that, for every Pd-FLIP game G, the quantity Stretch11+γ (G) is at most d+1+γd, as shown in [Caragiannis et al., 2017].
Now we define the notion of spread. Its definition relies on two additional quantities, namely the maximum value and the minmax value. While applied to potential games, these notions are more general: the maximum and minmax values are defined for all strategic games, while the spread applies to all games in SG++.
Maximum Value, Minmax Value, and Spread. Consider a strategic game G = ⟨N, (Si)i∈N, (ui)i∈N⟩ ∈ SG. For every player i ∈ N, the maximum value of i is defined as umax i = maxs∈SN ui(s), i.e., the maximum payoff achievable by player i over all strategy profiles.
The minmax value of player i, denoted by ui , captures the best payoff player i can ensure in the worst-case scenario, where the other players behave adversarially. Formally, ui = miny∈S i maxx∈Si ui([x, y]).
Finally, assume that G ∈ SG++. The spread of player i is defined as umax iui . Since G ∈ SG++, the quantity ui is strictly positive, and the ratio is therefore well defined. Moreover, the maximum value can also be written as umax i = maxy∈S i maxx∈Si ui([x, y]), which shows that the spread measures how much larger the best-case payoff of player i can be compared to the worst-case guaranteed payoff. The spread of the game is then defined as Γ(G) = maxi∈N umax iui .
We conclude the section with two simple examples of upper bounds on the spread. First, consider the game introduced in Example 2. If player 2 selects strategy 0, the maximum payoff achievable by player 1 is m, whereas if player 2 selects 1, the maximum achievable payoff becomes M. Since M > m, the spread of player 1 is exactly M/m. By symmetry, the same holds for player 2, and therefore the spread of the game is M/m.
Next, consider an instance G of the Pd-FLIP games introduced in Example 1. A key property of these games is that, for every player i and every strategy profile s i ∈ S i, umax i ≤ ui([s-i, true]) + ui([s-i, false]). Therefore, for every fixed choice of the other players, at least one of the two strategies guarantees player i a payoff of at least umax i /2. It follows that every Pd-FLIP game has spread at most 2.
4 Description of Algorithm 1
Algorithm 1 takes as input a potential game G ∈ PG++, an initial state sI ∈ SN, an integer k ≥ 1, and an accuracy parameter γ ∈ (0, 1]. It is instantiated with parameters β, σ ≥ 1 satisfying β ≥ Stretchk1+γ (G) and σ ≥ Γ(G), and returns a (1 + γ)-improving trajectory τ from sI to a (β + 3γ)- approximate pure Nash equilibrium. The length of τ is polynomial in β, σ, and the logarithm of the maximum payoff attainable by any player.
The first part of the algorithm (lines 2-14) partitions the set of players N into m disjoint blocks B1,B2, . . . ,Bm according to the values ˆui = maxx∈Si ui([sI i , x]), computed for every player i in lines 4-6. The quantity ˆui represents the maximum payoff that player i can obtain by performing a unilateral move from the initial state sI .
The blocks are defined through a geometrically decreasing sequence of boundaries b0, b1, . . . , bm. Specifically, b0 is initialized to maxi∈N ˆui (line 7), and each subsequent boundary is defined by br := ∆ 2 br-1 (lines 9-11), while bm is set to 0 (line 12). The parameter ∆ is chosen as a function of |N|, β, σ, and γ 1 (lines 2-3), and the value of m is selected so that the entire range of possible values of ˆui is covered (line 8).
Each player i is then assigned to the unique block whose interval contains its value ˆui: block B1 contains the players with ˆui ∈ [b1, b0] (line 13), while, for every r ∈ {2, . . . ,m}, block Br contains the players with ˆui ∈ [br, br-1) (line 14).
The second part of the algorithm (lines 15-28) consists of a sequence of m phases. Before the execution of the phases, the current state s is initialized to sI and the trajectory τ to ⟨sI ⟩ (lines 15-16). The phases are defined as follows.
Phase 0 (lines 17-21). The algorithm repeatedly searches for a k-group T ⊆ B1 having a (1 + γ)-improving move. Whenever such a group exists, the strategy of T is updated to an optimal strategy. The phase terminates when no such group remains, in which case the resulting strategy profile is a (1 + γ)-approximate k-optimal strategy for B1.
Algorithm 1
Input: G = ⟨N, I, (ΨP )P∈I, (Si)i∈N, (ui)i∈N⟩ ∈ PG++, sI ∈ SN, an integer k ≥ 1, a parameter γ ∈ (0, 1]; Output: A trajectory τ of G; 1: Let β and σ be two parameters such that β ≥ Stretchk1+γ (G) and σ ≥ Γ(G); 2: δ := (β +γ)(β +2)|N|γ 1 ; 3: ∆ := |N|δσ2 ; 4: for i ← 1 to |N| do 5: ˆui :=maxx∈Si ui([sI-i, x]); 6: end for 7: b0 :=maxi∈N ˆui; 8: m := ⌈log∆ b0⌉ + 1; 9: for r ← 1 to m-1 do 10: br :=∆ 2 br-1; 11: end for 12: bm := 0; 13: B1 := {i ∈ N | ˆui ∈ [b1, b0]}; 14: Br := {i ∈ N | ˆui ∈ [br, br-1)}, for every r ∈ {2, . . . ,m}; 15: s ← sI ; 16: τ ← ⟨sI ⟩; /* Phase 0 */ 17: while ∃ a k-group T ⊆ B1 that has a (1+γ)-improving move do 18: Let r∗ ∈ argmaxr∈ST uT ([s T , r]); 19: s ← [s T , r∗ ]; 20: τ ← τ ⊕ s; 21: end while /* Phases 1, 2, . . . , m - 1 */ 22: for r ← 1 to m-1 do 23: while ∃ a k-group T such that either T ⊆ Br+1 and T has a (1 + γ)-improving move or T ⊆ Br+1∪Br and T has a (β + γ)-improving move do 24: Let r∗ ∈ argmaxr∈ST uT ([s T , r]); 25: s ← [s T , r∗ ]; 26: τ ← τ ⊕ s; 27: end while 28: end for 29: return τ;Phase r ∈ {1, . . . ,m-1} (lines 23-27). The algorithm considers the two consecutive blocks Br and Br+1 and repeatedly performs the following updates. If there exists a k-group T ⊆ Br+1 having a (1 + γ)-improving move, or a k-group T ⊆ Br ∪ Br+1 having a (β + γ)-improving move, then the strategy of T is updated to an optimal strategy. At the end of phase r, the resulting strategy profile is a (β+γ)-approximate k-optimal strategy for Br ∪Br+1 and a (1+γ)-approximate k-optimal strategy for Br+1.
@inproceedings{ijcai2026p378,
  title     = {Computing Better Approximate Pure Nash Equilibria in Payoff-maximization Potential Games},
  author    = {Fanelli, Angelo},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {3402--3409},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/378},
  url       = {https://doi.org/10.24963/ijcai.2026/378},
}
TY - CPAPER TI - Computing Better Approximate Pure Nash Equilibria in Payoff-maximization Potential Games AU - Fanelli, Angelo T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 3402 EP - 3409 DO - 10.24963/ijcai.2026/378 UR - https://doi.org/10.24963/ijcai.2026/378 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





