
Transferable Attacks on Open-Vocabulary Video Instance Segmentation via Dual-Objective Triggers
Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence. Main Track. Pages 1613-1621.
https://doi.org/10.24963/ijcai.2026/180
Keywords
- Computer Vision: Adversarial learning, adversarial attack and defense methods
- Machine Learning: Multi-modal learning
- Computer Vision: Video analysis and understanding
- Machine Learning: Adversarial machine learning
- Computer Vision: Vision, language and reasoning
Abstract
Open‑vocabulary video instance segmentation (OV‑VIS) couples spatial‑temporal reasoning with language grounding, yet its adversarial robustness has remained unexplored. We present the Dual-Objective Triggers (DOT), the first transferable attack on OV-VIS that simultaneously exploits the vision–language coupling and temporal coherence. DOT deploys a Dual Semantic Perturbation Module that overlays two complementary triggers: a Semantic Suppression Trigger erases the alignment between the true object and the query, while a Plausible Replacement Trigger steers the tracker toward a phantom trajectory that is visually plausible and text‑consistent. To amplify cross‑model transferability without sacrificing perceptual fidelity, we introduce Phase‑Guided Adversarial Training, which injects perturbations primarily in the phase spectrum while blending amplitudes with clean references. Extensive experiments on four state‑of‑the‑art OV‑VIS implementations demonstrate that DOT reduces mAP by up to 69.3% and raises attack success rate by up to 98%, outperforming the strongest baselines by a factor of 1.6× on average, while maintaining a PSNR of 52.49 dB, thus exposing critical security vulnerabilities and laying a foundation for future research on robust and trustworthy vision–language systems.
- [Chen et al., 2025a] Long Chen, Yuling Chen, Zhi Ouyang, Hui Dou, Yangwen Zhang, and Haiwei Sang. Boost- ing adversarial transferability in vision-language models via multimodal feature heterogeneity. Scientific Reports, 15(1):7366, 2025.
- [Chen et al., 2025b] Xingbai Chen, Tingchao Fu, Renyang Liu, Wei Zhou, and Chao Yi. Mba: Multimodal bidirec- tional attack for referring expression segmentation models. arXiv preprint arXiv:2506.16157, 2025.
- [Chhipa et al., 2024] Prakash Chandra Chhipa, Kanjar De, Meenakshi Subhash Chippa, Rajkumar Saini, and Marcus Liwicki. Open-vocabulary object detectors: Robustness challenges under distribution shifts. In European Confer- ence on Computer Vision, pages 62-79. Springer, 2024.
- [Fang et al., 2024] Hao Fang, Peng Wu, Yawei Li, Xinxin Zhang, and Xiankai Lu. Unified embedding alignment for open-vocabulary video instance segmentation. In Eu- ropean Conference on Computer Vision, pages 225-241. Springer, 2024.
- [Goodfellow et al., 2014] Ian J Goodfellow, Jonathon Shlens, and Christian Szegedy. Explaining and harnessing adversarial examples. arXiv preprint arXiv:1412.6572, 2014.
- [Gu et al., 2022] Jindong Gu, Hengshuang Zhao, Volker Tresp, and Philip HS Torr. Segpgd: An effective and ef- ficient adversarial attack for evaluating and boosting seg- mentation robustness. In European Conference on Com- puter Vision, pages 308-325. Springer, 2022.
- [Guo et al., 2025] Pinxue Guo, Hao Huang, Peiyang He, Xuefeng Liu, Tianjun Xiao, and Wenqiang Zhang. Open- vis: Open-vocabulary video instance segmentation. In Proceedings of the AAAI Conference on Artificial Intelli- gence, volume 39, pages 3275-3283, 2025.
- [Jia et al., 2023] Xiaojun Jia, Jindong Gu, Yihao Huang, Simeng Qin, Qing Guo, Yang Liu, and Xiaochun Cao. Transegpgd: Improving transferability of adversarial examples on semantic segmentation. arXiv preprint arXiv:2312.02207, 2023.
- [Kim et al., 2023] Hee-Seon Kim, Minji Son, Minbeom Kim, Myung-Joon Kwon, and Changick Kim. Breaking temporal consistency: Generating video universal adver- sarial perturbations using image models. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 4325-4334, 2023.
- [Lee et al., 2024] Seunghun Lee, Jiwan Seo, Kiljoon Han, Minwoo Choi, and Sunghoon Im. Context-aware video instance segmentation. arXiv preprint arXiv:2407.03010, 2024.
- [Li and Wang, 2021] Haoxuan Li and Zheng Wang. Univer- sal sparse adversarial attack on video recognition mod- els. International Journal of Multimedia Data Engineer- ing and Management (IJMDEM), 12(3):1-15, 2021.
- [Li et al., 2023] Ping Li, Yu Zhang, Li Yuan, Jian Zhao, Xianghua Xu, and Xiaoqin Zhang. Adversarial attacks on video object segmentation with hard region discovery, 2023.
- [Li et al., 2024] Fengpeng Li, Kemou Li, Haiwei Wu, Jinyu Tian, and Jiantao Zhou. Dat: Improving adversarial ro- bustness via generative amplitude mix-up in frequency do- main. Advances in Neural Information Processing Sys- tems, 37:127099-127128, 2024.
- [Lu et al., 2017] Jiajun Lu, Hussein Sibai, and Evan Fabry. Adversarial examples that fool detectors. arXiv preprint arXiv:1712.02494, 2017.
- [Mu et al., 2021] Ronghui Mu, Wenjie Ruan, Leandro So- riano Marcolino, and Qiang Ni. Sparse adversarial video attacks with spatial transformations. arXiv preprint arXiv:2111.05468, 2021.
- [Nguyen Tiet Nguyen et al., 2024] Khoi Nguyen Tiet Nguyen, Wenyu Zhang, Kangkang Lu, Yuhuan Wu, Xingjian Zheng, Hui Li Tan, and Liangli Zhen. A survey and evaluation of adversarial attacks for object detection. arXiv e-prints, pages arXiv-2408, 2024.
- [Pan et al., 2024] Yi Pan, Jun-Jie Huang, Zihan Chen, Wen- tao Zhao, and Ziyue Wang. Svastin: Sparse video ad- versarial attack via spatio-temporal invertible neural net- works. In 2024 IEEE International Conference on Multi- media and Expo (ICME), pages 1-6. IEEE, 2024.
- [Pony et al., 2021] Roi Pony, Itay Naeh, and Shie Mannor. Over-the-air adversarial flickering attacks against video recognition networks. In Proceedings of the IEEE/CVF conference on computer vision and pattern recognition, pages 515-524, 2021.
- [Rahaman et al., 2019] Nasim Rahaman, Aristide Baratin, Devansh Arpit, Felix Draxler, Min Lin, Fred Hamprecht, Yoshua Bengio, and Aaron Courville. On the spectral bias of neural networks. In International conference on ma- chine learning, pages 5301-5310. PMLR, 2019.
- [Schlarmann et al., 2024] Christian Schlarmann, Na- man Deep Singh, Francesco Croce, and Matthias Hein. Robust clip: Unsupervised adversarial fine-tuning of vi- sion embeddings for robust large vision-language models. arXiv preprint arXiv:2402.12336, 2024.
- [Szegedy et al., 2013] Christian Szegedy, Wojciech Zaremba, Ilya Sutskever, Joan Bruna, Dumitru Erhan, Ian Goodfellow, and Rob Fergus. Intriguing properties of neural networks. arXiv preprint arXiv:1312.6199, 2013.
- [Wang et al., 2021] Zeyuan Wang, Chaofeng Sha, and Su Yang. Reinforcement learning based sparse black- box adversarial attack on video recognition models. arXiv preprint arXiv:2108.13872, 2021.
- [Wang et al., 2023] Haochen Wang, Cilin Yan, Shuai Wang, Xiaolong Jiang, Xu Tang, Yao Hu, Weidi Xie, and Efs- tratios Gavves. Towards open-vocabulary video instance segmentation. In proceedings of the IEEE/CVF interna- tional conference on computer vision, pages 4057-4066, 2023.
- [Wei et al., 2018] Xingxing Wei, Siyuan Liang, Ning Chen, and Xiaochun Cao. Transferable adversarial attacks for image and video object detection. arXiv preprint arXiv:1811.12641, 2018. IJCAI
- [Wu et al., 2024] Junfeng Wu, Yi Parcel Jiang, Qihao Liu, Zehuan Yuan, Xiang Bai, and Song Bai. General object foundation model for images and videos at scale. In Pro- ceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 3783-3795, 2024.
- [Yan et al., 2025] Bin Yan, Martin Sundermeyer, David Joseph Tan, Huchuan Lu, and Federico Tombari. Towards real-time open-vocabulary video instance segmentation. In 2025 IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), pages 1861-1871. IEEE, 2025.
- [Yin et al., 2023] Ziyi Yin, Muchao Ye, Tianrong Zhang, Tianyu Du, Jinguo Zhu, Han Liu, Jinghui Chen, Ting Wang, and Fenglong Ma. Vlattack: Multimodal adversar- ial attacks on vision-language tasks via pre-trained mod- els. Advances in Neural Information Processing Systems, 36:52936-52956, 2023.
- [Zhang et al., 2023a] Chaoning Zhang, Fachrina Dewi Pus- pitasari, Sheng Zheng, Chenghao Li, Yu Qiao, Taegoo Kang, Xinru Shan, Chenshuang Zhang, Caiyan Qin, Fran- cois Rameau, et al. A survey on segment anything model (sam): Vision foundation model meets prompt engineer- ing. arXiv preprint arXiv:2306.06211, 2023.
- [Zhang et al., 2023b] Tao Zhang, Xingye Tian, Yu Wu, Shunping Ji, Xuebo Wang, Yuan Zhang, and Pengfei Wan. Dvis: Decoupled video instance segmentation framework. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 1282-1291, 2023.
- [Zhang et al., 2025] Peng-Fei Zhang, Guangdong Bai, and Zi Huang. Maa: Meticulous adversarial attack against vision-language pre-trained models. arXiv preprint arXiv:2502.08079, 2025.
- [Zheng et al., 2024a] Rongkun Zheng, Lu Qi, Xi Chen, Yi Wang, Kun Wang, Yu Qiao, and Hengshuang Zhao. Syncvis: Synchronized video instance segmentation. Advances in Neural Information Processing Systems, 37:49461-49483, 2024.
- [Zheng et al., 2024b] Sheng Zheng, Chaoning Zhang, and Xinhong Hao. Black-box targeted adversarial attack on segment anything (sam). IEEE Transactions on Multime- dia, 2024.
- [Zhou et al., 2023a] Dawei Zhou, Nannan Wang, Heng Yang, Xinbo Gao, and Tongliang Liu. Phase-aware ad- versarial defense for improving adversarial robustness. In International Conference on Machine Learning, pages 42724-42741. PMLR, 2023.
- [Zhou et al., 2023b] Tao Zhou, Qi Ye, Wenhan Luo, Kaihao Zhang, Zhiguo Shi, and Jiming Chen. F&f attack: Adver- sarial attack against multiple object trackers by inducing false negatives and false positives. In Proceedings of the IEEE/CVF International Conference on Computer Vision, pages 4573-4583, 2023.
- [Zhu et al., 2024] Wenqi Zhu, Jiale Cao, Jin Xie, Shuang- ming Yang, and Yanwei Pang. Clip-vis: Adapting clip for open-vocabulary video instance segmentation. IEEE Transactions on Circuits and Systems for Video Technol- ogy, 2024.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Video instance segmentation (VIS) is a fundamental task in video understanding, aiming to segment and track object instances across a video sequence. Deep learning models have greatly improved VIS performance [Zhang et al., 2023b; Zheng et al., 2024a; Lee et al., 2024]. Advancing this paradigm, Open-vocabulary video instance segmentation (OV-VIS) extends this by incorporating language guidance, allowing segmentation of arbitrary categories defined by text. Despite these achievements, the adversarial robustness of OV-VIS remains underexplored. In particular, its vulnerability to transfer-based adversarial attacks has not been systematically studied. While prior work [Gu et al., 2022;
Jia et al., 2023] has demonstrated the susceptibility of traditional image-based segmentation models to adversarial perturbations, existing methods perform poorly on OV-VIS, failing to reveal its inherent risks. This gap is not merely a theoretical gap but a practical security concern; it leaves a clear opening for adversaries.
OV-VIS systems now underpin safety-critical applications, e.g., autonomous driving and video surveillance. However, adversaries can manipulate textual queries or exploit model vulnerabilities to suppress or misdirect the segmentation of critical objects, thereby causing negative economic and societal impacts. These concerns underscore the urgency of systematically investigating adversarial attacks on OV-VIS. The interplay between open-vocabulary queries and the requirement for spatio-temporal consistency of instance masks presents distinctive challenges for attack design. Concretely, in a typical attack scenario, the adversary designs to mislead the model's segmentation mask, causing it to deviate from the intended target. Simultaneously, the attacker must preserve spatio-temporal coherence among instances; otherwise, excessive disorder would render the attack conspicuous and easily detected. The difficulty is further exacerbated in realworld scenarios, where OV-VIS models vary significantly in terms of architecture, training data, and vision-language fusion strategies. Such heterogeneity introduces substantial uncertainty, preventing the adversary from reliably inferring the model in use. Consequently, any practical attack must therefore generalize across architectures, data distributions, and fusion strategies to achieve high transferability.
Transferable adversarial attacks [Goodfellow et al., 2014; Wei et al., 2018; Yin et al., 2023; Chen et al., 2025a] generally craft input perturbations that generalize across a set of held-out models; however, design assumptions inherited from static single-modality image regimes substantially limit their effectiveness in open-vocabulary video instance segmentation. An effective perturbation must first disrupt the fine-grained alignment between free-form textual queries and visual content, yet existing methods often neglect the linguistic modality or replace it with sparse geometric cues such as points or bounding boxes [Zheng et al., 2024b; Zhang et al., 2023a], thereby failing to exert direct influence over the language-conditioned mask prediction. Attacks that manipulate only a subset of frames fail to preserve temporal coherence, inducing perceptible flickering artifacts, and allow recurrent inference to recover the correct target in later frames [Pony et al., 2021; Li et al., 2023]. Moreover, the pronounced heterogeneity of OV-VIS architectures, training corpora, and fusion strategies leads to a sharp decline in transfer performance once a perturbation is evaluated outside its development family. These observations indicate that a practical transferable attack for OV-VIS must jointly optimize over vision and language and remain robust to architectural diversity. These qualities current approaches do not yet exhibit.
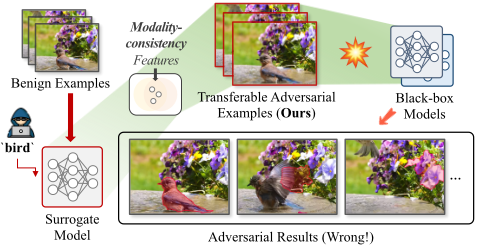
To tackle the above challenges, we propose Dual-Objective Triggers (DOT) in Figure 1, the first transfer-oriented adversarial framework for OV-VIS. Specifically, DOT introduces two modules, namely a Dual Semantic Perturbation Module (DSPM) and a Phase-Guided Adversarial Training strategy (PGAT). DSPM is designed to produce transferable perturbations with two complementary adversarial triggers. These triggers break the association between the text query and the genuine object while keeping spatio-temporal consistency. The first trigger, termed the Semantic Suppression Trigger, aims to weaken or erase the semantic features of the original target object in the video. The second trigger, named Plausible Replacement Trigger, leads the model to generate a misleading yet coherent instance trajectory and align the trajectory semantically with the corresponding class. To balance stealth and efficacy, we further devise a PhaseGuided Adversarial Training strategy that blends clean and adversarial amplitudes while keeping the adversarial phase intact. This suppresses visible artifacts and lets the phase carry the semantic structure that drives transferability.
In brief, our contributions can be summarized as follows:
- To our knowledge, this is the first to systematically investigate how open-vocabulary video instance segmentation behaves under cross-model adversarial settings, revealing that current state-of-the-art systems remain highly vulnerable despite their strong spatio-temporal and language-vision coupling.
- We introduce a novel framework that couples a Semantic Suppression Trigger with a Plausible Replacement Trigger to break cross-modal alignment and preserve realistic video dynamics, and we further enhance its trans-
- ferability and imperceptibility through a Phase-Guided Adversarial Training strategy.
- Extensive experiments on four state-of-the-art OV-VIS architectures show that our method DOT cuts mAP by up to 69.3% while retaining a perceptual quality of 52.4 dB PSNR, outperforming the strongest baseline by an average factor of 1.6×.
2 RelatedWorks
Open-Vocabulary Video Instance Segmentation. OV-VIS treats classification, tracking, and segmentation under a single language-conditioned framework. The task was formalized by OV2Seg [Wang et al., 2023], which introduced the large-scale LV-VIS benchmark and utilized a memory-induced transformer to propagate masks to unseen classes. Subsequent works refined the query design: InstFormer [Guo et al., 2025] enriches instance tokens with CLIP text embeddings and re-trains only lightweight category heads, markedly improving cross-category generalization; CLIP-VIS [Zhu et al., 2024] repurposes a frozen CLIP image encoder by adding a lightweight video head that propagates CLIP-based queries across frames, preserving zero-shot semantics with minimal extra computation; and OVFormer [Fang et al., 2024] jointly encodes video frames and text prompts via a transformer backbone with a small alignment layer to bridge instance queries and vision-language features. Recent studies emphasize efficiency, such as GLEE [Wu et al., 2024], which handles multiple tasks in a unified foundation model, and TrOY-VIS [Yan et al., 2025], which introduces a lightweight tracking-by-query paradigm to reduce per-frame computation.
Adversarial Attacks. Adversarial attacks craft imperceptible input perturbations to mislead deep models [Goodfellow et al., 2014; Szegedy et al., 2013]. For videos, Flickering-Noise (FN) offers cheap, physically deployable temporal flashes [Lu et al., 2017], while Frame-by-Frame (F&F) per-frame optimization extends classic image attacks and inspires sparser variants [Zhou et al., 2023b; Mu et al., 2021; Wang et al., 2021]. SVASTIN explores the full spatio-temporal volume with transferable patches resilient to motion and deformation [Pan et al., 2024]. Universal schemes such as BTC and US-Attack learn a single perturbation that generalizes across clips [Kim et al., 2023; Li and Wang, 2021], whereas ARA limits gradient computation to Regions of Interest for interpretable, task-oriented noise [Li et al., 2023]. The rise of open-vocabulary detectors has further revealed vulnerabilities in cross-modal alignment [Chhipa et al., 2024; Schlarmann et al., 2024; Zhang et al., 2025; Nguyen Tiet Nguyen et al., 2024]. However, existing video attacks are ill-suited to OV-VIS. FN and F&F perturb early detections or association graphs but leave the language branch untouched. SVASTIN targets per-frame semantic segmentation without enforcing temporal coherence. ARA assumes fixed categorical priors and thus fails to mislead open-set queries.
3 Preliminary
In this section, we first briefly introduce open-vocabulary video instance segmentation. Then, we formally define the threat model for a transfer attack on OV-VIS.
3.1 Open-Vocabulary Video Instance Segmentation
Given a training dataset Dtrain containing pixel-level annotations for a set of training categories Ctrain, traditional VIS aims to train a model F(·) to be tested on a dataset Dtest = {Vi}, where Vi ∈ RT×H×W×3 refers to a video clip with spatial shape (H,W) and T frames. F(·) is supposed to predict a sequence of segmentation masks Mpred = {mt}Tt=1 ∈ RT×H×W and a category label c ∈ Ctrain for each object in videos from the training categories, while the objects from novel categories Cnovel are ignored.
In contrast, Open-Vocabulary VIS aims to train a model F(·) on Dtrain, and then test on Dtest for both training categories Ctrain and novel categories Cnovel. Let C denote the complete category set, defined as the union of training and novel classes: C := Ctrain ∪ Cnovel. Specifically, given a test video clip Vi ∈ RT×H×W×3 during inference, the trained model Fs(·) is required to predict the segmentation mask sequenceMpred and the category label c ∈ C for each object p in Vi:
where mt ∈ RH×W is the segmentation mask for each frame t. In the experiments, we term the training categories as base categories, while the categories disjoint from base categories are referred to as novel categories.
3.2 Threat Model
Attacker's Goals: Given a clean video V and the corresponding label c, we seek to generate a video-domain adversarial patch P = {pt}Tt=1 to mislead the surrogate model Fs into producing a mask sequence that deviates from the ground truth and instead aligns with a predefined target mask sequence Mtarget = { ˜mt}Tt=1 :
where the operator ⊕ represents an addition of a video adversarial patch P. To satisfy the imperceptibility constraint, the perturbation must remain nearly imperceptible to human observers and downstream preprocessing. We therefore impose a perceptual budget with ε≪1:
Within these constraints, the attacker optimises P on a single surrogate model, yet expects it to transfer across heterogeneous unseen OV-VIS models encountered in the wild. By generating adversarial examples under these objectives and directly applying them to the target OV-VIS model, the attacker can influence the model's output.
Attacker's Capabilities: We assume a strict limited-access threat model that mimics realistic deployments: the attacker can access or train one surrogate OV-VIS network but has no knowledge of the architecture, parameters, or training data of the production model. The perturbation is crafted on this surrogate and then directly injected into the target stream-no gradient queries, score queries, or test-time fine-tuning are allowed. Consequently, the attack must rely purely on crossmodel transferability to succeed against heterogeneous OVVIS systems in the wild.
4 Transferable OV-VIS Attack
In this section, we present the proposed Dual-Objective Triggers (DOT) framework, a transfer-oriented adversarial attack framework, as illustrated in Figure 2. The framework comprises two key components: the Dual Semantic Perturbation Module (DSPM) and the Phase-Guided Adversarial Training (PGAT) strategy. Specifically, DSPM is designed to suppress the semantic features of the source object, while forcing the model to produce trajectories that are deceptive yet temporally coherent. Furthermore, PGAT exploits phase information in the frequency domain to enhance both the robustness and the cross-model transferability of the generated adversarial examples.
4.1 Dual Semantic PerturbationModule
OV-VIS tackles video instance segmentation conditioned on open-vocabulary text queries. In contrast to fixed-category benchmarks, the task requires models to jointly align freeform language with visual content and to preserve consistent instance identities across the video timeline. To effectively attack OV-VIS models, we aim to break the association between the target object and the given text description, while ensuring that the generated segmentation remains temporally coherent. Since both triggers are injected only at the input level and do not rely on model-specific gradients or internal features, DSPM is inherently architecture-agnostic and thus highly transferable.
Given a clean video V = {vt}Tt=1 and a corresponding textual query c, we utilize a surrogate OV-VIS model Fs to obtain a sequence of predicted instance masks M = {m1,m2, · · · ,mT} over T frames of the target. Let the superscript s mark the source object and p mark the distractor (phantom). To induce predictions that are spatially and temporally consistent yet deviated from the original object location, we introduce two adversarial patches: Semantic Suppression Trigger P s = {pst }Tt=1 and Plausible Replacement Trigger P p = {ppt }Tt=1 . The purpose of P s is to suppress or eliminate the semantic features of the original target object, thereby hindering the model's ability to recognize it. In contrast, P p is designed to guide the model toward generating a misleading instance trajectory that remains coherent across space and time. The patch pst is centered at the centroid rs t ∈ {0, 1}H×W of the predicted instance mask mt, and rp t ∈ {0, 1}H×W is obtained by spatially shifting rs t with an offset (∆x,∆y) to rs t-1 . For the t-th frame, an adversarial frame is formulated as:
where vt ∈ RH×W×3 denotes the clean input frame and vadv t denotes its adversarial counterpart. pst and ppt are applied to disjoint spatial regions defined by binary masks rs t and rp t .
After obtaining the adversarial video, we employ the surrogate model to infer the corresponding instance predictions.
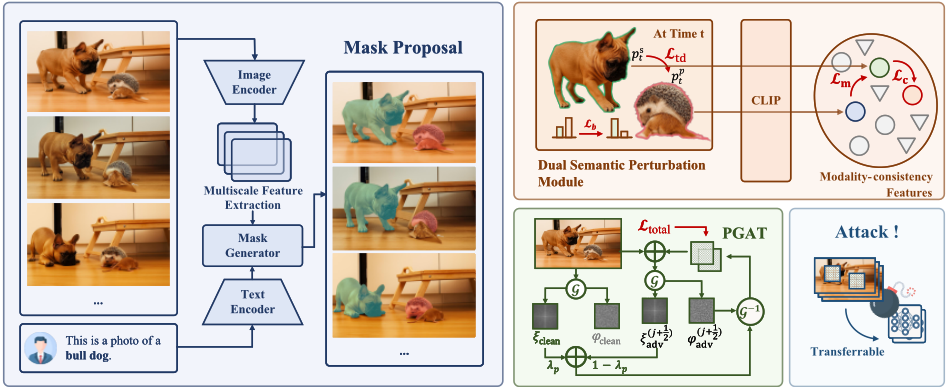
For a given adversarial video, in order to ensure that the predicted instances remain spatially and temporally aligned with the adversarial target while exhibiting controlled deviations, we introduce a trajectory deviation loss, which constrains the extent of spatiotemporal displacement between the predicted trajectory and the target trajectory.
For a given adversarial video, to enforce consistency between the masks predicted by the model and the target masks Mtarget = {˜mt}Tt=1 , we employ a pixel-wise binary crossentropy (BCE) loss, formulated as
where yi t ∈ [0, 1] denotes the predicted foreground probability at pixel i in frame t, and qi t ∈ {0, 1} represents the corresponding binary value of pixel i in the target mask ˜mt.
In our task, the optimization objective targets two adversarial components: the Semantic Suppression Trigger and the Plausible Replacement Trigger. To ensure these adversarial patches function as intended, we process the adversarial video on a frame-by-frame basis. Specifically, for the t-th frame, we randomly sample K regions centered around and encompassing the Semantic Suppression Trigger, denoted as {vs t(i) }Ki=1 , and crop K regions centered around the Plausible Replacement Triggers, denoted as {vp t(i) }Ki=1 . Each of the cropped regions is then resized to a uniform resolution and passed through the CLIP model to extract its corresponding feature representation as follows:
After obtaining the cropped feature representations of the Semantic Suppression Trigger {{xst(i) }Ki=1 }Tt=1 and the Plausible Replacement Trigger {{xpt(i) }Ki=1 }Tt=1 , we introduce a contrastive loss to disrupt the original alignment between the source object's visual trajectory and its corresponding textual query, while simultaneously binding the Plausible Replacement Trigger region to the same textual query.
To achieve this, we propose a contrastive loss to push the Semantic Suppression Trigger features xst(i) away from the genuine victim class description ysrc and closer to a fabricated class description ytgt. At the same time, it pulls the Plausible Replacement Trigger features xpt(i) toward ysrc. The loss is defined as:
where {yj}Cj=1 denote the set of text embeddings for all C classes.
To further guide the model toward predicting the instance mask in the region of the Plausible Replacement Trigger, we introduce an additional margin loss to enforce that the similarity between the Plausible Replacement Trigger features xpt(i) and the source class description ysrc exceeds that between the Semantic Suppression Trigger features xst(i) and ysrc by at least a margin γ:
where γ is a positive margin hyperparameter that controls the minimum separation between the two similarity scores. The total loss is defined as:
Note that every loss term is defined purely on surrogate outputs; no target-model feedback is required, which is critical for transfer attacks.
4.2 Phase-Guided Adversarial Training Strategy
Recent studies on frequency-domain representations of images have revealed that the phase spectrum encodes most of the structural and semantic information, while the amplitude spectrum mainly governs low-level appearance such as color and contrast [Chen et al., 2025b; Li et al., 2024; Zhou et al., 2023a; Rahaman et al., 2019]. Inspired by these findings, we ask: can adversarial optimization be guided to alter phase components primarily, so as to maximize featurelevel impact while preserving visual plausibility? This question motivates our Phase-Guided Adversarial Training strategy, which explicitly regularizes perturbations in the frequency domain to encode semantics in phase and preserve amplitude statistics for natural appearance.
We implement this idea inside a PGD-style optimization that jointly updates the two patches. Let Ltotal denote the adversarial objective (contrastive / task losses + regularizers). At PGD iteration j the intermediate (pre-regularization) updates for the t-th frame are
where α is the step size.
Following the gradient step, we apply a frequency-domain regularization to improve visual quality and to bias perturbations toward phase changes. Let G(·) be the Discrete Fourier Transform (DFT) that returns amplitude and phase, and G-1 (·) its inverse. For a patch p∗t ∈ {pst , ppt }, denote
where p∗t,clean is a clean reference patch (e.g., the initial patch or a local image crop without adversarial modification). We construct a regularized amplitude by linear interpolation:
We then reconstruct the spatial patch using the regularized amplitude and the adversarial phase, and enforce valid pixel range by clipping:
Intuitively, Eq. (13) preserves coarse appearance via the clean amplitude while allowing the phase φadv to encode adversarial structure that more strongly perturbs model features. Note we do not enforce a hard zeroing of amplitude changes; λp controls the trade-off between visual fidelity and attack flexibility.
4.3 Universal DOT (U-DOT)
To improve transferability across unseen videos, we further explore a universal variant (U-DOT), in which a shared pair of triggers (P su , P p u ) are optimized jointly over a batch of videos rather than per instance:
This allows the learned triggers to generalize across diverse scenes with negligible additional cost.
5 Experiments
5.1 Experiment Setup
Datasets and Metrics In this study, we benchmark our method using the LV-VIS and YTVIS-21 dataset, both are public corpus for OV-VIS. We report the Performance Drop (∆ %) in mean Average Precision (mAP) and mean Average Recall (mAR). To quantify the spatial deviation of the predicted masks caused by perturbations, we adopt metrics mIoU-GT and ASRIoU@30 (ASR in short) following the work of [Chen et al., 2025b]. mIoU-GT measures the IoU between ground truth and predictions, while ASR evaluates the success rate of adversarial videos in distorting under a 30% IoU threshold.
Baselines We port four strong segmentation attacks from Multiple Object Tracking and Video Instance Segmentation: Flickering-Noise (FN), Frame-by-Frame (F&F), SVASTIN, and Adversarial Region Attack (ARA). We generate pseudo boxes using a frozen Mask2Former for FN and F&F. We evaluate two OV-VIS pipelines, CLIP-VIS and OVFormer, both combining a CLIP-style image-text encoder with a maskedattention decoder (Mask2Former-style). We utilize the officially released pre-trained checkpoints and evaluate attacks under a strict black-box protocol setting without any direct access to model weights or gradients.
5.2 Transfer Settings and Implementations
We use InstFormer [Guo et al., 2025] as the surrogate OV-VIS model. Unless otherwise stated, all adversarial examples are generated once on InstFormer (surrogate) and evaluated without gradient access on every target model, faithfully reflecting a transfer-attack scenario. Both the SST and PRT are square patches whose side length is set to 0.8 × the shorter edge of the detected bounding box, constrained to [48, 256] pixels to maintain a reasonable scale. The patches are initialized with zeros, and K = 4 crops per frame are randomly sampled. Perturbations are optimized for J = 60 iterations with step size α = 2/255 under an ℓ∞ budget of ε = 16/255. The displacements ∆x and ∆y are randomly constrained to 10%-20% of the source object's shorter edge. We set λtd = 1.0, λb = 1.0, λc = 1.0, λm = 1.0, and λp = 0.5. All experiments are performed on an NVIDIA A100-80 GB GPU with seed 42. To select the phantom object description ytgt, we adopt a simple yet effective strategy: we choose the category that has the lowest CLIP similarity to the source category ysrc.
| Model | Method | LV-VIS | YTVIS-21 | ||||||
|---|---|---|---|---|---|---|---|---|---|
| mAP ∆ ↑ | mAR∆ ↑ | IoU-GT ↓ | ASR ↑ | mAP ∆ ↑ | mAR∆ ↑ | IoU-GT ↓ | ASR ↑ | ||
| FN Attack | 9.1 | 7.8 | 13.8 | 81.8 | 3.7 | 13.2 | 14.2 | 84.4 | |
| CLIP-VIS F&F Attack | 19.2 | 33.4 | 9.4 | 88.2 | 25.4 | 10.2 | 18.8 | 87.0 | |
| SVASTIN | 17.0 | 18.0 | 9.6 | 86.1 | 24.7 | 12.0 | 13.6 | 90.4 | |
| [R-50] ARA | 21.8 | 31.0 | 8.8 | 91.1 | 48.7 | 22.4 | 12.1 | 93.8 | |
| DOT (Ours) | 36.4 | 30.2 | 3.9 | 98.9 | 55.2 | 38.9 | 7.8 | 97.2 | |
| FN Attack | 3.2 | 4.7 | 12.5 | 85.3 | 32.3 | 17.4 | 21.1 | 73.8 | |
| CLIP-VIS F&F Attack | 13.3 | 21.4 | 11.4 | 89.8 | 28.8 | 45.0 | 13.6 | 84.6 | |
| SVASTIN | 9.6 | 3.7 | 10.3 | 87.8 | 23.5 | 12.8 | 13.9 | 82.7 | |
| [Conv-B] ARA | 16.7 | 8.7 | 10.0 | 92.0 | 20.8 | 39.9 | 12.7 | 87.5 | |
| DOT (Ours) | 28.5 | 23.6 | 9.3 | 95.0 | 91.3 | 88.0 | 5.4 | 98.4 | |
| FN Attack | 24.9 | 16.8 | 11.1 | 81.5 | 24.5 | 17.5 | 18.0 | 89.7 | |
| OVFormer F&F Attack | 36.4 | 35.9 | 11.1 | 87.1 | 89.0 | 21.4 | 16.0 | 87.5 | |
| SVASTIN | 26.3 | 16.1 | 12.6 | 79.0 | 83.5 | 86.0 | 21.2 | 82.2 | |
| [R-50] ARA | 42.1 | 31.0 | 10.5 | 92.4 | 85.5 | 49.7 | 16.1 | 95.4 | |
| DOT (Ours) | 69.3 | 61.2 | 9.2 | 98.0 | 91.5 | 64.1 | 5.6 | 98.6 | |
| FN Attack | 28.4 | 20.1 | 10.6 | 84.4 | 38.4 | 33.6 | 14.7 | 86.7 | |
| OVFormer F&F Attack | 41.7 | 46.8 | 10.4 | 84.1 | 85.0 | 84.3 | 31.3 | 88.9 | |
| SVASTIN | 16.7 | 7.0 | 13.7 | 79.0 | 84.1 | 82.8 | 25.6 | 81.4 | |
| [Swin-B] ARA | 41.2 | 32.1 | 10.4 | 91.7 | 88.0 | 87.7 | 15.3 | 94.2 | |
| DOT (Ours) | 62.8 | 52.8 | 11.2 | 97.9 | 94.6 | 92.4 | 6.0 | 98.2 | |
| InstFormer | CLIP-VIS | OVFormer | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| mAP | mAR | IoU-GT | ASR | mAP | mAR | IoU-GT | ASR | mAP | mAR | IoU-GT | ASR | |
| InstFormer | - | - | - | - | 36.4 | 30.2 | 3.9 | 98.9 | 69.3 | 61.2 | 9.2 | 98.0 |
| CLIP-VIS | 43.1 | 36.4 | 8.4 | 96.7 | - | - | - | - | 37.2 | 30.4 | 9.1 | 96.2 |
| OVFormer | 69.3 | 62.9 | 7.3 | 97.2 | 49.8 | 41.5 | 7.9 | 98.9 | - | - | - | - |
5.3 Experimental Results
Table 1 summarises DOT's performance on the LV-VIS and YTVIS-21 benchmarks across two OV-VIS architectures and two backbones. DOT consistently ranks first or second across all metrics and shows clear advantages on precision-oriented indicators.
Among the strongest baselines, ARA and F&F operate in feature space. On CLIP-VIS[ResNet-50], ARA achieves slightly higher recall gain, while F&F nearly matches DOT on OVFormer[Swin-B]. In contrast, DOT prioritises mislocalization through aggressive semantic suppression, resulting in comparable recall degradation but stronger localisation errors, reflected by higher IoU-GT under strong backbones.
Table 2 further demonstrates DOT's cross-architecture transferability. DOT induces substantial performance drops across models, with mAP reductions up to 69.3% and consistently high ASR (often above 96%), indicating robust, highconfidence mislocalisation even under transfer settings.
These results validate the effectiveness of DOT's dualtrigger design: semantic suppression disrupts correct grounding, while plausible replacement enforces coherent false trajectories, yielding strong architectural generality. Standard defenses such as JPEG compression and Bit-Red show only marginal mitigation effects.
5.4 Ablation Study
We perform an ablation study to assess the contributions of the DSPM and PGAT modules. Additional ablations on loss weights, patch size, and crop count show that DOT is robust to hyperparameter variations.
Effectiveness of the DSPMModule
Table 3 indicates that the trajectory-deviation loss Ltd is essential for recall degradation, while the cross-modal contrastive loss Lc mainly governs precision by decoupling visual and textual semantics.
Trigger ablations reveal complementary effects: removing Plausible Replacement Trigger causes the largest precision drop, whereas removing Semantic Suppression Trigger mainly harms recall and leads to the lowest ASR, showing that a coherent phantom trajectory is crucial for effective attacks.
| mAP ∆ ↑ | mAR∆ ↑ | ASR ↑ | |
|---|---|---|---|
| Ours w/o Ltd w/o Lb w/o Lc w/o Lm w/o w/o | 36.4% | 30.2% | 98.9% |
| 20.5% | 6.9% | 86.7% | |
| 14.9% | 19.8% | 84.0% | |
| 11.9% | 17.7% | 86.0% | |
| 24.7% | 20.8% | 85.7% | |
| PRT | 31.1% | 17.1% | 80.1% |
| SST | 25.0% | 21.2% | 65.0% |
| ASR ↑ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | |
|---|---|---|---|---|
| Ours w/o | 98.9% | 52.4 dB | 99.3% | .014 |
| PGAT | 99.2% | 49.3 dB | 98.8% | .031 |
Balance of Effectiveness and Imperceptibility
We conducted ablations to isolate the contribution of individual components in DOT. Imperceptibility is evaluated using three metrics: Peak Signal-to-Noise Ratio (PSNR, dB), Structural Similarity Index (SSIM), and Learned Perceptual Image Patch Similarity (LPIPS).
Table 4 shows that the PGAT-enhanced attack preserves comparable effectiveness while significantly improving perceptual fidelity. It boosts PSNR by 3.1 dB, increases SSIM to 99.3%, and reduces LPIPS by more than half.
Gap between Universal and Video-Specific Solution
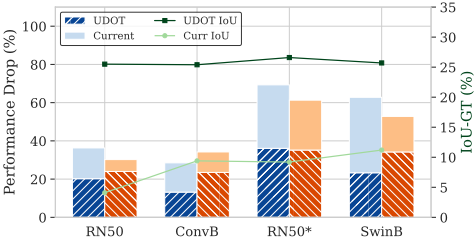
Figure 3 compares a Universal DOT (UDOT) with the videospecific DOT under the same ℓ∞ budget. UDOT achieves moderate degradation across detectors but is substantially weaker than per-video DOT. Its higher IoU-GT indicates more global, less object-aligned perturbations.
These results suggest that UDOT captures dataset-level priors with limited temporal adaptation, while per-video DOT exploits clip-specific gradients to induce stronger semantic disruption. In practice, UDOT offers a lightweight alternative under resource constraints, whereas per-video DOT remains optimal for maximal attack effectiveness.
Amplitude vs. Phase vs. Mixed (PGAT Ablation)
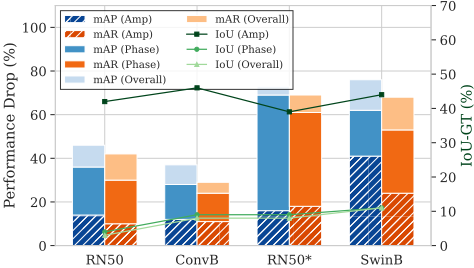
To examine the contribution of the phase and amplitude components in the proposed PGAT, we conduct a controlled ablation where adversarial updates are applied to only the amplitude (Amplitude-guided), only the phase (Phase-guided), or both components with amplitude blending (Overall). All variants share identical optimization settings.
As shown in Figure 4, phase-guided perturbations consistently outperform amplitude-only variants in mAP/mAR degradation while maintaining much lower IoU-GT, indicating superior stealth and mask misalignment. The mixed strategy achieves the strongest overall attack with IoU-GT comparable to the phase-guided variant, offering the best trade-off between effectiveness and imperceptibility.
These results suggest that phase modulation captures semantically meaningful structure critical to model perception, while amplitude-only perturbations mainly affect low-level appearance. Blending both enables PGAT to preserve visual naturalness while enhancing cross-model transferability.
6 Conclusion
In this paper, we propose DOT, a transferable adversarial framework for open-vocabulary video instance segmentation that explicitly accounts for temporal coherence. DOT jointly suppresses genuine object semantics and induces coherent phantom trajectories through frequency-guided optimization. Its Dual Semantic Perturbation Module and Phase-Guided Adversarial Training enable imperceptible yet highly transferable phase-based perturbations. Extensive experiments across two architectures and four backbones show that DOT substantially outperforms existing attacks, achieving up to 69% ∆mAP degradation with near-perfect attack success rates. Beyond exposing vulnerabilities, DOT also yields challenging adversarial videos that can be used as hard negatives for improving robustness, highlighting critical security gaps in current vision-language pipelines.
Ethical Statement
This work studies transferable adversarial attacks on openvocabulary video instance segmentation for the sole purpose of revealing and ultimately reducing real-world vulnerabilities. No private or proprietary data were used: all experiments rely exclusively on the publicly available OV-VIS benchmark, whose licenses permit research use. The method never interacts with human subjects, nor does it process personally identifiable information; accordingly, institutional review board (IRB) oversight is not required. We adhere to the IJCAI Code of Professional Ethics: the work advances scientific understanding of model robustness, the presentation is honest and complete, and the responsible-release protocol balances scientific openness with social responsibility. Ultimately, we believe the benefits of exposing OV-VIS vulnerabilities outweigh the residual risks, yet we urge practitioners to incorporate robust defense mechanisms before deploying vision-language models in safety-critical settings.
Contribution Statement
Minghao Shou and Kesen Wang contributed equally to this work. Zonghui Wang is the corresponding author. Minghao Shou and Kesen Wang conceived and designed the method, conducted the experiments, and wrote the manuscript. Tong Zhang and Han Bao provided feedback and assisted with experiments. Zonghui Wang supervised the project and revised the manuscript.
@inproceedings{ijcai2026p180,
  title     = {Transferable Attacks on Open-Vocabulary Video Instance Segmentation via Dual-Objective Triggers},
  author    = {Shou, Minghao and Wang, Kesen and Zhang, Tong and Bao, Han and Wang, Zonghui},
  booktitle = {Proceedings of the Thirty-Fifth International Joint Conference on
               Artificial Intelligence, {IJCAI-26}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Diego Calvanese},
  pages     = {1613--1621},
  year      = {2026},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2026/180},
  url       = {https://doi.org/10.24963/ijcai.2026/180},
}
TY - CPAPER TI - Transferable Attacks on Open-Vocabulary Video Instance Segmentation via Dual-Objective Triggers AU - Shou, Minghao AU - Wang, Kesen AU - Zhang, Tong AU - Bao, Han AU - Wang, Zonghui T2 - Proceedings of the Thirty-Fifth International Joint Conference on Artificial Intelligence, IJCAI-26 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2026 SP - 1613 EP - 1621 DO - 10.24963/ijcai.2026/180 UR - https://doi.org/10.24963/ijcai.2026/180 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





