
Hierarchical Object-oriented Spatio-Temporal Reasoning for Video Question Answering
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 636-642.
https://doi.org/10.24963/ijcai.2021/88
Keywords
- Computer Vision: Language and Vision
Abstract
Video Question Answering (Video QA) is a powerful testbed to develop new AI capabilities. This task necessitates learning to reason about objects, relations, and events across visual and linguistic domains in space-time. High-level reasoning demands lifting from associative visual pattern recognition to symbol like manipulation over objects, their behavior and interactions. Toward reaching this goal we propose an object-oriented reasoning approach in that video is abstracted as a dynamic stream of interacting objects. At each stage of the video event flow, these objects interact with each other, and their interactions are reasoned about with respect to the query and under the overall context of a video. This mechanism is materialized into a family of general-purpose neural units and their multi-level architecture called Hierarchical Object-oriented Spatio-Temporal Reasoning (HOSTR) networks. This neural model maintains the objects' consistent lifelines in the form of a hierarchically nested spatio-temporal graph. Within this graph, the dynamic interactive object-oriented representations are built up along the video sequence, hierarchically abstracted in a bottom-up manner, and converge toward the key information for the correct answer. The method is evaluated on multiple major Video QA datasets and establishes new state-of-the-arts in these tasks. Analysis into the model's behavior indicates that object-oriented reasoning is a reliable, interpretable and efficient approach to Video QA.
- [Baradel et al., 2018] Fabien Baradel, Natalia Neverova, Christian Wolf, Julien Mille, and Greg Mori. Object level visual reasoning in videos. In Proceedings of the European Conference on Computer Vision (ECCV), pages 105-121, 2018.
- [Chao et al., 2018] Yu-Wei Chao, Sudheendra Vijayanarasimhan, Bryan Seybold, David A Ross, Jia Deng, and Rahul Sukthankar. Rethinking the faster r-cnn architecture for temporal action lo- calization. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 1130-1139, 2018.
- [Desta et al., 2018] Mikyas T Desta, Larry Chen, and Tomasz Ko- rnuta. Object-based reasoning in VQA. In 2018 IEEE Winter Conference on Applications of Computer Vision (WACV), pages 1814-1823. IEEE, 2018.
- [Gao et al., 2018] Jiyang Gao, Runzhou Ge, Kan Chen, and Ram Nevatia. Motion-appearance co-memory networks for video ques- tion answering. In Proceedings of the IEEE Conference on Com- puter Vision and Pattern Recognition, pages 6576-6585, 2018.
- [Huang et al., 2020] Deng Huang, Peihao Chen, Runhao Zeng, Qing Du, Mingkui Tan, and Chuang Gan. Location-aware graph convo- lutional networks for video question answering. In AAAI, pages 11021-11028, 2020.
- [Jain et al., 2016] Ashesh Jain, Amir R Zamir, Silvio Savarese, and Ashutosh Saxena. Structural-rnn: Deep learning on spatio- temporal graphs. In Proceedings of the ieee conference on com- puter vision and pattern recognition, pages 5308-5317, 2016.
- [Jang et al., 2017] Yunseok Jang, Yale Song, Youngjae Yu, Youngjin Kim, and Gunhee Kim. Tgif-qa: Toward spatio-temporal reason- ing in visual question answering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 2758-2766, 2017.
- [Kalogeiton et al., 2017] Vicky Kalogeiton, Philippe Weinzaepfel, Vittorio Ferrari, and Cordelia Schmid. Action tubelet detector for spatio-temporal action localization. In Proceedings of the IEEE International Conference on Computer Vision, pages 4405-4413, 2017.
- [Kim et al., 2017] Kyung-Min Kim, Min-Oh Heo, Seong-Ho Choi, and Byoung-Tak Zhang. DeepStory: video story QA by deep embedded memory networks. In IJCAI, pages 2016-2022. AAAI Press, 2017. IJCAI
- [Lake et al., 2017] Brenden M Lake, Tomer D Ullman, Joshua B Tenenbaum, and Samuel J Gershman. Building machines that learn and think like people. Behavioral and Brain Sciences, 40, 2017.
- [Le et al., 2020a] Thao Minh Le, Vuong Le, Svetha Venkatesh, and Truyen Tran. Hierarchical conditional relation networks for video question answering. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 9972-9981, 2020.
- [Le et al., 2020b] Thao Minh Le, Vuong Le, Svetha Venkatesh, and Truyen Tran. Neural reasoning, fast and slow, for video question answering. In IJCNN, 2020.
- [Liang et al., 2018] Junwei Liang, Lu Jiang, Liangliang Cao, Li-Jia Li, and Alexander G Hauptmann. Focal visual-text attention for visual question answering. In Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition, pages 6135-6143, 2018.
- [Pan et al., 2020] Boxiao Pan, Haoye Cai, De-An Huang, Kuan-Hui Lee, Adrien Gaidon, Ehsan Adeli, and Juan Carlos Niebles. Spatio- temporal graph for video captioning with knowledge distillation. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 10870-10879, 2020.
- [Spelke and Kinzler, 2007] Elizabeth S Spelke and Katherine D Kin- zler. Core knowledge. Developmental science, 10(1):89-96, 2007.
- [Tran et al., 2018] Du Tran, Heng Wang, Lorenzo Torresani, Jamie Ray, Yann LeCun, and Manohar Paluri. A closer look at spatiotem- poral convolutions for action recognition. In Proceedings of the IEEE conference on Computer Vision and Pattern Recognition, pages 6450-6459, 2018.
- [Wang and Gupta, 2018] Xiaolong Wang and Abhinav Gupta. Videos as space-time region graphs. In Proceedings of the Eu- ropean conference on computer vision (ECCV), pages 399-417, 2018.
- [Wang et al., 2019] Anran Wang, Anh Tuan Luu, Chuan-Sheng Foo, Hongyuan Zhu, Yi Tay, and Vijay Chandrasekhar. Holistic multi- modal memory network for movie question answering. IEEE Transactions on Image Processing, 29:489-499, 2019.
- [Wojke et al., 2017] Nicolai Wojke, Alex Bewley, and Dietrich Paulus. Simple online and realtime tracking with a deep associa- tion metric. In ICIP. IEEE, 2017.
- [Xie et al., 2018] Saining Xie, Chen Sun, Jonathan Huang, Zhuowen Tu, and Kevin Murphy. Rethinking spatiotemporal feature learning: Speed-accuracy trade-offs in video classification. In Proceedings of the European Conference on Computer Vision (ECCV), pages 305-321, 2018.
- [Xu et al., 2017] Dejing Xu, Zhou Zhao, Jun Xiao, Fei Wu, Han- wang Zhang, Xiangnan He, and Yueting Zhuang. Video question answering via gradually refined attention over appearance and motion. In ACM Multimedia, 2017.
- [Yang et al., 2020] Zekun Yang, Noa Garcia, Chenhui Chu, Mayu Otani, Yuta Nakashima, and Haruo Takemura. Bert representa- tions for video question answering. In The IEEE Winter Con- ference on Applications of Computer Vision, pages 1556-1565, 2020.
- [Ye et al., 2017] Yunan Ye, Zhou Zhao, Yimeng Li, Long Chen, Jun Xiao, and Yueting Zhuang. Video question answering via attribute-augmented attention network learning. In Proceedings of the 40th International ACM SIGIR Conference on Research and Development in Information Retrieval, pages 829-832. ACM, 2017.
- [Yi et al., 2020] Kexin Yi, Chuang Gan, Yunzhu Li, Pushmeet Kohli, Jiajun Wu, Antonio Torralba, and Joshua B. Tenenbaum. CLEVRER: collision events for video representation and reason- ing. In ICLR, 2020.
- [Zeng et al., 2019] Runhao Zeng, Wenbing Huang, Mingkui Tan, Yu Rong, Peilin Zhao, Junzhou Huang, and Chuang Gan. Graph convolutional networks for temporal action localization. In Pro- ceedings of the IEEE International Conference on Computer Vi- sion, pages 7094-7103, 2019.
- [Zhao et al., 2018] Zhou Zhao, Xinghua Jiang, Deng Cai, Jun Xiao, Xiaofei He, and Shiliang Pu. Multi-turn video question answering via multi-stream hierarchical attention context network. In IJCAI, pages 3690-3696, 2018. IJCAI
- [Zhao et al., 2019] Zhou Zhao, Zhu Zhang, Shuwen Xiao, Zhenxin Xiao, Xiaohui Yan, Jun Yu, Deng Cai, and Fei Wu. Long-form video question answering via dynamic hierarchical reinforced networks. IEEE Transactions on Image Processing, 28(12):5939- 5952, 2019.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Much of the recent impressive progress of AI can be attributed to the availability of suitable large-scale testbeds. A powerful testbed - largely under-explored - is Video Question Answering (Video QA). This task demands a wide range of cognitive capabilities including learning and reasoning about objects and dynamic relations in space-time, in both visual and linguistic domains. A major challenge of reasoning over video is extracting question-relevant high-level facts from low-level moving pixels over an extended period of time. These facts include objects, their motion profiles, actions, interactions, events, and consequences distributed in space-time. Another challenge is to learn the long-term temporal relation of visual objects conditioning on the guidance clues from the question - effectively bridging the semantic gulf between the two domains. Finally, learning to reason from relational data is an open problem on its own, as it pushes the boundary of learning from simple one-step classification to dynamically construct question-specific computational graphs that realize the iterative reasoning process.
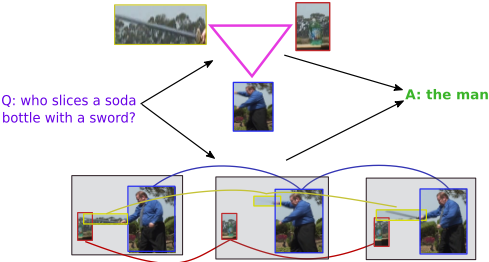
A highly plausible path to tackle these challenges is via object-centric learning since objects are fundamental to cognition [Spelke and Kinzler, 2007]. Objects pave the way towards more human-like reasoning capability and symbolic computing [Lake et al., 2017; Spelke and Kinzler, 2007]. Unlike objects in static images, objects in video have unique evolving lives throughout space-time. As object lives throughout the video, it changes its appearance and position, and interacts with other objects at arbitrary time. When observed in the videos, all these behaviors play out on top of a background of rich context of the video scene. Furthermore, in the question answering setting, these object-oriented information must be considered from the specific view point set by the linguistic query. With these principles, we pinpoint the key to Video QA to be the effective high-level relational reasoning of spatiotemporal objects under the video context and the perspective provided by the query (see Fig. 1). This is challenging for the complexity of the video spatio-temporal structure and the cross-domain compatibility gap between linguistic query and visual objects.
Toward such challenge we design a general-purpose neural unit called Object-oriented Spatio-Temporal Reasoning (OSTR) that operates on a set of video object sequences, a contextual video feature, and an external linguistic query. OSTR models object lifelong interactions and returns a summary representation in the form of a singular set of objects. The specialties of OSTR are in the partitioning of intra-object temporal aggregation and inter-object spatial interaction that leads to the efficiency of the reasoning process. Being flexible and generic, OSTR units are suitable building blocks for constructing powerful reasoning models.
For Video QA problem, we use OSTR units to build up Hierarchical Object-oriented Spatio-Temporal Reasoning (HOSTR) model. The network consists of OSTR units arranged in layers corresponding to the levels of video temporal structure. At each level, HOSTR finds local object interactions and summarizes them toward a higher-level, longer-term representation with the guidance of the linguistic query.
HOSTR stands out with its authentic and explicit modeling of video objects leading to the effective and interpretable reasoning process. The hierarchical architecture also allows the model to efficiently scale to a wider range of video formats and lengths. These advantages are demonstrated in a comprehensive set of experiments on multiple major Video QA tasks and datasets.
In summary, this paper makes three major contributions: (1) A semantic-rich object-oriented representation of videos that paves the way for spatio-temporal reasoning (2) A generalpurpose neural reasoning unit with dynamic object interactions per context and query; and (3) A hierarchical network that produces reliable and interpretable video question answering.
2 RelatedWork
Video QA has been developed on top of traditional video analysis schemes such as recurrent networks of frame features [Zhao et al., 2019] or 3D convolutional operators [Tran et al., 2018]. Video representations are then fused with or gated by the linguistic query through co-attention [Jang et al., 2017; Ye et al., 2017], hierarchical attention [Liang et al., 2018; Zhao et al., 2018], and memory networks [Kim et al., 2017; Wang et al., 2019]. More recent works advance the field by exploiting hierarchical video structure [Le et al., 2020a] or separate reasoning out of representation learning [Le et al., 2020b]. A share feature between these works is considering the whole video frames or segments as the unit component of reasoning. In contrast, our work make a step further by using detail objects from the video as primitive constructs for reasoning.
Object-centric Video Representation inherits the modern capability of object detection on images [Desta et al., 2018] and continuous tracking through temporal consistency [Wojke et al., 2017]. Tracked objects form tubelets [Kalogeiton et al., 2017] whose representation contributes to breakthroughs in action detection [Xie et al., 2018] and event segmentation
[Chao et al., 2018]. For tasks that require abstract reasoning, the connection between objects beyond temporal object permanence can be established through relation networks [Baradel et al., 2018]. The concurrence of objects' 2D spatial- and 1D temporal- relations naturally forms a 3D spatio-temporal graphs [Wang and Gupta, 2018]. This graph can be represented as either a single flattened one where all parts connect together [Zeng et al., 2019], or separated spatial- and temporalgraphs [Pan et al., 2020]. They can also be approximated as a dynamic graph where objects live through the temporal axis of the video while their properties and connection evolve [Jain et al., 2016].
Object-based Video QA is still in infancy. The works in [Yang et al., 2020] and [Huang et al., 2020] extract object features and feed them to generic relational engines without prior structure of reasoning through space-time. At the other extreme, detected objects are used to scaffold the symbolic reasoning computation graph [Yi et al., 2020] which is explicit but limited in flexibility and cannot recover from object extraction errors. Our work is a major step toward the object-centric reasoning with the balance between explicitness and flexibility. Here video objects serve as active agents which build up and adjust their interactions dynamically in the spatio-temporal space as instructed by the linguistic query.
3 Method
3.1 ProblemDefinition
Given a video V and linguistic question q, our goal is to learn a mapping function Fθ(.) that returns a correct answer ¯a from an answer set A as follows:
In this paper, a video V is abstracted as a collection of object sequences tracked in space and time. Function Fθ is designed to have the form of a hierarchical object-oriented network that takes the object sequences, modulates themwith the overall video context, dynamically infers object interactions as instructed by the question q so that key information regarding a arises from the mix. This object-oriented representation is presented next in Sec. 3.2, followed by Sec. 3.3 describing the key computation unit and Sec. 3.4 the resulting model.
3.2 Data Representation
Video as a Set of Object Sequences
Different frommost of the prominent VideoQAmethods [Jang et al., 2017; Gao et al., 2018; Le et al., 2020a] where videos are represented by frame features, we break down a video of length L into a list of N object sequences O = {on,t}N,L n=1,t=1 constructed by chaining corresponding objects of the same identity n across the video. These objects are represented by a combination of (1) appearance features (RoI pooling features) oan,t ∈ R2048 (representing "what"); and (2) the positional features opn,t = [ xmin W , ymin H , xmax W , ymax H , wW , hH , wh WH ] ("where"), with w and h are the sizes of the bounding box and W,H are those of the video frame, respectively.
In practice, we use Faster R-CNN with ROI-pooling to extract positional and appearance features; and DeepSort for multi-object tracking. We assume that the objects live from the beginning to the end of the video. Occluded or missed objects have their features marked with special null values which will be specially dealt with by the model.
Joint Encoding of "What" and "Where"
Since the appearance oan,t of an object may remain relatively stable over time while opn,t constantly changes, we must find joint positional-appearance features of objects to make them discriminative in both space and time. Specifically, we propose the following multiplicative gating mechanism to construct
where f2(opn,t ) ∈ (0, 1) serves as a position gate to (softly) turn on/off the localized appearance features f1(oan,t ). We choose f1(x) = tanh (Wax+ ba) and f2(x) = sigmoid (Wpx + bp), where Wa and Wp are network weights with height of d.
Along with the object sequences, we also maintain global features of video frames which hold the information of the background scene and possible missed objects. Specifically, for each frame t, we form the the global features gt as the combination of the frame's appearance features (pretrained ResNet pool5 vectors) and motion feature (pretrained ResNeXt-101) extracted from such frame.
With these ready, the video is represented as a tuple of object sequences On and frame-wise global features gt: V = ({On | On ∈ RL×d} Nn=1 , {gt}Lt=1).
Linguistic Representation
We utilize a BiLSTM running on top of GloVe embedding of the words in a query of length S to generate contextual embeddings {es}Ss=1 for es ∈ Rd , which share the dimension d with object features. We also maintain a global representation of the question by summarizing the two end LSTM states qg ∈ Rd . We further use qg to drive the attention mechanism and combine contextual words into a unified query representation q = ∑Ss=1 αses where αs = softmaxs(Wq(es ⊙ qg)).
3.3 Object-oriented Spatio-Temporal Reasoning (OSTR)
With the videos represented as object sequences, we need to design a scalable reasoning framework that can work natively on the structures. Such a framework must be modular so it is flexible to different input formats and sizes. Toward this goal, we design a generic reasoning unit called Objectoriented Spatio-Temporal Reasoning (OSTR) that operates on this object-oriented structure and supports layering and parallelism.
Algorithmically, OSTR takes as input a query representation q, a context representation c, a set of N object sequences X = {Xn | Xn ∈ RT×d }Nn=1 of equal length T, and individual identities {n}. In practice, X can be a subsegment of the whole object sequences O, and c is gathered from the frame features gt constructed in Sec. 3.2. The output of the OSTR is a set of object instances of the same identity.
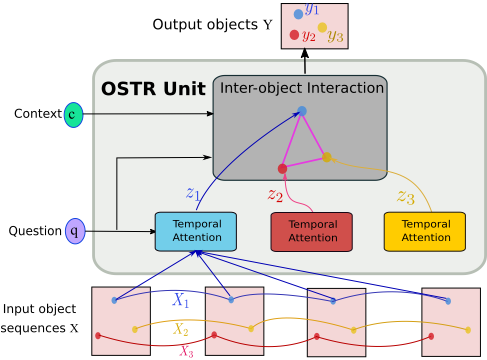
Across the space-time domains, real-world objects have distinctive properties (appearance, position, etc.) and behaviors (motion, deformation, etc.) throughout their lives. Meanwhile, different objects living in the same period can interact with each other. The OSTR closely reflects this nature by containing the two main components: (1) Intra-object temporal attention and (2) Inter-object interaction (see Fig. 2).
Intra-object Temporal Attention
The goal of the temporal attention module is to produce a query-specific summary of each object sequence Xn = {xn,t}Tt=1 into a single vector zn. The attention weights are driven by the query q to reflect the fact that the relevance to the query varies across the sequence. In details, the summarized vector zn is calculated by
where ⊙ is the Hadamard product, {Wa,Wq,Wx} are learnable weights, γ is a binary mask vector to handle the null values caused by missed detections as mentioned in Sec. 3.2.
When the sequential structure is particularly strong, we can optionally employ a BiLSTM to model the sequence. We can then either utilize the last state of the forward LSTM and the first state of the backward LSTM, or place attention across the hidden states instead of object feature embeddings.
Inter-object Interaction
Fundamentally, the lifelines of object sequences are not only described by their internal behavior through time but also by the interactions with their neighbor objects coexisting in the same space. In order to represent such complex relationship, we build a spatio-temporal computation graph to facilitate the inter-object interactions modulated by the query q. This graph G(Z,E) contains vertices as the summarized objects Z = {zn}Nn=1 generated in Eq. 4, and the edges E represented by an adjacency matrix A ∈ RN×N . A is calculated dynamically as the query-induced correlation matrix between the objects:
Here an is the relevance of object n w.r.t. the query q. The norm operator is implemented as a softmax function over objects in our implementation.
Given the graph G,we use a Graph Convolutional Network (GCN) equipped with skip-connections to refine objects in relation with their neighboring nodes. Starting with the initialization H0 = (z1, z2, ..., zn) ∈ RN×d , the representations of nodes are updated through a number of refinement iterations. At iteration i, the new hidden states are calculated by:
where σ (·) is a nonlinear activation (ELU in our implementation). After a fixed number of GCN iterations, the hidden states of the final layer are gathered as Himax = {hn}Nn=1 .
To recover the underlying background scene information and compensate for possible undetected objects, we augment the object representations with the global context c:
These vectors line up to form the final output of the OSTR unit as a set of objects Y = {yn}Nn=1 .
3.4 Hierarchical Object-oriented Spatio-Temporal Reasoning (HOSTR)
Even though the partitioning of temporal and spatial interaction in OSTR brings the benefits of efficiency and modularity, such separated treatment can cause the loss of spatio-temporal information, especially with long sequences. This limitation prevents us from using OSTR directly on the full video object sequences. To allow temporal and spatial reasonings to cooperate along the way, we break down a long video into multiple short (overlapping) clips and impose an hierarchical structure on top. With such division, the two types of interactions can be combined and interleaved across clips and allow full spatio-temrporal reasoning.
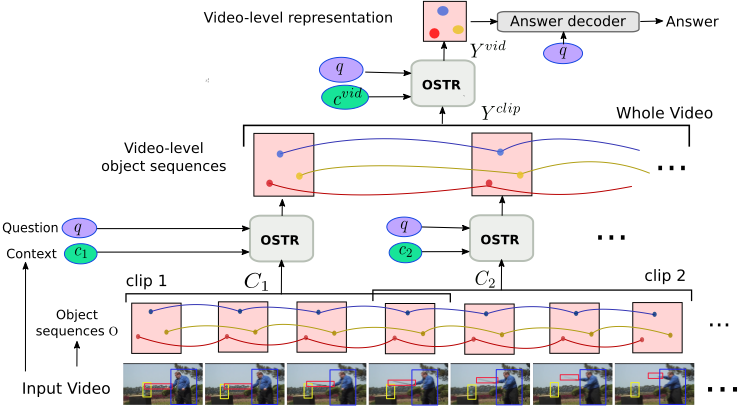
Based on this motive, we design a novel hierarchical structure called Hierarchical Object-oriented Spatio-Temporal Reasoning (HOSTR) that follows the video multi-level structure and utilizes the OSTR units as building blocks. Our architecture shares the design philosophy of hierarchical reasoning structures with HCRN [Le et al., 2020a] as well as the other general neural building blocks such as ResNet and InceptionNet. Thanks to the genericity of OSTR, we can build a hierachy of arbitrary depth. For concreteness, we present here a two-layer HOSTR corresponding to the video structure: clip-level and video-level (see Fig. 3).
In particular, we first split all object sequences O constructed in Sec. 3.2 into K equal-sized chunks C = {C1,C2, ...,CK} corresponding to the video clips, each of T frames. As the result, each chunk includes the object subsequences Ck = {on,t}N,tk+T n=1,t=tk , where on,t are the object features extracted in Eq. 2, and tk is the starting time of clip k.
Similarly, we divide the sequence of global frame features {gt}Lt=1 into K parts corresponding to the video clips. The global context ck for clip k is derived from each part by an identical operation with the temporal attention for objects in Eqs. 3,4: ck = temporal attention ({gt}tk+T ).
Clip-level OSTR units work on each of these subsequences Ck, context cclip k and query q, and generate the clip-level representation of the chunk yclip k ∈ RN×d :
Outputs of the K clip-level OSTRs are K different sets of objects yclip k = {yn,k}Nn=1 whose identities nwere maintained. Therefore, we can easily chain these objects of the same identity from different clips together to form the video-level se-
At the video level, we have a single OSTR unit that takes in the object sequence Y clip , query q, and videolevel context cvid . The context cvid is again derived from the clip-level context cclip k by temporal attention: cvid = temporal attention ({cclip k }K ) .
The video-level OSTR models the long-term relationships between input object sequences in the whole video:
The output of this unit is a set of N vectors Y vid = {yvid n | yvid n ∈ Rd }Nn=1 . The set is further summarized using an attention mechanism using the query q into the final representation vector r:
3.5 Answer Decoders
We follow the common settings for answer decoders (e.g., see [Jang et al., 2017]) which combine the final representation r with the query q using an MLP followed by a softmax to rank the possible answer choices. More details about the answer decoders per question types are available in the supplemental material. We use the cross-entropy as the loss function to training the model from end to end for all tasks except counting, where Mean Square Error is used.
4 Experiments
4.1 Datasets
We evaluate our proposed HOSTR on the three public video QA benchmarks, namely, TGIF-QA [Jang et al., 2017], MSVD-QA [Xu et al., 2017] and MSRVTT-QA [Xu et al., 2017]. More details are as follows.
MSVD-QA consists of 50,505 QA pairs annotated from 1,970 short video clips. The dataset covers five question types: What, Who, How, When, and Where, of which 61% of the QA pairs for training, 13% for validation and 26% for testing.
MSRVTT-QA contains 10K real videos (65% for training, 5% for validation, and 30% for testing) with more than 243K
| Model | Test Accuracy (%) | |
|---|---|---|
| MSVD-QA | MSRVTT-QA | |
| ST-VQA | 31.3 | 30.9 |
| Co-Mem | 31.7 | 32.0 |
| AMU | 32.0 | 32.5 |
| HME | 33.7 | 33.0 |
| HCRN | 36.1 | 35.4 |
| HOSTR | 39.4 | 35.9 |
| Model | TGIF-QA | |||
|---|---|---|---|---|
| Action↑ | Trans.↑ | Frame↑ | Count↓ | |
| ST-TP (R+C) | 62.9 | 69.4 | 49.5 | 4.32 |
| Co-Mem (R+F) | 68.2 | 74.3 | 51.5 | 4.10 |
| PSAC (R) | 70.4 | 76.9 | 55.7 | 4.27 |
| HME (R+C) | 73.9 | 77.8 | 53.8 | 4.02 |
| HCRN (R) | 70.8 | 79.8 | 56.4 | 4.38 |
| HCRN (R+F) | 75.0 | 81.4 | 55.9 | 3.82 |
| HOSTR (R) | 75.6 | 82.1 | 58.2 | 4.13 |
| HOSTR (R+F) | 75.0 | 83.0 | 58.0 | 3.65 |
question-answer pairs. Similar to MSVD-QA, questions are of five types: What, Who, How, When, and Where.
TGIF-QA is one of the largest Video QA datasets with 72K animated GIFs and 120K question-answer pairs. Questions cover four tasks - Action, Event Transition, FrameQA, Count. We refer readers to the supplemental material for the dataset description and statistics.
4.2 Comparison Against SOTAs
Implementation: We use Faster R-CNN 1 for frame-wise object detection. The number of object sequences per video for MSVD-QA , MSRVTT-QA is 40 and TGIF-QA is 50. We embed question words into 300-D vectors and initialize them with GloVe during training. Default settings are with 6 GCN layers for each OSTR unit. The feature dimension d is set to be 512 in all sub-networks.
We compare the performance of HOSTR against recent state-of-the-art (SOTA) methods on all three datasets. Prior results are taken from [Le et al., 2020a].
MSVD-QA and MSRVTT-QA: Table 1 shows detailed comparisons on MSVD-QA and MSRVTT-QA datasets. It is clear that our proposed method consistently outperforms all SOTA models. Specifically, we significantly improve performance on the MSVD-QA by 3.3 absolute points while the improvement on the MSRVTT-QA is more modest. As videos in the MSRVTT-QA are much longer (3 times longer than those in MSVD-QA) and contain more complicated interaction, it might require a larger number of input object sequences than what in our experiments (40 object sequences).
TGIF-QA: Table 2 presents the results on TGIF-QA dataset. As pointed out in [Le et al., 2020a], short-termmotion features are helpful for action task while long-term motion features are crucial for event transition and count tasks. Hence, we provide two variants of our model: HOSTR (R) makes use of ResNet features as the context information for OSTR units; and HOSTR (R+F) makes use of the combination of ResNet features and motion features (extracted by ResNeXt, the same as in HCRN) as the context representation. HOSTR (R+F) shows exceptional performance on tasks related to motion. Note that we only use the context modulation at the video level to concentrate on the long-termmotion. Even without the use of motion features, HOSTR (R) consistently shows more favorable performance than existing works.
1 https://github.com/airsplay/py-bottom-up-attention
The quantitative results prove the effectiveness of the objectoriented reasoning compared to the prior approaches of totally relying on frame-level features. Incorporating the motion features as context information also shows the flexibility of the design, suggesting that HOSTR can leverage a variety of input features and has the potentials to apply to other problems.
4.3 Ablation Studies
To provide more insight about our model, we examine the contributions of different design components to the model's performance on the MSVD-QA dataset. We detail the results in Table 3. As shown, intra-object temporal attention seems to be more effective in summarizing the input object sequences to work with relational reasoning than BiLSTM. We hypothesize that it is due to the selective nature of the attention mechanism - it keeps only information relevant to the query.
As for the inter-object interaction, increasing the number of GCN layers up to 6 generally improves the performance. It gradually degrades when we stack more layers due to the gradient vanishing. The ablation study also points out the significance of the contextual representation as the performance steeply drops from 39.4 to 37.8 without them.
Last but not least, we conduct two experiments to demonstrate the significance of video hierarchical modeling. "1-level hierarchy" refers to when we replace all clip-level OSTRs with the global average pooling operation to summarize each object sequence into a vector while keeping the OSTR unit at the video level. "1.5-level hierarchy", on the other hand, refers to when we use an average pooling operation at the video level while keeping the clip-level the same as in our HOSTR. Empirically, it shows that going deeper in hierarchy consistently improves performance on this dataset. The hierarchy may have greater effects in handling longer videos such as those in the MSRVTT-QA and TGIF-QA datasets.
4.4 Qualitative Analysis
To provide more analysis on the behavior of HOSTR in practice, we visualize the spatio-temporal graph formed during HOSTR operation on a sample in MSVD-QA dataset. In Fig. 4, the spatio-temporal graph of the two most important clips (judged by the temporal attention scores) are visualized in order of their appearance in the video's timeline. Blue boxes indicate the six objects with highest edge weights (row summation of the adjacency matrix A calculated in Eq.6). The red lines indicates the most prominent edges of the graph with intensity scaled to the edge strength.
In this example, HOSTR attended mostly on the objects related to the concepts relevant to answer the question (the girl, ball and dog). Furthermore, the relationships between the girl and her surrounding objects are the most important among the edges, and this intuitively agrees with how human might visually examine the scene given the question.
| Model | Test Acc. (%) |
|---|---|
| Default config. (*) | 39.4 |
| Temporal attention (TA) | |
| Attention at both levels | 39.4 |
| BiLSTM at clip, TA at video level | 39.4 |
| BiLSTM at both levels | 38.8 |
| Inter-object Interaction | |
| SR with 1 GCN layer | 38.3 |
| SR with 4 GCN layers | 38.7 |
| SR with 8 GCN layers | 39.0 |
| Contextual representation | |
| w/o contextual representation | 37.8 |
| Hierarchy | |
| 1-level hierarchy | 38.0 |
| 1.5-level hierarchy | 38.7 |
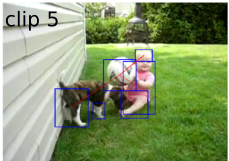
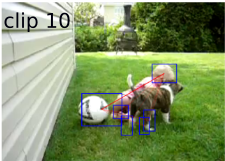
Figure 4: A visualization of the spatio-temporal graph formed in HOSTR. The six most attended objects in each clip are drawn in blue bounding boxes. Red links indicates the importances of the edges.
5 Conclusion
We presented a new object-oriented approach to Video QA where objects living in the video are treated as the primitive constructs. This brings us closer to symbolic reasoning, which is arguably more human-like. To realize this high-level idea, we introduced a general-purpose neural unit dubbed Objectoriented Spatio-Temporal Reasoning (OSTR). The unit reasons about its contextualized input - which is a set of object sequences - as instructed by the linguistic query. It first selectively transforms each sequence to an object node, then dynamically induces links between the nodes to build a graph. The graph enables iterative relational reasoning through collective refinement of object representation, gearing toward reaching an answer to the given query. The units are then stacked in a hierarchy that reflects the temporal structure of a typical video, allowing higher-order reasoning across space and time. Our architecture establishes new state-of-the-arts on major Video QA datasets designed for complex compositional questions, relational, temporal reasoning. Our analysis shows that object-oriented reasoning is a reliable, interpretable and effective approach to Video QA.
@inproceedings{ijcai2021p88,
  title     = {Hierarchical Object-oriented Spatio-Temporal Reasoning for Video Question Answering},
  author    = {Dang, Long Hoang and Minh Le, Thao and Le, Vuong and Tran, Truyen},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {636--642},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/88},
  url       = {https://doi.org/10.24963/ijcai.2021/88},
}
TY - CPAPER TI - Hierarchical Object-oriented Spatio-Temporal Reasoning for Video Question Answering AU - Dang, Long Hoang AU - Minh Le, Thao AU - Le, Vuong AU - Tran, Truyen T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 636 EP - 642 DO - 10.24963/ijcai.2021/88 UR - https://doi.org/10.24963/ijcai.2021/88 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





