
Improved Guarantees and a Multiple-descent Curve for Column Subset Selection and the Nystrom Method (Extended Abstract)
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Sister Conferences Best Papers. Pages 4765-4769.
https://doi.org/10.24963/ijcai.2021/647
Keywords
- Machine Learning: Dimensionality Reduction
- Machine Learning: Kernel Methods
- Machine Learning: Explainable/Interpretable Machine Learning
- Machine Learning: Unsupervised Learning
Abstract
The Column Subset Selection Problem (CSSP) and the Nystrom method are among the leading tools for constructing interpretable low-rank approximations of large datasets by selecting a small but representative set of features or instances. A fundamental question in this area is: what is the cost of this interpretability, i.e., how well can a data subset of size k compete with the best rank k approximation? We develop techniques which exploit spectral properties of the data matrix to obtain improved approximation guarantees which go beyond the standard worst-case analysis. Our approach leads to significantly better bounds for datasets with known rates of singular value decay, e.g., polynomial or exponential decay. Our analysis also reveals an intriguing phenomenon: the cost of interpretability as a function of k may exhibit multiple peaks and valleys, which we call a multiple-descent curve. A lower bound we establish shows that this behavior is not an artifact of our analysis, but rather it is an inherent property of the CSSP and Nystrom tasks. Finally, using the example of a radial basis function (RBF) kernel, we show that both our improved bounds and the multiple-descent curve can be observed on real datasets simply by varying the RBF parameter.
- [Alaoui and Mahoney, 2015] Ahmed El Alaoui and Michael W. Mahoney. Fast randomized kernel ridge regression with statistical guarantees. In Proceedings of the 28th International Conference on Neural Information Processing Systems, pages 775-783, 2015.
- [Anari et al., 2016] Nima Anari, Shayan Oveis Gharan, and Alireza Rezaei. Monte carlo markov chain algorithms for sampling strongly rayleigh distributions and determinantal point processes. In 29th Annual Conference on Learning Theory, volume 49, pages 103-115, 2016.
- [Bartlett et al., 2019] P. L. Bartlett, P. M. Long, G. Lugosi, and A. Tsigler. Benign overfitting in linear regression. Technical Report Preprint: arXiv:1906.11300, 2019.
- [Calandriello et al., 2020] Daniele Calandriello, Michał Dereziński, and Michal Valko. Sampling from a k-dpp without looking at all items. In Advances in Neural Infor- mation Processing Systems, volume 33, pages 6889-6899, 2020.
- [Chang and Lin, 2011] Chih-Chung Chang and Chih-Jen Lin. LIBSVM: A library for support vector machines. ACM Transactions on Intelligent Systems and Technology, 2:27:1-27:27, 2011.
- [Dereziński and Mahoney, 2021] Michał Dereziński and Michael W Mahoney. Determinantal point processes in randomized numerical linear algebra. Notices of the American Mathematical Society, 68(1):34-45, 2021.
- [Dereziński et al., 2019] Michał Dereziński, Daniele Calan- driello, and Michal Valko. Exact sampling of determi- nantal point processes with sublinear time preprocessing. In Advances in Neural Information Processing Systems, pages 11542-11554. 2019.
- [Dereziński et al., 2020] Michał Dereziński, Feynman Liang, and Michael W Mahoney. Exact expressions for double descent and implicit regularization via surrogate random design. In Advances in Neural Information Processing Systems, volume 33, pages 5152-5164, 2020.
- [Dereziński, 2019] Michał Dereziński. Fast determinantal point processes via distortion-free intermediate sampling. In Proceedings of the Thirty-Second Conference on Learn- ing Theory, pages 1029-1049, 2019.
- [Deshpande and Rademacher, 2010] Amit Deshpande and Luis Rademacher. Efficient volume sampling for row/column subset selection. In Proceedings of the 2010 IEEE 51st Annual Symposium on Foundations of Com- puter Science, pages 329-338, 2010.
- [Deshpande et al., 2006] Amit Deshpande, Luis Rademacher, Santosh Vempala, and Grant Wang. Matrix approximation and projective clustering via volume sampling. In Proc. 17th Annual Symposium on Discrete Algorithm, pages 1117-1126, 2006.
- [Drineas and Mahoney, 2005] P. Drineas and M. W. Ma- honey. On the Nyström method for approximating a Gram matrix for improved kernel-based learning. Journal of Ma- chine Learning Research, 6:2153-2175, 2005.
- [Gautier et al., 2019] Guillaume Gautier, Guillermo Polito, Rémi Bardenet, and Michal Valko. DPPy: DPP sam- pling with python. Journal of Machine Learning Research, 20(180):1-7, 2019.
- [Gittens and Mahoney, 2016] Alex Gittens and Michael W. Mahoney. Revisiting the Nyström method for improved large-scale machine learning. J. Mach. Learn. Res., 17(1):3977-4041, January 2016.
- [Gong et al., 2014] Boqing Gong, Wei-Lun Chao, Kristen Grauman, and Fei Sha. Diverse sequential subset selec- tion for supervised video summarization. In Advances in Neural Information Processing Systems 27, pages 2069- 2077. 2014.
- [Guruswami and Sinop, 2012] Venkatesan Guruswami and Ali K. Sinop. Optimal column-based low-rank matrix re- construction. In Proceedings of the Twenty-third Annual ACM-SIAM Symposium on Discrete Algorithms, pages 1207-1214, Kyoto, Japan, January 2012.
- [Hough et al., 2006] J. Ben Hough, Manjunath Krishnapur, Yuval Peres, Bálint Virág, et al. Determinantal processes and independence. Probability surveys, 3:206-229, 2006.
- [Kim et al., 2016] Been Kim, Rajiv Khanna, and Oluwasanmi Koyejo. Examples are not enough, learn to criticize! criticism for interpretability. In Advances in Neural Information Processing Systems, 2016.
- [Kulesza and Taskar, 2011] Alex Kulesza and Ben Taskar. k- DPPs: Fixed-Size Determinantal Point Processes. In Pro- ceedings of the 28th International Conference on Machine Learning, pages 1193-1200, June 2011.
- [Kulesza and Taskar, 2012] Alex Kulesza and Ben Taskar. Determinantal Point Processes for Machine Learning. Now Publishers Inc., Hanover, MA, USA, 2012.
- [Macchi, 1975] Odile Macchi. The coincidence approach to stochastic point processes. Advances in Applied Probabil- ity, 7(1):83-122, 1975.
- [Mahoney and Drineas, 2009] Michael W Mahoney and Pet- ros Drineas. Cur matrix decompositions for improved data analysis. Proceedings of the National Academy of Sci- ences, 106(3):697-702, 2009.
- [Mutny et al., 2020] Mojmir Mutny, Michał Dereziński, and Andreas Krause. Convergence analysis of block coordi- nate algorithms with determinantal sampling. In Interna- tional Conference on Artificial Intelligence and Statistics, pages 3110-3120, 2020.
- [Warlop et al., 2019] Romain Warlop, Jérémie Mary, and Mike Gartrell. Tensorized determinantal point processes for recommendation. In Proceedings of the 25th ACM SIGKDD International Conference on Knowledge Discov- ery & Data Mining, KDD '19, pages 1605-1615, 2019.
- [Williams and Seeger, 2001] Christopher K. I. Williams and Matthias Seeger. Using the Nyström method to speed up kernel machines. In T. K. Leen, T. G. Dietterich, and V. Tresp, editors, Advances in Neural Information Pro- cessing Systems 13, pages 682-688. MIT Press, 2001.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
We consider the task of selecting a small but representative sample of column vectors from a large matrix. Known as the Column Subset Selection Problem (CSSP), this is a wellstudied combinatorial optimization task with many applications in machine learning. In a commonly studied variant of this task, we aim to minimize the squared error of projecting all columns of the matrix onto the subspace spanned by the chosen column subset.
* This is an abridged version invited to IJCAI 2021 of a longer paper with the same title that appeared in NeurIPS 2020 and received a Best Paper Award.
† Corresponding author.
Definition 1 (CSSP). Given an m× n matrix A, pick a set S ⊆ {1, ..., n} of k column indices, to minimize
where ‖ · ‖F is the Frobenius norm, PS is the projection onto span{ai : i ∈ S} and ai denotes the ith column of A.
Another variant of the CSSP emerges in the kernel setting under the name Nystr¨om method [Williams and Seeger, 2001; Drineas and Mahoney, 2005; Gittens and Mahoney, 2016]. We also discuss this variant, showing how our analysis applies in this context. Both the CSSP and the Nystr¨om method are ways of constructing accurate low-rank approximations by using submatrices of the target matrix. Therefore, it is natural to ask how close we can get to the best possible rank k approximation error:
While the best possible rank k approximation has the lowest approximation error, the approximated matrix B is not input-sparse. As such, it is not interpretable since a practitioner is unable to attribute the quality of approximation to specific physical quantities represented by the columns of the matrix A [Mahoney and Drineas, 2009]. Such interpretable dimensionality reduction is desirable in many machine learning applications. Our goal is to find a subset S of size k for which the cost of interpretability is small, as measured by what we call the approximation factor: the ratio between ErA(S) and OPTk. Furthermore, a brute force search requires iterating over all (nk) subsets, which is prohibitively expensive, so we would like to find our subset more efficiently.
In terms of worst-case analysis, [Deshpande et al., 2006] gave a randomized method which returns a set S of size k such that:
While the original algorithm was slow, efficient implementations have been provided since then [Deshpande and Rademacher, 2010; Derezi´nski, 2019]. The method belongs to the family of cardinality constrained Determinantal Point Processes (DPPs), and will be denoted as S ∼ k-DPP(A⊤A); for an overview of DPPs, see Section 2 and [Derezi´nski and Mahoney, 2021]. The approximation factor k+1 is optimal in the worst-case, since for any 0 < k < n ≤ m and 0 < δ < 1, an m × n matrix A can be constructed for which ErA(S) OPTk ≥ (1-δ)(k+1) for all subsets S of size k. Yet it is known that, in practice, CSSP algorithms perform better than worst-case, so the question we consider is: how can we go beyond the usual worst-case analysis to accurately reflect what is possible in the CSSP?
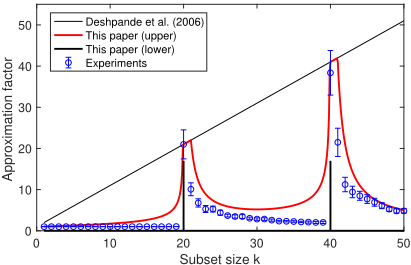
Contributions. We provide improved guarantees for the CSSP approximation factor, which go beyond the worst-case analysis and which lead to surprising conclusions.
- New upper bounds: We develop a family of upper bounds on the CSSP approximation factor (Theorem 1), which we call the Master Theorem as they can be used to derive a number of new guarantees. In particular, we show that when the data matrix A exhibits a known spectral decay, then (1) can often be drastically improved (Theorem 2).
- New lower bound: Even though the worst-case upper bound in (1) can often be loose, there are cases when it cannot be improved. We give a new lower bound construction (Theorem 3) showing that there are matrices A for which multiple different subset sizes exhibit worstcase behavior.
- Multiple-descent curve: Our upper and lower bounds reveal that for some matrices the CSSP approximation factor can exhibit peaks and valleys as a function of the subset size k (see Figure 1). We show that this phenomenon is an inherent property of the CSSP (Corollary 1).
2 Determinantal Point Processes
Since our main results rely on randomized subset selection via determinantal point processes (DPPs), we provide a brief overview of the relevant aspects of this class of distributions. First introduced by [Macchi, 1975], a determinantal point process is a probability distribution over subsets S ⊆ [n], where we use [n] to denote the set {1, ..., n}. The relative probability of a subset being drawn is governed by a positive semidefinite (p.s.d.) matrix K ∈ Rn×n , as stated in the definition below, where we use KS,S to denote the |S| × |S| submatrix of K with rows and columns indexed by S.
Definition 2. For an n × n p.s.d. matrix K, define S ∼ DPP(K) as a distribution over all subsets S ⊆ [n] so that
A restriction to subsets of size k is denoted as k-DPP(K).
DPPs can be used to introduce diversity in the selected set or to model the preference for selecting dissimilar items, where the similarity is stated by the kernel matrix K. DPPs are commonly used in many machine learning applications where these properties are desired, e.g., recommender systems [Warlop et al., 2019], model interpretation [Kim et al., 2016], text and video summarization [Gong et al., 2014], and others [Kulesza and Taskar, 2012]. For a recent survey, see [Derezi´nski and Mahoney, 2021].
Given a p.s.d. matrix K ∈ Rn×n with eigenvalues λ1, ... λn, the size of the set S ∼ DPP(K) is distributed as a Poisson binomial random variable, namely, the number of successes in n Bernoulli random trials where the probability of success in the ith trial is given by λi λi+1 . This leads to a simple expression for the expected subset size:
Note that if S ∼ DPP( 1α K), where α > 0, then Pr(S) is proportional to α-|S| det(KS,S), so rescaling the kernel by a scalar only affects the distribution of the subset sizes, giving us a way to set the expected size to a desired value (larger α means smaller expected size). Nevertheless, it is still often preferrable to restrict the size of S to a fixed k, obtaining a k-DPP(K) [Kulesza and Taskar, 2011].
Both DPPs and k-DPPs can be sampled efficiently, with some of the first algorithms provided by [Hough et al., 2006], [Deshpande and Rademacher, 2010], [Kulesza and Taskar, 2011] and others. These approaches rely on an eigendecomposition of the kernel K, at the cost of O(n3 ). When K = A⊤A, as in the CSSP, and the dimensions satisfy m ≪ n, then this can be improved to O(nm2 ). More recently, algorithms that avoid computing the eigendecomposition have been proposed [Derezi´nski, 2019; Derezi´nski et al., 2019; Calandriello et al., 2020; Anari et al., 2016], resulting in running times of ˜O(n) when given matrix K and ˜O(nm) for matrix A, assuming small desired subset size. See [Gautier et al., 2019] for an efficient Python implementation of DPP sampling.
The key property of DPPs that enables our analysis is a formula for the expected value of the random matrix that is the orthogonal projection onto the subspace spanned by vectors selected by DPP(A⊤A). In the special case when A is a square full rank matrix, the following result can be derived as a corollary of Theorem 1 by [Mutny et al., 2020], and a variant for DPPs over continuous domains can be found as Lemma 8 of [Derezi´nski et al., 2020].
Lemma 1. For any A and S ⊆ [n], let PS be the projection onto the span{ai : i ∈ S}. If S ∼ DPP(A⊤A), then
Lemma 1 implies a simple closed form expression for the expected error in the CSSP presented next. Here, we use a rescaling parameter α > 0 for controlling the distribution of the subset sizes. Note that it is crucial that we are using a DPP with random subset size, because the corresponding expression for the expected error of the fixed size k-DPP is combinatorial, and therefore much harder to work with.
Lemma 2. For any α > 0, if S ∼ DPP( 1α A⊤A), then
3 Main Results
Our upper bounds rely on the notion of effective dimensionality called stable rank [Alaoui and Mahoney, 2015]. Here, we use an extended version of this concept, as defined by [Bartlett et al., 2019].
Definition 3 (Stable rank). Let λ1 ≥ λ2 ≥ ... denote the eigenvalues of the matrix A⊤A. For 0 ≤ s < rank(A), we define the stable rank of order s as srs(A) = λ-1 s+1 ∑i>s λi.
In the following result, we define a family of functions Φs(k) which bound the approximation factor ErA(S)/OPTk in the range of k between s and s + srs(A). We call this the Master Theorem because we use it to derive a number of more specific upper bounds.
Theorem 1 (Master Theorem). Given 0 ≤ s < rank(A), let ts = s+srs(A), and suppose that s+ 7 ϵ4 ln2 1ϵ ≤ k ≤ ts-1, where 0 < ϵ ≤ 1 2 . If S ∼ k-DPP(A⊤A), then
Note that we separated out the dependence on ϵ from the function Φs(k), because the term (1 + 2ϵ)2 is an artifact of a concentration of measure analysis that is unlikely to be of practical significance. We conjecture that the dependence on ϵ can be eliminated from the statement entirely.
We next examine the consequences of the Master Theorem, starting with a sharp transition that occurs as k approaches the stable rank of A.
Remark 1 (Sharp transition). For any k it is true that:
- For all A, if k ≤ sr0(A)-1, then there is a subset S of size k such that ErA(S) OPTk = O(√k ).
- There is A such that sr0(A)-1 < k < sr0(A) and for every size k subset S, ErA(S) OPTk ≥ 0.9k.
Part 1 of Remark 1 follows from the Master Theorem by setting s = 0, whereas part 2 follows from the lower bound of [Guruswami and Sinop, 2012]. Observe how the worstcase approximation factor jumps from O(√k ) to Ω(k), as k approaches sr0(A). An example of this sharp transition is shown in Figure 1, where the stable rank of A is around 20.
While certain matrices directly exhibit the sharp transition fromRemark 1, many do not. In particular, for matrices with a known rate of spectral decay, the Master Theorem can be used to provide improved guarantees on the CSSP approximation factor over all subset sizes.
To illustrate this, we give novel bounds for the two most commonly studied decay rates: polynomial and exponential.
Theorem 2 (Examples without sharp transition). Let λ1 ≥ λ2 ≥ ... be the eigenvalues of A⊤A. There is an absolute constant c such that for any 0<c1≤c2, with γ = c2/c1, if:
1. (polynomial spectral decay) c1i-p ≤λi ≤c2i-p for all i, with p > 1, then S ∼ k-DPP(A⊤A) satisfies
- (exponential spectral decay) c1(1-δ)i ≤ λi ≤ c2(1-δ)i for all i, with δ ∈ (0, 1), then S ∼ k-DPP(A⊤A) satisfies
Note that for polynomial decay, unlike in (1), the approximation factor is constant, i.e., it does not depend on k. For exponential decay, our bound provides an improvement over (1) when δ = o(1). To illustrate how these types of bounds can be obtained from the Master Theorem, consider the function Φs(k) for some s > 0. The first term in the function, 1+ s k-s , decreases with k, whereas the second term (the square root) increases, albeit at a slower rate. This creates a U-shaped curve which, if sufficiently wide, has a valley where the approximation factor can get arbitrarily close to 1. This will occur when srs(A) is large, i.e., when the spectrum of A⊤A has a relatively flat region after the sth eigenvalue (Figure 1 for k between 20 and 40). Note that a peak value of some function Φs1 may coincide with a valley of some Φs2 , so only taking a minimum over all functions reveals the true approximation landscape predicted by the Master Theorem.
The peaks and valleys of the CSSP approximation factor suggested by Theorem 1 are in fact an inherent property of the problem, rather than an artifact of our analysis or the result of using a particular algorithm. We prove this by constructing a family of matrices A for which the best possible approximation factor is large, i.e., close to the worst-case upper bound of [Deshpande et al., 2006], not just for one size k, but for a sequence of increasing sizes.
Theorem 3 (Lower bound). For any δ ∈ (0, 1) and 0=k0< k1 <...<kt <n ≤ m, there is a matrix A ∈ Rm×n such that for any subset S of size ki, where i ∈ {1, ..., t},
Combining the Master Theorem with the lower bound of Theorem 3 we can easily provide an example matrix for which the optimal solution to the CSSP problem exhibits multiple peaks and valleys. We refer to this phenomenon as the multiple-descent curve.
Corollary 1 (Multiple-descent curve). For t ∈ N and δ ∈ (0, 1), there is a sequence 0 < kl1 < ku 1 < kl2 < ku 2 < ... < klt < ku t and A ∈ Rm×n such that for any i ∈ {1, ..., t}:
The Nystr¨om method. We briefly discuss how our results translate to guarantees for the Nystr¨om mehod, a variant of the CSSP in the kernel setting which has gained considerable interest in the machine learning literature [Drineas and Mahoney, 2005; Gittens and Mahoney, 2016]. In this context, rather than being given the column vectors explicitly, we consider the n×n matrix K whose entry (i, j) is the dot product between the ith and jth vector in the kernel space, 〈ai, aj〉K. A Nystr¨om approximation of K based on subset S is defined as ̂K(S) = CB†C⊤, where B is the |S| × |S| submatrix of K indexed by S, whereas C is the n × |S| submatrix with columns indexed by S.
Remark 2. If K = A⊤A and ‖ · ‖∗ is the trace norm, then ∥∥K- ̂K(S)∥∥∗ = ErA(S) for all S ⊆ {1, ..., n}. Moreover, the trace norm error of the best rank k approximation of K, is equal to the squared Frobenius norm error of the best rank k approximation of A, i.e.,
4 Empirical Evaluation
In this section, we provide an empirical evaluation designed to demonstrate how our improved guarantees for the CSSP and Nystr¨om method, as well as the multiple-descent phenomenon, can be easily observed on real datasets. We use a standard experimental setup for data subset selection using the Nystr¨om method [Gittens and Mahoney, 2016], where an n×n kernel matrix K for a dataset of size n is defined so that the entry (i, j) is computed using the Gaussian Radial Basis Function (RBF) kernel: 〈ai, aj〉K = exp(-‖ai-aj‖2 /σ2 ), where σ is a free parameter. We are particularly interested in the effect of varying σ. Nystr¨om subset selection is performed using S ∼ k-DPP(K) (Definition 2), and we plot the expected approximation factor E[‖K- ̂K(S)‖∗]/OPTk (averaged over 1000 runs), where ̂K(S) is the Nystr¨om approximation of K based on the subset S, ‖ · ‖∗ is the trace norm, and OPTk is the trace norm error of the best rank k approximation. This task is equivalent to the CSSP task defined on the matrix A such that K = A⊤A.
The aim of our empirical evaluation is to verify the following two claims motivated by our theory (and to illustrate that doing so is as easy as varying the RBF parameter σ):
- When the spectral decay is sufficiently slow/smooth, the approximation factor for CSSP/Nystr¨om is much better than suggested by previous worst-case bounds.
- A drop in spectrum around the kth eigenvalue results in a peak in the approximation factor near subset size k. Several drops result in the multiple-descent curve.
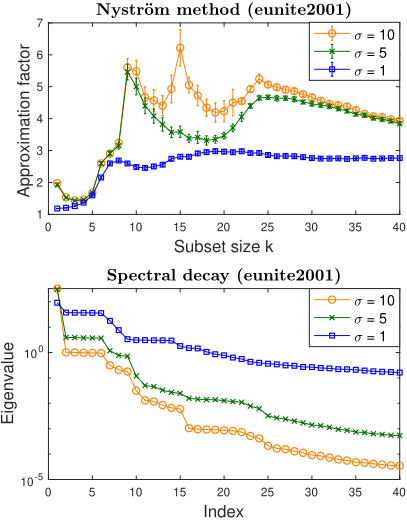
In Figure 2 (top), we plot the approximation factor against the subset size k (in the range of 1 to 40) for a benchmark regression dataset eunite2001 from the Libsvm repository [Chang and Lin, 2011]. In Figure 2 (bottom), we also show the top 40 eigenvalues of the RBF kernel K in decreasing order, for three different values of the parameter σ.
The dataset eunite2001 (Figure 2) exhibits a full multipledescent curve with up to three peaks for large values of σ (see top plot), and the peaks are once again aligned with the spectrum drops (see bottom plot). Decreasing σ gradually eliminates the peaks, resulting in a uniformly small approximation factor. Thus, both of our theoretical claims can easily be verified on this dataset simply by adjusting the RBF parameter.
While the right choice of the parameter σ ultimately depends on the downstream machine learning task, it has been observed that varying σ has a pronounced effect on the spectral properties of the kernel matrix, [Gittens and Mahoney, 2016]. The main takeaway from our results here is that, depending on the structure of the problem, we may end up in the regime where the Nystr¨om approximation factor exhibits a multiple-descent curve (e.g., due to a hierarchical nature of the data) or in the regime where it is relatively flat.
@inproceedings{ijcai2021p647,
  title     = {Improved Guarantees and a Multiple-descent Curve for Column Subset Selection and the Nystrom Method (Extended Abstract)},
  author    = {Dereziński, Michał and Khanna, Rajiv and Mahoney, Michael W.},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {4765--4769},
  year      = {2021},
  month     = {8},
  note      = {Sister Conferences Best Papers},
  doi       = {10.24963/ijcai.2021/647},
  url       = {https://doi.org/10.24963/ijcai.2021/647},
}
TY - CPAPER TI - Improved Guarantees and a Multiple-descent Curve for Column Subset Selection and the Nystrom Method (Extended Abstract) AU - Dereziński, Michał AU - Khanna, Rajiv AU - Mahoney, Michael W. T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 4765 EP - 4769 DO - 10.24963/ijcai.2021/647 UR - https://doi.org/10.24963/ijcai.2021/647 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





