
Faster Guarantees of Evolutionary Algorithms for Maximization of Monotone Submodular Functions
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 1661-1667.
https://doi.org/10.24963/ijcai.2021/229
Keywords
- Heuristic Search and Game Playing: Combinatorial Search and Optimisation
Abstract
In this paper, the monotone submodular maximization problem (SM) is studied. SM is to find a subset of size kappa from a universe of size n that maximizes a monotone submodular objective function f . We show using a novel analysis that the Pareto optimization algorithm achieves a worst-case ratio of (1 − epsilon)(1 − 1/e) in expectation for every cardinality constraint kappa < P , where P ≤ n + 1 is an input, in O(nP ln(1/epsilon)) queries of f . In addition, a novel evolutionary algorithm called the biased Pareto optimization algorithm, is proposed that achieves a worst-case ratio of (1 − epsilon)(1 − 1/e − epsilon) in expectation for every cardinality constraint kappa < P in O(n ln(P ) ln(1/epsilon)) queries of f . Further, the biased Pareto optimization algorithm can be modified in order to achieve a a worst-case ratio of (1 − epsilon)(1 − 1/e − epsilon) in expectation for cardinality constraint kappa in O(n ln(1/epsilon)) queries of f . An empirical evaluation corroborates our theoretical analysis of the algorithms, as the algorithms exceed the stochastic greedy solution value at roughly when one would expect based upon our analysis.
- [Badanidiyuru et al., 2014] Ashwinkumar Badanidiyuru, Baharan Mirzasoleiman, Amin Karbasi, and Andreas Krause. Streaming submodular maximization: massive data summarization on the fly. In ACM SIGKDD Inter- national Conference on Knowledge Discovery and Data Mining (KDD), 2014.
- [Bian et al., 2017] Andrew An Bian, Joachim M Buhmann, Andreas Krause, and Sebastian Tschiatschek. Guaran- tees for greedy maximization of non-submodular functions with applications. In International Conference on Machine Learning (ICML), 2017.
- [Bian et al., 2020] Chao Bian, Chao Feng, Chao Qian, and Yang Yu. An efficient evolutionary algorithm for subset selection with general cost constraints. In AAAI Confer- ence on Artificial Intelligence (AAAI), 2020.
- [Crawford, 2019] Victoria G. Crawford. An efficient evo- lutionary algorithm for minimum cost submodular cover. In International Joint Conference on Artificial Intelligence (IJCAI), 2019. IJCAI
- [Das and Kempe, 2011] Abhimanyu Das and David Kempe. Submodular meets Spectral: Greedy Algorithms for Sub- set Selection, Sparse Approximation and Dictionary Se- lection. Proceedings of the 28th International Conference on Machine Learning (ICML), 2011.
- [Friedrich and Neumann, 2014] Tobias Friedrich and Frank Neumann. Maximizing submodular functions under ma- troid constraints by evolutionary algorithms. In Interna- tional Conference on Parallel Problem Solving from Na- ture (PPSN), 2014.
- [Friedrich et al., 2010] Tobias Friedrich, Jun He, Nils Heb- binghaus, Frank Neumann, and Carsten Witt. Approxi- mating covering problems by randomized search heuristics using multi-objective models. Evolutionary Computation, 18(4):617-633, 2010.
- [Kaufman and Rousseeuw, 2009] Leonard Kaufman and Pe- ter J Rousseeuw. Finding groups in data: an introduction to cluster analysis, volume 344. John Wiley & Sons, 2009.
- [Kempe et al., 2003] David Kempe, Jon Kleinberg, and Éva Tardos. Maximizing the spread of influence through a so- cial network. In Proceedings of the ninth ACM SIGKDD international conference on Knowledge discovery and data mining, pages 137-146. ACM, 2003.
- [Krizhevsky et al., 2009] Alex Krizhevsky, Geoffrey Hinton, et al. Learning multiple layers of features from tiny images. Technical Report, University of Toronto, 2009.
- [Kulesza et al., 2012] Alex Kulesza, Ben Taskar, et al. De- terminantal point processes for machine learning. Founda- tions and Trends R in Machine Learning, 5(2-3):123-286, 2012.
- [Laumanns et al., 2002] Marco Laumanns, Lothar Thiele, Eckart Zitzler, Emo Welzl, and Kalyanmoy Deb. Running time analysis of multi-objective evolutionary algorithms on a simple discrete optimization problem. In Interna- tional Conference on Parallel Problem Solving from Na- ture (PPSN), 2002.
- [Mirzasoleiman et al., 2013] Baharan Mirzasoleiman, Amin Karbasi, Rik Sarkar, and Andreas Krause. Distributed submodular maximization: Identifying representative ele- ments in massive data. In Advances in Neural Information Processing Systems (NeurIPS), 2013.
- [Mirzasoleiman et al., 2015] Baharan Mirzasoleiman, Ash- winkumar Badanidiyuru, Amin Karbasi, Jan Vondrak, and Andreas Krause. Lazier Than Lazy Greedy. In AAAI Con- ference on Artificial Intelligence (AAAI), 2015.
- [Nemhauser and Wolsey, 1978] G L Nemhauser and L A Wolsey. Best Algorithms for Approximating the Maxi- mum of a Submodular Set Function. Mathematics of Op- erations Research, 3(3):177-188, 1978.
- [Neumann and Wegener, 2007] Frank Neumann and Ingo Wegener. Randomized local search, evolutionary algo- rithms, and the minimum spanning tree problem. Theo- retical Computer Science, 378(1):32-40, 2007.
- [Qian et al., 2015a] Chao Qian, Yang Yu, and Zhi-Hua Zhou. On constrained boolean pareto optimization. In Interna- tional Joint Conference on Artificial Intelligence (IJCAI), 2015. IJCAI
- [Qian et al., 2015b] Chao Qian, Yang Yu, and Zhi-Hua Zhou. Subset selection by pareto optimization. In Advances in Neural Information Processing Systems (NeurIPS), 2015.
- [Qian et al., 2017] Chao Qian, Jing-cheng Shi, Yang Yu, Ke Tang, and Zhi-hua Zhou. Subset Selection under Noise. In Advances in Neural Information Processing Systems (NeurIPS), 2017.
- [Roostapour et al., 2019] Vahid Roostapour, Aneta Neu- mann, Frank Neumann, and Tobias Friedrich. Pareto op- timization for subset selection with dynamic cost con- straints. In AAAI Conference on Artificial Intelligence (AAAI), 2019.
- [Soma and Yoshida, 2016] Tasuku Soma and Yuichi Yoshida. Maximizing monotone submodular functions over the integer lattice. In International Conference on Integer Programming and Combinatorial Optimization (IPCO), 2016.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
A function f : 2U → R≥0 defined on subsets of a ground set U of size n is monotone submodular if it possesses the following two properties: (i) For all A ⊆ B ⊆ U, f(A) ≤ f(B) (monotonicity); (ii) For all A ⊆ B ⊆ U and x /∈ B, f (A ∪ {x}) - f (A) ≥ f (B ∪ {x}) - f (B) (submodularity). Monotone submodular set functions are found in many applications in machine learning and data mining. Applications of SM include influence in social networks [Kempe et al., 2003], data summarization [Mirzasoleiman et al., 2013], dictionary selection [Das and Kempe, 2011], and monitor placement [Soma and Yoshida, 2016]. As a result, there has been much recent interest in optimization problems involving monotone submodular functions. One such optimization problem is the NP-hard Submodular Maximization Problem (SM), defined as follows.
Problem 1 (Submodular Maximization Problem (SM)). Let f : 2U → R≥0 be a monotone submodular function defined on subsets of the ground set U of size n, and f(∅) = 0. Given a budget κ ∈ [0, n], SM is to find argmax|X|≤κ f(X).
An instance of SM is referred to as SM(f, κ). It is assumed that the function f is provided as a value oracle, which when queried with a set X returns the value of f(X). Time is measured in queries of f, as is the convention in submodular optimization [Badanidiyuru et al., 2014].
To approximate SM, the standard greedy algorithm is very effective. Nemhauser and Wolsey [1978] showed that the standard greedy algorithm achieves the best ratio of (1-1/e) for SM in O(nk) queries to f. In addition, faster versions of the greedy algorithm have been developed for SM [Badanidiyuru et al., 2014; Mirzasoleiman et al., 2015]. In particular, the stochastic greedy algorithm (SG) of Mirzasoleiman et al. [2015] achieves ratio 1 - 1/e - ϵ in expectation in O(n ln(1/ϵ)) queries to f .
Alternatively, one may take the Pareto optimization approach to SM: Instead of maximizing f for a cardinality constraint κ, SM is re-formulated as a bi-objective optimization problem where the goal is to both maximize f as well as minimize cardinality. Instead of a single solution, we seek a pool of solutions none of which dominate another 1 . Greedy algorithms can be used to develop such a pool, however previous works [Friedrich and Neumann, 2014; Qian et al., 2015b] have employed bi-objective evolutionary algorithms because they iteratively improve the entire pool of solutions and can be run indefinitely. The evolutionary algorithm PARETO OPTIMIZATION (PO) has previously been shown to find a 1 - 1/e approximate solution to SM(f, κ) for all κ < P, where P ≤ n + 1 is an input, in expected O(nP 2 ) queries to f [Friedrich and Neumann, 2014]. Further, PO has been demonstrated to make significant empirical improvements over the standard greedy algorithms for SM [Qian et al., 2015b]. But as the size of data has grown exponentially in recent times, a query complexity that is cubic in n (for P = Ω(n)) makes these evolutionary algorithms a less attractive option.
1.1 Contributions
In this work, a novel analysis is provided for the algorithm PO, and it is proven that PO achieves a worst-case ratio of
1 In this context, a solution Y dominates X if f(X) ≤ f(Y ), |X| ≥ |Y |, and at least one of the two inequalities is strict.
(1 - ϵ)(1 - 1/e) in expectation for every instance SM(f, κ) with κ < P , where P ≤ n + 1 is an input, in O(nP ln(1/ϵ)) queries of f . This removes a factor of P from the query complexity of Friedrich and Neumann [2014]. This novel analysis has potential to improve the query complexity of other problems in monotone submodular optimization beyond SM [Qian et al., 2015a; Qian et al., 2017; Crawford, 2019; Bian et al., 2020]. This result is proven in Theorem 1.
Next, a novel algorithm BIASED PARETO OPTIMIZATION (BPO) is proposed that is a similar in spirit but faster version of PO for SM. It is proven that BPO achieves a worst-case ratio of (1-ϵ)(1-1/e-ϵ) in expectation for every instance SM(f, κ) with κ < P in O(n ln(P) ln(1/ϵ)) queries of f. This result is proven in Theorem 2. Further, a version of BPO for a specific cardinality constraint κ, κ-BIASED PARETO OPTIMIZATION (κ-BPO), is proven to achieve a worst-case ratio of (1 - ϵ)(1 - 1/e - ϵ) in expectation for instance SM(f, κ) in O(n ln(1/ϵ)) queries of f. This result is proven in Theorem 3. This new algorithm κ-BPO thus matches the optimal SG algorithm in terms of both approximation ratio and query complexity, while maintaining the ability of PO to continuously improve a pool of solutions.
The above theoretical results all extend to the more general setting of monotone γ-weakly submodular 2 functions [Das and Kempe, 2011], but with different approximation guarantees that depend on γ.
An empirical evaluation corroborates our theoretical analysis of the algorithms, as the algorithms exceed the SG solution value at roughly when one would expect based upon our analysis.
1.2 Additional RelatedWork
Evolutionary algorithms have been studied for many combinatorial optimization problems [Laumanns et al., 2002; Neumann and Wegener, 2007; Friedrich et al., 2010]. In particular, evolutionary algorithms have been analyzed for problems in submodular optimization including SM [Friedrich and Neumann, 2014; Qian et al., 2015b; Roostapour et al., 2019], submodular cover [Qian et al., 2015a; Crawford, 2019], SM with more general cost constraints [Bian et al., 2020], and noisy versions of SM [Qian et al., 2017].
Friedrich and Neumann [2014] studied a slight variant of PO where the pool S is initialized to contain a random set, and P = n. Friedrich and Neumann proved that their variant of PO finds a 1 - 1/e approximate solution to SM(f, κ) in expected O(n2 ln(n) + n2κ) queries of f. It is easy to modify their analysis to see that PO finds a 1 - 1/e approximate solution to SM(f, κ) for all κ < P in expected O(nP 2 ) queries of f. The argument of PO used in the proof of Theorem 1 of Section 2.1 is substantially different compared to the argument of Friedrich and Neumann because it analyzes the expected time until an expected approximation ratio is analyzed, resulting in a speedup to O(nP) queries of f. In addition, the result of Theorem 1 is in deterministic time due to an application of the Chernoff bound.
2 A function f : 2U → R≥0 is γ-weakly submodular if for all X ⊆ Y ⊆ U, and u /∈ Y , ∑u∈Y \X ∆f(X, u) ≥ γ (f(X ∪ Y ) - f(X)). If γ = 1, then f is submodular.
Qian et al. [2015b] considered the subset selection problem, which is a special case of the monotone γ-weakly submodular maximization problem. Qian et al. fixed P = 2κ, and showed that for the cardinality constraint κ PO finds a 1 - e-γ approximate solution in expected O(nκ2 ) queries of f . Their results can be generalized beyond subset selection to the monotone γ-weakly submodular maximization problem with cardinality constraint κ.
The algorithm BPO, presented in Section 2.2, uses a novel, biased selection procedure to identify sets for mutation. Because of the biased selection procedure, BPO is the first evolutionary algorithm that has an approximation guarantee in nearly linear queries of f close to that of the greedy algorithm for SM.
2 Algorithms and Theoretical Results
The theoretical contributions of the paper are presented in this section. In particular, a new theoretical analysis of the algorithm PARETO OPTIMIZATION (PO) is presented for SM in Section 2.1, the novel algorithm BIASED PARETO OPTIMIZATION (BPO) is presented and analyzed for SM in Section 2.2, and the faster modification of BPO for a specific cardinality constraint, κ-BIASED PARETO OPTIMIZATION (κBPO), is presented and analyzed for SM in Section 2.3. The full version of the paper includes an appendix where additional theoretical details from Section 2 are filled in.
Definitions and Notation The following notation and definitions will be used throughout Section 2. Let f : 2U → R≥0, X ⊆ U, and x ∈ U. (i) Marginal gain: ∆f(X, x) = f(X ∪ {x}) - f(X). (ii) The membership of x is flipped in X means that if x ∈ X, then x is removed from X; and if x /∈ X, then x is added to X. (iii) If ν is a random variable, then E [ν] denotes the expected value of ν. If A is a random event, then P (A) denotes the probability of A occurring. (iv) Let S ⊆ 2U . Then if there exists a unique Y ∈ S such that |Y | = i, define S[i] = Y . If no such Y exists, or there are multiple elements of S of cardinality i, S[i] is undefined. (v) Let X, Y ⊆ U. Then X ⪯ Y if f(Y ) ≥ f(X) and |Y | ≤ |X|. If at least one of the two inequalities is strict, then X ≺ Y and Y dominates X. If f(Y ) = f(X) and |Y | = |X| then it is said that X is equivalent to Y .
2.1 Pareto Optimization (PO)
In this section, it is proven that in time O(nP ln(1/ϵ)), PO produces a (1-ϵ)(1-1/e) approximate solution in expectation for every cardinality constraint κ < P , where P ≤ n+1 is an input. If P = O(κ) for a fixed cardinality constraint κ, then PO produces solutions for SM with similar theoretical guarantees to that of the standard greedy algorithm in the same asymptotic time, which shows the practicality of evolutionary algorithms such as PO for SM.
Description of PO
In this section, PO (Alg. 1) is described. The set S ⊆ 2U is referred to as the pool, and each iteration of the for loop is referred to as an iteration. The pool initially contains only the empty set; its maximum size is determined by input parameter P. During each iteration, i ∈ {0, ..., P - 1} is chosen
Algorithm 1 PO (f, P, T ): PARETO OPTIMIZATION (PO)
1: Input: f : 2U →R≥0; P ∈ {1, ..., n+1}; T ∈ Z≥0. 2: Output: S ⊆ 2U . 3: S ← {∅} 4: for t ← 1 to T do 5: i ← UNIFORM-RANDOM({0, ..., P - 1}) 6: if S[i] exists then 7: B ←S[i] 8: B′ ←MUTATE (B) 9: if |B′ | < P and ∄Y ∈ S such that B′ ⪯ Y then 10: S ← S ∪ {B′ } \ {Y ∈ S : Y ≺ B′ } 11: end if 12: end if 13: end for 14: return Suniformly randomly (Line 5 of Alg. 1), and if B = S[i] exists then it is selected from S to be mutated, otherwise PO continues to the next iteration. The subroutine MUTATE takes B and randomly mutates it into B′ ⊆ U as follows: for each u ∈ U, flip the membership of u in B with probability 1/n. Finally, if no set in the pool dominates or is equivalent to B′ and |B′ | < P, then B′ is added to the pool and all sets that B′ dominates are removed. There is at most one new query of f on each iteration of PO, and therefore the input T is equal to the query complexity. Pseudocode for the subroutine MUTATE is provided in the appendix.
Analysis of PO for SM
In this section, the approximation result of the algorithm PO for SM is presented. Omitted proofs are given in the appendix. The statement of Theorem 1 easily generalizes to γweakly submodular objectives f, where 1 - 1/e is replaced with 1 - 1/eγ .
Theorem 1. Suppose PO is run with input (f, P, T), where f : 2U → R≥0 is monotone submodular, P ∈ {1, ..., n + 1}, and T > 8enP ln(1/ϵ). Let S be the pool of PO at the end of iteration T . Then for any κ < P ,
Overview of Proof of Theorem 1 Given SM(f, κ) with optimal solution A∗ , the standard greedy algorithm iteratively picks into its solution the element in U of highest marginal gain until κ elements have been picked. Existing analyses of PO for SM [Friedrich and Neumann, 2014; Qian et al., 2015b] analyze the time it takes until essentially the standard greedy algorithm randomly occurs within PO. If instead of iteratively picking the element of highest marginal gain, a uniformly random element of A∗ (possibly already chosen) is picked into the solution until κ elements are picked (this could be viewed as an idealized version of the stochastic greedy algorithm of Mirzasoleiman et al. [2015]) then the same approximation guarantee as the standard greedy algorithm (1 - 1/e) is achieved in expectation. In the proof of Theorem 1, the expected time until this second algorithm randomly occurs within PO is analyzed, which is a factor of P faster.
Proof. Line numbers referenced are those in Algorithm 1. Throughout the proof of Theorem 1, the probability space of all possible runs of PO with the stated inputs is considered. Let κ < P, and let A∗ = argmax|X|≤κ f(X). We may assume that |A∗ | = κ, since f is monotone. In the proof of Theorem 1, the random variable ω will be used, defined inductively as follows:
- (i) Before the first iteration of PO, ω is set to 0.
- (ii) If the following two conditions aremet, ω is incremented at the end of an iteration: 1) B = argmax{f(X) : X ∈ S, |X| ≤ ω} is selected on Line 5; and 2) MUTATE on Line 8 results in the membership of a single element a∗ ∈ A∗ being flipped (i.e., it is either the case that MUTATE returns B′ = B ∪ {a∗ } for a∗ ∈ A∗ \ B or B′ = B \ {a∗ } for a∗ ∈ A∗ ∩ B).
Intuitively, ω is used to track a solution within S that has a high f value relative to its cardinality. In particular, the following lemma describes the key property of ω.
Lemma 1. At the end of every iteration of PO
A further key point is that once a solution appears in PO, i.e., it is returned by MUTATE, there always exists at least as good of a solution within S.
Lemma 2. Let Y ⊆ U and |Y | ≤ a < P. If Y is returned by MUTATE during iteration i of PO, then at the end of any iteration j ≥ i it holds that max{f(X) : X ∈ S, |X| ≤ a} ≥ f (Y ).
Let event F be that at the completion of a run of PO, ω ≥ κ. Then it follows from Lemmas 1 and 2 that
Then the remainder of the proof of Theorem 1 is to deal with the probability that ω reaches κ. To this end, the following lemma states that the run of PO may be interpreted as a Bernoulli process.
Lemma 3. Consider a run of PO as a series of Bernoulli trials Y1, ..., YT , where each iteration is a trial and a success is defined to be when ω is incremented. Then Y1, ..., YT are independent, identically distributed Bernoulli trials where the probability of success is
Then Lemma 3 and the Chernoff bound can be used to prove that the probability of ω not reaching κ after T ≥ 8enP ln(1/ϵ) iterations of PO is small. This is stated in the following lemma.
Finally, Theorem 1 follows from the law of total expectation, Inequality 1 and Lemma 4.
Algorithm 2 BPO (f, P, T, p, ϵ, ξ): BIASED PARETO OPTIMIZATION
- 1: Input: f : 2U → R≥0; P ∈ {1, ..., n + 1}; T ∈ Z≥0;
p ∈ (0, 1]; ϵ ∈ (0, 1); ξ ∈ (0, 1). 2: Output: S ⊆ 2U . 3: M ← ⌈ln(P )/ ln (1/ξ)⌉ 4: βi ← 0, ℓi ← 0, Hi ← e ln(1/ϵ)/ξ i ∀i ∈ {1, ...,M} 5: S ← {∅} 6: for t ← 1 to T do 7: i ← UNIFORM-RANDOM({0, ..., P - 1}) 8: if FLIP-COIN(p) = heads then 9: j ← UNIFORM-RANDOM({1, ...,M}) 10: i ← | argmax{f(X) : X ∈ S, |X| ≤ βj}| 11: ℓj ← ℓj + 1 12: if ℓj =Hj then 13: ℓj ← 0 14: βj ← βj + 1 15: end if 16: end if 17: if S[i] exists then 18: B ←S[i] 19: B′ ←MUTATE (B) 20: if |B′ | < P and ∄Y ∈ S such that B′ ⪯ Y then 21: S ← S ∪ {B′ } \ {Y ∈ S : Y ≺ B′ } 22: end if 23: end if 24: end for 25: return S2.2 Biased Pareto Optimization (BPO)
BIASED PARETO OPTIMIZATION (BPO) is a novel evolutionary algorithm with nearly the same approximation results as PO for SM in faster time. Specifically, it is proven that in time O(n ln(P ) ln(1/ϵ)), BPO finds a (1 - ϵ)(1 - 1/e - ϵ)- approximate solution in expectation for every cardinality constraint κ < P, where P ≤ n + 1 is an input. Thus, BPO is faster than PO by a factor of Ω(P/ ln(P)); further, it works similarly to PO but has a biased selection procedure instead of choosing uniformly randomly.
Description of BPO
In this section, BPO (Alg. 2) is presented. Pseudocode for BPO can be found in Alg. 2. In overview, BPO follows a similar iterative procedure to PO: every iteration of the for loop, a set in the S is chosen for mutation; and only sets that are not dominated by any others are kept. The difference from PO is in the selection of the set for mutation; a certain subset of sets in S are selected more frequently than others, as determined by the parameters p ∈ (0, 1], ϵ ∈ (0, 1), and ξ ∈ (0, 1), and the variables βj for j ∈ {1, ...,M}, where M = ⌈ln(P )/ ln (1/ξ)⌉. There is at most one new query of f on each iteration of BPO, and therefore the input T is equal to the query complexity. Next, the selection process is described in detail.
Selection process During each iteration, with probability p BPO chooses j from {1, ...,M} uniformly randomly (Line 9) and then sets i = | argmax{f(X) : X ∈ S, |X| ≤ βj}| (Line 10). Otherwise i is chosen uniformly randomly from
{0, ..., P - 1} (Line 7). If B = S[i] exists then it is selected from S to be mutated, otherwise BPO continues to the next iteration. Initially, βj = 0 ∀j ∈ {1, ...,M}. βj is incremented to βj + 1 if on Hj =e ln(1/ϵ)/ξ j iterations since the last increment of βj j was chosen on Line 9. The variable ℓj is used to determine when βj should be incremented: βj is incremented during an iteration if and only if ℓj is set to 0 on Line 13. Notice that if p = 0, BPO is equivalent to PO.
Analysis of BPO for SM
The approximation results of BPO for SM are now presented. Lemmas referenced in the proof of Theorem 2 can be found in the appendix. The statement of Theorem 2 easily generalizes to γ-weakly submodular objectives f, where 1 - 1/e - ϵ is replaced with 1 - 1/eγ - ϵ.
Theorem 2. Suppose BPO is run with input (f, P, T, p, ϵ, ξ) where f : 2U → R≥0 is monotone submodular, P ∈ {1, ..., n + 1}, T ≥ max{αn⌈ln(P )/ ln (1/ξ)⌉, β ln(n)⌈ln(P )/ ln (1/ξ)⌉}, where α = 2e ln(1/ϵ)/p and β = 8/p, p ∈ (0, 1], ϵ ∈ (0, 1), and ξ ∈ (0, 1). Let S be the pool of BPO at the end of iteration T . Then for any κ < P ,
Overview of Proof of Theorem 2 Consider SM(f, κ) with optimal solution A∗ . Recall that in the proof of Theorem 1 in Section 2.1, the approximation ratio for SM(f, κ) was proven by analyzing the expected time until a variable ω reaches κ. In order for ω to be incremented during an iteration, | argmax{f(X) : X ∈ S, |X| ≤ ω}| must be selected on Line 5, which occurs with probability 1/P . If we instead consider an alternative version of PO where the selection is biased towards choosing | argmax{f(X) : X ∈ S, |X| ≤ ω}| with constant probability α > 1/P, then ω reaches κ faster. The difficulty is that the value of ω is unknown, since it depends on MUTATE flipping the membership of an a∗ ∈ A∗ and nothing else. The idea behind BPO is that we can approximately track ω, and therefore bias the selection. In particular, for each SM(f, κ) with κ < P, there exists a βi that is approximately equal to the corresponding ω for κ.
Proof. Proofs of lemmas used can be found in the appendix. Lines numbers referenced are those in Algorithm 2. Throughout the proof of Theorem 2, the probability space of all possible runs of BPO with the stated inputs is considered. An iteration of the for loop in BPO is simply referred to as an iteration.
Consider any κ < P. Define A∗ = argmax|X|≤κ f(X). Without loss of generality we may assume that |A∗ | = κ, since f is monotone. There exists q ∈ {1, ..., ⌈ln(P )/ ln (1/ξ)⌉} such that
Then define ω = βq .
The ω defined here serves a similar purpose to that defined in the proof of Theorem 1; To track a solution within S that has a high f value relative to its cardinality, as described in the following lemma.
Lemma 5. At the end of every iteration of BPO
In addition, the property of PO detailed in Lemma 2 of Theorem 1 clearly also holds for BPO.
Define the event F to be that at the completion of a run of BPO ℓq has been incremented (Line 11 of Algorithm 2) Hqκ times. If ℓq has been incremented Hqκ times, then one may see that ω has been incremented κ times. Once ω reaches κ, it clearly follows from Lemmas 5 and 2 that
where A = argmaxX∈S,|X|≤κ f (X).
We now analyze the probability that ℓq has been incremented Hqκ times. To this end, we have the following lemma.
Lemma 6. Consider a run of BPO as a series of Bernoulli trials Y1, ..., YT , where each iteration is a trial and a success is defined to be when ℓq is incremented. Then Y1, ..., YT are independent, identically distributed Bernoulli trials where the probability of success is p/⌈ln(P)/ ln (1/ξ)⌉.
Finally, an analogous argument to that of Theorem 1 can be used to complete the proof of Theorem 2. In particular, we bound the probability of event F not occurring after T ≥ max{αn⌈ln(P )/ ln (1/ξ)⌉, β ln(n)⌈ln(P )/ ln (1/ξ)⌉}, where α = 2e ln(1/ϵ)/p and β = 8/p, iterations of BPO by ϵ using the Chernoff bound, and then apply the law of total expectation. The details of the argument can be found in the appendix.
2.3 κ-Biased Pareto Optimization (κ-BPO)
If a specific cardinality constraint κ is provided, a modified version of BPO, κ-BIASED PARETO OPTIMIZATION (κ-BPO), can produce an approximate solution in expectation even faster than BPO. In this section, the algorithm κ-BPO is described, and it is proven that κ-BPO finds a (1 - ϵ)(1 - 1/e - ϵ)-approximate solution to SM(f, κ) in O(n ln(1/ϵ)) queries of f .
Description of κ-BPO
Pseudocode for κ-BPO can be found in the appendix. κBPO is similar to BPO except κ-BPO is only biased towards picking a single element of S, determined by the variable β. The input parameters of κ-BPO are the same as BPO except ξ ∈ (0, 1) is not needed.
During each iteration, with probability p κ-BPO sets i = | argmax{f(X) : X ∈ S, |X| ≤ β}|. Otherwise i is chosen uniformly randomly from {0, ..., P - 1}. If B = S[i] exists then it is selected from S to be mutated, otherwise κ-BPO continues to the next iteration. Initially, β = 0. β is incremented to β + 1 if on H = en ln(1/ϵ)/κ iterations since the last increment of β, i was chosen to be | argmax{f(X) : X ∈ S, |X| ≤ β}|. The variable ℓ is used to determine when β should be incremented: β is incremented during an iteration if and only if ℓ is set to 0.
Analysis of κ-BPO for SM
The approximation results of κ-BPO for SM are now presented. The statement of Theorem 3 easily generalizes to γweakly submodular objectives f in the analogous manner as BPO.
Theorem 3. Suppose κ-BPO is run with input (f, κ, P, T, p, ϵ) where f : 2U → R≥0 is monotone submodular, κ ∈ {1, ..., n} P ∈ {κ + 1, ..., n + 1}, T ≥ max{2en ln(1/ϵ)/p, 8 ln(n)/p}, p ∈ (0, 1], and ϵ ∈ (0, 1). Let S be the pool of κ-BPO at the end of iteration T . Then,
Proof. The proof of Theorem 3 is any easy modification of the proof of Theorem 2 and therefore details are left to the reader. The key point is that Lemma 6 should be replaced with the following lemma.
Lemma 7. Consider a run of κ-BPO as a series of Bernoulli trials Y1, ..., YT , where each iteration is a trial and a success is defined to be when ℓ is incremented. Then Y1, ..., YT are independent, identically distributed Bernoulli trials where the probability of success is p.
3 Experimental Evaluation
In this section, the algorithms PO and κ-BPO are evaluated on instances of data summarization with submodular and non-submodular objectives f. In summary, the faster runtime for PO proven in Theorem 1 is demonstrated empirically. Also, the results demonstrate that κ-BPO quickly finds solutions better than the standard greedy algorithm, the stochastic greedy algorithm SG [Mirzasoleiman et al., 2015], and PO.
The algorithms evaluated in Section 3 are:
- the standard greedy algorithm [Nemhauser and Wolsey, 1978]
- the stochastic greedy (SG) algorithm of [Mirzasoleiman et al., 2015].
- PO: the variant of the algorithm of Friedrich and Neumann [2014] as detailed in Alg. 1 and analyzed in Section 2.1.
- κ-BPO: the version of BPO that biases towards only one set in S, based on the input κ as discussed in Section 2.3.
For both PO and κ-BPO, the parameter P = 2κ is used on all instances.
3.1 Application
In data summarization (DS), we have a set U of data points and we wish to find a subset of U of cardinality κ that best summarizes the entire dataset U. f : 2U → R≥0 takes X ⊆ U to a measure of how effectively X summarizes U. For the ground set U, we use: (i) A set of 10 dimensional vectors drawn from κ gaussian distributions (Gaussian), and (ii) a set of 32×32 color images from the CIFAR-100 dataset
[Krizhevsky et al., 2009] each represented by a 3072 dimensional vector of pixels (CIFAR). For the objective f, we use: (i) The monotonic and submodular objective k-medoid objective [Kaufman and Rousseeuw, 2009] (fMED), and (ii) the monotone weakly submodular objective based on Determinantal Point Process (DPP) [Kulesza et al., 2012] (fDPP ). A lower bound on the submodularity ratio has been proven for the latter objective [Bian et al., 2017].
3.2 Results
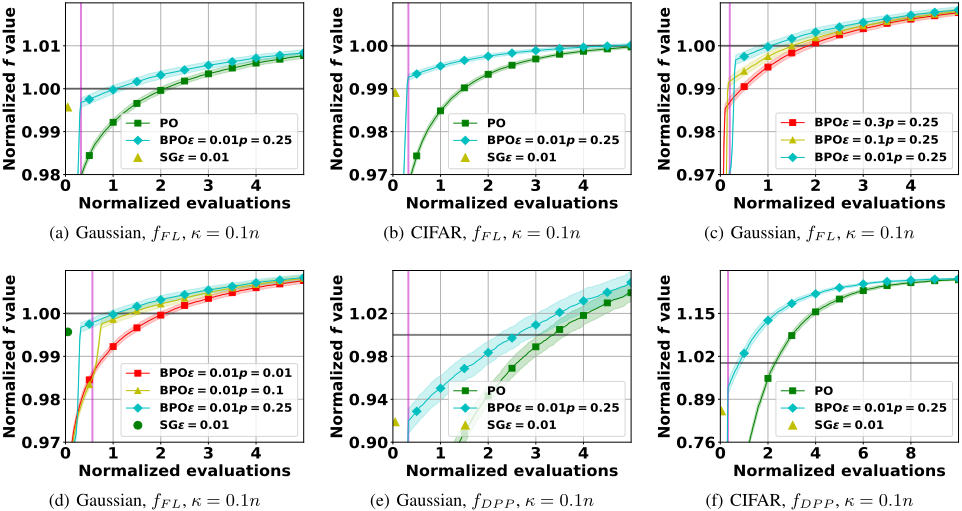
The experimental results are shown in Figure 1. All results are the mean of 50 repetitions of each algorithm; shaded regions represent one standard deviation from the mean. Objective and runtime are normalized by the objective value of and number of queries made (nκ) by the standard greedy algorithm. The value of the solution of the standard greedy algorithm is plotted as a dotted gray horizontal line y = 1. The time where β in κ-BPO reached κ is plotted as a vertical magenta line.
The best solution value obtained by each algorithm is shown as the rightmost point in each plot. Both κ-BPO and PO were eventually able to find better solutions than the standard greedy algorithm (i.e., normalized value > 1.0), especially on the non-submodular objective (Figures 1(e) and 1(f)). Observe that PO typically exceeds the stochastic greedy objective value within cκn, where c ≤ 2. This behavior corroborates our theoretical analysis that PO achieves a good solution in expectation in O(κn) queries. In addition, κ-BPO exceeds the SG value in cn queries. Finally, for PO, recall that the theoretical anlaysis shows that for any κ < P, the approximation ratio holds.
Because PO and κ-BPO can be terminated at any time, the running time may be compared by observing where any vertical line intersects the curves for each algorithm. The running time of the standard greedy corresponds to the line x = 1 (not plotted). κ-BPO reaches solution values closer to the standard greedy algorithm in significantly faster time than PO, as expected by its design. The effect of varying the parameters ε and p on the behavior of κ-BPO is shown in Figs. 1(c), 1(d), respectively: smaller ε leads to a higher initial increase but the initial increase is slower, while smaller p slows down the rate of the initial increase.
4 Conclusions
In this work, we have re-analyzed the evolutionary algorithm PO, originally analyzed for submodular maximization by Friedrich and Neumann [2014], and showed that it achieves nearly the optimal worst-case ratio in expectation on SM for any κ < P in O(nP) queries. In contrast, Friedrich and Neumann [2014] showed that the optimal worst-case ratio is achieved in expected O(nP 2 ) queries. This improved rate of convergence is supported by an empirical evaluation.
Further, it has been shown that changing the selection process in PO results in improved query complexity to O(n log(P)) to obtain the same approximation results. A variant of this algorithm κ-BPO is shown empirically to have a much faster initial rate of convergence to a good solution than PO, without sacrificing the long-term behavior of the PO algorithm.
@inproceedings{ijcai2021p229,
  title     = {Faster Guarantees of Evolutionary Algorithms for Maximization of Monotone Submodular Functions},
  author    = {Crawford, Victoria G.},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {1661--1667},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/229},
  url       = {https://doi.org/10.24963/ijcai.2021/229},
}
TY - CPAPER TI - Faster Guarantees of Evolutionary Algorithms for Maximization of Monotone Submodular Functions AU - Crawford, Victoria G. T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 1661 EP - 1667 DO - 10.24963/ijcai.2021/229 UR - https://doi.org/10.24963/ijcai.2021/229 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





