
Step-Wise Hierarchical Alignment Network for Image-Text Matching
Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence. Main Track. Pages 765-771.
https://doi.org/10.24963/ijcai.2021/106
Keywords
- Computer Vision: Language and Vision
Abstract
Image-text matching plays a central role in bridging the semantic gap between vision and language. The key point to achieve precise visual-semantic alignment lies in capturing the fine-grained cross-modal correspondence between image and text. Most previous methods rely on single-step reasoning to discover the visual-semantic interactions, which lacks the ability of exploiting the multi-level information to locate the hierarchical fine-grained relevance. Different from them, in this work, we propose a step-wise hierarchical alignment network (SHAN) that decomposes image-text matching into multi-step cross-modal reasoning process. Specifically, we first achieve local-to-local alignment at fragment level, following by performing global-to-local and global-to-global alignment at context level sequentially. This progressive alignment strategy supplies our model with more complementary and sufficient semantic clues to understand the hierarchical correlations between image and text. The experimental results on two benchmark datasets demonstrate the superiority of our proposed method.
- [Anderson et al., 2018] Peter Anderson, Xiaodong He, Chris Buehler, Damien Teney, Mark Johnson, Stephen Gould, and Lei Zhang. Bottom-up and top-down attention for im- age captioning and visual question answering. In IEEE Conference On Computer Vision And Pattern Recognition, pages 6077-6086, 2018.
- [Antol et al., 2015] Stanislaw Antol, Aishwarya Agrawal, Ji- asen Lu, Margaret Mitchell, Dhruv Batra, C Lawrence Zit- nick, and Devi Parikh. Vqa: Visual question answering. In IEEE International Conference On Computer Vision, pages 2425-2433, 2015.
- [Chen et al., 2020] Hui Chen, Guiguang Ding, Xudong Liu, Zijia Lin, Ji Liu, and Jungong Han. Imram: Iterative matching with recurrent attention memory for cross-modal image-text retrieval. In IEEE Conference On Computer Vi- sion And Pattern Recognition, pages 12655-12663, 2020.
- [Faghri et al., 2017] Fartash Faghri, David J Fleet, Jamie Ryan Kiros, and Sanja Fidler. Vse++: Im- proving visual-semantic embeddings with hard negatives. ArXiv Preprint ArXiv:1707.05612, 2017.
- [Feng et al., 2019] Yang Feng, Lin Ma, Wei Liu, and Jiebo Luo. Unsupervised image captioning. In IEEE Confer- ence On Computer Vision And Pattern Recognition, pages 4125-4134, 2019.
- [Frome et al., 2013] Andrea Frome, Greg S Corrado, Jon Shlens, Samy Bengio, Jeff Dean, Marc'aurelio Ranzato, and Tomas Mikolov. Devise: A deep visual-semantic em- bedding model. In Advances In Neural Information Pro- cessing Systems, pages 2121-2129, 2013.
- [Hu et al., 2019] Zhibin Hu, Yongsheng Luo, Jiong Lin, Yan Yan, and Jian Chen. Multi-level visual-semantic align- ments with relation-wise dual attention network for image and text matching. In International Joint Conference on Artificial Intelligence, pages 789-795, 2019. IJCAI
- [Karpathy and Fei-Fei, 2015] Andrej Karpathy and Li Fei- Fei. Deep visual-semantic alignments for generating im- age descriptions. In IEEE Conference On Computer Vision And Pattern Recognition, pages 3128-3137, 2015.
- [Kiros et al., 2014] Ryan Kiros, Ruslan Salakhutdinov, and Richard S Zemel. Unifying visual-semantic embeddings with multimodal neural language models. ArXiv Preprint ArXiv:1411.2539, 2014.
- [Krizhevsky et al., 2012] A. Krizhevsky, I. Sutskever, and G. E. Hinton. Imagenet classification with deep convo- lutional neural networks, 2012. Advances In Neural Infor- mation Processing Systems.
- [Lee et al., 2018] Kuang-Huei Lee, Xi Chen, Gang Hua, Houdong Hu, and Xiaodong He. Stacked cross atten- tion for image-text matching. In European Conference On Computer Vision, pages 201-216, 2018.
- [Ma et al., 2015] Lin Ma, Zhengdong Lu, Lifeng Shang, and Hang Li. Multimodal convolutional neural networks for matching image and sentence. In IEEE International Con- ference On Computer Vision, pages 2623-2631, 2015.
- [Nam et al., 2017] Hyeonseob Nam, Jung-Woo Ha, and Jeonghee Kim. Dual attention networks for multimodal reasoning and matching. In IEEE Conference On Com- puter Vision And Pattern Recognition, pages 299-307, 2017.
- [Song and Soleymani, 2019] Yale Song and Mohammad So- leymani. Polysemous visual-semantic embedding for cross-modal retrieval. In IEEE Conference On Computer Vision And Pattern Recognition, pages 1979-1988, 2019.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, ŁUkasz Kaiser, and Illia Polosukhin. Attention is all you need. In Advances In Neural Information Processing Sys- tems, pages 5998-6008, 2017.
- [Wang et al., 2019] Zihao Wang, Xihui Liu, Hongsheng Li, Lu Sheng, Junjie Yan, Xiaogang Wang, and Jing Shao. Camp: Cross-modal adaptive message passing for text- image retrieval. In IEEE International Conference On Computer Vision, pages 5764-5773, 2019.
- [Wang et al., 2020a] Haoran Wang, Zhong Ji, Zhigang Lin, Yanwei Pang, and Xuelong Li. Stacked squeeze-and- excitation recurrent residual network for visual-semantic matching. Pattern Recognition, 105:107359, 2020.
- [Wang et al., 2020b] Haoran Wang, Ying Zhang, Zhong Ji, Yanwei Pang, and Lin Ma. Consensus-aware visual- semantic embedding for image-text matching. In Euro- pean Conference On Computer Vision (ECCV), pages 18- 34, 2020.
- [Wang et al., 2020c] Jingwen Wang, Lin Ma, and Wenhao Jiang. Temporally grounding language queries in videos by contextual boundary-aware prediction. In AAAI Confer- ence On Artificial Intelligence, pages 12168-12175, 2020.
- [Wang et al., 2020d] Sijin Wang, Ruiping Wang, Ziwei Yao, Shiguang Shan, and Xilin Chen. Cross-modal scene graph matching for relationship-aware image-text retrieval. In The IEEE Winter Conference On Applications Of Com- puter Vision, pages 1508-1517, 2020.
- [Wu et al., 2019] Yiling Wu, Shuhui Wang, Guoli Song, and Qingming Huang. Learning fragment self-attention em- beddings for image-text matching. In ACM International Conference On Multimedia, pages 2088-2096, 2019.
- [Yu et al., 2020] Yunlong Yu, Zhong Ji, Jungong Han, and Zhongfei Zhang. Episode-based prototype generating network for zero-shot learning. In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, pages 14035-14044, 2020.
- [Zhang et al., 2019] Wei Zhang, Bairui Wang, Lin Ma, and Wei Liu. Reconstruct and represent video contents for cap- tioning via reinforcement learning. IEEE Transactions On Pattern Analysis And Machine Intelligence, 42(12):3088- 3101, 2019.
- [Zhang et al., 2020] Qi Zhang, Zhen Lei, Zhaoxiang Zhang, and Stan Z Li. Context-aware attention network for image- text retrieval. In IEEE Conference On Computer Vision And Pattern Recognition, pages 3536-3545, 2020.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Associating vision with language and exploring the correlations between them have attracted broad attention in the field of Artificial Intelligence during last decades. Thanks to the rapid development of deep learning [Krizhevsky et al., 2012], plenty of areas have made tremendous progress in effectively bridging vision and language, such as visual question answering (VQA) [Antol et al., 2015; Anderson et al., 2018], image captioning [Zhang et al., 2019; Feng et al., 2019], image-text matching [Song and Soleymani, 2019; Wang et al., 2020b], visual grounding [Wang et al., 2020c], and zero-shot learning [Yu et al., 2020]. In this paper, we focus on the task of image-text matching, which aims to provide flexible retrieval across samples from different modalities. It remains challenging since it is difficult for machines to understand the heterogeneous contents in images and texts so as to accurately infer the cross-modal similarity, especially when encountering hard negative example pairs which share similar semantics but convey slight differences (As shown in Fig.1).
∗ indicates corresponding author
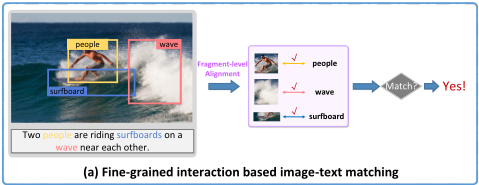
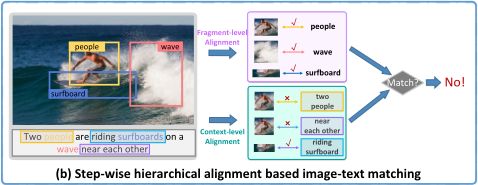
To address this problem, early works [Frome et al., 2013; Faghri et al., 2017] usually map the whole images and texts into a shared embedding space, in which the cross-modal relevance can be directly measured by calculating the distance between heterogeneous samples. However, these global embedding based learning methods ignore that a visual or textual instance is actually composed of significant local fragments (e.g., salient regions in image and key words in text) and insignificant ones. Therefore, represent them from a global view may not fully exploit the fine-grained details in fragment-level and introduce some noisy background information. Based on this observation, another stride of approaches [Karpathy and Fei-Fei, 2015; Lee et al., 2018] have been proposed to mitigate this issue by concentrating on the fine-grained interactions between image regions and textual words. These fine-grained interaction based learning methods align image and text by aggregating the local similarities of all available region-word pairs. Afterwards, recent works resort to attention mechanism [Vaswani et al., 2017; Nam et al., 2017; Lee et al., 2018; Hu et al., 2019] to pinpoint the discriminative parts of fragment-level representations, which can neatly align image and text via discovering more fine-grained cross-modal correspondence and further leads to promising matching performance.
However, most existing fine-grained interaction learning based methods tend to discriminate image-text pairs according to the apparently distinct and distinguishable portions, which may consequently fail to distinguish those hard negative examples with similar semantic contents but slightly different context information. For example, as shown in Fig.1 (a), previous fine-grained interaction based methods may probably assign high matching score to the combination of the given image and the sentence "Two people are riding surfboards on a wave near each other.", due to they both contain the salient foreground objects, e.g. "people", "surfboard" and "wave". The failure may be attributed to the inability of the previous methods, which only rely on single-step inference whilst pay less attention to the global context information that can provide some high-level clues between semantically similar samples. By contrast, when people want to precisely associate an image with a specific text, we typically not only attend to the fragment-level entities ("people", "surfboard", "wave"), but also leverage the context-level semantic information, e.g., attributes ("two") and relationships ("near each other"), as complementary hints to capture the complicated cross-modal correspondence. Accordingly, these observations motivate us to explore multi-step visual-semantic alignments for cross-modal correlation learning.
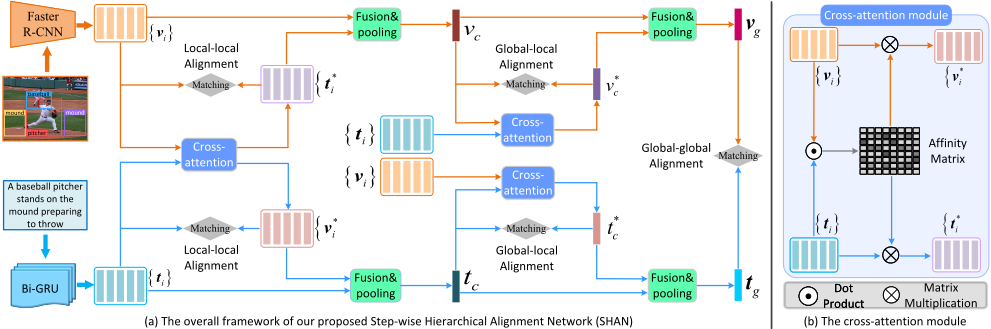
To circumvent the aforementioned issues, in this work, we propose a Step-wise Hierarchical Alignment Network (SHAN) for image-text matching, which performs hierarchical cross-modal alignment at two semantic levels, i.e., fragment-level alignment and context-level alignment. Specifically, we measure the relevance of an image-text pair by performing three steps of alignments progressively. First of all, we employ cross-attention mechanism to align image regions with textual words to achieve fragment-level localto-local (L2L) alignment, followed by adopting an adaptive cross-modal feature fusion strategy to produce the visual and textual global context representations by fully exploiting the intermediate information produced by last alignment process. Then, based on the generated context representation, we perform global-to-local (G2L) alignment to measure the cross-modal similarities at context-level. Finally, we further perform a global-to-global (G2G) cross-modal alignment by leveraging more context-level information. The main highlights of our proposed method are summarized as follows:
- We propose a novel Step-wise Hierarchical Alignment Network to progressively explore the visual-semantic relevance for image-text matching, which leverages the multi-step hierarchical alignment to provide more com-
- plementary cues to capture the fine-grained cross-modal semantic correlation.
- We conduct experiments on two public datasets: e.g. Flickr30k and MS-COCO, and the quantitative experimental results validate that our model can achieve stateof-the-art performance on both datasets. Detailed visualization on L2L and G2L alignment step also qualitatively verify the effectiveness of our proposed method.
2 RelatedWork
A stride of typical solutions for cross-modal image-text matching [Kiros et al., 2014; Ma et al., 2015; Faghri et al., 2017; Wang et al., 2020a] can be classified as global embedding based image-text matching, which learns a joint embedding space for these heterogeneous data samples, so that the similarity of a given image-text pair can be directly compared. For example, [Kiros et al., 2014] employed a convolution neural network (CNN) and an recurrent neural network (RNN) to extract the global representations for image and text respectively and utilized hinge-based triplet ranking loss to align these heterogeneous data. [Faghri et al., 2017] further modified the ranking loss with hard negative mining and yielded encouraging cross-modal retrieval performance improvement.
Another line of studies [Lee et al., 2018; Hu et al., 2019; Wang et al., 2019] can be summarized as fine-grained interaction based image-text matching, which focuses on exploring the fine-grained interactions between images and texts to obtain a deeper understanding of cross-modal correspondence. [Karpathy and Fei-Fei, 2015] developed a unified deep model to infer the latent alignment between textual segments and the implicit local regions of the image that they depict, and the global image-text similarity is finally calculated by aggregating all the region-word similarities. [Chen et al., 2020] proposed an iterative matching scheme to capture the correspondences between image regions and textual words with multiple steps of alignments, which is mostly relevant to our work. However, they paid less attention to explore the context-level information in images and texts. By contrast, we perform visual-semantic alignment from both perspectives including fragment-level and context-level.
3 Our Method
We construct a Step-wise Hierarchical Alignment Network (SHAN) to progressively explore the semantic alignments between image and text. The overall framework is illustrated in Fig.2 (a). Next, we will introduce the details of our proposed SHAN that contains following three parts: 1) Features representation for image and text; 2) The implementation details of designed Step-wise Hierarchical Alignment model and 3) Objective function for model learning.
3.1 Feature Representation
Image Representation
For image feature extraction, we adopt an off-the-shelf object detection model (i.e. Faster R-CNN) which is pre-trained on Visual Genome dataset to detect k salient objects O =
{o1, · · ·, ok} ∈ Rk×2048 in an image, then a fully-connect layer is followed to project them into D-dimension vectors:
In our experiments, the number of extracted salient regions for each image is set to 36.
Text Representation
We extract the word-level features W = {w1, · · · ,wn} to represent a given text, where n is the number of words in the given sentence. Concretely, We first apply one-hot encoding on input words based on the whole vocabulary of the training dataset, then leverage a pre-trained word embedding model Glove and a learnable embedding layer to transform one-hot codes into fixed vectors and updatable vectors respectively. We then concatenate the two vectors to obtain the final word representations wj .
Next, we employ a bidirectional GRU to enhance the wordlevel representations by capturing the context information in the sentence from both forward and backward directions:
where -→ hj and ←- hj denote the GRU hidden states for forward and backward directions respectively, note that we set the hidden dimension of GRU as D, therefore finally we can get word features T = {t1, · · · , tn} ∈ Rn×D by averaging -→ hj and ←- hj: tj = -→ hj+←- hj 2 .
3.2 Step-wise Hierarchical Alignment
Fragment-level L2L Alignment
In the first step, we carry out fine-grained fragment-level local-to-local matching between visual regions and textual words based on bidirectional cross-attention mechanism (see Fig.2 (b)). Mathematically, we first calculate the region-word affinity matrix as:
where A ∈ Rk×n is the region-word affinity matrix and Aij denotes the semantic similarity of the i-th region and the j-th word.
For region-queried cross-attention, each regional feature is used as a query to assign weights over the n words, then we can construct an attended text-level representation t∗i based on region feature vi by applying weighted combination over the n words, such process can be formulated as follows:
where λ is the temperature parameter of the softmax function. Similarly, we can obtain word attended image-level representations by regarding each word feature as query:
We then define the region-related L2L matching scores and word-related L2L matching scores as follows:
Finally, the L2L matching score for the target image I and text T is obtained through taking average of all region-based matching scores and word-based matching scores as follows:
where µ1 is a hyper-parameter to balance the contributions of region-related L2L relevance and word-related L2L relevance.
Context-level G2L Alignment
At the second step of our SHAN model, we implement a context-level global-to-local alignment mechanism to explore a deeper visual-semantic interaction. This alignment module plays a key role in exploiting the context-level information as complementary clues to understand the semantic correlations between image and text. The global representations for image and text in our model are obtained by implementing fusion and pooling operation on original object/word features and they are both enhanced by cross-modal attention. Specifically, we regard the region-attended text-level representations T∗ = {t∗1 , · · · , t∗k } as the aggregated message passed from textual to visual modality, and the word-attended image-level representations V∗ = {v∗ 1 , · · · , v∗n } as the aggregated message passed from visual to textual modality. Then we fuse the original fragment features with aggregated message from another modality to obtain the global context representation.
Taking the visual regional features V = {v1, · · · , vk} and region-attended text-level representations T∗ = {t∗1 , · · · , t∗k } as an example. We first perform element-wise fusion operation in a dynamic way as follows:
where vc i denotes the contextual information provided by the i-th region vi and its attended semantic knowledge t∗i from textual modality, g ∈ [0, 1] is a gate value to adaptively balance the importance of fused information from vi and t∗i , cat() denotes concatenation on vi and t∗i . Empirically, we found that such an adaptive fusion strategy outperforms the traditional average pooling operation.
For the k regions in an image, we can acquire k fused visual contextual representations Vc = {vc1 , · · · , vck } ∈ Rk×D . Similarly, for the n words in a sentence, n fused textual contextual representations Tc = {tc1 , · · · , tcn } ∈ Rn×D are also obtained. Then we use a simple self-attention mechanism to aggregate these separate features of k regions and n words into one global vector to represent the whole image and the whole sentence:
where γv ∈ R1×k and γt ∈ R1×n denote the weights for convex combination generated by two linear projection layers respectively, vc ∈ R1×D is the global context representation for image I, and tc ∈ R1×D is the global context representation for text T.
Based on the generated visual and textual global context representations, similar to L2L alignment module, we then perform G2L alignment by resorting to bidirectional crossattention mechanism. Specifically, for visual global-queried cross-modal attention, vc is used as an anchor vector to assign weights over n different words according to the semantic similarity between vc and n word features, then we use a convex combination to aggregate textual word features into a visual global-attended text-level representation:
where sim(., .) denotes the distance function to measure the similarity of the two vectors, and sim() represents the Cosine distance function. Similarly, for textual global-queried crossattention, we can obtain the textual global-attended imagelevel representation as follows:
Then the visual global-related G2L matching score and textual global-related G2L matching score are derived as follows:
Afterwards, we define the final G2L matching score between image I and text T by summing up the two matching scores:
where µ2 is a hyper-parameter to balance the contributions of the two matching scores.
Context-level G2G Alignment
On the top level of our SHAN model, we aim to further align the image and text from a global perspective. Specifically, the context-level global representations for image and text are obtained via fusing the intermediate semantic information produced during G2L alignment module, i.e. fusing vc and t∗c to obtain the final visual context-level global representation , and fusing tc and v∗ c to obtain the final textual context-level global representation:
where ⊕ denotes element-wise sum. Our hypothesis is that after L2L and G2L alignment, the generated representations vc and tc have already captured rich implicit information regarding fine-grained visual-textual correlations, such a crossattention based fusion strategy would further encourage the mutual information propagation between both modalities so as to learn more discriminative context-level features.
Then the overall G2G matching score between image I and text T is derived by computing the cosine distance of vg and tg :
3.3 Learning Objective
As aforementioned, our model eventually acquire three matching scores (e.g.SL2L(I, T), SG2L(I, T) and SG2G(I, T)) at different levels for a given image-text pair < I, T >, and the final cross-modal similarity can be defined as follows:
Then, we train our model with a bidirectional hinge-based triplet ranking loss [Faghri et al., 2017; Wang et al., 2020b] that enforces the similarity of matched image-text pair to be higher than that of unmatched ones.
| Method | Text Retrieval | Image Retrieval | Rsum | ||||
|---|---|---|---|---|---|---|---|
| R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | ||
| SCAN [Lee et al., 2018] | 67.4 | 90.3 | 95.8 | 48.6 | 77.7 | 85.2 | 465.0 |
| SAEM [Wu et al., 2019] | 69.1 | 91.0 | 95.1 | 52.4 | 81.1 | 88.1 | 477.0 |
| RDAN [Hu et al., 2019] | 68.1 | 91.0 | 95.9 | 54.1 | 80.9 | 87.2 | 477.2 |
| SGM [Wang et al., 2020d] | 71.8 | 91.7 | 95.5 | 53.5 | 79.6 | 86.5 | 478.6 |
| CAAN [Zhang et al., 2020] | 70.1 | 91.6 | 97.2 | 52.8 | 79.0 | 87.9 | 478.6 |
| SHAN-T2I | 72.5 | 92.3 | 95.8 | 53.6 | 78.6 | 85.5 | 478.3 |
| SHAN-I2T | 70.6 | 91.7 | 95.5 | 50.5 | 77.1 | 85.2 | 470.6 |
| SHAN-full | 74.6 | 93.5 | 96.9 | 55.3 | 81.3 | 88.4 | 490.0 |
| Method | Text Retrieval | Image Retrieval | Rsum | ||||
|---|---|---|---|---|---|---|---|
| R@1 | R@5 | R@10 | R@1 | R@5 | R@10 | ||
| SCAN [Lee et al., 2018] | 72.7 | 94.8 | 98.4 | 58.8 | 88.4 | 94.8 | 507.9 |
| SAEM [Wu et al., 2019] | 71.2 | 94.1 | 97.7 | 57.8 | 88.6 | 94.9 | 504.3 |
| RDAN [Hu et al., 2019] | 74.6 | 96.2 | 98.7 | 61.6 | 89.2 | 94.7 | 515.0 |
| SGM [Wang et al., 2020d] | 73.4 | 93.8 | 97.8 | 57.5 | 87.3 | 94.3 | 504.1 |
| CAAN [Zhang et al., 2020] | 75.5 | 95.4 | 98.5 | 61.3 | 89.7 | 95.2 | 515.6 |
| SHAN-T2I | 75.9 | 96.1 | 98.7 | 60.7 | 88.2 | 94.2 | 513.8 |
| SHAN-I2T | 73.0 | 95.8 | 97.9 | 58.5 | 87.3 | 94.0 | 506.5 |
| SHAN-full | 76.8 | 96.3 | 98.7 | 62.6 | 89.6 | 95.8 | 519.8 |
where m is a tuning margin parameter. ˆ T = argmaxt̸=TS(I, t) and ˆ I = argmaxi̸=IS(i, T) stand for contrastive negative samples in a mini-batch. The entire model is trained in an end-to-end manner.
4 Experiments
4.1 Dataset and EvaluationMetric
Dataset
Two benchmark datasets are used in our experiments to testify the performance of our method: (1) Flickr30k contains 31783 images and each image is annotated with 5 sentences. Following [Karpathy and Fei-Fei, 2015], we split the dataset into 1000 test images, 1000 validation images and 29000 training images. (2) MS-COCO is another large-scale image captioning dataset with 123287 images and each image is relative with 5 descriptions. We follow [Lee et al., 2018] to split the dataset into 5000 images for validation, 5000 images for testing and the rest 113287 images for training. We report the matching performance by averaging the 5-folds over 1k test images.
Evaluation Metric
We take Recall@K (R@K, K = 1, 5, 10) that describes the fraction of ground truth instance being retrieved at the top 1, 5, 10 results as the evaluation metric. Following previous works, we evaluate our approach on both text retrieval (find the most related text given an image) and image retrieval (find the matched image described by certain text) tasks. Additionally, the overall matching metric "Rsum" that sums over all recall values is also used to compare our model with other state-of-the-art methods.
4.2 Implementation Details
We present three variants of SHAN model to systematically investigate the effectiveness of our proposed approach: (1) SHAN-T2I applies hierarchical alignment only in text-toimage direction, the global representation for image in G2G alignment module is obtained simply by taking average over extracted regional features. (2) SHAN-I2T applies hierarchical alignment only in image-to-text direction, the global representation for text in G2G alignment module is obtained by taking average over word features. (3) SHAN-full applies hierarchical alignment both in text-to-image and image-to-text direction. We train our model with Adam optimizer for 30 epochs on each dataset. The dimension of joint embedding space for image regions and textual words are set to 1024, and the dimension of word embeddings is set to be 300, other parameters are empirically set as follows: µ1= 0.3, µ2= 0.5, λ= 15 and m = 0.2.
4.3 Comparison with State-of-the-art Methods
Table 1 and Table 2 display the performance comparison between our SHAN model and several state-of-the-art methods on Flickr30k and MS-COCO dataset, respectively. We can observe that our model achieves the best retrieval results on both datasets. Specifically, for text retrieval, our SHAN-full achieves a maximal improvement of 2.8% and 1.3% in terms of R@1 score on Flickr30k and MS-COCO, respectively. As for image retrieval, our best model reaches at 55.3% R@1 score and a 62.6% R@1 score on Flickr30k and MS-COCO respectively, which also surpasses other state-of-the-art methods. Similar performance improvement can be seen from other evaluation metrics (e.g. R@5, R@10).
Step: 2
| Method | Text Retrieval | Image Retrieval | Rsum | ||
|---|---|---|---|---|---|
| R@1 | R@5 | R@1 | R@5 | ||
| SHAN-T2I Glove | 74.8 | 94.9 | 59.9 | 88.4 | 510.9 |
| SHAN-T2I ∆Glove | 74.9 | 95.2 | 59.7 | 88.0 | 510.7 |
| SHAN-T2I random | 75.0 | 96.0 | 59.6 | 87.6 | 510.2 |
| SHAN-T2I L2L | 72.4 | 94.5 | 58.2 | 87.5 | 504.4 |
| SHAN-T2I L2L+G2L | 74.9 | 95.5 | 59.3 | 88.4 | 510.5 |
| SHAN-T2I | 75.9 | 96.1 | 60.7 | 88.2 | 513.8 |
Table 3: Ablation experimental results on MS-COCO 1k testing set in terms of Recall@K(R@K).
4.4 Ablation Studies
In this section, we perform ablation studies to investigate the contributions of each component in our proposed SHAN approach. We first validate the effect of different word embedding models by training SHAN-T2I with fixed Glove embedding only (SHAN-T2IGlove), fine-tuned Glove embedding only (SHAN-T2I∆Glove) and a learnable embedding layer only (SHAN-T2Irandom). Then, we train SHAN-T2I by removing the G2L alignment module (SHAN-T2IL2L) and G2G alignment module (SHAN-T2IL2L + G2L) respectively to testify the impact of the proposed hierarchical alignment framework. The experimental results are shown in Table 3. From Table 3, we can draw the following conclusions: (1) The combination of pre-trained Glove embedding model with learnable embedding model can lead to better performance, in comparison to using Glove only or learnable embedding model only; (2) The proposed context-level global-to-local alignment module and context-level global-to-global alignment module are both validated to be effective by providing considering performance boost.
4.5 Visualization
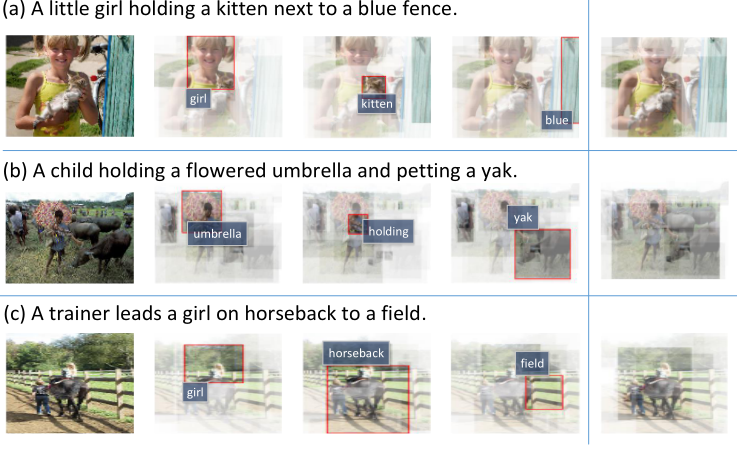
From the qualitative results in Fig.3, we can observe that the words are appropriately matched with its corresponding depicted regions at alignment step 1. For example, in Fig. 3 (b), our model can well generate interpretable attention weights on nouns like "umbrella" and "yak", as well as the actions like "holding". It reveals that L2L alignment module is really conducive to bridging the gap between heterogeneous fragments. At step 2 of alignment, we can see that the meaningful image regions contributing to understanding the global context information are highlighted and trivial ones are suppressed. Overall, these observations confirm the effectiveness of our proposed alignment modules.
5 Conclusion
In this paper, we proposed a Step-wise Hierarchical Alignment Network (SHAN) for image-text matching. Specifically, fragment-level local-to-local alignment, context-level global-to-local alignment and context-level global-to-global alignment were performed progressively to learn the visualsemantic correspondence between instances from different modalities. We conducted extensive experiments and ablation studies on two widely-used benchmark datasets, and the experimental results demonstrated our method can achieve competitive results.
@inproceedings{ijcai2021p106,
  title     = {Step-Wise Hierarchical Alignment Network for Image-Text Matching},
  author    = {Ji, Zhong and Chen, Kexin and Wang, Haoran},
  booktitle = {Proceedings of the Thirtieth International Joint Conference on
               Artificial Intelligence, {IJCAI-21}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Zhi-Hua Zhou},
  pages     = {765--771},
  year      = {2021},
  month     = {8},
  note      = {Main Track},
  doi       = {10.24963/ijcai.2021/106},
  url       = {https://doi.org/10.24963/ijcai.2021/106},
}
TY - CPAPER TI - Step-Wise Hierarchical Alignment Network for Image-Text Matching AU - Ji, Zhong AU - Chen, Kexin AU - Wang, Haoran T2 - Proceedings of the Thirtieth International Joint Conference on Artificial Intelligence, IJCAI-21 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2021 SP - 765 EP - 771 DO - 10.24963/ijcai.2021/106 UR - https://doi.org/10.24963/ijcai.2021/106 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





