
SBAT: Video Captioning with Sparse Boundary-Aware Transformer
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 630-636.
https://doi.org/10.24963/ijcai.2020/88
Keywords
- Computer Vision: Video: Events, Activities and Surveillance
- Computer Vision: Language and Vision
Abstract
In this paper, we focus on the problem of applying the transformer structure to video captioning effectively. The vanilla transformer is proposed for uni-modal language generation task such as machine translation. However, video captioning is a multimodal learning problem, and the video features have much redundancy between different time steps. Based on these concerns, we propose a novel method called sparse boundary-aware transformer (SBAT) to reduce the redundancy in video representation. SBAT employs boundary-aware pooling operation for scores from multihead attention and selects diverse features from different scenarios. Also, SBAT includes a local correlation scheme to compensate for the local information loss brought by sparse operation. Based on SBAT, we further propose an aligned cross-modal encoding scheme to boost the multimodal interaction. Experimental results on two benchmark datasets show that SBAT outperforms the state-of-the-art methods under most of the metrics.
- [Aafaq et al., 2019] Nayyer Aafaq, Naveed Akhtar, Wei Liu, Syed Zulqarnain Gilani, and Ajmal Mian. Spatio-temporal dynamics and semantic attribute enriched visual encoding for video captioning. In CVPR, 2019.
- [Antol et al., 2015] Stanislaw Antol, Aishwarya Agrawal, Ji- asen Lu, Margaret Mitchell, Dhruv Batra, C Lawrence Zit- nick, and Devi Parikh. Vqa: Visual question answering. In ICCV, 2015.
- [Carreira and Zisserman, 2017] Joao Carreira and Andrew Zisserman. Quo vadis, action recognition? a new model and the kinetics dataset. In CVPR, 2017.
- [Chen and Dolan, 2011] David L Chen and William B Dolan. Collecting highly parallel data for paraphrase eval- uation. In ACL, 2011.
- [Chen and Jiang, 2019] Shaoxiang Chen and Yu-Gang Jiang. Motion guided spatial attention for video captioning, 2019.
- [Chen et al., 2018] Ming Chen, Yingming Li, Zhongfei Zhang, and Siyu Huang. Tvt: Two-view transformer net- work for video captioning. In ACML, 2018.
- [Gan et al., 2017] Zhe Gan, Chuang Gan, Xiaodong He, Yunchen Pu, Kenneth Tran, Jianfeng Gao, Lawrence Carin, and Li Deng. Semantic compositional networks for visual captioning. In CVPR, 2017.
- [Hori et al., 2017] Chiori Hori, Takaaki Hori, Teng-Yok Lee, Ziming Zhang, Bret Harsham, John R Hershey, Tim K Marks, and Kazuhiko Sumi. Attention-based multimodal fusion for video description. In ICCV, 2017.
- [Jin et al., 2019a] Tao Jin, Siyu Huang, Yingming Li, and Zhongfei Zhang. Low-rank hoca: Efficient high-order cross-modal attention for video captioning. arXiv preprint arXiv:1911.00212, 2019.
- [Jin et al., 2019b] Tao Jin, Yingming Li, and Zhongfei Zhang. Recurrent convolutional video captioning with global and local attention. Neurocomputing, 2019.
- [Kingma and Ba, 2014] Diederik P Kingma and Jimmy Ba. Adam: A method for stochastic optimization. arXiv preprint arXiv:1412.6980, 2014.
- [Li et al., 2019] Xiangpeng Li, Jingkuan Song, Lianli Gao, Xianglong Liu, Wenbing Huang, Xiangnan He, and Chuang Gan. Beyond rnns: Positional self-attention with co-attention for video question answering. In AAAI, 2019.
- [Long et al., 2018] Xiang Long, Chuang Gan, and Gerard de Melo. Video captioning with multi-faceted attention. TACL, 2018.
- [Pan et al., 2017] Yingwei Pan, Ting Yao, Houqiang Li, and Tao Mei. Video captioning with transferred semantic at- tributes. In CVPR, 2017.
- [Pei et al., 2019] Wenjie Pei, Jiyuan Zhang, Xiangrong Wang, Lei Ke, Xiaoyong Shen, and Yu-Wing Tai. Memory-attended recurrent network for video captioning. In CVPR, 2019.
- [Shen et al., 2017] Zhiqiang Shen, Jianguo Li, Zhou Su, Minjun Li, Yurong Chen, Yu-Gang Jiang, and Xiangyang Xue. Weakly supervised dense video captioning. In CVPR, 2017.
- [Szegedy et al., 2017] Christian Szegedy, Sergey Ioffe, Vin- cent Vanhoucke, and Alexander A Alemi. Inception-v4, inception-resnet and the impact of residual connections on learning. In AAAI, 2017.
- [Vaswani et al., 2017] Ashish Vaswani, Noam Shazeer, Niki Parmar, Jakob Uszkoreit, Llion Jones, Aidan N Gomez, Łukasz Kaiser, and Illia Polosukhin. Attention is all you need. In NIPS, 2017.
- [Venugopalan et al., 2015] Subhashini Venugopalan, Mar- cus Rohrbach, Jeffrey Donahue, Raymond Mooney, Trevor Darrell, and Kate Saenko. Sequence to sequence- video to text. In ICCV, 2015.
- [Wang et al., 2019] Bairui Wang, Lin Ma, Wei Zhang, Wen- hao Jiang, Jingwen Wang, and Wei Liu. Controllable video captioning with pos sequence guidance based on gated fu- sion network. In ICCV, 2019.
- [Xu et al., 2016] Jun Xu, Tao Mei, Ting Yao, and Yong Rui. Msr-vtt: A large video description dataset for bridging video and language. In CVPR, 2016.
- [Yao et al., 2015] Li Yao, Atousa Torabi, Kyunghyun Cho, Nicolas Ballas, Christopher Pal, Hugo Larochelle, and Aaron Courville. Describing videos by exploiting tempo- ral structure. In ICCV, 2015.
- [You et al., 2016] Quanzeng You, Hailin Jin, Zhaowen Wang, Chen Fang, and Jiebo Luo. Image captioning with semantic attention. In CVPR, 2016.
- [Zhou et al., 2018] Luowei Zhou, Yingbo Zhou, Jason J Corso, Richard Socher, and Caiming Xiong. End-to- end dense video captioning with masked transformer. In CVPR, 2018.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
Recently, the combination of vision and language attracts more and more attention [You et al., 2016; Pan et al., 2017; Antol et al., 2015; Li et al., 2019]. Video captioning is a valuable but challenging task in this topic, where the goal is to generate text descriptions for video data directly. The difficulties of video captioning mainly lie in the modeling of temporal dynamics and the fusion of multiple modalities.
Encoder-decoder structures are widely used in video captioning [Shen et al., 2017; Aafaq et al., 2019; Pei et al., 2019; Wang et al., 2019; Gan et al., 2017]. In general, the encoder learns multiple types of features from raw video data. The decoder utilizes these features to generate words. Most encoder-decoder structures are built upon the long short-term memory (LSTM) unit, however, LSTM has two main drawbacks. First, LSTM-based decoder does not allow a parallel prediction of words at different time steps, since its hidden
∗Corresponding author.
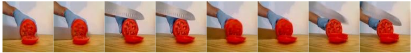
Figure 1: An example of redundancy between video frames.
state is computed based on the previous one. Second, LSTMbased encoder has insufficient capacity to capture the longrange temporal correlations.
To tackle these issues, [Chen et al., 2018] and [Zhou et al., 2018] proposed to replace LSTMwith transformer for video understanding. Specifically, [Chen et al., 2018] used multiple transformer-based encoders to encode video features and a transformer-based decoder to generate descriptions. Similarly, [Zhou et al., 2018] utilized transformer for dense video captioning, [Zhou et al., 2018] utilized a transformer-based encoder to detect action proposals and described them simultaneously with a transformer-based decoder. Different from LSTM, the self-attention mechanism in transformer correlates the features at any two time steps, enabling the global association of features. However, the vanilla transformer is limited in processing video features with much temporal redundancy like the example in Fig. 1. In addition, the crossmodal interaction between different modalities is ignored in the existing transformer-based methods.
Motivated by the above observations, we propose a novel method named sparse boundary-aware transformer (SBAT) to improve the transformer-based encoder and decoder architectures for video understanding. In the encoder, we employ sparse attention mechanism to better capture the global and local dynamic information by solving the redundancy between consecutive video frames. Specifically, to capture the global temporal dynamics, we divide all the time steps into n chunks according to the gradient values of attention logits and select n time steps with top-n gradient values. To capture the local temporal dynamics, we implement self-attention between r adjacent time steps. In the decoder, we also employ the boundary-aware strategy for encoder-decoder multihead attention. In addition, we implement cross-modal sparse attention following the self-attention layer to align multimodal features along temporal dimension. We conduct extensive empirical studies on two benchmark video captioning datasets. The quantitative, qualitative and ablation experimental results comprehensively reveal the effectiveness of our proposed methods.
The main contributions of this paper are three-folded:
- We propose the sparse boundary-aware transformer (SBAT) to improve the vanilla transformer. We use boundaryaware pooling operation following the preliminary scores of multihead attention and select the features of different scenarios to reduce the redundancy.
- We develop a local correlation scheme to compensate for the local information loss brought by sparse operation. The scheme can be implemented synchronously with the boundary-aware strategy.
- We further propose a cross-modal encoding scheme to align the multimodal features along the temporal dimension.
2 RelatedWork
As a popular variant of RNN, LSTM is widely used in existing video captioning methods. [Venugopalan et al., 2015] utilized LSTMto encode video features and decodewords. [Yao et al., 2015] integrated the attention mechanism into video captioning, where the encoded features are given different attention weights according to the queries of decoder. [Hori et al., 2017] further proposed a two-level attention mechanism for video captioning. The first level focuses on different time steps, and the second level focuses on different modalities. [Long et al., 2018] and [Jin et al., 2019b] detected local attributes and used them as supplementary information. [Jin et al., 2019a] introduced cross-modal correlation into attention mechanism. Recently, [Chen et al., 2018] proposed to replace LSTM with transformer in video captioning models. However, directly using transformer for video captioning has several drawbacks, i.e., the redundancy of video features and the lack of multimodal interaction modeling. In this paper, we propose a novel approach called sparse boundary-aware transformer (SBAT) to address these problems.
3 Transformer-based Video Captioning
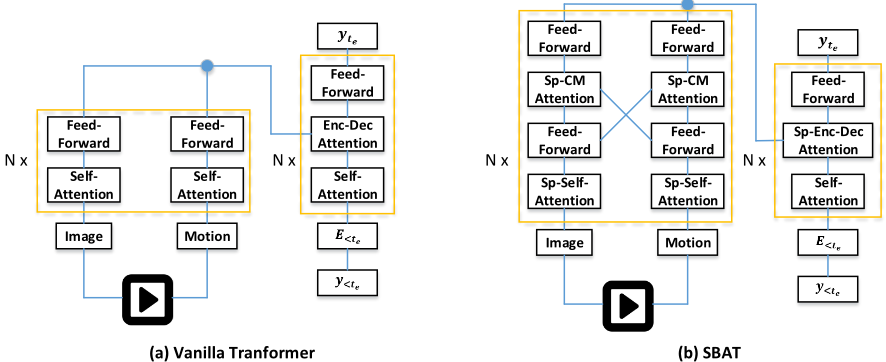
Transformer [Vaswani et al., 2017] is originally proposed for machine translation. Due to the effectiveness and scalability, transformer is employed in many other tasks including video captioning. A simple illustration of transformer-based video captioning model is shown in Fig. 2(a). The encoder and decoder both consist of multihead attention blocks and feedforward neural network.
3.1 Encoder
Different from the uni-modal inputs of machine translation, the inputs of video captioning are typically multimodal. As shown in Fig. 2(a), two separate encoders process image and motion features, respectively. We use I ∈ RTi×d and M ∈ RTm×d to denote the image and motion features, respectively. Here we take the process of image encoding as an example. The self-attention layer is formulated as
where "Cat" denotes concatenation operation, W1 ∈ Rd×d is a trainable variable. Multihead attention is a special variant of attention, where each head is calculated as
where W Q i , W K i , and W V i ∈ Rd× dh are also trainable variables, "Attention" denotes scaled dot-product attention:
where d is dimension of Q and K. We adopt residual connection and layer normalization after the self-attention layer:
Every self-attention layer is followed by a feed-forward layer (FFN) that employs non-linear transformation:
where W2 ∈ Rd×4d , b2 ∈ R4d , W3 ∈ R4d×d , and b3 ∈ Rd are trainable variables. The encoded image features I ′ is the output of an encoder block. The encoded motion features M ′ are calculated in the same way.
3.2 Decoder
The decoder block consists of self-attention layer, enc-dec attention layer, and feed-forward layer. In the self-attention layer, the word embeddings of different time steps associate with each other, and we take the output features as queries. In the enc-dec multihead attention layer, the query first associates image and motion features to get two context vectors respectively, then generates the words. The feed-forward layer in decoder is the same as Eqns. 6 and 7. We also adopt residual connection and layer normalization after all the layers of the decoder.
Specifically, we use E ∈ RTe×d to denote the embeddings of target words. To predict the word yte at time step te, the self-attention layer is formulated as
where E<te ∈ R(te-1)×d denotes the word embeddings of time steps less than te. The enc-dec attention layer is:
Following [Hori et al., 2017], we employ a hierarchical attention layer for Ite andMte :
V ′ te = LayerNorm(Vte + FFN(Vte )) denotes the output of feed-forward layer. We calculate the probability distributions of words as:
where I ′ andM ′ denote the encoded video features. The optimization goal is to minimize the cross-entropy loss function defined as accumulative loss from all the time steps:
where y∗ te denotes the ground-truth word at time step te.
4 Sparse Boundary-Aware Attention
Considering the redundancy of video features, it is not appropriate to compute attention weights using vanilla multihead attention. To solve the problem, we introduce a novel sparse boundary-aware strategy into the multihead attention. In Section 4.1, we introduce the sparse boundary-aware strategy. In Section 4.2, we provide the analysis of sparse boundaryaware strategy. In Section 4.3, we introduce the local correlation attention which compensates for the local information loss. In Section 4.4, we introduce an aligned cross-modal encoding scheme based on SBAT.
4.1 Sparse Boundary-Aware Pooling
We employ sparse boundary-aware strategy following the scaled dot-product attention logits. Specifically, the original logits are calculated as follows:
where Q ∈ RTq×d and K ∈ RTk×d denote the query and key, respectively; d represents the dimension of Q and K. We utilize Pi,j to represent the associated result of Qi ∈ Rd and Kj ∈ Rd . The discrete first derivative of P in the second dimension is obtained as follows:
For time step i of the query, we choose top-n values in P ′ i , since the boundary of two scenarios always has high gradient value.
where ci is the n-th largest value of P ′ i . We implement softmax function for the processed H(P, n).
Furthermore, to keep the time steps with large original logits, we define P ∗ i,j to replace P ′ i,j :
(18) P ′ i,j is a special variant of P ∗ i,j when α = 1.
4.2 Theoretical Analysis of Boundary-Aware Pooling
Suppose we randomly choose one time step of Q ∈ RTq×d as query q ∈ Rd , the query q associates K ∈ RTk×d at all the time steps. The logits of scaled dot-product attention are [p1, p2, ..., pTk ] ∈ RTk . We calculate the attention weight of each time step as:
To the best of our knowledge, there are about 3-5 scenarios on average in a ten-second video clip at a coarse granularity, like the example in Fig. 1. One-second clip usually contains 25 frames. Therefore, most frames in the same scenario are redundant. Existing methods sample the video to a fixed number of frames or directly reduce the frame rate. Although such methods are effective to some extent, there is still much redundancy in the scenarios that have a large number of time steps. The total attention weights of the scenarios with fewer time steps may be influenced. Specifically, we divide Tk time steps into two groups. The scenario one occupies T1 time steps, the remaining T2 time steps belong to scenario two. Suppose that the features of different time steps in the same scenario are the same, we obtain the total weights of two scenarios as follows:
where Asγ denotes the total weight of scenario γ, psγ denotes the associated logit. Suppose the query is related to scenario two (ps1 < ps2 ) and T1 > T2, the ratio of T1 to T2 may influence the total attention weights (As1 and As2 ) of two scenarios.
More concretely, we assume that T1 is 0.75Tk and T2 is 0.25Tk. As1 and As2 are calculated as:
if we apply sparse boundary-aware pooling strategy (P ′ i,j ) for the logits and sample one time step in each scenario. Both As1 and As2 are transformed and the weight of scenario two obviously increases.
However, when the query is related to scenario one (ps1 > ps2 ). It is not appropriate to reduce the proportion of scenario one. Therefore, we define P ∗ i,j to replace P ′ i,j and select not only the boundaries of scenarios, but also the time steps with large original logits. Specifically, the number of selected steps is n, we sample two boundaries in the two scenarios and the remaining n-2 time steps belong to scenario one. A′s1 is obtained as:
for the increase from As1 in Eqn. 21 to A′s1 in Eqn. 25, we just need to ensure that n - 1 > 3.
When the video clip has more than two scenarios, we also divide them into two groups. One has the scenarios with larger logits, the other has the remaining scenarios. The above analysis of two scenarios is approximately applicable in this situation.
4.3 Local Correlation
Since we employ sparse boundary-aware strategy for the attention logits, the local information between consecutive frames is ignored. We develop a local correlation scheme based on the multihead attention to compensate for the information loss. Formally, the original logits P are obtained following Eqn. 16. The correlation scheme is
where r denotes the maximum distance of two frames and the correlation size is 2r. In practice, the local correlation and boundary-aware correlation are utilized simultaneously.
4.4 Cross-Modal Scheme
Existing methods deal with different modalities separately in the encoder and ignore the interaction between different modalities. Here, we propose an aligned cross-modal scheme based on sparse boundary-aware attention. We divide the video into a fixed number of video chunks and then extract image and motion features from these chunks at the same intervals. Therefore, the feature vectors at the same step are extracted from the same video chunk. We directly apply our sparse boundary-aware attention to the aligned features. When the query is image modality, the key is motion modality, vice versa. Taking the former situation as an example, we compute the results of vanilla and boundary-aware crossmodal attentions as follows:
where CM denotes cross-modal.
5 Video Captioning with SBAT
We introduce the encoder-decoder structure combined with our sparse boundary-aware attention for video captioning. As shown in Fig. 2(b), we replace all the vanilla multihead attention blocks with boundary-aware attention blocks, except for the self-attention block for target word embeddings. Different from the original structure, an additional cross-modal attention layer is adopted following the self-attention layer in the encoder. In the decoder, we also introduce the boundaryaware attention into the enc-dec attention layer, but we set α to 0 in Eqn. 18 and do not use local correlation.
6 Experimental Methodology
6.1 Datasets andMetrics
We evaluate SBAT on two benchmark video captioning datasets, MSVD [Chen and Dolan, 2011] and MSR-VTT [Xu et al., 2016]. Both the datasets are provided by Microsoft Research, and a series of state-of-the-art methods have been proposed based on these datasets in recent years. MSVD contains 1970 video clips and each video clip is about 10 to 25 seconds long and annotated with about 40 English sentences. MSR-VTT is larger than MSVD with 10000 YouTube video clips in total and each clip is annotated with 20 English sentences. We follow the commonly used protocol in the previous work and evaluate methods under four standard metrics including BLEU, ROUGE, METEOR, and CIDEr.
| Method | MSVD | MSR-VTT | ||||||
|---|---|---|---|---|---|---|---|---|
| BLEU4 | ROUGE | METEOR | CIDEr | BLEU4 | ROUGE | METEOR | CIDEr | |
| Vanilla Transformer | 51.4 | 69.7 | 34.6 | 86.4 | 40.9 | 60.4 | 28.5 | 48.9 |
| SBAT (w/o CM) | 52.4 | 71.2 | 35.0 | 87.0 | 42.0 | 60.8 | 28.5 | 50.1 |
| SBAT (w/o Local) | 53.5 | 72.3 | 35.2 | 88.9 | 41.9 | 61.0 | 28.4 | 50.5 |
| SBAT (Sample) | 51.3 | 71.9 | 35.2 | 88.6 | 42.3 | 61.0 | 28.7 | 51.0 |
| SBAT | 53.1 | 72.3 | 35.3 | 89.5 | 42.9 | 61.5 | 28.9 | 51.6 |
6.2 Data Preprocessing
We extract image features and motion features of video data. For image features, we sample video data to 80 frames and use the pre-trained Inception-ResNet-v2 [Szegedy et al., 2017] model to obtain the activations from the penultimate layer. For motion features, we divide the raw video data into video chunks centered on the sampled frames and use the pretrained I3D [Carreira and Zisserman, 2017] model to obtain the activations from the last convolutional layer. We implement a mean-pooling operation along the temporal dimension to get the motion features. On MSR-VTT, we also employ glove embeddings of the auxiliary video category labels to facilitate feature encoding.
6.3 Experimental Details
The hidden size is set to 512 for all the multihead attention mechanisms. The numbers of heads and attention blocks are 8 and 4, respectively. The value of α is set to 0.8 in the encoder and 0 in the decoder. In the training phase, we use Adam [Kingma and Ba, 2014] algorithm to optimize the loss function. The learning rate is initially set to 0.0001. If the CIDEr on validation set does not improve over 10 epochs, we change the learning rate to 0.00002. The batch size is set to 32. In the testing phase, we use the beam-search method with a beam-width of 5 to generate words. We use the pre-trained word2vec embeddings to initialize the word vectors. Each word is represented as a 300-dimension vector.
7 Experimental Results
7.1 Impact of Sparse Boundary-Aware Attention
We first evaluate the effectiveness of different variants of SBAT, as shown in Table 1. Vanilla Transformer and SBAT
denote the models in Fig. 2(a) and (b). SBAT (w/o CM) denotes the model without aligned cross-modal attention. SBAT (w/o Local) denotes the model without local correlation in the encoder. SBAT (Sample) denotes the model with equidistant sampling for all the time steps, rather than our boundaryaware operation.
In Table 1, Vanilla Transformer achieves relatively bad results on both datasets. However, when we adopt boundaryaware or equidistant sampling strategies in the multihead attentions, the performances are obviously improved. SBAT with boundary-aware attention, local correlation, and aligned cross-modal interaction achieves promising results under all the metrics. The comparison between SBAT (w/o CM) and SBAT shows that the cross-modal interaction provides useful cues for generating words. The comparison between SBAT (w/o Local) and SBAT shows that the local correlation can make up the loss of local information. Comparing SBAT and SBAT (Sample), although equidistant sampling reduces the feature redundancy to some extent, the ratio between different scenarios is not considered, while SBAT solves this problem effectively.
7.2 Comparison of P ′ and P
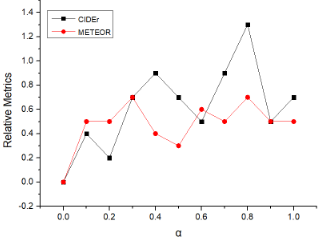
To evaluate the impact of P ∗ and find an appropriate ratio between P ′ and P, we adjust the value of α in Eqn. 18 based on SBAT. The experimental results are shown in Fig. 3. Note that we only adjust the value of α in the encoder, and the value of α in the decoder is always 0. We observe that P ∗ with α = 0.8 achieves the best performances on both METEOR and CIDEr. In addition, only using original logits P (α = 0) shows the worst performances, indicating that our proposed boundary-aware strategy P ′ is a significant boost for the transformer-based video captioning model.
7.3 Comparison with State-of-the-art
Table 2 shows the results of different methods on MSVD and MSR-VTT. For a fair comparison, we compare SBAT with the methods which also use image features and motion features. The comparison methods include TVT [Chen et al., 2018], MGSA [Chen and Jiang, 2019], Dense Cap [Shen et al., 2017], MARN [Pei et al., 2019], GRU-EVE [Aafaq et al., 2019], POS-CG [Wang et al., 2019], SCN [Gan et al., 2017]. In Table 2, SBAT shows better or competitive performances compared with the state-of-the-art methods. On MSR-VTT, SBAT outperforms TVT, MGSA, Dense Cap, MARN, GRU-EVE, POS-CG on all the metrics. In partic-
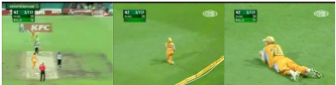
Vanilla Transformer: two teams are playing football
SBAT: a player is playing cricket
GT: men are playing cricket
Vanilla Transformer: a woman is slicing an apple SBAT: a woman is slicing a tomato
GT: someone is slicing a tomato
GT: two men are wrestling
| Dataset | Method | B | R | M | C |
|---|---|---|---|---|---|
| MSR- VTT | TVT | 40.1 | 61.1 | 28.2 | 47.7 |
| MGSA | 42.4 | - | 27.6 | 47.5 | |
| Dense Cap | 41.4 | 61.1 | 28.3 | 48.9 | |
| MARN | 40.4 | 60.7 | 28.1 | 47.1 | |
| GRU-EVE | 38.3 | 60.7 | 28.4 | 48.1 | |
| POS-CG | 42.0 | 61.1 | 28.1 | 49.0 | |
| SBAT | 42.9 | 61.5 | 28.9 | 51.6 | |
| MSVD | TVT | 53.2 | - | 35.2 | 86.8 |
| SCN | 51.1 | - | 33.5 | 77.7 | |
| MARN | 48.6 | 71.9 | 35.1 | 92.2 | |
| GRU-EVE | 47.9 | 71.5 | 35.0 | 78.1 | |
| POS-CG | 52.5 | 71.3 | 34.1 | 88.7 | |
| SBAT | 53.1 | 72.3 | 35.3 | 89.5 |
Table 2: Evaluation results of video captioning, where B, R, M, C denote BLEU4, ROUGE, METEOR, CIDEr, respectively.
ular, SBAT achieves 51.6% on CIDEr, making an improvement of 2.6% over POS-CG. On MSVD, SBAT outperforms SCN, GRU-EVE, POS-CG on all the metrics and has a better overall performance than TVT and MARN.
7.4 Visualization of AttentionMechanism
To further illustrate the effectiveness of SBAT, we conduct a case study and visualize the attention distributions of SBAT and Vanilla Transformer. In Fig. 5, we take a video clip for example. Note that we only visualize the weights of image modality for convenience, and we do not show the local attention weights. Fig. 5(a) shows that the attention weights of Vanilla Transformer are dispersed and Vanilla Transformer has a poor ability to detect the boundary of different scenarios. While Fig. 5(b) shows that (1) SBAT has more sparse attention weights than Vanilla Transformer; (2) SBAT accurately detects the scenario boundaries.
7.5 Qualitative Results
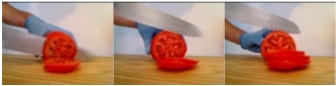
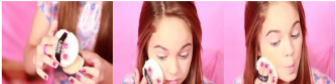
Fig. 4 shows several qualitative examples. We compare the descriptions generated by Vanilla Transformer, SBAT, and ground truth (GT). With the help of redundancy reduction and a better usage of global and local information, SBAT generates more accurate descriptions that are close to GT.
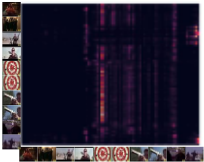
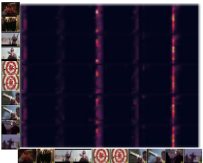
Figure 5: Visualization of attention mechanism. (a) and (b) denote Vanilla Transformer and SBAT, respectively. x and y axes both denote continuous video frames. The generated descriptions of two methods are both "a man is shooting a gun".
8 Conclusion
In this paper, we have proposed a new method called sparse boundary-aware transformer (SBAT) for video captioning. Specifically, we have proposed sparse boundary-aware strategy for improving the attention logits in vanilla transformer. Combined with local correlation and cross-modal encoding, SBAT can effectively reduce the feature redundancy and capture the global-local video information. The quantitative, qualitative, and ablation experiments on two benchmark datasets have demonstrated the advantage of SBAT.
Acknowledgments
This work is supported in part by Science and Technology Innovation 2030 -"New Generation Artificial Intelligence" Major Project No.(2018AAA0100904), National Key R&D Program of China (No. 2018YFB1403600), NSFC (No. 61672456, 61702448, U19B2043), Artificial Intelligence Research Foundation of Baidu Inc., the funding from HIKVision and Horizon Robotics, and ZJU Converging Media Computing Lab.
@inproceedings{ijcai2020p88,
  title     = {SBAT: Video Captioning with Sparse Boundary-Aware Transformer},
  author    = {Jin, Tao and Huang, Siyu and Chen, Ming and Li, Yingming and Zhang, Zhongfei},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {630--636},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/88},
  url       = {https://doi.org/10.24963/ijcai.2020/88},
}
TY - CPAPER TI - SBAT: Video Captioning with Sparse Boundary-Aware Transformer AU - Jin, Tao AU - Huang, Siyu AU - Chen, Ming AU - Li, Yingming AU - Zhang, Zhongfei T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 630 EP - 636 DO - 10.24963/ijcai.2020/88 UR - https://doi.org/10.24963/ijcai.2020/88 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





