
Individual Fairness Revisited: Transferring Techniques from Adversarial Robustness
Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence. Main track. Pages 437-443.
https://doi.org/10.24963/ijcai.2020/61
Keywords
- Machine Learning: Adversarial Machine Learning
- AI Ethics: Fairness
Abstract
We turn the definition of individual fairness on its head - rather than ascertaining the fairness of a model given a predetermined metric, we find a metric for a given model that satisfies individual fairness. This can facilitate the discussion on the fairness of a model, addressing the issue that it may be difficult to specify a priori a suitable metric. Our contributions are twofold:
First, we introduce the definition of a minimal metric and characterize the behavior of models in terms of minimal metrics. Second, for more complicated models, we apply the mechanism of randomized smoothing from adversarial robustness to make them individually fair under a given weighted Lp metric. Our experiments show that adapting the minimal metrics of linear models to more complicated neural networks can lead to meaningful and interpretable fairness guarantees at little cost to utility.
- [Andrzejak et al., 2001] Ralph G Andrzejak, Klaus Lehn- ertz, Florian Mormann, Christoph Rieke, Peter David, and Christian E Elger. Indications of nonlinear deterministic and finite-dimensional structures in time series of brain electrical activity: Dependence on recording region and brain state. Physical Review E, 64(6):061907, 2001.
- [Angwin et al., 2016] Julia Angwin, Jeff Larson, Surya Mattu, and Lauren Kirchner. Machine bias: There's soft- ware used across the country to predict future criminals. and it's biased against blacks. ProPublica, 2016.
- [Calmon et al., 2017] Flavio Calmon, Dennis Wei, Bhanuki- ran Vinzamuri, Karthikeyan Natesan Ramamurthy, and Kush R Varshney. Optimized pre-processing for discrimi- nation prevention. In Advances in Neural Information Pro- cessing Systems, pages 3992-4001, 2017.
- [Canetti et al., 2019] Ran Canetti, Aloni Cohen, Nishanth Dikkala, Govind Ramnarayan, Sarah Scheffler, and Adam Smith. From soft classifiers to hard decisions: How fair can we be? In ACM Conference on Fairness, Accountabil- ity, and Transparency, pages 309-318, 2019.
- [Chouldechova and Roth, 2018] Alexandra Chouldechova and Aaron Roth. The frontiers of fairness in machine learning. arXiv preprint arXiv:1810.08810, 2018.
- [City of Chicago, 2017] City of Chicago. Strategic Sub- ject List. https://data.cityofchicago.org/Public-Safety/ Strategic-Subject-List/4aki-r3np, 2017. Link
- [Cohen et al., 2019] Jeremy Cohen, Elan Rosenfeld, and Zico Kolter. Certified adversarial robustness via random- ized smoothing. In International Conference on Machine Learning, pages 1310-1320, 2019.
- [Dua and Karra Taniskidou, 2017] Dheeru Dua and Efi Karra Taniskidou. UCI machine learning repository. https://archive.ics.uci.edu/ml, 2017. Link
- [Dwork et al., 2012] Cynthia Dwork, Moritz Hardt, Toniann Pitassi, Omer Reingold, and Richard Zemel. Fairness through awareness. In Innovations in Theoretical Com- puter Science, pages 214-226, 2012.
- [Equivant, 2019] Equivant. Practitioner's guide to COMPAS core. http://www.equivant.com/wp-content/uploads/ Practitioners-Guide-to-COMPAS-Core-040419.pdf, 2019. Link
- [Gillen et al., 2018] Stephen Gillen, Christopher Jung, Michael Kearns, and Aaron Roth. Online learning with an unknown fairness metric. In Advances in Neural Information Processing Systems, pages 2600-2609, 2018.
- [Goodfellow et al., 2015] Ian J Goodfellow, Jonathon Shlens, and Christian Szegedy. Explaining and harnessing adversarial examples. In International Conference on Learning Representations, 2015.
- [Hardt et al., 2016] Moritz Hardt, Eric Price, and Nati Sre- bro. Equality of opportunity in supervised learning. In Ad- vances in Neural Information Processing Systems, pages 3315-3323, 2016.
- [Ilvento, 2019] Christina Ilvento. Metric learning for indi- vidual fairness. arXiv preprint arXiv:1906.00250, 2019.
- [Jung et al., 2019] Christopher Jung, Michael Kearns, Seth Neel, Aaron Roth, Logan Stapleton, and Zhiwei Steven Wu. Eliciting and enforcing subjective individual fairness. arXiv preprint arXiv:1905.10660, 2019.
- [Kairouz et al., 2016] Peter Kairouz, Sewoong Oh, and Pramod Viswanath. Extremal mechanisms for local dif- ferential privacy. Journal of Machine Learning Research, 17(1):492-542, 2016.
- [Lohia et al., 2019] Pranay K Lohia, Karthikeyan Natesan Ramamurthy, Manish Bhide, Diptikalyan Saha, Kush R Varshney, and Ruchir Puri. Bias mitigation post- processing for individual and group fairness. In IEEE In- ternational Conference on Acoustics, Speech and Signal Processing, pages 2847-2851, 2019.
- [Madras et al., 2018] David Madras, Elliot Creager, Toniann Pitassi, and Richard Zemel. Learning adversarially fair and transferable representations. In International Confer- ence on Machine Learning, pages 3381-3390, 2018.
- [Neyman and Pearson, 1933] Jerzy Neyman and Egon Sharpe Pearson. On the problem of the most efficient tests of statistical hypotheses. Philosophical Transactions of the Royal Society of London, 231(694- 706):289-337, 1933.
- [Szegedy et al., 2014] Christian Szegedy, Wojciech Zaremba, Ilya Sutskever, Joan Bruna, Dumitru Erhan, Ian Goodfellow, and Rob Fergus. Intriguing properties of neural networks. In International Conference on Learning Representations, 2014.
- [Tan et al., 2019] Zilong Tan, Samuel Yeom, Matt Fredrik- son, and Ameet Talwalkar. Learning fair representa- tions for kernel models. arXiv preprint arXiv:1906.11813, 2019.
- [Yeom and Fredrikson, 2020] Samuel Yeom and Matt Fredrikson. Individual fairness revisited: Transferring techniques from adversarial robustness. arXiv preprint arXiv:2002.07738, 2020.
- [Zafar et al., 2017] Muhammad Bilal Zafar, Isabel Valera, Manuel Gomez Rodriguez, and Krishna P Gummadi. Fairness beyond disparate treatment & disparate impact: Learning classification without disparate mistreatment. In International Conference on World Wide Web, pages 1171-1180, 2017.
- [Zemel et al., 2013] Rich Zemel, Yu Wu, Kevin Swersky, Toni Pitassi, and Cynthia Dwork. Learning fair representa- tions. In International Conference on Machine Learning, pages 325-333, 2013.
References were extracted automatically from the PDF and may contain errors.
Full text extracted automatically from the PDF; figures, tables and equations may differ. The PDF is the version of record.
1 Introduction
When machine learning models are deployed to make predictions about people, it is important that the model treats individuals fairly. Individual fairness [Dwork et al., 2012] captures the notion that similar people should be treated similarly by imposing a continuity requirement on models. However, this raises the difficult societal question of how to define which people are "similar".
We start in Section 4 from the insight that it may be easier to determine whether a given similarity metric is reasonable than it is to construct one from scratch. Thus, rather than imposing individual fairness with a predetermined similarity metric, we find a metric that corresponds to the behavior of a given model, which can then guide the discussion on whether the model is fair. To facilitate this, we introduce the notion of a minimal fairness metric, and show that in many cases there exists a unique metric that best characterizes the behavior of a given model for this purpose.
In Section 5, we deal with more complicated models, such as deep neural networks, whose minimal metrics are not easily computable. We show that we can make any model provably individually fair by post-processing it with randomized smoothing [Cohen et al., 2019] to impose a given weighted Lp metric. As randomized smoothing was originally applied as a defense against adversarial examples, our result brings to light the connection between individual fairness and adversarial robustness. However, our theorems are in a sense stronger because individual fairness is a uniform requirement that applies to all points in the input space, whereas the certified threshold of Cohen et al. is a function of the input point. Our Laplace and Gaussian smoothing mechanisms are versatile in that they can make a model provably individually fair under any given weighted Lp metric, and we show the minimality of this metric for the smoothed model to argue that we do not add more noise than is necessary.
Finally, our experiments combine the two main elements of our paper-we smooth neural networks to be individually fair under a metric that is proportional to the minimal metrics of linear models trained on the same datasets. Our results on four real datasets show that the neural networks smoothed with Gaussian noise in particular are often approximately as accurate as the original models. Moreover, we can achieve models with similar favorable individual fairness guarantees to those of linear models while still enjoying the increased predictive accuracy enabled by the neural network.
2 RelatedWork
Dwork et al. [2012] introduced the definition of individual fairness, which contrasts with group-based notions of fairness [Hardt et al., 2016; Zafar et al., 2017] that require demographic groups to be treated similarly on average. Motivated in part by group fairness, Zemel et al. [2013] learn a representation of the data that excludes information about a protected attribute, such as race or gender, whose use is often legally prohibited. This work has spurred more research on fair representations [Calmon et al., 2017; Madras et al., 2018; Tan et al., 2019], and the resulting representations implicitly define a similarity metric. However, unlike the weighted Lp metrics that we use, these metrics are harder for humans to interpret and are primarily designed to attain group fairness.
Others approximate individual fairness based on a limited number of oracle queries, which represent human judgments, about whether pair of individuals is similar. Gillen et al. [2018] attempt to learn a similarity metric that is consistent with the human judgments in the setting of online linear contextual bandits. In a more general setting, Ilvento [2019] derives an approximate metric using comparison queries that ask which of two individuals a given third individual is more similar to. Finally, Jung et al. [2019] apply constrained optimization directly without assuming that the human judgments are consistent with a metric.
By contrast, we post-process a model using randomized smoothing to provably ensure individual fairness. Cohen et al. [2019] previously analyzed randomized smoothing in the context of adversarial robustness. In the context of fairness, most post-processing approaches [Hardt et al., 2016; Canetti et al., 2019] do not take individual fairness into account, and although Lohia et al. [2019] consider individual fairness, they define two individuals to be similar if and only if they differ only in the pre-specified protected attribute.
3 Background
In this section, we present the definitions and notation that we will use throughout the paper.
Definition 1 (Distance metric). A nonnegative function D : X ×X → R is a distance metric in X if it satisfies the following three conditions: nonnegativity, symmetry, and triangle inequality.
In common mathematical usage, Definition 1 is a pseudometric, and metrics must also satisfy the condition that D(x1, x2) = 0 if and only if x1 = x2. However, throughout this paper we will refer to pseudometrics as metrics, following the convention in the field of metric learning.
One commonly used family of metrics is the standard Lp metric, which is defined over Rd . In this paper, we consider a more general family of metrics that allows each coordinate to be weighted differently.
Definition 2 (Weighted Lp metric). The weighted Lp metric, with p ≥ 1 and weights wi ≥ 0, is a distance metric in Rd that is defined by the equation
where x1i and x2i are the i-th coordinates of x1 and x2, respectively.
We place the restriction that p ≥ 1 because otherwise the function D does not satisfy the triangle inequality. When wi = 1 for all i, we have the standard Lp metric.
Throughout this paper, we will use X and Y to denote a model's input and output spaces, respectively. Moreover, we will assume a distance metric DY : Y × Y → R that characterizes how close two points in the output space are.
Definition 3 (Individual fairness [Dwork et al., 2012]). A model h : X → Y is individually fair under metric DX : X × X → R if, for all x1, x2 ∈ X ,
Individual fairness captures the intuition that the model should not behave arbitrarily. In particular, it formalizes the notion that similar individuals should be treated similarly, i.e., given two individuals x1, x2 ∈ X , if the distance DX (x1, x2) between them is small, then the distance DY(h(x1), h(x2)) between the outputs of the model on these individuals should also be small.
4 Minimal Distance Metric
One criticism of individual fairness is that it is difficult to apply in practice because it requires one to specify the metric DX [Chouldechova and Roth, 2018]. The choice of a metric in X dictates which individuals should be considered similar, which is highly context-dependent and often controversial. Thus, we take a slightly different approach-rather than specifying a metric DX and asking whether a model is individually fair under that metric, we find one metric under which the model is individually fair. Then, we can reason about whether the metric is appropriate for the task at hand.
However, there could be multiple metrics for which a model is individually fair. In fact, if DX(x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ X, then any model that is individually fair under D′X is also fair under DX , as the metrics are simply upper bounds on the extent to which a model's outputs can vary. On the other hand, our goal is to characterize the behavior of a model, for which we need a tight upper bound. This notion of tightness is captured by the minimality of a distance metric, defined in Definition 4.
Definition 4 (Minimal distance metric). Let M be a set of distance metrics in X. A metric DX ∈ M is minimal inM with respect to model h : X → Y if (1) h is individually fair under DX , and (2) there does not exist a different D′X ∈ M such that h is individually fair under D′X and DX (x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ X .
To see how one may reason about the minimal distance metric, consider a hiring model with a binary output that informs whether a given applicant should be hired. A natural DY in this setting is the 0-1 loss DY(y1, y2) = 1[y1 ̸= y2]. Then, if the hiring model satisfies individual fairness under a metric DX such that DX(x1, x2) = 0 whenever x1 and x2 differ only in race, we can reason that it does not directly use race to discriminate.
We now present Theorem 1, which identifies the unique minimal metric among the set of all metrics.
Theorem 1. Let h : X → Y be a model, and let Mall be the set of all metrics that satisfy the conditions in Definition 1. Then, the metric DX , defined as
for all x1, x2 ∈ X , is the unique minimal metric inMall with respect to h.
Proof. We first prove that DX is a minimal metric, and later we will prove that no other metric is minimal. Since we assume DY to be a metric, it easily follows that DX is also a metric under Definition 1. Moreover, the equality in Eq. (2) always holds by our definition of DX , so h is individually fair under DX . Thus, it remains to show that there does not exist a different D′X ∈ Mall such that h is individually fair under D′X and DX (x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ X .
Now we prove that DX is the unique minimal metric, arguing that D′X cannot be minimal if D′X ̸= DX . If there
Suppose such D′X exists. Since D′X ̸= DX , there must exist some x1, x2 ∈ X such that DX (x1, x2) > D′X (x1, x2). This, combined with Eq. (3), contradicts our assumption that h is individually fair under D′X .
exist x1, x2 ∈ X such that DX(x1, x2) > D′X (x1, x2), then h is not individually fair under D′X . Thus, we must have D′X (x1, x2) ≥ DX(x1, x2) for all x1, x2 ∈ X, but then h is individually fair under DX , so D′X cannot be minimal.
Theorem 1 shows that the minimal metric DX in Mall is defined directly in terms of the model in question. Ideally, we want the minimal metric to be simpler than the model so that it can help us interpret and reason about the fairness of the model. Thus, in the rest of this paper we only consider weighted Lp metrics, which comprise a broad and interpretable family of metrics defined over Rd .
With this set of metrics, we can no longer prove a theorem as general as Theorem 1, so we now prove a result for linear regression models. In this setting, we have Y = R, and the distance metric is simply the absolute value DY(y1, y2) = |y1 - y2|. Theorem 2 identifies the weighted Lp metric that is uniquely minimal for a given linear regression model.
Theorem 2. Let h : Rd → R be a linear regression model with coefficients β1, . . . , βd, and let ML be the set of all weighted Lp metrics. Then, the L1 metric with weights wi = |βi| is the unique minimal metric in ML with respect to h.
Proof. DX is clearly in ML by definition. To see that h is individually fair under DX , note that for all x1, x2 ∈ Rd
The rest of the proof closely mirrors the argument given in the proof of Theorem 1, so we only mention how the proofs differ. As in the proof of Theorem 1, we assume that there exists x1, x2 ∈ Rd such that DX(x1, x2) > D′X (x1, x2). Our goal is to show that D′X is not individually fair, and for this proof we have the additional condition that D′X ∈ML. However, it is not necessarily true that D′X (x1, x2) < DY(h(x1), h(x2)), so we instead construct x′2 such that D′X (x1, x′2 ) < DY(h(x1), h(x′2 )).
Let x′2i = x1i - sgn(βi)|x1i - x2i|. With Eq. (1), we can verify that DX (x1, x2) = DX (x1, x′2 ) for any DX ∈ ML. Moreover, βi(x1i - x′2i ) ≥ 0 for all i, so the equality in Eq. (4) holds if we replace x2 by x′2 . Combining all of these relations, we arrive at the desired result:
5 Randomized Smoothing
For settings without a simple linear relation between the inputs and the outputs, neural networks often replace linear models. However, neural networks are often susceptible to adversarial examples [Szegedy et al., 2014; Goodfellow et al., 2015], which are inputs to the model that are created by applying a small perturbation to an original input with the goal of causing a very large change in the model's output. The frequent success of these attacks show that a small change in X can cause a large change in Y, which is contrary to individual fairness.
Previously, Cohen et al. [2019] introduced randomized smoothing, a post-processing method that ensures that the post-processed model is robust against perturbations of size, measured with the standard L2 norm, up to a threshold that depends on the input point. In this section, for any given metric, we apply a modified version of randomized smoothing and prove that the resulting model is individually fair under that metric. We note that this result does not immediately follow from prior results-individual fairness imposes the same constraint on every point in the input space, whereas the certified threshold of Cohen et al. is a function of the input point.
In the rest of this paper, we assume that Y is categorical, following the setting of Cohen et al. [2019]. In this section, we present and prove two methods for deriving an individually fair model from an arbitrary function f : Rd → Y. Like the models considered by Dwork et al. [2012], our fair model hf,g maps Rd to ∆(Y), which is the set of probability distributions over Y. It is important to note that hf,g is deterministic and that we treat its output simply as an array of probabilities. To avoid confusion with the randomness that we introduce in Section 6, we will write hf,g(x)[y] to denote the probability Pr[hf,g(x) = y].
Definition 5 (Randomized smoothing). Let f : Rd → Y be an arbitrary model, and let g : Rd → R be a probability distribution 1 . Then, the smoothed model hf,g : Rd →∆(Y) is defined by
for all y ∈ Y, and g is called the smoothing distribution.
Intuitively, f is the original model, and the value of the smoothed model hf,g at x is found by querying f on points around x. We choose the points around x according to the distribution g, and the output hf,g(x) of the smoothed model is a probability distribution of the values of f at the queried points. To reason about the individual fairness of hf,g, we use the total variation distance (Eq. (6)) to define the distance D∆(Y) between probability distributions.
5.1 Laplace Smoothing Distribution
One main difference between this setting and that in Section 4 is that we have a choice of the smoothing distribution g. Thus, instead of simply finding a metric under which the model is individually fair, we adapt the smoothing distribution to a given metric. Theorem 3 shows that, for any weighted Lp metric DX , there exists a smoothing distribution g that guarantees that hf,g is individually fair under DX for all f.
Theorem 3 (Laplace smoothing). Let ML be the set of all weighted Lp metrics. For any DX ∈ ML, let g(t) = exp(-2DX(0, t))/Z, where Z is the normalization factor ∫Rd exp(-2DX(0, t)) dt. Then, hf,g is individually fair under DX for all f.
1 We abuse notation and use g to denote both the distribution and its probability density function.
Proof. We will show that D∆(Y)(hf,g(x), hf,g(x + ϵ)) ≤ DX (x, x + ϵ) for all x, ϵ ∈ Rd .
First, since DX (t, t - ϵ) = DX (0, ϵ) for all weighted Lp metric DX , we have
by the triangle inequality. We can apply the first inequality in Eq. (7) to bound the probability g(t - ϵ) in terms of g(t).
Then, for all y ∈ Y we have
Similarly, we can apply the second inequality in Eq. (7) to derive the upper bound
We can now apply a previous result by Kairouz et al. [2016, Theorem 6] to determine the maximum distance between hf,g(x) and hf,g(x + ϵ) that is attainable with the above constraints. For brevity, let c denote exp(-2DX(0, ϵ)). In the context of ε-local differential privacy, Kairouz et al. showed that the maximum possible total variation distance is (eε-1)/(eε+1). Replacing eε with c, we see that the distance between hf,g(x) and hf,g(x + ϵ) is at most (c - 1)/(c + 1).
Finally, it remains to be proven that this quantity is not more than DX(x, x + ϵ), which is equivalent to DX(0, ϵ) for weighted Lp metrics. Since this distance can be written as (ln c)/2, it suffices to show that (c-1)/(c+1) ≤ (ln c)/2 for all c ≥ 1. This inequality follows from the fact that equality holds at c = 1 and that the derivative of the right-hand side is never less than that of the left-hand side for c ≥ 1.
Although Theorem 3 identifies a smoothing distribution that ensures the individual fairness of the resulting model under DX , we also want the smoothed model to retain the utility of the original model f. In the extreme case where g is the uniform distribution over Rd , the resulting model will be a constant function and therefore satisfy individual fairness under any metric, but it will not be very useful for classification tasks. More generally, smoothed models that are individually fair under smaller distance metrics tend to not preserve as much locally relevant information about f . Thus, we argue that a smoothing distribution does not unnecessarily lower the model's utility by showing that DX is minimal. The definition of minimality that we use here differs from Definition 4 in that the smoothed model must be individually fair for all f .
Definition 6 (Minimal distance metric, smoothing). Let M ⊆ ML be a set of distance metrics in Rd . A metric DX ∈ M is minimal in M with respect to a smoothing distribution g if (1) hf,g is individually fair under DX for all f, and (2) there does not exist a different D′X ∈ M such that hf,g is individually fair under D′X for all f and DX (x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ Rd .
For general weighted Lp metrics, the inequalities in Eq. (7) are strict for most t, so the bounds in Eqs. (8) and (9) are not tight, and DX is not guaranteed to be minimal. On the other hand, if DX is a weighted L1 metric, Theorem 4 shows that it is minimal with respect to its Laplace smoothing distribution.
Theorem 4. Let M1 be the set of all weighted L1 metrics. For any DX ∈ M1, let g(t) = exp(-2DX(0, t))/Z, where Z is the normalization factor ∫Rd exp(-2DX(0, t)) dt. Then, DX is uniquely minimal inM1 with respect to g.
Proof. We have already proven in Theorem 3 that hf,g is individually fair under DX for all f. It remains to show that there does not exist a different D′X ∈M1 such that hf,g is individually fair under D′X for all f and DX (x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ Rd .
Let w1, . . . , wd and w′1 , . . . , w′d be the weights of DX and D′X , respectively. If DX(x1, x2) ≥ D′X (x1, x2) for all x1, x2 ∈ Rd , we must have wi ≥ w′i for all i. Moreover, since DX ̸= D′X , there exists i such that wi > w′i . We now construct f such that hf,g is not individually fair under D′X .
Uniqueness follows from the argument given in the last paragraph of the proof of Theorem 1.
Let f : Rd → {0, 1} be a function such that f(x) = 1[xi ≥ 0]. We will show that there exists ϵ > 0 such that D∆(Y)(hf,g(0), hf,g(ϵei)) > D′X (0, ϵei), where ei is the basis vector that is one in the i-th coordinate and zero in all others. Applying Eq. (5) and simplifying, we get hf,g(0)[0] = 1/2 and hf,g(ϵei)[0] = exp(-2wiϵ)/2. Therefore, the distance D∆(Y) is (1 - exp(-2wiϵ))/2. Moreover, we have D′X = w′i ϵ. The ratio D∆(Y)/D′X approaches wi/w′i > 1 as ϵ → 0, so when ϵ is sufficiently small, we have D∆(Y) > D′X .
5.2 Gaussian Smoothing Distribution
As we show in Section 7, in practice Laplace smoothing distributions do not preserve well the utility of f due to their relatively high densities at the tails. Thus, we present Gaussian smoothing as an alternative, which Theorem 5 shows is individually fair under any weighted L2 metric. Since D2(x1, x2) ≤ dmax(0,1/2-1/p)Dp(x1, x2) for any weighted L2 and Lp metrics D2 and Dp with the same weights, we can then scale the weights accordingly to make hf,g fair under any given Lp metric. For simplicity, we only consider the setting of binary classification, i.e., Y = {0, 1}.
Theorem 5 (Gaussian smoothing). Let DX be a weighted L2 metric with weights w1, . . . , wd, and let Σ be a diagonal matrix with Σii = (2πwi)-1 . If g is Gaussian with mean 0 and variance Σ, hf,g is individually fair under DX for all f : Rd → {0, 1}.
To prove this theorem, we will apply the Neyman-Pearson lemma [Neyman and Pearson, 1933], as formulated by Cohen et al. [2019, Lemma 3].
Lemma 6 (Neyman-Pearson). Let X1 and X2 be random variables in Rd with densities µX1 and µX2 , and let f, f ⋆ : Rd → {0, 1} such that f ⋆ (t) = 1 if and only if
Proof of Theorem 5. We proceed by showing that D∆(Y)(hf,g(x), hf,g(x + ϵ)) ≤ DX(x, x + ϵ) for all x, ϵ ∈ Rd and f : Rd → {0, 1}. For any given f, we will first find f ⋆ such that
We will then show that hf ⋆ ,g is individually fair under DX , which together with Eq. (10) implies that hf,g is also individually fair under DX .
Fix x, ϵ ∈ Rd , and assume without loss of generality that hf,g(x)[1] ≤ hf,g(x + ϵ)[1]. Then, we have
We apply Lemma 6 by choosing X1 and X2 such that g(t) = µX1 (x + t) = µX2 (x + ϵ + t). By Eq. (5), we have Pr[f(X1) = 1] = hf,g(x)[1] and Pr[f(X2) = 1] = hf,g(x + ϵ)[1], and similar relations hold between f ⋆ and hf ⋆ ,g. Therefore, if there exists f ⋆ that satisfies the condition in Lemma 6 such that hf,g(x)[1] = hf ⋆ ,g(x)[1], then hf,g(x + ϵ)[1] ≤ hf ⋆ ,g(x + ϵ)[1]. Combining these two (in)equalities, we get
and Eq. (10) follows from Eq. (11) and its hf ⋆ ,g counterpart. We now show that it is possible to find f ⋆ such that hf ⋆ ,g(x)[1] = hf,g(x)[1]. By construction, we have that f ⋆ (t) = 1 if and only if
for some k > 0. Substituting in the Gaussian density function and solving for t, we see that this inequality holds whenever ϵT Σ-1 t ≥ κ, where κ is a constant with respect to t. When evaluating hf ⋆ ,g(x) as per Eq. (5), t is distributed normally, and therefore ϵT Σ-1 t is also (univariate) Gaussian. Thus, with the appropriate value of κ we can obtain the desired f ⋆ .
Finally, it remains to show that hf ⋆ ,g is individually fair under DX . Let τ = ϵT Σ-1 t, and let γ be the density function of τ. With some computation, we see that f ⋆ (t) and f ⋆ (t + ϵ) differ if and only if κ ≤ τ < κ + ϵT Σ-1 ϵ. Moreover, since t has variance Σ, the variance of τ = ϵT Σ-1 t is ϵT Σ-1Var(t)(ϵT Σ-1 )T = ϵT Σ-1 ϵ, and thus the maximum value of γ is (2πϵT Σ-1 ϵ)-1/2 . We apply these two facts to arrive at the desired result:
We end this section with Theorem 7, which states that an L2 metric DX is minimal with respect to its Gaussian smoothing distribution. We omit the proof since it is very similar to that of Theorem 4.
Theorem 7. Let M2 be the set of all weighted L2 metrics. For any DX ∈M2, let w1, . . . , wd be the weights, and let Σ be a diagonal matrix with σii = (2πwi)-1 . If g is a Gaussian with mean 0 and variance Σ, DX is uniquely minimal in M2 with respect to g.
6 Practical Implementation
In practice, it is infeasible to compute hf,g(x) because of the integral in Eq. (5). Therefore, to apply randomized smoothing in practice, we approximate the integral by sampling n points independently from the smoothing distribution g, evaluating the model with this noise added to x, and returning the observed probability of predicting each class on the sampled points. However, the resulting model may not be individually fair due to the finite sample size. Thus, we define and prove (ϵ, δ)-individual fairness, which requires that the model be close to individually fair with high probability.
Definition 7 ((ϵ, δ)-individual fairness). A randomized model h : X → ∆(Y) is (ϵ, δ)-individually fair under metric DX : X × X → R if, for all x1, x2 ∈ X ,
with probability at least 1 - δ. The probability is taken over the randomness of h.
Theorem 8. Let hnf,g be a model that approximates hf,g with n samples. If |Y| = m and hf,g is fair under DX , then hnf,g is (ϵ, 2me-4nϵ2 /m2 )-individually fair under DX .
Proof. Consider any two points x1, x2 ∈ Rd . Since hf,g is individually fair under DX , we have
We will show that |diff[y]| > 2ϵ/mwith probability less than 2e-4nϵ2 /m2 , where diff[y] = (hnf,g (x1)[y] - hnf,g (x2)[y]) - (hf,g(x1)[y] - hf,g(x2)[y]). Then, by union bound, with probability at least 1 - 2me-4nϵ2 /m2 we will have diff[y] > 2ϵ/m for all y ∈ Y, which leads to our desired result.
Fix y ∈ Y, and let Xij = 1[f(xi + tij) = y], where tij is the j-th sample drawn from the smoothing distribution g while evaluating hnf,g (xi). Then, hnf,g (xi)[y] = 1n ∑nj=1 Xij and hf,g(xi)[y] = 1n E[∑nj=1 Xij ], so diff = 1n ∑nj=1 (X1j - X2j -E[X1j -X2j ]). The theorem follows from Hoeffding's inequality.
In the extended version of this paper [Yeom and Fredrikson, 2020], we provide pseudocode of an implementation of randomized smoothing.
7 Experiments
Theorems 3, 5, and 8 show that smoothed models created using randomized smoothing are individually fair, but we have no similar results about their utility except heuristic arguments fromminimality. In this section we measure the utility of smoothed models hf,g on four real-world datasets (detailed below), using the smoothing distributions described in Theorems 3 and 5.
The weights of DX were chosen to be proportional to those of a logistic regression model trained on the same dataset, so the features that receive little weight in the linear model, which are thus less likely to be predictive, have little effect on the output of the smoothed model. The linear model weights were multiplied by a constant between 0.5 and 5 (depending on the dataset) to make the mean weight of DX equal 1. For each dataset, we trained a neural network f with two dense hidden layers of 128 ReLU neurons each, as well as a logistic regression model to use for deriving the targeted metric. When training neural networks, we augmented training data with noise drawn from the smoothing distribution, as prior work [Cohen et al., 2019] shows that this improves the utility of the smoothed model. For smoothing, we sampled n = 105 points, which by Theorem 8 corresponds to a guarantee of δ = 1.8 × 10⁻⁴ at ϵ = 10-2 .
Adult. Our model uses the five numerical features from the UCI Adult dataset [Dua and Karra Taniskidou, 2017] to predict whether a person earns more than $50,000 per year.
COMPAS. We use the dataset compiled by ProPublica [Angwin et al., 2016] to analyze the COMPAS recidivism prediction model [Equivant, 2019]. Our model uses eight features (15 when one-hot encoded) to predict whether a person will recidivate within the next two years.
SSL. The Strategic Subject List dataset [City of Chicago, 2017] contains scores given by Chicago Police Department's model to rate a person's risk of being involved in a shooting incident, either as a perpetrator or a victim. Our model uses the same eight numerical features used by Chicago's model to predict a person's SSL risk score.
Seizure. In the UCI Epileptic Seizure dataset [Dua and Karra Taniskidou, 2017; Andrzejak et al., 2001], every row consists of 178 readings from an EEG taken over a second. Our model predicts whether a person is experiencing a seizure during that second.
7.1 Results
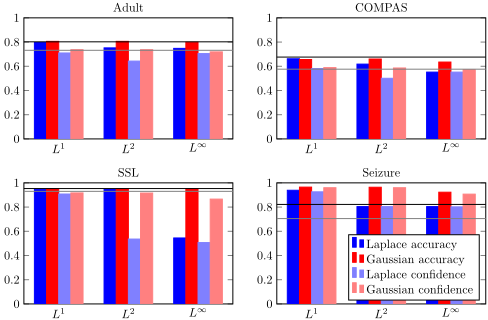
We applied both Laplace and Gaussian smoothing to create models that are individually fair under the weighted L1 , L2 , or L∞ metrics, with weights derived from those of the corresponding logistic regression model as previously described. Because the outputs of the smoothed models are probabilities, we measured their utilities both in terms of standard accuracy and the mean probit confidence assigned to the correct class, E(x,y)[hf,g(x)[y]]. Although accuracy is a more common measure of utility, its use of the thresholding operator argmax is incompatible with the individual fairness of hf,g.
The results in Fig. 1 show that Gaussian-smoothed models approximately match or exceed the performance of the logistic model while achieving similar individual fairness guarantees. We note that for all datasets except for Seizure, the accuracy of the unsmoothed neural network was within 1.5% of the logistic regression model; on Seizure, the neural network achieved 96.6% whereas the logistic model gave 82.2% accuracy. The Gaussian-smoothed Seizure model came very close (≤ 0.2%) to the unsmoothed neural network for L1 and L2 metrics, far exceeding the performance of the linear model.
We conclude by noting that, although L1 metrics are minimal with respect to Laplace smoothing, Gaussian smooothing outperforms on these metrics in practice. Laplace distributions have higher densities at the tails, resulting in more queries that are very dissimilar to the input point x. Thus, in practice it can be preferable to use Gaussian smoothing for every Lp metric, adjusting the weights as shown in Section 5.2 to account for the value of p.
Acknowledgments
This material is based upon work supported by Bosch Corporation, an NVIDIA GPU grant, and the National Science Foundation under Grant No. CNS-1704845. The authors would like to thank Shayak Sen for his helpful feedback.
@inproceedings{ijcai2020p61,
  title     = {Individual Fairness Revisited: Transferring Techniques from Adversarial Robustness},
  author    = {Yeom, Samuel and Fredrikson, Matt},
  booktitle = {Proceedings of the Twenty-Ninth International Joint Conference on
               Artificial Intelligence, {IJCAI-20}},
  publisher = {International Joint Conferences on Artificial Intelligence Organization},
  editor    = {Christian Bessiere},
  pages     = {437--443},
  year      = {2020},
  month     = {7},
  note      = {Main track},
  doi       = {10.24963/ijcai.2020/61},
  url       = {https://doi.org/10.24963/ijcai.2020/61},
}
TY - CPAPER TI - Individual Fairness Revisited: Transferring Techniques from Adversarial Robustness AU - Yeom, Samuel AU - Fredrikson, Matt T2 - Proceedings of the Twenty-Ninth International Joint Conference on Artificial Intelligence, IJCAI-20 PB - International Joint Conferences on Artificial Intelligence Organization PY - 2020 SP - 437 EP - 443 DO - 10.24963/ijcai.2020/61 UR - https://doi.org/10.24963/ijcai.2020/61 ER -Copied
Machine-readable versions of this paper, for tools and AI agents:





